

File: README.md
Sentence Transformers: Embeddings, Retrieval, and Reranking
This framework provides an easy method to compute embeddings for accessing, using, and training state-of-the-art embedding and reranker models. It can be used to compute embeddings using Sentence Transformer models (quickstart), to calculate similarity scores using Cross-Encoder (a.k.a. reranker) models (quickstart), to generate sparse embeddings using Sparse Encoder models (quickstart) or to compute token-level embeddings for ColBERT-style late-interaction retrieval using Multi-Vector Encoder models (quickstart). This unlocks a wide range of applications, including semantic search, semantic textual similarity, and paraphrase mining.
A wide selection of over 15,000 pre-trained Sentence Transformers models are available for immediate use on 🤗 Hugging Face, including many of the state-of-the-art models from the Massive Text Embeddings Benchmark (MTEB) leaderboard. Additionally, it is easy to train or finetune your own embedding models, reranker models, sparse encoder models or multi-vector encoder models using Sentence Transformers, enabling you to create custom models for your specific use cases.
For the full documentation, see www.SBERT.net.
Installation
We recommend Python 3.10+, PyTorch 2.2+, and transformers v5.0+.
pip install -U sentence-transformersSee Installation in the docs for uv, conda, source, and editable installs, CUDA setup, and extras ([image], [audio], [video], [train], [onnx], [openvino], [dev]).
Getting Started
See Quickstart in our documentation.
Embedding Models
First download a pretrained embedding a.k.a. Sentence Transformer model.
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("sentence-transformers/all-MiniLM-L6-v2")
Then provide some texts to the model.
sentences = [
    "The weather is lovely today.",
    "It's so sunny outside!",
    "He drove to the stadium.",
]
embeddings = model.encode(sentences)
print(embeddings.shape)
# => (3, 384)
And that's already it. We now have numpy arrays with the embeddings, one for each text. We can use these to compute similarities.
similarities = model.similarity(embeddings, embeddings)
print(similarities)
# tensor([[1.0000, 0.6660, 0.1046],
#         [0.6660, 1.0000, 0.1411],
#         [0.1046, 0.1411, 1.0000]])
Reranker Models
First download a pretrained reranker a.k.a. Cross Encoder model.
from sentence_transformers import CrossEncoder

# 1. Load a pretrained CrossEncoder model
model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2")
Then provide some texts to the model.
# The texts for which to predict similarity scores
query = "How many people live in Berlin?"
passages = [
    "Berlin had a population of 3,520,031 registered inhabitants in an area of 891.82 square kilometers.",
    "Berlin has a yearly total of about 135 million day visitors, making it one of the most-visited cities in the European Union.",
    "In 2013 around 600,000 Berliners were registered in one of the more than 2,300 sport and fitness clubs.",
]

# 2a. predict scores for pairs of texts
scores = model.predict([(query, passage) for passage in passages])
print(scores)
# => [8.607139 5.506266 6.352977]
And we're good to go. You can also use model.rank to avoid having to perform the reranking manually:
# 2b. Rank a list of passages for a query
ranks = model.rank(query, passages, return_documents=True)

print("Query:", query)
for rank in ranks:
    print(f"- #{rank['corpus_id']} ({rank['score']:.2f}): {rank['text']}")
"""
Query: How many people live in Berlin?
- #0 (8.61): Berlin had a population of 3,520,031 registered inhabitants in an area of 891.82 square kilometers.
- #2 (6.35): In 2013 around 600,000 Berliners were registered in one of the more than 2,300 sport and fitness clubs.
- #1 (5.51): Berlin has a yearly total of about 135 million day visitors, making it one of the most-visited cities in the European Union.
"""
Sparse Encoder Models
First download a pretrained sparse embedding a.k.a. Sparse Encoder model.
from sentence_transformers import SparseEncoder

# 1. Load a pretrained SparseEncoder model
model = SparseEncoder("naver/splade-cocondenser-ensembledistil")

# The sentences to encode
sentences = [
    "The weather is lovely today.",
    "It's so sunny outside!",
    "He drove to the stadium.",
]

# 2. Calculate sparse embeddings by calling model.encode()
embeddings = model.encode(sentences)
print(embeddings.shape)
# [3, 30522] - sparse representation with vocabulary size dimensions

# 3. Calculate the embedding similarities
similarities = model.similarity(embeddings, embeddings)
print(similarities)
# tensor([[   35.629,     9.154,     0.098],
#         [    9.154,    27.478,     0.019],
#         [    0.098,     0.019,    29.553]])

# 4. Check sparsity stats
stats = SparseEncoder.sparsity(embeddings)
print(f"Sparsity: {stats['sparsity_ratio']:.2%}")
# Sparsity: 99.84%
Multi-Vector Encoder Models
First download a pretrained multi-vector a.k.a. late-interaction (ColBERT-style) model.
from sentence_transformers import MultiVectorEncoder

# 1. Load a pretrained MultiVectorEncoder model
model = MultiVectorEncoder("lightonai/GTE-ModernColBERT-v1")

queries = ["What is the capital of France?"]
documents = [
    "Paris is the capital of France.",
    "Berlin is the capital of Germany.",
]

# 2. Encode queries and documents into sequences of token-level embeddings
query_embeddings = model.encode_query(queries)
document_embeddings = model.encode_document(documents)
print(query_embeddings[0].shape, document_embeddings[0].shape)
# (10, 128) (9, 128)  # one 128-dimensional vector per token

# 3. Score them with late interaction (MaxSim)
scores = model.similarity(query_embeddings, document_embeddings)
print(scores)
# tensor([[9.6037, 9.4055]])
Pre-Trained Models
We provide a large list of pretrained models for more than 100 languages. Some models are general purpose models, while others produce embeddings for specific use cases.
- Pretrained Sentence Transformer (Embedding) Models
- Pretrained Cross Encoder (Reranker) Models
- Pretrained Sparse Encoder (Sparse Embeddings) Models
- Pretrained Multi-Vector Encoder (Late Interaction) Models
Training
Tip: Using an AI coding agent (Claude Code, Codex, Cursor, Gemini CLI, ...)? Install the
train-sentence-transformersHugging Face Agent Skill viahf skills add train-sentence-transformers [--claude] [--global]and ask your agent to fine-tune a model on your data.
This framework allows you to fine-tune your own sentence embedding methods, so that you get task-specific sentence embeddings. You have various options to choose from in order to get perfect sentence embeddings for your specific task.
- Embedding Models
- Reranker Models
- Sparse Embedding Models
- Multi-Vector (Late Interaction) Models
Some highlights across the different types of training are:
- Support of various transformer networks including BERT, RoBERTa, XLM-R, DistilBERT, Electra, BART, ...
- Multilingual and multi-task learning
- Evaluation during training to find optimal model
- 20+ loss functions for embedding models, 10+ loss functions for reranker models and 10+ loss functions for sparse embedding models, allowing you to tune models specifically for semantic search, paraphrase mining, semantic similarity comparison, clustering, triplet loss, contrastive loss, etc.
Companion Blog Posts
The following Hugging Face blog posts complement this documentation with narrative walkthroughs and full training examples:
Training guides:
- Training and Finetuning Embedding Models: end-to-end training of bi-encoder embedding models.
- Training and Finetuning Reranker Models: training Cross Encoder models for the second stage of retrieve-and-rerank pipelines.
- Training and Finetuning Sparse Embedding Models: training SPLADE and other sparse encoders.
Multimodal:
- Multimodal Embedding & Reranker Models: using text, image, audio, and video models through a single API.
- Training and Finetuning Multimodal Embedding & Reranker Models: training multimodal models, with a Visual Document Retrieval walkthrough.
Efficiency techniques:
- Introduction to Matryoshka Embedding Models: variable-size embeddings that can be truncated with minimal quality loss.
- Train 400x faster Static Embedding Models: CPU-friendly embedding models without attention.
- Binary and Scalar Embedding Quantization for Significantly Faster & Cheaper Retrieval: post-training compression of embedding vectors.
Application Examples
You can use this framework for:
Computing Sentence Embeddings
Semantic Textual Similarity
Semantic Search
Retrieve & Re-Rank
and many more use-cases.
For all examples, see examples/sentence_transformer/applications.
Development setup
After cloning the repo (or a fork) to your machine, in a virtual environment, run:
python -m pip install -e ".[dev]"

pre-commit install
To test your changes, run:
pytestCiting & Authors
If you find this repository helpful, feel free to cite our publication Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks:
@inproceedings{reimers-2019-sentence-bert,
    title = "Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks",
    author = "Reimers, Nils and Gurevych, Iryna",
    booktitle = "Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing",
    month = "11",
    year = "2019",
    publisher = "Association for Computational Linguistics",
    url = "https://arxiv.org/abs/1908.10084",
}
If you use one of the multilingual models, feel free to cite our publication Making Monolingual Sentence Embeddings Multilingual using Knowledge Distillation:
@inproceedings{reimers-2020-multilingual-sentence-bert,
    title = "Making Monolingual Sentence Embeddings Multilingual using Knowledge Distillation",
    author = "Reimers, Nils and Gurevych, Iryna",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing",
    month = "11",
    year = "2020",
    publisher = "Association for Computational Linguistics",
    url = "https://arxiv.org/abs/2004.09813",
}
Please have a look at Publications for our different publications that are integrated into SentenceTransformers.
Maintainers
Maintainer: Tom Aarsen, 🤗 Hugging Face
Don't hesitate to open an issue if something is broken (and it shouldn't be) or if you have further questions.
This project was originally developed by the Ubiquitous Knowledge Processing (UKP) Lab at TU Darmstadt. We're grateful for their foundational work and continued contributions to the field.
This repository contains experimental software and is published for the sole purpose of giving additional background details on the respective publication.
File: docs/cross_encoder/training/examples.rst
Training Examples
.. toctree::
:maxdepth: 1
:caption: Supervised Learning
../../../examples/cross_encoder/training/sts/README
../../../examples/cross_encoder/training/nli/README
../../../examples/cross_encoder/training/quora_duplicate_questions/README
../../../examples/cross_encoder/training/ms_marco/README
../../../examples/cross_encoder/training/rerankers/README
../../../examples/cross_encoder/training/distillation/README
../../../examples/cross_encoder/training/multimodal/README
.. toctree::
:maxdepth: 1
:caption: Advanced Usage
../../sentence_transformer/training/distributed
File: docs/cross_encoder/usage/backend_export_sidebar.rst
.. sidebar:: Export, Optimize, and Quantize Hugging Face models
This Hugging Face Space provides a user interface for exporting, optimizing, and quantizing models for either ONNX or OpenVINO:
sentence-transformers/backend-export <https://huggingface.co/spaces/sentence-transformers/backend-export>_
File: docs/cross_encoder/usage/custom_models.rst
Creating Custom Models
Modular Architecture
Every CrossEncoder is composed of sequential modules, just like a
:class:~sentence_transformers.sentence_transformer.model.SentenceTransformer. The :class:~sentence_transformers.cross_encoder.model.CrossEncoder class
is a subclass of :class:~sentence_transformers.base.model.BaseModel, which inherits from :class:torch.nn.Sequential.
You can inspect the module chain by printing the model:
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("Qwen/Qwen3-Reranker-0.6B")
print(model)
"""
CrossEncoder(
(0): Transformer({'transformer_task': 'text-generation', 'modality_config': {'text': {'method': 'forward', 'method_output_name': 'logits'}, 'message': {'method': 'forward', 'method_output_name': 'logits', 'format': 'flat'}}, 'module_output_name': 'causal_logits', 'architecture': 'Qwen3ForCausalLM'})
(1): LogitScore({'true_token_id': 9693, 'false_token_id': 2152, 'module_input_name': 'causal_logits'})
)
"""
Module Chains
^^^^^^^^^^^^^
There are several standard module chain patterns for :class:~sentence_transformers.cross_encoder.model.CrossEncoder models:
Encoder-based (Sequence Classification)
For traditional encoder-based CrossEncoders (e.g. BERT, RoBERTa), a single module is used:
- :class:
~sentence_transformers.base.modules.Transformerwithtransformer_task="sequence-classification": Loads the model via :class:~transformers.AutoModelForSequenceClassificationand returns the classification scores directly.
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2")
print(model)
"""
CrossEncoder(
(0): Transformer({'transformer_task': 'sequence-classification', 'modality_config': {'text': {'method': 'forward', 'method_output_name': 'logits'}}, 'module_output_name': 'scores', 'architecture': 'BertForSequenceClassification'})
)
"""
CausalLM-based (Text Generation + LogitScore)
For generative rerankers (e.g. Qwen, Llama), the modules are generally:
- :class:
~sentence_transformers.base.modules.Transformerwithtransformer_task="text-generation": Loads the model via :class:~transformers.AutoModelForCausalLMand returns the raw logits from the language model head. - :class:
~sentence_transformers.cross_encoder.modules.LogitScore: Extracts the logits at the last token position and computes a score. If bothtrue_token_idandfalse_token_idare set, the score is the log-odds:logit[true] - logit[false]. If onlytrue_token_idis set, the score is simply the logit for that token.
This is determined automatically in :meth:CrossEncoder._load_default_modules() <sentence_transformers.cross_encoder.model.CrossEncoder._load_default_modules>:
when the model architecture ends with ForCausalLM, the :class:~sentence_transformers.base.modules.Transformer is loaded with transformer_task="text-generation"
and a :class:~sentence_transformers.cross_encoder.modules.LogitScore module is appended with true_token_id andfalse_token_id based on the "yes" and "no" tokens, respectively. Otherwise, the
:class:~sentence_transformers.base.modules.Transformer is loaded with transformer_task="sequence-classification" (the traditional encoder-based approach).
Feature Extraction + Pooling + Dense
A more memory-efficient alternative to the Text Generation + LogitScore approach is to use feature extraction without the LM head:
- :class:
~sentence_transformers.base.modules.Transformerwithtransformer_task="feature-extraction": Loads only the base model via :class:~transformers.AutoModel(no LM head), outputting hidden states. - :class:
~sentence_transformers.sentence_transformer.modules.Poolingwithpooling_mode="lasttoken": Extracts the hidden state of the last token. - :class:
~sentence_transformers.base.modules.Dense: Projects the hidden state to a single score.
.. code-block:: python
from sentence_transformers import CrossEncoder
from sentence_transformers.cross_encoder.modules import Transformer, Dense
from sentence_transformers.sentence_transformer.modules import Pooling
transformer = Transformer("Qwen/Qwen3.5-0.8B", transformer_task="feature-extraction")
pooling = Pooling(transformer.get_embedding_dimension(), pooling_mode="lasttoken")
Initialize Dense weights to approximate LogitScore: weight = embed("1") - embed("0")
true_id = transformer.tokenizer.convert_tokens_to_ids("1")
false_id = transformer.tokenizer.convert_tokens_to_ids("0")
embeddings = transformer.model.get_input_embeddings().weight.data
init_weight = (embeddings[true_id] - embeddings[false_id]).unsqueeze(0)
dense = Dense(
in_features=transformer.get_embedding_dimension(),
out_features=1,
bias=False,
activation_function=None,
init_weight=init_weight,
module_output_name="scores",
)
model = CrossEncoder(modules=[transformer, pooling, dense])
Because most causal language models (LM) tie input embeddings with the LM head weights, initializing the Dense weight as embed("1") - embed("0") gives a starting point equivalent to computing log-odds over the "1" and "0" tokens. This approach skips the expensive LM head computation over the full vocabulary.
.. tip::
See the multimodal training examples <https://github.com/UKPLab/sentence-transformers/tree/master/examples/cross_encoder/training/multimodal>_ for a complete comparison of the Text Generation + LogitScore and Feature Extraction + Pooling + Dense approaches.
Constructing Custom Module Chains
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
You can manually construct a :class:~sentence_transformers.cross_encoder.model.CrossEncoder with custom modules. For example, to use "1" and "0" as the true/false tokens instead of the default "yes" and "no":
.. code-block:: python
from sentence_transformers import CrossEncoder
from sentence_transformers.cross_encoder.modules import Transformer, LogitScore
transformer = Transformer("Qwen/Qwen3-Reranker-0.6B", transformer_task="text-generation")
Look up the token IDs for "1" and "0" in the tokenizer
true_id = transformer.tokenizer.convert_tokens_to_ids("1")
false_id = transformer.tokenizer.convert_tokens_to_ids("0")
model = CrossEncoder(
modules=[transformer, LogitScore(true_token_id=true_id, false_token_id=false_id)]
)
Saving CrossEncoder Models
^^^^^^^^^^^^^^^^^^^^^^^^^^
Whenever a CrossEncoder model is saved via :meth:CrossEncoder.save_pretrained <sentence_transformers.cross_encoder.model.CrossEncoder.save_pretrained>, three types of files are generated:
modules.json: A list of module names, paths, and types used to reconstruct the model.config_sentence_transformers.json: Configuration options including the model type, saved prompts, the default prompt name, and the activation function.- Module-specific files: Each module is saved in a separate subfolder named after the module index and class name (e.g.,
1_LogitScore), except the first module which may be saved in the root directory if it hassave_in_root = True(this is the case for the :class:~sentence_transformers.base.modules.Transformermodule).
For example, saving a CausalLM-based :class:~sentence_transformers.cross_encoder.model.CrossEncoder produces the following directory structure:
.. code-block:: bash
my-cross-encoder/
├── 1_LogitScore
│ └── config.json
├── README.md
├── chat_template.jinja
├── config.json
├── config_sentence_transformers.json
├── generation_config.json
├── model.safetensors
├── modules.json
├── sentence_bert_config.json
├── tokenizer.json
└── tokenizer_config.json
The modules.json contains metadata about each module:
.. code-block:: json
[
{
"idx": 0,
"name": "0",
"path": "",
"type": "sentence_transformers.base.modules.transformer.Transformer"
},
{
"idx": 1,
"name": "1",
"path": "1_LogitScore",
"type": "sentence_transformers.cross_encoder.modules.logit_score.LogitScore"
}
]
The config_sentence_transformers.json contains model-level configuration:
.. code-block:: json
{
"version": {
"sentence_transformers": "5.4.0",
"transformers": "5.5.0",
"pytorch": "2.10.0"
},
"activation_fn": "torch.nn.modules.linear.Identity",
"default_prompt_name": "query",
"model_type": "CrossEncoder",
"prompts": {
"query": "Given a web search query, retrieve relevant passages that answer the query"
}
}
And the 1_LogitScore/config.json stores the LogitScore module's configuration:
.. code-block:: json
{
"true_token_id": 9693,
"false_token_id": 2152,
"module_input_name": "causal_logits"
}
The sentence_bert_config.json stores the :class:~sentence_transformers.base.modules.Transformer module's configuration:
.. code-block:: json
{
"transformer_task": "text-generation",
"modality_config": {
"text": {
"method": "forward",
"method_output_name": "logits"
},
"message": {
"method": "forward",
"method_output_name": "logits",
"format": "flat"
}
},
"module_output_name": "causal_logits"
}
The "format" key in the "message" modality controls how chat-template inputs are structured:
"structured": Content is a list of typed dicts, e.g.[{"type": "text", "text": "hello"}]."flat": Content is the direct value, e.g."hello".
This is inferred automatically from the model's chat template. Most vision-language models use structured format, while text-only causal LMs typically use flat format.
Loading CrossEncoder Models
^^^^^^^^^^^^^^^^^^^^^^^^^^^
To load a :class:~sentence_transformers.cross_encoder.model.CrossEncoder model, modules.json is read to determine the modules that make up the model. Each module class is resolved from its type field, and the module is initialized from the configuration stored in the corresponding module directory. For example, the :class:~sentence_transformers.cross_encoder.modules.LogitScore module is loaded by reading 1_LogitScore/config.json and passing the values as keyword arguments to LogitScore(...).
If no modules.json is found (e.g., loading a pure transformers model), the :meth:~sentence_transformers.cross_encoder.model.CrossEncoder._load_default_modules method automatically determines the module chain based on the model architecture: ForCausalLM models get [Transformer, LogitScore], while all other models get [Transformer] with transformer_task="sequence-classification".
Like Sentence Transformer models, CrossEncoder models can declare which dependency versions they need to load correctly, see Declaring Version Requirements <../../sentence_transformer/usage/custom_models.html#declaring-version-requirements>_.
Multimodal CrossEncoder Models
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
The :class:~sentence_transformers.base.modules.Transformer module handles multimodal inputs natively. It automatically detects the supported modalities of the underlying model (text, image, audio, video) via modality_config and routes inputs to the correct processing method. You can build a multimodal :class:~sentence_transformers.cross_encoder.model.CrossEncoder by using a multimodal backbone:
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("Qwen/Qwen3-VL-Reranker-2B")
print(model)
"""
CrossEncoder(
(0): Transformer({'transformer_task': 'any-to-any', 'modality_config': {'text': ..., 'image': ..., 'video': ..., 'message': {..., 'format': 'structured'}}, 'module_output_name': 'causal_logits', 'processing_kwargs': {...}, 'unpad_inputs': False, 'architecture': 'Qwen3VLForConditionalGeneration'})
(1): LogitScore({'true_token_id': 9693, 'false_token_id': 2152, 'module_input_name': 'causal_logits'})
)
"""
Score text-only and image-text pairs
scores = model.predict([
("A bee on a pink flower", "This image shows a bee on a pink flower"),
("A bee on a pink flower", "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"),
])
When building a multimodal :class:~sentence_transformers.cross_encoder.model.CrossEncoder from scratch (e.g. from a base multimodal model), use transformer_task="any-to-any" to load the full causal LM with its language model head:
.. code-block:: python
from sentence_transformers import CrossEncoder
from sentence_transformers.cross_encoder.modules import Transformer, LogitScore
transformer = Transformer("Qwen/Qwen3.5-0.8B", transformer_task="any-to-any")
score_head = LogitScore(
true_token_id=transformer.tokenizer.convert_tokens_to_ids("1"),
false_token_id=transformer.tokenizer.convert_tokens_to_ids("0"),
)
model = CrossEncoder(
modules=[transformer, score_head],
prompts={
"image_to_text": "Given the image, judge whether the text matches it. Respond with 1 if they match, 0 if they don't.",
"text_to_image": "Given the text, judge whether the image matches it. Respond with 1 if they match, 0 if they don't.",
},
)
Advanced: Custom Modules
All modules available for building a :class:~sentence_transformers.cross_encoder.model.CrossEncoder can be imported from :mod:sentence_transformers.cross_encoder.modules:
- :class:
~sentence_transformers.base.modules.Transformer: The primary input module for loading Transformers models. - :class:
~sentence_transformers.cross_encoder.modules.LogitScore: Converts causal LM logits into relevance scores. - :class:
~sentence_transformers.base.modules.Dense: A feed-forward layer for dimensionality reduction or score projection. - :class:
~sentence_transformers.base.modules.Router: Routes inputs through different module chains based on task or modality. - :class:
~sentence_transformers.base.modules.Module: Base class for creating custom non-input modules. - :class:
~sentence_transformers.base.modules.InputModule: Base class for creating custom input modules.
Input Modules
^^^^^^^^^^^^^
The first module in a pipeline is called the input module. It is responsible for preprocessing the inputs and generating the input features for the subsequent modules. The input module can be any module that implements the :class:~sentence_transformers.base.modules.InputModule class, which is a subclass of the :class:~sentence_transformers.base.modules.Module class.
It has two abstract methods that you need to implement, and one method that you should override:
A :meth:
~sentence_transformers.base.modules.Module.forwardmethod that accepts afeaturesdictionary and returns an updatedfeaturesdictionary.A :meth:
~sentence_transformers.base.modules.Module.savemethod that saves the module's configuration and optionally weights to a provided directory.A :meth:
~sentence_transformers.base.modules.InputModule.preprocessmethod that accepts a list of inputs and an optionalpromptstring, and returns afeaturesdictionary that will be passed to the module's ownforwardmethod. The keys should match whatforwardexpects (e.g.input_ids,attention_mask,pixel_values, etc.). The base :class:~sentence_transformers.base.modules.InputModuleclass provides a default implementation that delegates totokenize(), but you should override it. Its full signature is:.. code-block:: python
def preprocess(
self,
inputs: list[SingleInput | PairInput],
prompt: str | None = None,
**kwargs,
) -> dict[str, torch.Tensor | Any]:
...For :class:
~sentence_transformers.cross_encoder.model.CrossEncodermodels, theinputsparameter contains pairs of inputs. Each element in a pair can be a text string, a PIL image, a numpy/torch array for audio or video, a multimodal dictionary with modality keys (e.g.{"text": ..., "image": ...}), or a chat-style message list.
Optionally, you can also implement or override the following:
- A :attr:
~sentence_transformers.base.modules.InputModule.modalitiesproperty that returns the list of modalities supported by the module. Defaults to["text"]. Each entry can be a single modality string (e.g."text") or a tuple for compound modalities (e.g.("image", "text")). Tuples should be sorted alphabetically. :meth:BaseModel.preprocess <sentence_transformers.base.model.BaseModel.preprocess>validates input modalities against this list before calling the module'spreprocess(), so you don't need to handle unsupported modalities yourself. - A :meth:
~sentence_transformers.base.modules.Module.loadclass method that loads the module from a saved directory or Hugging Face model. - A
max_seq_lengthproperty that returns the maximum sequence length the module can process.
.. note::
The tokenize() method is deprecated in favor of preprocess(). If you are writing a new custom input module, implement preprocess() instead.
Subsequent Modules
^^^^^^^^^^^^^^^^^^
Subsequent modules in the pipeline are called non-input modules. They process the features dictionary produced by the input module and either transform it or extract final scores. Non-input modules can be any module that implements the :class:~sentence_transformers.base.modules.Module class.
It has two abstract methods that you need to implement:
- A :meth:
~sentence_transformers.base.modules.Module.forwardmethod that accepts afeaturesdictionary and returns an updatedfeaturesdictionary. For :class:~sentence_transformers.cross_encoder.model.CrossEncodermodels, the final module should set the"scores"key. - A :meth:
~sentence_transformers.base.modules.Module.savemethod that saves the module's configuration and optionally weights to a provided directory.
Optionally, you can also implement:
- A :meth:
~sentence_transformers.base.modules.Module.loadclass method that loads the module from a saved directory or Hugging Face model.
Example Custom Module
^^^^^^^^^^^^^^^^^^^^^
For example, we can create a custom scoring module that applies temperature scaling to the logits before computing the log-odds score:
.. code-block:: python
temperature_logit_score.py
import torch
from sentence_transformers.cross_encoder.modules import Module
class TemperatureLogitScore(Module):
config_keys: list[str] = ["true_token_id", "false_token_id", "temperature", "module_input_name"]
def __init__(
       self,
       true_token_id: int,
       false_token_id: int | None = None,
       temperature: float = 1.0,
       module_input_name: str = "causal_logits",
       **kwargs,
   ) -> None:
       super().__init__()
       self.true_token_id = true_token_id
       self.false_token_id = false_token_id
       self.temperature = temperature
       self.module_input_name = module_input_name

   def forward(self, features: dict[str, torch.Tensor], **kwargs) -> dict[str, torch.Tensor]:
       logits = features[self.module_input_name][:, -1]
       # Apply temperature scaling
       logits = logits / self.temperature

       if self.false_token_id is None:
           scores = logits[:, self.true_token_id]
       else:
           scores = logits[:, self.true_token_id] - logits[:, self.false_token_id]

       features["scores"] = scores.unsqueeze(1)
       return features

   def save(self, output_path: str, *args, safe_serialization: bool = True, **kwargs) -> None:
       self.save_config(output_path)

   # The default `load` method reads `config.json` and passes the values
   # (i.e. the `config_keys`) as kwargs to __init__. This works for us,
   # so no need to override it.
Key points about this example:
config_keys: Lists the instance attributes that should be saved inconfig.json. These are automatically extracted by :meth:~sentence_transformers.base.modules.Module.get_config_dictand used by the default :meth:~sentence_transformers.base.modules.Module.loadmethod to reconstruct the module.forward: Reads from thefeaturesdictionary and writes the"scores"key, which is what :meth:~sentence_transformers.cross_encoder.model.CrossEncoder.predictexpects from the final module.save: Calls :meth:~sentence_transformers.base.modules.Module.save_configto write the config. Since this module has no trainable weights, there is nothing else to save. A module with trainable parameters should also call :meth:~sentence_transformers.base.modules.Module.save_torch_weights.
This can now be used as a module in a :class:~sentence_transformers.cross_encoder.model.CrossEncoder:
.. code-block:: python
from sentence_transformers import CrossEncoder
from sentence_transformers.cross_encoder.modules import Transformer
from temperature_logit_score import TemperatureLogitScore
transformer = Transformer("Qwen/Qwen3-Reranker-0.6B", transformer_task="text-generation")
score_head = TemperatureLogitScore(
true_token_id=transformer.tokenizer.convert_tokens_to_ids("yes"),
false_token_id=transformer.tokenizer.convert_tokens_to_ids("no"),
temperature=2.0,
)
model = CrossEncoder(modules=[transformer, score_head])
print(model)
"""
CrossEncoder(
(0): Transformer({'transformer_task': 'text-generation', ...})
(1): TemperatureLogitScore({'true_token_id': 9693, 'false_token_id': 2152, 'temperature': 2.0, 'module_input_name': 'causal_logits'})
)
"""
scores = model.predict([("How many people live in Berlin?", "Berlin has a population of 3,520,031.")])
You can save this model with :meth:CrossEncoder.save_pretrained <sentence_transformers.cross_encoder.model.CrossEncoder.save_pretrained>, resulting in a modules.json of:
.. code-block:: json
[
{
"idx": 0,
"name": "0",
"path": "",
"type": "sentence_transformers.base.modules.transformer.Transformer"
},
{
"idx": 1,
"name": "1",
"path": "1_TemperatureLogitScore",
"type": "temperature_logit_score.TemperatureLogitScore"
}
]
To ensure that temperature_logit_score.TemperatureLogitScore can be imported, you should copy the temperature_logit_score.py file to the directory where you saved the model. If you push the model to the Hugging Face Hub <https://huggingface.co/models>_, then you should also upload the temperature_logit_score.py file to the model's repository. Then, everyone can use your custom module by calling :meth:CrossEncoder("your-username/your-model-id", trust_remote_code=True) <sentence_transformers.cross_encoder.model.CrossEncoder>.
.. note::
Using a custom module requires that your users specify trust_remote_code as True when loading the model, whether it is loaded from the Hugging Face Hub or from a local path. This is a security measure to prevent remote code execution attacks.
.. note::
Adding **kwargs to the __init__, forward, save, load, and preprocess methods is recommended to ensure that the methods remain compatible with future updates to the Sentence Transformers library.
If you have your models and custom modelling code on the Hugging Face Hub, then it might make sense to separate your custom modules into a separate repository. This way, you only have to maintain one implementation of your custom module, and you can reuse it across multiple models. You can do this by updating the type in modules.json to include the path to the repository where the custom module is stored like {repository_id}--{dot_path_to_module}. For example, if the temperature_logit_score.py file is stored in a repository called my-user/my-model-implementation, then the modules.json file may look like this:
.. code-block:: json
[
{
"idx": 0,
"name": "0",
"path": "",
"type": "sentence_transformers.base.modules.transformer.Transformer"
},
{
"idx": 1,
"name": "1",
"path": "1_TemperatureLogitScore",
"type": "my-user/my-model-implementation--temperature_logit_score.TemperatureLogitScore"
}
]
Advanced: Keyword Argument Passthrough in Custom Modules
^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
If you want your users to be able to specify custom keyword arguments via the :meth:CrossEncoder.predict <sentence_transformers.cross_encoder.model.CrossEncoder.predict> method, then you can add their names to the modules.json file. For example, if your module should behave differently based on a task keyword argument, then your modules.json might look like:
.. code-block:: json
[
{
"idx": 0,
"name": "0",
"path": "",
"type": "custom_transformer.CustomTransformer",
"kwargs": ["task"]
},
{
"idx": 1,
"name": "1",
"path": "1_LogitScore",
"type": "sentence_transformers.cross_encoder.modules.logit_score.LogitScore"
}
]
Then, you can access the task keyword argument in the forward method of your custom module:
.. code-block:: python
from sentence_transformers.cross_encoder.modules import Transformer
class CustomTransformer(Transformer):
def forward(self, features: dict[str, torch.Tensor], task: str | None = None, **kwargs) -> dict[str, torch.Tensor]:
if task == "default":
# Do something
...
else:
# Do something else
...
return features
This way, users can specify the task keyword argument when calling :meth:CrossEncoder.predict <sentence_transformers.cross_encoder.model.CrossEncoder.predict>:
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("your-username/your-model-id", trust_remote_code=True)
pairs = [("query", "document")]
model.predict(pairs, task="default")
File: docs/cross_encoder/usage/efficiency.rst
Speeding up Inference
Sentence Transformers supports 3 backends for performing inference with Cross Encoder models, each with its own optimizations for speeding up inference:
.. raw:: html
<a href="#pytorch" class="box">
        PyTorch
        The default backend for Cross Encoders.
    </a>
    <a href="#onnx" class="box">
        ONNX
        Flexible and efficient model accelerator.
    </a>
    <a href="#openvino" class="box">
        OpenVINO
        Optimization of models, mainly for Intel Hardware.
    </a>
    <a href="#benchmarks" class="box">
        Benchmarks
        Benchmarks for the different backends.
    </a>
    <a href="#user-interface" class="box">
        User Interface
        GUI to export, optimize, and quantize models.
    </a>
PyTorch
The PyTorch backend is the default backend for Cross Encoders. If you don't specify a device, it will use the strongest available option across "cuda", "mps", and "cpu". Its default usage looks like this:
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2")
query = "Which planet is known as the Red Planet?"
passages = [
"Venus is often called Earth's twin because of its similar size and proximity.",
"Mars, known for its reddish appearance, is often referred to as the Red Planet.",
"Jupiter, the largest planet in our solar system, has a prominent red spot.",
"Saturn, famous for its rings, is sometimes mistaken for the Red Planet."
]
scores = model.predict([(query, passage) for passage in passages])
print(scores)
If you're using a GPU, then you can use the following options to speed up your inference:
.. tab:: float16 (fp16)
Float32 (fp32, full precision) is the default floating-point format in torch, whereas float16 (fp16, half precision) is a reduced-precision floating-point format that can speed up inference on GPUs at a minimal loss of model accuracy. To use it, you can specify the torch_dtype during initialization or call :meth:model.half() <torch.Tensor.half> on the initialized model:
.. code-block:: python
from sentence_transformers import CrossEncoder

  model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", model_kwargs={"torch_dtype": "float16"})
  # or: model.half()

  query = "Which planet is known as the Red Planet?"
  passages = [
     "Venus is often called Earth's twin because of its similar size and proximity.",
     "Mars, known for its reddish appearance, is often referred to as the Red Planet.",
     "Jupiter, the largest planet in our solar system, has a prominent red spot.",
     "Saturn, famous for its rings, is sometimes mistaken for the Red Planet."
  ]

  scores = model.predict([(query, passage) for passage in passages])
  print(scores)
.. tab:: bfloat16 (bf16)
Bfloat16 (bf16) is similar to fp16, but preserves more of the original accuracy of fp32. To use it, you can specify the torch_dtype during initialization or call :meth:model.bfloat16() <torch.Tensor.bfloat16> on the initialized model:
.. code-block:: python
from sentence_transformers import CrossEncoder

  model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", model_kwargs={"torch_dtype": "bfloat16"})
  # or: model.bfloat16()

  query = "Which planet is known as the Red Planet?"
  passages = [
     "Venus is often called Earth's twin because of its similar size and proximity.",
     "Mars, known for its reddish appearance, is often referred to as the Red Planet.",
     "Jupiter, the largest planet in our solar system, has a prominent red spot.",
     "Saturn, famous for its rings, is sometimes mistaken for the Red Planet."
  ]

  scores = model.predict([(query, passage) for passage in passages])
  print(scores)
.. tab:: Flash Attention
Flash Attention <https://github.com/Dao-AILab/flash-attention>_ can be enabled by specifying
attn_implementation="flash_attention_2" in model_kwargs (installable via pip install kernels or
pip install flash-attn):
.. code-block:: python
from sentence_transformers import CrossEncoder

  model = CrossEncoder(
      "cross-encoder/ms-marco-MiniLM-L6-v2",
      model_kwargs={"torch_dtype": "float16", "attn_implementation": "flash_attention_2"},
  )
However, we do not currently recommend it for Cross Encoder models: the automatic input unpadding that makes
Flash Attention shine for Sentence Transformer and Multi-Vector Encoder models only applies to the
feature-extraction task, as classification heads are incompatible with flattened inputs. Without unpadding, our
benchmarks measured the bare kernel swap at equal speed to fp16 on long texts and 20 to 45% slower on short
texts, across all four benchmarked rerankers. Prefer plain fp16 by simply dropping attn_implementation.
.. tab:: torch.compile
:meth:model.compile() <sentence_transformers.base.model.BaseModel.compile> wraps the model's forward pass with
:func:torch.compile. Whether it helps depends strongly on the model and hardware: the benefit grows with model
size, and very small models on a fast GPU can see little gain or even a slight slowdown, since their inference is
dominated by tokenization and Python overhead. Always measure on your own model, hardware, and inputs. It composes
with the fp16/bf16 options above.
.. code-block:: python
from sentence_transformers import CrossEncoder

  model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", model_kwargs={"torch_dtype": "bfloat16"})
  model.compile(dynamic=True)

  query = "Which planet is known as the Red Planet?"
  passages = [
     "Venus is often called Earth's twin because of its similar size and proximity.",
     "Mars, known for its reddish appearance, is often referred to as the Red Planet.",
  ]
  pairs = [(query, passage) for passage in passages]
  scores = model.predict(pairs)
dynamic=True enables dynamic shapes so a compiled graph can handle variable sequence lengths, reducing
recompilation when your inputs vary in length. For the largest speedup, use mode="reduce-overhead" instead:
it applies CUDA graphs to remove the per-kernel launch overhead that dominates batch-size-1 inference.
.. code-block:: python
model.compile(mode="reduce-overhead") However, CUDA graphs capture one graph per input shape, so they need stable shapes. Pad every input to a fixed
length near your typical length by passing padding="max_length" through processing_kwargs when predicting:
.. code-block:: python
scores = model.predict(pairs, processing_kwargs={"text": {"padding": "max_length", "max_length": 256}}) max_length sets the fixed length that shorter inputs are padded up to and longer inputs are truncated down to.
It is optional and defaults to the tokenizer's model_max_length.
Padding up to a large model_max_length (for example 8192) makes every call process the full length and is slower
than not compiling at all. CUDA graphs also reuse output buffers, so clone anything you keep across calls (the
default convert_to_numpy=True already copies off the GPU and is safe). Compilation is lazy, so warm the model
up on representative inputs before benchmarking or serving.
ONNX
.. include:: backend_export_sidebar.rst
ONNX can be used to speed up inference by converting the model to ONNX format and using ONNX Runtime to run the model. To use the ONNX backend, you must install Sentence Transformers with the onnx or onnx-gpu extra for CPU or GPU acceleration, respectively:
.. code-block:: bash
pip install sentence-transformers[onnx-gpu]
or
pip install sentence-transformers[onnx]
To convert a model to ONNX format, you can use the following code:
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", backend="onnx")
query = "Which planet is known as the Red Planet?"
passages = [
"Venus is often called Earth's twin because of its similar size and proximity.",
"Mars, known for its reddish appearance, is often referred to as the Red Planet.",
"Jupiter, the largest planet in our solar system, has a prominent red spot.",
"Saturn, famous for its rings, is sometimes mistaken for the Red Planet."
]
scores = model.predict([(query, passage) for passage in passages])
print(scores)
If the model path or repository already contains a model in ONNX format, Sentence Transformers will automatically use it. Otherwise, it will convert the model to the ONNX format.
.. note::
If you wish to use the ONNX model outside of Sentence Transformers, you might need to apply your chosen activation function (e.g. Sigmoid) to get identical results as the Cross Encoder in Sentence Transformers.
All keyword arguments passed via model_kwargs will be passed on to :meth:ORTModelForSequenceClassification.from_pretrained <optimum.onnxruntime.ORTModel.from_pretrained>. Some notable arguments include:
provider: ONNX Runtime provider to use for loading the model, e.g."CPUExecutionProvider". See https://onnxruntime.ai/docs/execution-providers/ for possible providers. If not specified, the strongest provider (E.g."CUDAExecutionProvider") will be used.file_name: The name of the ONNX file to load. If not specified, will default to"model.onnx"or otherwise"onnx/model.onnx". This argument is useful for specifying optimized or quantized models.export: A boolean flag specifying whether the model will be exported. If not provided,exportwill be set toTrueif the model repository or directory does not already contain an ONNX model.
.. tip::
It's heavily recommended to save the exported model to prevent having to re-export it every time you run your code. You can do this by calling :meth:model.save_pretrained() <sentence_transformers.cross_encoder.model.CrossEncoder.save_pretrained> if your model was local:
.. code-block:: python
model = CrossEncoder("path/to/my/model", backend="onnx")
  model.save_pretrained("path/to/my/model")
or with :meth:model.push_to_hub() <sentence_transformers.cross_encoder.model.CrossEncoder.push_to_hub> if your model was from the Hugging Face Hub:
.. code-block:: python
model = CrossEncoder("Alibaba-NLP/gte-reranker-modernbert-base", backend="onnx")
  model.push_to_hub("Alibaba-NLP/gte-reranker-modernbert-base", create_pr=True)
Optimizing ONNX Models
^^^^^^^^^^^^^^^^^^^^^^
.. include:: backend_export_sidebar.rst
ONNX models can be optimized using Optimum <https://huggingface.co/docs/optimum/index>_, allowing for speedups on CPUs and GPUs alike. To do this, you can use the :func:~sentence_transformers.backend.export_optimized_onnx_model function, which saves the optimized in a directory or model repository that you specify. It expects:
model: a Sentence Transformer, Sparse Encoder, or Cross Encoder model loaded with the ONNX backend.optimization_config:"O1","O2","O3", or"O4"representing optimization levels from :class:~optimum.onnxruntime.AutoOptimizationConfig, or an :class:~optimum.onnxruntime.OptimizationConfiginstance.model_name_or_path: a path to save the optimized model file, or the repository name if you want to push it to the Hugging Face Hub.push_to_hub: (Optional) a boolean to push the optimized model to the Hugging Face Hub.create_pr: (Optional) a boolean to create a pull request when pushing to the Hugging Face Hub. Useful when you don't have write access to the repository.file_suffix: (Optional) a string to append to the model name when saving it. If not specified, the optimization level name string will be used, or just"optimized"if the optimization config was not just a string optimization level.
See this example for exporting a model with :doc:optimization level 3 <optimum-onnx:onnxruntime/usage_guides/optimization> (basic and extended general optimizations, transformers-specific fusions, fast Gelu approximation):
.. tab:: Hugging Face Hub Model
Only optimize once::
from sentence_transformers import CrossEncoder, export_optimized_onnx_model

  model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", backend="onnx")
  export_optimized_onnx_model(
      model=model,
      optimization_config="O3",
      model_name_or_path="cross-encoder/ms-marco-MiniLM-L6-v2",
      push_to_hub=True,
      create_pr=True,
  )
Before the pull request gets merged::
from sentence_transformers import CrossEncoder

  pull_request_nr = 2 # NOTE: Update this to the number of your pull request
  model = CrossEncoder(
      "cross-encoder/ms-marco-MiniLM-L6-v2",
      backend="onnx",
      model_kwargs={"file_name": "onnx/model_O3.onnx"},
      revision=f"refs/pr/{pull_request_nr}"
  )
Once the pull request gets merged::
from sentence_transformers import CrossEncoder

  model = CrossEncoder(
      "cross-encoder/ms-marco-MiniLM-L6-v2",
      backend="onnx",
      model_kwargs={"file_name": "onnx/model_O3.onnx"},
  )
.. tab:: Local Model
Only optimize once::
from sentence_transformers import CrossEncoder, export_optimized_onnx_model

  model = CrossEncoder("path/to/my/mpnet-legal-finetuned", backend="onnx")
  export_optimized_onnx_model(
      model=model, optimization_config="O3", model_name_or_path="path/to/my/mpnet-legal-finetuned"
  )
After optimizing::
from sentence_transformers import CrossEncoder

  model = CrossEncoder(
      "path/to/my/mpnet-legal-finetuned",
      backend="onnx",
      model_kwargs={"file_name": "onnx/model_O3.onnx"},
  )
Quantizing ONNX Models
^^^^^^^^^^^^^^^^^^^^^^
.. include:: backend_export_sidebar.rst
ONNX models can be quantized to int8 precision using Optimum <https://huggingface.co/docs/optimum/index>_, allowing for faster inference on CPUs. To do this, you can use the :func:~sentence_transformers.backend.export_dynamic_quantized_onnx_model function, which saves the quantized in a directory or model repository that you specify. Dynamic quantization, unlike static quantization, does not require a calibration dataset. It expects:
model: a Sentence Transformer, Sparse Encoder, or Cross Encoder model loaded with the ONNX backend.quantization_config:"arm64","avx2","avx512", or"avx512_vnni"representing quantization configurations from :class:~optimum.onnxruntime.AutoQuantizationConfig, or an :class:~optimum.onnxruntime.QuantizationConfiginstance.model_name_or_path: a path to save the quantized model file, or the repository name if you want to push it to the Hugging Face Hub.push_to_hub: (Optional) a boolean to push the quantized model to the Hugging Face Hub.create_pr: (Optional) a boolean to create a pull request when pushing to the Hugging Face Hub. Useful when you don't have write access to the repository.file_suffix: (Optional) a string to append to the model name when saving it. If not specified,"qint8_quantized"will be used.
On my CPU, each of the default quantization configurations ("arm64", "avx2", "avx512", "avx512_vnni") resulted in roughly equivalent speedups.
See this example for quantizing a model to int8 with :doc:avx512_vnni <optimum-onnx:onnxruntime/usage_guides/quantization>:
.. tab:: Hugging Face Hub Model
Only quantize once::
from sentence_transformers import CrossEncoder, export_dynamic_quantized_onnx_model

  model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", backend="onnx")
  export_dynamic_quantized_onnx_model(
      model=model,
      quantization_config="avx512_vnni",
      model_name_or_path="sentence-transformers/cross-encoder/ms-marco-MiniLM-L6-v2",
      push_to_hub=True,
      create_pr=True,
  )
Before the pull request gets merged::
from sentence_transformers import CrossEncoder

  pull_request_nr = 2 # NOTE: Update this to the number of your pull request
  model = CrossEncoder(
      "cross-encoder/ms-marco-MiniLM-L6-v2",
      backend="onnx",
      model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
      revision=f"refs/pr/{pull_request_nr}",
  )
Once the pull request gets merged::
from sentence_transformers import CrossEncoder

  model = CrossEncoder(
      "cross-encoder/ms-marco-MiniLM-L6-v2",
      backend="onnx",
      model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
  )
.. tab:: Local Model
Only quantize once::
from sentence_transformers import CrossEncoder, export_dynamic_quantized_onnx_model

  model = CrossEncoder("path/to/my/mpnet-legal-finetuned", backend="onnx")
  export_dynamic_quantized_onnx_model(
      model=model, quantization_config="avx512_vnni", model_name_or_path="path/to/my/mpnet-legal-finetuned"
  )
After quantizing::
from sentence_transformers import CrossEncoder

  model = CrossEncoder(
      "path/to/my/mpnet-legal-finetuned",
      backend="onnx",
      model_kwargs={"file_name": "onnx/model_qint8_avx512_vnni.onnx"},
  )
OpenVINO
.. include:: backend_export_sidebar.rst
OpenVINO allows for accelerated inference on CPUs by exporting the model to the OpenVINO format. To use the OpenVINO backend, you must install Sentence Transformers with the openvino extra:
.. code-block:: bash
pip install sentence-transformers[openvino]
To convert a model to OpenVINO format, you can use the following code:
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", backend="openvino")
query = "Which planet is known as the Red Planet?"
passages = [
"Venus is often called Earth's twin because of its similar size and proximity.",
"Mars, known for its reddish appearance, is often referred to as the Red Planet.",
"Jupiter, the largest planet in our solar system, has a prominent red spot.",
"Saturn, famous for its rings, is sometimes mistaken for the Red Planet."
]
scores = model.predict([(query, passage) for passage in passages])
print(scores)
If the model path or repository already contains a model in OpenVINO format, Sentence Transformers will automatically use it. Otherwise, it will convert the model to the OpenVINO format.
.. note::
If you wish to use the OpenVINO model outside of Sentence Transformers, you might need to apply your chosen activation function (e.g. Sigmoid) to get identical results as the Cross Encoder in Sentence Transformers.
.. raw:: html
All keyword arguments passed via model_kwargs will be passed on to OVBaseModel.from_pretrained(). Some notable arguments include:
file_name: The name of the ONNX file to load. If not specified, will default to"openvino_model.xml"or otherwise"openvino/openvino_model.xml". This argument is useful for specifying optimized or quantized models.export: A boolean flag specifying whether the model will be exported. If not provided,exportwill be set toTrueif the model repository or directory does not already contain an OpenVINO model.
.. tip::
It's heavily recommended to save the exported model to prevent having to re-export it every time you run your code. You can do this by calling :meth:model.save_pretrained() <sentence_transformers.cross_encoder.model.CrossEncoder.save_pretrained> if your model was local:
.. code-block:: python
model = CrossEncoder("path/to/my/model", backend="openvino")
  model.save_pretrained("path/to/my/model")
or with :meth:model.push_to_hub() <sentence_transformers.cross_encoder.model.CrossEncoder.push_to_hub> if your model was from the Hugging Face Hub:
.. code-block:: python
model = CrossEncoder("Alibaba-NLP/gte-reranker-modernbert-base", backend="openvino")
  model.push_to_hub("Alibaba-NLP/gte-reranker-modernbert-base", create_pr=True)
Quantizing OpenVINO Models
^^^^^^^^^^^^^^^^^^^^^^^^^^
.. include:: backend_export_sidebar.rst
OpenVINO models can be quantized to int8 precision using Optimum Intel <https://huggingface.co/docs/optimum/main/en/intel/index>_ to speed up inference.
To do this, you can use the :func:~sentence_transformers.backend.export_static_quantized_openvino_model function,
which saves the quantized model in a directory or model repository that you specify.
Post-Training Static Quantization expects:
model: a Sentence Transformer, Sparse Encoder, or Cross Encoder model loaded with the OpenVINO backend.quantization_config: (Optional) The quantization configuration. This parameter accepts either:Nonefor the default 8-bit quantization, a dictionary representing quantization configurations, or
an :class:~optimum.intel.OVQuantizationConfiginstance.model_name_or_path: a path to save the quantized model file, or the repository name if you want to push it to the Hugging Face Hub.dataset_name: (Optional) The name of the dataset to load for calibration. If not specified, defaults tosst2subset from thegluedataset.dataset_config_name: (Optional) The specific configuration of the dataset to load.dataset_split: (Optional) The split of the dataset to load (e.g., 'train', 'test').column_name: (Optional) The column name in the dataset to use for calibration.push_to_hub: (Optional) a boolean to push the quantized model to the Hugging Face Hub.create_pr: (Optional) a boolean to create a pull request when pushing to the Hugging Face Hub. Useful when you don't have write access to the repository.file_suffix: (Optional) a string to append to the model name when saving it. If not specified,"qint8_quantized"will be used.
See this example for quantizing a model to int8 with static quantization <https://huggingface.co/docs/optimum/main/en/intel/openvino/optimization#static-quantization>_:
.. tab:: Hugging Face Hub Model
Only quantize once::
from sentence_transformers import CrossEncoder, export_static_quantized_openvino_model

  model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", backend="openvino")
  export_static_quantized_openvino_model(
      model=model,
      quantization_config=None,
      model_name_or_path="cross-encoder/ms-marco-MiniLM-L6-v2",
      push_to_hub=True,
      create_pr=True,
  )
Before the pull request gets merged::
from sentence_transformers import CrossEncoder

  pull_request_nr = 2 # NOTE: Update this to the number of your pull request
  model = CrossEncoder(
      "cross-encoder/ms-marco-MiniLM-L6-v2",
      backend="openvino",
      model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
      revision=f"refs/pr/{pull_request_nr}"
  )
Once the pull request gets merged::
from sentence_transformers import CrossEncoder

  model = CrossEncoder(
      "cross-encoder/ms-marco-MiniLM-L6-v2",
      backend="openvino",
      model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
  )
.. tab:: Local Model
Only quantize once::
from sentence_transformers import CrossEncoder, export_static_quantized_openvino_model
  from optimum.intel import OVQuantizationConfig

  model = CrossEncoder("path/to/my/mpnet-legal-finetuned", backend="openvino")
  quantization_config = OVQuantizationConfig()
  export_static_quantized_openvino_model(
      model=model, quantization_config=quantization_config, model_name_or_path="path/to/my/mpnet-legal-finetuned"
  )
After quantizing::
from sentence_transformers import CrossEncoder

  model = CrossEncoder(
      "path/to/my/mpnet-legal-finetuned",
      backend="openvino",
      model_kwargs={"file_name": "openvino/openvino_model_qint8_quantized.xml"},
  )
Benchmarks
The following images show the benchmark results for the different backends on GPUs and CPUs. Each backend runs at its best batch size per model and dataset, and the bars show the median speedup over PyTorch fp32 across those combinations.
.. raw:: html
Expand the benchmark detailsSpeedup ratio:
<li>
     **Batch sizes: **each backend is measured at increasing batch sizes until its throughput declines or memory is exceeded, and the ratios compare peak against peak. Columns still climbing at the largest measured batch size (mainly the Flash Attention ones) are shown conservatively.
  </li>
  <li>
     **Hardware: **RTX 3090 GPU, i7-13700K CPU. The GPU results were re-measured in July 2026 under WSL2 (Linux) with torch 2.12 to add the Flash Attention backends. The CPU results are from the original benchmark. Ratios are only comparable within one figure: the Linux re-measurement made the fp32 baseline itself faster for small models, which compresses their speedup ratios relative to the original figures.
  </li>
  <li>
     **Datasets: ** 2000 samples for GPU tests, 1000 samples for CPU tests.

        <li>
           [sentence-transformers/stsb](https://huggingface.co/datasets/sentence-transformers/stsb): `sentence1` and `sentence2` columns as pairs, with 38.94 ± 13.97 and 38.96 ± 14.05 characters on average, respectively.
        </li>
        <li>
           [sentence-transformers/natural-questions](https://huggingface.co/datasets/sentence-transformers/natural-questions): `query` and `answer` columns as pairs, with 46.99 ± 10.98 and 619.63 ± 345.30 characters on average, respectively.
        </li>
        <li>
           [stanfordnlp/imdb](https://huggingface.co/datasets/stanfordnlp/imdb): Two variants used from the `text` column: first 100 characters (100.00 ± 0.00 characters) and each sample repeated 4 times (16804.25 ± 10178.26 characters).
        </li>

  </li>
  <li>
     **Models: **

        <li>
           [cross-encoder/ms-marco-MiniLM-L6-v2](https://huggingface.co/cross-encoder/ms-marco-MiniLM-L6-v2): 22.7M parameters. Batch sizes of 16, 32, 64, 128 and 256.
        </li>
        <li>
           [BAAI/bge-reranker-base](https://huggingface.co/BAAI/bge-reranker-base): 278M parameters. Batch sizes of 16, 32, 64, and 128.
        </li>
        <li>
           [mixedbread-ai/mxbai-rerank-large-v1](https://huggingface.co/mixedbread-ai/mxbai-rerank-large-v1): 435M parameters. Batch sizes of 8, 16, 32, and 64. Also 128 and 256 for GPU tests.
        </li>
        <li>
           [BAAI/bge-reranker-v2-m3](https://huggingface.co/BAAI/bge-reranker-v2-m3): 568M parameters. Batch sizes of 2, 4. Also 8, 16, and 32 for GPU tests.
        </li>

  </li>
Performance ratio: The same models and hardware was used. We compare the performance against the performance of PyTorch with fp32, i.e. the default backend and precision.
<li>
     **Evaluation: **

        <li>
           **Information Retrieval: **NDCG@10 based on cosine similarity on the MS MARCO and NQ subsets from the [NanoBEIR](https://huggingface.co/collections/zeta-alpha-ai/nanobeir-66e1a0af21dfd93e620cd9f6) collection of datasets, computed via the CrossEncoderNanoBEIREvaluator.
        </li>

  </li>


  <li>
     **Backends: **

        <li>
           `torch-fp32`: PyTorch with float32 precision (default).
        </li>
        <li>
           `torch-fp16`: PyTorch with float16 precision, via `model_kwargs={"torch_dtype": "float16"}`.
        </li>
        <li>
           `torch-bf16`: PyTorch with bfloat16 precision, via `model_kwargs={"torch_dtype": "bfloat16"}`.
        </li>
        <li>
           `torch-fp16-fa2` and `torch-bf16-fa2`: half precision with FlashAttention-2, via `model_kwargs={"torch_dtype": ..., "attn_implementation": "flash_attention_2"}`. Input unpadding does not apply to the sequence-classification task, so these measure the attention kernel swap alone.
        </li>
        <li>
           `onnx`: ONNX with float32 precision, via `backend="onnx"`.
        </li>
        <li>
           `onnx-O1`: ONNX with float32 precision and O1 optimization, via `export_optimized_onnx_model(..., optimization_config="O1", ...)` and `backend="onnx"`.
        </li>
        <li>
           `onnx-O2`: ONNX with float32 precision and O2 optimization, via `export_optimized_onnx_model(..., optimization_config="O2", ...)` and `backend="onnx"`.
        </li>
        <li>
           `onnx-O3`: ONNX with float32 precision and O3 optimization, via `export_optimized_onnx_model(..., optimization_config="O3", ...)` and `backend="onnx"`.
        </li>
        <li>
           `onnx-O4`: ONNX with float16 precision and O4 optimization, via `export_optimized_onnx_model(..., optimization_config="O4", ...)` and `backend="onnx"`.
        </li>
        <li>
           `onnx-qint8`: ONNX quantized to int8 with "avx512_vnni", via `export_dynamic_quantized_onnx_model(..., quantization_config="avx512_vnni", ...)` and `backend="onnx"`. The different quantization configurations resulted in roughly equivalent speedups.
        </li>
        <li>
           `openvino`: OpenVINO, via `backend="openvino"`.
        </li>
        <li>
           `openvino-qint8`: OpenVINO quantized to int8 via `export_static_quantized_openvino_model(..., quantization_config=OVQuantizationConfig(), ...)` and `backend="openvino"`.
        </li>

  </li>
Note that the aggressive averaging across models, datasets, and batch sizes prevents some more intricate patterns from being visible. For example, ONNX seems to perform stronger at low batch sizes. However, ONNX and OpenVINO can even perform slightly worse than PyTorch, so we recommend testing the different backends with your specific model and data to find the best one for your use case. The Flash Attention backends are not recommended for Cross Encoders: without input unpadding (feature-extraction only), they measured at or below plain fp16 everywhere. Compared to the original benchmark, the ONNX ratios dropped to roughly break-even (0.9 to 1.1x): exported graphs are static and do not inherit the torch runtime improvements that made the fp32 baseline much faster, so PyTorch with fp16 is now the better GPU default. Half precision still pays off 2 to 3x on the larger rerankers. Note that checkpoints stored in half precision (e.g. mxbai-rerank-large-v1, stored in fp16) load in that dtype by default since transformers v5, so they already run at fp16 speed without any configuration. The benchmark forces true fp32 for its baseline. On CPU, half precision must be avoided altogether: torch-fp16 and torch-bf16 run at roughly 0.17x.
.. image:: ../../img/ce_backends_benchmark_gpu.png
:alt: Benchmark for GPUs
:width: 45%
.. image:: ../../img/ce_backends_benchmark_cpu.png
:alt: Benchmark for CPUs
:width: 45%
Recommendations
^^^^^^^^^^^^^^^
Based on the benchmarks, this flowchart should help you decide which backend to use for your model:
.. mermaid::
%%{init: {
"theme": "neutral",
"flowchart": {
"curve": "bumpY"
}
}}%%
graph TD
A("What is your hardware?") -->|GPU| F[float16]
A -->|CPU| C("Are minor performancedegradations acceptable?")
C -->|yes| G[openvino-qint8]
C -->|no| H("Do you have an Intel CPU?")
H -->|yes| I[openvino]
H -->|no| J[onnx-O3]
click F "#pytorch"
click G "#quantizing-openvino-models"
click I "#openvino"
click J "#optimizing-onnx-models"
.. note::
Your mileage may vary, and you should always test the different backends with your specific model and data to find the best one for your use case.
User Interface
^^^^^^^^^^^^^^
This Hugging Face Space provides a user interface for exporting, optimizing, and quantizing models for either ONNX or OpenVINO:
sentence-transformers/backend-export <https://huggingface.co/spaces/sentence-transformers/backend-export>_
File: docs/cross_encoder/usage/usage.rst
Usage
Characteristics of Cross Encoder (a.k.a reranker) models:
- Calculates a similarity score given pairs of inputs (typically text pairs, but also image-text or other modalities).
- Generally provides superior performance compared to a Sentence Transformer (a.k.a. bi-encoder) model.
- Often slower than a Sentence Transformer model, as it requires computation for each pair rather than each text.
- Due to the previous 2 characteristics, Cross Encoders are often used to re-rank the top-k results from a Sentence Transformer model.
Once you have installed <../../installation.html>_ Sentence Transformers, you can easily use Cross Encoder models:
.. sidebar:: Documentation
- :class:
~sentence_transformers.cross_encoder.model.CrossEncoder - :meth:
CrossEncoder.predict <sentence_transformers.cross_encoder.model.CrossEncoder.predict> - :meth:
CrossEncoder.rank <sentence_transformers.cross_encoder.model.CrossEncoder.rank>
.. note::
MS Marco models return logits rather than scores between 0 and 1. Load the :class:~sentence_transformers.cross_encoder.model.CrossEncoder with activation_fn=torch.nn.Sigmoid() to get scores between 0 and 1. This does not affect the ranking.
::
from sentence_transformers import CrossEncoder
1. Load a pre-trained CrossEncoder model
model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2")
2. Predict scores for a pair of sentences
scores = model.predict([
("How many people live in Berlin?", "Berlin had a population of 3,520,031 registered inhabitants in an area of 891.82 square kilometers."),
("How many people live in Berlin?", "Berlin is well known for its museums."),
])
=> array([ 8.607138 , -4.3200774], dtype=float32)
3. Rank a list of passages for a query
query = "How many people live in Berlin?"
passages = [
"Berlin had a population of 3,520,031 registered inhabitants in an area of 891.82 square kilometers.",
"Berlin is well known for its museums.",
"In 2014, the city state Berlin had 37,368 live births (+6.6%), a record number since 1991.",
"The urban area of Berlin comprised about 4.1 million people in 2014, making it the seventh most populous urban area in the European Union.",
"The city of Paris had a population of 2,165,423 people within its administrative city limits as of January 1, 2019",
"An estimated 300,000-420,000 Muslims reside in Berlin, making up about 8-11 percent of the population.",
"Berlin is subdivided into 12 boroughs or districts (Bezirke).",
"In 2015, the total labour force in Berlin was 1.85 million.",
"In 2013 around 600,000 Berliners were registered in one of the more than 2,300 sport and fitness clubs.",
"Berlin has a yearly total of about 135 million day visitors, which puts it in third place among the most-visited city destinations in the European Union.",
]
ranks = model.rank(query, passages)
Print the scores
print("Query:", query)
for rank in ranks:
print(f"{rank['score']:.2f}\t{passages[rank['corpus_id']]}")
"""
Query: How many people live in Berlin?
8.92 The urban area of Berlin comprised about 4.1 million people in 2014, making it the seventh most populous urban area in the European Union.
8.61 Berlin had a population of 3,520,031 registered inhabitants in an area of 891.82 square kilometers.
8.24 An estimated 300,000-420,000 Muslims reside in Berlin, making up about 8-11 percent of the population.
7.60 In 2014, the city state Berlin had 37,368 live births (+6.6%), a record number since 1991.
6.35 In 2013 around 600,000 Berliners were registered in one of the more than 2,300 sport and fitness clubs.
5.42 Berlin has a yearly total of about 135 million day visitors, which puts it in third place among the most-visited city destinations in the European Union.
3.45 In 2015, the total labour force in Berlin was 1.85 million.
0.33 Berlin is subdivided into 12 boroughs or districts (Bezirke).
-4.24 The city of Paris had a population of 2,165,423 people within its administrative city limits as of January 1, 2019
-4.32 Berlin is well known for its museums.
"""
Some CrossEncoder models also support multimodal inputs, allowing you to score pairs that include images, not just text. You can check which modalities a model supports using the :attr:~sentence_transformers.cross_encoder.model.CrossEncoder.modalities property and the :meth:~sentence_transformers.cross_encoder.model.CrossEncoder.supports method. Each element in a pair can be any of the following:
.. tip::
Multimodal models require additional dependencies. Install them with e.g. pip install -U "sentence-transformers[image]" for image support. See Installation <../../installation.html>_ for all options.
- Text: strings.
- Image: PIL images, file paths, URLs, or numpy/torch arrays.
- Audio: file paths, numpy/torch arrays, dicts with
"array"and"sampling_rate"keys, or (iftorchcodecinstalled) :class:torchcodec.AudioDecoder <torchcodec.decoders.AudioDecoder>instances. - Video: file paths, numpy/torch arrays, dicts with
"array"and"video_metadata"keys, or (iftorchcodecinstalled) :class:torchcodec.VideoDecoder <torchcodec.decoders.VideoDecoder>instances. - Multimodal dicts: a dict mapping modality names to values, e.g.
{"text": ..., "image": ...}. The keys must be"text","image","audio", or"video".
The two elements in a pair can have different modalities (e.g. a text query with an image document), depending on the underlying model architecture:
.. sidebar:: Modality Support
.. code-block:: python
from sentence_transformers import CrossEncoder

  model = CrossEncoder("Qwen/Qwen3-VL-Reranker-2B")

  # List all supported modalities
  print(model.modalities)
  # ['text', 'image', 'video', 'message']

  # Check for a specific modality
  print(model.supports("image"))
  # True

  print(model.supports(("image", "text")))
  # True
.. code-block:: python
from sentence_transformers import CrossEncoder
model = CrossEncoder("Qwen/Qwen3-VL-Reranker-2B")
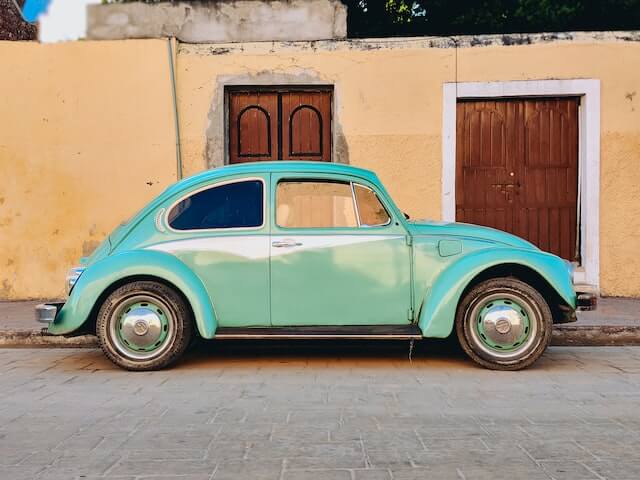
query = "A green car parked in front of a yellow building"
documents = [
# Image documents (URL or local file path)
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg",
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
# Text document
"A vintage Volkswagen Beetle painted in bright green sits in a driveway.",
# Combined text + image document
{
"text": "A car in a European city",
"image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/car.jpg",
},
]
rankings = model.rank(query, documents)
for rank in rankings:
print(f"{rank['score']:.4f}\t(document {rank['corpus_id']})")
"""
0.9375 (document 0)
0.5000 (document 3)
-1.2500 (document 2)
-2.4375 (document 1)
"""
In this example, the multimodal CrossEncoder uses the same modular architecture as a text-only CausalLM CrossEncoder (:class:~sentence_transformers.base.modules.Transformer + :class:~sentence_transformers.cross_encoder.modules.LogitScore), but the :class:~sentence_transformers.base.modules.Transformer module is backed by a vision-language model that can process both images and text through its chat template.
.. toctree::
:maxdepth: 1
:caption: Tasks and Advanced Usage
Cross-Encoder vs Bi-Encoder <../../../examples/cross_encoder/applications/README>
../../../examples/sentence_transformer/applications/retrieve_rerank/README
custom_models
efficiency
File: docs/cross_encoder/loss_overview.md
Loss Overview
Loss Table
Loss functions play a critical role in the performance of your fine-tuned Cross Encoder model. Sadly, there is no "one size fits all" loss function. Ideally, this table should help narrow down your choice of loss function(s) by matching them to your data formats.
.. note::

    You can often convert one training data format into another, allowing more loss functions to be viable for your scenario. For example, ``(input_A, input_B) pairs`` with ``class`` labels can be converted into ``(anchor, positive, negative) triplets`` by sampling inputs with the same or different classes.

    Additionally, :func:`~sentence_transformers.util.hard_negatives.mine_hard_negatives` can easily be used to turn ``(anchor, positive)`` to:

    - ``(anchor, positive, negative) triplets`` with ``output_format="triplet"``,
    - ``(anchor, positive, negative_1, …, negative_n) tuples`` with ``output_format="n-tuple"``.
    - ``(anchor, document, label) labeled pairs`` with a label of 0 for negative and 1 for positive with ``output_format="labeled-pair"``,
    - ``(anchor, [doc1, doc2, ..., docN], [label1, label2, ..., labelN]) triplets`` with labels of 0 for negative and 1 for positive with ``output_format="labeled-list"``

As well as formats with similarity scores instead of binarized labels, by setting ``output_scores=True``.| Inputs | Labels | Number of Model Output Labels | Appropriate Loss Functions |
|---|---|---|---|
(input_A, input_B) pairs |
class |
num_classes |
CrossEntropyLoss |
(anchor, positive) pairs |
none |
1 |
MultipleNegativesRankingLossCachedMultipleNegativesRankingLoss |
(anchor, positive/negative) pairs |
1 if positive, 0 if negative |
1 |
BinaryCrossEntropyLoss |
(input_A, input_B) pairs |
float similarity score between 0 and 1 |
1 |
BinaryCrossEntropyLoss |
(anchor, positive, negative) triplets |
none |
1 |
MultipleNegativesRankingLossCachedMultipleNegativesRankingLoss |
(anchor, positive, negative_1, ..., negative_n) |
none |
1 |
MultipleNegativesRankingLossCachedMultipleNegativesRankingLoss |
(query, [doc1, doc2, ..., docN]) |
[score1, score2, ..., scoreN] |
1 |
Distillation
These loss functions are specifically designed to be used when distilling the knowledge from one model into another.
For example, when finetuning a small model to behave more like a larger & stronger one, or when finetuning a model to become multi-lingual.
| Inputs | Labels | Appropriate Loss Functions |
|---|---|---|
(input_A, input_B) pairs |
similarity score |
MSELoss |
(query, document_one, document_two) triplets |
gold_sim(query, document_one) - gold_sim(query, document_two) |
MarginMSELoss |
(query, positive, negative_1, ..., negative_n) |
[gold_sim(query, positive) - gold_sim(query, negative_i) for i in 1..n] |
MarginMSELoss |
(query, positive, negative) |
[gold_sim(query, positive), gold_sim(query, negative)] |
MarginMSELoss |
(query, positive, negative_1, ..., negative_n) |
[gold_sim(query, positive), gold_sim(query, negative_i)...] |
MarginMSELoss |
Commonly used Loss Functions
In practice, not all loss functions get used equally often. The most common scenarios are:
(input_A, input_B) pairswithfloat similarity scoreor1 if positive, 0 if negative:BinaryCrossEntropyLossis a traditional option that remains very challenging to outperform.(anchor, positive) pairswithout any labels: combined withmine_hard_negatives- with
output_format="labeled-list", thenLambdaLossis frequently used for learning-to-rank tasks. - with
output_format="labeled-pair", thenBinaryCrossEntropyLossremains a strong option.
- with
Custom Loss Functions
Advanced users can create and train with their own loss functions. Custom loss functions only have a few requirements:

- They must be a subclass of :class:`torch.nn.Module`.
- They must have ``model`` as the first argument in the constructor.
- They must implement a ``forward`` method that accepts ``inputs`` and ``labels``. The former is a nested list of texts in the batch, with each element in the outer list representing a column in the training dataset. You have to combine these texts into pairs that can be 1) tokenized and 2) fed to the model. The latter is an optional (list of) tensor(s) of labels from a ``label``, ``labels``, ``score``, or ``scores`` column in the dataset. The method must return a single loss value or a dictionary of loss components (component names to loss values) that will be summed to produce the final loss value. When returning a dictionary, the individual components will be logged separately in addition to the summed loss, allowing you to monitor the individual components of the loss.

To get full support with the automatic model card generation, you may also wish to implement:

- a ``get_config_dict`` method that returns a dictionary of loss parameters.
- a ``citation`` property so your work gets cited in all models that train with the loss.

Consider inspecting existing loss functions to get a feel for how loss functions are commonly implemented.
File: docs/cross_encoder/pretrained_models.md
Pretrained Models
We have released various pre-trained Cross Encoder models via our Cross Encoder Hugging Face organization. Additionally, numerous community Cross Encoder models have been publicly released on the Hugging Face Hub.

* **Original models**: `Cross Encoder Hugging Face organization <https://huggingface.co/models?library=sentence-transformers&author=cross-encoder>`_.
* **Community models**: `All Cross Encoder models on Hugging Face <https://huggingface.co/models?library=sentence-transformers&pipeline_tag=text-ranking>`_.

Each of these models can be easily downloaded and used like so:from sentence_transformers import CrossEncoder
import torch
# Load https://huggingface.co/cross-encoder/ms-marco-MiniLM-L6-v2
model = CrossEncoder("cross-encoder/ms-marco-MiniLM-L6-v2", activation_fn=torch.nn.Sigmoid())
scores = model.predict([
("How many people live in Berlin?", "Berlin had a population of 3,520,031 registered inhabitants in an area of 891.82 square kilometers."),
("How many people live in Berlin?", "Berlin is well known for its museums."),
])
# => array([0.9998173 , 0.01312432], dtype=float32)Cross-Encoders require pairs as inputs and output a score (0 to 1 if the Sigmoid activation function is used). Most models work with text pairs, but some also support non-text inputs such as images (see Multimodal Rerankers). Cross-Encoders do not work for individual sentences and they don't compute embeddings for individual texts.
MS MARCO
MS MARCO Passage Retrieval is a large dataset with real user queries from Bing search engine with annotated relevant text passages. Models trained on this dataset are very effective as rerankers for search systems.
.. note::
You can initialize these models with ``activation_fn=torch.nn.Sigmoid()`` to force the model to return scores between 0 and 1. Otherwise, the raw value can reasonably range between -10 and 10.| Model Name | NDCG@10 (TREC DL 19) | MRR@10 (MS Marco Dev) | Docs / Sec |
|---|---|---|---|
| cross-encoder/ms-marco-TinyBERT-L2-v2 | 69.84 | 32.56 | 9000 |
| cross-encoder/ms-marco-MiniLM-L2-v2 | 71.01 | 34.85 | 4100 |
| cross-encoder/ms-marco-MiniLM-L4-v2 | 73.04 | 37.70 | 2500 |
| cross-encoder/ms-marco-MiniLM-L6-v2 | 74.30 | 39.01 | 1800 |
| cross-encoder/ms-marco-MiniLM-L12-v2 | 74.31 | 39.02 | 960 |
| cross-encoder/ms-marco-electra-base | 71.99 | 36.41 | 340 |
For details on the usage, see Retrieve & Re-Rank.
SQuAD (QNLI)
QNLI is based on the SQuAD dataset (HF) and was introduced by the GLUE Benchmark (HF). Given a passage from Wikipedia, annotators created questions that are answerable by that passage. These models output higher scores if a passage answers a question.
| Model Name | Accuracy on QNLI dev set |
|---|---|
| cross-encoder/qnli-distilroberta-base | 90.96 |
| cross-encoder/qnli-electra-base | 93.21 |
STSbenchmark
The following models can be used like this:
from sentence_transformers import CrossEncoder

model = CrossEncoder("cross-encoder/stsb-roberta-base")
scores = model.predict([("It's a wonderful day outside.", "It's so sunny today!"), ("It's a wonderful day outside.", "He drove to work earlier.")])
# => array([0.60443085, 0.00240758], dtype=float32)
They return a score 0...1 indicating the semantic similarity of the given sentence pair.
| Model Name | STSbenchmark Test Performance |
|---|---|
| cross-encoder/stsb-TinyBERT-L4 | 85.50 |
| cross-encoder/stsb-distilroberta-base | 87.92 |
| cross-encoder/stsb-roberta-base | 90.17 |
| cross-encoder/stsb-roberta-large | 91.47 |
Quora Duplicate Questions
These models have been trained on the Quora duplicate questions dataset. They can used like the STSb models and give a score 0...1 indicating the probability that two questions are duplicate questions.
| Model Name | Average Precision dev set |
|---|---|
| cross-encoder/quora-distilroberta-base | 87.48 |
| cross-encoder/quora-roberta-base | 87.80 |
| cross-encoder/quora-roberta-large | 87.91 |
.. note::
    The model don't work for question similarity. The question "How to learn Java?" and "How to learn Python?" will get a low score, as these questions are not duplicates. For question similarity, a :class:`~sentence_transformers.sentence_transformer.model.SentenceTransformer` trained on the Quora dataset will yield much more meaningful results.
NLI
Given two sentences, are these contradicting each other, entailing one the other or are these neutral? The following models were trained on the SNLI and MultiNLI datasets.
| Model Name | Accuracy on MNLI mismatched set |
|---|---|
| cross-encoder/nli-deberta-v3-base | 90.04 |
| cross-encoder/nli-deberta-base | 88.08 |
| cross-encoder/nli-deberta-v3-xsmall | 87.77 |
| cross-encoder/nli-deberta-v3-small | 87.55 |
| cross-encoder/nli-roberta-base | 87.47 |
| cross-encoder/nli-MiniLM2-L6-H768 | 86.89 |
| cross-encoder/nli-distilroberta-base | 83.98 |
from sentence_transformers import CrossEncoder

model = CrossEncoder("cross-encoder/nli-deberta-v3-base")
scores = model.predict([
    ("A man is eating pizza", "A man eats something"),
    ("A black race car starts up in front of a crowd of people.", "A man is driving down a lonely road."),
])

# Convert scores to labels
label_mapping = ["contradiction", "entailment", "neutral"]
labels = [label_mapping[score_max] for score_max in scores.argmax(axis=1)]
# => ['entailment', 'contradiction']
Multimodal Rerankers
Multimodal rerankers can score pairs involving different modalities such as images, video, audio, and text. These models use the same :class:`~sentence_transformers.base.modules.Transformer` + :class:`~sentence_transformers.cross_encoder.modules.LogitScore` architecture as text-only decoder rerankers, but with a multimodal backbone that can process non-text inputs. You can check whether a model supports a given modality using :attr:`~sentence_transformers.cross_encoder.model.CrossEncoder.modalities` and :meth:`~sentence_transformers.cross_encoder.model.CrossEncoder.supports`... seealso::
See the `Multimodal Embedding & Reranker Models <https://huggingface.co/blog/multimodal-sentence-transformers>`_ blogpost for an inference walkthrough and an overview of the multimodal models supported at the time of writing.Here are some community models:
- Qwen/Qwen3-VL-Reranker-2B
- Qwen/Qwen3-VL-Reranker-8B
- nvidia/llama-nemotron-rerank-vl-1b-v2
- jinaai/jina-reranker-m0
See Cross Encoder > Usage for usage examples, and the training scripts in examples/cross_encoder/training/multimodal/ to fine-tune your own multimodal reranker.
Community Models
Some notable models from the Community include:
- BAAI/bge-reranker-base
- BAAI/bge-reranker-large
- BAAI/bge-reranker-v2-m3
- BAAI/bge-reranker-v2-gemma
- BAAI/bge-reranker-v2-minicpm-layerwise
- jinaai/jina-reranker-v1-tiny-en
- jinaai/jina-reranker-v1-turbo-en
- mixedbread-ai/mxbai-rerank-xsmall-v1
- mixedbread-ai/mxbai-rerank-base-v1
- mixedbread-ai/mxbai-rerank-large-v1
- maidalun1020/bce-reranker-base_v1
- Alibaba-NLP/gte-reranker-modernbert-base
- Alibaba-NLP/gte-multilingual-reranker-base
File: docs/cross_encoder/training_overview.md
Training Overview
.. tip::

   Using an AI coding agent (Claude Code, Codex, Cursor, Gemini CLI, ...)?

   .. code-block:: bash
      :class: tight-code

      hf skills add train-sentence-transformers [--claude] [--global]

   And ask your agent to fine-tune a reranker for whatever task you have in mind.
Why Finetune?
Cross Encoder models are very often used as 2nd stage rerankers in a Retrieve and Rerank search stack. In such a situation, the Cross Encoder reranks the top X candidates from the retriever (which can be a Sentence Transformer model). To avoid the reranker model reducing the performance on your use case, finetuning it can be crucial. Rerankers always have just 1 output label.
Beyond that, Cross Encoder models can also be used as pair classifiers. For example, a model trained on Natural Language Inference data can be used to classify pairs of texts as "contradiction", "entailment", and "neutral". Pair Classifiers generally have more than 1 output label.
See Training Examples for numerous training scripts for common real-world applications that you can adopt.
Training Components
Training Cross Encoder models involves between 4 to 6 components, just like training Sentence Transformer models:
<a href="#model" class="box">
    Model
    Learn how to initialize the **model** for training.
</a>
<a href="#dataset" class="box">
    Dataset
    Learn how to prepare the **data** for training.
</a>
<a href="#loss-function" class="box">
    Loss Function
    Learn how to prepare and choose a **loss** function.
</a>
<a href="#training-arguments" class="box optional">
    Training Arguments
    Learn which **training arguments** are useful.
</a>
<a href="#evaluator" class="box optional">
    Evaluator
    Learn how to **evaluate** during and after training.
</a>
<a href="#trainer" class="box">
    Trainer
    Learn how to start the **training** process.
</a>
Model
/* Detailed source-code truncated for AI context efficiency. */Dataset
/* Detailed source-code truncated for AI context efficiency. */Dataset Format
/* Detailed source-code truncated for AI context efficiency. */Multimodal Datasets
/* Detailed source-code truncated for AI context efficiency. */Hard Negatives Mining
The success of training CrossEncoder models often depends on the quality of the negatives, i.e. the passages for which the query-negative score should be low. Negatives can be divided into two types:
- Soft negatives: passages that are completely unrelated.
- Hard negatives: passages that seem like they might be relevant for the query, but are not.
A concise example is:
- Query: Where was Apple founded?
- Soft Negative: The Cache River Bridge is a Parker pony truss that spans the Cache River between Walnut Ridge and Paragould, Arkansas.
- Hard Negative: The Fuji apple is an apple cultivar developed in the late 1930s, and brought to market in 1962.
/* Detailed source-code truncated for AI context efficiency. */Click to see the outputs of this script.
/* Detailed source-code truncated for AI context efficiency. */Loss Function
Loss functions quantify how well a model performs for a given batch of data, allowing an optimizer to update the model weights to produce more favourable (i.e., lower) loss values. This is the core of the training process.
Sadly, there is no single loss function that works best for all use-cases. Instead, which loss function to use greatly depends on your available data and on your target task. See Dataset Format to learn what datasets are valid for which loss functions. Additionally, the Loss Overview will be your best friend to learn about the options.
Most loss functions can be initialized with just the :class:`~sentence_transformers.cross_encoder.model.CrossEncoder` that you're training, alongside some optional parameters, e.g.:

.. sidebar:: Documentation

    - :class:`sentence_transformers.cross_encoder.losses.MultipleNegativesRankingLoss`
    - `Losses API Reference <../package_reference/cross_encoder/losses.html>`_
    - `Loss Overview <loss_overview.html>`_

::

    from datasets import load_dataset
    from sentence_transformers import CrossEncoder
    from sentence_transformers.cross_encoder.losses import MultipleNegativesRankingLoss

    # Load a model to train/finetune (num_labels=1 is for rerankers)
    model = CrossEncoder("FacebookAI/xlm-roberta-base", num_labels=1, model_kwargs={"torch_dtype": "float32"})

    # Initialize the MultipleNegativesRankingLoss
    # This loss requires pairs of related texts or triplets
    loss = MultipleNegativesRankingLoss(model)

    # Load an example training dataset that works with our loss function:
    train_dataset = load_dataset("sentence-transformers/gooaq", split="train")
Training Arguments
The :class:`~sentence_transformers.cross_encoder.training_args.CrossEncoderTrainingArguments` class can be used to specify parameters for influencing training performance as well as defining the tracking/debugging parameters. Although it is optional, it is heavily recommended to experiment with the various useful arguments.Key Training Arguments for improving training performance
[`learning_rate`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.learning_rate)
[`lr_scheduler_type`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.lr_scheduler_type)
[`warmup_steps`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.warmup_steps)
[`num_train_epochs`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.num_train_epochs)
[`max_steps`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.max_steps)
[`per_device_train_batch_size`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.per_device_train_batch_size)
[`per_device_eval_batch_size`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.per_device_eval_batch_size)
[`auto_find_batch_size`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.auto_find_batch_size )
[`fp16`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.fp16)
[`bf16`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.bf16)
[`load_best_model_at_end`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.load_best_model_at_end)
[`metric_for_best_model`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.metric_for_best_model)
[`gradient_accumulation_steps`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.gradient_accumulation_steps)
[`gradient_checkpointing`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.gradient_checkpointing)
[`eval_accumulation_steps`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.eval_accumulation_steps)
[`optim`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.optim)
[`dataloader_num_workers`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.dataloader_num_workers)
[`dataloader_persistent_workers`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.dataloader_persistent_workers)
[`dataloader_prefetch_factor`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.dataloader_prefetch_factor)
[`batch_sampler`](../package_reference/cross_encoder/training_args.html#sentence_transformers.cross_encoder.training_args.CrossEncoderTrainingArguments)
[`multi_dataset_batch_sampler`](../package_reference/cross_encoder/training_args.html#sentence_transformers.cross_encoder.training_args.CrossEncoderTrainingArguments)
[`learning_rate_mapping`](../package_reference/cross_encoder/training_args.html#sentence_transformers.cross_encoder.training_args.CrossEncoderTrainingArguments)
Key Training Arguments for observing training performance
[`eval_strategy`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.eval_strategy)
[`eval_steps`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.eval_steps)
[`save_strategy`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.save_strategy)
[`save_steps`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.save_steps)
[`save_total_limit`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.save_total_limit)
[`report_to`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.report_to)
[`run_name`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.run_name)
[`log_level`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.log_level)
[`logging_steps`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.logging_steps)
[`push_to_hub`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.push_to_hub)
[`hub_model_id`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.hub_model_id)
[`hub_strategy`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.hub_strategy)
[`hub_private_repo`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.hub_private_repo)Here is an example of how :class:`~sentence_transformers.cross_encoder.training_args.CrossEncoderTrainingArguments` can be initialized:from sentence_transformers.cross_encoder import CrossEncoderTrainingArguments
args = CrossEncoderTrainingArguments(
# Required parameter:
output_dir="models/reranker-MiniLM-msmarco-v1",
# Optional training parameters:
num_train_epochs=1,
per_device_train_batch_size=16,
per_device_eval_batch_size=16,
learning_rate=2e-5,
warmup_steps=0.1,
fp16=True, # Set to False if you get an error that your GPU can't run on FP16
bf16=False, # Set to True if you have a GPU that supports BF16
batch_sampler=BatchSamplers.NO_DUPLICATES, # losses that use "in-batch negatives" benefit from no duplicates
# Optional tracking/debugging parameters:
eval_strategy="steps",
eval_steps=0.1,
save_strategy="steps",
save_steps=0.1,
save_total_limit=2,
logging_steps=0.01,
run_name="reranker-MiniLM-msmarco-v1", # Will be used in W&B if `wandb` is installed
)Evaluator
/* Detailed source-code truncated for AI context efficiency. */Trainer
/* Detailed source-code truncated for AI context efficiency. */Callbacks
This CrossEncoder trainer integrates support for various :class:`transformers.TrainerCallback` subclasses, such as:

- :class:`~transformers.integrations.WandbCallback` to automatically log training metrics to W&B if ``wandb`` is installed
- :class:`~transformers.integrations.TensorBoardCallback` to log training metrics to TensorBoard if ``tensorboard`` is accessible.
- :class:`~transformers.integrations.CodeCarbonCallback` to track the carbon emissions of your model during training if ``codecarbon`` is installed.

    - Note: These carbon emissions will be included in your automatically generated model card.

See the Transformers `Callbacks <https://huggingface.co/docs/transformers/main/en/main_classes/callback>`_
documentation for more information on the integrated callbacks and how to write your own callbacks.
Multi-Dataset Training
The top performing models are trained using many datasets at once. Normally, this is rather tricky, as each dataset has a different format. However, :class:`~sentence_transformers.cross_encoder.trainer.CrossEncoderTrainer` can train with multiple datasets without having to convert each dataset to the same format. It can even apply different loss functions to each of the datasets. The steps to train with multiple datasets are:

- Use a dictionary of :class:`~datasets.Dataset` instances (or a :class:`~datasets.DatasetDict`) as the ``train_dataset`` (and optionally also ``eval_dataset``).
- (Optional) Use a dictionary of loss functions mapping dataset names to losses. Only required if you wish to use different loss function for different datasets.

Each training/evaluation batch will only contain samples from one of the datasets. The order in which batches are samples from the multiple datasets is defined by the :class:`~sentence_transformers.base.sampler.MultiDatasetBatchSamplers` enum, which can be passed to the :class:`~sentence_transformers.cross_encoder.training_args.CrossEncoderTrainingArguments` via ``multi_dataset_batch_sampler``. Valid options are:

- ``MultiDatasetBatchSamplers.ROUND_ROBIN``: Round-robin sampling from each dataset until one is exhausted. With this strategy, it’s likely that not all samples from each dataset are used, but each dataset is sampled from equally.
- ``MultiDatasetBatchSamplers.PROPORTIONAL`` (default): Sample from each dataset in proportion to its size. With this strategy, all samples from each dataset are used and larger datasets are sampled from more frequently.
Training Tips
/* Detailed source-code truncated for AI context efficiency. */Deprecated Training
/* Detailed source-code truncated for AI context efficiency. */Comparisons with SentenceTransformer Training
Training :class:`~sentence_transformers.cross_encoder.model.CrossEncoder` models is very similar as training :class:`~sentence_transformers.sentence_transformer.model.SentenceTransformer` models, with some key differences:

- In :class:`~sentence_transformers.sentence_transformer.model.SentenceTransformer` training, you cannot use lists of inputs (e.g. texts) in a column of the training/evaluation dataset(s). For :class:`~sentence_transformers.cross_encoder.model.CrossEncoder` training, you **can** use (variably sized) lists of texts in a column. This is required for the :class:`~sentence_transformers.cross_encoder.losses.ListNetLoss` class, for example.

See the `Sentence Transformer > Training Overview <../sentence_transformer/training_overview.html>`_ documentation for more details on training :class:`~sentence_transformers.sentence_transformer.model.SentenceTransformer` models.
End-to-End Example
For a complete end-to-end training example, see the Training and Finetuning Reranker Models blogpost. It applies the components described on this page to a real training task, then benchmarks the resulting reranker against its base checkpoint and against other reranker models of various sizes. For multimodal reranker training, there's some details in the Training and Finetuning Multimodal Embedding & Reranker Models blogpost.
File: docs/package_reference/util/distributed.rst
distributed
.. automodule:: sentence_transformers.util.distributed
:members: