

1. Project Overview & Quickstart (QwenLM/common-workflow)
common-workflow
Open-source repository QwenLM/common-workflow
Repository Details
- Repository: QwenLM/common-workflow
- Primary Language: Code
Note: High-volume repository documentation is actively indexed and synchronized by YakaAI.
2. Official Technical Reference & Guides (QwenLM/QwenLM.github.io)
File: content/about/index.md
title: "About Us"
search_hidden: true
show_bread_crumbs: false
hide_meta: true
disable_share: true
header:
background: "linear-gradient(to top, #30cfd0 0%, #330867 100%);"
Qwen Team
The Qwen team aims at chasing artificial general intelligence and now focuses on building generalist models, including large language models and large multimodal models. We embrace opensource and previously we have released the Qwen model series, including the language models (Qwen), expert models (Qwen-Coder and Qwen-Math), and multimodal models (Qwen-VL and Qwen-Audio). Additionally, we have built web service and APP for users to benefit from the assistance of Qwen for your daily work and life. We are a group of people with diverse talents and interests. Feel free to chat with us and welcome to join us!
Links
In the following, we provide important links for you to refer to our opensource resources.
Resources
{{< button href="https://github.com/QwenLM/Qwen" label="GITHUB" external=true >}}
{{< button href="https://modelscope.com/organization/qwen" label="MODELSCOPE" external=true >}}
{{< button href="https://huggingface.co/Qwen" label="HUGGING FACE" external=true >}}
{{< button href="https://www.kaggle.com/models/qwen-lm" label="KAGGLE" external=true >}}
Social Media
{{< button href="https://x.com/Alibaba_Qwen" label="X" external=true >}}
{{< button href="https://www.linkedin.com/company/qwen/" label="LINKEDIN" external=true >}}
{{< button href="https://discord.com/invite/CV4E9rpNSD" label="DISCORD" external=true >}}
API
{{< button href="https://www.alibabacloud.com/en/product/modelstudio" label="ALIBABA CLOUD" external=true >}}
{{< button href="https://www.aliyun.com/product/bailian" label="ALIYUN" external=true >}}
File: content/blog/chinese-clip/index.md
title: "Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese"
date: 2022-12-24T14:54:19+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
author: ["Junyang Lin", "Binyuan Hui"]
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: false
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "cnclip_banner.jpg"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
CLIP[^1] is a phenomenal playmaker in vision and multimodal representation learning. It plays not only as a foundation model but also a bridge between vision and language. It has triggered a series of research in different fields, especially text-to-image generation. However, we find that there is a necessity for a language-specific CLIP for applications, especially cross-modal retrieval, and there is no opensourced Chinese CLIP with good performance. We therefore launched this project to promote the Chinese multimodal representation learning.
{{< button href="https://arxiv.org/abs/2211.01335" label="Paper" external=true >}}
{{< button href="https://github.com/OFA-Sys/Chinese-CLIP" label="GitHub" external=true >}}
{{< button href="https://www.modelscope.cn/models/damo/multi-modal_clip-vit-base-patch16_zh/summary" label="ModelScope" external=true >}}
{{< button href="https://huggingface.co/spaces/OFA-Sys/chinese-clip-zero-shot-image-classification" label="Demo" external=true >}}
Background
In real-world vision-language applications, e.g., cross-modal retrieval, the language plays an important role. Suppose we directly use CLIP and translation for texts, the quality of translation will significantly impact the downstream performance. Furthermore, another significant issue is the domains of pretraining data. If we hope the model achieve good performance on the Chinese data, there is also a necessity for CLIP to adapt to the domain of images in the Chinese websites, which reflect cultural values, social landscape, etc.
Here is an example of the search with mCLIP[^2]. We find that it is really hard for the model to understand some concepts in Chinese, and it can only retrieve relevant items that belong to western culture.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/search.jpg#center" width="80%" >}}

Also, we have conducted experiments on cross-modal retrieval with the original CLIP plus machine translation. The performance significantly degrades and falls far back behind our Chinese CLIP. This is also an evidence to support why we need a language-specific CLIP.
Method
In general, we follow the setups of the original CLIP, and we propose a two-stage pretraining method that shows better performance than training from scratch. We believe this is a more cost-effective way to transfer CLIP to another language.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/chinese-clip-model-v3.jpg#center" width="80%" >}}

In the first stage, we initialize the two towers with pretrained models, which are the vision encoder of CLIP, e.g., ViT-B, ResNet, etc., and Chinese RoBERTa RoBERTA-wwm-Chinese. We freeze the image encoder and contrastively tune the language encoder that maps its representation to the output space of CLIP vision encoder. In the second stage, we unlock the vision encoder and contrastively tune the two towers so that the vision encoder can learn to model the distribution of the images of Chinese data.
To make this research reproducible, we mostly use the public datasets for pretraining, including the part marked with "zh" in LAION-5B[^3], Wukong dataset[^4], the translated data from Visual Genome and MSCOCO, etc. The total amount of the image-text pairs reaches 200 million.
We released 5 versions of Chinese CLIP, including ResNet-50, ViT-B/16, ViT-L/14, ViT-L/14
@336px, and ViT-H/14. The statistics are listed below.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/model_variants.jpg#center" width="80%" >}}

Experiments
The experiments are conducted on 3 cross-modal retrieval datasets, including the Chinese native dataset MUGE, and the English-native datasets (which means the images and texts are not from the Chinese websites) Flickr30K-CN and COCO-CN. On all datasets, Chinese CLIP performs the best, and its gap with the previous best models in MUGE is much larger than those in the other datasets. This demonstrates that our method is contributive to building a language specific CLIP model that can perform much better on native datasets.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/muge.jpg#center" width="80%" >}}

{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/flickr.jpg#center" width="80%" >}}

{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/coco.jpg#center" width="80%" >}}

We also try Chinese CLIP on zero-shot image classification, and we participate in the ELEVATER benchmark[^5] by translating all labels and prompts to Chinese manually. Results show that Chinese CLIP can also achieve a competitive performance in the English-native benchmark.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/elevater.jpg#center" width="80%" >}}

For the ablation, it can be found that in comparison with training from scratch, the two-stage pretraining method demonstrates much better performance, and the second-stage pretraining can further level up the model performance in cross-modal retrieval.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/ablation.jpg#center" title="Ablation studies." >}}

Limitations and Future Work
Though the above contents show the effectiveness of Chinese CLIP, we still need to work on validating its role as a vision foundation model. Empirically, it should be a strong foundation model for tasks of Chinese-native data. Thus, in the next step, we will work on building a benchmark for Chinese multimodal representation learning and vision representation learning.
Feel free to visit our GitHub repo and use the codes and checkpoints. Hope they will be helpful for your research or applications!
[^1]: Radford, A., Kim, J.W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., Krueger, G., & Sutskever, I. (2021).
Learning Transferable Visual Models From Natural Language Supervision.
International Conference on Machine Learning.
[^2]: Carlsson, F., Eisen, P., Rekathati, F., & Sahlgren, M. (2022).
Cross-lingual and Multilingual CLIP.
International Conference on Language Resources and Evaluation.
[^3]: Schuhmann, C., Beaumont, R., Vencu, R., Gordon, C., Wightman, R., Cherti, M., Coombes, T., Katta, A., Mullis, C., Wortsman, M., Schramowski, P., Kundurthy, S., Crowson, K., Schmidt, L., Kaczmarczyk, R., & Jitsev, J. (2022).
LAION-5B: An open large-scale dataset for training next generation image-text models.
arXiv, abs/2210.08402.
[^4]: Gu, J., Meng, X., Lu, G., Hou, L., Niu, M., Xu, H., Liang, X., Zhang, W., Jiang, X., & Xu, C. (2022).
Wukong: 100 Million Large-scale Chinese Cross-modal Pre-training Dataset and A Foundation Framework.
arXiv, abs/2202.06767.
[^5]: Li, C., Liu, H., Li, L., Zhang, P., Aneja, J., Yang, J., Jin, P., Lee, Y.J., Hu, H., Liu, Z., & Gao, J. (2022).
ELEVATER: A Benchmark and Toolkit for Evaluating Language-Augmented Visual Models.
arXiv, abs/2204.08790.
File: content/blog/chinese-clip/index.zh.md
title: "Chinese CLIP: 中文图文对比学习预训练"
date: 2022-12-24T14:54:19+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
author: ["Junyang Lin", "Binyuan Hui"]
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: false
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "cnclip_banner.jpg"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
lang: zh-CNs
CLIP[^1]是多模态表示学习领域一个现象级的模型。它不仅扮演基础模型,并且建立了视觉和语言的桥梁。它还推动了很多其他领域技术的发展,尤其是文本生成图像。然而,我们还需要特定语言的CLIP,尤其在现实应用中,比如跨模态检索。在此之前还没有效果较好的开源中文CLIP。因此我们希望通过这个项目推动中文多模态的发展。
{{< button href="https://arxiv.org/abs/2211.01335" label="论文" external=true >}}
{{< button href="https://github.com/OFA-Sys/Chinese-CLIP" label="Github" external=true >}}
{{< button href="https://www.modelscope.cn/models/damo/multi-modal_clip-vit-base-patch16_zh/summary" label="ModelScope" external=true >}}
{{< button href="https://huggingface.co/spaces/OFA-Sys/chinese-clip-zero-shot-image-classification" label="体验" external=true >}}
背景
在诸如跨模态检索的图文应用中,语言往往扮演重要的角色。假设直接使用CLIP和翻译文本,翻译质量将严重影响下游任务表现。此外,预训练数据的分布也同样重要。我们希望能够有一个模型较好地建模中文世界的数据,那么CLIP的图像学习同样需要适应到中文世界图像的领域中,这些图像在很多维度都有自己的特色,比如它所蕴含的文化价值、展现的社会风貌等。
下面是一个多语言CLIP[^2]检索的例子。不难看出,模型难以理解一些中文概念,甚至只能召回一些西方文化类似的概念的图片。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/search.jpg#center" width="80%" >}}
并且,我们还做了相关实验,对比原始CLIP配合翻译文本和中文CLIP在跨模态检索任务上的表现。原始CLIP的效果远低于中文CLIP,这也一定程度反映语言特定的CLIP模型的必要性。
方法
我们尽可能采用和原始CLIP一致的设定,不去增加模块或者设计复杂化的训练方法。而为了更加高效的训练,包括训练效率和最终迁移效果的提升,我们没有选择从头开始预训练,而是提出一个两阶段预训练的方法。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/chinese-clip-model-v3.jpg#center" width="80%" >}}
在第一阶段中,我们将CLIP的双塔用已有的预训练模型进行初始化,分别是CLIP的视觉侧(如ViT-B、ResNet等)以及中文RoBERTa RoBERTA-wwm-Chinese。我们冻结图像塔,通过对比学习让文本塔的输出表示和图像塔的一致。在第二阶段中,我们解冻图像塔,进行对比学习继续训练,从而图像塔也能学习建模中文领域的图像数据分布。
在可复现性方面,我们尽可能采用公开数据集,其中包括LAION-5B[^3]的中文部分、悟空数据集[^4]、来自VG和MSCOCO等的翻译数据。总数据量大约2亿。
我们推出了5个规模的中文CLIP模型,其中包括ResNet-50、ViT-B/16、ViT-L/14、ViT-L/14@336px和ViT-H/14。具体数据详见下表。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/model_variants.jpg#center" width="80%" >}}
实验
我们做了3个跨模态检索的实验,其中包括中文原生的MUGE和英文原生的Flickr30K-CN和COCO-CN。在所有数据集上,中文CLIP都取得了最好的效果,而尤其在MUGE上中文CLIP相比此前模型的优势最为巨大。这也反映中文CLIP在中文原生数据集上能够取得更好的表现。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/muge.jpg#center" width="80%" >}}
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/flickr.jpg#center" width="80%" >}}
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/coco.jpg#center" width="80%" >}}
我们也尝试了中文CLIP的零样本分类能力,并在ELEVATER[^5]上做了测试,具体实现包括翻译标签和提示词。实验结果也反映中文CLIP在英文原生的基准上同样能取得有竞争力的表现。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/elevater.jpg#center" width="80%" >}}
我们补充了实验说明两阶段训练方法的有效性。对比从头训练,不管是收敛效率还是最终迁移效果上,两阶段的方法都取得更好的效果,并且对比单纯的一阶段联合训练,第二阶段预训练的加入还能进一步提升效果。这也意味着当我们打造一个语言特定的中文CLIP其实不需要从头来,可以在已有模型的基础上站得更高。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/cnclip/ablation.jpg#center" title="Ablation studies." >}}
局限性及未来工作
尽管上文介绍了中文CLIP的强大之处,但我们仍需要认识到当前中文CLIP还没有充分验证其作为视觉基础模型的作用。经验上,它应当在中文原生数据上表现更好。因此,在下一阶段的工作中,我们将研究构造一个针对中文多模态表示学习和视觉表示学习的基准。
欢迎大家访问我们的GitHub存储库和ModelScope模型库,并使用我们的代码和模型。希望能够帮助到你们的研究和应用!
[^1]: Radford, A., Kim, J.W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., Krueger, G., & Sutskever, I. (2021).
Learning Transferable Visual Models From Natural Language Supervision.
International Conference on Machine Learning.
[^2]: Carlsson, F., Eisen, P., Rekathati, F., & Sahlgren, M. (2022).
Cross-lingual and Multilingual CLIP.
International Conference on Language Resources and Evaluation.
[^3]: Schuhmann, C., Beaumont, R., Vencu, R., Gordon, C., Wightman, R., Cherti, M., Coombes, T., Katta, A., Mullis, C., Wortsman, M., Schramowski, P., Kundurthy, S., Crowson, K., Schmidt, L., Kaczmarczyk, R., & Jitsev, J. (2022).
LAION-5B: An open large-scale dataset for training next generation image-text models.
arXiv, abs/2210.08402.
[^4]: Gu, J., Meng, X., Lu, G., Hou, L., Niu, M., Xu, H., Liang, X., Zhang, W., Jiang, X., & Xu, C. (2022).
Wukong: 100 Million Large-scale Chinese Cross-modal Pre-training Dataset and A Foundation Framework.
arXiv, abs/2202.06767.
[^5]: Li, C., Liu, H., Li, L., Zhang, P., Aneja, J., Yang, J., Jin, P., Lee, Y.J., Hu, H., Liu, Z., & Gao, J. (2022).
ELEVATER: A Benchmark and Toolkit for Evaluating Language-Augmented Visual Models.
arXiv, abs/2204.08790.
File: content/blog/codeqwen1.5/index.md
title: "Code with CodeQwen1.5"
date: 2024-04-16T13:33:00+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
draft: true
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: true
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "path"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
{{< button href="https://github.com/QwenLM/CodeQwen1.5" label="GITHUB" external=true >}}
{{< button href="https://huggingface.co/Qwen" label="HUGGING FACE" external=true >}}
{{< button href="https://modelscope.cn/organization/qwen" label="MODELSCOPE" external=true >}}
{{< button href="https://huggingface.co/spaces/Qwen/CodeQwen1.5-7b-Chat-demo" label="DEMO" external=true >}}
{{< button href="https://discord.gg/yPEP2vHTu4" label="DISCORD" external=true >}}
Introduction
The advent of advanced programming tools, which harnesses the power of large language models (LLMs), has significantly enhanced programmer productivity and accuracy. Notwithstanding these advancements, dominant coding assistants like Github Copilot, built upon proprietary LLMs, pose notable challenges in terms of cost, privacy, security, and potential copyright infringement. Recognizing the imperative for a more transparent and accessible alternative, the open-source community has embarked on a concerted endeavor to develop open codeLLMs. This initiative has already given rise to several promising open-source models, including StarCoder2, CodeLlama, and DeepSeek-Coder, offering a path forward, albeit one that necessitates continued refinement.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/intro.png#center" width="100%">}}

Today, we are delighted to introduce a new member of the Qwen1.5 open-source family, the CodeQwen1.5-7B, a specialized codeLLM built upon the Qwen1.5 language model. CodeQwen1.5-7B has been pretrained with around 3 trillion tokens of code-related data. It supports an extensive repertoire of 92 programming languages, and it exhibits exceptional capacity in long-context understanding and generation with the ability to process information of 64K tokens. In terms of performance, CodeQwen1.5 demonstrates impressive capabilities in basic code generation, long-context modeliing, code editation and SQL. We believe this model can significantly enhance developer productivity and streamline software development workflows within diverse technological environments.
CodeQwen is a Basic Coder
Code generation is a key competence for large language models, as they are tasked with translating natural language instructions into executable code with unwavering precision. CodeQwen1.5, with only 7 billion parameters, has surpassed larger models in basic code generation capabilities, further narrowing the gap in coding proficiency between GPT-4 and opensource code LLMs. We conducted a thorough evaluation on HumanEval and MBPP to provide a clear and fair comparison as follows.
| Model | Size | HumanEval
0-shot | HumanEval+
0-shot | MBPP
0-shot | MBPP+
0-shot | MBPP
3-shot |
| --- | --- | --- | --- | --- | --- | --- |
| Base Model | | | | | | |
| CodeLlama-Base | 7B | 33.5 | 25.6 | 52.1 | 41.6 | 38.6 |
| StarCoder2 | 7B | 35.4 | 29.9 | 54.4 | 45.6 | 51.0 |
| DeepSeek-Coder-Base | 6.7B | 47.6 | 39.6 | 70.2 | 56.6 | 60.6 |
| CodeQwen1.5 | 7B | 51.8 | 45.7 | 72.2 | 60.2 | 61.8 |
| Chat Model | | | | | | |
| GPT-3.5-Turbo | - | 76.8 | 70.7 | 82.5 | 69.7 | 70.8 |
| GPT-4-Turbo (Nov 2023) | - | 85.4 | 81.7 | 83.5 | 70.7 | 80.0 |
| DeepSeek-Coder-Instruct | 6.7B | 78.6 | 70.1 | 73.2 | 63.4 | 65.4 |
| CodeQwen1.5-Chat | 7B | 83.5 | 78.7 | 77.7 | 67.2 | 70.6 |
In addition to the widely recognized HumanEval and MBPP benchmarks, we explored LiveCodeBench. This benchmark assesses code performance by introducing fresh challenges sourced from coding competitions such as LeetCode, AtCoder, and CodeForces over time. Our evaluation of CodeQwen1.5 on LiveCodeBench spanned from September 1, 2023, to April 1, 2024. The findings indicate that CodeQwen1.5 ranks among the top open-access models currently available. Note: it is possible that the inclusion of LeetCode data in our pretraining corpus may contribute to the performance in LiveCodeBench.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/livecode.png#center" width="75%">}}

The evaluations mentioned primarily revolve around Python capabilities; however, CodeQwen1.5 is not merely a Python specialist but also an expert across multiple programming languages. We conducted a comprehensive evaluation of CodeQwen1.5 in the eight mainstream languages featured in MultiPL-E, including Python, C++, Java, PHP, TypeScript, C#, Bash, and JavaScript. The results highlight the exceptional programming capabilities of CodeQwen1.5.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/radar-vertical.png#center" width="40%">}}

CodeQwen is a Long Context Coder
Long context capability is crucial for code LLMs, serving as the core skill for understanding repository-level code and becoming a code agent. However, current code models still have very limited support for length, which hinders their potential for practical application. CodeQwen1.5 aims to further advance the progress of open-source code models in long context modeling. To achieve this, we have collected and constructed long sequence code data at the repository level for pre-training. Through careful data proportioning and organization, we have enabled it to support input lengths of up to 64K tokens.
Evaluation 1: We collected high-quality repo from GitHub Trending repositories on 2024-3-28 that were not included in CodeQwen1.5's training data to observe the effectiveness of long context modeling. The following figure demonstrates that as the sequence length increases, CodeQwen1.5's Perplexity (PPL) still manages to maintain a downward trend.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/longcontext-ppl.png#center" width="90%">}}

Evaluation 2: We created a synthetic task called Needle in the Code, inspired by popular long-context evaluations in the text domain. In this task, we inserted a very simple custom function at various positions within a longer codebase (we chose Megatron to honor its contributions to open-source LLMs!) and tested whether the model could replicate this function at the end of the codebase. The figure below shows that CodeQwen is capable of successfully completing this task within a 64k length range.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/longcontext-needle.png#center" width="90%">}}

Both Evaluation 1 and Evaluation 2 serve as initial and foundational assessments. For the Chat model, we aim to evaluate its long context capabilities with more practical tasks. However, our objective is to examine the Chat model's capability to handle long contexts through more pragmatic, real-world evaluation tasks.
Evaluation 3: SWE Bench is a benchmark designed to assess the ability of Large Language Models (LLMs) or agents to tackle practical software development challenges. It presents contestants with a code repository and an associated issue, tasking them with generating a commit patch that resolves the issue effectively. The benchmark uniquely emphasizes the long-context processing capabilities of code LLMs, necessitating both deep comprehension of the given codebase and the generation of extensive, unit-test-passing code.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/swe-bench.png#center" width="95%">}}

Currently, participants in the SWE Bench competition predominantly are proprietary models. We introduce CodeQwen1.5 as an open-source model entry. Despite achieving a score of 0.89, CodeQwen1.5 surpasses ChatGPT-3.5, demonstrating the nascent yet promising competitiveness of open-source code models against their proprietary counterparts.
CodeQwen is a Debugger
An effective code assistant must demonstrate proficiency in both generating code in response to given specifications and adeptly modifying or debugging existing code to accommodate evolving requirements or rectify errors. In assessing CodeQwen1.5's proficiency in code modification tasks, we concentrated our evaluation on the CodeEditorBench suite, encompassing four distinct dimensions: Debugging, Translation, Language Switching, and Code Polishing. The results indicate that CodeQwen1.5 achieves the SOTA performance at the 7 billion parameter scale.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/codeedit.jpeg#center" width="90%">}}

CodeQwen is a SQLer
CodeQwen1.5 serves as a solution to bridge the gap between non-programming professionals and efficient data interaction. It alleviates the steep learning curve associated with SQL by enabling users without coding expertise to query databases through natural language. We evaluated CodeQwen1.5-Chat's performance on two popular Text-to-SQL benchmarks, Spider and Bird. Experimental results pose CodeQwen1.5 a second position close to GPT-4 (results come from DIN-SQL, a SOTA prompting method). This outstanding performance is attributed to the utilization of synthetic data throughout both pre-training and fine-tuning stages. Synthetic data, characterized by its scalability, verifiability, and variety, emerges as a compelling area for future research due to its proven effectiveness in enhancing CodeQwen1.5's SQL capabilities.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/sql-score.png#center" width="90%">}}

Develop with CodeQwen1.5
CodeQwen1.5 is part of the Qwen1.5 open-source family. We advise you to read our blog for Qwen1.5 to figure out the usages with Transformers, vLLM, llama.cpp, Ollama, etc.
Conclusion
We have released CodeQwen1.5-7B and CodeQwen1.5-7B-Chat, an open and versatile code LLM. The models are intended to aid progress in code assistance and code agents, benefiting the research community. We'll keep investing heavily in smart code development, with the ultimate goal of creating AI programmers.
Citation
@misc{codeqwen1.5,
    title = {Code with CodeQwen1.5},
    url = {https://qwenlm.github.io/blog/codeqwen1.5/},
    author = {Qwen Team},
    month = {April},
    year = {2024}
}
File: content/blog/codeqwen1.5/index.zh.md
title: "与 CodeQwen1.5 结对编程"
date: 2024-04-16T13:33:00+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
draft: false
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: true
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "path"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
{{< button href="https://github.com/QwenLM/CodeQwen1.5" label="GITHUB" external=true >}}
{{< button href="https://huggingface.co/Qwen" label="HUGGING FACE" external=true >}}
{{< button href="https://modelscope.cn/organization/qwen" label="MODELSCOPE" external=true >}}
{{< button href="https://huggingface.co/spaces/Qwen/CodeQwen1.5-7b-Chat-demo" label="DEMO" external=true >}}
{{< button href="https://discord.gg/yPEP2vHTu4" label="DISCORD" external=true >}}
简介
代码助手,是一种基于 LLMs 的智能化的编程工具,它可以帮助程序员更高效、更准确的编写代码,使得整个软件开发过程更加流畅和高效。然而流行的代码助手,比如 Github Copilot,依赖于闭源的商业模型,不仅昂贵还会引起如隐私、安全、版权等方面的担忧。幸运的是,开源社区正在致力于打造开放代码模型来实现开放的代码助手。近期涌现出了一批优秀的 Open CodeLLMs,比如 StarCoder2、CodeLlama、DeepSeek-Coder 等,提供了一条新的路径,但仍然值得探索。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/intro.png#center" width="100%">}}
今天,我们非常激动地和大家介绍来自 Qwen1.5 开源家族的新成员,一个代码专家模型 CodeQwen1.5! CodeQwen1.5 基于 Qwen 语言模型初始化,拥有 7B 参数的模型,其拥有 GQA 架构,经过了 ~3T tokens 代码相关的数据进行预训练,共计支持 92 种编程语言、且最长支持 64K 的上下文输入。效果方面,CodeQwen1.5 展现出了非凡的代码生成、长序列建模、代码修改、SQL 能力等,该模型可以大大提高开发人员的工作效率,并在不同的技术环境中简化软件开发工作流程。
CodeQwen 是基础的 Coder
代码生成是大语言模型的关键能力之一,期待模型将自然语言指令转换为具有精确的、可执行的代码。仅拥有 70 亿参数的 CodeQwen1.5 在基础代码生成能力上已经超过了更尺寸的模型,进一步缩小了开源代码 LLM 和 GPT-4 之间的编码能力差距。我们对 HumanEval 和 MBPP 进行了评估,下面是具体的比较。
| Model | Size | HumanEval
0-shot | HumanEval+
0-shot | MBPP
0-shot | MBPP+
0-shot | MBPP
3-shot |
| --- | --- | --- | --- | --- | --- | --- |
| Base Model | | | | | | |
| CodeLlama-Base | 7B | 33.5 | 25.6 | 52.1 | 41.6 | 38.6 |
| StarCoder2 | 7B | 35.4 | 29.9 | 54.4 | 45.6 | 51.0 |
| DeepSeek-Coder-Base | 6.7B | 47.6 | 39.6 | 70.2 | 56.6 | 60.6 |
| CodeQwen1.5 | 7B | 51.8 | 45.7 | 72.2 | 60.2 | 61.8 |
| Chat Model | | | | | | |
| GPT-3.5-Turbo | - | 76.8 | 70.7 | 82.5 | 69.7 | 70.8 |
| GPT-4-Turbo (Nov 2023) | - | 85.4 | 81.7 | 83.5 | 70.7 | 80.0 |
| DeepSeek-Coder-Instruct | 6.7B | 78.6 | 70.1 | 73.2 | 63.4 | 65.4 |
| CodeQwen1.5-Chat | 7B | 83.5 | 78.7 | 77.7 | 67.2 | 70.6 |
除了流行的 Humaneval 与 MBPP 外,我们还注意到了 LiveCodeBench,一个对 LLM 代码能力进行更全面、随着时间动态更新的评估。LiveCodeBench 不断地从 LeetCode、AtCoder 和 CodeForces 三个竞赛平台中收集问题来测试模型的泛化能力。我们选择在 LiveCodeBench (2023-09-01->2024-04-01)上对 CodeQwen1.5 进行评估,结果展示出了 CodeQwen1.5 极具竞争力的效果。但值得注意的是,在预训练语料中包含的 LeetCode 数据可能对该评测有帮助。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/livecode.png#center" width="75%">}}
上述的评估主要围绕 Python 能力,但 CodeQwen1.5 不仅仅是 Python 专家,还是一个多编程语言专家。我们在 MultiPL-E 的 8 种主流语言(Python、C++、Java、PHP、TypeScript、C#、Bash,JavaScript)上对 CodeQwen1.5 进行全面评估。这些结果证明了 CodeQwen1.5 强大的编程能力。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/radar-vertical.png#center" width="40%">}}
CodeQwen 是长序列 Coder
长序列能力对于代码模型来说至关重要,是理解仓库级别代码、成为 Code Agent 的核心能力。而当前的代码模型对于长度的支持仍然非常有限,阻碍了其实际应用的潜力。CodeQwen1.5 希望进一步推进开源代码模型在长序列建模上的进展,我们收集并构造了仓库级别的长序列代码数据进行预训练,通过精细的数据配比和组织方式,使其最终可以最长支持 64K 的输入长度。
评估一:我们选择了不在 CodeQwen1.5 训练数据、最新产生的高质量 github 仓库 (来自 2024-3-28 的 Github Trending 仓库),来观测其长序列建模的有效性。下图可以发现在序列不断增长的情况下, CodeQwen1.5 的 PPL 仍然可以保持下降的趋势。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/longcontext-ppl.png#center" width="90%">}}
评估二:一个名为 Needle in the Code 的合成任务, 其效仿文本领域流行的长序列评测。我们在一个较长的代码库(我们选择了 Megatron,向其对开源 LLMs 的贡献致敬)的不同位置中插入非常简单的一个自定义函数,测试模型能否在代码库最后重复这个函数。下图可以发现,CodeQwen 能够在 64k 长度范围内仍然可以很好的完成这个任务。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/longcontext-needle.png#center" width="90%">}}
无论是评估一还是评估二,都是初步的、基础的评估方式,仅仅是一个起点而非全部。但是,对于 Chat 模型,我们希望用更实际的任务来评估其长序列能力。
评估三:SWE Bench 的目的是解决真实软件开发中的问题,给定一个代码仓库和 issue,期待 LLMs/Agents 能够给出相应的 commit patch 来解决这个 issue。SWE Bench 对 Code LLMs 的长序列能力提出了更高的要求,不仅需要理解代码仓库,还要生成可通过单测的代码。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/swe-bench.png#center" width="95%">}}
目前 SWEBench 竞技场上的玩家都依赖闭源模型,我们让 CodeQwen1.5 首次入局,尽管仅有 0.89 的分数但仍强于 ChatGPT3.5,这展示了开源代码模型与专有模型的竞争力尽管尚处于初期,但具有潜力。
CodeQwen 是优秀的代码修改者
一个好的代码助手不仅可以根据指令生成代码,还能够针对已有代码或者新的需求进行修改或错误修复。为此,我们评估了 CodeQwen1.5 在代码修改方面的能力。我们首先在关注 CodeEditorBench,涉及到 Debug、Translate、Switch、Polish 等四个方面的代码修改能力,结果表明 CodeQwen1.5 在 7B 规模上达到了最好的效果。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/codeedit.jpeg#center" width="90%">}}
CodeQwen 是出色的 SQL 专家
CodeQwen1.5 可以作为一个智能的 SQL 专家,弥合了非编程专业人士与高效数据交互之间的差距。它通过自然语言使无编程专业知识的用户能够查询数据库,从而缓解了与SQL相关的陡峭学习曲线。我们在两个流行的文本到SQL基准测试Spider和Bird上评估了CodeQwen1.5-Chat的性能。实验结果显示,CodeQwen1.5在接近GPT-4的位置排名第二(结果来自DIN-SQL,一种 SOTA 的提示方法)。这一出色的表现得益于在预训练和微调阶段均广泛利用了合成数据。合成数据具有可扩展性、可验证性和多样性的特点,在增强CodeQwen1.5的SQL能力方面已被证明是一项具有吸引力的未来研究领域。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/codeqwen1.5/sql-score.png#center" width="90%">}}
部署 CodeQwen1.5
CodeQwen1.5 隶属 Qwen1.5 开源家族,我们推荐您阅读我们的 Qwen1.5 文档来了解具体的使用方式,目前已支持 Transformers, vLLM, llama.cpp, Ollama, 等等。
结论
我们发布了 CodeQwen1.5-7B 及 CodeQwen1.5-7B-Chat,一个开放的、多面体的 Code LLM,我们希望这个模型能在 Code 助手、Code Agent 等方面为社区贡献。未来我们仍然会积极的投入代码智能建设,实现真正的 AI 程序员。
引用
@misc{codeqwen1.5,
    title = {Code with CodeQwen1.5},
    url = {https://qwenlm.github.io/blog/codeqwen1.5/},
    author = {Qwen Team},
    month = {April},
    year = {2024}
}
File: content/blog/global-load-balance/index.md
title: "Global-batch load balance almost free lunch to improve your MoE LLM training"
date: 2025-01-21T00:00:03+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
draft: true
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: true
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "path"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/main_results.png#center" width="100%">}}

{{< button href="https://github.com/QwenLM/Qwen2-Math" label="GITHUB" external=true >}}
{{< button href="https://huggingface.co/collections/Qwen/qwen25-math-66eaa240a1b7d5ee65f1da3e" label="HUGGING FACE" external=true >}}
{{< button href="https://modelscope.cn/organization/qwen" label="MODELSCOPE" external=true >}}
{{< button href="https://discord.gg/yPEP2vHTu4" label="DISCORD" external=true >}}
Background
The Mixture-of-Experts (MoEs) architecture has become a popular model-parameter-scale-up technique. Typically, one MoE layer consists of a router (often parameterized as one single Linear layer) and a group of experts (for transformer-based models, each expert is one feedforward layer). Given an input, only a subset of experts will be activated, and then their outputs will be aggregated based on the scores the router assigned. Specifically,
$$
\mathbb{y}=\sum_{i\in N_E,g_i\in\operatorname{topK}}g_i(\mathbb{x})E_i(\mathbb{x})
$$
Load Balancing loss
Load balancing loss is an essential regularization technique in training MoE-based networks, and high-level intuition encourages the balanced activation of all experts. It can be calculated as:
$$
L_{\text{balance}}=N_E \sum_{i=1}^{N_E} f_ip_i
$$
where $f_i$ is the activation frequency of the expert $E_i$, and the $p_i$ is the the average gating score that the expert $E_i$ is assigned.
However, most existing MoE training frameworks (e.g., Megatron-core), implement micro-batch level balance, which means the $L_{\text{balance}}$ is calculated within every micro-batch and is then averaged on the global batch level.
Our key point is that this implementation could be problematic if one micro-batch does not contain diverse data. For instance, imagine one micro-batch only contains some code data; the aforementioned load-balancing loss still pushes the router to distribute these code tokens to all experts uniformly, potentially hurting the model performance and preventing expert specialization.
This situation is even more common in training MoE-based LLMs: the data in one micro-batch is often from the same domain. This partially explains why most existing open-source MoE-based LLMs do not achieve notable expert specialization.
This drawback motivates us to extend the current method to the global-batch level balance.
From micro-batch balance to global-batch balance
One easy way to calculate global-batch balance loss is to 1) Synchronize expert selection frequency $f_i$ across all parallel groups; 2) Calculate the load-balancing loss in each parallel group (e.g., one GPU); 3) Aggregate the loss across all micro-batches.
Specifically,
$$
L_{\text{global}}=N_E\sum_{i=1}^{N_E}f_i^{\text{global}}p_i^{\text{global}}=N_E\sum_{i=1}^{n_E}f_i^{\text{global}}\cdot(\frac{1}{N_p}\sum_{j=1}^{N_p}p_j)= \frac{1}{N_P} \sum_{j=1}^{N_p}(N_E \sum_{i=1}^{N_E} \bar{f_i} \cdot P^j_i)
$$
Note that the expert selection frequency is just one expert-num-dimentional vector! It is almost free to synchronize them across micro-batches.
Results: More Performant and Interpretable MoE
We experiment with three MoE configs (3.4B with 0.6B activated, 15B with 2.54B activated, and 43B with 6.6B activated) and two data configs (120B tokens and 400B tokens). The results are shown in the following figure and chart.
In short, compared to the micro-batch-level loss, the global batch one achieves better performance in all settings (model, data, and tasks). More importantly, the MoE model achieves significant domain specialization with the global batch balance. In Figure (b) left, almost all experts are uniformly activated regardless of the domain. But in Figure (b) right, some experts are frequently activated by a specific domain, demonstrating their specialization.
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/table_results.png#center" width="90%">}}

We further compare the model performance with balance batch size on a 3.4B with 0.6B activated model. The ptr-training PPL decreases rapidly from balance BSZ 2 to 128, and gradually saturates after 128. In the current mainstream MoE framework, even with cross expert-parallel groups communication, the balance BSZ is generally between 8 and 16 for larger models, which further reflects the significance of our method.
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/different_balance_BSZ.png#center" width="70%">}}

Using global batch balance may result in a degradation in micro-batch balance, potentially affecting the computational efficiency of MoE. We further experimented with the effect of adding micro-batch balance loss on top of the global-batch balance loss (with constant weights of 0.01 of the global batch loss). It can be seen that adding local equalization improves the speed of the model (from 1.64 to 1.59 seconds per update step) while the effectiveness of the model is almost unaffected.
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/efficiency.png#center" width="70%">}}

Conclusion
In summary, we investigate the challenges associated with the LBL in training MoEs models. By introducing global-batch balance loss, we achieve improved performance and foster expert specialization within the MoE model. We believe this advancement addresses an essential limitation in existing MoE training, offering a novel perspective for MoEs model optimization.
Though mainly experimenting with language-based tasks, we hope our work could pave the way for training more substantial and specialised MoE models in various domains.
Citation
If you find our work helpful, feel free to give us a citation.
@article{qiu2025demonsdetailimplementingload,
  title={Demons in the Detail: On Implementing Load Balancing Loss for Training Specialized Mixture-of-Expert Models},
  author={
    Zihan Qiu and Zeyu Huang and Bo Zheng and Kaiyue Wen and Zekun Wang and Rui Men and Ivan Titov and Dayiheng Liu and Jingren Zhou and Junyang Lin
  },
  journal={arXiv preprint arXiv:2501.11873},
  year={2025}
}
File: content/blog/global-load-balance/index.zh.md
title: "通过全局负载均衡提升混合专家模型的性能和特异化程度"
date: 2025-01-21T00:00:03+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
draft: true
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: true
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "path"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/main_results.png#center" width="100%">}}
{{< button href="https://github.com/QwenLM/Qwen2-Math" label="GITHUB" external=true >}}
{{< button href="https://huggingface.co/collections/Qwen/qwen25-math-66eaa240a1b7d5ee65f1da3e" label="HUGGING FACE" external=true >}}
{{< button href="https://modelscope.cn/organization/qwen" label="MODELSCOPE" external=true >}}
{{< button href="https://discord.gg/yPEP2vHTu4" label="DISCORD" external=true >}}
**引言**
混合专家模型(MoEs)通过路由机制动态并稀疏地激活模型参数,使得能高效地增大模型参数规模。基于 TopK 机制的稀疏激活会在训练中会遇到专家激活不均衡的问题:少数被频繁选择的专家会被优化得更多,进一步使得这些专家被更频繁地选择,最终导致只选择少数专家,造成剩余专家的冗余。因此,MoE 在训练中需要引入额外的辅助损失(load balance loss,LBL)来鼓励专家的选择趋于均衡。
目前主流 MoE 训练框架中 LBL 实现其实是局部的负载均衡,这使得模型需要将局部的输入都均匀分配给不同的专家。然而,局部的输入往往只来自个别领域,局部负载均衡会让模型将所有领域的输入都均匀分配。这种均匀分配会阻碍某些专家更多处理特定领域的数据,也即阻碍专家出现领域层次的分化特征。我们发现,将局部的负载均衡放松到全局的负载均衡,能显著增强专家的特异化并提高模型性能。
从局部均衡到全局均衡
LBL 的计算公式为 $N_E \sum_{i=1}^{N_E} f_ip_i$ ,其中 $N_E$ 为专家数, $f_i$ 为专家 i 被选择的频率, $p_i$ 为路由赋予专家 i 的平均分数。目前 Megatron-mcore 等主流框架中的 LBL 都是在每一张卡上统计计算后再全局平均,这使得 $f_i$ 也是在局部统计,而优化 LBL 也鼓励模型将每个局部的输入都均匀分配给所有的专家。这也解释了为什么目前大部分 MoE 工作没有观察到领域层面的专家分化。
得益于 LBL 计算的格式,我们可以通过通信不同节点的 $f_i$ 来将局部的 LBL 转化为全局的 LBL。因为 $f_i$ 只是一个专家数大小的向量,即使是在全局通信的情况下也不会带来明显的开销。此外由于 LBL 的计算与模型其它部分的计算相对独立,还可以用计算掩盖等策略进一步消除同步 $f_i$ 的通信开销。
扩大均衡的范围带来稳定的提升
我们在三种参数规模(3.4B 激活 0.6B, 15B 激活 2.54B,43B 激活 6.6B)下分别训练了 120B 和 400B tokens,对比了不同的均衡范围(Balance BSZ)对模型性能的影响。所有模型都使用了细粒度专家、共享专家及 dropless 策略(专家不会抛弃超过容量的tokens)。可以看到,将均衡范围从一般框架实现的 4,8 或者 16 增大到 128 以上后模型在 Benchmark 指标和 PPL 都有明显提升。
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/table_results.png#center" width="90%">}}
我们在 3.4B 激活 0.6B 的模型训练 400B tokens 到设置上进一步对比了模型效果随着均衡范围的变化,可以看到 balance BSZ 从 2 到 128 模型的 PPL 在快速降低,在 128 后逐渐饱和。目前主流 MoE 框架中即使是进行了机内通信,对于较大的模型 balance BSZ 也一般在 8 到 16 的,这进一步体现了我们通信方法的意义。
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/different_balance_BSZ.png#center" width="70%">}}
添加少量局部均衡损失能提高模型效率
只使用全局均衡会导致局部均衡状况有所降低,这会一定程度影响 MoE 的计算效率。我们进一步实验了在主要使用全局均衡的情况下,在训练过程中添加局部均衡(默认实现的 LBL,损失权重为全局 LBL 的 1%)限制对于模型性能和效率的影响。可以看到,添加局部均衡能提升模型的速度(每个更新步耗时从 1.64秒提升到1.59秒),同时模型的效果也几乎不受影响。
{{< figure src="https://qianwen-res.oss-cn-beijing.aliyuncs.com/assets/balance/efficiency.png#center" width="70%">}}
结论
我们回顾了目前 MoE 训练框架中均衡损失,发现目前的实现方式会将所有来自相同领域的局部输入都均匀分配,限制了专家的分化。通过轻量的通信将局部均衡放松为全局均衡,MoE 模型的性能和专家特异性都得到了显著的提升。我们认为这一进展解决了现有MoE训练中的一个关键问题,为MoE模型的优化提供了新的视角,并有助于构建更加可解释的模型。尽管我们的实验主要集中在基于语言的任务上,我们希望我们的工作能够为在不同领域训练更大规模、更有效的 MoE 模型提供帮助。
引用
如果你觉得我们的工作有用,欢迎引用!
@article{qiu2025demonsdetailimplementingload,
  title={Demons in the Detail: On Implementing Load Balancing Loss for Training Specialized Mixture-of-Expert Models},
  author={
    Zihan Qiu and Zeyu Huang and Bo Zheng and Kaiyue Wen and Zekun Wang and Rui Men and Ivan Titov and Dayiheng Liu and Jingren Zhou and Junyang Lin
  },
  journal={arXiv preprint arXiv:2501.11873},
  year={2025}
}
File: content/blog/gspo/index.md
title: "GSPO: Towards Scalable Reinforcement Learning for Language Models"
date: 2025-07-27T15:00:00+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
draft: true
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: true
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "path"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
{{< button href="https://huggingface.co/papers/2507.18071" label="PAPER" external=true >}}
{{< button href="https://discord.gg/yPEP2vHTu4" label="DISCORD" external=true >}}
Introduction
Reinforcement Learning (RL) has emerged as a pivotal paradigm for scaling language models and enhancing their deep reasoning and problem-solving capabilities. To scale RL, the foremost prerequisite is maintaining stable and robust training dynamics. However, we observe that existing RL algorithms (such as GRPO) exhibit severe instability issues during long training and lead to irreversible model collapse, hindering further performance improvements with increased compute.
To enable successful RL scaling, we propose the Group Sequence Policy Optimization (GSPO) algorithm. Unlike previous RL algorithms, GSPO defines the importance ratio based on sequence likelihood and performs sequence-level clipping, rewarding, and optimization. Compared to GRPO, GSPO demonstrates remarkable advantages in the following aspects:
- Performant and Efficient: GSPO possesses significantly higher training efficiency and can achieve continuous performance improvements through increasing training compute;
- Notably Stable: GSPO maintains stable training processes and inherently resolves the stability challenges in the RL training of large Mixture-of-Experts (MoE) models;
- Infrastructure-Friendly: Due to sequence-level optimization, GSPO is fundamentally more tolerant to precision discrepancies, offering attractive potential for simplifying RL infrastructure.
These merits have contributed to the exceptional performance of the latest Qwen3 models (Instruct, Coder, Thinking).
Sequence-Level Optimization Objective
Let $x$ be a query, $\pi_{\theta_\mathrm{old}}$ be the old policy that generates responses, $\{y_i\}_{i=1}^G$ be the sampled response group, $\widehat{A}_{i}$ be the group relative advantage of each response, and $\pi_\theta$ be the current policy to be optimized. GSPO adopts the following optimization objective:
{{< rawhtml >}}
$$
\mathcal{J}\text{GSPO} (\theta)
=,
\mathbb{E}{ x \sim \mathcal{D},, {y_i}{i=1}^G \sim \pi{\theta_\mathrm{old}}( \cdot | x) }
\left[
\frac{1}{G} \sum_{i=1}^{G}
\min \left( s_{i}(\theta) \widehat{A}{i}, , \mathrm{clip} \left( s{i}(\theta), 1 - {\varepsilon}, 1 + {\varepsilon} \right) \widehat{A}_{i} \right)
\right],
$$
{{< /rawhtml >}}
where
{{< rawhtml >}} $$ s_{i}(\theta)
\left( \frac{ \pi_{\theta} (y_i | x) }{ \pi_{\theta_\text{old}} (y_i | x)} \right)^{\frac{1}{|y_i|}}
\exp \left( \frac{1}{|y_i|} \sum_{t=1}^{|y_i|} \log \frac{ \pi_{\theta} (y_{i,t} | x, y_{i,<t}) }{ \pi_{\theta_\text{old}} (y_{i,t} | x,y_{i,<t})} \right).
$$
{{< /rawhtml >}}
Here, $s_i(\theta)$ is the importance ratio defined based on sequence likelihood in GSPO, where we perform length normalization to reduce variance and unify the numerical range of $s_i(\theta)$.
Training Efficiency and Performance
We experiment with a cold-start model fine-tuned from Qwen3-30B-A3B-Base and report its training reward curves as well as performance curves on the AIME'24, LiveCodeBench, and CodeForces benchmarks. We compare against GRPO as the baseline. Note that GRPO necessitates the Routing Replay training strategy for the normal convergence of MoE RL (which we will discuss later), while GSPO has obviated the need for this strategy.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/results.jpg#center" title="Experimental results">}}
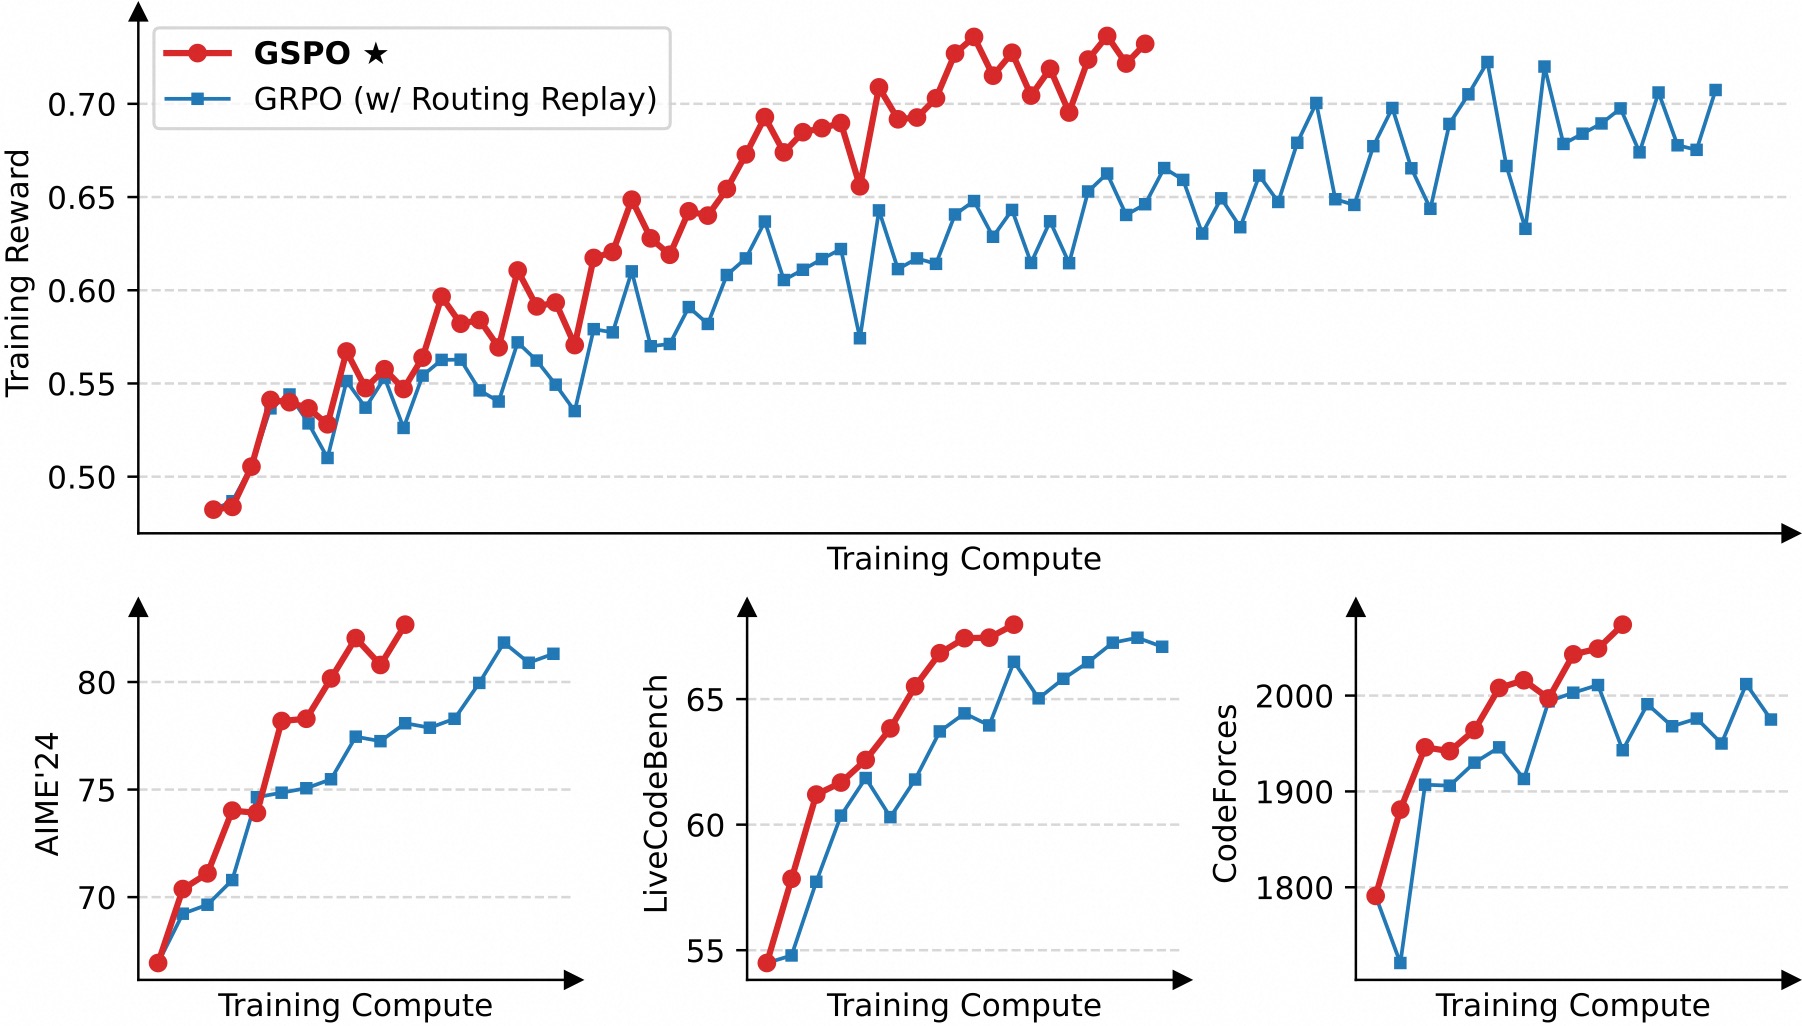
As shown in the figure above, GSPO demonstrates significantly higher training efficiency than GRPO, achieving better performance under the same training cost. Particularly, we observe that GSPO can deliver continuous performance improvement through increasing the training compute, regularly updating the query set, and extending the generation length — this is exactly the scalability we expect from an algorithm. Ultimately, we successfully applied GSPO to the large-scale RL training of the latest Qwen3 models, further unleashing the potential of RL scaling!
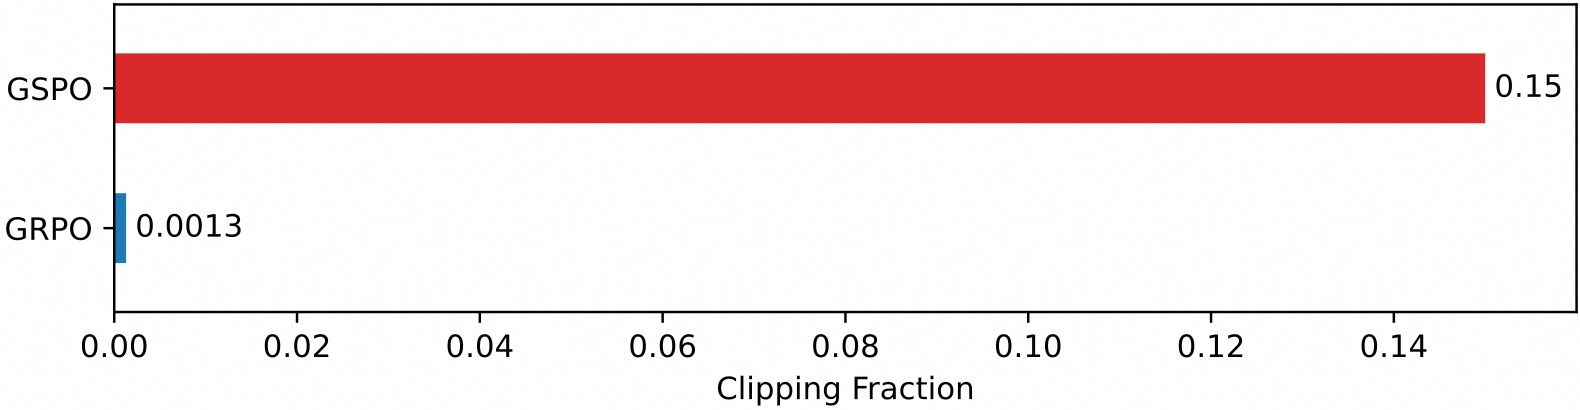
An interesting observation is that the fraction of tokens clipped in GSPO is two orders of magnitude higher than that in GRPO (as shown in the figure below), while GSPO still achieves higher training efficiency. This further demonstrates that GRPO's token-level optimization objective is noisy and inefficient, while GSPO's sequence-level approach provides a more reliable and effective learning signal.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/clipping.jpg" title="Fractions of clipped tokens">}}
Benefits for MoE RL and Infrastructure
We found that when adopting the GRPO algorithm, the expert activation volatility of MoE models prevents RL training from converging properly. To address this challenge, we previously employed the Routing Replay training strategy, which caches the activated experts in $\pi_{\theta_\text{old}}$ and "replays" these routing patterns in $\pi_\theta$ when computing importance ratios. As shown in the figure below, Routing Replay is crucial for normal convergence of GRPO training on MoE models. However, the Routing Replay strategy incurs additional memory and communication overhead and may limit the actual capacity of MoE models.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/routing_replay.jpg" title="Effect of Routing Replay in the GRPO training of MoE models">}}
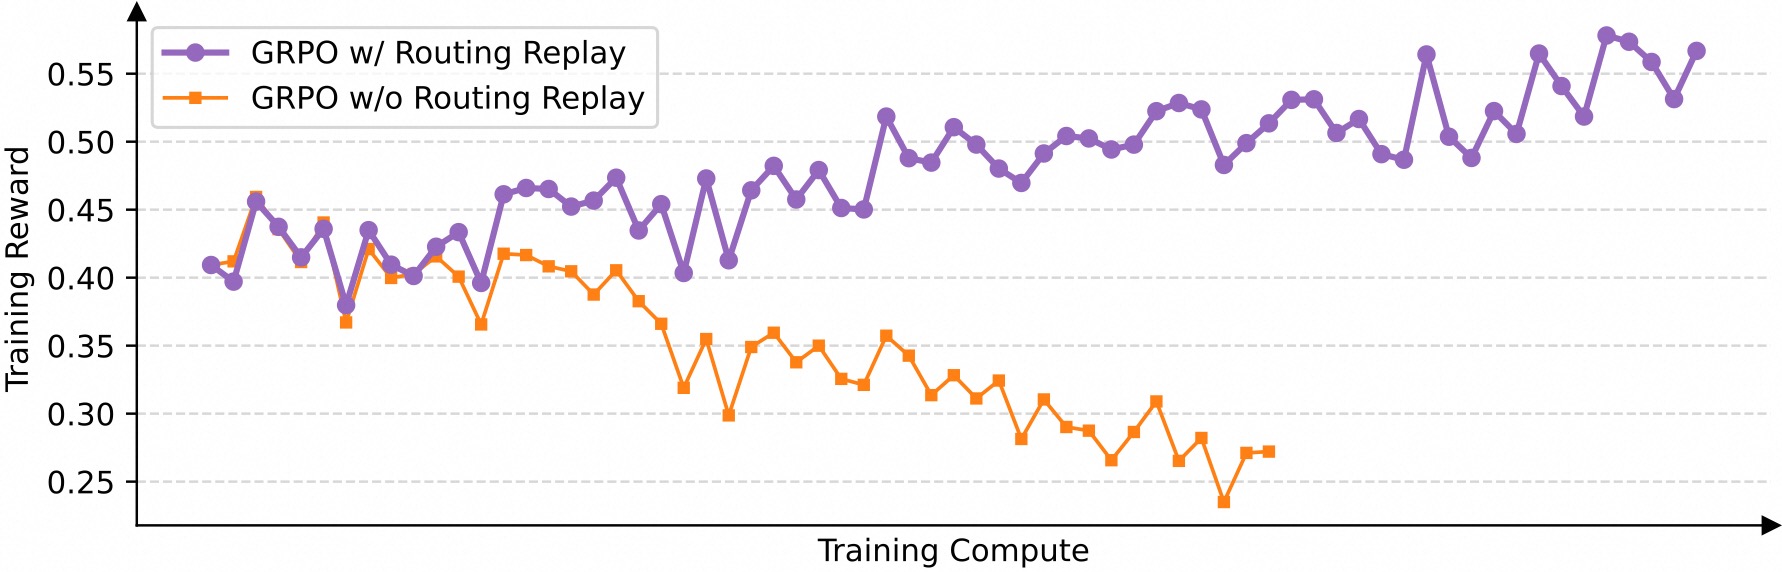
The notable advantage of GSPO lies in completely eliminating the dependency on Routing Replay. The key insight is that GSPO only focuses on sequence-level likelihood (i.e., $\pi_\theta(y_i|x)$) and is not sensitive to individual token likelihood (i.e., $\pi_\theta(y_{i,t}|x,y_{i,<t})$). Therefore, it does not require infrastructure-heavy workarounds like Routing Replay, both simplifying and stabilizing the training process while allowing models to maximize their capacity.
Additionally, since GSPO uses only sequence-level rather than token-level likelihoods for optimization, intuitively the former is much more tolerant of precision discrepancies. Therefore, GSPO makes it possible to directly use likelihoods returned by inference engines for optimization, eliminating the need for recomputation with training engines. This is particularly beneficial in scenarios such as partial rollout, multi-turn RL, and training-inference disaggregated frameworks.
Conclusion
We propose Group Sequence Policy Optimization (GSPO), a new RL algorithm for training language models. GSPO demonstrates notably superior training stability, efficiency, and performance compared to GRPO and exhibits particular efficacy for the large-scale RL training of MoE models, laying the foundation for the exceptional improvements in the latest Qwen3 models. With GSPO as our algorithmic cornerstone, we will continue to push the boundaries of RL scaling and look forward to the resulting fundamental advances in intelligence.
Citation
If you find our work helpful, feel free to give us a citation.
@article{gspo,
  title={Group Sequence Policy Optimization},
  author={
    Chujie Zheng and Shixuan Liu and Mingze Li and Xiong-Hui Chen and Bowen Yu and
    Chang Gao and Kai Dang and Yuqiong Liu and Rui Men and An Yang and Jingren Zhou and
    Junyang Lin
  },
  journal={arXiv preprint arXiv:2507.18071},
  year={2025}
}
File: content/blog/gspo/index.zh.md
title: "GSPO:迈向持续拓展的语言模型强化学习"
date: 2025-07-27T15:00:00+08:00
weight: 1
aliases: ["/first"]
tags: ["Research"]
draft: true
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: true
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "path"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
relative: true # To use relative path for cover image, used in hugo Page-bundles
responsive_images: true
hidden: false
header:
background: "" # background css value
background_image: ""
gradient: false
blur: false
{{< button href="https://huggingface.co/papers/2507.18071" label="PAPER" external=true >}}
{{< button href="https://discord.gg/yPEP2vHTu4" label="DISCORD" external=true >}}
引言
强化学习 (Reinforcement Learning,RL)已成为拓展语言模型、增强其深度推理与问题求解能力的关键技术范式。为了持续拓展 RL,首要前提是确保稳定、鲁棒的训练过程。然而,我们观察到现有的 RL 算法(如 GRPO)在长期训练中会暴露出严重的不稳定性问题并招致不可逆转的模型崩溃,阻碍了通过增加计算以获得进一步的性能提升。
为了能够持续拓展 RL,我们提出了 Group Sequence Policy Optimization (GSPO) 算法。不同于过去的 RL 算法,GSPO 定义了序列级别的重要性比率,并在序列层面执行裁剪、奖励和优化。相较于 GRPO,GSPO 在以下方面展现出突出优势:
- 强大高效:GSPO 具备显著更高的训练效率,并且能够通过增加计算获得持续的性能提升;
- 稳定性出色:GSPO 能够保持稳定的训练过程,并且根本地解决了混合专家(Mixture-of-Experts,MoE)模型的 RL 训练稳定性问题;
- 基础设施友好:由于在序列层面执行优化,GSPO 原则上对精度容忍度更高,具有简化 RL 基础设施的诱人前景。
以上优点促成了最新的 Qwen3 模型(Instruct、Coder、Thinking)的卓越性能。
序列级别的优化目标
设 $x$ 为查询,$\pi_{\theta_\mathrm{old}}$ 为用于采样回复的策略,$\{y_i\}_{i=1}^G$ 为采样得到的回复组,$\widehat{A}_{i}$ 为各个回复的组内相对优势,$\pi_\theta$ 为需优化的当前策略。GSPO 采用以下优化目标:
{{< rawhtml >}} $$ \mathcal{J}_\text{GSPO} (\theta)
\mathbb{E}{ x \sim \mathcal{D},, {y_i}{i=1}^G \sim \pi_{\theta_\text{old}}( \cdot | x) }
\left[
\frac{1}{G} \sum_{i=1}^{G}
\min \left( s_{i}(\theta) \widehat{A}{i}, , \mathrm{clip} \left( s{i}(\theta), 1 - {\varepsilon}, 1 + {\varepsilon} \right) \widehat{A}_{i} \right)
\right],
$$
{{< /rawhtml >}}
其中
{{< rawhtml >}} $$ s_{i}(\theta)
\left( \frac{ \pi_{\theta} (y_i | x) }{ \pi_{\theta_\text{old}} (y_i | x)} \right)^{\frac{1}{|y_i|}}
\exp \left( \frac{1}{|y_i|} \sum_{t=1}^{|y_i|} \log \frac{ \pi_{\theta} (y_{i,t} | x, y_{i,<t}) }{ \pi_{\theta_\text{old}} (y_{i,t} | x,y_{i,<t})} \right).
$$
{{< /rawhtml >}}
这里的 $s_i(\theta)$ 即为 GSPO 基于序列似然定义的重要性比率,其中我们进行了长度归一化以降低方差并统一 $s_i(\theta)$ 的数值范围。
训练效率与性能
我们使用基于 Qwen3-30B-A3B-Base 微调得到的冷启动模型进行实验,并汇报其训练奖励曲线以及在 AIME'24、LiveCodeBench 和 CodeForces 等基准上的性能曲线。我们对比 GRPO 作为基线。注意 GRPO 必需采用 Routing Replay 训练策略才能正常收敛(我们将在后文讨论),而 GSPO 则无需该策略。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/results.jpg#center" title="实验结果">}}
从上图可见,GSPO 表现出比 GRPO 显著更高的训练效率,即在同等计算开销下能够取得更优的性能。特别地,我们观察到 GSPO 可以通过增加算力来获得持续的性能提升——这正是我们所期待的算法的可拓展性。最终,我们成功地将 GSPO 应用于最新的 Qwen3 模型的大规模 RL 训练,进一步释放了 RL scaling 的潜能!
一个有趣的观察是,GSPO 所裁剪的 token 比例比 GRPO 要高上两个数量级(如下图所示),但却具有更高的训练效率。这进一步表明 GRPO 采用的 token 级别的优化目标是有噪和低效的,而 GSPO 的序列级别的优化目标则提供了更可靠、有效的学习信号。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/clipping.jpg#center" title="被裁剪的 token 比例">}}
对 MoE RL 和基础设施的收益
我们发现,当采用 GRPO 算法时,MoE 模型的专家激活波动性会使得 RL 训练无法正常收敛。为了解决这一挑战,我们过去采用了**路由回放(Routing Replay)**训练策略,即缓存 $\pi_{\theta_\text{old}}$ 中激活的专家,并在计算重要性比率时在 $\pi_\theta$ 中“回放”这些路由模式。从下图可见,Routing Replay 对于 GRPO 训练 MoE 模型的正常收敛至关重要。然而,Routing Replay 的做法会产生额外的内存和通信开销,并可能限制 MoE 模型的实际可用容量。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/routing_replay.jpg#center" title="Routing Replay 对 MoE 模型的 GRPO 训练的作用">}}
GSPO 的一大突出优势在于彻底消除了对 Routing Replay 的依赖。其核心洞见在于:GSPO 仅关注序列级别的似然(即 $\pi_\theta(y_i|x)$),而对个别 token 的似然(即 $\pi_\theta(y_{i,t}|x,y_{i,<t})$)不敏感。因此,其无需 Routing Replay 等对基础设施负担较大的手段,既简化和稳定了训练过程,又使得模型能够最大化地发挥容量与潜能。
此外,鉴于 GSPO 仅使用序列级别而非 token 级别的似然进行优化,直观上前者对精度差异的容忍度要高得多。因此,GSPO 使得直接使用推理引擎返回的似然进行优化成为可能,从而无需使用训练引擎进行重计算,这在 partial rollout、多轮 RL 以及训推分离框架等场景中特别有益。
结论
我们提出了 Group Sequence Policy Optimization (GSPO),这是用于训练语言模型的全新 RL 算法。相较于 GRPO,GSPO 在训练稳定性、效率和性能方面展现出显著优势,并在 MoE 模型的大规模 RL 训练中表现出突出的功效。这些优点为最新 Qwen3 模型的卓越性能奠定了算法基础。以 GSPO 作为算法基石,我们将持续推动 RL scaling 的边界,并期待由此带来的智能进步。
引用
如果你觉得我们的工作有用,欢迎引用!
@article{gspo,
  title={Group Sequence Policy Optimization},
  author={
    Chujie Zheng and Shixuan Liu and Mingze Li and Xiong-Hui Chen and Bowen Yu and
    Chang Gao and Kai Dang and Yuqiong Liu and Rui Men and An Yang and Jingren Zhou and
    Junyang Lin
  },
  journal={arXiv preprint arXiv:2507.18071},
  year={2025}
}
File: content/blog/ofa/index.md
title: "OFA: Towards Building a One-For-All Model"
date: 2022-11-14T16:01:41+08:00
weight: 2
aliases: ["/first"]
tags: ["Research"]
author: ["Junyang Lin", "Binyuan Hui"]
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: false
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "ofa_banner.jpg"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
hidden: true
relative: true # To use relative path for cover image, used in hugo Page-bundles
edit_post:
url: "https://github.com//content"
text: "Suggest Changes" # edit text
append_file_path: true # to append file path to Edit link
{{< video src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/demo.mp4" autoplay=true loop=true class="gallery" >}}
2022 is a year of generalist models! With the bloom of multimodal pretraining, especially the unified model, we have witnessed the opportunity to building a generalist model that is capable of processing tasks of different modalities or multi-modalities! Thus, we propose OFA[^1], namely One-For-All, a unified multimodal pretrained model that unifies understanding and generation tasks concerning modalities into a single framework, and we pretrain OFA with the instruction-based multitask-pretraining that endows it with multiple capabilities. We opensourced both the pretrained and finetuned models to the community, hoping this pioneer work can help accelerate the development of generalist models.
{{< button href="https://arxiv.org/abs/2202.03052" label="Paper" external=true >}}
{{< button href="https://github.com/OFA-Sys/OFA" label="Github" external=true >}}
{{< button href="https://www.modelscope.cn/models?name=ofa" label="ModelScope" external=true >}}
{{< button href="https://huggingface.co/spaces/OFA-Sys/OFA-Generic_Interface" label="Demo" external=true >}}
Background
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/uniter.jpg#center" width="80%" >}}

Multimodal pretraining has been developing rapidly ever since the transfer of BERT[^bert] to cross-modal representation learning. Representative studies include UNITER[^2], VilBERT[^3], etc. These studies directly incorporate the Transformer-based BERT[^bert] to a single-stream or dual stream framework for multimodal pretraining, and transform the image to a sequence of object features to be concatenated with the word embeddings as the input of Transformer. Later in 2021, with the rise of Vision Transformer[^5], there came methods that got rid of object-level features, which depend on complex preprocessing pipelines, say Faster-RCNN[^6]: For example, the simplest ViLT[^7] based on patch projection, the CLIP-based[^8] CLIP-ViL[^9], etc. One milestone after should be the proposal of SimVLM[^10], which leverages the T5/BART method for multimodal pretraining and achieves new SoTA in many tasks. These progress should be regarded as the foundation of unified multimodal pretrained models in 2022, including OFA of ours, Unified-IO[^11], Flamingo[^12], BeiT-3[^13], etc.
Method
What OFA wants to achieve is the unification of tasks, modalities, and architecture. We suppose there are three features for a unified model, i.e., task agnostic, modality agnostic, and task comprehensiveness. To further explain them, "task agnostic" indicates that the unified model should be able to accept tasks without modifying its own architecture and training methods, "modality agnostic" indicates that a unified model should accept inputs of different modalities without knowing what they are and designing complex preprocessing, and "task comprehensiveness" indicates that the unified model should learn as many tasks as possible so that it can transfer to unseen tasks with the composition of existing capabilities. Thus, we propose 3 types of unification for OFA, namely the unification of modalities, architecture, and tasks. Let's figure them out one by one.
For the unification of modalities, one key issue is the tokenization of inputs of different modalities, or to say, the discretization. Otherwise, there should be other solutions like diffusion models[^14] for the generation. There is no need to change the tokenization for texts, but the images and bounding boxes need to be discretized. Owing to the success of vector quantization[^15][^16] and text-to-image generation with Transformer[^17][^18], images can be represented with VQ tokens. Inspired by pix2seq[^19], bounding boxes can also be discretized with bins.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/io.jpg#center" width="80%" >}}

We choose the universal Transformer encoder-decoder architecture, due to its successful usages in NLP unified models like T5[^20]. Note that for the input of images to the Transformer, we use the first three blocks of ResNet. For the Transformer architecture, we modify the design by incorporating Normformer[^21] for the training stability and transfer performance.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/arc.jpg#center" width="80%" >}}

The multitask learning is the key innovation of OFA. Specifically, we pretrain the model with 8 tasks, including 5 vision-language tasks, 2 vision tasks, and 1 language task. The vision-language tasks include visual grounding, grounded captioning, visual question answering, image-text matching, and image captioning. The vision tasks include detection and image infilling. The language task is text infilling. To help the model differentiate tasks, we insert an instruction, which is simply a piece of text describing the task. Thus, we expect the model to perform zero-shot generation based on a new instruction indicating an unseen task.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/task.jpg#center" width="80%" >}}

To make this research as reproducible as possible, our pretraining is dependent on public datasets. Therefore, we expect the researchers following this work can reproduce our results with our opensourced code.
We have released OFA models of 5 sizes, including OFA-Tiny (33M), OFA-Medium (93M), OFA-Base (180M), OFA-Large(470M), OFA-Huge (930M). See the table below for more statistics.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/variants.jpg#center" width="80%" >}}

Experiments
We have conducted experiments on multiple cross-modal tasks and unimodal tasks. On vision-language understanding, we test the models on VQA and SNLI-VE. We find that the huge-size model can achieve a comparable performance to the 80B-parameter model Flamingo and the 2B-parameter model CoCa pretrained on 5B image-text pairs. Furthermore, we achieve the best performance on visual entailment. For vision-language generation, we focus on the classical image captioning, and our OFA achieves the SoTA performance in both setups of cross-entropy optimization and CIDEr optimization. Also, we have transformed the task of visual grounding to a generation task, and we find that even the base-size OFA can outperform the previous SoTA, and the scaling of model size consistently brings performance improvements. This shows the significance of the unification of modalities and tasks.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/vqa.jpg#center" width="60%" >}}

{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/caption.jpg#center" width="80%" >}}

{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/vg.jpg#center" width="80%" >}}

Additionally, we test OFA on text-to-image generation, as we believe that the image infilling task in pretraining endows it with the capability to generate image codes. We show that OFA can achieve a low FID score in the evaluation, and further finetuning on a larger dataset can significantly boost its performance. See cases below.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/t2i.jpg#center" width="80%" >}}

{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/t2i_cases.jpg#center" width="80%" >}}

As to the unimodal tasks, we evaluate OFA on the GLUE benchmark for NLU, Gigaword summarization for NLG, and ImageNet classification for vision understanding. We show that OFA can be competitive with both RoBERTa and DeBERTa, and the previous multimodal pretrained model often falls far behind the SoTAs in NLU. Similarly, OFA can achieve good performance on NLG and outperform the previous best models. As to image classification, it can also achieve similar performance with the self-supervised vision models like BeiT[^22] and MAE[^23].
We observe that OFA based on multitask pretraining demonstrates potential in transferring to unseen tasks and unseen domains. We show them with two cases below.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/unseen_task.jpg#center" width="80%" >}}

The preceding case demonstrates the model's ability of compositional generalization by understanding the instruction and leveraging two learned capabilities to perform the new task. We set up a new task called Grounded VQA, which is a combination of VQA and grounded captioning. What we need to change is the instruction. The new task instruction with both question and region information directs the model to provide a correct answer.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/unseen_domain.jpg#center" width="80%" >}}

Also, we find that OFA can transfer to unseen domains effectively. One example is the visual grounding on images of animation. OFA can perform well in this setup as it has been pretrained on some anime data and it has been pretrained on visual grounding on general-domain data. This again shows the compositional ability of the unified model.
Conclusion
This is the starting point of our research for the technically "One-For-All" model, or to say, the generalist model. We show that this research direction is promising as Transformer is a really powerful architecture and tasks and modalities can be unified to a single training framework. Like GPT-3[^24], we believe that there will soon be a powerful foundation model in multimodal representation learning.
[^1]: Wang, P., Yang, A., Men, R., Lin, J., Bai, S., Li, Z., Ma, J., Zhou, C., Zhou, J., & Yang, H. (2022).
Unifying Architectures, Tasks, and Modalities Through a Simple Sequence-to-Sequence Learning Framework.
International Conference on Machine Learning.
[^2]: Chen, Y., Li, L., Yu, L., Kholy, A.E., Ahmed, F., Gan, Z., Cheng, Y., & Liu, J. (2019).
UNITER: UNiversal Image-TExt Representation Learning.
European Conference on Computer Vision.
[^3]: Lu, J., Batra, D., Parikh, D., & Lee, S. (2019).
ViLBERT: Pretraining Task-Agnostic Visiolinguistic Representations for Vision-and-Language Tasks.
Neural Information Processing Systems.
[^bert]: Devlin, J., Chang, M., Lee, K., & Toutanova, K. (2019).
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding.
arXiv, abs/1810.04805.
[^5]: Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., Uszkoreit, J., & Houlsby, N. (2020).
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale.
arXiv, abs/2010.11929.
[^6]: Ren, S., He, K., Girshick, R.B., & Sun, J. (2015).
Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks.
IEEE Transactions on Pattern Analysis and Machine Intelligence, 39, 1137-1149.
[^7]: Kim, W., Son, B., & Kim, I. (2021).
ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision.
International Conference on Machine Learning.
[^8]: Radford, A., Kim, J.W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., Krueger, G., & Sutskever, I. (2021).
Learning Transferable Visual Models From Natural Language Supervision.
International Conference on Machine Learning.
[^9]: Shen, S., Li, L.H., Tan, H., Bansal, M., Rohrbach, A., Chang, K., Yao, Z., & Keutzer, K. (2021).
How Much Can CLIP Benefit Vision-and-Language Tasks?
arXiv, abs/2107.06383.
[^10]: Wang, Z., Yu, J., Yu, A.W., Dai, Z., Tsvetkov, Y., & Cao, Y. (2021).
SimVLM: Simple Visual Language Model Pretraining with Weak Supervision.
arXiv, abs/2108.10904.
[^11]: Lu, J., Clark, C., Zellers, R., Mottaghi, R., & Kembhavi, A. (2022).
Unified-IO: A Unified Model for Vision, Language, and Multi-Modal Tasks.
arXiv, abs/2206.08916.
[^12]: Alayrac, J., Donahue, J., Luc, P., Miech, A., Barr, I., Hasson, Y., Lenc, K., Mensch, A., Millican, K., Reynolds, M., Ring, R., Rutherford, E., Cabi, S., Han, T., Gong, Z., Samangooei, S., Monteiro, M., Menick, J., Borgeaud, S., Brock, A., Nematzadeh, A., Sharifzadeh, S., Binkowski, M., Barreira, R., Vinyals, O., Zisserman, A., & Simonyan, K. (2022).
Flamingo: a Visual Language Model for Few-Shot Learning.
arXiv, abs/2204.14198.
[^13]: Wang, W., Bao, H., Dong, L., Bjorck, J., Peng, Z., Liu, Q., Aggarwal, K., Mohammed, O., Singhal, S., Som, S., & Wei, F. (2022).
Image as a Foreign Language: BEiT Pretraining for All Vision and Vision-Language Tasks.
arXiv, abs/2208.10442.
[^14]: Ho, J., Jain, A., & Abbeel, P. (2020).
Denoising Diffusion Probabilistic Models.
arXiv, abs/2006.11239.
[^15]: Razavi, A., Oord, A.V., & Vinyals, O. (2019).
Generating Diverse High-Fidelity Images with VQ-VAE-2.
arXiv, abs/1906.00446.
[^16]: Esser, P., Rombach, R., & Ommer, B. (2020).
Taming Transformers for High-Resolution Image Synthesis.
2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 12868-12878.
[^17]: Ramesh, A., Pavlov, M., Goh, G., Gray, S., Voss, C., Radford, A., Chen, M., & Sutskever, I. (2021).
Zero-Shot Text-to-Image Generation.
arXiv, abs/2102.12092.
[^18]: Ding, M., Yang, Z., Hong, W., Zheng, W., Zhou, C., Yin, D., Lin, J., Zou, X., Shao, Z., Yang, H., & Tang, J. (2021).
CogView: Mastering Text-to-Image Generation via Transformers.
Neural Information Processing Systems.
[^19]: Chen, T., Saxena, S., Li, L., Fleet, D.J., & Hinton, G.R. (2021).
Pix2seq: A Language Modeling Framework for Object Detection.
arXiv, abs/2109.10852.
[^20]: Raffel, C., Shazeer, N.M., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P.J. (2019).
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer.
arXiv, abs/1910.10683.
[^21]: Shleifer, S., Weston, J., & Ott, M. (2021).
NormFormer: Improved Transformer Pretraining with Extra Normalization.
arXiv, abs/2110.09456.
[^22]: Bao, H., Dong, L., & Wei, F. (2021).
BEiT: BERT Pre-Training of Image Transformers.
arXiv, abs/2106.08254.
[^23]: He, K., Chen, X., Xie, S., Li, Y., Doll'ar, P., & Girshick, R.B. (2021).
Masked Autoencoders Are Scalable Vision Learners.
2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 15979-15988.
[^24]: Brown, T.B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., Agarwal, S., Herbert-Voss, A., Krueger, G., Henighan, T.J., Child, R., Ramesh, A., Ziegler, D.M., Wu, J., Winter, C., Hesse, C., Chen, M., Sigler, E., Litwin, M., Gray, S., Chess, B., Clark, J., Berner, C., McCandlish, S., Radford, A., Sutskever, I., & Amodei, D. (2020).
Language Models are Few-Shot Learners.
arXiv, abs/2005.14165.
File: content/blog/ofa/index.zh.md
title: "OFA:走向通用统一模型"
date: 2022-11-14T16:01:41+08:00
weight: 2
aliases: ["/first"]
tags: ["Research"]
author: ["Junyang Lin", "Binyuan Hui"]
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: false
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
lang: zh-CN
cover:
image: "ofa_banner.jpg"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
hidden: true
relative: true # To use relative path for cover image, used in hugo Page-bundles
edit_post:
url: "https://github.com//content"
text: "Suggest Changes" # edit text
append_file_path: true # to append file path to Edit link
{{< video src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/demo.mp4" autoplay=true loop=true class="gallery" >}}
2022年可以说是属于通用模型的一年!随着多模态预训练的蓬勃发展,尤其是通用模型,我们看到实现一个具有处理多种模态的多种任务的能力的通用模型的机会。因此我们提出OFA[^1],即One-For-All。它是一个统一的多模态预训练模型,以统一的模型架构和任务形式兼容多模态和单模态的理解与生成任务。我们使用多模态多任务的方式预训练OFA,使其成为一个接近全能的模型。我们将OFA的模型和代码全部开源到社区,希望能推动通用模型的发展。
{{< button href="https://arxiv.org/abs/2202.03052" label="论文" external=true >}}
{{< button href="https://github.com/OFA-Sys/OFA" label="GitHub" external=true >}}
{{< button href="https://www.modelscope.cn/models?name=ofa" label="ModelScope" external=true >}}
{{< button href="https://huggingface.co/spaces/OFA-Sys/OFA-Generic_Interface" label="体验" external=true >}}
背景
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/uniter.jpg#center" width="80%" >}}
自BERT[^bert]成功迁移到多模态领域,多模态预训练蓬勃发展,代表性的工作包括UNITER[^2]、VilBERT[^3]等。这些工作将基于Transformer的BERT[^bert]结合到单流或双流的架构中,并将图像处理成物体特征接入Transformer中。而到了2021年,随着ViT[^5]的兴起,越来越多放弃物体特征的工作出现,不再依赖复杂的如Faster-RCNN[^6]的流程,比如最简单的使用patch映射ViLT[^7]、使用CLIP[^8]的CLIP-ViL[^9],等等。而SimVLM[^10]作为这个领域一个代表工作,利用了T5/BART的特性将理解和生成任务兼容并实现多项最优表现。这些进展都奠定了通用统一模型的发展基础,2022年涌现了一批工作,包括我们的OFA、Unified-IO[^11]、Flamingo[^12]、BeiT-3[^13]等。
方法
OFA希望实现的是任务、模态和架构的统一。我们提出统一模型应当具备三大特性,即任务无关、模态无关和任务全面性。任务无关即统一模型应当能接受多种任务形式而无需针对性做模型结构和训练方法的改变,模态无关即不需针对模态做特定模型结构和训练方法修改,任务全面性即模型应当尽可能学习多的任务从而让自己能力更全面更能融会贯通迁移到没学习过的新任务上。因此我们提出了三大统一,即模态、架构和任务的统一。下面我们逐一解释。
统一模态最大的难题是不同模态的离散化表示,不然我们就需要使用diffusion模型[^14]来解决问题。文本表示无需改动,主要的变化在于图像和物体框。得益于近年来vector quantization的快速发展[^15][^16]以及基于Transformer的文本生成图像模型[^17][^18],图像可以用VQ token来进行表示。而针对物体框,则可以采用分桶的方式对连续的坐标值实现离散化。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/io.jpg#center" width="80%" >}}
模型架构上我们选择的是基于Transformer的编码-解码器。它已经在NLP领域取得巨大成功,如T5[^20]。而对于图像输入,我们使用ResNet的前3个stage。而对于Transformer,我们加入Normformer[^21]的方法提升模型训练稳定性和最终迁移效果。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/arc.jpg#center" width="80%" >}}
多任务学习是OFA的一大特点。我们使用了8个任务做预训练,其中包括5个图文任务、2个视觉任务和1个自然语言任务。图文任务包括视觉定位、定位物体描述、视觉问答、图文匹配和图像描述,视觉任务包括目标检测和图像还原,语言任务则是文本还原。为了让模型识别不同任务,我们为每个任务增加相应的文本提示,说明任务的内容。我们希望模型遇到新的提示能实现零样本学习。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/task.jpg#center" width="80%" >}}
我们使用了公开数据集进行预训练。我们希望研究人员能够利用我们的开源复现相应的结果。
我们一共开源了5个规模的模型,分别是OFA-Tiny (33M),OFA-Medium (93M),OFA-Base (180M),OFA-Large(470M)和OFA-Huge (930M)。具体数据查看下表。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/variants.jpg#center" width="80%" >}}
实验
我们在多模态和单模态任务上都做了实验。在视觉-语言理解上,我们在视觉问答和视觉推理上做了实验。在VQA上,OFA的效果和800亿参数的Flamingo以及基于50亿图文数据训练的20亿参数的CoCa效果相当,并且在视觉推理上取得最优成绩。而在视觉-语言生成上,OFA在两个阶段的图像描述评测均取得最优效果。而在视觉定位任务上,base规模的模型就可以超出此前最好的模型,也反映了生成式的方法和多任务训练的有效性,并且随着规模的增加,模型效果也能实现稳定增长。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/vqa.jpg#center" width="60%" >}}
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/caption.jpg#center" width="80%" >}}
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/vg.jpg#center" width="80%" >}}
此外,我们还在文本图像生成任务上做了测试,因为预训练中我们设计了图像还原任务,模型应当具备一定的图像生成能力。可以看到OFA可以达到非常低的FID分数,并且在更大的数据上微调能明显提升它的生成效果。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/t2i.jpg#center" width="80%" >}}
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/t2i_cases.jpg#center" width="80%" >}}
单模态方面,我们在GLUE上验证OFA的自然语言理解能力,Gigaword上验证自然语言生成能力,以及ImageNet上验证视觉理解能力。可以看到OFA在GLUE上可以取得匹敌RoBERTa和DeBERTa的效果,而此前的多模态模型距离最优的自然语言模型差距都很大。在摘要生成上,OFA也取得最优效果。而视觉分类上,OFA也能取得匹敌BeiT[^22]和MAE[^23]的效果。
另外,我们观察到OFA具备一定的新任务和新领域的迁移能力。如下图所示。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/unseen_task.jpg#center" width="80%" >}}
这个例子说明OFA对提示的理解和组合多项技能的能力。我们设计了一个基于定位的视觉问答的任务,相当于视觉问答和定位描述的组合。具体实现方式就是修改任务的提示。包含了问题和定位信息的提示引导模型做出了正确的回答。
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofa/unseen_domain.jpg#center" width="80%" >}}
另外,OFA迁移到新领域的能力也比较不错。在动画领域数据的定位上,模型能实现较为精准的物体定位。这是因为模型学过这个任务而预训练又见过该领域数据。这也体现了模型的组合能力。
总结
这是我们通用统一模型研究工作的起点。我们认为这个方向很有前景,因为Transformer有着一统天下的趋势,同时它能很好地兼容多种模态和任务。我们相信,多模态领域很快也会迎来属于它的GPT-3[^24]!
[^1]: Wang, P., Yang, A., Men, R., Lin, J., Bai, S., Li, Z., Ma, J., Zhou, C., Zhou, J., & Yang, H. (2022).
Unifying Architectures, Tasks, and Modalities Through a Simple Sequence-to-Sequence Learning Framework.
International Conference on Machine Learning.
[^2]: Chen, Y., Li, L., Yu, L., Kholy, A.E., Ahmed, F., Gan, Z., Cheng, Y., & Liu, J. (2019).
UNITER: UNiversal Image-TExt Representation Learning.
European Conference on Computer Vision.
[^3]: Lu, J., Batra, D., Parikh, D., & Lee, S. (2019).
ViLBERT: Pretraining Task-Agnostic Visiolinguistic Representations for Vision-and-Language Tasks.
Neural Information Processing Systems.
[^bert]: Devlin, J., Chang, M., Lee, K., & Toutanova, K. (2019).
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding.
arXiv, abs/1810.04805.
[^5]: Dosovitskiy, A., Beyer, L., Kolesnikov, A., Weissenborn, D., Zhai, X., Unterthiner, T., Dehghani, M., Minderer, M., Heigold, G., Gelly, S., Uszkoreit, J., & Houlsby, N. (2020).
An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale.
arXiv, abs/2010.11929.
[^6]: Ren, S., He, K., Girshick, R.B., & Sun, J. (2015).
Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks.
IEEE Transactions on Pattern Analysis and Machine Intelligence, 39, 1137-1149.
[^7]: Kim, W., Son, B., & Kim, I. (2021).
ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision.
International Conference on Machine Learning.
[^8]: Radford, A., Kim, J.W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., Krueger, G., & Sutskever, I. (2021).
Learning Transferable Visual Models From Natural Language Supervision.
International Conference on Machine Learning.
[^9]: Shen, S., Li, L.H., Tan, H., Bansal, M., Rohrbach, A., Chang, K., Yao, Z., & Keutzer, K. (2021).
How Much Can CLIP Benefit Vision-and-Language Tasks?
arXiv, abs/2107.06383.
[^10]: Wang, Z., Yu, J., Yu, A.W., Dai, Z., Tsvetkov, Y., & Cao, Y. (2021).
SimVLM: Simple Visual Language Model Pretraining with Weak Supervision.
arXiv, abs/2108.10904.
[^11]: Lu, J., Clark, C., Zellers, R., Mottaghi, R., & Kembhavi, A. (2022).
Unified-IO: A Unified Model for Vision, Language, and Multi-Modal Tasks.
arXiv, abs/2206.08916.
[^12]: Alayrac, J., Donahue, J., Luc, P., Miech, A., Barr, I., Hasson, Y., Lenc, K., Mensch, A., Millican, K., Reynolds, M., Ring, R., Rutherford, E., Cabi, S., Han, T., Gong, Z., Samangooei, S., Monteiro, M., Menick, J., Borgeaud, S., Brock, A., Nematzadeh, A., Sharifzadeh, S., Binkowski, M., Barreira, R., Vinyals, O., Zisserman, A., & Simonyan, K. (2022).
Flamingo: a Visual Language Model for Few-Shot Learning.
arXiv, abs/2204.14198.
[^13]: Wang, W., Bao, H., Dong, L., Bjorck, J., Peng, Z., Liu, Q., Aggarwal, K., Mohammed, O., Singhal, S., Som, S., & Wei, F. (2022).
Image as a Foreign Language: BEiT Pretraining for All Vision and Vision-Language Tasks.
arXiv, abs/2208.10442.
[^14]: Ho, J., Jain, A., & Abbeel, P. (2020).
Denoising Diffusion Probabilistic Models.
arXiv, abs/2006.11239.
[^15]: Razavi, A., Oord, A.V., & Vinyals, O. (2019).
Generating Diverse High-Fidelity Images with VQ-VAE-2.
arXiv, abs/1906.00446.
[^16]: Esser, P., Rombach, R., & Ommer, B. (2020).
Taming Transformers for High-Resolution Image Synthesis.
2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 12868-12878.
[^17]: Ramesh, A., Pavlov, M., Goh, G., Gray, S., Voss, C., Radford, A., Chen, M., & Sutskever, I. (2021).
Zero-Shot Text-to-Image Generation.
arXiv, abs/2102.12092.
[^18]: Ding, M., Yang, Z., Hong, W., Zheng, W., Zhou, C., Yin, D., Lin, J., Zou, X., Shao, Z., Yang, H., & Tang, J. (2021).
CogView: Mastering Text-to-Image Generation via Transformers.
Neural Information Processing Systems.
[^19]: Chen, T., Saxena, S., Li, L., Fleet, D.J., & Hinton, G.R. (2021).
Pix2seq: A Language Modeling Framework for Object Detection.
arXiv, abs/2109.10852.
[^20]: Raffel, C., Shazeer, N.M., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P.J. (2019).
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer.
arXiv, abs/1910.10683.
[^21]: Shleifer, S., Weston, J., & Ott, M. (2021).
NormFormer: Improved Transformer Pretraining with Extra Normalization.
arXiv, abs/2110.09456.
[^22]: Bao, H., Dong, L., & Wei, F. (2021).
BEiT: BERT Pre-Training of Image Transformers.
arXiv, abs/2106.08254.
[^23]: He, K., Chen, X., Xie, S., Li, Y., Doll'ar, P., & Girshick, R.B. (2021).
Masked Autoencoders Are Scalable Vision Learners.
2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 15979-15988.
[^24]: Brown, T.B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., Agarwal, S., Herbert-Voss, A., Krueger, G., Henighan, T.J., Child, R., Ramesh, A., Ziegler, D.M., Wu, J., Winter, C., Hesse, C., Chen, M., Sigler, E., Litwin, M., Gray, S., Chess, B., Clark, J., Berner, C., McCandlish, S., Radford, A., Sutskever, I., & Amodei, D. (2020).
Language Models are Few-Shot Learners.
arXiv, abs/2005.14165.
File: content/blog/ofasys/index.md
title: "OFASys: Enabling Multitask Learning with One Line of Code! "
date: 2022-12-28T18:01:21+08:00
weight: 2
aliases: ["/first"]
tags: ["Research"]
author: ["Junyang Lin", "Binyuan Hui"]
comments: false
disable_share: false
hide_meta: false
hide_summary: false # to hide summary in list
hide_footer: false
math: false
search_hidden: false # to hide from search page
show_reading_time: true
show_bread_crumbs: true
show_post_nav_links: false # the prev/next after the content
show_code_copy_buttons: true
show_word_count: true
use_hugo_toc: true
show_toc: true
toc_open: true # default expand all
cover:
image: "ofa_banner.jpg"
# can also paste direct link from external site
# ex. https://i.ibb.co/K0HVPBd/paper-mod-profilemode.png
alt: ""
caption: ""
hidden: true
relative: true # To use relative path for cover image, used in hugo Page-bundles
edit_post:
url: "https://github.com//content"
text: "Suggest Changes" # edit text
append_file_path: true # to append file path to Edit link
Intro
Generalist Models are hot! We all see an opportunity towards a real generalist model by multimodal multitask learning. We previously release an opensourced unified multimodal pretrained model OFA for this goal. However, we actually met a lot of difficulties in our implementation. For example, it is hard to set up multiple tasks concerning multiple modalities, and it is hard to organize multitask learning, e.g., how to batchify your data and how to make your training stable. Therefore, we propose OFASys, an AI framework targeting multimodal multitask learning. In brief, it uses a simple interface called Instruction, which is a template for task-specific instruction and input information. Therefore, with 1 line of code for the Instruction, you can build a job of multimodal multitask learning with no worries about the complex processes, e.g., data preprocessing, model building, training, etc. OFASys helps you get rid of many details and gives a chance to focus on designing tasks and modalities.
{{< button href="https://arxiv.org/abs/2212.04408" label="Paper" external=true >}}
{{< button href="https://github.com/OFA-Sys/OFASys" label="GitHub" external=true >}}
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofasys/demo.jpg#center" width="80%" >}}

Background
Thanks to Transformer and pretraining, we have witnessed an unprecedented opportunity towards general-purpose AI! In the field of natural language, we now have more than GPT-3[^1], and we even have ChatGPT with extremely comprehensive capabilities in question answering, dialog, creative writing, etc. In the field of multimodal representation learning, we have seen unified models that try to unify tasks and modalities to build a more general AI system, including our proposed OFA[^2], GATO[^3], Unified-IO[^4], etc. However, the key difficulties lie in the implementation. What makes deep learning engineers struggled is how to implement and train such a generalist model with so many datasets concerning inputs of different modalities and tasks. Although we now have PyTorch and TensorFlow for deep learning, and many beautiful frameworks for building Transformer, e.g., Hugging Face Transformers, fairseq, etc., there is still no designated system that provides neat abstractions and tools for task-agnostic generalist model learning.
User Interface
Before introducing the system design, we first move into the world of OFASys to see how we can build a multitask learning model with a single line of code. To be more specific, what you need to do is composing a proper Instruction. Here are several examples of Instruction for different tasks:
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofasys/caption_instruction.jpg#center" width="80%" >}}

The two sentences separated by “->” describe the task input and its desired output, respectively. In this case, “<tt>[IMAGE:img]</tt>” specifies that there is an image input bound to a data column named <tt>img</tt> in the dataset. The plain texts in the Instruction indicate the task is about captioning an image. The output of the task is a text sequence, which is the <tt>cap</tt> column in the dataset.
Another example is for an NLI task:
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofasys/mnli_instruction.jpg#center" width="80%" >}}

Similar to the previous one, we use a template and indicators for inputs to build an Instruction. Differently, there are two inputs for the encoder. Besides, as we find repeating the input in the decoder is helpful for the downstream performance, we use a signal <tt>no_loss</tt> to avoid loss computation. As the label set is closed for NLI, we use a signal <tt>closed_set</tt> for the indication.
To sum up, things can be much easier if you use OFASys. What you need might only be 1 line of code for the Instruction.
System Design
A neat system design is what lies behind an easy-to-use interface. An overview is demonstrated below.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofasys/overview.jpg#center" width="80%" >}}

OFASys accesses the task definition and task data through Instruction by parsing Instructions into task plans. In each plan, there is a model hierarchy, consisting of modality-specific preprocessors/postprocessors and adapters, as well as a modality-agnostic computation model. The universal model is namely a general module for fusing multimodal inputs and generating outputs. As the inputs and the outputs are consistently being representation sequences, the implementation of the universal model is highly versatile, regardless of the modality intricacies. The outputs of the universal model is finally postprocessed by the adapters and postprocessors, in order to generate content consistent with the input formats. Stage-wise components, including criteria and generators, provide support in training and inference, which have a variety of out-of-the-box implementations. In this way, different multi-modal data can go through the system with consistent inner interfaces to improve development efficiency.
In multitask learning, there are multiple such plans parsed from the Instructions. OFASys shares the trainable parameters of the adapters and the universal model by default, such that each parameter can be optimized on as many examples as possible. A task scheduler manages task precedence and joint optimization, and a logical scheduler arranges the workflow on multiple physical devices.
Application Example: OFA+
To validate its effectiveness, we train a generalist model based on OFA, OFA+, which can handle text, image, speech, video and motion data all-in-one for the first time. Specifically, we have trained a OFA-based OFA+ (Generalist) and an improved version with modality-level MoE, OFA+ (Generalist MoE). For comparison, we use the original OFA (OFA+ (Specialist)) which is finetuned on each specific task.
{{< figure src="https://qianwen-res.oss-accelerate-overseas.aliyuncs.com/assets/blog/ofasys/results.jpg#center" width="80%" >}}

In general, OFA+ is able to preserve 95+% of the performance of the specialist model while scaling to 23 diverse tasks over 7 modalities. This shows that multitask learning not only endows the generalist model with multiple capabilities but also helps it achieve top-level performance on specific tasks.
Conclusion
As generalist models attract increasing interests, the lack of designated system and library for multimodal multitask stands out as an obstacle in the path for rapid growth. OFASys is developed to match the need in multimodal multitask learning of extreme modality and task scaling. We hope OFASys would push forward the research in multimodal multitask learning and facilitate the construction of generalist models that are even more general.
[^1]: Brown, T.B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., Agarwal, S., Herbert-Voss, A., Krueger, G., Henighan, T.J., Child, R., Ramesh, A., Ziegler, D.M., Wu, J., Winter, C., Hesse, C., Chen, M., Sigler, E., Litwin, M., Gray, S., Chess, B., Clark, J., Berner, C., McCandlish, S., Radford, A., Sutskever, I., & Amodei, D. (2020).
Language Models are Few-Shot Learners.
arXiv, abs/2005.14165.
[^2]: Wang, P., Yang, A., Men, R., Lin, J., Bai, S., Li, Z., Ma, J., Zhou, C., Zhou, J., & Yang, H. (2022).
Unifying Architectures, Tasks, and Modalities Through a Simple Sequence-to-Sequence Learning Framework.
International Conference on Machine Learning.
[^3]: Reed, S., Zolna, K., Parisotto, E., Colmenarejo, S.G., Novikov, A., Barth-Maron, G., Gimenez, M., Sulsky, Y., Kay, J., Springenberg, J.T., Eccles, T., Bruce, J., Razavi, A., Edwards, A.D., Heess, N.M., Chen, Y., Hadsell, R., Vinyals, O., Bordbar, M., & Freitas, N.D. (2022).
A Generalist Agent.
arXiv, abs/2205.06175.
[^4]: Lu, J., Clark, C., Zellers, R., Mottaghi, R., & Kembhavi, A. (2022).
Unified-IO: A Unified Model for Vision, Language, and Multi-Modal Tasks.
arXiv, abs/2206.08916.