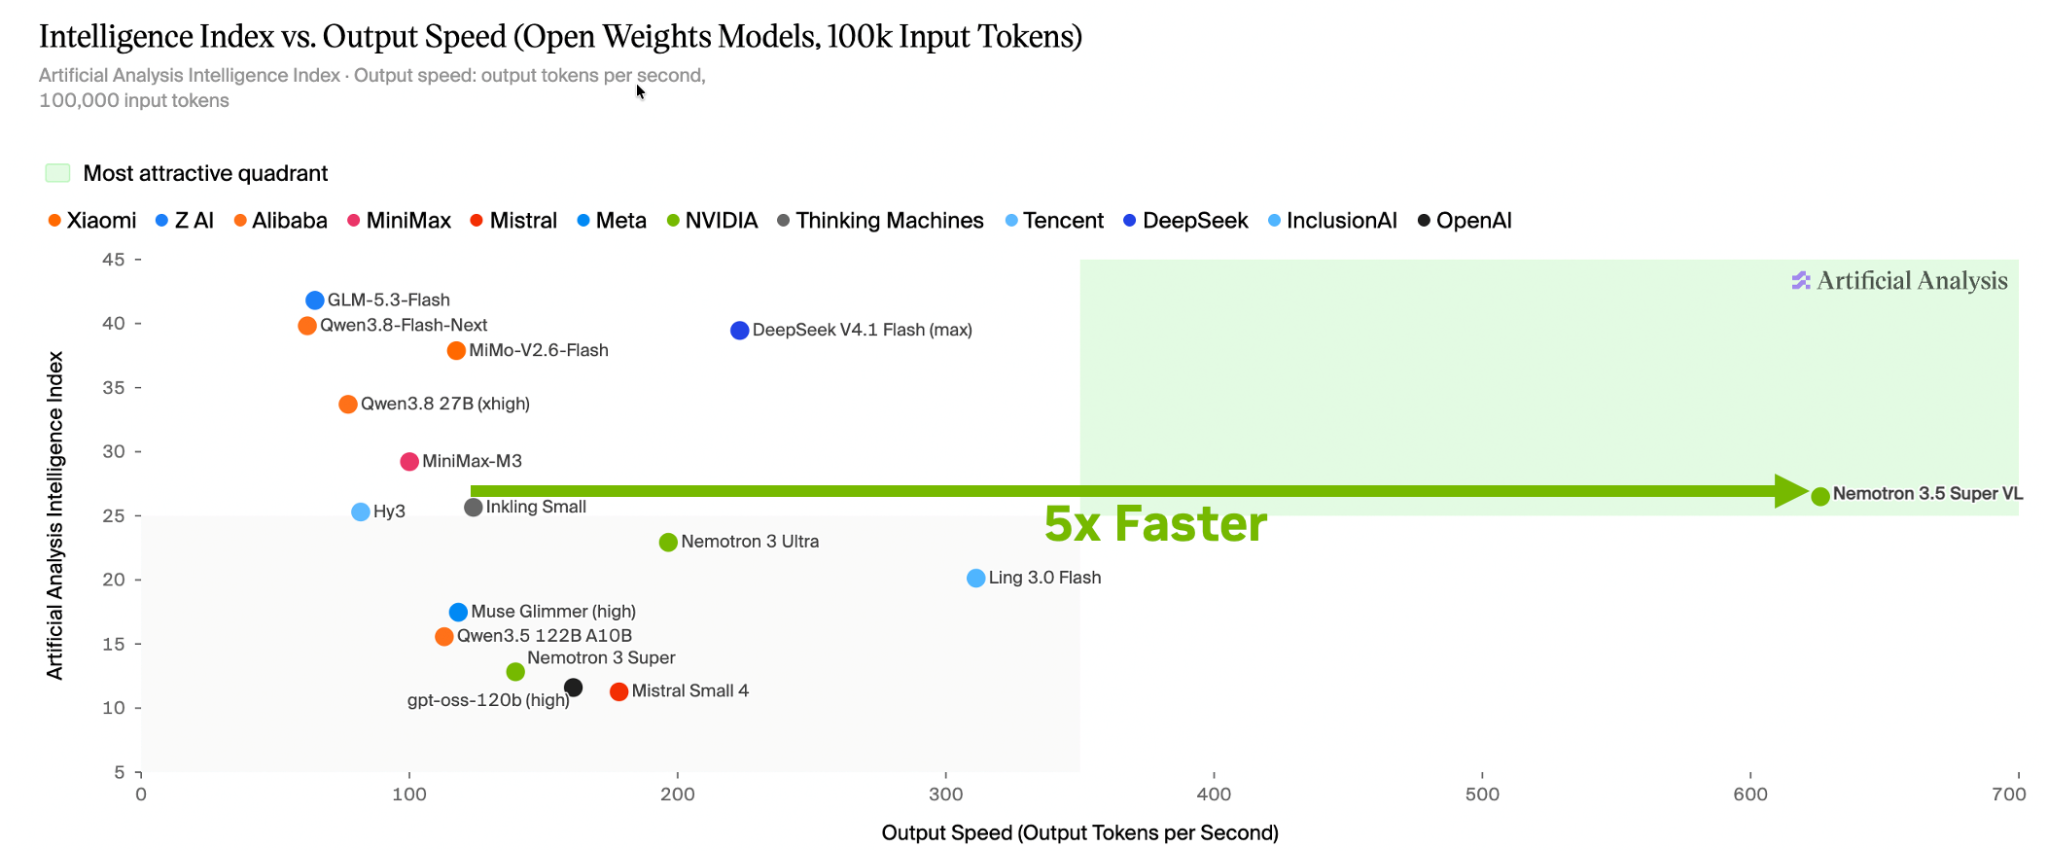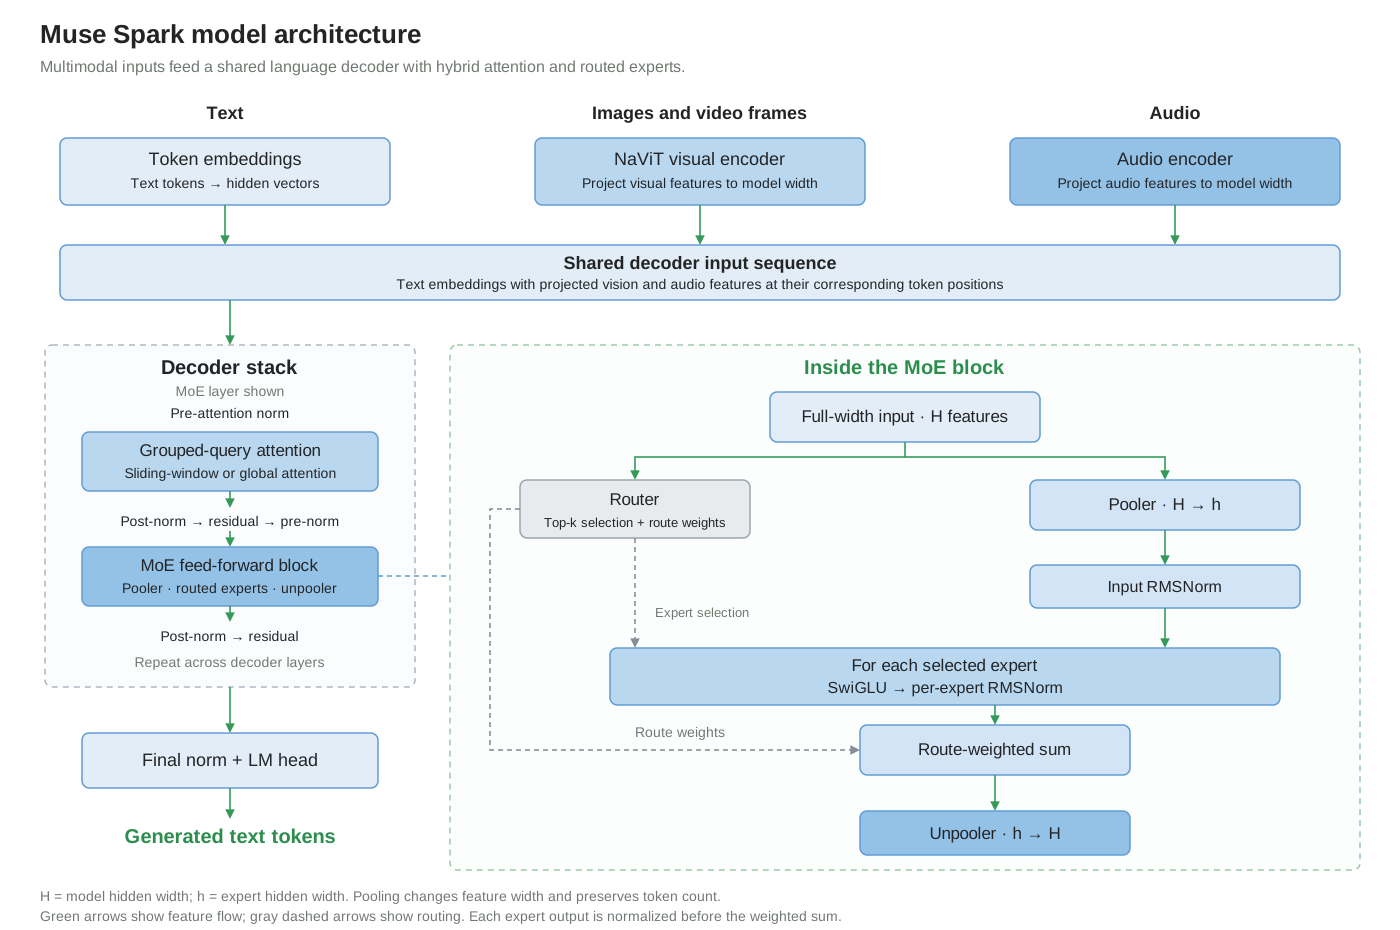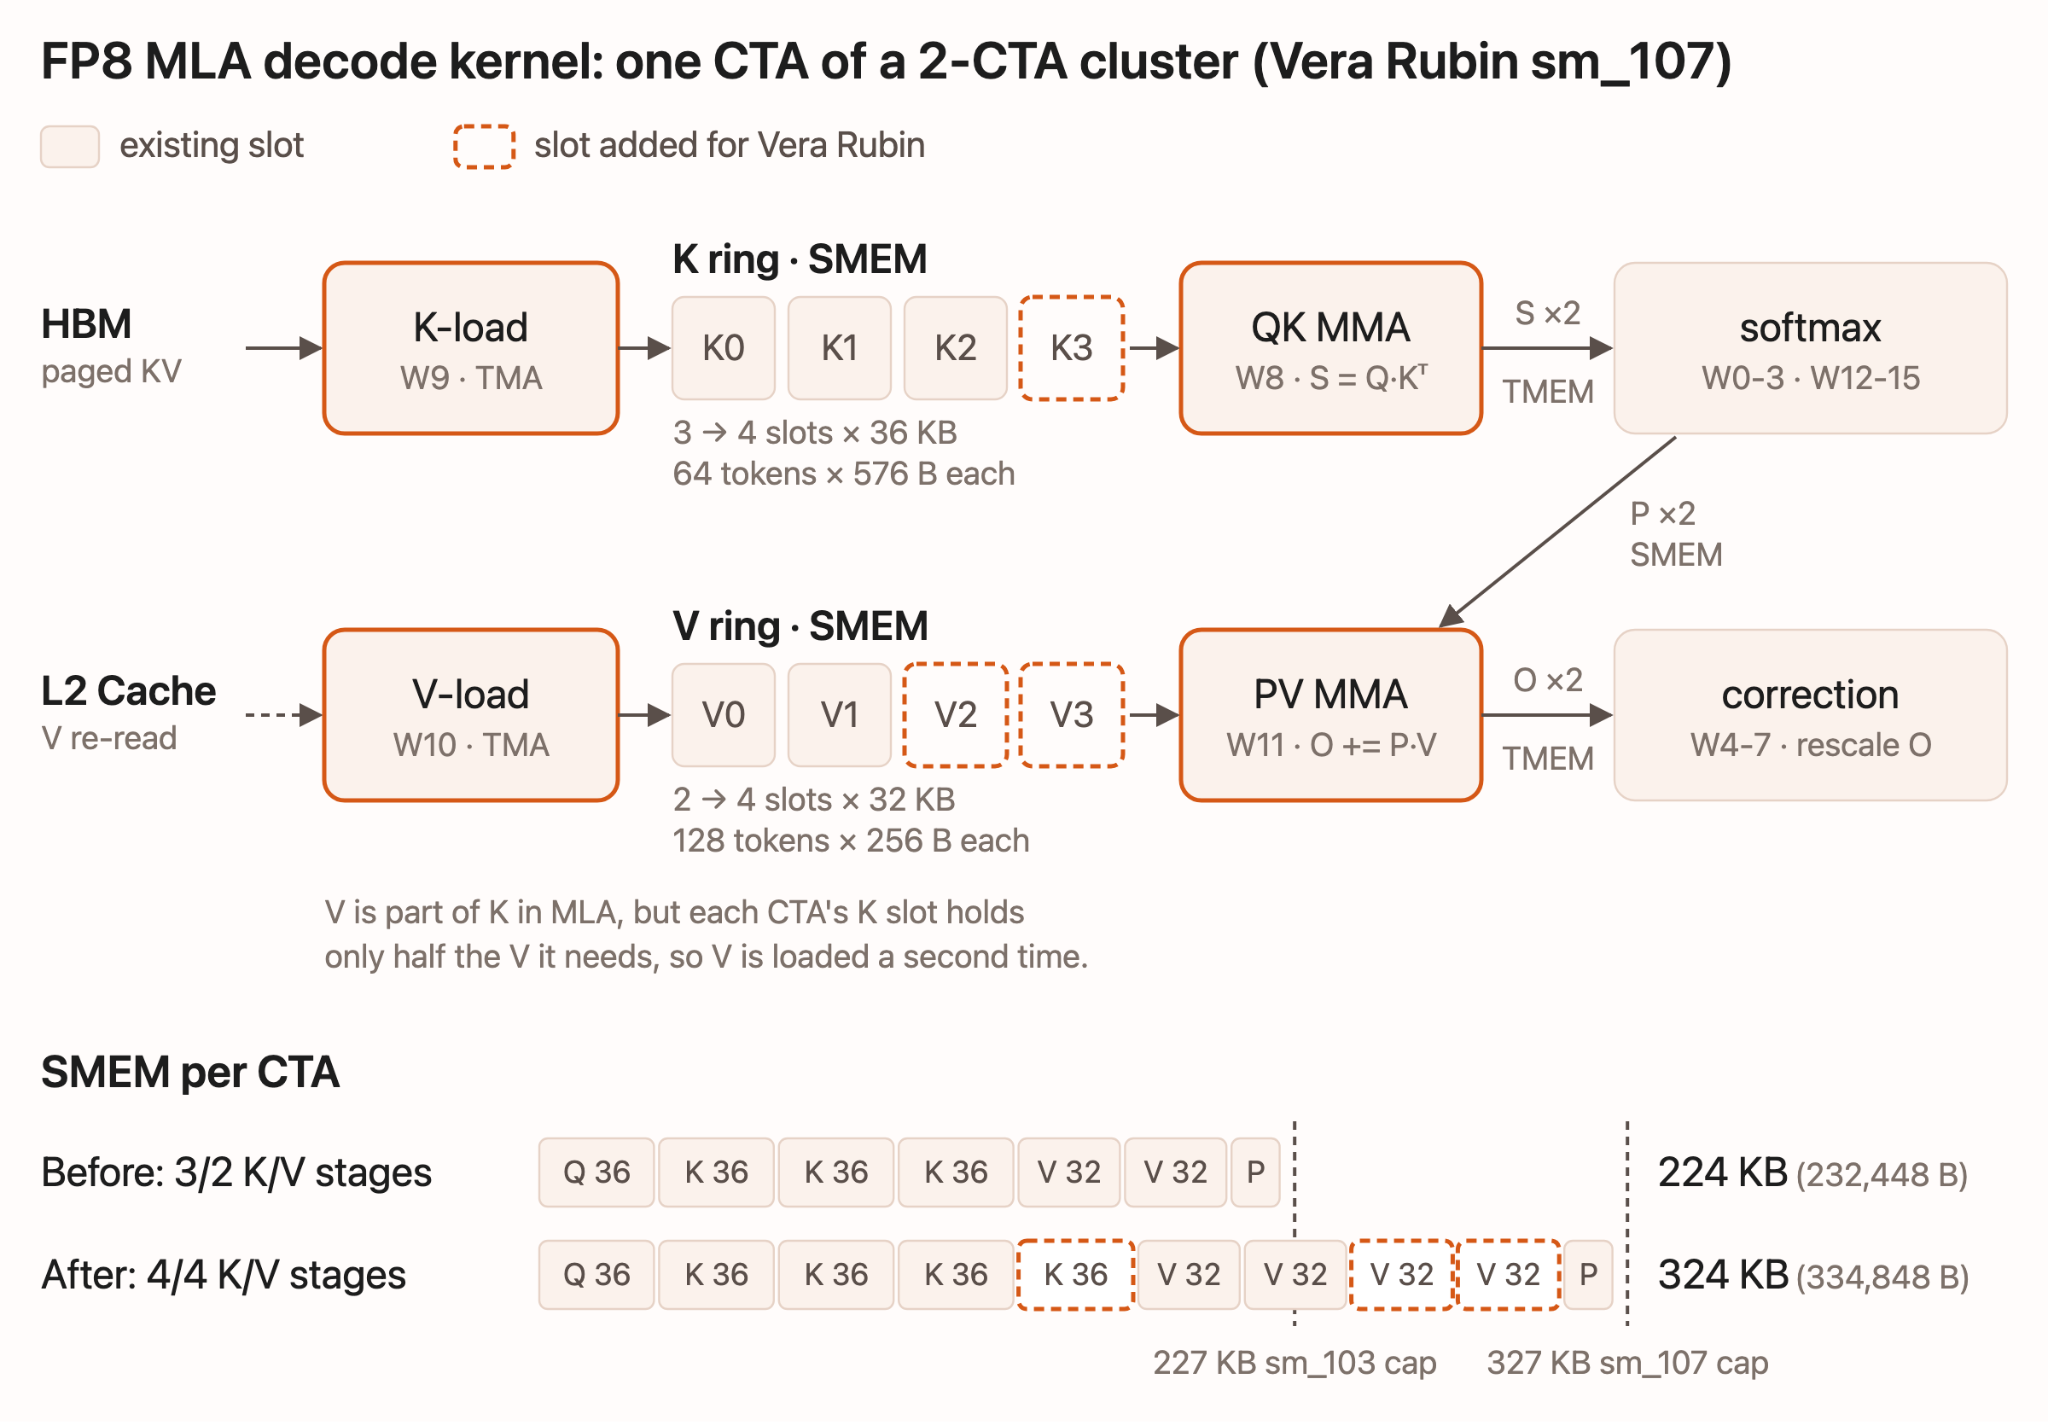
# Technical Documentation: sgl-project/sglang

> ℹ️ **Provenance:** Multi-Tier Ingestion · [CodeWiki Reference](https://codewiki.google/github.com/sgl-project/sglang)

### Overview (README.md)

# SGLang: Fast inference for LLMs and multimodal models

<p align="center" id="sglangtop">
<img src="https://raw.githubusercontent.com/sgl-project/sglang/main/assets/logo.png" alt="SGLang" width="400">
</p>

<p align="center">
  <a href="https://pypi.org/project/sglang/"><img src="https://img.shields.io/pypi/v/sglang?style=flat&amp;label=PyPI&amp;labelColor=555555&amp;color=orange" alt="PyPI version"></a>
  <a href="LICENSE"><img src="https://img.shields.io/badge/License-Apache%202.0-green?style=flat&amp;labelColor=555555" alt="License: Apache 2.0"></a>
  <a href="https://pypistats.org/packages/sglang"><img src="https://img.shields.io/pypi/dm/sglang?style=flat&amp;label=Downloads&amp;labelColor=555555&amp;color=blue" alt="PyPI downloads per month"></a>
</p>

<p align="center">
  <a href="https://docs.sglang.io/">Docs</a> |
  <a href="https://cookbook.sglang.io/">Cookbook</a> |
  <a href="https://www.sglang.io/">Website</a> |
  <a href="https://lmsys.org/blog/">Blog</a> |
  <a href="https://slack.sglang.io/">Slack</a>
</p>

SGLang is an open-source inference framework for large language, vision-language, and diffusion models, optimized for agentic workloads, large-scale serving, and RL rollouts. [SGLang Diffusion](https://docs.sglang.io/docs/sglang-diffusion) is its built-in image and video generation engine, included in this repository and the `sglang` Python package.

👋 Get started below, or meet the community at [SGLang Events](https://www.sglang.io/events), including meetups, developer meetings, workshops, and office hours.

> **[SGLang Summit 2026: Meet the builders of open AI](https://www.sglang.io/summit)**<br>
> **Our flagship annual gathering · November 12–13 · San Francisco**
>
> Go deep on inference, training, and AI hardware through technical talks, live demos, and hands-on workshops. Bring your deployment challenges and meet the engineers and researchers building the stack.

## Get Started

Pull the Docker image, which includes SGLang and its dependencies:

```bash
docker pull lmsysorg/sglang:latest
```

Alternatively, install SGLang in an activated Python environment with uv:

```bash
uv pip install --prerelease=allow sglang
```

Next, launch your model:

- [Quickstart](https://docs.sglang.io/docs/get-started/quickstart): Run your first model and send a request.
- [Cookbook](https://cookbook.sglang.io/): Choose your model and hardware to get a ready-to-run launch command.

## Supported Hardware

SGLang supports a wide range of GPUs, TPUs, NPUs, CPUs, and Apple Silicon platforms.

| Platform | Representative hardware |
| --- | --- |
| [NVIDIA](https://docs.sglang.io/docs/hardware-platforms/nvidia-gpus) | B200/B300/GB200/GB300; H100/H200/H800/H20; A100; RTX 30/40/50 series, RTX 6000 Ada / PRO 6000; DGX Spark, Jetson Orin |
| [AMD](https://docs.sglang.io/docs/hardware-platforms/amd_gpu) | Instinct MI300X, MI325X, MI350X, MI355X |
| [Google TPU](https://docs.sglang.io/docs/hardware-platforms/tpu) | v6e, v7; [SGLang-TorchTPU](https://github.com/sgl-project/sglang-torchtpu) / [SGL-JAX](https://github.com/sgl-project/sglang-jax) |
| Intel ([GPU](https://docs.sglang.io/docs/hardware-platforms/xpu) / [CPU](https://docs.sglang.io/docs/hardware-platforms/cpu_server)) | Arc / Arc Pro B-Series GPUs, Xeon CPUs |
| [Apple Silicon](https://docs.sglang.io/docs/hardware-platforms/apple_metal) | Macs via Metal / MLX |
| [Huawei Ascend](https://docs.sglang.io/docs/hardware-platforms/ascend-npus/getting-started/installation) | A2, A3, 950PR/DT NPUs |
| [Moore Threads](https://docs.sglang.io/docs/hardware-platforms/mthreads_gpu) | MTT S5000 GPUs |

Integrations in progress: AWS Trainium, [Alibaba T-Head PPU](https://github.com/sgl-project/sglang/issues/37519), [Cambricon MLU](https://github.com/sgl-project/sglang/pull/26898), Qualcomm QAIC, MetaX, Hygon HCU/DCU, Iluvatar CoreX, and more.

SGLang-TorchTPU brings the SGLang serving engine to Google TPUs through PyTorch, torch_tpu, and Pallas kernels. It supports LLM and vision-language serving on TPU7x (Ironwood), including tensor and expert parallelism across hosts. SGL-JAX provides the JAX-based TPU serving path.

See the [Cookbook](https://cookbook.sglang.io/) and platform guides for model compatibility and setup.

## SGL Ecosystem

| Area | Projects | Purpose |
| --- | --- | --- |
| Diffusion | [SGLang Diffusion](https://docs.sglang.io/docs/sglang-diffusion/installation) | Built into SGLang for image and video generation with diffusion models. |
| Audio | [SGLang Omni](https://github.com/sgl-project/sglang-omni) | Audio model serving for text-to-speech (TTS) and automatic speech recognition (ASR). |
| Speculative Decoding | [SpecForge](https://github.com/sgl-project/SpecForge) | Train draft models for speculative decoding and deploy them with SGLang. |
| RL and Post-Training | [Miles](https://github.com/radixark/miles), [slime](https://github.com/THUDM/slime), [AReaL](https://github.com/inclusionAI/AReaL), [Tunix](https://github.com/google/tunix), [verl](https://github.com/volcengine/verl) | Training frameworks that integrate SGLang for rollout generation. |
| Deployment and Orchestration | [SMG](https://github.com/smg-project/smg), [RBG](https://github.com/sgl-project/rbg), [llm-d](https://llm-d.ai/docs/dev/operations/disaggregation/sglang), [Ray Serve](https://docs.ray.io/en/latest/serve/llm/user-guides/sglang.html), [NVIDIA Dynamo](https://docs.nvidia.com/dynamo/backends/sg-lang/reference-guide) | Deploy and scale SGLang inference services with routing, load balancing, and cluster orchestration. |
| Education | [Mini-SGLang](https://github.com/sgl-project/mini-sglang), [zero-to-sglang](https://github.com/datawhalechina/zero-to-sglang), [DeepLearning.AI course](https://www.deeplearning.ai/short-courses/efficient-inference-with-sglang-text-and-image-generation/) | Learn inference engine design and efficient text and image generation through code and hands-on courses. |

## Development and Contributing

Contributions are welcome, from bug fixes and documentation to model support and performance improvements.

### Development setup

Start from the `lmsysorg/sglang:dev` Docker image, which provides development tools and most dependencies. Clone or mount your SGLang checkout inside the container, then install it in editable mode from the repository root so tests use your local Python changes:

```bash
pip install -e "python"
```

In an activated virtual environment, you can use `uv pip install --prerelease=allow -e "python"` instead. See the [development guide](https://docs.sglang.io/docs/developer_guide/development_guide_using_docker) for container setup and testing.

### Contribute

1. Fork the repository and create a branch for your changes. For larger changes, discuss your proposal in a [GitHub issue](https://github.com/sgl-project/sglang/issues) or on [Slack](https://slack.sglang.io/).
2. Make your changes, run the relevant tests, and add regression coverage for fixes or new behavior. Run `pre-commit run --all-files` before submitting.
3. Open a pull request describing the change and how you tested it. Include benchmarks or accuracy evaluations when relevant.

See the [contributor guide](https://docs.sglang.io/docs/developer_guide/contribution_guide) for formatting, testing, and pull request instructions. Documentation contributors can start with the [docs guide](docs/README.md).

## Community and Sponsorship

SGLang is hosted by [LMSYS](https://lmsys.org/about/), a non-profit open-source organization.

- **Community discussions:** Join [Slack](https://slack.sglang.io/) for technical questions and development discussions.
- **Events:** Find meetups, workshops, and office hours on [SGLang Events](https://www.sglang.io/events).
- **Updates:** Follow [X](https://x.com/lmsysorg) and [LinkedIn](https://www.linkedin.com/company/sgl-project/) for project updates, and the [LMSYS Blog](https://lmsys.org/blog/) for release announcements and technical articles.
- **Project resources:** Explore the [documentation](https://docs.sglang.io/), [Cookbook](https://cookbook.sglang.io/), [roadmap](https://roadmap.sglang.io/), [release notes](https://github.com/sgl-project/sglang/releases), [issue tracker](https://github.com/sgl-project/sglang/issues), and [contributor guide](https://docs.sglang.io/docs/developer_guide/contribution_guide).
- **Contact Us:** For enterprise adoption and deployment, technical consulting, sponsorship, or partnership inquiries, please contact [sglang@lmsys.org](mailto:sglang@lmsys.org).
- **Contributor sponsorship:** Long-term active SGLang contributors are eligible for coding agent sponsorship, including Cursor, Claude Code, or OpenAI Codex. To apply, email [sglang@lmsys.org](mailto:sglang@lmsys.org) with links to your key commits or pull requests.

## Trusted by Industry and Research

SGLang serves production workloads across AI labs, cloud platforms, enterprises, and universities.

<img src="https://raw.githubusercontent.com/sgl-project/sgl-learning-materials/refs/heads/main/slides/adoption.png" alt="Organizations adopting SGLang" width="800">

## Acknowledgment
We learned the design and reused code from the following projects: [Guidance](https://github.com/guidance-ai/guidance), [vLLM](https://github.com/vllm-project/vllm), [LightLLM](https://github.com/ModelTC/lightllm), [FlashInfer](https://github.com/flashinfer-ai/flashinfer), [Outlines](https://github.com/outlines-dev/outlines), and [LMQL](https://github.com/eth-sri/lmql).

---

### README (`docs/README.md`)

# SGLang Documentation

The official documentation and cookbook for [SGLang](https://github.com/sgl-project/sglang) — a high-performance serving framework for large language models and vision-language models.

- **Docs**: Getting started guides, installation, and reference
- **Cookbook**: Battle-tested recipes for deploying specific models (Qwen, DeepSeek, Llama, GLM, etc.) on various hardware


## Project structure

```
.
├── docs.json              # Site configuration (navigation, theme, metadata)
├── index.mdx              # Homepage
├── docs/                  # Documentation pages
│   └── get-started/
│       └── install.mdx    # Installation guide
├── cookbook/              # Model deployment recipes (one .mdx page per model)
│   ├── intro.mdx          # Cookbook overview and recipe index
│   └── autoregressive/    # Autoregressive recipes (also: diffusion/, omni/, …)
│       └── DeepSeek/
│           └── DeepSeek-V4.mdx
└── src/snippets/          # Config-driven cookbook engine
    ├── _deployment.jsx    # Shared deploy-matrix engine (no model-specific code)
    ├── _playground.jsx    # Shared override-playground engine
    └── configs/
        └── deepseek-ai/   # Per-model config + benchmarks (HF-org folder)
            └── deepseek-v4.jsx
```

Pages are `.mdx` files with YAML frontmatter. Navigation is defined in `docs.json`.

## Local development

### Prerequisites

- Node.js >= 20

### Setup

```bash
# Install the CLI
npm i mint

# From docs/ (where docs.json lives), start the dev server (hot reload)
mint dev
```

Preview at `http://localhost:3000`.

### Useful commands

```bash
mint dev            # Start local preview server
mint broken-links   # Check for broken links
mint update         # Update the CLI
```

## Contributing

We welcome contributions! Whether you want to add a recipe for a new model, improve existing docs, or fix a typo — PRs are appreciated.

### Quick edit (GitHub)

1. Navigate to the file you want to edit on GitHub
2. Click the pencil icon to edit
3. Submit a pull request

### Local development workflow

```bash
# 1. Fork sgl-project/sglang and clone your fork
git clone https://github.com/<YOUR_USERNAME>/sglang.git
cd sglang/docs

# 2. Create a branch
git checkout -b my-changes

# 3. Start the dev server and make your changes
mint dev

# 4. Verify links aren't broken
mint broken-links

# 5. Commit and push
git add <files>
git commit -m "docs: describe your change"
git push origin my-changes

# 6. Open a pull request on GitHub
```

### Adding a new cookbook recipe

The autoregressive cookbook is **config-driven**: two shared engines —
`src/snippets/_deployment.jsx` (the deploy matrix) and `src/snippets/_playground.jsx`
(the override playground) — contain **no** model-specific code. Adding a model means adding
*data*: a per-model config (plus optional benchmarks) that both engines consume, and an
`.mdx` page that imports them. Copy [`DeepSeek-V4`](cookbook/autoregressive/DeepSeek/DeepSeek-V4.mdx)
as the reference instance.

**Recommended — use the Claude Code skill `/cookbook-add-model`.** It walks the whole flow
interactively: collect the model card + verified `sglang serve` recipes → instantiate the
template → wire up the nav/card → validate → fill in measured benchmarks. Related skills:
`/cookbook-migrate-model` (port an existing legacy-template page) and `/cookbook-review-pr`
(review a cookbook PR against the checklist).

**The files it creates / edits — using DeepSeek-V4 as the example:**

| File | Purpose |
|---|---|
| `src/snippets/configs/deepseek-ai/deepseek-v4.jsx` | Per-model config: `supportedHardware`, `variants`, `quantizations`, `strategies`, the `cells[]` deploy matrix (verified env + flags per `hw × variant × quant × strategy × nodes`), and `playgroundFeatures`. |
| `src/snippets/configs/deepseek-ai/deepseek-v4-benchmarks.jsx` | One entry per cell with measured speed/accuracy + the `sglang_version` it ran on. Optional — skip until you have numbers. |
| `cookbook/autoregressive/DeepSeek/DeepSeek-V4.mdx` | The page: imports the engines + config, renders `<Deployment>` / `<Playground>`, and adds prose (intro + specs + license, config tips, advanced usage). |
| `docs.json` | Nav entry under Cookbook → category → vendor. |
| `cookbook/autoregressive/intro.mdx` | Vendor `<Card>` on the category homepage. |

Note the two folder conventions: under `configs/` the folder is the **HuggingFace org**
(`deepseek-ai`); under `cookbook/` it's the **display vendor** (`DeepSeek`). The page wires
everything together with data only — no engine edits:

```mdx
import { Deployment } from "/src/snippets/_deployment.jsx";
import { Playground } from "/src/snippets/_playground.jsx";
import { config }     from "/src/snippets/configs/deepseek-ai/deepseek-v4.jsx";
import { benchmarks } from "/src/snippets/configs/deepseek-ai/deepseek-v4-benchmarks.jsx";

<Deployment config={config} benchmarks={benchmarks} />
<Playground config={config} />
```

Keep `tag: NEW` on the new page and strip it from same-vendor siblings (≤1 per vendor), then
validate from `docs/`: `mint validate`, `mint broken-links`, and `mint dev` for a visual
smoke test.

> Diffusion / omni / specbundle pages follow their own category structure — don't force the
> autoregressive config-driven template on them.

### Writing guidelines

- Use active voice: "Run the command" not "The command should be run"
- Address the reader as "you"
- Keep sentences concise — one idea per sentence
- Lead with the goal, then the steps
- Use consistent terminology
- Include concrete examples and code snippets

## Acknowledgements

Thank you to all the authors who contributed to the original documentation in `sglang/docs/` and the original cookbook in [`sgl-cookbook`](https://github.com/sgl-project/sgl-cookbook). The migration to the new Mintlify-based documentation was led by the following [ACM-VIT](https://github.com/ACM-VIT) students:

[@Adhyan Jain](https://github.com/Adhyan-Jain), [@Maitri-shah29](https://github.com/Maitri-shah29), [@architnigam](https://github.com/architnigam), [@Nakul-Sinha](https://github.com/Nakul-Sinha), [@divyamagrawal06](https://github.com/divyamagrawal06), [@A-Taman](https://github.com/A-Taman), [@nimeshas](https://github.com/nimeshas), [@IshhanKheria](https://github.com/IshhanKheria), [@Krishang-Zinzuwadia](https://github.com/Krishang-Zinzuwadia), [@pokymono](https://github.com/pokymono), [@Ishitajoshii](https://github.com/Ishitajoshii), [@AdityaVKochar](https://github.com/AdityaVKochar)

Advised by [@adarshxs](https://github.com/adarshxs) (ACM-VIT) and [@wisclmy0611](https://github.com/wisclmy0611), [@Richardczl98](https://github.com/Richardczl98) (LMSYS).

## Community

- [GitHub](https://github.com/sgl-project/sglang)
- [Slack](https://slack.sglang.io/)
- [Discord](https://discord.gg/4ugb2t6YY2)
- [X / Twitter](https://x.com/lmsysorg)
- [LinkedIn](https://www.linkedin.com/company/sgl-project/)

## License

Apache License 2.0 — see the [LICENSE](LICENSE) for details.

---

### Index (`docs/index.mdx`)

---
title: Welcome to SGLang
description: High-performance serving framework for large language and multimodal models.
keywords:
  - sglang
  - llm serving
  - multimodal
  - inference runtime
mode: wide
---

import { popularModels } from "/src/snippets/configs/popular-models.jsx";
import { PopularModels } from "/src/snippets/_popular_models.jsx";

{/* One hero per model, rotating. The Cookbook landing page renders the same
    list as a compact strip. Edit the list, not this page. */}
<PopularModels models={popularModels} variant="hero" />

<a
  class="github-button"
  href="https://github.com/sgl-project/sglang"
  data-size="large"
  data-show-count="true"
  aria-label="Star sgl-project/sglang on GitHub"
>
  Star
</a>
<a
  class="github-button"
  href="https://github.com/sgl-project/sglang/fork"
  data-icon="octicon-repo-forked"
  data-size="large"
  data-show-count="true"
  aria-label="Fork sgl-project/sglang on GitHub"
>
  Fork
</a>
<script async defer src="https://buttons.github.io/buttons.js"></script>
<br></br>

<CardGroup cols={2}>
  <Card title="Performance & Runtime" icon="arrow-trend-up">
    Designed for low-latency, high-throughput inference with RadixAttention, prefix caching, and multi-GPU parallelism.
  </Card>

<Card title="Models & Ecosystem" icon="hexagon-nodes">
  Broad support for Llama, Qwen, DeepSeek, and more. Compatible with Hugging
  Face and OpenAI APIs.
</Card>

<Card title="Extensive Hardware Support" icon="microchip">
  Native support across <a href="./docs/hardware-platforms/overview">Hardware Platforms</a>
  including NVIDIA, AMD, Intel Xeon, Google TPU, Ascend NPU, and Moore Threads MUSA accelerators.
</Card>

  <Card title="Community & Training" icon="users">
    Open-source with widespread adoption, powering 400k+ GPUs and integrated with major RL frameworks.
  </Card>
</CardGroup>

SGLang powers large-scale production deployments, generating trillions of tokens each day across more than 400,000 GPUs worldwide. It is hosted under the non-profit open-source organization [LMSYS](https://lmsys.org/about/).

---

## Get Started

SGLang is an inference framework meant for production level serving.
It is designed to deliver low-latency and high-throughput inference across a wide range of setups, from a single GPU to large distributed clusters.

<CardGroup cols={2}>
<Card title="Quickstart" icon="zap" href="./docs/get-started/quickstart">
  Start a model server and send a request to verify it is running.
</Card>

<Card title="Examples" icon="code" href="/docs/get-started/examples">
  Stream replies, request tool calls, and process multiple prompts from Python.
</Card>
</CardGroup>

For environment setup and other installation methods, see the [Installation guide](/docs/get-started/install).

## News and latest blogs

{/* BEGIN_LMSYS_SGLANG_BLOG_CARDS */}
<div className="not-prose">
  <div
    style={{
      display: "grid",
      gridTemplateColumns: "repeat(auto-fit, minmax(300px, 1fr))",
      gap: "1rem",
      alignItems: "stretch",
    }}
  >
    <a
      href="https://lmsys.org/blog/2026-10-15-nvidia-nemotron-3-5-super-vl/"
      target="_blank"
      rel="noopener noreferrer"
      style={{
        display: "block",
        border: "1px solid rgba(128, 128, 128, 0.3)",
        borderRadius: "0.75rem",
        overflow: "hidden",
        textDecoration: "none",
        color: "inherit",
        height: "100%",
      }}
    >
      <div
        style={{
          aspectRatio: "16 / 9",
          overflow: "hidden",
          background: "rgba(128, 128, 128, 0.15)",
        }}
      >
        <img
          src="https://lmsys.org/images/blog/nemotron-3-5-super-vl/image1.png"
          alt="SGLang Adds Day-0 Support for NVIDIA Nemotron 3.5 Super VL"
          style={{
            width: "100%",
            height: "100%",
            objectFit: "cover",
            objectPosition: "center",
            display: "block",
          }}
        />
      </div>
      <div style={{ padding: "0.9rem 1rem 1rem" }}>
        <p
          style={{
            margin: 0,
            fontWeight: 600,
            lineHeight: 1.35,
            fontSize: "0.98rem",
          }}
        >
          {"SGLang Adds Day-0 Support for NVIDIA Nemotron 3.5 Super VL"}
        </p>
        <p
          style={{
            margin: "0.55rem 0 0",
            fontSize: "0.85rem",
            opacity: 0.75,
          }}
        >
          {"October 15, 2026"}
        </p>
      </div>
    </a>
    <a
      href="https://lmsys.org/blog/2026-10-15-meta-muse-spark-open/"
      target="_blank"
      rel="noopener noreferrer"
      style={{
        display: "block",
        border: "1px solid rgba(128, 128, 128, 0.3)",
        borderRadius: "0.75rem",
        overflow: "hidden",
        textDecoration: "none",
        color: "inherit",
        height: "100%",
      }}
    >
      <div
        style={{
          aspectRatio: "16 / 9",
          overflow: "hidden",
          background: "rgba(128, 128, 128, 0.15)",
        }}
      >
        <img
          src="https://lmsys.org/images/blog/meta-muse-spark-open/muse-spark-architecture.svg"
          alt="SGLang and Miles Add Day-0 Support for Muse Spark Open"
          style={{
            width: "100%",
            height: "100%",
            objectFit: "cover",
            objectPosition: "center",
            display: "block",
          }}
        />
      </div>
      <div style={{ padding: "0.9rem 1rem 1rem" }}>
        <p
          style={{
            margin: 0,
            fontWeight: 600,
            lineHeight: 1.35,
            fontSize: "0.98rem",
          }}
        >
          {"SGLang and Miles Add Day-0 Support for Muse Spark Open"}
        </p>
        <p
          style={{
            margin: "0.55rem 0 0",
            fontSize: "0.85rem",
            opacity: 0.75,
          }}
        >
          {"October 15, 2026"}
        </p>
      </div>
    </a>
    <a
      href="https://lmsys.org/blog/2026-10-09-vera-rubin/"
      target="_blank"
      rel="noopener noreferrer"
      style={{
        display: "block",
        border: "1px solid rgba(128, 128, 128, 0.3)",
        borderRadius: "0.75rem",
        overflow: "hidden",
        textDecoration: "none",
        color: "inherit",
        height: "100%",
      }}
    >
      <div
        style={{
          aspectRatio: "16 / 9",
          overflow: "hidden",
          background: "rgba(128, 128, 128, 0.15)",
        }}
      >
        <img
          src="https://lmsys.org/images/blog/vera-rubin/mla-pipeline.png"
          alt="SGLang and Miles on NVIDIA Vera Rubin"
          style={{
            width: "100%",
            height: "100%",
            objectFit: "cover",
            objectPosition: "center",
            display: "block",
          }}
        />
      </div>
      <div style={{ padding: "0.9rem 1rem 1rem" }}>
        <p
          style={{
            margin: 0,
            fontWeight: 600,
            lineHeight: 1.35,
            fontSize: "0.98rem",
          }}
        >
          {"SGLang and Miles on NVIDIA Vera Rubin"}
        </p>
        <p
          style={{
            margin: "0.55rem 0 0",
            fontSize: "0.85rem",
            opacity: 0.75,
          }}
        >
          {"October 9, 2026"}
        </p>
      </div>
    </a>
    <a
      href="https://lmsys.org/blog/2026-09-25-sglang-decision-models/"
      target="_blank"
      rel="noopener noreferrer"
      style={{
        display: "block",
        border: "1px solid rgba(128, 128, 128, 0.3)",
        borderRadius: "0.75rem",
        overflow: "hidden",
        textDecoration: "none",
        color: "inherit",
        height: "100%",
      }}
    >
      <div
        style={{
          aspectRatio: "16 / 9",
          overflow: "hidden",
          background: "rgba(128, 128, 128, 0.15)",
        }}
      >
        <img
          src="https://lmsys.org/images/blog/sglang-decision-models/title-card.png"
          alt="Scaling JEV-like Decision Models with SGLang"
          style={{
            width: "100%",
            height: "100%",
            objectFit: "cover",
            objectPosition: "center",
            display: "block",
          }}
        />
      </div>
      <div style={{ padding: "0.9rem 1rem 1rem" }}>
        <p
          style={{
            margin: 0,
            fontWeight: 600,
            lineHeight: 1.35,
            fontSize: "0.98rem",
          }}
        >
          {"Scaling JEV-like Decision Models with SGLang"}
        </p>
        <p
          style={{
            margin: "0.55rem 0 0",
            fontSize: "0.85rem",
            opacity: 0.75,
          }}
        >
          {"September 25, 2026"}
        </p>
      </div>
    </a>
    <a
      href="https://lmsys.org/blog/2026-09-16-nvfp4-kv-cache/"
      target="_blank"
      rel="noopener noreferrer"
      style={{
        display: "block",
        border: "1px solid rgba(128, 128, 128, 0.3)",
        borderRadius: "0.75rem",
        overflow: "hidden",
        textDecoration: "none",
        color: "inherit",
        height: "100%",
      }}
    >
      <div
        style={{
          aspectRatio: "16 / 9",
          overflow: "hidden",
          background: "rgba(128, 128, 128, 0.15)",
        }}
      >
        <img
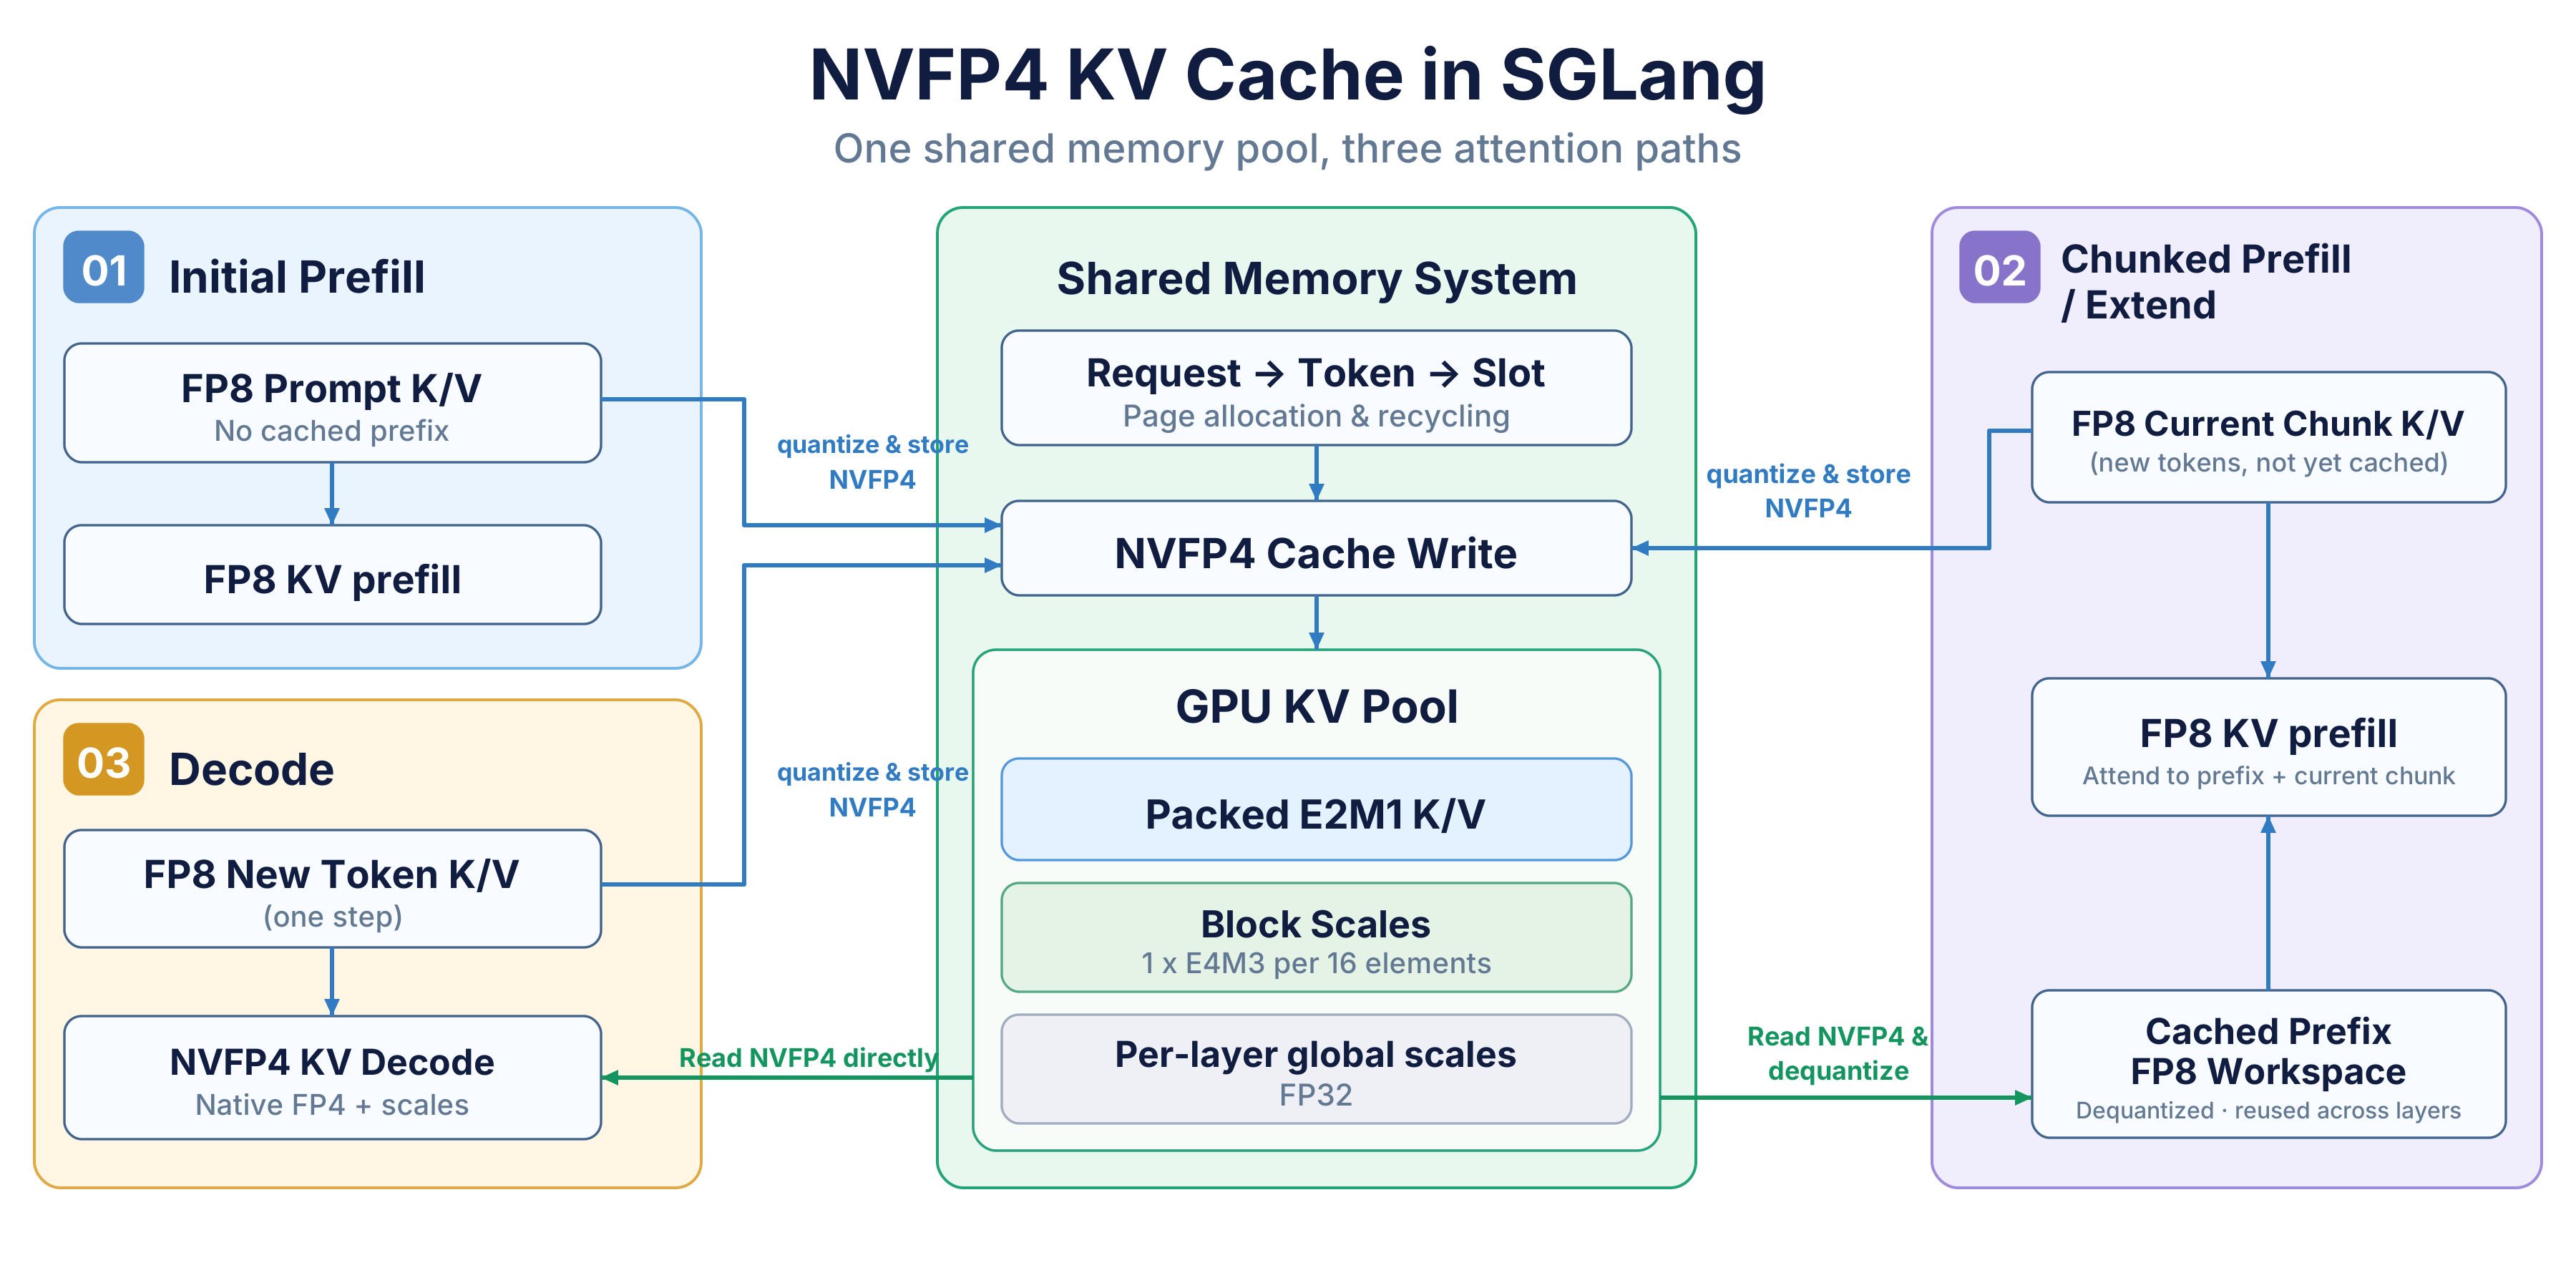
          src="https://lmsys.org/images/blog/nvfp4-kv-cache/kv-cache-layout.svg"
          alt="Accelerating Long-Context and Agentic Inference with NVFP4 KV Cache"
          style={{
            width: "100%",
            height: "100%",
            objectFit: "cover",
            objectPosition: "center",
            display: "block",
          }}
        />
      </div>
      <div style={{ padding: "0.9rem 1rem 1rem" }}>
        <p
          style={{
            margin: 0,
            fontWeight: 600,
            lineHeight: 1.35,
            fontSize: "0.98rem",
          }}
        >
          {"Accelerating Long-Context and Agentic Inference with NVFP4 KV Cache"}
        </p>
        <p
          style={{
            margin: "0.55rem 0 0",
            fontSize: "0.85rem",
            opacity: 0.75,
          }}
        >
          {"September 16, 2026"}
        </p>
      </div>
    </a>
    <a
      href="https://lmsys.org/blog/2026-09-10-deepseek-v41/"
      target="_blank"
      rel="noopener noreferrer"
      style={{
        display: "block",
        border: "1px solid rgba(128, 128, 128, 0.3)",
        borderRadius: "0.75rem",
        overflow: "hidden",
        textDecoration: "none",
        color: "inherit",
        height: "100%",
      }}
    >
      <div
        style={{
          aspectRatio: "16 / 9",
          overflow: "hidden",
          background: "rgba(128, 128, 128, 0.15)",
        }}
      >
        <img
          src="https://lmsys.org/images/blog/deepseek-v41/preview.png"
          alt="SGLang and Miles Add Day-0 Support for DeepSeek-V4.1"
          style={{
            width: "100%",
            height: "100%",
            objectFit: "cover",
            objectPosition: "center",
            display: "block",
          }}
        />
      </div>
      <div style={{ padding: "0.9rem 1rem 1rem" }}>
        <p
          style={{
            margin: 0,
            fontWeight: 600,
            lineHeight: 1.35,
            fontSize: "0.98rem",
          }}
        >
          {"SGLang and Miles Add Day-0 Support for DeepSeek-V4.1"}
        </p>
        <p
          style={{
            margin: "0.55rem 0 0",
            fontSize: "0.85rem",
            opacity: 0.75,
          }}
        >
          {"September 10, 2026"}
        </p>
      </div>
    </a>
  </div>
</div>
{/* END_LMSYS_SGLANG_BLOG_CARDS */}

---

## Community and resources

- [Slack](https://slack.sglang.io/): Technical questions and development discussions.
- Events: [Meetups, workshops, and office hours](https://www.sglang.io/events) | [Developer meetings](https://meet.sglang.io/).
- Updates: [X](https://x.com/lmsysorg) | [LinkedIn](https://www.linkedin.com/company/sgl-project/) | [LMSYS Blog](https://lmsys.org/blog/).
- Contribute: [Contributor guide](/docs/developer_guide/contribution_guide) | [Roadmap](https://roadmap.sglang.io/).
- [Release notes](https://github.com/sgl-project/sglang/releases): Changes in each release.

---

### Cookbook Intro (`docs/cookbook/intro.mdx`)

---
title: SGLang Cookbook
metatags:
    description: The SGLang Cookbook is a practical collection of examples and guides that show developers how to efficiently run SGLang with a variety of models on different platforms.
---

A community-maintained repository of practical guides and recipes for deploying and using SGLang in production environments. Our mission is simple: answer the question **"How do I use SGLang (and related models) on hardware Y for task Z?"** with clear, actionable solutions.

import { popularModels } from "/src/snippets/configs/popular-models.jsx";
import { PopularModels } from "/src/snippets/_popular_models.jsx";

{/* Edit the list in /src/snippets/configs/popular-models.jsx — the docs landing
    page's featured hero reads the same file. */}
<PopularModels models={popularModels} />

## Guides

<CardGroup cols={3}>
  <Card
    title="Autoregressive Models"
    mode="card"
    href="./autoregressive/intro"
    img="/cards/Autoregressive-card.png"
  />
  <Card
    title="Diffusion Models"
    mode="card"
    href="./diffusion/intro"
    img="/cards/Diffusion-card.png"
  />
  <Card
    title="VLA (Vision-Language-Action) Models"
    mode="card"
    href="./vla/intro"
    img="/cards/VLA-card.png"
  />
</CardGroup>

## Benchmarks

<CardGroup cols={2}>
  <Card
    title="Autoregressive Model Benchmark"
    mode="card"
    href="./base/benchmarks/autoregressive_model_benchmark"
    img="/cards/Autoregressive-benchmark-card.png"
  />
  <Card
    title="Diffusion Model Benchmark"
    mode="card"
    href="./base/benchmarks/diffusion_model_benchmark"
    img="/cards/Diffusion-benchmark-card.png"
  />
</CardGroup>

---

### Cookbook Autoregressive Intro (`docs/cookbook/autoregressive/intro.mdx`)

---
title: Overview
mode: wide
description: Practical guides for deploying and using large language models and vision language models with SGLang.
metatags:
    description: "Explore SGLang autoregressive model cookbooks for LLM and VLM deployment, invocation, optimization, and benchmarking examples."
---

<CardGroup cols={3}>
  <Card
    title="Reflection"
    mode="card"
    href="/cookbook/autoregressive/Reflection/Beam-1_0"
    img="/cards/logos/reflection.png"
  />
  <Card
    title="IQuestLab"
    mode="card"
    href="/cookbook/autoregressive/IQuestLab/IQuest-Q1"
    img="/cards/logos/iquestlab.png"
  />
  <Card
    title="IFM"
    mode="card"
    href="/cookbook/autoregressive/IFM/K2-Horizon"
    img="/cards/logos/ifm.png"
  />
  <Card
    title="Kimi (Moonshot AI)"
    mode="card"
    href="/cookbook/autoregressive/Moonshotai/Kimi-K3"
    img="/cards/logos/moonshotai.png"
  />
  <Card
    title="Thinking Machines"
    mode="card"
    href="/cookbook/autoregressive/ThinkingMachines/Inkling"
    img="/cards/logos/thinkingmachines.png"
  />
  <Card
    title="GigaChat"
    mode="card"
    href="/cookbook/autoregressive/GigaChat/GigaChat3.5"
    img="/cards/logos/gigachat.png"
  />
  <Card
    title="GLM"
    mode="card"
    href="/cookbook/autoregressive/GLM/GLM-5.3-Flash"
    img="/cards/logos/glm.png"
  />
  <Card
    title="Qwen"
    mode="card"
    href="/cookbook/autoregressive/Qwen/Qwen3.8-Flash-Next"
    img="/cards/logos/qwen.png"
  />
  <Card
    title="DeepSeek"
    mode="card"
    href="/cookbook/autoregressive/DeepSeek/DeepSeek-V4_1"
    img="/cards/logos/deepseek.png"
  />
  <Card
    title="DeepReinforce"
    mode="card"
    href="/cookbook/autoregressive/DeepReinforce/Ornith-1.5"
    img="/cards/logos/deepreinforce.png"
  />
  <Card
    title="Meta"
    mode="card"
    href="/cookbook/autoregressive/Meta/MuseSparkOpen"
    img="/cards/logos/meta.png"
  />
  <Card
    title="Meituan"
    mode="card"
    href="/cookbook/autoregressive/Meituan/LongCat-2.0"
    img="/cards/logos/meituan.png"
  />
  <Card
    title="Google"
    mode="card"
    href="/cookbook/autoregressive/Google/Gemma4"
    img="/cards/logos/google.png"
  />
  <Card
    title="IBM"
    mode="card"
    href="/cookbook/autoregressive/IBM/Granite-4.2"
    img="/cards/logos/ibm.png"
  />
  <Card
    title="LiquidAI"
    mode="card"
    href="/cookbook/autoregressive/LiquidAI/LFM2.5"
    img="/cards/logos/liquidai.png"
  />
  <Card
    title="OpenAI"
    mode="card"
    href="/cookbook/autoregressive/OpenAI/GPT-OSS"
    img="/cards/logos/openai.png"
  />
  <Card
    title="MiniMax"
    mode="card"
    href="/cookbook/autoregressive/MiniMax/MiniMax-M3"
    img="/cards/logos/minimax.png"
  />
  <Card
    title="NVIDIA"
    mode="card"
    href="/cookbook/autoregressive/NVIDIA/Nemotron3.5-Super"
    img="/cards/logos/nvidia.png"
  />
  <Card
    title="Baidu"
    mode="card"
    href="/cookbook/autoregressive/Baidu/PaddleOCR-VL"
    img="/cards/logos/baidu.svg"
  />
  <Card
    title="Ernie"
    mode="card"
    href="/cookbook/autoregressive/Ernie/Ernie4.5"
    img="/cards/logos/ernie.png"
  />
  <Card
    title="StepFun"
    mode="card"
    href="/cookbook/autoregressive/StepFun/Step-5-Preview"
    img="/cards/logos/stepfun.png"
  />
  <Card
    title="InclusionAI"
    mode="card"
    href="/cookbook/autoregressive/InclusionAI/Ling-3.1-flash"
    img="/cards/logos/inclusionai.png"
  />
  <Card
    title="InternLM"
    mode="card"
    href="/cookbook/autoregressive/InternLM/Intern-S2-Mobius"
    img="/cards/logos/internlm.png"
  />
  <Card
    title="InternVL"
    mode="card"
    href="/cookbook/autoregressive/InternVL/InternVL3.5"
    img="/cards/logos/internvl.png"
  />
  <Card
    title="OpenBMB"
    mode="card"
    href="/cookbook/autoregressive/OpenBMB/MiniCPM-V-4_7"
    img="/cards/logos/openbmb.png"
  />
  <Card
    title="Jina AI"
    mode="card"
    href="/cookbook/autoregressive/Jina/Jina-reranker-m0"
    img="/cards/logos/jina.png"
  />
  <Card
    title="Mistral"
    mode="card"
    href="/cookbook/autoregressive/Mistral/Ministral-3"
    img="/cards/logos/mistral.png"
  />
  <Card
    title="Xiaomi"
    mode="card"
    href="/cookbook/autoregressive/Xiaomi/MiMo-V2.6"
    img="/cards/logos/xiaomi.png"
  />
  <Card
    title="FlashLabs"
    mode="card"
    href="/cookbook/autoregressive/FlashLabs/Chroma1.0"
    img="/cards/logos/flashlabs.png"
  />
  <Card
    title="Tencent"
    mode="card"
    href="/cookbook/autoregressive/Tencent/Hy4-Preview"
    img="/cards/logos/tencent.png"
  />
  <Card
    title="Recursive"
    mode="card"
    href="/cookbook/autoregressive/Recursive/Flint"
    img="/cards/logos/recursive.png"
  />
  <Card
    title="Poolside"
    mode="card"
    href="/cookbook/autoregressive/Poolside/Laguna-S-2.1"
    img="/cards/logos/poolside.png"
  />
  <Card
    title="Perplexity"
    mode="card"
    href="/cookbook/autoregressive/Perplexity/PPLX-Decider-v1.1-27B"
    img="/cards/logos/perplexity.png"
  />
  <Card
    title="Cloudflare"
    mode="card"
    href="/cookbook/autoregressive/Cloudflare/clef"
    img="/cards/logos/cloudflare.png"
  />
  <Card
    title="Kev"
    mode="card"
    href="/cookbook/autoregressive/Kev/kev"
  />
</CardGroup>

---

### Cookbook Diffusion README (`docs/cookbook/diffusion/README.mdx`)

---
title: "Diffusion Cookbook"
description: "Author and review deployment-focused diffusion model recipes for SGLang."
metatags:
    description: "SGLang diffusion cookbook structure, model-page standards, and contribution guidance."
---

# SGLang Diffusion Cookbook

The diffusion cookbook is a set of model-specific, validated deployment guides. Each page
should let a reader answer three questions quickly: what the model is good at, which
checkpoint and base topology to choose, and which optional features change performance,
memory, or quality.

## What every model page includes

1. A compact capability tag row using the shared `DiffusionModelTags` component.
2. A short introduction that states the model's capability range, strongest use case, and
   an important limitation or deployment tradeoff.
3. Verified base launch recipes for the hardware actually tested.
4. Matching request examples for every public task or checkpoint partition.
5. Optional attention, quantization, caching, compile, and offload recipes with explicit
   quality contracts and validation scope.

Tags describe the model, not every runtime flag. Prefer `video + audio`, `multi-reference`,
or `4–15 seconds` over generic labels such as `native`, `fast`, or `high quality`.

## Keep the command picker small

The command picker selects a runnable base recipe: hardware topology, checkpoint partition,
request mode, and a validated placement profile. Independent feature knobs do not need to
become picker dimensions.

Document orthogonal controls as feature overlays instead:

| Feature class | Where it belongs | Required context |
| --- | --- | --- |
| Attention backend | Optional feature overlays | Default backend, precision/approximation contract, installation, measured hardware |
| Online or pre-quantized weights | Optional feature overlays | Weight source, protected precision-sensitive layers, quality and memory tradeoff |
| Cache-DiT and sampling controls | Request/sampling recipes | Quality level, incompatible placement modes, task-specific validation |
| TP, Ulysses, Ring, FSDP, residency | Base picker only for verified cells | Exact GPU count, topology, memory, and latency evidence |

For memory placement, prefer the unified
[`--component-residency`](/docs/sglang-diffusion/api/cli#component-residency)
selector. Each component resolves to exactly one of `resident`,
`component-offload`, or `layerwise-offload`. Existing options such as
`--dit-cpu-offload`, `--text-encoder-cpu-offload`,
`--image-encoder-cpu-offload`, and `--vae-cpu-offload` remain supported by all
recipes that already use them.

## Contributing a model

Use the repo-local `cookbook-add-model` skill and its
`templates/diffusion-page.mdx.tmpl` template. The full category contract lives in
`.claude/skills/cookbook-add-model/references/diffusion-authoring.md`.

Before opening a PR, run:

```bash Command
node docs/scripts/check_cookbook_configs.mjs
cd docs
mint validate
mint broken-links --check-anchors --check-redirects
```

The static cookbook check requires every diffusion model page to use the shared tag widget,
the standard introduction heading, 4–6 tags, and a substantive two-paragraph lead. Mintlify
validation then catches MDX, navigation, and internal-link problems.

For runtime concepts and platform support, see the
[SGLang Diffusion documentation](/docs/sglang-diffusion/index) and
[supported model catalog](/docs/sglang-diffusion/compatibility_matrix).

---

### Cookbook Diffusion Intro (`docs/cookbook/diffusion/intro.mdx`)

---
title: Overview
mode: wide
description: Practical guides for deploying and using diffusion models with SGLang.
metatags:
    description: "Explore SGLang diffusion model cookbooks for image and video generation deployment, invocation, optimization, and benchmarking examples."
---

Choose a recipe by output modality. The sidebar stays organized by model family, while this overview separates image, video, and realtime/world workloads.

## Image Models

Image models generate one image request as a bounded denoising job, usually with bidirectional attention over the whole latent sequence.

<CardGroup cols={3}>
  <Card
    title="HunyuanImage-3.0-Instruct"
    mode="card"
    href="/cookbook/diffusion/Tencent/HunyuanImage3"
    img="/cards/logos/tencent.png"
  />
  <Card
    title="FLUX"
    mode="card"
    href="/cookbook/diffusion/FLUX/FLUX"
    img="/cards/logos/flux.png"
  />
  <Card
    title="Ideogram 4"
    mode="card"
    href="/cookbook/diffusion/Ideogram/Ideogram4"
    img="/cards/logos/ideogram.png"
  />
  <Card
    title="Qwen-Image"
    mode="card"
    href="/cookbook/diffusion/Qwen-Image/Qwen-Image-2.1"
    img="/cards/logos/qwen.png"
  />
  <Card
    title="SenseNova-U1.5"
    mode="card"
    href="/cookbook/diffusion/SenseNova/SenseNova-U1.5-8B-MoT"
    img="/cards/logos/internvl.png"
  />
  <Card
    title="LongCat-Image"
    mode="card"
    href="/cookbook/diffusion/LongCat/LongCat-Image"
    img="/cards/logos/meituan.png"
  />
  <Card
    title="Z-Image"
    mode="card"
    href="/cookbook/diffusion/Z-Image/Z-Image-Turbo"
    img="/cards/logos/zimage.png"
  />
  <Card
    title="Ming-Image"
    mode="card"
    href="/cookbook/diffusion/inclusionAI/Ming-Image"
    img="/cards/logos/inclusionai.png"
  />
  <Card
    title="Krea"
    mode="card"
    href="/cookbook/diffusion/Krea/Krea-2"
    img="/cards/logos/krea.png"
  />
  <Card
    title="ERNIE-Image"
    mode="card"
    href="/cookbook/diffusion/Ernie-Image/Ernie-Image"
    img="/cards/logos/ernie.png"
  />
</CardGroup>

## Video Models

Video models denoise a bounded latent video sequence for each request. Use these recipes for offline text-to-video, image-to-video, and video generation serving.

<CardGroup cols={3}>
  <Card
    title="FLUX.3"
    mode="card"
    href="/cookbook/diffusion/FLUX/FLUX.3"
    img="/cards/logos/flux.png"
  />
  <Card
    title="Cosmos"
    mode="card"
    href="/cookbook/diffusion/Cosmos/Cosmos3"
    img="/cards/logos/nvidia.png"
  />
  <Card
    title="Wan"
    mode="card"
    href="/cookbook/diffusion/Wan/Wan2.2"
    img="/cards/logos/wan.png"
  />
  <Card
    title="LongLive 2.0"
    mode="card"
    href="/cookbook/diffusion/LongLive/LongLive-2.0"
    img="/cards/logos/nvidia.png"
  />
  <Card
    title="LTX"
    mode="card"
    href="/cookbook/diffusion/LTX/LTX2 & LTX2.3"
    img="/cards/logos/ltx.svg"
  />
  <Card
    title="SANA-Video"
    mode="card"
    href="/cookbook/diffusion/SANA-Video/SANA-Video"
    img="/cards/logos/sana.png"
  />
  <Card
    title="JoyAI-Echo"
    mode="card"
    href="/cookbook/diffusion/JoyEcho/JoyEcho"
    img="/cards/logos/joyai-echo.svg"
  />
  <Card
    title="MOVA"
    mode="card"
    href="/cookbook/diffusion/MOVA/MOVA"
    img="/cards/logos/mova.png"
  />
  <Card
    title="MiniMax-H3"
    mode="card"
    href="/cookbook/diffusion/MiniMax/MiniMax-H3"
    img="/cards/logos/minimax.png"
  />
  <Card
    title="MOSS-Image"
    icon="image"
    mode="card"
    href="/cookbook/diffusion/OpenMOSS/MOSS-Image"
  />
  <Card
    title="LingBot Video MoE"
    mode="card"
    href="/cookbook/diffusion/LingBot-Video/LingBot-Video-MoE"
    img="/cards/logos/inclusionai.png"
  />
</CardGroup>

## Realtime / World Models

Realtime models keep a session alive and generate chunk by chunk with causal state, control signals, and cached video history.

<CardGroup cols={3}>
  <Card
    title="LingBot World"
    mode="card"
    href="/cookbook/diffusion/LingBot-World/LingBot-World-2.0"
    img="/cards/logos/inclusionai.png"
  />
  <Card
    title="SANA-WM"
    mode="card"
    href="/cookbook/diffusion/SANA-WM/SANA-WM"
    img="/cards/logos/sana.png"
  />
</CardGroup>

Use the sidebar group for LingBot World family variants. The overview links the newer LingBot World 2.0 recipe directly.

---

### Cookbook Omni Intro (`docs/cookbook/omni/intro.mdx`)

---
title: Overview
mode: wide
description: Practical guides for deploying and using omni models (TTS, audio) with SGLang.
metatags:
    description: "Explore SGLang omni model cookbooks for speech, audio, and multimodal deployment examples."
---

<CardGroup cols={3}>
  <Card
    title="FishAudio"
    mode="card"
    href="/cookbook/omni/FishAudio/S2-Pro.mdx"
    img="/cards/logos/fishaudio.png"
  />
</CardGroup>

---

### Cookbook Vla Intro (`docs/cookbook/vla/intro.mdx`)

---
title: Overview
mode: wide
description: Practical guides for deploying and using Vision-Language-Action policies with SGLang.
metatags:
    description: "Explore SGLang Vision-Language-Action policy cookbooks for robot action serving, OpenPI compatibility, caching, and performance tuning."
---

Vision-Language-Action policies map camera observations, language instructions, and robot state into continuous action chunks. They share some runtime machinery with diffusion pipelines, but the user-facing workload is robot action inference rather than image or video generation.

This section keeps VLA policies separate from the diffusion model cookbook so robot deployments can document their own input schemas, policy endpoints, cache behavior, and control-loop performance targets.

## OpenPI

<CardGroup cols={2}>
  <Card
    title="Pi0.5"
    mode="card"
    href="/cookbook/vla/OpenPI/Pi0.5"
  />
</CardGroup>

## FLUX

<CardGroup cols={2}>
  <Card
    title="FLUX 3 Action"
    mode="card"
    href="/cookbook/vla/FLUX/FLUX-3-Action"
  />
</CardGroup>

---

### Docs Advanced Features Overview (`docs/docs/advanced_features/overview.mdx`)

---
title: Advanced Features
description: Advanced configuration, optimization, and deployment features for SGLang.
---

- [Server Arguments](./server_arguments)
- [Session-Aware Radix Cache](./session_radix_cache)
- [Hyperparameter Tuning](./hyperparameter_tuning)
- [Attention Backend](./attention_backend)
- [Speculative Decoding](./speculative_decoding)
- [Structured Outputs](./structured_outputs)
- [Quantization](./quantization)
- [Expert Parallelism](./expert_parallelism)
- [Prefill Context Parallelism](./prefill_cp)
- [Decode Context Parallelism](./dcp)
- [LoRA](./lora)
- [PD Disaggregation](./pd_disaggregation)
- [Pipeline Parallelism](./pipeline_parallelism)
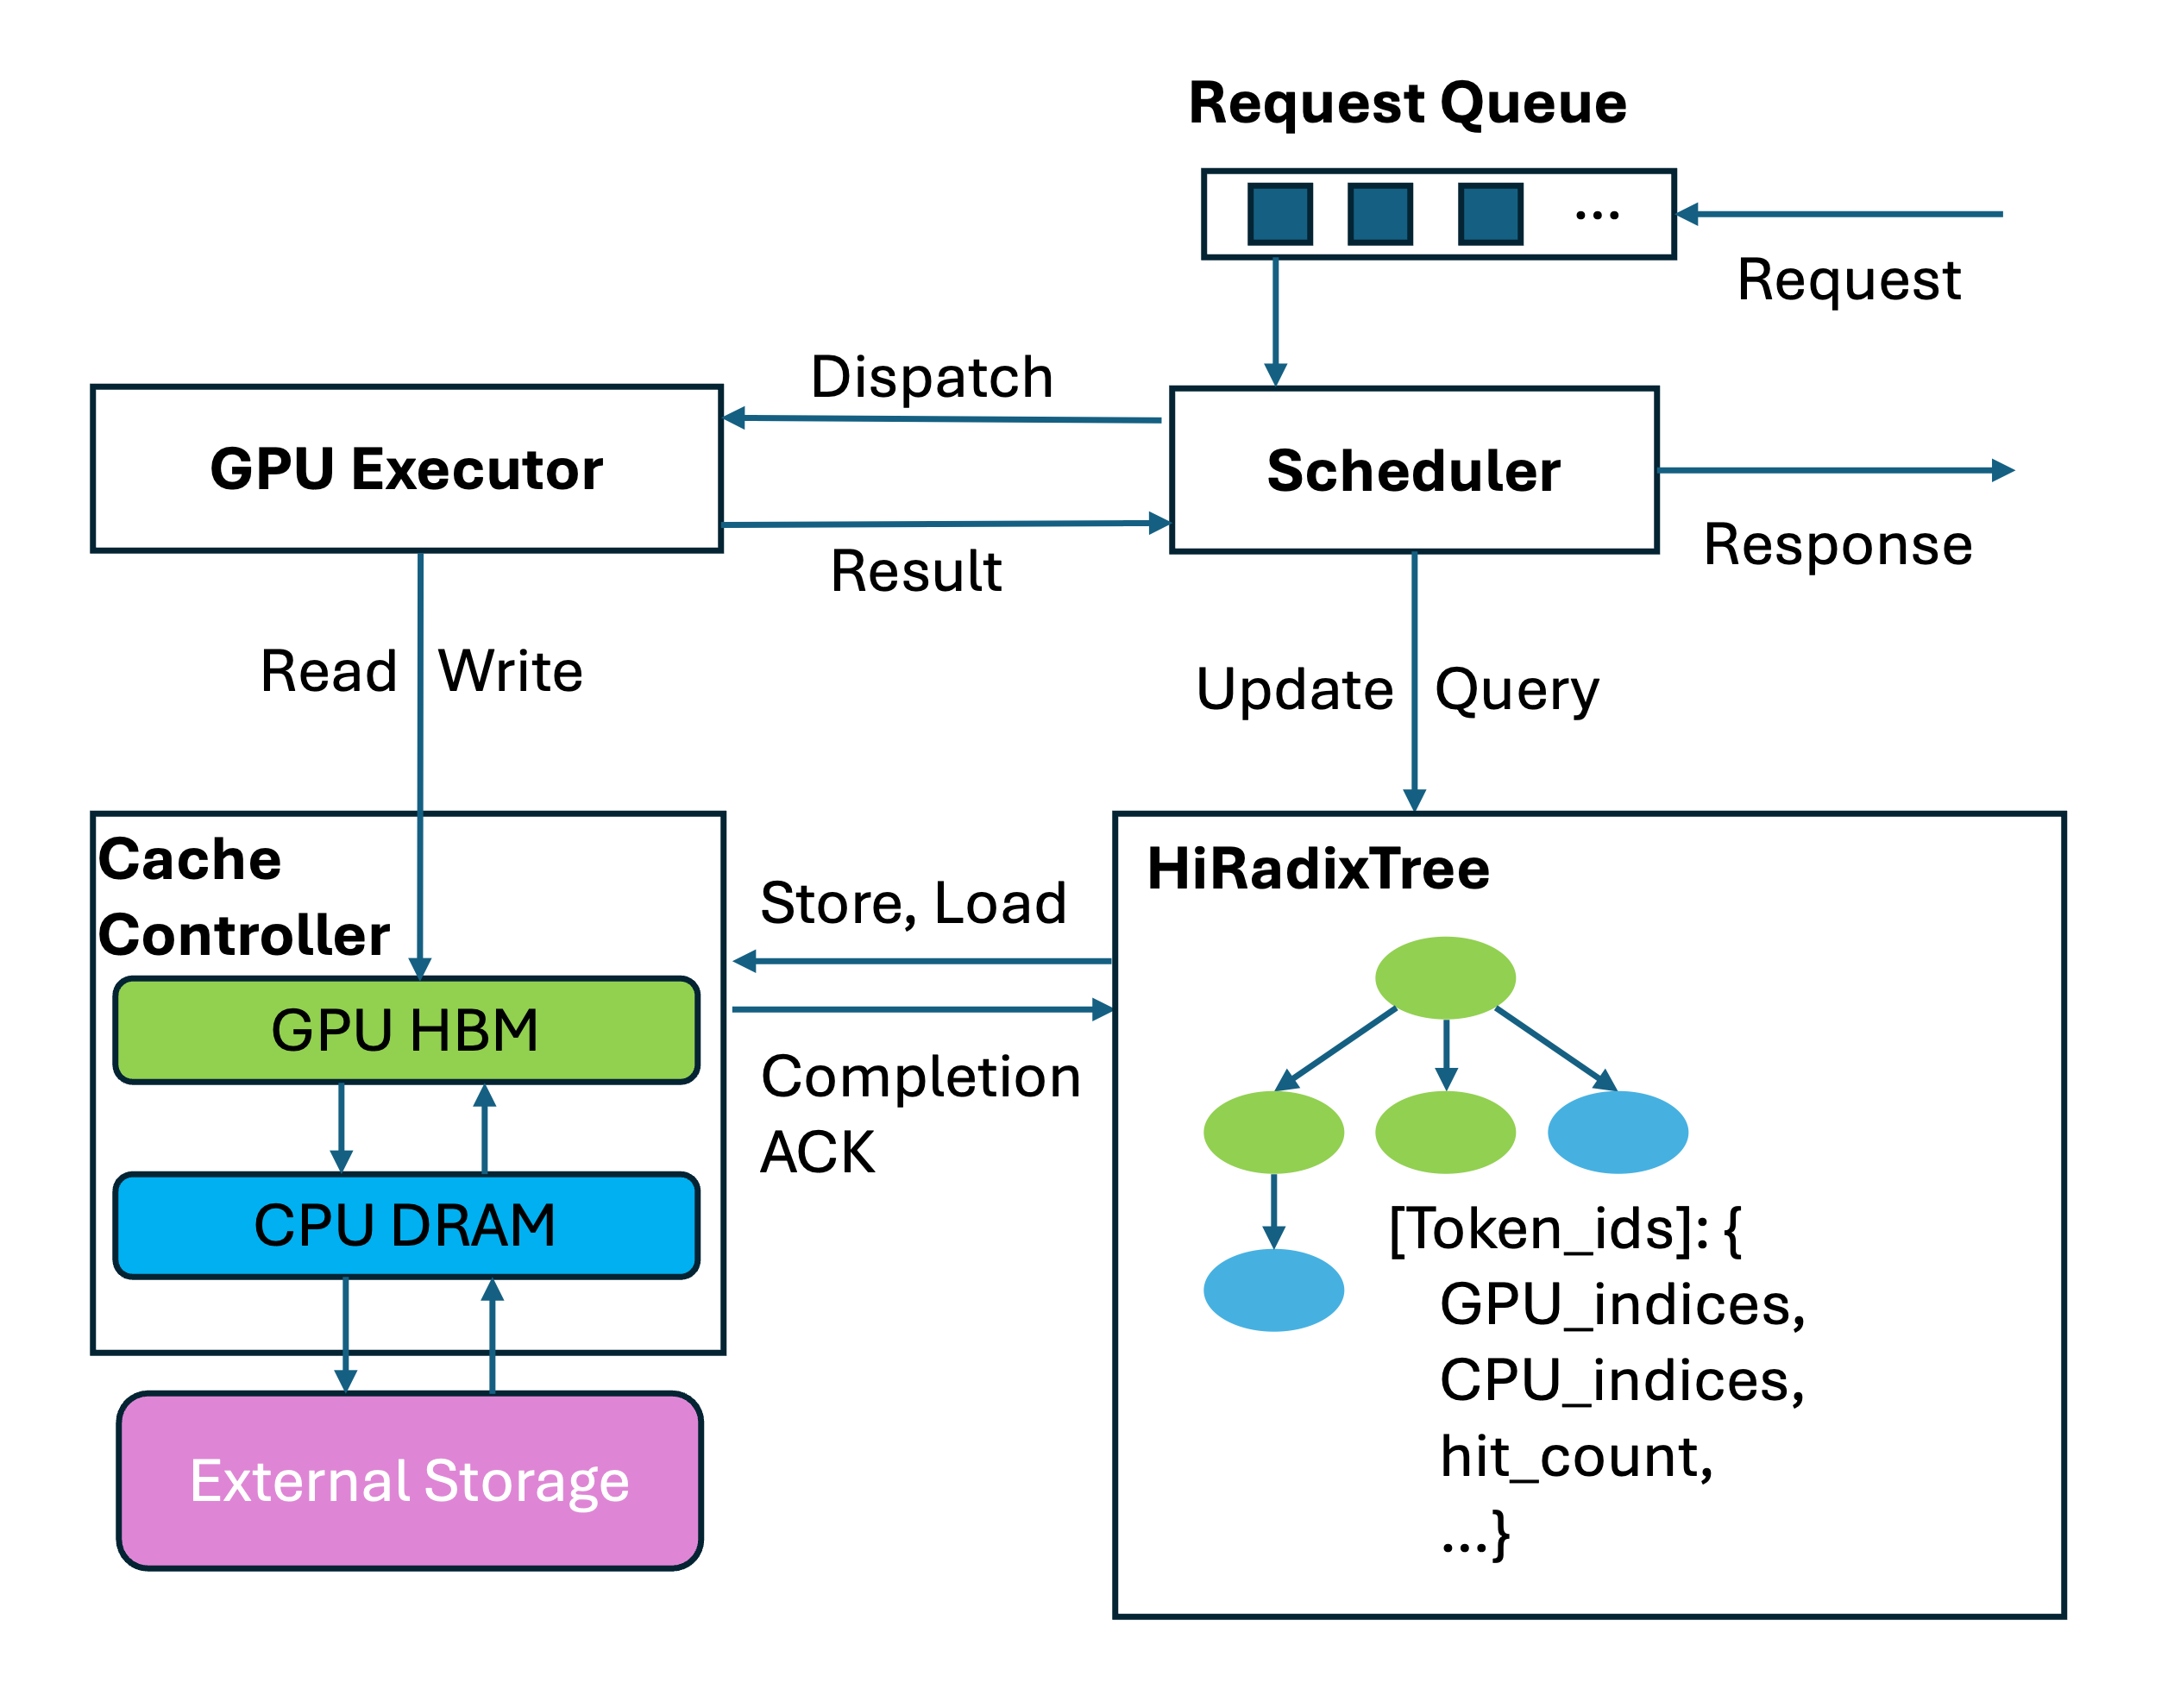
- [HiCache](./hicache_best_practices)
- [SGLang Simulator](./sglang_simulator)
- [Observability](./observability)
- [And more…](./server_arguments)

---

### Docs Basic Usage Overview (`docs/docs/basic_usage/overview.mdx`)

---
title: Basic Usage
description: Core APIs and common usage patterns for SGLang.
---

- [OpenAI-Compatible APIs](./openai_api_completions) — Chat completions, vision, and embeddings
- [Anthropic-Compatible API](./anthropic_api) — `/v1/messages`, including Claude Code integration
- [Ollama API](./ollama_api)
- [Offline Engine API](./offline_engine_api)
- [Native API](./native_api)
- [Sampling Parameters](./sampling_params)
- [Popular Model Usage](/cookbook/autoregressive/intro) — DeepSeek, GLM, Qwen, Llama, and more

---

### Docs Developer Guide Overview (`docs/docs/developer_guide/overview.mdx`)

---
title: Developer Guide
description: Contributing to SGLang — development setup, benchmarking, and evaluation.
---

- [Contribution Guide](./contribution_guide)
- [Add an out-of-tree serve backend](/docs/developer_guide/serve_backend_plugins)
- [Development Guide (Docker)](./development_guide_using_docker)
- [JIT Kernels](./development_jit_kernel_guide)
- [Quantization Contribution Guide](./quantization_contribution_guide)
- [Layer boundaries](/docs/developer_guide/layer_boundary)
- [Benchmark and Profiling](./benchmark_and_profiling)
- [Bench Serving](./bench_serving)
- [Evaluating New Models](./evaluating_new_models)
- [MSProbe Debugging Guide](./msprobe_debugging_guide)

---

### Docs Get Started Quickstart (`docs/docs/get-started/quickstart.mdx`)

---
title: "Quickstart"
description: "Start a model server and verify it with one request."
---

## Install and start

These commands target Linux with an NVIDIA GPU and a CUDA 13-compatible driver. See [Installation](/docs/get-started/install) for environment requirements and other setup options.

<Tabs>
<Tab title="Docker">

With Docker and NVIDIA Container Toolkit configured, pull the image. Skip this command if you have already pulled it:

```bash
docker pull lmsysorg/sglang:latest
```

Start the server on the GPU host. Replace `MODEL_PATH` with your Hugging Face model ID (for example, `Qwen/Qwen3-0.6B`):

```bash
docker run --rm --gpus all --ipc=host \
  -p 30000:30000 \
  lmsysorg/sglang:latest \
  sglang serve MODEL_PATH --host 0.0.0.0 --port 30000
```

</Tab>
<Tab title="uv">

With uv installed, create a Python environment and install SGLang. Skip this block if you already have an environment with SGLang installed:

```bash
uv venv --python 3.12
source .venv/bin/activate
uv pip install --prerelease=allow sglang
```

Start the server in that environment. Replace `MODEL_PATH` with your Hugging Face model ID (for example, `Qwen/Qwen3-0.6B`):

```bash
sglang serve MODEL_PATH --host 0.0.0.0 --port 30000
```

</Tab>
</Tabs>

For additional model-specific launch arguments, see the [Cookbook](/cookbook/intro). Wait for `The server is fired up and ready to roll!`.

## Send a request

In another terminal on the same host, send a request to verify the server. Use the same model ID for `MODEL_PATH`:

```bash
curl http://localhost:30000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "MODEL_PATH",
    "messages": [
      {"role": "user", "content": "What is the capital of France?"}
    ]
  }'
```

Check `choices[0].message.content` for the answer. Press `Ctrl+C` in the server terminal to stop.

See [Examples](/docs/get-started/examples) for a complete 27B deployment, streaming, and tool calls.

---

### Docs Hardware Platforms Overview (`docs/docs/hardware-platforms/overview.mdx`)

---
title: Hardware Platforms
description: Platform-specific guides for running SGLang on GPUs, TPUs, NPUs, CPUs, and more.
---

- [NVIDIA GPUs](./nvidia-gpus)
- [AMD GPUs](./amd_gpu)
- [Ascend NPUs](./ascend-npus/getting-started/installation)
- [CPU Server](./cpu_server)
- [NVIDIA Jetson Orin](./nvidia_jetson)
- [TPU](./tpu)
- [XPU](./xpu)
- [Moore Threads GPUs](./mthreads_gpu)

---

### Docs References Overview (`docs/docs/references/overview.mdx`)

---
title: References
description: FAQ, environment variables, production metrics, deployment guides, and more.
---

- [FAQ](./faq)
- [Environment Variables](./environment_variables)
- [Production Metrics](./production_metrics)
- [Production Request Trace](./production_request_trace)
- [Multi-Node Deployment](./multi_node_deployment/multi_node)
- [Custom Chat Template](./custom_chat_template)
- [Frontend Language](./frontend/frontend_tutorial)
- [Post-Training Integration](./post_training_integration)

---

### Docs Sglang Diffusion Index (`docs/docs/sglang-diffusion/index.mdx`)

---
title: SGLang Diffusion
description: Accelerated image and video generation with diffusion models.
---
SGLang Diffusion is SGLang's built-in inference engine for image and video generation. It ships in the same [repository](https://github.com/sgl-project/sglang) and `sglang` Python package, using the shared `sglang generate` and `sglang serve` commands.

It provides native SGLang pipelines, diffusers backend support, an OpenAI-compatible server, and an optimized kernel stack built on both precompiled `sgl-kernel` operators and JIT kernels for key inference paths.

## Key Features

- Broad model support across Wan, Hunyuan, Qwen-Image, FLUX, Z-Image, GLM-Image, and more
- Fast inference with `sgl-kernel`, JIT kernels, scheduler improvements, and caching acceleration
- Multiple interfaces: `sglang generate`, `sglang serve`, and an OpenAI-compatible API
- Multi-platform support for NVIDIA, AMD, Intel XPU, Ascend, Apple Silicon, and Moore Threads

## Quick Start

Start with the [recommended Docker setup](/docs/sglang-diffusion/installation) for Linux GPU deployments. The installation guide also covers pip/uv, source installation, and other platforms.

Run the following commands inside the container or your activated Python environment. Generate an image:

```bash
sglang generate --model-path Qwen/Qwen-Image \
  --prompt "A beautiful sunset over the mountains" \
  --save-output
```

Or start an HTTP server:

```bash
sglang serve --model-path Qwen/Qwen-Image --host 0.0.0.0 --port 30000
```

## Start Here

- [Installation](/docs/sglang-diffusion/installation): install SGLang Diffusion and platform dependencies
- [Supported Models](/docs/sglang-diffusion/compatibility_matrix): browse supported model families, tasks, and public checkpoints
- [CLI](/docs/sglang-diffusion/api/cli): run one-off generation jobs or launch a persistent server
- [OpenAI-Compatible API](/docs/sglang-diffusion/api/openai_api): send image and video requests to the HTTP server
- [ComfyUI plugin](/docs/sglang-diffusion/comfyui): use SGLang from ComfyUI in server mode or as a per-step DiT backend
- [Performance Overview](/docs/sglang-diffusion/performance-optimization): choose speed, memory, parallelism, caching, and quality-tradeoff levers
- [Caching Acceleration](/docs/sglang-diffusion/caching-acceleration): use Cache-DiT, TeaCache, or Spectrum to reduce denoising cost
- [Quantization](/docs/sglang-diffusion/quantization): configure component checkpoint and causal KV-cache quantization
- [Realtime and Causal Video Models](/docs/sglang-diffusion/realtime_models): understand session state, causal caches, and realtime-only controls
- [Contributing](/docs/sglang-diffusion/contributing): contribution workflow, adding new models, and CI perf baselines

## Additional Documentation

- [Post-Processing](/docs/sglang-diffusion/api/post_processing): frame interpolation and upscaling
- [Models with AR Stage](/docs/sglang-diffusion/models_with_ar): run hybrid diffusion pipelines like GLM-Image with a separate AR encoder server
- [Models with Prompt Enhancement](/docs/sglang-diffusion/models_with_pe): run ERNIE-Image with either built-in PE or a separate PE server
- [Deployment and Performance Modes](/docs/sglang-diffusion/deployment_cookbook): choose `--performance-mode`, offload, FSDP, CFG parallelism, SP, and TP
- [Attention Backends](/docs/sglang-diffusion/attention_backends): choose the best backend for your model and hardware
- [Sequence Parallelism](/docs/sglang-diffusion/ring_sp_performance): configure SP, Ulysses, and ring-based splitting for long sequences
- [Encoder Parallelism](/docs/sglang-diffusion/encoder_parallel): fold, data-parallel, or replicate the text/image encoders across idle GPUs
- [Inference Batching](/docs/sglang-diffusion/dynamic_batching): batch compatible native diffusion requests during serving
- [Progressive Resolution Generation](/docs/sglang-diffusion/progressive_resolution): run early denoising steps at lower latent resolution for selected pipelines
- [Environment Variables](/docs/sglang-diffusion/environment_variables): platform, caching, storage, and debugging configuration

## Developer Documentation

- [Support New Models](/docs/sglang-diffusion/support_new_models): implementation guide for new diffusion pipelines
- [CI Performance Baselines](/docs/sglang-diffusion/ci_perf): generate and update performance baselines used in CI

## References

- [SGLang GitHub](https://github.com/sgl-project/sglang)
- [Cache-DiT](https://github.com/vipshop/cache-dit)
- [FastVideo](https://github.com/hao-ai-lab/FastVideo)
- [xDiT](https://github.com/xdit-project/xDiT)
- [Diffusers](https://github.com/huggingface/diffusers)

---

### Docs References Frontend Frontend Index (`docs/docs/references/frontend/frontend_index.mdx`)

---
title: "Frontend Language"
metatags:
    description: "SGLang frontend language documentation: tutorials and choices methods reference."
---
- [Frontend Tutorial](./frontend_tutorial)
- [Choices Methods](./choices_methods)

---

### Docs References Multi Node Deployment Multi Node Index (`docs/docs/references/multi_node_deployment/multi_node_index.mdx`)

---
title: "Multi-Node Deployment"
metatags:
    description: "SGLang multi-node deployment index: K8s, LWS, RBG, PD disaggregation guides."
---
- [Multi Node](./multi_node)
- [Deploy On K8S](./deploy_on_k8s)
- [Lws Pd Deploy](./lws_pd/lws_pd_deploy)
- [Deepseekv32 Pd](./rbg_pd/deepseekv32_pd)
- [Deploying DeepSeek with PD Disaggregation on 96 H100 GPUs](https://lmsys.org/blog/2025-05-05-large-scale-ep/)
- [Deploying Kimi K2 with PD Disaggregation on 128 H200 GPUs](https://lmsys.org/blog/2025-07-20-k2-large-scale-ep/)

---

### Python Sglang Srt Mem Cache Storage Hf3fs Docs README (`python/sglang/srt/mem_cache/storage/hf3fs/docs/README.md`)

# Using HF3FS as L3 Global KV Cache

This document provides step-by-step instructions for setting up a k8s + 3FS + SGLang runtime environment from scratch, describing how to utilize deepseek-hf3fs as the L3 KV cache for SGLang.
The process consists of five main steps:

## Step 1: Install deepseek-3fs via 3fs-Operator
Refer to the [3fs-operator documentation](https://github.com/aliyun/kvc-3fs-operator/blob/main/README_en.md) to deploy 3FS components in your Kubernetes environment using the Operator with one-click deployment.

## Step 2: Launch SGLang Pod
Start your SGLang Pod while specifying 3FS-related labels in the YAML configuration. Follow the [fuse-client-creation guide](https://github.com/aliyun/kvc-3fs-operator/blob/main/README_en.md#fuse-client-creation).

## Step 3: Configure Usrbio Client in SGLang Pod
The Usrbio client is required for accessing 3FS. Install it in your SGLang Pod using either method below:

**Alternative 1 (Recommend):** Built from the source code, the following provides quick installation commands (refer to [setup_usrbio_client.md](setup_usrbio_client.md))

```
set -e; \
. /etc/os-release; \
case "$VERSION_ID" in \
  "22.04") \
    CLANG_VERSION="14"; \
    GIT_BRANCH=main; \
    GIT_COMMIT_ID=6f029c439d0d22995900ca357d51b37975c6ffb5; \
    ;; \
  "24.04") \
    CLANG_VERSION="18"; \
    GIT_BRANCH="ubuntu24.04"; \
    GIT_COMMIT_ID=d0cf83a42395cdb2a66d3ce83cb0a11a46bee9f3; \
  ;; \
  *) \
    echo "Unsupported Ubuntu version: $VERSION_ID"; \
    exit 1; \
  ;; \
esac; \
apt-get update && apt-get install -y --no-install-recommends \
        clang-format-$CLANG_VERSION clang-$CLANG_VERSION clang-tidy-$CLANG_VERSION lld-$CLANG_VERSION meson google-perftools \
        libaio-dev libdouble-conversion-dev libdwarf-dev libgflags-dev libgmock-dev libgoogle-perftools-dev liblz4-dev liblzma-dev libuv1-dev \
        && rm -rf /var/lib/apt/lists/* \
        && apt-get clean \
        && git clone https://github.com/novitalabs/3FS.git -b $GIT_BRANCH 3fs \
        && cd 3fs \
        && git checkout $GIT_COMMIT_ID \
        && git submodule update --init --recursive \
        && ./patches/apply.sh \
        && CMAKE_BUILD_PARALLEL_LEVEL=32 python3 setup.py bdist_wheel -d dist \
        && pip install dist/*.whl \
        && cd .. \
        && rm -rf 3fs
export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib/python3.12/dist-packages
```

**Alternative 2:** Run `pip3 install hf3fs-py-usrbio` (Follow https://pypi.org/project/hf3fs-py-usrbio/#files)

## Step 4: Deploy Model Serving

### Single Node Deployment
```bash
export LD_LIBRARY_PATH=$LD_LIBRARY_PATH:/usr/local/lib/python3.12/dist-packages
python3 -m sglang.launch_server \
    --model-path /code/models/Qwen3-32B/ \
    --host 0.0.0.0 --port 10000 \
    --page-size 64 \
    --enable-hierarchical-cache \
    --hicache-ratio 2 --hicache-size 0 \
    --hicache-write-policy write_through \
    --hicache-storage-backend hf3fs
```

### Multi-Node Deployment (Shared KV Cache)
Follow the [deploy_sglang_3fs_multinode.md](deploy_sglang_3fs_multinode.md) guide to deploy SGLang with 3FS across multiple nodes for shared KV caching.

---

### AGENTS (`docs/AGENTS.md`)

---
name: sglang-docs-mintlify
description: Build and maintain the SGLang documentation site and integrated cookbook using Mintlify. Use when
  creating docs pages, configuring navigation, adding components, or setting up
  API references.
license: Apache-2.0
compatibility: Requires Node.js for CLI. Works with any Git-based workflow.
metadata:
  author: SGLang Team
  version: "1.0"
  mintlify-proj: mintlify
---

# SGLang Mintlify documentation guide for agents

## Non-negotiables

- **Do not guess flags, defaults, or behavior.**
  If you’re documenting CLI args, env vars, APIs, or performance behavior, verify against:
  - the upstream codebase (`sgl-project/sglang`)
  - the current public docs (`docs.sglang.io`) until the migration is complete
  - or an authoritative vendor doc when platform-specific (ROCm, CANN/Ascend, Intel XPU).
- **Prefer fixing the docs-site version of an internal link** instead of copying links from older docs.
- **Keep examples copy/pasteable.** Use placeholders consistently (e.g., `MODEL_PATH`, `HF_TOKEN`, `HOST`, `PORT`).

## Source of truth hierarchy

1. **This repo**
   - `docs.json` for site structure + navigation
   - existing MDX pages for voice + conventions
2. **Canonical current docs**
   - `docs.sglang.io` (Sphinx site) is currently the reference structure and content baseline.
3. **Implementation**
   - `sgl-project/sglang` for anything that can change with releases (flags, env vars, defaults, supported models).
4. **Cookbook**
   - `cookbook.sglang.io` / `sgl-project/sgl-cookbook` for recipe patterns and model-specific operational guidance.

## Writing standards (SGLang-specific)

### Voice and structure

* Second person (“you”), active voice.
* Prefer **short, scannable sections** with clear outcomes.
* Headings in **sentence case**.
* Put prerequisites before commands.

### Technical accuracy patterns

For pages that include commands/configs, always specify:

* **Platform** (NVIDIA CUDA / AMD ROCm / Intel XPU / Ascend NPU / CPU)
* **OS** (if relevant) and **version constraints**
* **Model identifier** format (e.g., Hugging Face repo id) and where it goes (`--model-path`, `--model`, etc.)
* **Parallelism knobs** used in the example (`--tp`, `--dp`, node count, etc.)
* Any required secrets/tokens (`HF_TOKEN`) and where they are used.

# Mintlify best practices

**Always consult [mintlify.com/docs](https://mintlify.com/docs) for components, configuration, and latest features.**

If you are not already connected to the Mintlify MCP server, [https://mintlify.com/docs/mcp](https://mintlify.com/docs/mcp), add it so that you can search more efficiently.

**Always** favor searching the current Mintlify documentation over whatever is in your training data about Mintlify.

Mintlify is a documentation platform that transforms MDX files into documentation sites. Configure site-wide settings in the `docs.json` file, write content in MDX with YAML frontmatter, and favor built-in components over custom components.

Full schema at [mintlify.com/docs.json](https://mintlify.com/docs.json).

## Before you write

### Understand the project

Read `docs.json` in the project root. This file defines the entire site: navigation structure, theme, colors, links, API and specs.

Understanding the project tells you:

* What pages exist and how they're organized
* What navigation groups are used (and their naming conventions)
* How the site navigation is structured
* What theme and configuration the site uses

### Check for existing content

Search the docs before creating new pages. You may need to:

* Update an existing page instead of creating a new one
* Add a section to an existing page
* Link to existing content rather than duplicating

### Read surrounding content

Before writing, read 2-3 similar pages to understand the site's voice, structure, formatting conventions, and level of detail.

### Understand Mintlify components

Review the Mintlify [components](https://www.mintlify.com/docs/components) to select and use any relevant components for the documentation request that you are working on.

## Quick reference

### CLI commands

* `npm i mint` - Install the Mintlify CLI
* `mint dev` - Local preview at localhost:3000
* `mint broken-links` - Check internal links
* `mint a11y` - Check for accessibility issues in content
* `mint rename` - Rename/move files and update references
* `mint validate` - Validate documentation builds

### Required files

* `docs.json` - Site configuration (navigation, theme, integrations, etc.). See [global settings](https://www.mintlify.com/docs/organize/settings) for all options.
* `*.mdx` files - Documentation pages with YAML frontmatter

### Example file structure

```
project/
├── docs.json           # Site configuration
├── introduction.mdx
├── quickstart.mdx
├── guides/
│   └── example.mdx
├── openapi.yml         # API specification
├── images/             # Static assets
│   └── example.png
└── snippets/           # Reusable components
    └── component.jsx
```

## Page frontmatter

Every page requires `title` in its frontmatter. Include `description` for SEO and navigation.

```yaml theme={null}
---
title: "Clear, descriptive title"
description: "Concise summary for SEO and navigation."
---
```

Optional frontmatter fields:

* `sidebarTitle`: Short title for sidebar navigation.
* `icon`: Lucide or Font Awesome icon name, URL, or file path.
* `tag`: Label next to the page title in the sidebar (for example, "NEW").
* `mode`: Page layout mode (`default`, `wide`, `custom`).
* `keywords`: Array of terms related to the page content for local search and SEO.
* Any custom YAML fields for use with personalization or conditional content.

## File conventions

* Match existing naming patterns in the directory
* If there are no existing files or inconsistent file naming patterns, use kebab-case: `getting-started.mdx`, `api-reference.mdx`
* Use root-relative paths without file extensions for internal links: `/getting-started/quickstart`
* Do not use relative paths (`../`) or absolute URLs for internal pages
* When you create a new page, add it to `docs.json` navigation or it won't appear in the sidebar

## Organize content

When a user asks about anything related to site-wide configurations, start by understanding the [global settings](https://www.mintlify.com/docs/organize/settings). See if a setting in the `docs.json` file can be updated to achieve what the user wants.

### Navigation

The `navigation` property in `docs.json` controls site structure. Choose one primary pattern at the root level, then nest others within it.

**Choose your primary pattern:**

| Pattern       | When to use                                                                                    |
| ------------- | ---------------------------------------------------------------------------------------------- |
| **Groups**    | Default. Single audience, straightforward hierarchy                                            |
| **Tabs**      | Distinct sections with different audiences (Guides vs API Reference) or content types          |
| **Anchors**   | Want persistent section links at sidebar top. Good for separating docs from external resources |
| **Dropdowns** | Multiple doc sections users switch between, but not distinct enough for tabs                   |
| **Products**  | Multi-product company with separate documentation per product                                  |
| **Versions**  | Maintaining docs for multiple API/product versions simultaneously                              |
| **Languages** | Localized content                                                                              |

**Within your primary pattern:**

* **Groups** - Organize related pages. Can nest groups within groups, but keep hierarchy shallow
* **Menus** - Add dropdown navigation within tabs for quick jumps to specific pages
* **`expanded: false`** - Collapse nested groups by default. Use for reference sections users browse selectively
* **`openapi`** - Auto-generate pages from OpenAPI spec. Add at group/tab level to inherit

**Common combinations:**

* Tabs containing groups (most common for docs with API reference)
* Products containing tabs (multi-product SaaS)
* Versions containing tabs (versioned API docs)
* Anchors containing groups (simple docs with external resource links)

### Links and paths

* **Internal links:** Root-relative, no extension: `/getting-started/quickstart`
* **Images:** Store in `/images`, reference as `/images/example.png`
* **External links:** Use full URLs, they open in new tabs automatically

## Customize docs sites

**What to customize where:**

* **Brand colors, fonts, logo** → `docs.json`. See [global settings](https://www.mintlify.com/docs/organize/settings)
* **Component styling, layout tweaks** → `custom.css` at project root
* **Dark mode** → Enabled by default. Only disable with `"appearance": "light"` in `docs.json` if brand requires it

Start with `docs.json`. Only add `custom.css` when you need styling that config doesn't support.

## Write content

### Components

The [components overview](https://mintlify.com/docs/components) organizes all components by purpose: structure content, draw attention, show/hide content, document APIs, link to pages, and add visual context. Start there to find the right component.

**Common decision points:**

| Need                       | Use                     |
| -------------------------- | ----------------------- |
| Hide optional details      | `<Accordion>`           |
| Long code examples         | `<Expandable>`          |
| User chooses one option    | `<Tabs>`                |
| Linked navigation cards    | `<Card>` in `<Columns>` |
| Sequential instructions    | `<Steps>`               |
| Code in multiple languages | `<CodeGroup>`           |
| API parameters             | `<ParamField>`          |
| API response fields        | `<ResponseField>`       |

**Callouts by severity:**

* `<Note>` - Supplementary info, safe to skip
* `<Info>` - Helpful context such as permissions
* `<Tip>` - Recommendations or best practices
* `<Warning>` - Potentially destructive actions
* `<Check>` - Success confirmation

### Reusable content

**When to use snippets:**

* Exact content appears on more than one page
* Complex components you want to maintain in one place
* Shared content across teams/repos

**When NOT to use snippets:**

* Slight variations needed per page (leads to complex props)

Import snippets with `import { Component } from "/path/to/snippet-name.jsx"`.

## Writing standards

### Voice and structure

* Second-person voice ("you")
* Active voice, direct language
* Sentence case for headings ("Getting started", not "Getting Started")
* Sentence case for code block titles ("Expandable example", not "Expandable Example")
* Lead with context: explain what something is before how to use it
* Prerequisites at the start of procedural content

### What to avoid

**Never use:**

* Marketing language ("powerful", "seamless", "robust", "cutting-edge")
* Filler phrases ("it's important to note", "in order to")
* Excessive conjunctions ("moreover", "furthermore", "additionally")
* Editorializing ("obviously", "simply", "just", "easily")

**Watch for AI-typical patterns:**

* Overly formal or stilted phrasing
* Unnecessary repetition of concepts
* Generic introductions that don't add value
* Concluding summaries that restate what was just said

### Formatting

* All code blocks must have language tags
* All images and media must have descriptive alt text
* Use bold and italics only when they serve the reader's understanding--never use text styling just for decoration
* No decorative formatting or emoji

### Code examples

* Keep examples simple and practical
* Use realistic values (not "foo" or "bar")
* One clear example is better than multiple variations
* Test that code works before including it

## Deploy

Mintlify deploys automatically when changes are pushed to the connected Git repository.

**What agents can configure:**

* **Redirects** → Add to `docs.json` with `"redirects": [{"source": "/old", "destination": "/new"}]`
* **SEO indexing** → Control with `"seo": {"indexing": "all"}` to include hidden pages in search

**Requires dashboard setup (human task):**

* Custom domains and subdomains
* Preview deployment settings
* DNS configuration

For `/docs` subpath hosting with Vercel or Cloudflare, agents can help configure rewrite rules. See [/docs subpath](https://mintlify.com/docs/deploy/vercel).

## Workflow

### 1. Understand the task

Identify what needs to be documented, which pages are affected, and what the reader should accomplish afterward. If any of these are unclear, ask.

### 2. Research

* Read `docs.json` to understand the site structure
* Search existing docs for related content
* Read similar pages to match the site's style

### 3. Plan

* Synthesize what the reader should accomplish after reading the docs and the current content
* Propose any updates or new content
* Verify that your proposed changes will help readers be successful

### 4. Write

* Start with the most important information
* Keep sections focused and scannable
* Use components appropriately (don't overuse them)
* Mark anything uncertain with a TODO comment:

```mdx theme={null}
{/* TODO: Verify the default timeout value */}
```

### 5. Update navigation

If you created a new page, add it to the appropriate group in `docs.json`.

### 6. Verify

Before submitting:

* [ ] Frontmatter includes title and description
* [ ] All code blocks have language tags
* [ ] Internal links use root-relative paths without file extensions
* [ ] New pages are added to `docs.json` navigation
* [ ] Content matches the style of surrounding pages
* [ ] No marketing language or filler phrases
* [ ] TODOs are clearly marked for anything uncertain
* [ ] Run `mint broken-links` to check links
* [ ] Run `mint validate` to find any errors

## Edge cases

### Migrations

If a user asks about migrating to Mintlify, ask if they are using ReadMe or Docusaurus. If they are, use the [@mintlify/scraping](https://www.npmjs.com/package/@mintlify/scraping) CLI to migrate content. If they are using a different platform to host their documentation, help them manually convert their content to MDX pages using Mintlify components.

### Hidden pages

Any page that is not included in the `docs.json` navigation is hidden. Use hidden pages for content that should be accessible by URL or indexed for the assistant or search, but not discoverable through the sidebar navigation.

### Exclude pages

The `.mintignore` file is used to exclude files from a documentation repository from being processed.

## Common gotchas

1. **Component imports** - JSX components need explicit import, MDX components don't
2. **Frontmatter required** - Every MDX file needs `title` at minimum
3. **Code block language** - Always specify language identifier
4. **Never use `mint.json`** - `mint.json` is deprecated. Only ever use `docs.json`

## Resources

* [Documentation](https://mintlify.com/docs)
* [https://github.com/sgl-project/sglang](https://github.com/sgl-project/sglang)
* [Configuration schema](https://mintlify.com/docs.json)
* [Feature requests](https://github.com/orgs/mintlify/discussions/categories/feature-requests)
* [Bugs and feedback](https://github.com/orgs/mintlify/discussions/categories/bugs-feedback)

---

### CONTRIBUTING (`docs/CONTRIBUTING.md`)

> **Customize this file**: Tailor this template to your project by noting specific contribution types you're looking for, adding a Code of Conduct, or adjusting the writing guidelines to match your style.

# Contribute to the documentation

Thank you for your interest in contributing to our documentation! This guide will help you get started.

## How to contribute

### Option 1: Edit directly on GitHub

1. Navigate to the page you want to edit
2. Click the "Edit this file" button (the pencil icon)
3. Make your changes and submit a pull request

### Option 2: Local development

1. Fork and clone this repository
2. Install the Mintlify CLI: `npm i mint`
3. Create a branch for your changes
4. Make changes
5. Run `mint dev`
6. Preview your changes at `http://localhost:3000`
7. Commit your changes and submit a pull request

For more details on local development, see our [development guide](development.mdx).

## Writing guidelines

- **Use active voice**: "Run the command" not "The command should be run"
- **Address the reader directly**: Use "you" instead of "the user"
- **Keep sentences concise**: Aim for one idea per sentence
- **Lead with the goal**: Start instructions with what the user wants to accomplish
- **Use consistent terminology**: Don't alternate between synonyms for the same concept
- **Include examples**: Show, don't just tell

---

### Docs Supported Models (`docs/docs/supported-models.mdx`)

---
title: Supported models
description: See which families of SGLang-compatible models are actively maintained.
mode: wide
---

SGLang supports model families across text generation, retrieval, and reward workflows. Browse the sections below for the primary product paths and jump to the detail pages when you are ready to explore a specific class.

### Text generation

<CardGroup cols={3}>
  <Card
    title="Large language models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./supported-models/generative_models"
    img="/cards/LLM-card.png"
  >
    Production-tuned Llama and Qwen families validated for high-throughput
    serving.
  </Card>
  <Card
    title="Vision language models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./supported-models/multimodal_language_models"
    img="/cards/VLM-card.png"
  >
    Vision-text hybrids that stay responsive on multi-GPU setups.
  </Card>
  <Card
    title="Diffusion language models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./sglang-diffusion/index"
    img="/cards/dLLM-card.png"
  >
    Score-based and diffusion backbones for structured text generation
    workflows.
  </Card>
</CardGroup>

### Retrieval and ranking

<CardGroup cols={3}>
  <Card
    title="Embedding models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./supported-models/embedding_models"
    img="/cards/Embedding-card.png"
  >
    Dense and sparse embeddings optimized with FlashInfer kernels.
  </Card>
  <Card
    title="Rerank models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./supported-models/rerank_models"
    img="/cards/Rerank-card.png"
  >
    Low-latency rerankers for multi-stage retrieval pipelines.
  </Card>
  <Card
    title="Classification models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./supported-models/classify_models"
    img="/cards/Classification-card.png"
  >
    Lightweight classifiers covering safety, intent, and context filters.
  </Card>
</CardGroup>

### Specialized models

<CardGroup cols={3}>
  <Card
    title="Reward models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./supported-models/reward_models"
    img="/cards/Reward-card.png"
  >
    RLHF and reward scoring pipelines optimized for production latency.
  </Card>
  <Card
    title="Decision models"
    mode="card"
    className="max-w-sm mx-auto"
    href="./supported-models/decision_models"
    icon="list-check"
  >
    Typed choice, score, and yes or no answers with a probability for every option.
  </Card>
</CardGroup>

---

### Cookbook Specbundle Specbundle Usage (`docs/cookbook/specbundle/specbundle_usage.mdx`)

---
title: SpecBundle Usage
metatags:
    description: "SpecBundle usage guide - production-grade EAGLE3 speculative decoding with SGLang for faster LLM inference."
---


## About SpecBundle

Speculative decoding, especially EAGLE3, offer strong theoretical guarantees alongside consistent empirical improvements in token acceptance rate and end-to-end inference speed. However, despite these advances, adoption of speculative decoding—especially EAGLE3—remains limited in the open-source ecosystem, due primarily to three key factors.

1. Lack of production-ready training infrastructure: Existing speculative decoding toolchains are largely research prototypes, offering limited system-level optimization and inadequate support for diverse architectures and large-scale models.
2. Scarcity of high-quality draft models: Effective speculative decoding depends on strong draft models, yet publicly available EAGLE3-compatible checkpoints are extremely limited, primarily originating from the original authors.
3. Insufficient training scale of existing drafts: Most available draft models are trained on small or curated datasets and fail to generalize to the large, diverse corpora used in modern LLM training, resulting in low token acceptance rates and diminished practical speedups.

**SpecBundle** is a direct response to these limitations. Jointly driven by the open-source community and industry partners including **Ant Group**, **Meituan**, **Nex-AGI** and **EigenAI**, **SpecBundle** represents the **first open initiative** aimed at democratizing speculative decoding by providing high-performance, production-grade EAGLE3 draft model weights for mainstream open-source LLMs. This initiative also serves to verify the robustness of the [**SpecForge**](https://github.com/sgl-project/SpecForge) framework through multiple scales and architectures.

## Installation

```bash Command
git clone https://github.com/sgl-project/SpecForge.git
```

## Usage

### Launch SGLang Server with SpecBundle models

You can use the following command to launch the SGLang server with SpecBundle models. Please add `--tp`, `--ep` and `--mem-fraction-static` arguments when you encounter memory issues.

```bash Command
python3 -m sglang.launch_server \
    --model <target-model-path> \
    --speculative-algorithm EAGLE3 \
    --speculative-draft-model-path <draft-model-path> \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 4
```

For example:

```bash Command
SGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python3 -m sglang.launch_server \
    --model Qwen/Qwen3-30B-A3B-Instruct-2507 \
    --speculative-algorithm EAGLE3 \
    --speculative-draft-model-path lmsys/SGLang-EAGLE3-Qwen3-30B-A3B-Instruct-2507-SpecForge-Nex \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 4 \
    --tp 4
```

### Use SpecBundle to compare the performance of Speculative Decoding draft models

We provide a benchmark suite to evaluate the performance of SpecBundle draft models [here](https://github.com/sgl-project/SpecForge/tree/main/benchmarks).

#### Example:

1. Launch a SGLang Server

```bash Command
SGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python3 -m sglang.launch_server \
    --model Qwen/Qwen3-30B-A3B-Instruct-2507 \
    --speculative-algorithm EAGLE3 \
    --speculative-draft-model-path lmsys/SGLang-EAGLE3-Qwen3-30B-A3B-Instruct-2507-SpecForge-Nex \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 4 \
    --tp 4
```

2. Use the benchmark suite to evaluate the performance of SpecBundle draft models

`bench_eagle3.py` can help you launch a SGLang server process and a Benchmarking process concurrently. In this way, you don't have to launch the SGLang server manually, this script will manually handle the SGLang launch under different speculative decoding configurations. Some important arguments are:

- `--model-path`: the path to the target model.
- `--speculative-draft-model-path`: the path to the draft model.
- `--port`: the port to launch the SGLang server.
- `--trust-remote-code`: trust the remote code.
- `--mem-fraction-static`: the memory fraction for the static memory.
- `--tp-size`: the tensor parallelism size.
- `--attention-backend`: the attention backend.
- `--config-list`: the list of speculative decoding configuration to test, the format is `<batch-size>,<num-steps>,<topk>,<num-draft-tokens>`.
- `--benchmark-list`: the list of benchmarks to test, the format is `<benchmark-name>:<num-prompts>:<subset>`.

```bash Command
cd SpecForge/benchmarks
python bench_eagle3.py \
    --model-path Qwen/Qwen3-30B-A3B-Instruct-2507 \
    --port 30000 \
    --config-list 1,3,1,4 \
    --benchmark-list mtbench:5 gsm8k:100 \
    --skip-launch-server
```

**Interactive Command Generator**: Use the configuration selector below to automatically generate the appropriate test command for your model and benchmark.

import { SpecBundleDeployment } from "/src/snippets/specbundle/specbundle-deployment.jsx";

<SpecBundleDeployment />

It will generate a json file, content is listed below:

```json Config
{
  "mtbench": [
    {
      "batch_size": 1,
      "steps": null,
      "topk": null,
      "num_draft_tokens": null,
      "metrics": [
        {
          "latency": 12.232808108034078,
          "output_throughput": 319.71399906382845,
          "accept_length": 2.170366259711432,
          "accuracy": null,
          "num_questions": 5,
          "num_valid_predictions": 0,
          "categorical_performance": null
        }
      ],
      "num_samples": 5
    }
  ],
  "gsm8k": [
    {
      "batch_size": 1,
      "steps": null,
      "topk": null,
      "num_draft_tokens": null,
      "metrics": [
        {
          "latency": 37.42077191895805,
          "output_throughput": 373.6160234823207,
          "accept_length": 2.643410852713178,
          "accuracy": 0.96,
          "num_questions": 100,
          "num_valid_predictions": 100,
          "categorical_performance": null
        }
      ],
      "num_samples": 100
    }
  ]
}
```

## Performance Scores

We evaluate the performance of SpecBundle draft models on various benchmarks, please visit the [Performance Dashboard](https://docs.sglang.io/SpecForge/SpecBundle/index.html) for more details.

---

### Cookbook Specbundle Supported Models (`docs/cookbook/specbundle/supported_models.mdx`)

---
title: Supported Models
metatags:
    description: "SpecBundle supported EAGLE3 draft models for speculative decoding - Llama, Qwen, DeepSeek, GLM, and more."
---

## [Released Models](https://huggingface.co/collections/lmsys/specbundle)

We list the models released by the SpecForge and several industrial partners below. These models are released as part of the SpecBundle models, which are trained on large-scale multi-domain datasets and deliver exceptional performance on various benchmarks.

> We also include some of the models previously trained by the SpecForge team but not technically part of the SpecBundle release.
> We mark models trained on ShareGPT+Ultrachat datasets with a **\*** mark and models trained on Perfect-Blend datasets but released before SpecBundle with **+** mark.

### Llama Series

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50.0%"}} />
    <col style={{width: "50.0%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Target Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 Draft Model</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>meta-llama/Llama-3.1-8B-Instruct</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Llama-3.1-8B-Instruct-SpecForge)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>meta-llama/Llama-3.3-70B-Instruct</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Llama-3.3-70B-Instruct-SpecForge)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>meta-llama/Llama-4-Scout-17B-16E-Instruct</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Llama-4-Scout-17B-16E-Instruct-SpecForge)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>meta-llama/Llama-4-Maverick-17B-128E-Instruct</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face \*](https://huggingface.co/lmsys/sglang-EAGLE3-Llama-4-Maverick-17B-128E-Instruct-v1)</td>
    </tr>
  </tbody>
</table>

### Qwen Series

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50.0%"}} />
    <col style={{width: "50.0%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Target Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 Draft Model</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen/Qwen3-30B-A3B-Instruct-2507</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Qwen3-30B-A3B-Instruct-2507-SpecForge-Nex)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen/Qwen3-235B-A22B-Instruct-2507</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Qwen3-235B-A22B-Instruct-2507-SpecForge-Meituan)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen/Qwen3-Next-80B-A3B-Instruct-FP8</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Qwen3-Next-80B-A3B-Instruct-FP8-perfect-blend-regenerated)</td>
    </tr>
  </tbody>
</table>

### Qwen Coder Series

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50.0%"}} />
    <col style={{width: "50.0%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Target Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 Draft Model</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen/Qwen3-Coder-30B-A3B-Instruct</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Qwen3-Coder-30B-A3B-Instruct-SpecForge)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen/Qwen3-Coder-480B-A35B-Instruct</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/lmsys/SGLang-EAGLE3-Qwen3-Coder-480B-A35B-Instruct-SpecForge-EigenAI)</td>
    </tr>
  </tbody>
</table>

### Ling Series

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50.0%"}} />
    <col style={{width: "50.0%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Target Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 Draft Model</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>inclusionAI/Ling-flash-2.0</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/AQ-MedAI/Ling-Flash-2.0-eagle3)</td>
    </tr>
  </tbody>
</table>

### Kimi Series

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50.0%"}} />
    <col style={{width: "50.0%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Target Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 Draft Model</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>moonshotai/Kimi-K2-Instruct</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/AQ-MedAI/Kimi-K2-Instruct-eagle3)</td>
    </tr>
  </tbody>
</table>

### GPT-OSS Series

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50.0%"}} />
    <col style={{width: "50.0%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Target Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 Draft Model</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>openai/gpt-oss-20b</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face +](https://huggingface.co/zhuyksir/EAGLE3-gpt-oss-20b-bf16)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>openai/gpt-oss-120b</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face +](https://huggingface.co/lmsys/EAGLE3-gpt-oss-120b-bf16)</td>
    </tr>
  </tbody>
</table>

### Nex Series

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50.0%"}} />
    <col style={{width: "50.0%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Target Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 Draft Model</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>nex-agi/Qwen3-30B-A3B-Nex-N1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/nex-agi/SGLANG-EAGLE3-Qwen3-30B-A3B-Nex-N1)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>nex-agi/Qwen3-32B-Nex-N1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[🤗 Hugging Face](https://huggingface.co/nex-agi/SGLANG-EAGLE3-Qwen3-32B-Nex-N1)</td>
    </tr>
  </tbody>
</table>

---

### Docs Advanced Features Adaptive Speculative Decoding (`docs/docs/advanced_features/adaptive_speculative_decoding.mdx`)

---
title: "Adaptive Speculative Decoding"
metatags:
    description: "Configure adaptive speculative decoding so SGLang can adjust speculative steps and draft tokens at runtime based on acceptance behavior."
---

Adaptive speculative decoding lets SGLang adjust `speculative_num_steps/speculative_num_draft_tokens` at runtime instead of keeping a single fixed value for the whole server lifetime.
It is designed for workloads whose accept length changes over time, where one static step count is rarely optimal.

## Current support

- Only `--speculative-algorithm EAGLE` or `EAGLE3`
- Only `--speculative-eagle-topk 1`
- If either condition is not met, SGLang falls back to static speculative settings

## Why adaptive steps help

`speculative_num_steps` controls how many draft-model autoregressive steps run in each speculative round. In practice, the best value depends on the current workload.

- If `num_steps` is too small, the draft model could have produced more accepted tokens, but the round stops too early.
- If `num_steps` is too large, the draft model produces many candidate tokens that the target model rejects, so extra draft work is wasted.
- At **high batch sizes**, the cost of each wasted draft step is multiplied across all sequences in the batch, so the optimal step count is often lower than at low batch sizes.

Real traffic often moves between high-acceptance and low-acceptance phases, and batch sizes vary continuously. Adaptive mode follows both signals at runtime instead of hard-coding a single global `num_steps`.

## Design overview

The adaptive mechanism has three pieces:

- `AdaptiveSpeculativeParams`: the EMA-based policy
- `SpecRuntimeState`: the per-tier runtime state bundle
- `AdaptiveController`: the coordinator that queries the policy for the current batch size and activates the matching runtime state

### Per-batch-size independent tracking

The controller maintains **independent EMA trackers for each batch size range**, so observations at small BS don't pollute the large BS signal. Each BS range can have its own candidate steps, hysteresis thresholds, and ceiling coefficient.

BS ranges are defined as lower bounds in the config file (e.g., keys `"1"` and `"8"` mean BS 1–7 uses one slot, BS 8+ uses another). `SpecRuntimeState` objects are shared across BS ranges with the same step count — each state owns CUDA graphs captured for the reachable padded batch sizes of that step.

```mermaid
---
title: "SpecRuntimeState — speculative_num_steps / speculative_num_draft_tokens"
---
graph LR
  subgraph SR[" "]
    direction LR
    subgraph D["Draft stage"]
      direction TB
      d1[attn_backend]
      d2[cuda_graph]
    end
    subgraph V["Verify stage"]
      direction TB
      v1[attn_backend]
      v2[cuda_graph]
    end
    subgraph E["Extend stage"]
      direction TB
      e1[attn_backend]
      e2[cuda_graph]
    end
  end
```

This matters because `CudaGraphRunner` is shape-dependent. Each candidate tier owns its own graph and backend state, so runtime switching is a reference swap, not an online graph recapture.

## Runtime flow

The adaptive update happens in two places:

1. **Pre-draft**: query the optimal step for the current batch size and activate if different
2. **Post-verify**: update the matching BS slot's EMA with observed accept lengths

```mermaid
---
title: "EAGLEWorker.forward_batch_generation() — decode path"
---
flowchart TD
  Z["⓪ activate_step_by_batch(batch_size)<br/>query optimal step for current BS range, activate if different"]
  A["① draft(batch)<br/>draft model multi-step generation with current tier"]
  B["② verify(batch, spec_info)<br/>target model tree verification → produces num_correct_drafts_per_req"]
  C["③ forward_draft_extend_after_decode(batch)<br/>draft model KV-cache catch-up"]
  D["④ adaptive_controller.on_verify_complete(num_correct_drafts_per_req, batch_size)<br/>update EMA for matching BS slot, apply warmup / interval / hysteresis gates<br/>if tier changed, select a pre-built state from pool"]
  E["worker.apply_runtime_state(state)"]
  Z --> A --> B --> C --> D --> E
```

> Tier switch happens after the current round completes. Backends and CUDA graphs are never swapped mid-round.

## How the policy decides

After each verify pass, SGLang reads the accepted draft length per request, computes the batch average, smooths it with an exponential moving average (EMA), and switches among the candidate tiers for the matching BS slot.

The decision logic is intentionally conservative:

- `warmup_batches` skips the first few batches
- `update_interval` avoids switching every batch
- `down_hysteresis` and `up_hysteresis` reduce oscillation
- `ceiling_coeff` — an optional EMA ceiling rule can cap `num_steps` proportionally to observed draft quality, preventing over-speculation at high BS

Conceptually, the policy probes one step beyond the observed acceptance:

```text
target_steps ≈ clamp(round(ema_accept_len) + 1, min(candidate_steps), max(candidate_steps))
```

So if recent requests consistently accept more drafted tokens, the policy tends to move up. If they start rejecting earlier, it tends to move down.

## Usage

`--speculative-adaptive-config` is optional, but the speculative setup still needs to be valid for adaptive mode.

```bash
python3 -m sglang.launch_server \
    --model meta-llama/Llama-2-7b-chat-hf \
    --speculative-algorithm EAGLE \
    --speculative-draft-model-path lmsys/sglang-EAGLE-llama2-chat-7B \
    --speculative-eagle-topk 1 \
    --speculative-num-steps 3 \
    --speculative-num-draft-tokens 4 \
    --speculative-adaptive
```

If you want to override the defaults, add `--speculative-adaptive-config /path/to/adaptive_spec.json`.

Example config:

```json
{
  "ema_alpha": 0.2,
  "warmup_batches": 10,
  "update_interval": 5,
  "1": {"candidate_steps": [1, 3, 7], "up_hysteresis": 0.0, "down_hysteresis": -0.25, "ceiling_coeff": 0},
  "8": {"candidate_steps": [1],       "up_hysteresis": 0.0, "down_hysteresis": 0.0,   "ceiling_coeff": 0}
}
```

Non-integer keys (`ema_alpha`, `warmup_batches`, `update_interval`) are global overrides applied to every BS slot. Integer keys (`"1"`, `"8"`) define per-BS slots.

## Config file reference

The config file is optional. When provided, each integer BS-slot key must specify `candidate_steps`; all other keys fall back to defaults.

### Per-BS slot parameters

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
  </colgroup>
  <thead>
    <tr>
      <th>Key</th>
      <th>Default</th>
      <th>Meaning</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>candidate_steps</code></td>
      <td><em>required</em></td>
      <td>Candidate <code>speculative_num_steps</code> tiers for this BS range. Must be a non-empty list of positive ints; a slot that omits it raises a config error</td>
    </tr>
    <tr>
      <td><code>down_hysteresis</code></td>
      <td><code>-0.25</code></td>
      <td>Extra margin before moving to a smaller step</td>
    </tr>
    <tr>
      <td><code>up_hysteresis</code></td>
      <td><code>0.0</code></td>
      <td>Extra margin before moving to a larger step</td>
    </tr>
    <tr>
      <td><code>ceiling_coeff</code></td>
      <td><code>0</code> (disabled)</td>
      <td>EMA ceiling coefficient; set &gt; 0 to cap steps proportionally to draft quality</td>
    </tr>
  </tbody>
</table>

### Global parameters

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
  </colgroup>
  <thead>
    <tr>
      <th>Key</th>
      <th>Default</th>
      <th>Meaning</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>ema_alpha</code></td>
      <td><code>0.2</code></td>
      <td>EMA smoothing factor for accepted draft length</td>
    </tr>
    <tr>
      <td><code>update_interval</code></td>
      <td><code>5</code></td>
      <td>Recompute interval, in verify batches, after warmup</td>
    </tr>
    <tr>
      <td><code>warmup_batches</code></td>
      <td><code>10</code></td>
      <td>Number of verify batches to observe before switching</td>
    </tr>
  </tbody>
</table>

## Monitoring

You can inspect the active tier and acceptance metric via `/server_info`:

```bash
curl -s http://127.0.0.1:30000/server_info | jq '.internal_states[0] | {speculative_num_steps, avg_spec_accept_length}'
```

- `speculative_num_steps` is the current active tier
- `avg_spec_accept_length` helps explain whether the server is likely to move up or down

## Tuning tips

- Start with the built-in default (conservative) — it is safe for all draft model qualities
- For strong draft models, use the aggressive config with ceiling rule
- Use fewer candidate steps if you want lower startup GPU memory overhead
- Increase `ema_alpha` to react faster, or lower it for more stability
- Increase `warmup_batches` or `update_interval` if tier switching is too noisy
- At high batch sizes, narrower ladders (e.g., `[1, 2]` or `[1]`) often outperform wide ones
- If your workload is already stable and one static setting is well tuned, adaptive mode may not help much

## Recommended configs

The built-in default is conservative — safe for all draft models but may under-speculate for strong ones. Save one of these as a JSON file and pass via `--speculative-adaptive-config`.

### Conservative (default) — for weak draft models

This is the built-in default: BS 8–31 allows `[1, 3]`, and BS≥32 locks to `step=1` to avoid wasted compute. Best for models like MiniMax-M2.5, DSV4.

```json
{
  "1":  {"candidate_steps": [1, 3, 7], "up_hysteresis": 0.0, "down_hysteresis": -0.25, "ceiling_coeff": 0},
  "8":  {"candidate_steps": [1, 3],    "up_hysteresis": 0.0, "down_hysteresis": 0.0,   "ceiling_coeff": 0},
  "32": {"candidate_steps": [1],       "up_hysteresis": 0.0, "down_hysteresis": 0.0,   "ceiling_coeff": 0}
}
```

### Aggressive — for strong or high-variance draft models

Uses wider ladders with ceiling rule to cap speculation at high BS. Best for models like GLM-4.7-FP8.

```json
{
  "1":   {"candidate_steps": [1, 3, 7], "up_hysteresis": 0.0, "down_hysteresis": -0.25, "ceiling_coeff": 0},
  "8":   {"candidate_steps": [1, 3, 7], "up_hysteresis": 0.0, "down_hysteresis": -0.25, "ceiling_coeff": 3.0},
  "64":  {"candidate_steps": [1, 3],    "up_hysteresis": 0.0, "down_hysteresis": -0.25, "ceiling_coeff": 1.67},
  "128": {"candidate_steps": [1, 3],    "up_hysteresis": 0.0, "down_hysteresis": -0.25, "ceiling_coeff": 1.2}
}
```

### Custom per-model config

For the best performance, benchmark your specific model across batch sizes with different static `num_steps` values, then build a per-BS config that matches each range's optimal step. A well-tuned per-model config might outperform the generic presets above.

---

### Docs Advanced Features Attention Backend (`docs/docs/advanced_features/attention_backend.mdx`)

---
title: "Attention Backend"
metatags:
    description: "SGLang attention backend guide: FlashInfer, FA3, FA4, Triton, FlashMLA, TRTLLM MLA, hybrid attention. Support matrix for MHA and MLA models."
---
SGLang supports a large variety of attention backends. Each of them has different pros and cons.
You can test them according to your needs.

<Warning>
Selecting an optimal attention backend is crucial for maximizing your performance. Different backends excel in various scenarios, so choose based on your model, hardware, and use case. Not all backends are supported on all platforms and model architectures.

If you don't specify `--attention-backend`, SGLang makes a best effort to automatically select the most performant backend based on your hardware and model architecture.
</Warning>

## Support Matrix

The support matrix is split into two parts: MHA (standard attention) and MLA (multi-head latent attention). For an explanation of the key differences between MHA and MLA, please see the [SGLang documentation on DeepSeek MLA](/cookbook/autoregressive/DeepSeek/DeepSeek-V3#4-2-4-mla-optimizations) and the original [DeepSeek MLA paper](https://arxiv.org/pdf/2405.04434).

### MHA Backends

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "13%"}} />
    <col style={{width: "13%"}} />
    <col style={{width: "13%"}} />
    <col style={{width: "13%"}} />
    <col style={{width: "12%"}} />
    <col style={{width: "12%"}} />
    <col style={{width: "12%"}} />
    <col style={{width: "12%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**Backend**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>**Page Size > 1 (native)**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**FP8 KV Cache**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>**FP4 KV Cache**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**Spec topk=1**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>**Spec topk>1**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**Sliding Window**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>**MultiModal**</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FlashInfer**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FA3 (FlashAttention 3)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FA4 (FlashAttention 4)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>128</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Triton**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Torch Native (SDPA)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FlexAttention (PyTorch)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**TRTLLM MHA**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>16, 32 or 64</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Dual Chunk FlashAttention**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**HPC-Ops**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>64</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**AITER (ROCm)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Wave (ROCm)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Ascend (NPU)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Intel XPU**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Intel AMX (CPU)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
  </tbody>
</table>

### MLA Backends

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "15%"}} />
    <col style={{width: "15%"}} />
    <col style={{width: "14%"}} />
    <col style={{width: "14%"}} />
    <col style={{width: "14%"}} />
    <col style={{width: "14%"}} />
    <col style={{width: "14%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**Backend**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>**Native Page Sizes**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**FP8 KV Cache**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>**FP4 KV Cache**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**Chunked Prefix Cache**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>**Spec topk=1**</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>**Spec topk>1**</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FlashInfer MLA**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FlashMLA**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>64</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Cutlass MLA**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>128</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**TRTLLM MLA (Blackwell)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>32 or 64</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**CuteDSL MLA (Blackwell)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>32 or 64</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FA3 (FlashAttention 3)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>n/a</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>⚠️ (page_size=1 only)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Triton**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>n/a</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>⚠️ (page_size=1 only)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FA4**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Ascend MLA (NPU)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>128</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
    </tr>
  </tbody>
</table>

<Note>
Multimodal attention is selected by `--mm-attention-backend`. The "MultiModal" column indicates whether a corresponding multimodal implementation exists for that backend family.
</Note>

<Note>
- DSA is specifically designed for [DeepSeek V3.2](https://lmsys.org/blog/2025-09-29-deepseek-V32/). See the [DSA Attention Backend](#dsa-attention-backend) section and [DeepSeek V3.2 deployment guide](/cookbook/autoregressive/DeepSeek/DeepSeek-V3_2) for details.
</Note>

<Note>
For the KV4 FA4 scenario, FA4 requires using a different --decode-attention-backend to run. Except for trtllm_mha being incompatible with FA4, all other decode backends behave as shown in the table.
</Note>

<Tip>
Speculative decoding topk: `topk` is the number of draft tokens sampled per step from the draft model. `topk = 1` follows classic EAGLE; `topk > 1` explores multiple branches and requires backend support in both draft and verification paths.
</Tip>

<Tip>
Page size controls how many tokens are grouped into a KV cache block. For the prefix cache to take effect, the number of tokens must fill at least one complete page. For example, if your prompt is only 32 tokens and `page_size = 64`, it won't fill a complete page and cannot be matched in the prefix cache (pages cannot be padded). With 65 tokens and `page_size = 64`, only the first page of 64 tokens will be cached and matched; the remaining 1 token is discarded. Use `page_size = 1` for maximum prefix reuse (token-level matching). Note that higher page sizes generally improve attention kernel performance, so prefer `page_size > 1` when prefix cache reuse is not critical.
</Tip>

Many backends that do not natively operate on pages can emulate `page_size > 1` at the wrapper layer by expanding page tables to per-token indices. The "Page Size > 1 (native)" column indicates true in-kernel paging. Some backends require fixed native page sizes and cannot be reduced/emulated differently: TRTLLM MHA (16/32/64), TRTLLM MLA (32/64), CuteDSL MLA (32/64), FlashMLA (64), Cutlass MLA (128), Ascend (128), HPC-Ops (64).

MLA page-size constraints:
- FlashInfer MLA: page_size = 1.
- FlashMLA: page_size = 64.
- Cutlass MLA: page_size = 128.
- TRTLLM MLA: page_size ∈ &#123;32, 64&#125;.
- CuteDSL MLA: page_size ∈ &#123;32, 64&#125; (decode-only; prefill falls back to `trtllm_mla` when unset).

### GDN Attention Backends

GDN (Gated Delta Network) is a linear attention mechanism with O(n) complexity, used in hybrid models that alternate GDN linear attention layers with standard full attention layers. GDN is **not** selected via `--attention-backend`; it is automatically activated when the model architecture requires it (e.g., Qwen 3.5, Qwen 3 Next, Jet Nemotron, Jet VLM).

The GDN linear attention layers have their own kernel backends, selected via `--linear-attn-backend` (default: `triton`). You can override the kernel per phase with `--linear-attn-decode-backend` and `--linear-attn-prefill-backend`.

On SM100/SM103 with CUDA 13+, SGLang automatically selects FlashInfer for GDN prefill when the per-phase override is unset, the base linear-attention backend is Triton, recurrent state is BF16, key/value head dimensions are 128, dynamic chunking and page-major KV layout are disabled, and `--chunked-prefill-size` is between 1 and 8192. Radix caching may be disabled or use `no_buffer`, `extra_buffer`, or `extra_buffer_lazy`; the extra-buffer paths use state checkpoints.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "28%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "24%"}} />
    <col style={{width: "32%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Backend</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Decode</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Prefill / Extend</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Spec Decoding (Target Verify)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Triton (CUDA)</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Triton (AMD/ROCm)</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Triton (NPU)</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Triton (CPU)</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>CuTe DSL (CUDA only)</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>FlashInfer (CUDA, SM90/SM100/SM103)</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅ linear chain; tree falls back to Triton</td>
    </tr>
  </tbody>
</table>

<Warning>
GDN models are hybrid: the full-attention layers still require a standard `--attention-backend`. Platform constraints for the full-attention backend on hybrid GDN models:
- **Blackwell SM120 (e.g., RTX PRO 6000 Blackwell)**: `triton` or `flashinfer` for prefill/full attention; `trtllm_mha` is supported for `--decode-attention-backend` only.
- **Other Blackwell variants (including SM100 B200/GB200)**: `triton`, `trtllm_mha`, or `fa4` only.
- **NPU (Ascend)**: `ascend` only.
- **AMD (ROCm)**: `triton` recommended.
- **Other CUDA (Hopper, Ampere, etc.)**: auto-selection works; no special constraints.
</Warning>

### DSA Attention Backend

DSA (DeepSeek Sparse Attention) is a native sparse attention mechanism used by [DeepSeek V3.2](https://lmsys.org/blog/2025-09-29-deepseek-V32/). It is activated automatically when the model architecture requires it and is selected via `--attention-backend dsa` (deprecated alias: `nsa`).

Internally, the DSA backend dispatches to different sub-backends for prefill and decode phases. You can override these with `--dsa-prefill-backend` and `--dsa-decode-backend`:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "26%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "42%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Sub-backend</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Prefill</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Decode</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>flashmla_sparse</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Default prefill on Hopper and Blackwell (BF16)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>flashmla_sparse_q8</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Native FP8 (q8×kv8) sparse prefill on Hopper (SM90); BF16 or FP8 KV cache</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>triton_sparse_mla</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Fused Triton sparse prefill that works on the post-TP head count instead of padding heads to 64/128; opt-in. CUDA SM90+ (tiles tuned on SM90 and SM120; other architectures run an untuned tile and log a warning at startup), at most 32 query heads per rank, not with <code>index_kpool</code>. <code>--dsa-triton-union 2|4</code> lets adjacent query tokens share one gathered index set (exact; <code>num_q_heads * union</code> must be a power of two in [16, 32])</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>flashmla_kv</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Default for FP8 on Hopper (prefill + decode)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>flashmla_auto</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>❌</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Picks flashmla_sparse or flashmla_kv by KV cache dtype</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>fa3</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Default decode on Hopper (BF16)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>trtllm</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Default decode on Blackwell (BF16); default for FP8 on Blackwell (prefill + decode)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>tilelang</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Default on AMD (ROCm)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>aiter</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>AMD-specific kernel library (requires aiter package)</td>
    </tr>
  </tbody>
</table>

#### Gemma 4 on `aiter` (ROCm)

Gemma 4's hybrid attention mixes sliding-window layers (`head_dim` 256) with
full-attention layers (`head_dim` 512) and shares KV across layers. The `aiter`
backend supports this and is allow-listed for Gemma 4, so you can serve it with
`--attention-backend aiter` on MI300X/MI350X. Under the hood `aiter` routes the
`head_dim`-512 prefill through the Triton `unified_attention` kernel (the CK
batch-prefill path caps `head_dim` at 256), honors each layer's softmax scale,
and resolves the sliding-window KV pool for speculative-decode draft workers.
Non–sliding-window models (`head_dim` ≤ 256) are unaffected and keep using the
CK path.

<Warning>
For Gemma 4 on `aiter`, use bf16 KV cache (`--kv-cache-dtype auto`). Do **not**
use `--kv-cache-dtype fp8_e4m3`: batched decode currently returns incorrect
output under fp8 KV on this path (a pre-existing aiter fp8-decode issue, tracked
separately). bf16 KV is correct at every batch size.
</Warning>

For deployment examples, see the [DeepSeek V3.2 deployment guide](/cookbook/autoregressive/DeepSeek/DeepSeek-V3_2).

### Hybrid attention (different backends for prefill vs decode) (Experimental)

<Warning>
Hybrid attention is an experimental feature.
</Warning>

You can mix-and-match attention backends for prefill and decode. This is useful when one backend excels at prefill and another excels at decode. For the implementation details, please see `python/sglang/srt/layers/attention/hybrid_attn_backend.py`.

```bash Command
# Example: Prefill with FA4, Decode with TRTLLM MLA (Blackwell)
python3 -m sglang.launch_server \
  --model-path nvidia/DeepSeek-R1-FP4 \
  --tp 8 \
  --attention-backend trtllm_mla \
  --moe-runner-backend flashinfer_trtllm \
  --quantization modelopt_fp4 \
  --prefill-attention-backend fa4
```

#### Speculative decoding with hybrid attention

Hybrid attention also works with speculative decoding. The backend used for draft decoding and target verification depends on `--speculative-attention-mode`:

- `--speculative-attention-mode decode` (recommended): draft/verify use the decode backend.
- `--speculative-attention-mode prefill` (default): draft/verify use the prefill backend.

Constraints when combining hybrid attention with speculative decoding:

- If any attention backend is `trtllm_mha`, speculative decoding supports only `--speculative-eagle-topk 1`.
- For paged MHA backends with `--page-size > 1` and `--speculative-eagle-topk > 1`, only `flashinfer` is supported.
- CUDA Graph: the decode backend is always captured; the prefill backend is captured only when `--speculative-attention-mode prefill`.


<Tip>
If you set only one of `--prefill-attention-backend` or `--decode-attention-backend`, the unspecified phase inherits `--attention-backend`.
If both are specified and differ, SGLang automatically enables a hybrid wrapper to dispatch to the chosen backend per phase.
</Tip>

## Attention Backend Selection Guide (CUDA)

If the `--attention-backend` argument is not specified, SGLang automatically selects the best backend based on the hardware (CUDA) and model architecture.

### Automatic Selection Logic

**1. MHA Models (e.g., Llama, Qwen)**
- **Hopper (e.g., H100, H200)**: Defaults to `fa3` if using CUDA 12.3+ and the model configuration is supported.
- **Blackwell (e.g., B200)**: Defaults to `trtllm_mha`, unless using speculative decoding with `topk > 1`.
- **Other Architectures (Ampere, Ada, etc.)**: Defaults to `flashinfer` if available; otherwise falls back to `triton`.

**2. MLA Models (e.g., DeepSeek V3)**
- **Hopper**: Defaults to `fa3` (requires CUDA 12.3+).
- **Blackwell**: Defaults to `flashinfer`; `trtllm_mla` is auto-selected for DeepSeek V3 models specifically.
- **Other Architectures**: Defaults to `triton`.


## User Guide

### Launch Command for Different Attention Backends

- FlashInfer (Default for Non-Hopper Machines, e.g., A100, A40)
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend flashinfer
python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-V3 \
  --attention-backend flashinfer \
  --trust-remote-code
```

- FlashAttention 3 (Default for Hopper Machines, e.g., H100, H200, H20)
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend fa3
python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-V3 \
  --trust-remote-code \
  --attention-backend fa3
```

- Triton
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend triton
python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-V3 \
  --attention-backend triton \
  --trust-remote-code
```

- FlashMLA
```bash Command
python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-R1 \
  --attention-backend flashmla \
  --trust-remote-code
python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-R1 \
  --attention-backend flashmla \
  --kv-cache-dtype fp8_e4m3 \
  --trust-remote-code
```

- TRTLLM MLA (Optimized for Blackwell Architecture, e.g., B200)
```bash Command
python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-R1 \
  --attention-backend trtllm_mla \
  --trust-remote-code
```

- TRTLLM MLA with FP8 KV Cache (Higher concurrency, lower memory footprint)
```bash Command
python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-R1 \
  --attention-backend trtllm_mla \
  --kv-cache-dtype fp8_e4m3 \
  --trust-remote-code
```

- TRTLLM MHA (Optimized for Blackwell Architecture, e.g., B200)
```bash Command
python3 -m sglang.launch_server \
  --tp 4 \
  --model Qwen/Qwen3.5-35B-A3B-FP8 \
  --attention-backend trtllm_mha \
  --trust-remote-code
```

- TRTLLM MHA (XQA backend) (Optimized for SM90 and SM120, e.g., H20, H200, 5090)
  Note that TRTLLM XQA backend only works well for pagesize 64.
```bash Command
python3 -m sglang.launch_server \
  --tp 4 \
  --model Qwen/Qwen3.5-35B-A3B-FP8 \
  --decode-attention-backend trtllm_mha \
  --trust-remote-code
```

- HPC-Ops (MHA kernels from [HPC-Ops](https://github.com/Tencent/hpc-ops) by the Tencent Hunyuan AI Infra team; Hopper (SM90) only, requires installing the `hpc` package from source, page size 64, bf16 or fp8_e4m3 KV cache, head_dim 128, q/kv head group 4 or 8)
```bash Command
python3 -m sglang.launch_server \
  --model Qwen/Qwen3-30B-A3B-Instruct-2507-FP8 \
  --attention-backend hpc_ops \
  --page-size 64 \
  --trust-remote-code

# FP8 models should also set --kv-cache-dtype fp8_e4m3 to run the FP8 attention
# kernels. This enables the fused QKNorm+RoPE+FP8-quant+StoreKV op, which is
# currently wired for Hunyuan V3 and requires per-rank (q_heads, kv_heads) of
# (64, 8) or (8, 1), e.g. --tp 1 or --tp 8 for Hy3.
python3 -m sglang.launch_server \
  --tp 8 \
  --model tencent/Hy3-FP8 \
  --attention-backend hpc_ops \
  --kv-cache-dtype fp8_e4m3 \
  --page-size 64 \
  --trust-remote-code
```

- FlashAttention 4 (MHA & MLA)
```bash Command
# FA4 for both prefill and decode on SM90/SM100
python3 -m sglang.launch_server \
  --model-path Qwen/Qwen3-30B-A3B-Instruct-2507-FP8 \
  --attention-backend fa4 \
  --page-size 128 \
  --trust-remote-code

python3 -m sglang.launch_server \
  --tp 8 \
  --model deepseek-ai/DeepSeek-R1 \
  --prefill-attention-backend fa4 \
  --trust-remote-code
```

- Ascend
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend ascend
```

- Intel XPU
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend intel_xpu
```

- Wave
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend wave
```

- FlexAttention
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend flex_attention
```

- Torch Native
```bash Command
python3 -m sglang.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --attention-backend torch_native
```

## Steps to add a new attention backend
To add a new attention backend, you can learn from the existing backends
(`python/sglang/srt/layers/attention/triton_backend.py`, `python/sglang/srt/layers/attention/flashattention_backend.py`)
and follow the steps below.

<Note>
Linear attention kernel backends (GDN, KDA) follow a different pattern. They implement `LinearAttnKernelBase` in `python/sglang/srt/layers/attention/linear/kernels/` and are dispatched by `GDNKernelDispatcher` / `KDAKernelDispatcher` rather than registered via `@register_attention_backend`.
</Note>

1. Run without cuda graph. Support the two forward functions
    - forward_extend
        - Will be used for prefill, prefill with KV cache, and target verification
        - It will be called once per layer
    - forward_decode
        - Will be used for normal decode, and draft decode
        - It will be called once per layer
    - init_forward_metadata
        - Initialize the class and common metadata shared by all layers
        - Call the plan function for optimizations like split_kv
        - It will be called once per forward
2. Run with cuda graph. It has two phases (capture and replay) and you need to implement three functions
    - init_cuda_graph_state
        - It will be called once during life time
        - Create all common shared buffers
    - init_forward_metadata_capture_cuda_graph
        - It will be called before capturing a cuda graph
        - It is similar to init_forward_metadata but write the medatada to some pre-defined buffers
    - init_forward_metadata_replay_cuda_graph
        - It will be called before replaying a cuda graph
        - This function is in the critical path and needs to be fast

---

### Docs Advanced Features Breakable Cuda Graph (`docs/docs/advanced_features/breakable_cuda_graph.mdx`)

---
title: "Breakable CUDA Graph"
metatags:
    description: "Use Breakable CUDA Graph to insert targeted eager graph breaks for debugging and CUDA graph compatibility."
---

## Motivation

Standard CUDA graphs capture an entire forward pass as a single, opaque graph. This is great for performance, but creates two problems:

1. **Debugging is hard.** When something goes wrong inside a captured graph (wrong outputs, numerical mismatches, crashes), there is no way to step through the operations or insert print statements because the graph replays as a monolithic unit.

2. **Some ops are incompatible.** Certain operations — dynamic control flow, host-device synchronization, JIT compilation, or ops that change behavior across iterations — cannot be captured into a CUDA graph at all. Today, the only workaround is to disable CUDA graphs entirely, which sacrifices the kernel launch overhead savings for the rest of the model.

**Breakable CUDA Graph** solves both problems by allowing graph breaks to be inserted at specific points. The computation is split into multiple captured graph segments with eager (non-graph) execution in between. This preserves most of the CUDA graph performance benefit while allowing targeted operations to run outside the graph.

## Usage

### Debug Mode: Run Everything Eagerly

The simplest use case is debugging. The `--debug-cuda-graph` flag wraps the entire decode forward pass in a graph break, so every operation runs eagerly while still going through the full CUDA graph capture/replay code path. This lets you debug CUDA graph issues without changing model code.

```bash
python -m sglang.launch_server \
    --model meta-llama/Llama-3.1-8B-Instruct \
    --debug-cuda-graph
```

This mode is intended for debugging only — it eliminates the performance benefit of CUDA graphs since every op runs eagerly.

### Selective Graph Breaks in Model Code

For production use, you can mark specific functions as "non-graphable" using the `@eager_on_graph` decorator. During CUDA graph capture, these functions run eagerly between captured graph segments. Outside of capture, they behave normally.

```python
from sglang.srt.model_executor.runner_backend_utils.breakable_cuda_graph import eager_on_graph

@eager_on_graph
def my_dynamic_op(x):
    # This op is incompatible with CUDA graph capture
    return some_dynamic_operation(x)
```

You can also insert a bare graph break (no computation) using the `break_graph()` helper:

```python
from sglang.srt.model_executor.runner_backend_utils.breakable_cuda_graph import break_graph

def forward(self, x):
    x = self.layer1(x)
    break_graph()  # force a segment split here
    x = self.layer2(x)
    return x
```

To enable breakable CUDA graph at the environment level (without debug mode), set the environment variable:

```bash
export SGLANG_USE_BREAKABLE_CUDA_GRAPH=1
python -m sglang.launch_server \
    --model meta-llama/Llama-3.1-8B-Instruct
```

### Server Args

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "18%"}} />
    <col style={{width: "48%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--debug-cuda-graph</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>False</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Enable debug/eager mode. Wraps the entire forward pass in a graph break so every op runs eagerly through the capture/replay path.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>SGLANG_USE_BREAKABLE_CUDA_GRAPH</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>0</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Environment variable. Enables breakable CUDA graph without debug mode. Required for <code>@eager_on_graph</code> decorators to take effect.</td>
    </tr>
  </tbody>
</table>

## How It Works

### Capture

Breakable CUDA graph extends PyTorch's `torch.cuda.CUDAGraph` by splitting a single capture into multiple segments separated by graph breaks.

During capture, the flow is:

```
Begin capture (segment 1)
  ... graphable ops ...
  @eager_on_graph function encountered:
    1. End current capture segment
    2. Run the function eagerly (allocates output tensors)
    3. Record the function for later replay
    4. Begin new capture segment
  ... more graphable ops ...
End capture (segment N)
```

Each segment is independently instantiated as a CUDA graph executable. The non-graph functions and their argument references are stored for replay.

### Replay

During replay:

```
For each segment i:
  1. Launch CUDA graph segment i
  2. Run the recorded non-graph function i eagerly
Launch final CUDA graph segment
```

The non-graph functions are re-invoked with the same tensor references as capture time. Since these references point to the CUDA graph's static input/output buffers, they see updated values on each replay.

### Output Writeback

When a non-graph function produces output during replay, the result must be written back into the same tensor buffers that downstream graph segments reference. The mechanism handles:

- **Plain tensors**: In-place `copy_()` into the original buffer.
- **Structured outputs** (dataclasses, objects with tensor attributes): Tensor fields are copied in-place; non-tensor fields are replaced.
- **Dicts of tensors**: Tensor values are copied in-place; non-tensor values are replaced.

### Stream Fork/Join Tracking

Some models fork work onto secondary CUDA streams (e.g., for overlapped computation). Breakable CUDA graph hooks `torch.cuda.Stream.wait_stream` to track which streams are forked from the capture stream. When a graph break occurs, all forked streams are automatically joined back before ending the capture segment, and re-forked after beginning the next segment.

## Compatibility

- **CUDA and ROCm/HIP.** Breakable CUDA graph runs on both NVIDIA and AMD GPUs. Other platforms (NPU, CPU, MPS, XPU) are unsupported; there `--debug-cuda-graph` is automatically disabled with a warning.
- **Requires `cuda-python` on NVIDIA.** Stream-capture-status queries use the CUDA runtime via `cuda.bindings` (`pip install cuda-python`); the portable `torch.cuda.is_current_stream_capturing()` has proven unreliable on CUDA. On ROCm/HIP — where `cuda-python` is unavailable — the portable `torch.cuda` API (which maps to the HIP runtime) is used instead.
- **Not compatible with memory saver mode.** Cannot be used together with `SGLANG_MEMORY_SAVER_CUDA_GRAPH`.

## Performance

When no graph breaks are inserted, breakable CUDA graph has minimal overhead compared to standard CUDA graph — the capture/replay path is nearly identical.

Each graph break adds:
- One `cudaGraphLaunch` call (to replay the segment before the break)
- One eager Python function call
- One `cudaStreamBeginCapture` / `cudaStreamEndCapture` pair during capture

For typical use cases with a small number of graph breaks, the overhead is negligible compared to the saved kernel launch overhead from the captured segments.

## Code Reference

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "52%"}} />
    <col style={{width: "48%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>File</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>python/sglang/srt/model_executor/runner_backend_utils/breakable_cuda_graph/breakable_cuda_graph.py</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Core implementation: <code>eager_on_graph</code>, <code>BreakableCUDAGraph</code>, <code>BreakableCUDAGraphCapture</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>python/sglang/srt/model_executor/runner_backend_utils/breakable_cuda_graph/cuda_utils.py</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>CUDA runtime binding utilities (NVIDIA stream-capture queries)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>python/sglang/srt/model_executor/runner_backend/breakable_cuda_graph_backend.py</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Integration with CUDA graph runner backends</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>python/sglang/srt/server_args.py</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>--debug-cuda-graph</code> flag and environment variable handling</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>python/sglang/srt/environ.py</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>SGLANG_USE_BREAKABLE_CUDA_GRAPH</code> environment variable definition</td>
    </tr>
  </tbody>
</table>

---

### Docs Advanced Features Checkpoint Engine (`docs/docs/advanced_features/checkpoint_engine.mdx`)

---
title: "Checkpoint Engine Integration"
metatags:
    description: "SGLang checkpoint engine: distributed model weight loading, parallel multi-node setup, broadcast and P2P modes. Reduces loading time for large models."
---
The SGLang checkpoint engine integration provides an efficient way to load model weights using a distributed checkpoint loading system. This feature significantly reduces model loading time, especially for large models and multi-node setups, by parallelizing the weight loading process across multiple processes and nodes.

## Overview

The checkpoint engine integration allows SGLang to:
- Load model weights in parallel using multiple processes
- Distribute weight loading across multiple nodes to increase effective disk bandwidth
- Overlap weight loading with other initialization tasks like CUDA graph capture
- Support both single-node and multi-node deployments

## Installation

First, install the checkpoint engine package:

```bash Command
pip install 'checkpoint-engine[p2p]'
```

## Architecture

The system consists of two main components:

1. **SGLang Server**: Runs with `--checkpoint-engine-wait-weights-before-ready` flag to wait for weights before becoming ready
2. **Checkpoint Engine Workers**: Separate processes (managed by torchrun) that load and distribute model weights

The checkpoint engine uses a parameter server architecture with support for:
- **Broadcast mode**: Weights are broadcast from loading processes to inference processes
- **P2P mode**: Direct peer-to-peer weight transfer between processes
- **All mode**: Combination of both broadcast and P2P methods

## Usage Examples

### Single Node Setup

**Terminal 1 - Launch SGLang Server:**
```bash Command
python -m sglang.launch_server \
    --model-path Qwen/Qwen3-8B \
    --tp 8 \
    --load-format dummy \
    --checkpoint-engine-wait-weights-before-ready
```

**Terminal 2 - Run Checkpoint Engine:**

Using sglang entrypoint:
```bash Command
python -m sglang.srt.checkpoint_engine.update \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 8
```

Using torchrun directly:
```bash Command
torchrun --nproc-per-node 8 \
    examples/checkpoint_engine/update.py \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 8
```

### Multi-Node Setup (2 Nodes)

**Node 0:**

Launch SGLang server:
```bash Command
python -m sglang.launch_server \
    --model-path Qwen/Qwen3-8B \
    --tp 8 \
    --load-format dummy \
    --checkpoint-engine-wait-weights-before-ready \
    --host [IP]
```

Run checkpoint engine:

Using sglang entrypoint (recommended):
```bash Command
python -m sglang.srt.checkpoint_engine.update \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 8
```

Using torchrun directly:
```bash Command
torchrun --nproc-per-node 8 \
    --nnodes 2 \
    --node-rank 0 \
    --master-addr [IP] \
    --master-port 29500 \
    examples/checkpoint_engine/update.py \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 8
```

**Node 1:**

Launch SGLang server:
```bash Command
python -m sglang.launch_server \
    --model-path Qwen/Qwen3-8B \
    --tp 8 \
    --load-format dummy \
    --checkpoint-engine-wait-weights-before-ready \
    --host [IP]
```

Run checkpoint engine:

Using sglang entrypoint (recommended):
```bash Command
python -m sglang.srt.checkpoint_engine.update \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 8
```

Using torchrun directly:
```bash Command
torchrun --nproc-per-node 8 \
    --nnodes 2 \
    --node-rank 1 \
    --master-addr [IP] \
    --master-port 29500 \
    examples/checkpoint_engine/update.py \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 8
```

### Multi-Node Setup with Tensor Parallelism (TP=16)

**Node 0:**

Launch SGLang server:
```bash Command
python -m sglang.launch_server \
    --model-path Qwen/Qwen3-8B \
    --tp 8 \
    --load-format dummy \
    --checkpoint-engine-wait-weights-before-ready \
    --host [IP] \
    --dist-init-addr [IP]:9120 \
    --nnodes 2 \
    --node-rank 0
```

Run checkpoint engine:

Using sglang entrypoint (recommended):
```bash Command
python -m sglang.srt.checkpoint_engine.update \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 16
```

Using torchrun directly:
```bash Command
torchrun --nproc-per-node 8 \
    --nnodes 2 \
    --node-rank 0 \
    --master-addr [IP] \
    --master-port 29500 \
    examples/checkpoint_engine/update.py \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 16
```

**Node 1:**

Launch SGLang server:
```bash Command
python -m sglang.launch_server \
    --model-path Qwen/Qwen3-8B \
    --tp 8 \
    --load-format dummy \
    --checkpoint-engine-wait-weights-before-ready \
    --host [IP] \
    --dist-init-addr [IP]:9120 \
    --nnodes 2 \
    --node-rank 1
```

Run checkpoint engine:

Using sglang entrypoint (recommended):
```bash Command
python -m sglang.srt.checkpoint_engine.update \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 16
```

Using torchrun directly:
```bash Command
torchrun --nproc-per-node 8 \
    --nnodes 2 \
    --node-rank 1 \
    --master-addr [IP] \
    --master-port 29500 \
    examples/checkpoint_engine/update.py \
    --update-method broadcast \
    --checkpoint-path /path/to/Qwen/Qwen3-8B/ \
    --inference-parallel-size 16
```

## Configuration Options

### SGLang Server Options

- `--load-format dummy`: Use dummy format for initial loading (allows overlapping with other tasks)
- `--checkpoint-engine-wait-weights-before-ready`: Wait for checkpoint engine to provide weights before becoming ready
- `--host`: Host address for multi-node setups
- `--dist-init-addr`: Distributed initialization address for tensor parallelism

### Checkpoint Engine Options

- `--update-method`: Weight update method (`broadcast`, `p2p`, or `all`)
- `--checkpoint-path`: Path to model checkpoint directory
- `--inference-parallel-size`: Number of inference parallel processes
- `--endpoint`: SGLang server endpoint (default: `http://localhost:19730`)
- `--checkpoint-name`: Name for the checkpoint (default: `my-checkpoint-iter-0`)
- `--save-metas-file`: File to save checkpoint metadata
- `--load-metas-file`: File to load checkpoint metadata from
- `--uds`: Unix domain socket path for communication
- `--weight-version`: Version identifier for weights

## Performance Benefits

The checkpoint engine provides significant time savings in two main aspects:

1. **Multi-node Loading**: Each node only loads a portion of weights from disk, effectively increasing disk bandwidth. More participating nodes provide greater acceleration. Preliminary tests show 20-second acceleration when loading DeepSeek-R1 on H20-3e with two nodes.

2. **Single Process Optimization**: Using dummy format allows overlapping disk-to-CPU transfer with CUDA graph capture and other initialization tasks, providing additional time savings.

## Troubleshooting

- Ensure checkpoint engine package is installed: `pip install 'checkpoint-engine[p2p]'`
- Verify network connectivity between nodes in multi-node setups
- Check that the checkpoint path contains valid model files
- Monitor logs for connection errors between SGLang server and checkpoint engine
- Use `--sleep-time` parameter to add delays if needed for debugging

## References

- [Checkpoint Engine Repository](https://github.com/MoonshotAI/checkpoint-engine)

---

### Docs Advanced Features Cuda Graph For Multi Modal Encoder (`docs/docs/advanced_features/cuda_graph_for_multi_modal_encoder.mdx`)

---
title: "Cuda Graph for Multi-Modal Encoder in SGLang"
metatags:
    description: "CUDA Graph optimization for ViT in SGLang: reduce kernel launch overhead, dynamic input handling, support for Qwen2.5-VL and Qwen3-VL models."
---
## Motivation

In multimodal reasoning services, the visual encoder (ViT / Vision Transformer) typically has a few characteristic traits:

Many layers, fragmented operators: Each layer includes LN, QKV projections, attention, MLP, residual connections, etc., resulting in extremely frequent kernel launches.

Server-side “small batch / low latency” is common: The batch size is very small (sometimes it looks like 1 after “flattening” the batch), so kernel launch overhead accounts for a large portion of end-to-end latency.

Input token count (number of patches) varies frequently: Different image/video resolutions and different batch composition lead to different sequence lengths
S — and this is precisely the biggest obstacle for CUDA Graph (unstable shapes).

The value of CUDA Graph: It captures a long sequence of GPU kernels with fixed shapes and fixed memory addresses into a graph; later, for the same shapes, it can replay the graph directly, dramatically reducing launch overhead and making GPU scheduling more compact.

This led us to seek a CUDA Graph enabled feature for ViT in order to improve ViT performance.

## Design and Restrictions

The new CUDA Graph enabled ViT logic is built on ViTCudaGraphRunner. This runner captures the "blocks + merger + deepstack merger (optional)" part of a vision transformer into a CUDA graph and replays it for identical shapes. See the following design consideration and restrictions for more details.

### Dynamic inputs to fit static constraints of CUDA Graph

Variable sequence length S is very common in ViT. While CUDA Graph requires fixed shapes. The solution is to build a graph cache by S(e.g., graph_key = S). The first time create a new S, and then capture a graph; afterwards, replay it.

If there are many distinct S values, we need to increase VRAM usage which is graph-private memory pools for many graphs.

### Stable addresses

Everything "parameter-like" becomes a static buffer:

- block_input / block_ws / block_output
- cu_full_len / cu_window_len and their kk variants
- sin_cos_ws

In this way to solve the underlying requirement: during replay, not allowed to swap tensors, can only modify tensor contents.

### Attention backend arguments
Attention backend arguments are fixed inside the graph:

TritonAttn expects [cu_seqlens, cu_seqlens_kk, max_len]
FA3 expects [cu_seqlens, max_len]

max_len is frozen as an int constant.
cu_seqlens is cached into a dict during create_graph(), and its contents are not updated during subsequent replays.

For the same graph_key = S, you not only require the input shape to match, but also require the segmentation pattern in cu_seqlens (and window seqlens) to be identical. Otherwise, attention will segment the sequence incorrectly.

### Rotary buffer management
The feature reallocates a larger sin_cos_ws when seq_len increases.
The max_content_len is used to make sure the maximum size of the allocated rotary buffer.


## Command Example
You can enable CUDA Graph for ViT by setting env variable `SGLANG_VIT_ENABLE_CUDA_GRAPH=1`, for example:
```shell Command
SGLANG_VIT_ENABLE_CUDA_GRAPH=1 \
python3 -m sglang.launch_server \
  --model Qwen/Qwen3-VL-8B-Instruct
```
To run the ViT graph together with Piecewise CUDA Graph over the decoder's
prefill, ask for the prefill backend explicitly. Qwen3-VL is on neither
multimodal allowlist, so the default backend resolves prefill to `disabled` for
it; naming a backend locks the choice and skips that rule:
```shell Command
SGLANG_VIT_ENABLE_CUDA_GRAPH=1 \
python3 -m sglang.launch_server \
  --model Qwen/Qwen3-VL-8B-Instruct \
  --cuda-graph-backend-prefill breakable \
  --cuda-graph-max-bs-prefill 4096 \
  --cuda-graph-tc-compiler eager
```

## Known supported models
- Qwen2.5-VL (https://github.com/sgl-project/sglang/pull/14422)
- Qwen3-VL (https://github.com/sgl-project/sglang/pull/15320)

---

### Docs Advanced Features Dcp (`docs/docs/advanced_features/dcp.mdx`)

---
title: "Decode Context Parallelism"
metatags:
    description: "Shard MLA KV cache by token position across ranks to grow decode context capacity, then merge partial attention with an exact LSE reduction."
---

Decode context parallelism (DCP) stripes a request's MLA KV cache across ranks in an existing tensor-parallel group. With DCP size `c`, rank `r` owns position `p` when `p mod c = r`, so each rank stores and reads roughly `1/c` of the cache.

Local attention then sees only part of the context. The MLA path returns a partial output and log-sum-exp (LSE), exchanges both in one packed all-to-all, and merges them exactly. DCP complements TP and [attention data parallelism (DPA)](/docs/advanced_features/dp_dpa_smg_guide) rather than replacing them. The primary path is absorbed MLA decode and static target verification. `dcp_size=1` retains existing non-DCP behavior.

On Kimi K3, DCP applies only to MLA layers. Request-indexed KDA state is unchanged, so DCP grows long-context KV capacity but does not raise the KDA concurrency ceiling.

## Enable DCP

| Setting | Behavior |
| --- | --- |
| `--dcp-size N` | Enables DCP and widens virtual capacity and page size by `N`. Alias: `--decode-context-parallel-size`. |
| `--dcp-comm-backend` | Selects the decode partial-output merge (MLA on CUDA/ROCm, MHA on Intel XPU): `ag_rs`, `a2a`, or `fi_a2a`. Unset resolves to `fi_a2a` where the DCP group shares an MNNVL domain on Blackwell, otherwise `a2a` on CUDA/ROCm/XPU. |
| `--dcp-replicate-q-proj` | Removes the query all-gather for supported MLA weights. Use `--no-dcp-replicate-q-proj` to disable a model-specific default. |
| `--attn-dp-size N` | Composes only when DCP groups nest inside attention TP. |

A DCP group must fit inside one attention-TP group and one attention-DP replica:

```text Topology
attn_tp_size = tp_size / attn_dp_size
attn_tp_size % dcp_size == 0
```

For example, `TP=64, attention DP=4, DCP=16` creates four valid 16-rank attention replicas. `DCP=32` would cross replica boundaries and is invalid.

<Warning>
Startup currently checks only `tp_size % dcp_size == 0`, not the stronger condition above. Until that check is fixed, DPA+DCP deployments must enforce containment when choosing the topology.
</Warning>

MLA decode on DeepSeek-V3.1 with DCP 8 inside TP 8:

```bash Command
sglang serve \
  --model-path deepseek-ai/DeepSeek-V3.1 \
  --trust-remote-code \
  --tp-size 8 \
  --dcp-size 8 \
  --host 0.0.0.0 \
  --port 30000
```

Kimi K3 on 32 GPUs with DPA and DCP 8. The model override enables replicated Q by default; the communication backend resolves generically to `fi_a2a` on MNNVL systems, otherwise `a2a`:

```bash Command
sglang serve \
  --trust-remote-code \
  --model-path moonshotai/Kimi-K3 \
  --tp-size 32 \
  --ep-size 32 \
  --attn-dp-size 4 \
  --dcp-size 8 \
  --host 0.0.0.0 \
  --port 30000
```

See the [Kimi K3 cookbook](/cookbook/autoregressive/Moonshotai/Kimi-K3) for large-scale presets that combine DCP with DPA and expert parallelism.

## Why decode context parallelism?

Absorbed MLA shares one latent KV representation across all query heads. TP can split the heads and weights, but not that cache, so every attention-TP rank stores and reads the same context.

```mermaid
flowchart LR
    subgraph TP["TP only: every rank stores the full MLA context"]
        direction TB
        T0["Rank 0<br/>tokens 0 1 2 3 4 5 6 7"]
        T1["Rank 1<br/>tokens 0 1 2 3 4 5 6 7"]
        T2["Rank 2<br/>tokens 0 1 2 3 4 5 6 7"]
        T3["Rank 3<br/>tokens 0 1 2 3 4 5 6 7"]
    end

    TP -- "stripe by position" --> DCP

    subgraph DCP["DCP4: one interleaved shard per rank"]
        direction TB
        D0["Rank 0<br/>tokens 0 4"]
        D1["Rank 1<br/>tokens 1 5"]
        D2["Rank 2<br/>tokens 2 6"]
        D3["Rank 3<br/>tokens 3 7"]
    end
```

DCP stripes that cache round-robin by logical token position, keeps a shared virtual index on every rank, runs attention against the owner-local shard, and merges partial outputs by LSE into the usual TP-local head layout.

## Architecture

### Virtual KV layout

Let each rank have physical token capacity `C` and physical page size `P`. DCP exposes a shared virtual allocator:

```text Layout
virtual capacity  = C * c
virtual page size = P * c
owner(v)          = v mod c
physical(v)       = floor(v / c)
```

Every rank sees the same request-to-token map. On write, it keeps its positions and compacts them into the local physical pool. One widened virtual page maps to one physical page on each rank, so the layout stays balanced to within one token as a sequence grows.

### MLA decode dataflow

```mermaid
flowchart LR
    H["Hidden states"] --> Q["Full DCP-group query heads"]

    Q --> A0["Rank 0 local attention<br/>partial O0 + LSE0"]
    Q --> A1["Rank 1 local attention<br/>partial O1 + LSE1"]
    Q --> AN["Rank c-1 local attention<br/>partial O + LSE"]

    A0 --> A2A["Packed all-to-all"]
    A1 --> A2A
    AN --> A2A
    A2A --> MERGE["Exact LSE merge"]
    MERGE --> OUT["TP-local head shard"]
```

For context partition `r`, the kernel returns locally normalized output `o_r` and `lse_r`. The global result is `lse = logsumexp_r(lse_r)` and `o = sum_r(exp(lse_r - lse) * o_r)`. This is exact aside from floating-point reduction order. The merge uses the attention backend's LSE base, either base-e or base-2.

### Query-projection replication

Normally each layer all-gathers its absorbed and rotary query components. `--dcp-replicate-q-proj` gathers the query-projection and `w_kc` weights once at startup and computes the full DCP-group query locally. The trade is more weight memory and GEMM work for one fewer collective per layer. Only unquantized BF16/FP16 weights use this path; other layers fall back to the query all-gather.

### Communication backends

| Backend | DCP collectives per MLA layer | Notes |
| --- | --- | --- |
| `ag_rs` | Query AG + LSE AG + FP32 output RS | Fallback for platforms without the a2a path; opt in with `--dcp-comm-backend ag_rs` |
| `a2a`, gathered Q | Query AG + packed NCCL A2A | Two collectives |
| `a2a`, replicated Q | One packed NCCL A2A | Canonical low-latency path |
| `fi_a2a`, replicated Q | One FlashInfer MNNVL A2A | Requires Blackwell and a DCP group inside one MNNVL domain (GB200/GB300 fabric, or a single node) |

When `--dcp-comm-backend` is unset, every DCP launch resolves it the same way: `fi_a2a` where the DCP group shares one MNNVL domain on Blackwell, otherwise `a2a` on CUDA/ROCm/XPU, and `ag_rs` only on platforms without the a2a path. Query replication stays model-resolved: Kimi K3 enables it by default on the a2a family, and its decode backend is `cutedsl_mla`.

DCP adds a context-independent decode collective while cutting context-dependent KV storage and reads by about `c`. Extend is outside that decode cost model: it may gather cached prefix shards, restore token order, and append new tokens, and that work grows with prefix length.

## Compositions

### DCP × speculative decoding

The draft KV cache is replicated: every DCP rank stores the full draft context. DCP only stripes the target MLA KV, so it saves target cache, not draft cache.

Target verify and decode use the DCP-aware MLA kernel `cutedsl_mla`. It:

1. Builds a rank-local page table from the cyclic token map (`owner(p) = p mod c`).
2. Runs attention against that shard, passing `cp_world`, `cp_rank`, and the global KV lengths so causality still sees the full sequence.
3. Returns a rank-local `(output, LSE)` that the usual DCP all-to-all merge combines.

Draft steps use the same backend against the replicated draft cache, so they skip DCP metadata. Kimi K3 DCP selects `cutedsl_mla` automatically.

### DCP × PD disaggregation

A dense prefill page cannot be copied directly into striped decode storage. The PD sender uses the decode rank's DCP metadata to select and pack the right rows. See [PD disaggregation](/docs/advanced_features/pd_disaggregation) for the transfer engines.

- Equal DCP sizes require matching DCP ranks and use the existing page path.
- DCP1 prefill to DCP decode uses token relayout for MLA and hybrid-MLA pools.
- All other DCP-size transitions are rejected.

The plan includes the exact token count, so stale rows do not leak out of a partial final page. Mooncake and NIXL use the same plan. KDA state keeps its attention-TP mapping and bypasses DCP filtering.

This composition requires Mooncake or NIXL, matching physical page size and KV dtype, and prefill attention CP `1`. Decode radix cache and HiCache are not supported here.

### DCP × HiCache L2

HiCache keeps one widened logical page space across L1 and L2. The controller sees `P * c` slots, while each GPU and host buffer stores only its `P` local rows. See [HiCache](/docs/advanced_features/hicache) for the cache hierarchy.

Before H2D or D2H, both index lists keep positions owned by this rank and map `i` to `floor(i / c)`. Transfers cover whole widened pages, and every rank moves its shard independently, with no DCP collective. For Kimi K3 this applies to MLA KV; KDA/Mamba state uses its own request-indexed host pool.

The current scope is MLA L1/L2. L3, LMCache, HiSparse, non-MLA KV host pools, speculative decoding, and PD decode are not supported in this combination.

### DCP × DSA (GLM-5.2, GLM-5.3)

DeepSeek Sparse Attention attends over a top-k slice of the context, so DCP keeps the target's latent KV striped by position while the **index-K cache stays replicated** on every rank: each rank scores the whole sequence, takes the global top-k, and attends over the selected slots it owns. Decode, target verify and extend all follow the same path, so the prefix KV is never gathered.

1. The index-K cache is addressed by the widened virtual slot and costs `c` times its usual share of each rank's KV budget (about 6% at DCP2 and 17% at DCP4 on GLM-5.3).
2. Each layer maps the global top-k to rank-local rows with one Triton kernel; layers that share the previous layer's top-k reuse the mapping.
3. The TRT-LLM sparse kernel returns the per-head LSE and the usual DCP merge combines the partial outputs.
4. The MTP draft (nextn) layer keeps a replicated KV cache over the widened slots and attends without the DCP group, so MTP index share feeds the draft directly.

Requirements: CUDA SM100/SM103 with the `trtllm` DSA backends (selected automatically), an `fp8_e4m3` or `bf16` KV cache, `attn_tp_size % dcp_size == 0`, and, with speculative decoding, the checkpoint's own MTP draft as a single EAGLE chain (`--speculative-eagle-topk 1`, draft tokens equal to steps + 1). HiSparse, prefill CP, HiCache, PD disaggregation, unified memory and `index_kpool > 1` are not supported in this combination.

```bash Command
sglang serve \
  --model-path zai-org/GLM-5.3 \
  --trust-remote-code \
  --tp-size 8 \
  --dcp-size 2 \
  --speculative-algorithm EAGLE \
  --speculative-num-steps 5 \
  --speculative-eagle-topk 1 \
  --speculative-num-draft-tokens 6
```

## References

- [DCP and Helix Parallelism roadmap](https://github.com/sgl-project/sglang/issues/29736)
- [SGLang and Miles Add Day-0 Support for Kimi K3](https://www.lmsys.org/blog/2026-07-27-kimi-k3-day0-support#decode-context-parallelism)
- [Original SGLang DCP design](https://docs.google.com/document/d/1pjBSID0palpuI7rx8Ck7Z0BcyzBXAgnkDrf9uQg0uqU/edit?tab=t.0)

---

### Docs Advanced Features Deterministic Inference (`docs/docs/advanced_features/deterministic_inference.mdx`)

---
title: "Deterministic Inference"
metatags:
    description: "SGLang deterministic inference: consistent outputs for RL training, testing, and production. Supports FlashInfer, FA3, Triton backends with CUDA Graph."
---
## Why Deterministic Inference Matters

Deterministic inference ensures consistent LLM outputs across runs, which is critical for:
- **Reinforcement Learning**: Ensures consistent logprobs across runs, reducing stochastic noise and making RL training more stable, reproducible, and debuggable.
- **Testing & Debugging**: Enables reproducible validation
- **Production**: Improves reliability and user experience

Even with `temperature=0`, standard LLM inference can produce different outputs due to dynamic batching and varying reduction orders in GPU kernels.

## The Root Cause of Non-Determinism

The main source is **varying batch sizes**. Different batch sizes cause GPU kernels to split reduction operations differently, leading to different addition orders. Due to floating-point non-associativity (`(a + b) + c ≠ a + (b + c)`), this produces different results even for identical inputs.


## SGLang's Solution

Building on [Thinking Machines Lab's batch-invariant operators](https://github.com/thinking-machines-lab/batch_invariant_ops), SGLang achieves fully deterministic inference while maintaining compatibility with chunked prefill, CUDA graphs, radix cache, and non-greedy sampling. The development roadmap for deterministic inference features can be found in this [issue](https://github.com/sgl-project/sglang/issues/10278).

### Supported Backends

Deterministic inference is only supported with the following three attention backends: **FlashInfer**, **FlashAttention 3 (FA3)**, and **Triton**.

The following table shows feature compatibility for deterministic inference across different attention backends:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Attention Backend</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>CUDA Graph</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Chunked Prefill</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Radix Cache</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Non-greedy Sampling (Temp > 0)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FlashInfer**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌ No</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**FlashAttention 3 (FA3)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Triton**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>✅ Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes</td>
    </tr>
  </tbody>
</table>

## Usage

### Basic Usage

Enable deterministic inference by adding the `--enable-deterministic-inference` flag:

```bash Command
python3 -m sglang.launch_server \
    --model-path Qwen/Qwen3-8B \
    --attention-backend fa3 \
    --enable-deterministic-inference
```

### Server Arguments

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type/Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-deterministic-inference`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>flag; default: disabled</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Enable deterministic inference with batch-invariant operations</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--attention-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>string; default: fa3</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Choose attention backend (flashinfer, fa3, or triton)</td>
    </tr>
  </tbody>
</table>

### Example Configurations

#### Qwen3-8B
```bash Command
python3 -m sglang.launch_server \
    --model-path Qwen/Qwen3-8B \
    --attention-backend flashinfer \
    --enable-deterministic-inference
```

#### Llama Models
```bash Command
python3 -m sglang.launch_server \
    --model-path meta-llama/Llama-3.1-8B-Instruct \
    --attention-backend fa3 \
    --enable-deterministic-inference
```

#### Qwen3-30B-A3B (MoE Model)
```bash Command
python3 -m sglang.launch_server \
    --model-path Qwen/Qwen3-30B-A3B \
    --attention-backend fa3 \
    --enable-deterministic-inference
```

### Deterministic Inference with Non-Greedy Sampling (Temperature > 0)

SGLang supports deterministic inference even with non-greedy sampling by using sampling seeds. This is particularly useful for reinforcement learning scenarios like GRPO (Group Relative Policy Optimization) where you need multiple diverse but reproducible responses.

#### Default Behavior

By default, SGLang uses a sampling seed of `42` for reproducible sampling:

```python Example
import requests

response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "Tell me a joke",
        "sampling_params": {
            "temperature": 0.8,  # Non-greedy sampling
            "max_new_tokens": 128,
        },
    },
)
print(response.json())
# This will always produce the same response across runs
```

#### Generating Multiple Reproducible Responses

To sample different responses from the same prompt while maintaining reproducibility (e.g., for GRPO training), provide different sampling seeds in your requests:

```python Example
import requests

# Prepare a list of sampling seeds for different responses
sampling_seeds = [42, 43, 44, 45, 46]

responses = []
for seed in sampling_seeds:
    response = requests.post(
        "http://localhost:30000/generate",
        json={
            "text": "Tell me a joke",
            "sampling_params": {
                "temperature": 0.8,
                "max_new_tokens": 128,
                "sampling_seed": seed,  # Specify sampling seed
            },
        },
    )
    responses.append(response.json())

# Each seed will produce a different but reproducible response
# Using the same seed will always produce the same response
```

This approach ensures that:
- Different seeds produce diverse responses
- The same seed always produces the same response across different runs
- Results are reproducible for debugging and evaluation


## Verification

Run deterministic tests to verify consistent outputs:

```bash Command
# Single test: same prompt, varying batch sizes
python3 -m sglang.test.test_deterministic --test-mode single --n-trials 50

# Prefix test: prompts with different prefix lengths
python3 -m sglang.test.test_deterministic --test-mode prefix --n-trials 50

# Radix Cache Consistency mode: test radix cache determinism (cached vs uncached prefill)
python3 -m sglang.test.test_deterministic --test-mode radix_cache
```

Expected result: All tests should show `Unique samples: 1` (perfectly deterministic).

---

### Docs Advanced Features Dp Dpa Smg Guide (`docs/docs/advanced_features/dp_dpa_smg_guide.mdx`)

---
title: "DP, DPA and SGLang DP Router"
metatags:
    description: "Learn the differences between Data Parallelism, Data Parallelism Attention, and SGLang Model Gateway routing for production DP deployments."
---

This guide explains the difference between Data Parallelism (DP) and Data Parallelism Attention (DPA), how to enable each mode correctly, and how to use the SGLang Model Gateway (SMG) for production-grade DP deployments.

## Data Parallelism (DP)

**Data Parallelism (DP)** is the most common parallelism strategy that replicates the entire model across multiple GPU sets and processes different batches of requests in parallel. Each GPU set handles independent requests. With dedicated routing strategies, as we will introduce later, with those proper routing algorithms in SGLang Model Gateway, the throughput of your serving system could be multiplied nearly linearly.

### Key characteristics

- Each replica has a full copy of the model
- Requests are distributed/scattered across replicas
- No inter-replica communication during one request's inference (for simple DP)

## Data Parallelism Attention (DPA)

**Data Parallelism Attention (DPA)**, also known as DP Attention, is an advanced parallelism strategy. While DPA provides the most significant benefits for **Multi-Head Latent Attention (MLA)** models (such as DeepSeek, MiniMax, Kimi-K2), it also supports **standard attention models** like Qwen.

### The Problem with Tensor Parallelism for MLA Models

The most common parallelism strategy for inference is **Tensor Parallelism (TP)**. However, TP might not be the most efficient strategy for certain models. For example, DeepSeek models use MLA and only have **one KV head**. If we use tensor parallelism on 8 GPUs, it will lead to:

- **Duplicated KV cache** across all GPUs
- **Unwanted memory usage** that limits batch size
- **Reduced throughput** due to memory constraints

### How DPA Works

DPA addresses these limitations by applying **data parallelism specifically to the attention component**.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", verticalAlign: "top", backgroundColor: "rgba(255,255,255,0.02)"}}>
        <img src="/images/dpa.png" alt="DPA + EP Architecture" style={{width: "100%", height: "auto"}} />
      </td>
      <td style={{padding: "9px 12px", verticalAlign: "top", backgroundColor: "rgba(255,255,255,0.05)"}}>
        <p><strong>Each DP replica:</strong></p>
        <ul>
          <li>Processes different batches independently (can be in different forward modes: prefill, decode, or idle)</li>
          <li>Maintains its own KV cache (no duplication)</li>
          <li>Enables significantly larger batch sizes due to memory savings</li>
        </ul>
        <p><strong>Communication patterns in DPA + EP:</strong></p>
        <ul>
          <li><strong>All2All (Dispatch)</strong>: Routes tokens to expert sub-groups based on gating decisions</li>
          <li><strong>All2All (Combine)</strong>: Gathers computed results from experts back to original token positions</li>
        </ul>
      </td>
    </tr>
  </tbody>
</table>

### Key benefits of DPA

1. **Significantly reduced KV cache memory**: Each DP replica only stores KV cache for its own batches
2. **Larger batch sizes**: Memory savings enable larger batch sizes
3. **Improved decoding throughput**: Significant throughput gains for MLA-based models
4. **Independent forward modes**: Each DP replica can be in different forward modes (prefill, decode, or idle) and handles its assigned batches independently during attention computation

### DPA with Expert Parallelism for MoE

For MoE models like DeepSeek, DPA is **often** paired with Expert Parallelism (EP) for best throughput at scale. However, **DPA does not require EP**: you can enable DPA without EP if your deployment does not need expert sharding.

- Distribute 256+ expert weights across GPUs (cannot fit on a single GPU)
- Enable efficient all-to-all token routing via DeepEP
- Scale to large clusters (up to 5x throughput improvement over vanilla TP)

### Recommended setup for DeepSeek

```bash
python -m sglang.launch_server \
    --model-path deepseek-ai/DeepSeek-V3 \
    --tp 8 \
    --attn-dp-size 8 \
    --ep 8 \
    --moe-a2a-backend deepep \
    --moe-runner-backend deep_gemm
```

> **Note**: `--attn-dp-size` sets the number of attention data-parallel groups inside the TP group. If `attn_dp_size` is 1 (default), DPA is disabled.

For detailed EP configuration (DeepEP, Two-Batch Overlap, EPLB), see [Expert Parallelism](/docs/advanced_features/expert_parallelism).

### Target Models

DPA supports the following model architectures:

- **MLA (Multi-Head Latent Attention) models** - where DPA provides the most significant benefits:
  - DeepSeek family (DeepSeek-V2, DeepSeek-V3, DeepSeek-R1)
  - MiniMax models
  - Kimi-K2
  - Other models using MLA architecture

- **Standard attention models** - also supported:
  - Qwen models (see [PR #6121](https://github.com/sgl-project/sglang/pull/6121))

For models like Llama, with standard GQA, standard DP, or TP is typically recommended.

To enable DPA, add `--attn-dp-size N` (N > 1) to your server launch command.

### Activation Logic

DPA is enabled explicitly via server arguments (CLI or config) with `--attn-dp-size` (alias `--attention-data-parallel-size`). It creates N attention data-parallel groups inside the TP group, one scheduler each, while the FFN stays tensor parallel:

```bash
python -m sglang.launch_server \
    --model-path deepseek-ai/DeepSeek-V3 \
    --tp 8 \
    --attn-dp-size 8
```

**Important**: `--attn-dp-size` must be greater than 1 for DPA to work. When `attn_dp_size == 1` (default), DPA is disabled. The constraint `tp_size % attn_dp_size == 0` must also be satisfied. `--dp-size` only sets the number of data-parallel replicas of the model; combining replicas (`--dp-size` > 1) with DPA is not supported.

> **Deprecated**: `--enable-dp-attention` still works: `--dp-size N --enable-dp-attention` resolves to `--attn-dp-size N --dp-size 1` and prints a deprecation warning. Use `--attn-dp-size N` instead. The flag will be removed after 2026-12-31.
>
> Under DeepSeek context parallelism (DSA, MLA, and DeepSeek-V4 prefill CP), `--dp-size N` alone still runs N attention-DP groups, and logs a deprecation warning; it will be rejected after 2026-12-31. Use `--attn-dp-size N` there too.

**Elastic EP scale joiners.** A rank that joins an existing DPA deployment through elastic EP scale-up runs DPA even when it is launched with `--attn-dp-size 1`: its own attention DP group is one rank wide.

**DP rank count.** The number of DP ranks (one scheduler each) is `dp_size × attn_dp_size`; one of the two is always 1.
- `/server_info` reports `dp_size` (replicas) and `attn_dp_size` separately, so under DPA its `dp_size` is 1. Until the flag is removed, its deprecated `enable_dp_attention` field still reports whether DPA runs; new clients should read `attn_dp_size`.
- Wire formats that predate `--attn-dp-size` keep the key `dp_size` for the DP rank count: KV-event descriptors, the PD prefill server info, and load snapshots.

### TP LMHead with all-to-all

`dp-lm-head` keeps full weight and computes the local batch, making the gemm inefficient when batchsize per-rank is small. The existing `tp-lm-head` improves the gemm efficiency but introduce heavy allgather communication on full vocabulary.

Therefore, all-to-all can be applied to eliminate the heavy allgather while retaining the gemm efficiency under small per-rank batchsize. Each rank will send and receive only the local rows with sharded vocab, which is more lightweight.

This optimization is **enabled by default for decode node and pure DPA**. Users can use `--no-enable-tp-lm-head-all-to-all` to opt out, or `--enable-tp-lm-head-all-to-all` for force enabling.

```bash
python -m sglang.launch_server \
    --model-path MODEL_PATH \
    --disaggregation-mode decode \
    --tp 8 \
    --attn-dp-size 8
```

Prefill / colocated workers will fallback to TP LMHead with allgather, as well as other parallel strategies. More details can be found in [PR #32313](https://github.com/sgl-project/sglang/pull/32313).

### Standard DP for MLA models

Note that MLA models, of course, also support DP. Suppose you want to enable standard DP for MLA models. First, launch each MLA model's replica independently. You may launch these replicas one by one with DPA enabled. After launching each MLA model's replica, launch an SMG and connect all the replicas to the SMG. A detailed explanation of SMG is as follows.

## Modern Data Parallelism SGLang Model Gateway (SMG)

### Native DP Mode

Native DP (built-in Data Parallelism) in SGLang creates multiple worker processes within a single SGLang instance, under the control of `DataParallelController` with the launching parameter of `dp-size`.

```bash
# Native DP mode
python -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --dp-size 4
```

**Limitations:**

- Built-in in-process load balancing only (e.g., `round_robin`, `total_requests`, `total_tokens`)
- No cache-aware routing
- Limited observability and metrics
- No fault tolerance or circuit breakers
- Not suitable for production workloads

⚠️ Native DP is **highly not recommended for use right now**. It is only used in some ancient/outdated RL frameworks. You can use SGLang Model Gateway (SMG) to power up your data parallelism in any use case.

### SMG-Based DP (Recommended)

Starting from September 2024, SGLang Model Gateway, i.e., SMG, formerly named as SGLang DP Router, was built especially as a production-ready DP routing system with Rust. It starts from DP routing, but later we further expanded its scope to coordinate RL, PD Disaggregation, and other scenarios. This doc only discusses SMG's usage in DP routing. For other usage, please refer to [SGLang Model Gateway Documentation](/docs/advanced_features/sgl_model_gateway).

> To achieve the best production-level routing performance and reduce the overhead to an extreme extent, we use Rust to build SMG, but not Python, since Python is never FAST enough.

**We strongly recommend using the SGLang Model Gateway (SMG) for production-grade Data Parallelism.** SMG provides significant advantages over native DP mode.

```bash
# SMG-based DP mode (Recommended)
python -m sglang_router.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --dp-size 4
```

⚠️ Note that **SMG and Naive DP share the same launching parameter, `--dp-size`**. But the entrypoint of Naive DP is `python -m sglang.launch_server`, and SMG's entrypoint is `python -m sglang_router.launch_server`.

**Advantages of SMG-Based DP:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "28%"}} />
    <col style={{width: "34%"}} />
    <col style={{width: "38%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Feature</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Native DP</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>SMG-Based DP</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Load Balancing</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Built-in in-process methods</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Advanced policies (cache-aware, power-of-two, etc.)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Cache Awareness</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌ No</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes - significantly higher cache hit rate</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Throughput</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Baseline</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Significant improvement</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Multi-Node Support</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Limited</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Full support</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Worker Health Monitoring</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Basic</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Circuit breakers, health checks</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Reliability</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Basic</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Retries, rate limiting, queuing</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Observability</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Basic metrics</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ 40+ Prometheus metrics, OpenTelemetry</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Hot Worker Add/Remove</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>❌ No</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>✅ Yes</td>
    </tr>
  </tbody>
</table>

### SMG's Performance

The cache-aware routing policy in SMG significantly improves performance for workloads with shared prefixes:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Metric</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Without Cache-Aware</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>With Cache-Aware SMG</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Throughput (token/s)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>82,665</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>158,596 (+92%)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Cache Hit Rate</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>20%</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>75% (+275%)</td>
    </tr>
  </tbody>
</table>

*Benchmark from [SGLang v0.4 blog](https://lmsys.org/blog/2024-12-04-sglang-v0-4/), workload with multiple long prefix groups, 8x A100 80GB GPUs, dp-size=8*

### When to Use Each

**Use Native DP when:**

- ~Never use Native/Naive DP~
- Learning material of DP routing

**Use SMG-Based DP when:**

- In any case, when you think DP is needed
- Production deployments
- Multi-node distributed setups
- Workloads with shared prefixes (high cache reuse potential)
- You need high availability and reliability features
- You require detailed observability and metrics
- You want to have highly efficient RL rollout systems

Note that for RL rollout systems, **there are four crucial reasons that SMG-Based DP is far better than naive DP routing**. Details can be found at [Load Balancing Router in RL](/docs/advanced_features/sglang_for_rl#load-balancing-router).

### Quick Start For SMG

**Installation**

```bash
pip install sglang-router
# or
pip install "sglang[all]"
```

**Option A: Co-launch Workers and SMG (Simplest)**

This is the easiest way to get started - SMG and workers are launched together:

```bash
python -m sglang_router.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --dp-size 4 \
    --host 0.0.0.0 \
    --port 30000
```

**Option B: Separate Launch (Multi-Node)**

For distributed deployments across multiple machines:

1. Launch workers on each node

```bash
# Node 1
python -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --port 8000

# Node 2
python -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --port 8000
```

2. Launch SMG pointing to workers

```bash
python -m sglang_router.launch_router \
    --worker-urls http://node1:8000 http://node2:8000 \
    --policy cache_aware \
    --host 0.0.0.0 \
    --port 30000
```

**Option C: Dynamic Worker Registration**

For elastic deployments where workers can be added/removed dynamically:

```bash
# Launch SMG first
python -m sglang_router.launch_router \
    --policy cache_aware \
    --host 0.0.0.0 \
    --port 30000

# Register workers dynamically
curl -X POST http://localhost:30000/workers \
    -H "Content-Type: application/json" \
    -d '{"url": "http://worker1:8000"}'

curl -X POST http://localhost:30000/workers \
    -H "Content-Type: application/json" \
    -d '{"url": "http://worker2:8000"}'
```

### Load Balancing Policies

SMG supports multiple load balancing policies:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "24%"}} />
    <col style={{width: "42%"}} />
    <col style={{width: "34%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Policy</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Best For</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>cache_aware</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Combines cache locality with load balancing</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Recommended for most workloads</strong></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>round_robin</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Cycles through workers in order</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Simple, predictable distribution</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>random</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Random worker selection</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Baseline, testing</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>power_of_two</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Samples two workers, picks lighter one</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Low latency requirements</td>
    </tr>
  </tbody>
</table>

**Cache-Aware Policy (Default, Recommended)**

The cache-aware policy provides the best performance for most workloads:

```bash
python -m sglang_router.launch_router \
    --worker-urls http://worker1:8000 http://worker2:8000 \
    --policy cache_aware \
    --cache-threshold 0.5 \
    --balance-abs-threshold 32 \
    --balance-rel-threshold 1.5 \
    --eviction-interval-secs 120 \
    --max-tree-size 67108864
```

**How it works:**

1. Maintains an approximate radix tree for each worker based on request history
2. Routes requests to workers with the highest prefix match (cache hit)
3. Falls back to shortest-queue routing when load is imbalanced
4. Automatically evicts old entries to prevent memory overflow

### Best Practices

1. **Start with `cache_aware` policy** - It provides the best balance between cache locality and load distribution for most workloads
2. **Use SMG for production** - Prefer `sglang_router.launch_server` over `sglang.launch_server` for better reliability and observability
3. **Enable health checks** - Configure `--router-health-check-interval-secs` to detect and remove unhealthy workers automatically

**Recommended command with best practices applied:**

```bash
python -m sglang_router.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --dp-size 4 \
    --router-policy cache_aware \
    --router-health-check-interval-secs 30 \
    --router-prometheus-port 10001 \
    --host 0.0.0.0 \
    --port 30000
```

For advanced configuration (circuit breakers, retries, Prometheus metrics, K8s integration), see [SGLang Model Gateway Documentation](/docs/advanced_features/sgl_model_gateway).

### Verifying Traffic Distribution

After launching SMG, verify that traffic is being distributed correctly:

**1. Check worker status:**

```bash
curl http://localhost:30000/workers
```

**2. Check load distribution:**

```bash
curl http://localhost:30000/get_loads
```

**3. Monitor metrics (if Prometheus enabled):**

```bash
# Key metrics to check
smg_router_requests_total{model="..."}
smg_worker_requests_active{worker="..."}
sglang_cache_hit_rate{source="..."}
```

For detailed metrics and monitoring setup, see [SGLang Model Gateway Documentation](/docs/advanced_features/sgl_model_gateway).

## Reference

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Strategy</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Use Case</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Key Benefit</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>Native DP</strong> (<code>--dp-size</code>)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Never</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Easy to understand, not rust based</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>SMG-Based DP</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><strong>Production (recommended)</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Cache-aware routing, high availability</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>DPA</strong> (<code>--attn-dp-size N</code>)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepSeek/MLA models</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Eliminates KV cache duplication, improved throughput</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong>DPA + EP</strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepSeek MoE models</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Significant throughput improvement vs vanilla TP</td>
    </tr>
  </tbody>
</table>

**Recommended production setup for DeepSeek:**
1. Enable **DPA** for attention layers (`--attn-dp-size 8`)
2. Enable **EP** for MoE layers (`--ep 8 --moe-a2a-backend deepep`)
3. Use **SMG** with **cache_aware** policy

**Related documentation:**
- [Expert Parallelism](./expert_parallelism) - DeepEP, Two-Batch Overlap, EPLB
- [SGLang Model Gateway Documentation](./sgl_model_gateway) - SMG configuration & troubleshooting
- [Large-Scale EP Blog](https://lmsys.org/blog/2025-05-05-large-scale-ep/) - 96 GPU deployment guide

---

### Docs Advanced Features Dp For Multi Modal Encoder (`docs/docs/advanced_features/dp_for_multi_modal_encoder.mdx`)

---
title: "DP for Multi-Modal Encoder in SGLang"
metatags:
    description: "Data parallelism for VLM vision encoder in SGLang: reduce TTFT, boost throughput. Supports Qwen2.5-VL, Qwen3-VL, InternVL, GLM-4.5V/4.6V."
---
A typical VLM architecture involves two main components: an multi-modal encoder and a text decoder.

Most VLMs utilize a Vision Transformer (ViT) as their multi-modal encoder, it is responsible for processing visual data, extracting features (objects, colors, textures, etc.), and transforming them into a format that can be understood by the model.

The text deocoder is based on LLM. It processes textual data and generates output based on the encoded visual features.

However, since the size of ViT is very small compared to language decoders,
there is relatively little gain from TP. On the other hand, TP incurs significant communication
overhead because of all-reduce being performed after every layer.

Placing the ViT in data parallel while keeping the LLM in tensor parallel consistently lowers TTFT and boosts end-to-end throughput. In this hybrid layout, the vision front-end becomes parallel and lightweight, while scarce interconnect bandwidth and collective ops are reserved for the LLM.

Data parallelism replicates the entire model across multiple GPU sets and processes different batches of requests in parallel.

## Command Example
You can enable batch-level DP by setting `mm-enable-dp-encoder`, for example:
```shell Command
python3 -m sglang.launch_server \
    --model-path Qwen/Qwen2.5-VL-7B-Instruct \
    --tp 2 \
    --mm-enable-dp-encoder
```

## Known supported models
- Qwen2.5-VL (&lt;https://github.com/sgl-project/sglang/pull/13126&gt;)
- Qwen3-VL (&lt;https://github.com/sgl-project/sglang/pull/13724&gt;)
- InternVL (&lt;https://github.com/sgl-project/sglang/pull/13925&gt;)
- GLM-4.5V & GLM-4.6V (&lt;https://github.com/sgl-project/sglang/pull/14097&gt;)

---

### Docs Advanced Features Epd Disaggregation (`docs/docs/advanced_features/epd_disaggregation.mdx`)

---
title: "EPD Disaggregation"
metatags:
    description: "SGLang EPD disaggregation: separate encoder, prefill, decode stages for VLM inference. Independent scaling, load balancing, three-tier architecture."
---
## Why and What is EPD Disaggregation?

In modern Vision-Language Model (VLM) inference, request execution naturally decomposes into three distinct stages: Encoder, Prefill, and Decode.
The Encoder stage performs vision preprocessing and ViT-based image encoding, which is highly compute-intensive but only required during request initialization. The Prefill stage processes the full multimodal input sequence to initialize the language model’s Key-Value (KV) cache, while the Decode stage is dominated by memory bandwidth and KV cache access for autoregressive token generation.

Existing deployments typically colocate these stages within a unified execution engine, or at best apply Prefill–Decode (PD) disaggregation. However, such designs still tightly couple vision encoding with language prefill, leading to inefficient resource utilization, limited scalability for image-heavy workloads, and suboptimal scheduling under load.

To address these challenges, we introduce Encoder–Prefill–Decode (EPD) Disaggregation in SGLang. EPD further separates vision encoding from language processing, enabling independent horizontal scaling of encoder servers, improved load balancing for multimodal requests, and seamless integration with existing PD disaggregation to form a fully decoupled three-tier inference architecture.

### Usage

You can launch a language-only model using `--language-only`, or an encoder-only model using `--encoder-only`.
When launching a language-only model, you must additionally specify the encoder service endpoints via `--encoder-urls`.

We support multiple encoder transfer backends, including zmq_to_scheduler, zmq_to_tokenizer, and mooncake (the default is zmq_to_scheduler). The backend can be selected using `--encoder-transfer-backend`.

### Encoder transfer with Mooncake

`--encoder-transfer-backend mooncake` controls **how encoder outputs are transferred** between encoder and language/prefill services. It is an encoder transfer option and can be used independently of the global multimodal embedding cache.

Example:

```bash Command
# encoder
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --encoder-only \
  --encoder-transfer-backend mooncake \
  --port 30000

# language-only server
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --language-only \
  --encoder-urls http://127.0.0.1:30000 \
  --encoder-transfer-backend mooncake \
  --port 30002
```

### Global multimodal embedding cache with Mooncake

SGLang also supports a Mooncake-backed **global multimodal embedding cache** for EPD workloads. When enabled on encoder servers, repeated image inputs can reuse previously computed ViT embeddings across instances instead of running the vision encoder again.

This feature is useful when:

- the deployment serves repeated or overlapping image inputs,
- encoder compute is the bottleneck, and
- Mooncake is already available in the cluster.

At a high level, the encoder checks whether the image embedding already exists in Mooncake. Cache hits are prefetched from the global store, while misses are encoded normally and inserted into the cache in the background.

To enable it:

- install and configure Mooncake in the same way as other SGLang Mooncake integrations,
- add `--enable-mm-global-cache` on the encoder server.

`--enable-mm-global-cache` controls **whether multimodal embeddings are looked up and stored in the global Mooncake cache**. It is separate from `--encoder-transfer-backend`, which only controls encoder output transport.

For Mooncake deployment and configuration details, see [HiCache best practices](./hicache_best_practices#deployment-with-mooncake) and the [Mooncake backend README](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/mem_cache/storage/mooncake_store/README.md).

Example:

```bash Command
# Shared Mooncake configuration
export MOONCAKE_TE_META_DATA_SERVER="http://127.0.0.1:8080/metadata"
export MOONCAKE_MASTER="127.0.0.1:50051"
export MOONCAKE_PROTOCOL="rdma"
export MOONCAKE_GLOBAL_SEGMENT_SIZE="4gb"

# encoder with global multimodal cache enabled
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --encoder-only \
  --enable-mm-global-cache \
  --port 30000

# language-only server
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --language-only \
  --encoder-urls http://127.0.0.1:30000 \
  --port 30002
```

Notes:

- This cache is for **multimodal encoder embeddings**, not the language model KV cache.
- The feature currently uses Mooncake as the shared backing store.
- It can be enabled regardless of which `--encoder-transfer-backend` you use.
- It is most relevant for EPD or encoder-disaggregated VLM deployments where the same images are likely to appear across requests or instances.

#### Qwen VL

- EP Disaggregation

```bash Command
# encoder 0
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --encoder-only \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30000
# encoder 1
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --encoder-only \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30001
# language-only server
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --language-only \
  --encoder-urls http://127.0.0.1:30000 http://127.0.0.1:30001 \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30002
```

- EPD Disaggregation

```bash Command
# encoder 0
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --encoder-only \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30000
# encoder 1
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --encoder-only \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30001
# prefill 0
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --disaggregation-mode prefill \
  --language-only \
  --encoder-urls http://127.0.0.1:30000 http://127.0.0.1:30001 \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30002
# decode 0
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --disaggregation-mode decode \
  --port 30003
# router
python -m sglang_router.launch_router \
  --pd-disaggregation \
  --prefill http://$PREFILL_HOST:30002 \
  --decode http://$DECODE_HOST:30003 \
  --port 8000

```

#### gRPC Encoder (EPD)

You can run the encoder as a gRPC server while keeping prefill/decode as HTTP.
When using gRPC encoders, set `SGLANG_ENCODER_MM_RECEIVER_MODE=grpc` for the
prefill process so it uses the gRPC receiver.

```bash Command
# gRPC encoder
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --encoder-only \
  --grpc-mode \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30000

# prefill (HTTP) - tell it to use gRPC receiver
SGLANG_ENCODER_MM_RECEIVER_MODE=grpc \
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --disaggregation-mode prefill \
  --language-only \
  --encoder-urls grpc://127.0.0.1:30000 \
  --encoder-transfer-backend zmq_to_scheduler \
  --port 30002

# decode (HTTP)
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-VL-8B-Instruct \
  --disaggregation-mode decode \
  --port 30003

# router
python -m sglang_router.launch_router \
  --pd-disaggregation \
  --prefill http://$PREFILL_HOST:30002 \
  --decode http://$DECODE_HOST:30003 \
  --port 8000
```

---

### Docs Advanced Features Expert Parallelism (`docs/docs/advanced_features/expert_parallelism.mdx`)

---
title: "Expert Parallelism"
metatags:
    description: "SGLang Expert Parallelism: distribute MoE experts across GPUs, DeepEP all-to-all, grouped GEMMs, TBO/SBO overlap, EPLB load balancing."
---
Expert Parallelism (EP) in SGLang distributes expert weights across multiple devices in Mixture-of-Experts (MoE) models, addressing memory bottlenecks and enabling efficient scaling for high-performance inference. It is particularly vital for serving large-scale MoE models where tokens are dynamically routed to specialized experts across GPUs. By leveraging optimized all-to-all communication and grouped matrix multiplications (GEMMs), EP reduces latency, boosts throughput, and minimizes idle GPU time. SGLang's EP offers strong extensibility through its modular framework, allowing seamless integration of custom kernels, backends, and optimizations without refactoring core logic, supporting diverse hardware and quantization schemes.

## Supported Backends and Selection Guidance

SGLang's EP integrates diverse, highly efficient backends for different use cases, allowing fine-grained control over performance trade-offs. Users specify backends via command-line flags:
- `--moe-a2a-backend`: Selects the backend for all-to-all communication.
- `--moe-runner-backend`: Selects the backend for MoE computation.

### Backends for All-to-All Communication

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Backend</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Use Cases</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`none` (default)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disables all-to-all for EP. Uses All-Reduce or All-Gather for token dispatch.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Hybrid EP and TP setups.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`deepep`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepEP, a communication library for efficient token shuffling in MoE models.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Large-scale EP deployments.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`mooncake`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>An extension of DeepEP for elastic inference, leveraging RDMA for high-performance data transfers.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Elastic EP serving.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>nixl</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><a href="https://github.com/ai-dynamo/nixl/tree/main/examples/device/ep">NIXL-EP</a>, an elastic EP communication library built on NVIDIA's <a href="https://github.com/ai-dynamo/nixl">NIXL</a> framework with native RDMA and NVLink support.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Elastic EP serving with fault tolerance and dynamic scaling.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>mori</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>MORI-EP, AMD's native all-to-all communication implementation optimized for ROCm.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>AMD GPU deployments.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`flashinfer`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Flashinfer implementation of all-to-all.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Large-scale EP deployments.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`ascend_fuseep`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Ascend NPU native fused all-to-all communication.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Ascend NPU deployments.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`pplx`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><a href="https://github.com/perplexityai/pplx-kernels">pplx-kernels</a>, Perplexity's NVSHMEM-based all-to-all dispatch/combine kernels. Low-latency (masked) only; targets FP8 (DeepGEMM) MoE models on Hopper. Requires NVSHMEM 3.2.5, <code>nvshmem4py</code>, <code>cuda-python</code>, and a prebuilt <code>libpplx_kernels.so</code> (<code>sm_90a</code>).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Low-latency decode EP on Hopper.</td>
    </tr>
  </tbody>
</table>

DeepEP and Mooncake backends support two modes for token dispatch: `normal` mode (optimized for prefill workloads with high throughput) and `low_latency` mode (optimized for decode workloads with low latency and CUDA Graph compatibility). MORI backend only supports `normal` mode now. NIXL-EP and PPLX currently operate in low-latency mode with CUDA Graph support (PPLX reuses the DeepEP low-latency masked expert-compute path). Users are recommended to set `--deepep-mode auto` to enable automatic dispatch mode switching during runtime. Setting `--deepep-mode normal` or `--deepep-mode low_latency` is useful for debugging or development purposes.

Currently, DeepEP, Mooncake, NIXL-EP, `ascend_fuseep`, `pplx` and MORI only support cases where `ep_size = tp_size`. For hybrid EP and TP (i.e., `ep_size < tp_size`), only the `none` backend (All-Reduce or All-Gather-based dispatching) is supported. Note that `pplx` additionally requires DP attention with at least 2 attention DP groups (i.e., `--attn-dp-size` > 1, so `tp_size / attention_tp_size > 1`); otherwise pplx-kernels' AllToAll cannot be constructed.

### Backends for MoE Computation

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Backend</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Use Cases</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`auto` (default)**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Automatically selects the optimal backend based on model architecture, hardware (e.g., NVIDIA architecture like Ampere, Hopper, Blackwell), quantization scheme (e.g., FP8, FP4), and runtime conditions.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>General-purpose deployments; ensures compatibility and performance without user intervention.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`triton`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Triton-based implementation for grouped GEMMs. To achieve higher performance, it's highly recommended to create <a href="https://github.com/sgl-project/sglang/blob/main/benchmark/kernels/fused_moe_triton/README.md">tuned configurations</a>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Custom kernel development or scenarios requiring high extensibility with Torch compilation support.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`deep_gemm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepGEMM backend optimized for MoE matrix multiplications, supporting contiguous layouts for prefill and masked layouts for decode; often JIT-compiled for performance.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Large-scale EP deployments with FP8 block-wise quantization.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`cutlass`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>CUTLASS-based backend for efficient GEMMs.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>NVIDIA architectures with CUTLASS support.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`flashinfer_trtllm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>FlashInfer integrated with TensorRT-LLM for accelerated MoE computations, supporting FP4 communication operators and high-performance GEMMs.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Blackwell with TRT-LLM.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>flashinfer_trtllm_routed</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>FlashInfer integrated with TensorRT-LLM for accelerated routed MoE computations, consuming SGLang-computed top-k expert assignments and weights. Compatible with flashinfer all-to-all.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Blackwell with TRT-LLM.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`flashinfer_cutlass`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>FlashInfer combined with CUTLASS for high-performance grouped GEMMs in MoE layers, handling FP4/FP8 quantization efficiently.  Compatible with flashinfer all-to-all.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Blackwell with FP4/FP8 models.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`flashinfer_mxfp4`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>FlashInfer variant optimized for MXFP4 (mixed FP4) quantization in MoE runners, focusing on memory-efficient low-precision inference.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Low-precision models with MXFP4.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`flashinfer_cutedsl`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>FlashInfer with a custom DSL for flexible and efficient MoE kernel generation, integrated with ModelOpt FP4 quantization. Compatible with flashinfer all-to-all.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Low-precision models with NVFP4.</td>
    </tr>
  </tbody>
</table>

### Examples

Launch with DeepEP and DeepGEMM for DeepSeek-V3:

```bash Command
python -m sglang.launch_server --model-path deepseek-ai/DeepSeek-V3 --moe-a2a-backend deepep --moe-runner-backend deep_gemm --tp 8 --ep 8
```

## Extensible EP Framework

SGLang's EP framework provides modular abstractions for easy integration of custom kernels, backends, and optimizations. It decouples the MoE forward pass into stages (dispatch → pre-permute → core runner → post-permute → combine), enabling seamless extensions without refactoring core logic. A fused function registered for a layer's all-to-all and runner backends replaces the three middle stages.

### Framework Overview

The framework centers on `FusedMoE` as the unified entry point for a single, extensible structure. Key components include:
- **Dispatcher**: Manages dispatch/combine for backends like DeepEP (implements `BaseDispatcher` subclasses).
- **MoeRunner**: Orchestrates grouped-GEMM execution via `MoeRunnerCore` implementations (e.g., `TritonRunnerCore`).
- **FusedOpPool** and **PermuteMethodPool**: Auto-register fused functions per all-to-all and runner backend pair (`register_fused_func`) and layout conversions (`register_pre_permute` and `register_post_permute`). `MoeRunner.run` calls the fused function when one is registered for the layer's pair and LoRA is disabled; otherwise it runs pre-permute, the runner core, and post-permute, or hands the dispatch output to a `DispatchMoeRunnerCore`.
- **TopK Router**: Backend-agnostic expert selection.

This design supports multiple backends via `--moe-a2a-backend` and `--moe-runner-backend`, with quantization integrated through a standardized `apply()` method. The computation flow ensures modularity:

```text Output
[input_hidden_states]
          |
          v
     TopK.forward -> select_experts / triton_kernels.routing / bypass
          |
          v
     [TopKOutput]
          |
          v
   FusedMoE.forward -> Dispatcher.dispatch -> DeepEP / bypass
          |                     |
          |                     v
          |              [DispatchOutput]
          |                     |
          |                     v
          |             quant_method.apply -> MoeRunner.run
          |                     |              |
          |                     |              v
          |                     | fused func
          |                     | or DispatchMoeRunnerCore.run_from_dispatch
          |                     | or pre-permute + grouped_gemm + post-permute
          |                     |              |
          |                     |--------------
          |                     v
          |               [CombineInput]
          |                     |
          |                     v
          |            Dispatcher.combine -> DeepEP / bypass
          |                     |
          |---------------------
          v
[final_hidden_states]
```

For details, see the [MoE Refactor Roadmap](https://github.com/sgl-project/sglang/issues/8715).

### Implementing New Backends

To add a new backend:
1. For a new all-to-all dispatcher, implement a `BaseDispatcher` subclass with `dispatch` and `combine` methods.
2. For a new MoE runner backend, define a `MoeRunnerCore` subclass for core operations (e.g., grouped GEMMs).
3. Define new input/output formats for the dispatcher or model runner (e.g., `RunnerInput`, `RunnerOutput`).
4. Register permute/unpermute methods to ensure compatibility:
   - **Fused Mode** (static, torch.compile-compatible): Use `register_fused_func` for end-to-end operations.
   - **Permute Mode** (dynamic): Register `register_pre_permute` and `register_post_permute` for flexible layouts.

   When both are registered for a backend pair, the fused function takes precedence; the non-fused path still serves LoRA, which skips fused functions.

See the [MoE Refactor Implementation PR](https://github.com/sgl-project/sglang/pull/9269) for full changes, including type hints and config expansions.

### Examples

For an example implementation, see [moe_runner/triton.py](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/layers/moe/moe_runner/triton.py), which demonstrates Triton-based grouped GEMMs with a fused function registered for the `none` all-to-all backend and permutation functions as the fallback path, used for example with LoRA.

## Computation and Communication Overlap

SGLang's EP employs advanced overlap techniques to hide communication latency behind computation, maximizing GPU utilization in MoE layers.

### Two-Batch Overlap (TBO)

TBO splits requests into micro-batches, interleaving attention computation with dispatch/combine operations. Yield points in the execution graph allow pausing for overlaps, increasing overall throughput without peak memory spikes:

```python Example
operations = [
    self._forward_attn,
    YieldOperation(),  # Overlap with dispatch of prior micro-batch
    self._forward_dispatch,
    self._forward_mlp,
    YieldOperation(),  # Overlap with combine
    self._forward_combine,
]
```

Users need to specify `--enable-two-batch-overlap` to unlock up to 2x throughput. For details, see the [Large-Scale EP Blog](https://lmsys.org/blog/2025-05-05-large-scale-ep/#two-batch-overlap).

### Single-Batch Overlap (SBO)

SGLang introduces a dispatcher-hook system for Single-Batch Overlap (SBO), enabling the overlap of operations within a single batch—such as shared experts computation with communication—while decentralizing logic to enhance modularity. These hooks execute before and after the `dispatch` and `combine` operations without modifying core MoE modules. This design simplifies interfaces, reduces coupling, and improves extensibility. For implementation details and an example of overlapping shared experts with DeepEP's combine operation, refer to [PR #13327](https://github.com/sgl-project/sglang/pull/13327). Users can set `--enable-single-batch-overlap` to enable this feature.


## Workload Balancer

SGLang integrates the [Expert Parallelism Load Balancer (EPLB)](https://github.com/deepseek-ai/EPLB) from DeepSeek to address routing imbalances in MoE models. By analyzing expert activation statistics, EPLB computes an optimal expert arrangement, strategically placing or replicating experts to minimize GPU utilization variance, reduce idle cycles, and enhance scalability.

To enable EPLB, use the flags `--enable-eplb`. For optimal performance, increase batch sizes to stabilize activation statistics and configure periodic rebalancing (e.g., every 1000 requests) to adapt to evolving workloads. Simulations demonstrate significant improvements in load balancedness (ratio of mean to max computation time), correlating strongly with throughput gains.

For more details, refer to the [EPLB Section in the Large-Scale EP Blog](https://lmsys.org/blog/2025-05-05-large-scale-ep/#expert-parallelism-load-balancer) and the [EPLB Repository](https://github.com/deepseek-ai/eplb).


## Ascend NPU Guidance
### Guidance on SGLang configuration in Ascend NPU
- `--moe-a2a-backend` only supports `deepep` and `ascend_fuseep` backends,

    - `deepep`: The mechanism is consistent with the above description.

    - `ascend_fuseep`: Offer a large fused operator which integrates all operations between dispatch and combine to boost MoE computation. Only used for decode stage in PD Disaggregation Mode.

- `--moe-runner-backend` parameter does not need to be configured.

- `--deepep-mode`:

    - In PD mixed mode, please set `--deepep-mode auto`.

    - In PD Disaggregation Mode, prefill instance sets `--deepep-mode normal`, and decode instance sets `--deepep-mode low_latency`.

### DeepEP Ascend Introduction
DeepEP Ascend is the adapted version of the DeepEP communication library for Huawei Ascend NPUs, specifically designed for Mixture-of-Experts (MoE) model Expert Parallelism (EP).
It supports the Ant-moving Function (Split the sequence length into rounds for streaming batch transmission) to optimize the buffer size occupied during collective communication in prefill stage, especially for long sequences.

Ant-moving Function can be enabled for both the dispatch and combine phases via the following environment variables:

- `DEEPEP_NORMAL_LONG_SEQ_PER_ROUND_TOKENS`: Enable ant-moving function in dispatch stage. Indicates the number of tokens transmitted per round on each rank, default 8192.

- `DEEPEP_NORMAL_LONG_SEQ_ROUND`: Enable ant-moving function in dispatch stage. Indicates the number of rounds transmitted on each rank, default 1.

- `DEEPEP_NORMAL_COMBINE_ENABLE_LONG_SEQ`: Enable ant-moving function in combine stage, default 0 (means disabled).

`DEEPEP_NORMAL_LONG_SEQ_PER_ROUND_TOKENS * DEEPEP_NORMAL_LONG_SEQ_ROUND` means input sequence length. When the input sequence length exceeds 8192, it is recommended to enable the ant-moving function in both dispatch and combine phase.

The environment variable `HCCL_BUFFSIZE` is used to configure the buffer size (MB) actually allocated. Its calculation formula is as follows:
```text Output
# Enable Ant-moving Function
HCCL_BUFFSIZE >= 2 * (102MB + 4MB + DEEPEP_NORMAL_LONG_SEQ_PER_ROUND_TOKENS * (hidden_size + hidden_size + hidden_size) * topk) + PADDING_BUFFSIZE

# Disable Ant-moving Function
HCCL_BUFFSIZE >= 2 * (102MB + 4MB + TOTAL_SEQ_LEN * (hidden_size + hidden_size) * topk) + PADDING_BUFFSIZE
```
Wherein the parameters are described as follows:

- `hidden_size`: hidden size in model config.

- `topk`: The number of selected routing experts.

- `TOTAL_SEQ_LEN`: input sequence length.

- `PADDING_BUFFSIZE`: A value of 20 or greater is recommended.

---

### Docs Advanced Features Forward Hooks (`docs/docs/advanced_features/forward_hooks.mdx`)

---
title: "Model Forward Hooks"
metatags:
    description: "SGLang forward hooks: attach PyTorch hooks to model submodules via JSON config. Log activations, debug internals, export hidden states."
---

## Model Hooks

SGLang supports attaching PyTorch forward hooks to specific submodules in the loaded model, configured entirely via `server_args` JSON.

This is useful for:

* Logging intermediate activations
* Debugging model internals
* Exporting hidden states to external tooling

Hooks are attached once during `ModelRunner.initialize` and run on every forward pass.

***
### Configuration overview

Hooks are configured via a `ServerArgs` field:

```python Example
class ServerArgs:
    ...
    # For forward hooks
    forward_hooks: Optional[List[dict[str, Any]]] = None
````

In JSON form, a minimal configuration looks like:

```jsonc Example
{
  "forward_hooks": [
    {
      "name": "outer_linear_hooks",
      "target_modules": ["outer.0", "outer.1"],
      "hook_factory": "my_project.hooks:dummy_hook_factory",
      "config": {
        "tag": "outer-layer"
      }
    }
  ]
}
```

#### Top-level fields

* `forward_hooks` (optional list of objects)
  Each element is a hook spec describing:

  * Which modules to target
  * Which Python factory to call
  * What configuration to pass into that factory

***
### Hook spec schema

Each entry in `forward_hooks` is a JSON object with the following shape:

```jsonc Example
{
  "name": "optional-descriptive-name",
  "target_modules": ["pattern1", "pattern2", "..."],
  "hook_factory": "module.submodule:factory_name",
  "config": {
    "...": "arbitrary JSON"
  }
}
```

#### `name` (optional)

* Human-readable name for logging.
* Used only in log messages such as:

  ```text Output
  Registered forward hook 'outer_linear_hooks' on outer.0
  ```

#### `target_modules` (required)

* List of **module name patterns** used to match entries in `model.named_modules()`.
* Patterns are matched using `fnmatch.fnmatch`, so:

  * `"outer.0"` matches exactly `"outer.0"`.
  * `"outer.*"` matches `"outer.0"`, `"outer.1"`, `"outer.inner"`, etc.
  * `"outer.inner.*"` matches children under `outer.inner`.

> If no modules match the given patterns, hook registration does **not** fail.
> Instead, SGLang logs a warning and continues:
>
> ```text
> No modules matched hook spec 'name' patterns=['...']
> ```

#### `hook_factory` (required)

* String path to the Python factory function that creates the hook.
* Supported formats:

  * `"package.module:factory_name"`
  * `"package.module.submodule.factory_name"`

The path is resolved via:

```python Example
def resolve_callable(path: Optional[str]) -> Optional[Callable]:
    if path is None:
        return None

    if ":" in path:
        module_name, fn_name = path.split(":", 1)
    else:
        parts = path.split(".")
        if len(parts) < 2:
            raise ValueError(
                f"Invalid hook callable path '{path}'. "
                "Expected 'module.submodule:factory' or 'module.submodule.factory'."
            )
        *mod_parts, fn_name = parts
        module_name = ".".join(mod_parts)

    module = importlib.import_module(module_name)
    try:
        return getattr(module, fn_name)
    except AttributeError as e:
        raise AttributeError(
            f"Module '{module_name}' has no attribute '{fn_name}' "
            f"(from hook path '{path}')"
        ) from e
```

**Failure modes**:

* If the path is malformed (not enough dots and no `:`), a `ValueError` is raised at startup.
* If the module imports but the attribute is missing, an `AttributeError` is raised with a clear error message.
* If the hook factory returns `None`, a warning is logged and no hook is registered for that spec (initialization continues).

The first two cause initialization to fail fast with a descriptive error; the last one is non-fatal.

#### `config` (optional)

* Arbitrary JSON object.
* Passed directly to the hook factory as a Python `dict`.
* This lets you parameterize hook behavior from config (e.g. tags, log levels, sampling rates, etc.).

***
### Hook lifecycle and behavior

Hooks are registered in `ModelRunner.initialize()`:

```python Example
if server_args.forward_hooks:
    register_forward_hooks(self.model, server_args.forward_hooks)
```

The actual registration logic is implemented by `register_forward_hooks`:

```
/* Detailed source-code truncated for AI context efficiency. */
```

Key points:

* Hooks are **forward hooks only** (via `module.register_forward_hook`).
* They are attached once at initialization.
* Hook handles are currently not stored on `ModelRunner` (they cannot be removed later via this API).
* Failure to match any modules is non-fatal; a warning is logged instead.
* If a hook factory returns `None`, a warning is logged and that spec is skipped.

***
### Writing a hook factory

A hook factory is a regular Python function:

* Takes a `config: dict` (from JSON)
* Returns a forward hook function with signature `(module, inputs, output)`

Example:

```python Example
HOOK_CALLS = []

def dummy_hook_factory(config):
    """Factory that returns a forward hook capturing a tag from config."""
    tag = config.get("tag", "default")

    def hook(module, inputs, output):
        HOOK_CALLS.append(
            {
                "module_type": type(module).__name__,
                "tag": tag,
                "shape": tuple(output.shape),
            }
        )
        return output  # must return output if you don’t want to modify the tensor

    return hook
```

In JSON:

```jsonc Example
{
  "forward_hooks": [
    {
      "name": "capture_outer",
      "target_modules": ["outer.0", "outer.1"],
      "hook_factory": "my_project.hooks:dummy_hook_factory",
      "config": {
        "tag": "outer"
      }
    }
  ]
}
```

This will:

* Resolve `my_project.hooks:dummy_hook_factory` to a Python callable.
* Call it with `config = {"tag": "outer"}`.
* Use the returned hook for all modules matching `outer.0` and `outer.1`.
* Append metadata about each call to `HOOK_CALLS`.

***
### Summary

* Define `forward_hooks` as a list of specs in `ServerArgs` to turn on the feature.

* Each spec:

  * selects modules via `target_modules` (glob patterns over `model.named_modules()`),
  * points to a hook factory via `hook_factory`,
  * passes arbitrary `config` into that factory.

* Hook factories are resolved via `resolve_callable`, which supports `module:factory` and `module.submodule.factory`.

* Hooks are standard PyTorch forward hooks, attached once at startup and invoked on every forward pass.

* Misconfiguration is either:

  * **fatal and explicit** (bad path / missing attribute), or
  * **non-fatal with clear warnings** (no targets matched, or factory returned `None`).

---

### Docs Advanced Features Hicache (`docs/docs/advanced_features/hicache.mdx`)

---
title: "Hierarchical KV Caching (HiCache)"
metatags:
    description: "SGLang HiCache: three-tier KV caching (GPU, CPU, storage) for long-context and multi-turn inference. Supports Mooncake, 3FS, NIXL backends."
---
- [Hicache Best Practices](./hicache_best_practices)
- [Hicache Design](./hicache_design)
- [Hicache Storage Runtime Attach Detach](./hicache_storage_runtime_attach_detach)

---

### Docs Advanced Features Hicache Best Practices (`docs/docs/advanced_features/hicache_best_practices.mdx`)

---
title: "SGLang HiCache Best Practices"
metatags:
    description: "HiCache configuration guide: memory layout, prefetch policies, PD disaggregation, HF3FS and Mooncake deployment, custom storage backends."
---
## Why HiCache Matters

SGLang HiCache extends the traditional RadixAttention with a three-tier hierarchical KV caching system that dramatically improves performance for long-context and multi-turn conversation scenarios. By intelligently managing KV caches across GPU memory, host memory, and external storage backends, HiCache addresses the fundamental capacity bottleneck that limits cache hit rates in conventional systems.

<Note>
L1 and L2 are private to a single inference instance; only L3 can be shared. Host memory cannot be pooled across instances or across hosts, not even for two instances on the same node. Raising `--hicache-ratio` or `--hicache-size` only enlarges the instance's own private L2. Cross-instance reuse is the job of L3, which needs `--hicache-storage-backend` and a backend configured for the scope you want: the `file` backend defaults to the node-local `/tmp/hicache`, whereas `mooncake`, `hf3fs`, `nixl` and `aibrix` reach cluster scope when every instance shares the same namespace. See [Tier Sharing Scope](/docs/advanced_features/hicache_design#tier-sharing-scope).
</Note>

## Configuration Guidelines

## Core HiCache Parameters

```bash Command
# Essential HiCache flags
--page-size 64                        # Page size for cache management
--enable-hierarchical-cache           # Enable HiCache
--hicache-ratio 2                     # Host memory ratio (2x GPU memory)
--hicache-size 100                    # Host memory size in GBs, will override the above ratio
--hicache-io-backend kernel           # The I/O backend of moving data between CPU and GPU
--hicache-write-policy write_through  # Cache write policy from GPU to CPU
--hicache-storage-backend             # Optional storage backend (e.g., hf3fs, mooncake, etc.)
```

Notes:

- Besides configuring `--hicache-storage-backend` at startup, SGLang also supports **runtime attach/detach** of the HiCache storage backend (no restart required) via HTTP admin endpoints. See [Runtime Attach/Detach HiCache Storage Backend](./hicache_storage_runtime_attach_detach).

## Key Configurations with Storage Backends Enabled

### Host Pool Sizing

```bash Command
# Recommended: size the host pool as a multiple of the GPU KV pool
--hicache-ratio 2
--hicache-size 0
```

Guidelines:

- Storage (L3) hits are staged in the host pool before being loaded to the GPU, so the host pool needs free room at the time of the hit.
- With `write_through`, every token cached on the GPU also keeps a host copy. Once the GPU pool is full, at most `host pool tokens - GPU pool tokens` is left for storage hits.
- If the host pool is not larger than the GPU pool, storage hits are dropped and the prompt is recomputed. `sglang:storage_prefetch_unfulfilled_tokens_total{reason="host_capacity"}` grows.
- `--hicache-size` sets the host pool in GB and overrides `--hicache-ratio`. If you set it, check that the host pool is larger than the GPU pool in tokens, as reported in the startup log.

### Memory Layout Optimization

```bash Command
# Page-first: Optimized for I/O efficiency with zero-copy (recommended with kernel backend)
--hicache-mem-layout page_first
# Page-first-direct: Optimized for direct I/O operations (Compatible with fa3 and same zero-copy performance as page_first)
--hicache-mem-layout page_first_direct
# Layer-first
--hicache-mem-layout layer_first
```
**Layout Compatibility:**
- `page_first`: Only compatible with `kernel` I/O backend, automatically switches to `layer_first` with `direct` backend
- `page_first_direct`: Specifically designed for `direct` I/O backend with optimized memory organization

### Heterogeneous TP Support (GQA/MHA models)

HiCache storage supports cross-cluster KV reuse when different deployments use different TP sizes (for example, `tp=4` and `tp=8`) and share the same storage backend namespace.

Use `tp_lcm_size` in `--hicache-storage-backend-extra-config`:

```bash Command
# Example: heterogeneous TP = {4, 8}, so lcm = 8
--hicache-storage-backend-extra-config '{"tp_lcm_size": 8}'
```

Guidelines:

- Set `tp_lcm_size` to the least common multiple (LCM) of all TP sizes that will share the same HiCache storage.
- For MHA models with Mooncake and `page_head` layout, HiCache will split head shards based on `tp_lcm_size` to make keys reusable across heterogeneous TP deployments.
- If all clusters use the same TP size, this option is not needed.

### Prefetch Policies

```bash Command
# Best-effort: Terminate prefetch when needed
--hicache-storage-prefetch-policy best_effort
# Wait-complete: Ensure complete prefetch, higher cache reuse
--hicache-storage-prefetch-policy wait_complete
# Timeout: Balance between completion and best-effort
--hicache-storage-prefetch-policy timeout
```

### Integration with PD Disaggregation

HiCache works seamlessly with PD Disaggregation. You can choose between two configurations:

1. **Prefill-only HiCache**: Enable HiCache only on Prefill nodes, allowing KV cache sharing among Prefill instances
2. **Full HiCache with async offloading**: Enable HiCache on Prefill nodes and async KV cache offloading on Decode nodes, allowing Prefill nodes to reuse KV caches from Decode nodes in multi-turn dialogue scenarios

```bash Command
# Prefill node with HiCache enabled for cross-prefill sharing (ideal for SystemPrompt scenarios)
python3 -m sglang.launch_server \
  --model-path /xxx/DeepSeek-R1/ \
  --tp 8 \
  --host 0.0.0.0 \
  --port 10000 \
  --enable-metrics \
  --enable-cache-report \
  --mem-fraction-static 0.85 \
  --page-size 64 \
  --enable-hierarchical-cache \
  --hicache-ratio 2 \
  --hicache-size 0 \
  --hicache-mem-layout page_first_direct \
  --hicache-io-backend direct \
  --hicache-write-policy write_through \
  --hicache-storage-backend hf3fs \
  --hicache-storage-prefetch-policy wait_complete \
  --disaggregation-ib-device mlx5_0 \
  --disaggregation-mode prefill \
  --disaggregation-transfer-backend mooncake

# Decode node with async offloading enabled for KV cache reuse by Prefill (ideal for multi-turn conversations)
python3 -m sglang.launch_server \
  --model-path /xxx/DeepSeek-R1/ \
  --tp 8 \
  --host 0.0.0.0 \
  --port 10000 \
  --enable-metrics \
  --enable-cache-report \
  --page-size 64 \
  --hicache-ratio 2 \
  --hicache-size 0 \
  --hicache-mem-layout page_first_direct \
  --hicache-io-backend direct \
  --hicache-write-policy write_through \
  --hicache-storage-backend hf3fs \
  --hicache-storage-prefetch-policy wait_complete \
  --disaggregation-decode-enable-offload-kvcache \  # Enable async KV cache offloading in decode node
  --disaggregation-ib-device mlx5_0 \
  --disaggregation-mode decode \
  --disaggregation-transfer-backend mooncake
```


### Deployment with HF3FS

Here is an example of deploying DeepSeek-R1 with HiCache-HF3FS. For more details, see the [HF3FS Documentation](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/mem_cache/storage/hf3fs/docs/README.md).

```bash Command
python3 -m sglang.launch_server \
  --model-path /xxx/DeepSeek-R1/ \
  --log-level info \
  --tp 8 \
  --host 0.0.0.0 \
  --port 10000 \
  --enable-metrics \
  --enable-cache-report \
  --page-size 64 \
  --mem-fraction-static 0.85 \
  --enable-hierarchical-cache \
  --hicache-ratio 2 \
  --hicache-size 0 \
  --hicache-mem-layout page_first_direct \
  --hicache-io-backend direct \
  --hicache-write-policy write_through \
  --hicache-storage-backend hf3fs \
  --hicache-storage-prefetch-policy wait_complete \
```

### Deployment with Mooncake

Here is an example of deploying Qwen3-235B-A22B-Instruct-2507 with Mooncake. For more details, see the [Mooncake Documentation](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/mem_cache/storage/mooncake_store/README.md).

```bash Command
# Set Mooncake environment variables
export MOONCAKE_TE_META_DATA_SERVER="http://127.0.0.1:8080/metadata"
export MOONCAKE_GLOBAL_SEGMENT_SIZE=816043786240
export MOONCAKE_PROTOCOL="rdma"
export MOONCAKE_DEVICE="$DEVICE_LIST"
export MOONCAKE_MASTER=127.0.0.1:50051

# Launch SGLang server with Mooncake backend
python3 -m sglang.launch_server \
  --model-path $MODEL_PATH \
  --tp 8 \
  --page-size 64 \
  --enable-hierarchical-cache \
  --hicache-ratio 2 \
  --hicache-mem-layout page_first_direct \
  --hicache-io-backend direct \
  --hicache-storage-backend mooncake \
  --hicache-write-policy write_through \
  --hicache-storage-prefetch-policy timeout
```


## Custom Storage Backend Integration

To integrate a new storage backend:

1. **Implement three core methods:**
   - `get(key)`: Retrieve value by key
   - `exists(key)`: Check key existence
   - `set(key, value)`: Store key-value pair

2. **Register your backend:** Add your storage backend to the HiCache [BackendFactory](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/mem_cache/storage/backend_factory.py#L188)

The HiCache controller handles all scheduling and synchronization automatically.

### Dynamic Backend Loading

Alternatively, you can use dynamic loading to avoid hard-coding your backend in the repository:

```bash Command
python3 -m sglang.launch_server \
  --model-path your-model \
  --enable-hierarchical-cache \
  --hicache-storage-backend dynamic \
  --hicache-storage-backend-extra-config '{"backend_name":"custom_backend_name", "module_path": "your_module_path", "class_name": "YourHiCacheClassName"}'
```

**Configuration Parameters:**
- `--hicache-storage-backend`: Set to `dynamic`
- `--hicache-storage-backend-extra-config`: JSON configuration with:
  - `backend_name`: Custom backend identifier
  - `module_path`: Python module path to your implementation
  - `class_name`: Your HiCache implementation class name
  - `interface_v1`: 0 (disable) or 1 (enable) to control usage of batch_get_v1 and batch_set_v1 methods


## Community and Support

- **GitHub Issues**: Report bugs and feature requests
- **Slack Channel**: Join community discussions in #sgl-kv-cache-store
- **Documentation**: Refer to storage backend-specific guides

***
*This document will be continuously updated based on community feedback and new features. Contributions and suggestions are welcome!*

---

### Docs Advanced Features Hicache Design (`docs/docs/advanced_features/hicache_design.mdx`)

---
title: "HiCache System Design and Optimization"
metatags:
    description: "HiCache architecture: HiRadixTree metadata, L1/L2/L3 workflow, prefetch strategies, write-back policies, zero-copy transfers, multi-rank sync."
---
This document provides a comprehensive overview of SGLang HiCache, covering its system architecture, workflow and key components. It also details configuration parameters, optimization techniques, and integration with various L3 storage backends, serving as a complete reference for users and developers to understand and tune HiCache for efficient LLM inference.

## Why and What is HiCache?

In large language model inference, the prefill phase is often time-consuming: input sequences need to be first converted into Key-Value cache (KV cache) for subsequent decoding. When multiple requests share the same prefix, the KV cache for that prefix is identical. By caching and reusing these shared KV caches, redundant computation can be avoided. To address this, SGLang introduced RadixAttention, which leverages idle GPU memory to cache and reuse prefix KV caches, and **HiCache**, which extends this idea to host memory and distributed storage.

Inspired by the classic three-level cache design of modern CPUs, HiCache organizes GPU memory as L1, host memory as L2, and distributed storage as L3. This hierarchy enables HiCache to fully exploit the "idle" storage space of GPUs and CPUs, while integrating distributed cache systems such as Mooncake, 3FS, NIXL, and AIBrix KVCache for global KV cache storage and scheduling. As a result, HiCache significantly expands KV cache capacity while maintaining strong read performance—especially in workloads such as multi-QA and long-context inference, where KV cache reuse is frequent. For detailed benchmark results, see [this blog](https://lmsys.org/blog/2025-09-10-sglang-hicache/).


## System Design

### Overall Architecture

In many modern CPU architectures, the small but fast L1 and L2 caches are private to each core, enabling rapid access to the hottest data, while the larger L3 cache is shared across all cores to significantly reduce redundancy within the cache. Similarly, in HiCache, the L1 and L2 KV caches are private to each inference instance, whereas the L3 KV cache is shared among all inference instances within the cluster.

### Tier Sharing Scope

Which tier is private and which is shared decides where a cache hit can come from, so it is worth stating explicitly:

| Tier | Medium | Scope | Shared across instances? |
|---|---|---|---|
| **L1** | GPU memory (HBM) | One inference instance | No |
| **L2** | Host memory (CPU DRAM) | One inference instance, on its own node | **No** |
| **L3** | Storage backend (`file`, `mooncake`, `hf3fs`, `nixl`, `aibrix`, or a custom one) | Whatever the backend is configured to span | **Only if the backend is set up for it** |

```mermaid
flowchart TB
    subgraph N0["Node A"]
        subgraph I0["Instance 0"]
            L1A["L1 - GPU memory<br/>private"]
            L2A["L2 - host memory<br/>private to this instance"]
            L1A --- L2A
        end
        subgraph I1["Instance 1"]
            L1B["L1 - GPU memory<br/>private"]
            L2B["L2 - host memory<br/>private to this instance"]
            L1B --- L2B
        end
    end

    subgraph N1["Node B"]
        subgraph I2["Instance 2"]
            L1C["L1 - GPU memory<br/>private"]
            L2C["L2 - host memory<br/>private to this instance"]
            L1C --- L2C
        end
    end

    L3["L3 - storage backend<br/>shared by the instances the backend is configured to span"]

    L2A --> L3
    L2B --> L3
    L2C --> L3
```

**L2 is node-local and instance-private.** It is host memory owned by one inference instance's process, so two instances never read each other's L2, not even two instances on the same node. A KV cache produced by instance 0 becomes visible to instance 1 only after it reaches L3.

This is the answer to a common question: HiCache cannot pool the host memory of several machines into one larger L2. Growing `--hicache-ratio` or `--hicache-size` only makes each instance's own private L2 larger. Cross-instance reuse is the job of L3, so it needs `--hicache-storage-backend`.

L3 is the tier that *can* be shared, but whether it actually is depends on the backend and how it is configured. The `file` backend writes to `/tmp/hicache` by default (`SGLANG_HICACHE_FILE_BACKEND_STORAGE_DIR` overrides it), which is node-local unless that path is a shared mount. Distributed backends such as `mooncake`, `hf3fs`, `nixl` and `aibrix` give cluster-wide scope, but only when every instance is pointed at the same namespace and configuration.

### HiRadixTree: Metadata Organization in HiCache

For KV cache data organization, HiCache builds upon the RadixTree structure introduced in RadixAttention and proposes HiRadixTree. In RadixAttention, each node of the RadixTree corresponds to the KV cache of a consecutive span of tokens in GPU memory. A path from the root to a leaf node represents the prefix of a request, and shared prefixes across multiple requests can reuse the same nodes, thereby avoiding redundant storage.

HiRadixTree extends this idea: each node corresponds to the KV cache of a span of consecutive tokens and records where that KV cache is stored—whether in local GPU memory, CPU memory, L3 storage, or multiple of these tiers. If stored locally, HiRadixTree maintains precise metadata, including the exact storage address. However, to reduce overhead, HiRadixTree does not store or continuously synchronize metadata for L3 KV cache. Instead, when accessing L3 data, it queries the backend in real time to retrieve the necessary metadata, such as whether the data exists and on which server and location it resides.

### Overall Workflow

The workflow of HiCache mainly involves three key operations: **local match**, **prefetch** and **write-back**. When the system receives a new request, it first searches the local L1 and L2 caches for matching KV caches. For parts not found locally, it attempts to prefetch from L3. After prefetching, all required KV caches are loaded into the GPU for computation. Once the prefill computation is complete, the system considers storing the newly generated data into L2 or L3.

<Frame>
  <img src="https://lmsys.org/images/blog/hicache/hicache_overview.png" alt="HiCache Workflow"/>
</Frame>

### Local Match

Local matching is the first step in HiCache's workflow, where incoming request tokens are matched against the HiRadixTree to locate cached KV data in local memory tiers (L1 GPU memory and L2 host memory).

The matching algorithm traverses the HiRadixTree from the root node, following child nodes that match the token sequence prefix. At each node, the incoming token sequence is compared with the node’s stored token sequence. When `page_size > 1`, matching is performed at the page granularity to optimize memory access patterns. If a match terminates within a node’s stored sequence, the node is automatically split to create an exact boundary, improving the efficiency of future matches.

The algorithm returns a continuous prefix of the request, with the first part residing in L1 and the latter part in L2.

Since the process only requires traversing the local HiRadixTree and does not involve any actual data copying, local matching is extremely fast.

### Prefetch from L3

Data prefetching is one of HiCache’s core optimization techniques, designed to proactively load KV caches from L3 storage into local L2 memory, thereby reducing access latency during subsequent operations.

**Prefetch Trigger Conditions**:
After local matching, for the parts not found in L1 or L2, the system queries L3 to retrieve metadata for the next continuous matching KV caches. If the length of hit cache in L3 exceeds a threshold (default: 256 tokens, configurable), a prefetch operation is triggered.

**Prefetch Strategies**: HiCache provides three different prefetch termination strategies to address different scenario needs:
- **best_effort**: Terminates immediately when GPU can execute prefill computation, with no waiting time, suitable for scenarios extremely sensitive to latency.
- **wait_complete**: Must wait for all prefetch operations to complete, suitable for scenarios requiring high cache hit rates.
- **timeout**: Terminates after specified time or when complete, balancing latency and cache hit rate needs.

After prefetching stops, the data already fetched is used together with the local data for the prefill computation.

For **timeout** strategy, HiCache introduces three configuration parameters to support fine-grained control over prefetch timeout conditions:

* `prefetch_timeout_base`: the base timeout, representing overhead unrelated to the number of tokens (e.g., scheduling and synchronization). Default: `2` seconds.
* `prefetch_timeout_per_ki_token`: the incremental timeout per thousand tokens. Default: `0.1` seconds per 1024 tokens.
* `prefetch_timeout_max`: the upper bound applied to the linear timeout, preventing very long prompts from waiting unboundedly. Default: `30` seconds.

The timeout is computed as:

```python Example
timeout = min(
    prefetch_timeout_max,
    prefetch_timeout_base + prefetch_timeout_per_ki_token * num_token_to_fetch / 1024,
)
```

### Data Write-back

The write-back mechanism is responsible for moving frequently accessed KV caches from L1 to L2 and L3, enabling larger and longer-term storage as well as cache sharing across instances.

**Configurable Write-back Policies**: HiCache supports three write-back strategies:

* **write_through**: Every access is immediately written back to the next level. When bandwidth is sufficient, this strategy provides the strongest caching benefit.
* **write_through_selective**: Data is written back only after the access frequency exceeds a threshold. This strategy backs up only hot data, reducing I/O overhead.
* **write_back**: Data is written back to the next level only when it is evicted from the upper level. This strategy alleviates storage pressure and is suitable for scenarios where storage capacity is limited but memory utilization must be maximized.

**Cross-instance Sharing**: When data is written back from L2 to L3, only data not already present in L3 is transferred. KV caches stored in L3 can then be shared across all SGLang instances in the cluster (depending on the L3 backend implementation), significantly improving cache hit rates within the same memory budget.

### Multi-Rank Synchronization

During multi-GPU parallel computation, such as tensor parallelism (TP), HiCache must ensure consistent states across different ranks. Therefore, critical computation steps require the use of `all_reduce` for state synchronization.

For example, during prefetching, `all_reduce(op=min)` is used to ensure that all ranks obtain the same number of L3 hits, preventing inconsistent judgments about whether the prefetch threshold has been reached. Similarly, after prefetching completes or terminates, `all_reduce(op=min)` is again required to guarantee consensus among ranks on the prefix length of the successfully retrieved KV cache.

### Data Transfer Optimization

**Zero-Copy Data Transfers**: Both prefetching and write-back involve substantial data movement. Minimizing the number of data copies can significantly improve system performance. HiCache supports passing memory addresses and sizes directly when transferring data from L2 memory to an L3 backend.

**“Batch-Oriented” Data Organization**: The granularity of data reads and writes has a major impact on performance. To address this, HiCache L3 stores and transfers KV cache data at the granularity of **pages** and supports different data layouts beyond the existing `layer first` scheme, including `page first` and `page first direct`. Under the `page first` and `page first direct` layouts, all KV cache data belonging to the same page is placed in contiguous memory, allowing it to be passed as a single object to L3 using zero-copy transfers.
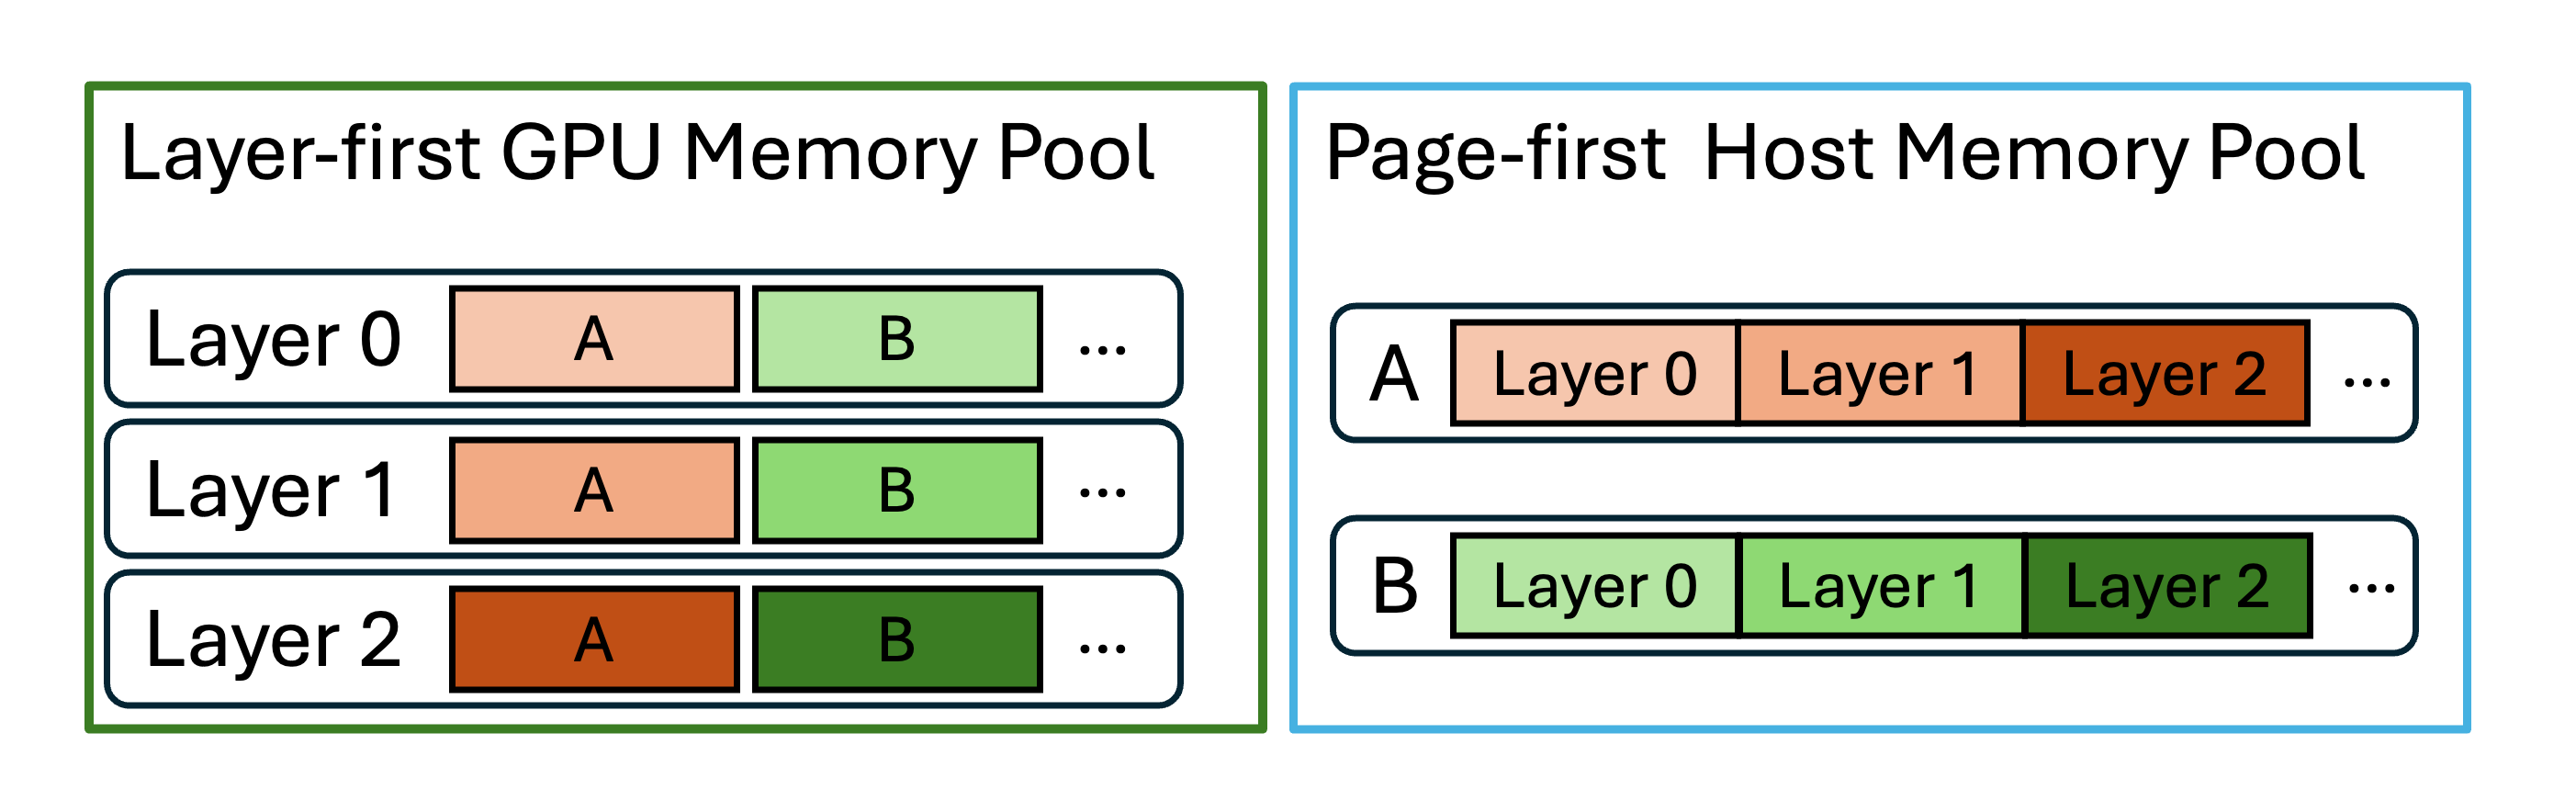
<Frame>
  <img src="https://lmsys.org/images/blog/hicache/hicache_layout.png" alt="HiCache L2 MEM layout"/>
</Frame>

However, because GPU KV computation is naturally performed layer by layer, the GPU inherently operates in a `layer first` layout. When transferring `page first` data from L2 to the GPU, data must be transferred at the granularity of one token per layer. The `page first direct` layout mitigates this issue by grouping together all tokens of a given layer within a page, allowing transfers from L2 to GPU to be aggregated at the page-layer level.

**CPU-to-GPU Transfer Optimizations**: In HiCache, moving data from CPU memory to GPU is as performance-critical as prefetching data from L3 to L2. HiCache employs several optimizations for this process:

* **Compute-Transfer Overlap**: During the prefill phase, when transferring data from CPU to GPU, HiCache overlaps layers by concurrently loading the KV cache of layer N+1 while computing layer N. This effectively hides data transfer latency.
* **GPU-assisted I/O Kernels**: On top of `cudaMemcpyAsync`, HiCache implements a set of GPU-assisted I/O kernels specifically optimized for KV cache transfers between CPU and GPU. Compared to the baseline approach, these kernels achieve up to 3x higher transfer speed.

**Write-back Optimization for MLA**: For MHA (Multi-Head Attention) models under multi-TP, each rank holds `1/tp_size` of a token’s KV data. In contrast, for MLA (Multi-Layer Attention) models, all ranks hold the complete and identical KV data for each token. HiCache includes a dedicated optimization for MLA: only one rank initiates the write-back operation, ensuring that data is not redundantly stored across ranks.

### Integration with PD-Disaggregation Deployment Mode

SGLang supports a PD (Prefill-Decode) disaggregation deployment mode through the Mooncake TransferEngine (for details, see [this doc](./pd_disaggregation)). In the PD-disaggregation deployment mode, HiCache can be enabled on both the prefill nodes and decode nodes to optimize prefill performance. If enabled on decode nodes, the decode output will also be written back to L3.

### Unified Interfaces and Rich L3 Storage Backends

HiCache encapsulates all read, write, and query operations on L3 backends within the `class HiCacheStorage(ABC)`, exposing a set of simple and consistent interfaces. This design supports a wide range of L3 storage backends and allows users to select the one that best fits their specific use cases.

When a backend is attached, HiCache hands it the host memory pools in a fixed order: `register_mem_pool_host` receives the anchor pool first, then every pool of the host pool group (Mamba state, indexer, SWA, draft sidecars, ...) arrives through `register_mem_host_pool_v2`, and `on_host_pools_registered` fires exactly once when this initial burst is over. Pools attached dynamically later still arrive through `register_mem_host_pool_v2` alone. Backends that talk to an external service whose instance specification must be complete up front (e.g. a remote cache manager) should finalize it inside `on_host_pools_registered`; raising there fails the attach.

- **Mooncake**: Mooncake is a high-performance caching system for LLM inference that leverages RDMA and multi-NIC resources to enable zero-copy, ultra-fast data transfers. Try Mooncake [here](https://github.com/sgl-project/sglang/tree/main/python/sglang/srt/mem_cache/storage/mooncake_store).

- **DeepSeek 3FS (HF3FS)**: HF3FS is a Kubernetes-native distributed storage solution with operator-based deployment. Try HF3FS [here](https://github.com/sgl-project/sglang/tree/main/python/sglang/srt/mem_cache/storage/hf3fs).

- **NIXL**: NIXL provides a unified API for accessing various storage plugins, including but not limited to DeepSeek's 3FS, GPU Direct Storage (GDS) and Amazon S3-compatible object storage. Try NIXL [here](https://github.com/sgl-project/sglang/tree/main/python/sglang/srt/mem_cache/storage/nixl).

- **AIBrix KVCache**: AIBrix KVCache is a production-ready KVCache Offloading Framework, which enables efficient memory tiering and low-overhead cross-engine reuse. Try AIBrix KVCache [here](https://github.com/sgl-project/sglang/tree/main/python/sglang/srt/mem_cache/storage/aibrix_kvcache).

- **HiCacheFile**: A simple file-based storage backend for demonstration purposes.

Specifically, **LMCache**, an efficient KV cache layer for enterprise-scale LLM inference, provides an alternative solution to HiCache. Try LMCache [here](https://github.com/sgl-project/sglang/tree/main/python/sglang/srt/mem_cache/storage/lmcache).

## Related Parameters

- **`--enable-hierarchical-cache`**: Enable hierarchical cache functionality. This is required to use HiCache.

- **`--hicache-ratio HICACHE_RATIO`**: The ratio of the size of host KV cache memory pool to the size of device pool. For example, a value of 2 means the host memory pool is twice as large as the device memory pool. The value of this parameter must be greater than 1, as the current implementation requires the host memory allocated for the KV cache to be larger than the device memory allocated for the KV cache.

- **`--hicache-size HICACHE_SIZE`**: The size of host KV cache memory pool in gigabytes. This parameter overrides `hicache-ratio` if set. For example, `--hicache-size 30` allocates 30GB (1GB = 1e9 bytes) for the host memory pool **for each rank**. If there are 8 ranks, then the total memory size is 240GB. Just like `hicache-ratio`, the value of this parameter must be larger than the size of device memory allocated for KV cache.

**Note**: `--hicache-ratio` and `--hicache-size` are two critical parameters. In general, a larger HiCache size leads to a higher cache hit rate, which improves prefill performance. However, the relationship between cache size and hit rate is not linear. Once most reusable KV data—especially hot tokens—are already cached, further increasing the size may yield only marginal performance gains. Users can set these parameters based on their workload characteristics and performance requirements.

- **`--page-size PAGE_SIZE`**: The number of tokens per page. This parameter determines the granularity of KV cache storage and retrieval. Larger page sizes reduce metadata overhead and improve I/O efficiency for storage backends, but may lower the cache hit rate when only part of a page matches the stored KV cache. For workloads with long common prefixes, larger pages can improve performance, while workloads with more diverse prefixes may benefit from smaller pages. See [Data Transfer Optimization](#data-transfer-optimization) for how page granularity affects I/O performance.

- **`--hicache-storage-prefetch-policy {best_effort,wait_complete,timeout}`**: Controls when prefetching from storage should stop. See [Prefetch from L3](#prefetch-from-l3) for details.
  - `best_effort`: Prefetch as much as possible without blocking
  - `wait_complete`: Wait for prefetch to complete before proceeding
  - `timeout`: Terminates after specified time or when complete (Recommended for production environments, as setting an appropriate timeout helps the system meet required SLOs)

- **`--hicache-write-policy {write_back,write_through,write_through_selective}`**: Controls how data is written from faster to slower memory tiers. See [Data Write-back](#data-write-back) for details.
  - `write_through`: Immediately writes data to all tiers (strongest caching benefits)
  - `write_through_selective`: Uses hit-count tracking to back up only frequently accessed data
  - `write_back`: Writes data back to slower tiers only when eviction is needed (reduces I/O load)

- **`--hicache-io-backend {direct,kernel}`**: Choose the I/O backend for KV cache transfer between CPU and GPU. See [Data Transfer Optimization](#data-transfer-optimization) for details.
  - `direct`: Standard CUDA memory copy operations
  - `kernel`: GPU-assisted I/O kernels (recommended for better performance)

- **`--hicache-mem-layout {layer_first,page_first,page_first_direct}`**: Memory layout for the host memory pool. See [Data Transfer Optimization](#data-transfer-optimization) for details.
  - `layer_first`: Compatible with GPU computation kernels (default for GPU memory)
  - `page_first`: Optimized for I/O efficiency
  - `page_first_direct`: Groups all tokens of a given layer within a page, allowing transfers from L2 to GPU to be aggregated at the page-layer level

- **`--hicache-storage-backend {file,mooncake,hf3fs,nixl,aibrix,dynamic}`**: Choose the storage backend for the L3 tier. Built-in backends: file, mooncake, hf3fs, nixl, aibrix. For dynamic backend, use --hicache-storage-backend-extra-config to specify: `backend_name` (custom name), `module_path` (Python module path), `class_name` (backend class name). See [Unified Interfaces and Rich L3 Storage Backends](#unified-interfaces-and-rich-l3-storage-backends) for available backends.

- **`--enable-lmcache`**: Using LMCache as an alternative hierarchical cache solution.

- **`--lmcache-config-file`**: Path to the LMCache YAML configuration file.

- **`--hicache-storage-backend-extra-config HICACHE_STORAGE_BACKEND_EXTRA_CONFIG`**: the extra config can be either
  - a JSON string containing extra configuration for the storage backend, e.g., `--hicache-storage-backend-extra-config '{"prefetch_threshold":512, "prefetch_timeout_base": 0.5, "prefetch_timeout_per_ki_token": 0.25}' `, or
  - a TOML or JSON or YAML file specifying the extra configuration for the storage backend (to differentiate from the JSON string input, prepend a `@` in front of the file name), e.g., `--hicache-storage-backend-extra-config "@config.toml"` where `config.toml` is the config file containing the complex configurations. This can be useful when the configuration consists of many or complex key-value pairs (for instance, it is preferred to use a config file for NIXL backend as its configurations can be complex).

---

### Docs Advanced Features Hicache Storage Runtime Attach Detach (`docs/docs/advanced_features/hicache_storage_runtime_attach_detach.mdx`)

---
title: "Runtime Attach/Detach HiCache Storage Backend (No Restart)"
metatags:
    description: "Dynamically attach/detach HiCache L3 storage backends at runtime via HTTP API. No restart required, idle-state safety checks."
---
This document explains how to **dynamically attach/detach the HiCache L3 storage backend at runtime** (e.g., `mooncake` / `hf3fs` / `nixl` / `file` / `aibrix` / `eic`) while **SGLang is already running and serving traffic**, without restarting the process.

For safety and consistency, the current implementation **strictly requires** these operations to happen only when the service is **idle**:

- **No running requests**
- **No waiting/queued requests**

If the idle condition is not met, the API will fail fast (HTTP 400) and **will not modify** the current service state.

***
## 1. Background and implementation overview

### 1.1 Architecture / control path

The control path is:

1. **HTTP Server** (`python/sglang/srt/entrypoints/http_server.py`)
   - Exposes `PUT /hicache/storage-backend`, `DELETE /hicache/storage-backend`, `GET /hicache/storage-backend`
2. **TokenizerManager** (`python/sglang/srt/managers/tokenizer_control_mixin.py`)
   - Sends the request to the Scheduler via `FanOutCommunicator`
3. **Scheduler** (`python/sglang/srt/managers/scheduler.py`)
   - Performs a **strict idle check**
   - Calls `tree_cache.attach_storage_backend(...)` / `detach_storage_backend(...)`
4. **UnifiedRadixCache** (`python/sglang/srt/mem_cache/unified_radix_cache.py`)
   - Parses `hicache_storage_backend_extra_config_json` (supports both backend config and prefetch knobs)
   - Calls `cache_controller.attach_storage_backend(...)` / `detach_storage_backend(...)`
5. **HiCacheController** (`python/sglang/srt/managers/cache_controller.py`)
   - Creates/destroys the storage backend instance (via `StorageBackendFactory`)
   - Starts/stops backend background threads at runtime (prefetch/backup)

***
## 2. Idle-state requirement (strict)

The Scheduler uses `is_fully_idle()` which checks:

- No running batches (including chunked prefill, overlap, pipeline-parallel, and disaggregation paths)
- No waiting requests in any queue (waiting, grammar, disagg bootstrap/prealloc/transfer/inflight)
- No DLLM staging requests

If the condition is not met, attach/detach returns an error like:

- `Reject attach: scheduler is not idle. #queue-req=... #running-req=...`

<Tip>
before switching, drain upstream traffic and wait for the server to become idle, then call attach/detach.
</Tip>

### 2.1 DP (data parallel) semantics

When `dp_size > 1`, the tokenizer dispatches the request to **all DP scheduler instances** and aggregates their responses:

- The final `success` is **true only if all DP ranks return success**
- The final `message` concatenates messages from all DP ranks

This is intended to prevent “silent partial success”, but it also means you may see:

- Overall **failure** even though **some ranks already succeeded**

Currently there is **no automatic partial rollback** across DP ranks (see TODO in code). Operationally:

- Prefer to keep backend config identical across ranks
- If attach fails, immediately call detach (best-effort/idempotent), fix config, then retry attach

***
## 3. How to use (HTTP Admin API)

The examples below assume your SGLang HTTP server is at `http://127.0.0.1:30000`.

### 3.1 Query current storage backend status

```bash Command
curl -s http://127.0.0.1:30000/hicache/storage-backend
```

Example response:

```json Config
{
  "hicache_storage_backend": "mooncake",
  "hicache_storage_backend_extra_config": "{\"master_server_address\":\"127.0.0.1:50051\", ...}"
}
```

### 3.2 Attach (enable) a storage backend
```bash Command
curl -s -X PUT http://127.0.0.1:30000/hicache/storage-backend \
  -H 'Content-Type: application/json' \
  -d '{
    "hicache_storage_backend": "mooncake"
  }'
```

```bash Command
curl -s -X PUT http://127.0.0.1:30000/hicache/storage-backend \
  -H 'Content-Type: application/json' \
  -d '{
    "hicache_storage_backend": "mooncake",
    "hicache_storage_backend_extra_config_json": "{\"master_server_address\":\"127.0.0.1:50051\",\"protocol\":\"tcp\",\"global_segment_size\":\"4gb\",\"prefetch_threshold\":256}",
    "hicache_storage_prefetch_policy": "timeout"
  }'
```

Notes:

- `hicache_storage_backend_extra_config_json` can include both:
  - **Backend configuration** (e.g., Mooncake master/metadata/protocol, etc.)
  - **Prefetch configuration** (`prefetch_threshold`, `prefetch_timeout_base`, `prefetch_timeout_per_ki_token`, `prefetch_timeout_max`, `hicache_storage_pass_prefix_keys`)

### 3.3 Detach (disable) the storage backend

```bash Command
curl -s -X DELETE http://127.0.0.1:30000/hicache/storage-backend
```

Notes:

- Detach only makes SGLang **stop using** the L3 storage backend and stops prefetch/backup threads
- It **does not automatically delete** data stored in Mooncake/HF3FS (or other remote backends)

***
## 4. Behavior and caveats

- **No restart required**: attach/detach switches in-process at runtime
- **Must be idle**: otherwise the request is rejected to avoid consistency issues
- **Host KV layout constraints still apply**: for example, Mooncake still requires layouts like `page_first/page_first_direct/page_head`; if the server's HiCache host-memory layout does not satisfy the backend requirements, attach will fail with an error
- **Observability**:
  - After attach, `server_args.hicache_storage_backend*` is updated on both the tokenizer and scheduler sides
  - If metrics are enabled, attach will create a storage metrics collector in `UnifiedRadixCache` on demand

---

### Docs Advanced Features Hisparse Guide (`docs/docs/advanced_features/hisparse_guide.mdx`)

---
title: "HiSparse: Hierarchical Sparse Attention"
metatags:
    description: "Use HiSparse hierarchical sparse attention to reduce decode GPU KV memory with CPU pinned host storage and PD disaggregation."
---

HiSparse reduces per-request GPU memory consumption during the decode phase by maintaining only a small "hot" KV buffer on GPU while keeping complete KV data in CPU pinned memory. Combined with PD disaggregation, it enables significantly higher decode concurrency.

> **Prerequisites**: HiSparse works with models that use **DeepSeek Sparse Attention (DSA)** architectures (e.g., DeepSeek-V3.2, GLM-5.1), **DeepSeek V4**, and **MiniMax M3**. These models natively select a subset of tokens for attention, making it possible to keep only the top-k KV on GPU while storing the full KV in host memory — without accuracy loss. Additionally, HiSparse currently requires **PD disaggregation mode** and is enabled on the **decode instance** only.

## Why HiSparse?

In long-context LLM inference, each decoding request holds a full-length KV cache on GPU, limiting the number of concurrent requests a decode instance can serve. HiSparse addresses this by:

- **Reducing GPU memory per request**: Each request occupies only a fixed-size device buffer (e.g., 4KB tokens) instead of the full sequence length.
- **On-demand swap-in**: A CUDA kernel dynamically loads the top-k most relevant KV entries from host memory based on attention scores.
- **Transparent to prefill**: HiSparse is entirely a decode-side optimization; the prefill instance requires no changes.

## Design Overview

### Decode Workflow

Each decode step follows this flow:

1. **Forward decode** — generate the next token
2. **Top-k selection** — select the most relevant token positions via attention scores
3. **Swap-in** — the CUDA kernel loads top-k KV entries from host to device buffer:
   - *Short sequences* (`seq_len ≤ device_buffer_size`): fast path, all KV already in buffer
   - *Long sequences*: hit detection → LRU reordering → miss handling (host → device copy)
4. **Decode attention** — compute attention using the top-k device locations
5. **Eager backup** — asynchronously copy the previous token's KV from device to host

### PD Disaggregation Integration (Direct-to-Host)

In PD disaggregation mode, the prefill instance transfers KV cache directly into the decode instance's host pool via RDMA, bypassing the GPU entirely on the decode side. This eliminates the transient GPU memory spike during KV transfer and removes the staging DMA step.

```
Prefill GPU  ──RDMA──▶  Decode Host Pool (CPU pinned memory)
                              │
                              ▼
                     alloc device buffer (4KB)
                              │
                              ▼
                     swap-in kernel (on-demand top-k)
```

For DeepSeek V4, the direct-to-host path writes only C4 KV into the decode host pool. The c4_indexer and C128 KV remain device-to-device transfers.

## Server Arguments

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
  </colgroup>
  <thead>
    <tr>
      <th>Argument</th>
      <th>Type / Default</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>--enable-hisparse</code></td>
      <td>flag; default: disabled</td>
      <td>Enable HiSparse on the decode instance</td>
    </tr>
    <tr>
      <td><code>--hisparse-config</code></td>
      <td>JSON string</td>
      <td>Configuration for HiSparse (see below)</td>
    </tr>
  </tbody>
</table>

### HiSparse Config Parameters

Pass as a JSON string via `--hisparse-config`:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
  </colgroup>
  <thead>
    <tr>
      <th>Parameter</th>
      <th>Type / Default</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>top_k</code></td>
      <td>int</td>
      <td>Number of topk entries</td>
    </tr>
    <tr>
      <td><code>device_buffer_size</code></td>
      <td>int</td>
      <td>Number of token slots in the per-request GPU device buffer</td>
    </tr>
    <tr>
      <td><code>host_to_device_ratio</code></td>
      <td>int</td>
      <td>Ratio of logical pool size to device pool size, determining host memory capacity</td>
    </tr>
    <tr>
      <td><code>swap_in_block_size</code></td>
      <td>int / 960</td>
      <td>CUDA thread-block size for the HiSparse swap-in kernel</td>
    </tr>
  </tbody>
</table>

Example: `--hisparse-config='{"top_k": 2048, "device_buffer_size": 6144, "host_to_device_ratio": 10, "swap_in_block_size": 960}'`

### Shared-index prefetch (automatic)

When a model reuses one anchor layer's top-k selection across a run of subsequent "skip" layers (DSA `index_topk_freq` / `index_topk_pattern`; native in GLM-5.2 as IndexShare), the working set of every skip layer is known the moment the anchor's index is computed. HiSparse exploits this automatically: the anchor's swap-in kernel records its miss plan (which host slots go to which device-buffer slots), and each skip layer replays that plan with a copy-only kernel issued ahead on a side stream, so the skip layers' host→device IO overlaps the intervening layers' compute instead of sitting on the decode critical path. The replay kernel uses a small fixed grid to keep its SM footprint low while overlapped.

The prefetch is enabled automatically for eligible models (no pipeline parallelism, no speculative decoding) and can be turned off for A/B comparison with `SGLANG_DISABLE_HISPARSE_PREFETCH=1`.

## Deployment

HiSparse currently requires **PD disaggregation mode** and is enabled only on the **decode instance**.

### Prefill Instance

```bash Command
python3 -m sglang.launch_server \
    --model-path /path/to/model \
    --trust-remote-code \
    --port 8000 --host 0.0.0.0 \
    --context-length 81920 \
    --chunked-prefill-size 65536 \
    --tp-size 8 --attn-dp-size 8 \
    --mem-fraction-static 0.85 \
    --disaggregation-mode prefill \
    --disaggregation-ib-device mlx5_0,mlx5_1,mlx5_2,mlx5_3 \
    --nnodes 1 --node-rank 0
```

### Decode Instance (with HiSparse)

```bash Command
python3 -m sglang.launch_server \
    --model-path /path/to/model \
    --trust-remote-code \
    --port 8000 --host 0.0.0.0 \
    --context-length 81920 \
    --tp-size 8 --attn-dp-size 8 \
    --mem-fraction-static 0.85 \
    --disable-radix-cache \
    --disaggregation-mode decode \
    --disaggregation-ib-device mlx5_0,mlx5_1,mlx5_2,mlx5_3 \
    --dist-init-addr 127.0.0.1:5757 \
    --nnodes 1 --node-rank 0 \
    --enable-hisparse \
    --hisparse-config='{"top_k": 2048, "device_buffer_size": 6144, "host_to_device_ratio": 10, "swap_in_block_size": 960}'
```

> **Note**: For DSA models, `--kv-cache-dtype` defaults to `auto`, which resolves to `fp8_e4m3` on SM100+ (Blackwell) and `bfloat16` on older architectures. The DSA decode backend is automatically selected based on KV dtype (`bfloat16` → `flashmla_sparse`, `fp8_e4m3` → `flashmla_kv`), except for GLM DSA models on SM120/SM121 with `fp8_e4m3`, which use `flashinfer_sparse_mla`. DSA backend flags apply only to DSA models; DeepSeek V4 uses its own `dsv4` attention backend.

### MiniMax M3

Dense-layer K/V and index K stay on GPU; sparse-layer K/V use host memory plus a GPU working set.

- Use TP 4 or greater, with the same TP size and PP 1 on both PD instances.
- Use `--attention-backend triton`, `--mm-attention-backend triton_attn`, `--disable-prefill-cuda-graph`, and `--disable-radix-cache`.
- Set `device_buffer_size` to at least 2048 in `--hisparse-config`; `top_k` does not override the model's selection width.
- PD retraction backup is not supported. Use `--num-reserved-decode-tokens` to reserve capacity for the expected output length.

### Benchmark

```bash Command
python3 -m sglang.bench_serving \
    --backend sglang \
    --dataset-path /path/to/ShareGPT_V3_unfiltered_cleaned_split.json \
    --dataset-name random \
    --random-input 40000 \
    --random-output 20000 \
    --num-prompts 200 \
    --max-concurrency 200 \
    --request-rate 40 \
    --random-range-ratio 1.0 \
    --host 127.0.0.1 \
    --port 20000 \
    --model /path/to/model \
    --flush-cache \
```

### Key Notes

- The prefill instance does not need `--enable-hisparse`; it is unaware of HiSparse.
- On the decode instance, `--enable-hisparse` and `--hisparse-config` are required for HiSparse.
- For DSA models, `--kv-cache-dtype bfloat16` uses `flashmla_sparse`, and `--kv-cache-dtype fp8_e4m3` uses `flashmla_kv`.
- On SM120/SM121 (e.g. RTX PRO 6000, RTX 5090) with GLM DSA models and `--kv-cache-dtype fp8_e4m3`, both DSA backends resolve to `flashinfer_sparse_mla`, which is the only DSA kernel available on that architecture. HiSparse accepts it there; no extra flag is needed.
- For DeepSeek V4, DSA backend flags are not applicable. DeepSeek V4 uses the `dsv4` attention backend and `fp8_e4m3` KV cache by default.
- `host_to_device_ratio` should be configured based on the host machine's available memory. For example:
  - **~1 TB** host memory → `host_to_device_ratio: 5`
  - **~2 TB** host memory → `host_to_device_ratio: 10`

## Acknowledgments

We would like to thank the SGLang team and community for the implementation and generous support, especially Zhiqiang Xie, Zhangheng Huang, Tingwei Huang, Shangming Cai, Teng Ma, and many others. We also thank the Alibaba Cloud TairKVCache team and the AntGroup SCT Inference team for their valuable contributions.

---

### Docs Advanced Features Hyperparameter Tuning (`docs/docs/advanced_features/hyperparameter_tuning.mdx`)

---
title: "Hyperparameter Tuning"
metatags:
    description: "SGLang performance tuning: batch size, token usage, mem-fraction-static, chunked-prefill-size, CUDA graph, DP/TP optimization."
---
## Achieving high throughput for offline batch inference

Achieving a large batch size is the most important thing for attaining high throughput in offline batch inference.
When the server is running at full load in a steady state, look for the following in the log:

```text Output
Decode batch. #running-req: 233, #token: 370959, token usage: 0.82, cuda graph: True, gen throughput (token/s): 4594.01, #queue-req: 317
```

### Adjust the request submission speed to control `#queue-req`

`#queue-req` indicates the number of requests in the queue.
If you frequently see `#queue-req: 0`, it suggests that your client code is submitting requests too slowly.
A healthy range for `#queue-req` is `100 - 2000`.
However, avoid making `#queue-req` too large, as this will increase the scheduling overhead on the server.

### Achieve a high `token usage`

`token usage` indicates the KV cache memory utilization of the server. `token usage > 0.9` means good utilization.

If you frequently see `token usage < 0.9` and `#queue-req > 0`, it means the server is too conservative about taking in new requests. You can decrease `--schedule-conservativeness` to a value like 0.3.
The case of a server being too conservative can happen when users send many requests with a large `max_new_tokens` but the requests stop very early due to EOS or stop strings.

On the other hand, if you see `token usage` very high and you frequently see warnings like
`KV cache pool is full. Retract requests. #retracted_reqs: 1, #new_token_ratio: 0.9998 -> 1.0000`, you can increase `--schedule-conservativeness` to a value like 1.3.
If you see `KV cache pool is full. Retract requests.` occasionally but not frequently (~1 time per minute), it is okay.

### Tune `--mem-fraction-static` to increase KV cache pool capacity
SGLang allocates memory as follows:

Total memory usage = model weights + KV cache pool + CUDA graph buffers + activations

The `--mem-fraction-static` parameter determines how much memory is allocated to the first two components:

mem_fraction_static = (model weights + KV cache pool) / GPU memory capacity

To support higher concurrency, you should maximize the KV cache pool capacity by setting `--mem-fraction-static` as high as possible while still reserving enough memory for activations and CUDA graph buffers.

SGLang uses simple heuristics to set the default value of `--mem-fraction-static`, but you can optimize it for your use cases.
As a rule of thumb, reserving 5–8 GB of memory for activations is typically sufficient. You can check this by inspecting the logs just before the server is ready.
Look for log entries like this:

```text Output
[2025-08-11 17:17:03] max_total_num_tokens=665690, chunked_prefill_size=8192, max_prefill_tokens=16384, max_running_requests=4096, context_len=65536, available_gpu_mem=13.50 GB
```

Check the `available_gpu_mem` value.
- If it is between 5–8 GB, the setting is good.
- If it is too high (e.g., 10 - 20 GB), increase `--mem-fraction-static` to allocate more memory to the KV cache.
- If it is too low, you risk out-of-memory (OOM) errors later, so decrease `--mem-fraction-static`.

Another straightforward approach is to increase `--mem-fraction-static` in increments of 0.01 until you encounter OOM errors for your workloads.

### Avoid out-of-memory errors by tuning `--chunked-prefill-size`, `--mem-fraction-static`, and `--max-running-requests`

If you encounter out-of-memory (OOM) errors, you can adjust the following parameters:

- If OOM occurs during prefill, try reducing `--chunked-prefill-size` to `4096` or `2048`. This saves memory but slows down the prefill speed for long prompts.
- If OOM occurs during decoding, try lowering `--max-running-requests`.
- You can also reduce `--mem-fraction-static` to a smaller value, such as 0.8 or 0.7. This decreases the memory usage of the KV cache memory pool and helps prevent OOM errors during both prefill and decoding. However, it limits maximum concurrency and reduces peak throughput.

### Tune `--cuda-graph-max-bs-decode`
By default, CUDA graph is enabled only for small batch sizes (e.g., less than 160 or 256).
However, for some models, especially at large tensor parallelism sizes, CUDA graph can be useful for batch sizes up to 512 or 768.
Therefore, it may be beneficial to increase `--cuda-graph-max-bs-decode` to a larger value.
Note that CUDA graph consumes more memory, so you may need to reduce `--mem-fraction-static` at the same time.

### Tune `--dp-size` and `--tp-size`

Data parallelism is better for throughput. When there is enough GPU memory, always favor data parallelism for throughput. Refer to [SGLang Model Gateway (former Router)](../advanced_features/sgl_model_gateway) for a better data parallelism rather than using `dp_size` parameter.

### Try other options

- `torch.compile` accelerates small models on small batch sizes. You can enable it with `--enable-torch-compile`.
- Try other quantization (e.g. FP8 quantization with `--quantization fp8`)
- Try other parallelism strategies (e.g. [expert parallelism](https://lmsys.org/blog/2025-05-05-large-scale-ep/)) or DP attention for deepseek models (with `--attn-dp-size 8`).
- If the workload has many shared prefixes, try `--schedule-policy lpm`. Here, `lpm` stands for longest prefix match. It reorders requests to encourage more cache hits but introduces more scheduling overhead.

---

### Docs Advanced Features Llm D (`docs/docs/advanced_features/llm-d.mdx`)

---
title: "llm-d"
metatags:
    description: "Run SGLang at fleet scale with llm-d: prefix-aware routing, distributed KV-cache management, prefill/decode disaggregation, SLO-aware autoscaling on Kubernetes."
---

[llm-d](https://llm-d.ai/) is a Kubernetes-native distributed inference framework for serving large language models at scale across a fleet of inference servers. SGLang is a supported inference engine in llm-d: llm-d coordinates a fleet of SGLang instances across a cluster so that performance holds up under real production traffic, achieving the fastest "time to state-of-the-art (SOTA) performance" for key OSS models across most hardware accelerators.

llm-d is a [CNCF Sandbox project](https://www.cncf.io/blog/2026/03/24/welcome-llm-d-to-the-cncf-evolving-kubernetes-into-sota-ai-infrastructure/) founded by Red Hat, Google Cloud, IBM Research, CoreWeave, and NVIDIA.

## What llm-d adds to an SGLang deployment

A single SGLang server is fast, and RadixAttention already maximizes cache reuse within each replica. But at scale the picture changes: across many replicas, cache locality breaks under round-robin load balancing as related requests scatter and radix-cache hit rates collapse, long prompts inflate time-to-first-token, and accelerators sit underused. llm-d adds the cluster-level layer that the engine does not aim to provide on its own:

- **[Prefix-aware routing](https://llm-d.ai/docs/guides/precise-prefix-cache-aware).** Instead of round-robin, the llm-d Router scores each replica on prefix-cache locality and current load, routing each request to the replica most likely to already hold its prefix — raising RadixAttention hit rates on multi-turn and shared-prefix workloads while avoiding saturated servers.
- **[Distributed KV-cache management](https://llm-d.ai/docs/guides#advanced-kv-cache-management).** A global index tracks which token blocks live on which replica, and tiered offloading spills cache to CPU memory or local SSD, extending the working set beyond accelerator HBM.
- **[Prefill/decode disaggregation](https://llm-d.ai/docs/guides/pd-disaggregation).** Prompt processing and token generation run on separate workers, with KV-cache moved over high-speed interconnects, lowering TTFT and steadying per-token latency on long prompts.
- **[SLO-aware autoscaling](https://llm-d.ai/docs/guides/workload-autoscaling) and [flow control](https://llm-d.ai/docs/guides/flow-control).** Scale SGLang pools on real inference signals (queue depth, true demand) rather than raw GPU utilization, with multi-tenant fairness and priority dispatch.
- **One control plane for mixed fleets.** llm-d schedules across engines, so platform teams can serve SGLang and vLLM pools behind the same gateway, policies, and observability instead of running parallel stacks.

These capabilities are composable. Most teams start by adding prefix-aware routing over an existing SGLang pool, then layer in the rest as specific bottlenecks appear.

## Kubernetes-native gateway

llm-d builds on the Gateway API Inference Extension, so SGLang pools are managed through standard Kubernetes resources (Gateway, HTTPRoute, InferencePool) and work with supported gateway providers such as Istio, GKE Inference Gateway, and agentgateway, rather than a bespoke routing tier.

## Performance

llm-d publishes reproducible benchmarks from production-scale deployments on [Prism](https://prism.llm-d.ai/). One representative result: prefix-aware routing delivered **3x higher output throughput and 2x faster TTFT** than round-robin load balancing (Llama 3.1 70B). The mechanism carries over directly to SGLang, where RadixAttention makes the cluster-level cache hit rate a function of routing.

## Get started

- **Deploy the optimized baseline with the [Quickstart](https://llm-d.ai/docs/getting-started/quickstart), selecting SGLang as the inference server.** It stands up an intelligent router (the llm-d Router) over an SGLang pool on Kubernetes in a tested configuration.
- Browse the [well-lit path guides](https://llm-d.ai/docs/guides), each a tested recipe for one of the capabilities above, and add the optimization that fits your workload.
- Read the [Introduction](https://llm-d.ai/docs/getting-started) and [Architecture overview](https://llm-d.ai/docs/architecture) to see how the scheduler, gateway, and model servers wrap your SGLang deployment.

Questions and contributions are welcome on [GitHub](https://github.com/llm-d/llm-d) and [Slack](https://llm-d.ai/slack).

## Current scope

SGLang is supported across the well-lit paths — including intelligent inference scheduling, precise prefix-cache routing (SGLang publishes KV-cache events that the llm-d Router subscribes to), tiered KV-cache management, prefill/decode disaggregation, flow control, and autoscaling. The one current exception is Multi-Node Wide Expert Parallelism, which is vLLM-specific today. See the llm-d documentation for the latest per-engine support status.

---

### Docs Advanced Features Lora (`docs/docs/advanced_features/lora.mdx`)

---
title: "LoRA Serving"
metatags:
    description: "SGLang multi-LoRA serving: S-LoRA and Punica techniques, DP attention, dynamic adapter loading, GPU pinning, overlap loading, Triton and CSGMV backends."
---
SGLang enables the use of [LoRA adapters](https://arxiv.org/abs/2106.09685) with a base model. By incorporating techniques from [S-LoRA](https://arxiv.org/pdf/2311.03285) and [Punica](https://arxiv.org/pdf/2310.18547), SGLang can efficiently support multiple LoRA adapters for different sequences within a single batch of inputs.


## Arguments for LoRA Serving


The following server arguments are relevant for multi-LoRA serving:

* `enable_lora`: Enable LoRA support for the model. This argument is automatically set to True if `--lora-paths` is provided for backward compatibility.

* `enable_lora_overlap_loading`: Enable asynchronous LoRA weight loading in order to overlap H2D transfers with GPU compute. This should be enabled if you find that your LoRA workloads are bottlenecked by adapter weight loading, for example when frequently loading large LoRA adapters.

* `lora_paths`: The list of LoRA adapters to load. Each adapter must be specified in one of the following formats: &lt;PATH&gt; | &lt;NAME&gt;=&lt;PATH&gt; | JSON with schema &#123;"lora_name":str,"lora_path":str,"pinned":bool&#125;.

* `max_loras_per_batch`: Maximum number of adaptors used by each batch. This argument can affect the amount of GPU memory reserved for multi-LoRA serving, so it should be set to a smaller value when memory is scarce. Defaults to be 8.

* `max_loaded_loras`: If specified, it limits the maximum number of LoRA adapters loaded in CPU memory at a time. The value must be greater than or equal to `max-loras-per-batch`.

* `lora_eviction_policy`: LoRA adapter eviction policy when GPU memory pool is full. `lru`: Least Recently Used (default, better cache efficiency). `fifo`: First-In-First-Out.

* `lora_backend`: The backend of running GEMM kernels for Lora modules. Currently we support Triton LoRA backend (`triton`) and Chunked SGMV backend (`csgmv`). In the future, faster backend built upon Cutlass or Cuda kernels will be added.

* `max_lora_rank`: The maximum LoRA rank that should be supported. If not specified, it will be automatically inferred from the adapters provided in `--lora-paths`. This argument is needed when you expect to dynamically load adapters of larger LoRA rank after server startup.

* `lora_target_modules`: The union set of all target modules where LoRA should be applied (e.g., `q_proj`, `k_proj`, `gate_proj`). If not specified, it will be automatically inferred from the adapters provided in `--lora-paths`. This argument is needed when you expect to dynamically load adapters of different target modules after server startup. You can also set it to `all` to enable LoRA for all supported modules. However, enabling LoRA on additional modules introduces a minor performance overhead. If your application is performance-sensitive, we recommend only specifying the modules for which you plan to load adapters.

* `max_lora_chunk_size`: Maximum chunk size for the ChunkedSGMV LoRA backend. Only used when --lora-backend is 'csgmv'. Choosing a larger value might improve performance. Please tune this value based on your hardware and workload as needed. Defaults to 16.

* `lora_drain_wait_threshold`: When any LoRA adapter request waits longer than this threshold (in seconds), the scheduler will selectively drain one running adapter to make room. This mitigates extreme tail latency under high or skewed workloads by preventing a small set of adapters from monopolizing batch slots. Set to 0 to disable draining (default).

* `tp_size`: LoRA serving along with Tensor Parallelism is supported by SGLang. `tp_size` controls the number of GPUs for tensor parallelism. More details on the tensor sharding strategy can be found in [S-Lora](https://arxiv.org/pdf/2311.03285) paper.

From client side, the user needs to provide a list of strings as input batch, and a list of adaptor names that each input sequence corresponds to.


## Usage

### Serving Single Adaptor


**Note:** SGLang supports LoRA adapters through two APIs:

1. **OpenAI-Compatible API** (`/v1/chat/completions`, `/v1/completions`): Use the `model:adapter-name` syntax. See [OpenAI API with LoRA](../basic_usage/openai_api_completions#using-lora-adapters) for examples.

2. **Native API** (`/generate`): Pass `lora_path` in the request body (shown below).


```python Example
import json
import requests

from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, terminate_process
```


```python Example
server_process, port = launch_server_cmd(
    # Here we set max-loras-per-batch to 2: one slot for adaptor and another one for base model
    """
python3 -m sglang.launch_server --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --enable-lora \
    --lora-paths lora0=algoprog/fact-generation-llama-3.1-8b-instruct-lora \
    --max-loras-per-batch 2 \
    --log-level warning \
"""
)

wait_for_server(f"http://localhost:{port}")
```


```python Example
url = f"http://127.0.0.1:{port}"
json_data = {
    "text": [
        "List 3 countries and their capitals.",
        "List 3 countries and their capitals.",
    ],
    "sampling_params": {"max_new_tokens": 32, "temperature": 0},
    # The first input uses lora0, and the second input uses the base model
    "lora_path": ["lora0", None],
}
response = requests.post(
    url + "/generate",
    json=json_data,
)
print(f"Output 0: {response.json()[0]['text']}")
print(f"Output 1: {response.json()[1]['text']}")
```


```python Example
terminate_process(server_process)
```

### Serving Multiple Adaptors


```python Example
server_process, port = launch_server_cmd(
    """
python3 -m sglang.launch_server --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --enable-lora \
    --lora-paths lora0=algoprog/fact-generation-llama-3.1-8b-instruct-lora \
    lora1=Nutanix/Meta-Llama-3.1-8B-Instruct_SFT_lora_4_alpha_16_humaneval_raw_json \
    --max-loras-per-batch 2 \
    --log-level warning \
"""
)

wait_for_server(f"http://localhost:{port}")
```


```python Example
url = f"http://127.0.0.1:{port}"
json_data = {
    "text": [
        "List 3 countries and their capitals.",
        "List 3 countries and their capitals.",
    ],
    "sampling_params": {"max_new_tokens": 32, "temperature": 0},
    # The first input uses lora0, and the second input uses lora1
    "lora_path": ["lora0", "lora1"],
}
response = requests.post(
    url + "/generate",
    json=json_data,
)
print(f"Output 0: {response.json()[0]['text']}")
print(f"Output 1: {response.json()[1]['text']}")
```


```python Example
terminate_process(server_process)
```

### Dynamic LoRA loading


Instead of specifying all adapters during server startup via `--lora-paths`. You can also load & unload LoRA adapters dynamically via the `/load_lora_adapter` and `/unload_lora_adapter` API.

When using dynamic LoRA loading, it's recommended to explicitly specify both `--max-lora-rank` and `--lora-target-modules` at startup. For backward compatibility, SGLang will infer these values from `--lora-paths` if they are not explicitly provided. However, in that case, you would have to ensure that all dynamically loaded adapters share the same shape (rank and target modules) as those in the initial `--lora-paths` or are strictly "smaller".


```python Example
lora0 = "Nutanix/Meta-Llama-3.1-8B-Instruct_SFT_lora_4_alpha_16_humaneval_raw_json"  # rank - 4, target modules - q_proj, k_proj, v_proj, o_proj, gate_proj
lora1 = "algoprog/fact-generation-llama-3.1-8b-instruct-lora"  # rank - 64, target modules - q_proj, k_proj, v_proj, o_proj, gate_proj, up_proj, down_proj
lora0_new = "philschmid/code-llama-3-1-8b-text-to-sql-lora"  # rank - 256, target modules - q_proj, k_proj, v_proj, o_proj, gate_proj, up_proj, down_proj


# The `--target-lora-modules` param below is technically not needed, as the server will infer it from lora0 which already has all the target modules specified.
# We are adding it here just to demonstrate usage.
server_process, port = launch_server_cmd(
    """
    python3 -m sglang.launch_server --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --enable-lora \
    --cuda-graph-max-bs-decode 2 \
    --max-loras-per-batch 2 \
    --max-lora-rank 256
    --lora-target-modules all
    --log-level warning
    """
)

url = f"http://127.0.0.1:{port}"
wait_for_server(url)
```

Load adapter lora0


```python Example
response = requests.post(
    url + "/load_lora_adapter",
    json={
        "lora_name": "lora0",
        "lora_path": lora0,
    },
)

if response.status_code == 200:
    print("LoRA adapter loaded successfully.", response.json())
else:
    print("Failed to load LoRA adapter.", response.json())
```

Load adapter lora1:


```python Example
response = requests.post(
    url + "/load_lora_adapter",
    json={
        "lora_name": "lora1",
        "lora_path": lora1,
    },
)

if response.status_code == 200:
    print("LoRA adapter loaded successfully.", response.json())
else:
    print("Failed to load LoRA adapter.", response.json())
```

Check inference output:


```python Example
url = f"http://127.0.0.1:{port}"
json_data = {
    "text": [
        "List 3 countries and their capitals.",
        "List 3 countries and their capitals.",
    ],
    "sampling_params": {"max_new_tokens": 32, "temperature": 0},
    # The first input uses lora0, and the second input uses lora1
    "lora_path": ["lora0", "lora1"],
}
response = requests.post(
    url + "/generate",
    json=json_data,
)
print(f"Output from lora0: \n{response.json()[0]['text']}\n")
print(f"Output from lora1 (updated): \n{response.json()[1]['text']}\n")
```

Unload lora0 and replace it with a different adapter:


```python Example
response = requests.post(
    url + "/unload_lora_adapter",
    json={
        "lora_name": "lora0",
    },
)

response = requests.post(
    url + "/load_lora_adapter",
    json={
        "lora_name": "lora0",
        "lora_path": lora0_new,
    },
)

if response.status_code == 200:
    print("LoRA adapter loaded successfully.", response.json())
else:
    print("Failed to load LoRA adapter.", response.json())
```

Check output again:


```python Example
url = f"http://127.0.0.1:{port}"
json_data = {
    "text": [
        "List 3 countries and their capitals.",
        "List 3 countries and their capitals.",
    ],
    "sampling_params": {"max_new_tokens": 32, "temperature": 0},
    # The first input uses lora0, and the second input uses lora1
    "lora_path": ["lora0", "lora1"],
}
response = requests.post(
    url + "/generate",
    json=json_data,
)
print(f"Output from lora0: \n{response.json()[0]['text']}\n")
print(f"Output from lora1 (updated): \n{response.json()[1]['text']}\n")
```


```python Example
terminate_process(server_process)
```

### OpenAI-compatible API usage

You can use LoRA adapters via the OpenAI-compatible APIs by specifying the adapter in the `model` field using the `base-model:adapter-name` syntax (for example, `qwen/qwen2.5-0.5b-instruct:adapter_a`). For more details and examples, see the “Using LoRA Adapters” section in the OpenAI API documentation: [openai_api_completions](../basic_usage/openai_api_completions).


### LoRA GPU Pinning


Another advanced option is to specify adapters as `pinned` during loading. When an adapter is pinned, it is permanently assigned to one of the available GPU pool slots (as configured by `--max-loras-per-batch`) and will not be evicted from GPU memory during runtime. Instead, it remains resident until it is explicitly unloaded.

This can improve performance in scenarios where the same adapter is frequently used across requests, by avoiding repeated memory transfers and reinitialization overhead. However, since GPU pool slots are limited, pinning adapters reduces the flexibility of the system to dynamically load other adapters on demand. If too many adapters are pinned, it may lead to degraded performance, or in the most extreme case (`Number of pinned adapters == max-loras-per-batch`), halt all unpinned requests. Therefore, currently SGLang limits maximal number of pinned adapters to `max-loras-per-batch - 1` to prevent unexpected starvations.

In the example below, we start a server with `lora1` loaded as pinned, `lora2` and `lora3` loaded as regular (unpinned) adapters. Please note that, we intentionally specify `lora2` and `lora3` in two different formats to demonstrate that both are supported.


```python Example
server_process, port = launch_server_cmd(
    """
    python3 -m sglang.launch_server --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --enable-lora \
    --cuda-graph-max-bs-decode 8 \
    --max-loras-per-batch 3 \
    --max-lora-rank 256 \
    --lora-target-modules all \
    --lora-paths \
        {"lora_name":"lora0","lora_path":"Nutanix/Meta-Llama-3.1-8B-Instruct_SFT_lora_4_alpha_16_humaneval_raw_json","pinned":true} \
        {"lora_name":"lora1","lora_path":"algoprog/fact-generation-llama-3.1-8b-instruct-lora"} \
        lora2=philschmid/code-llama-3-1-8b-text-to-sql-lora
    --log-level warning
    """
)


url = f"http://127.0.0.1:{port}"
wait_for_server(url)
```

You can also specify adapter as pinned during dynamic adapter loading. In the example below, we reload `lora2` as pinned adapter:


```python Example
response = requests.post(
    url + "/unload_lora_adapter",
    json={
        "lora_name": "lora1",
    },
)

response = requests.post(
    url + "/load_lora_adapter",
    json={
        "lora_name": "lora1",
        "lora_path": "algoprog/fact-generation-llama-3.1-8b-instruct-lora",
        "pinned": True,  # Pin the adapter to GPU
    },
)
```

Verify that the results are expected:


```python Example
url = f"http://127.0.0.1:{port}"
json_data = {
    "text": [
        "List 3 countries and their capitals.",
        "List 3 countries and their capitals.",
        "List 3 countries and their capitals.",
    ],
    "sampling_params": {"max_new_tokens": 32, "temperature": 0},
    # The first input uses lora0, and the second input uses lora1
    "lora_path": ["lora0", "lora1", "lora2"],
}
response = requests.post(
    url + "/generate",
    json=json_data,
)
print(f"Output from lora0 (pinned): \n{response.json()[0]['text']}\n")
print(f"Output from lora1 (pinned): \n{response.json()[1]['text']}\n")
print(f"Output from lora2 (not pinned): \n{response.json()[2]['text']}\n")
```


```python Example
terminate_process(server_process)
```

## Choosing LoRA Backend

SGLang supports two LoRA backends that you can choose from using the `--lora-backend` argument:

- `triton`: Basic Triton-based backend.
- `csgmv`: Default chunked SGMV backend optimized for high concurrency scenarios.

The `csgmv` backend was recently introduced to improve performance especially at high-concurrency scenarios. Our benchmark shows that it achieves 20% to 80% latency improvements over the basic triton backend.


```python Example
server_process, port = launch_server_cmd(
    """
    python3 -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --enable-lora \
    --lora-backend csgmv \
    --max-loras-per-batch 16 \
    --lora-paths lora1=path/to/lora1 lora2=path/to/lora2
    """
)
```


```python Example
terminate_process(server_process)
```

## LoRA with DP attention

SGLang supports LoRA serving with [data parallel attention (DPA)](/docs/advanced_features/dp_dpa_smg_guide). The model architecture must support DPA, and you must currently select the Triton LoRA backend. Other built-in LoRA backends reject this configuration at startup.

The following NVIDIA CUDA example uses four attention-DP ranks:

```bash
python3 -m sglang.launch_server \
    --model-path MODEL_PATH \
    --tp 4 \
    --attn-dp-size 4 \
    --enable-lora \
    --lora-backend triton \
    --lora-paths '{"lora_name":"ADAPTER_NAME","lora_path":"ADAPTER_PATH","pinned":true}'
```

Keep these constraints in mind:

- `--attn-dp-size` must equal `--tp-size`, so every attention DP rank owns its whole token batch. The server rejects other layouts at startup.
- All adapters must be GPU-pinned (`pinned: true`), including dynamically loaded adapters. You can pin at most `--max-loras-per-batch - 1` adapters; the remaining slot is reserved for the base model.
- Decode CUDA graphs are supported. LoRA prefill runs eagerly when DPA is enabled.
- `--max-loras-per-batch` limits the union of adapters active across all DP ranks in a synchronized forward, not the adapters on one rank alone.
- Dynamic load and unload requests are sent to every DP rank. An operation succeeds only if every rank reports success. After a partially successful load, retry unloading the same adapter name before loading it again.
- The built-in LoRA memory pool does not support `--enable-lora-overlap-loading` with DPA. The server rejects that combination rather than allowing DP ranks to assign different GPU slots.

## LoRA Overlap Loading


By using the `--enable-lora-overlap-loading` server argument, the SGLang engine is able to overlap the loading of LoRA weights with prefill and decode compute, essentially hiding the data movement for LoRA weights behind GPU computation. Our benchmarks show that under adversarial conditions, enabling this feature can result in a ~35% reduction in median TTFT - (see the [LoRA overlap loading PR](https://github.com/sgl-project/sglang/pull/15512) for detailed benchmarks).


```python Example
lora0 = "Nutanix/Meta-Llama-3.1-8B-Instruct_SFT_lora_4_alpha_16_humaneval_raw_json"
lora1 = "algoprog/fact-generation-llama-3.1-8b-instruct-lora"
lora2 = "philschmid/code-llama-3-1-8b-text-to-sql-lora"


server_process, port = launch_server_cmd(
    """
    python3 -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --enable-lora \
    --enable-lora-overlap-loading \
    --lora-paths lora0=Nutanix/Meta-Llama-3.1-8B-Instruct_SFT_lora_4_alpha_16_humaneval_raw_json \
    lora1=algoprog/fact-generation-llama-3.1-8b-instruct-lora \
    lora2=philschmid/code-llama-3-1-8b-text-to-sql-lora \
    --max-lora-rank 256 \
    --max-loras-per-batch 2 \
    --max-loaded-loras 4
    """
)

url = f"http://127.0.0.1:{port}"
wait_for_server(url)
```


```python Example
json_data = {
    "text": [
        "Write a very long fairy-tale.",
        "List 3 countries and their capitals.",
        "List 3 countries and their capitals.",
    ],
    "sampling_params": [
        {"max_new_tokens": 1024, "temperature": 0},
        {"max_new_tokens": 64, "temperature": 0},
        {"max_new_tokens": 64, "temperature": 0},
    ],
    "lora_path": ["lora0", "lora1", "lora2"],
}

# lora0 and lora1 will be loaded into the memory pool first, and because max_loras_per_batch = 2, lora2's request will remain in the queue.
# lora1's request will likely finish first, and once it does, lora2 will be loaded. With --enable-lora-overlap-loading, this loading will
# occur asynchronously and thus decoding for lora0's request won't be blocked.
response = requests.post(
    url + "/generate",
    json=json_data,
)

for i in range(3):
    print(f"Output from lora{i}: \n{response.json()[i]['text']}\n")
```


```python Example
terminate_process(server_process)
```

#### Limitations of LoRA Overlap Loading


However, LoRA overlap loading is not free and comes with two important caveats:

1. **Pinned CPU memory requirement**:
   Asynchronous H2D memory copies require LoRA weights to be pinned in CPU memory, which is a finite system resource. To mitigate excessive pinned-memory usage, SGLang currently restricts `max_loaded_loras` to be at most 2× `max_loras_per_batch` when LoRA overlap loading is enabled.

2. **Reduced multi-adapter prefill batching**:
   With overlap loading, adapters become available on the GPU at different times because each adapter is loaded asynchronously. This can reduce the scheduler’s ability to form multi-adapter prefill batches, since only requests whose adapters are currently loaded can be grouped together. As a result, requests for different adapters will be scheduled in separate (or smaller) prefill batches, which can increase TTFT when adapter load time is small compared to prefill compute time. This is why LoRA overlap loading is disabled by default: it should only be enabled when users have determined that LoRA weight loading is a bottleneck (EG high adapter churn, heavy adapter weights, or PCIe-bottlenecked workloads).


#### Example When Overlap Loading Results in Higher Latency


For instance, suppose we have four LoRA adapters: `lora0`, `lora1`, `lora2`, and `lora3`. Loading any adapter takes 2ms, while the prefill step for requests for that adapter takes 20ms.

1. **Baseline**:
  The engine loads all four adapters synchronously, then runs one combined prefill batch, giving us a total time of ≈ `2 * 4 + 20 = 28ms`

2. **With LoRA overlap loading enabled**:
  The engine begins loading `lora0` and, once it is ready, schedules a prefill batch containing only `lora0` while `lora1` loads in the background. Then it schedules `lora1`’s prefill while `lora2` loads, and so on. In the worst case where prefill cannot be batched across adapters, total time is ≈ `2 + 4 * 20 = 82ms`

In this scenario, overlap loading reduces adapter-load overhead, but the loss of multi-adapter prefill batching dominates and leads to higher TTFT.


## Future Works

The development roadmap for LoRA-related features can be found in this [issue](https://github.com/sgl-project/sglang/issues/2929). Other features, including Embedding Layer, Unified Paging, Cutlass backend are still under development.

---

### Docs Advanced Features Model Loading (`docs/docs/advanced_features/model_loading.mdx`)

---
title: "Model Loading"
description: "Control how SGLang loads model weights: load formats, model loader extra config, multithreaded loading, prefetching, and remote/streaming loaders."
---

`--model-path` selects the checkpoint to serve; `--load-format` and the weight-loading flags below control how those weights are read into memory. To stream weights from cloud object storage (S3/GCS/Azure), see [Loading Models from Object Storage](./object_storage).

## How loading works

SGLang picks a loader from `--load-format`, falling back to auto-detection from the checkpoint or model path. The default `auto` loader reads `safetensors` and falls back to PyTorch `.bin`.

```bash
python -m sglang.launch_server \
  --model-path Qwen/Qwen3.6-35B-A3B \
  --load-format auto
```

Some formats are auto-detected and override `auto`:

- A Mistral native checkpoint is detected and loaded with `mistral`.
- A `.gguf` model path is detected and loaded with `gguf`.
- An object storage URI (`s3://`, `gs://`, `az://`) is loaded with `runai_streamer`.
- A remote URI is loaded with `remote`.

## Load formats

Set with `--load-format`:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "20%"}} />
    <col style={{width: "80%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Format</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>auto</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Default. Load <code>safetensors</code> if available, otherwise fall back to the PyTorch <code>.bin</code> format.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>safetensors</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load weights in the safetensors format.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>instanttensor</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load Safetensors weights quickly with InstantTensor's distributed loading and pipelined prefetching. Supports CUDA and ROCm; requires PyTorch's <code>cuda</code> device interface. Distributed loading may retain communicator memory for the server lifetime.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>pt</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load weights in the PyTorch <code>.bin</code> format.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>npcache</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load PyTorch-format weights and store a numpy cache to speed up subsequent loads. Only supports <code>.bin</code> checkpoints.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>dummy</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Initialize weights with random values, for profiling.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>sharded_state</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Each tensor-parallel worker reads only its own pre-sharded shard rather than the full checkpoint, giving a fast load path for large TP models. See <code>examples/runtime/engine/save_sharded_state.py</code> for creating a sharded checkpoint.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>fastsafetensors</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load safetensors using the <code>fastsafetensors</code> iterator.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>layered</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load weights layer by layer, so a layer can be quantized before the next is loaded, lowering the peak memory envelope.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>gguf</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load weights in the GGUF format. Auto-detected from a <code>.gguf</code> model path.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>bitsandbytes</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load weights using bitsandbytes quantization.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>mistral</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load a Mistral native-format checkpoint. Auto-detected for such checkpoints.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>flash_rl</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load a BF16/FP16 checkpoint with native SGLang FP8 quantization for RL training. Requires <code>--rl-quant-profile</code>.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>runai_streamer</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Stream weights from SSDs, shared filesystems, or object storage. See <a href="./object_storage">Loading Models from Object Storage</a>.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>remote</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load tensors from a remote KV/filesystem connector. Auto-detected for remote URIs.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>remote_instance</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Pull weights over the network from another running SGLang instance (the "seed") rather than from disk. Configured with the <code>--remote-instance-weight-loader-*</code> flags.</td>
    </tr>
  </tbody>
</table>

## Model loader extra config

`--model-loader-extra-config` takes a JSON string passed to the loader selected by `--load-format`.

```bash
python -m sglang.launch_server \
  --model-path Qwen/Qwen3.6-35B-A3B \
  --model-loader-extra-config '{"enable_multithread_load": true, "num_threads": 16}'
```

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "20%"}} />
    <col style={{width: "24%"}} />
    <col style={{width: "40%"}} />
    <col style={{width: "16%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Load format</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, backgroundColor: "rgba(255,255,255,0.05)"}}>Key</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>auto</code> / <code>safetensors</code> / <code>pt</code> / <code>npcache</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>enable_multithread_load</code> (bool)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Read weight shards with a thread pool instead of sequentially. Disabled by default when <code>--weight-loader-prefetch-checkpoints</code> is set (to avoid I/O oversubscription with the prefetch threads); set this to <code>true</code> to opt back in.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>true</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>auto</code> / <code>safetensors</code> / <code>pt</code> / <code>npcache</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>num_threads</code> (int)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Number of worker threads when multithreaded loading is enabled.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>8</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>sharded_state</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>pattern</code> (str)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Filename pattern for per-rank shards.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>model-rank-&#123;rank&#125;-part-&#123;part&#125;.safetensors</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>fastsafetensors</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>enable_gds</code> (bool)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Use GPU Direct Storage. Set to <code>false</code> when the host does not provide the NVIDIA GPUDirect Storage kernel driver, such as in a gVisor sandbox.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>true</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>instanttensor</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>buffer_size</code> (int)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>GPU tensor buffer size in bytes. See the <a href="https://github.com/scitix/InstantTensor">InstantTensor GitHub homepage</a> for the latest optional parameters.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>null</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>instanttensor</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>chunk_size</code> (int)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>File I/O operation size in bytes.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>null</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>instanttensor</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>io_depth</code> (int)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Maximum number of rank-local I/O operations in flight.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>null</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>instanttensor</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>backend</code> (str / list)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>A backend name or an ordered list of candidates: <code>AIO</code>, <code>AIO_BUFFERED</code>, <code>URING</code>, <code>URING_BUFFERED</code>, <code>CUFILE</code>, <code>MMAP</code>, or the <code>BUFFERED</code> policy.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>null</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>bitsandbytes</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>qlora_adapter_name_or_path</code> (str)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>QLoRA adapter to apply on top of the bitsandbytes-quantized base weights.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>—</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>runai_streamer</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>distributed</code>, <code>concurrency</code>, <code>memory_limit</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Streaming controls. See <a href="./object_storage">Loading Models from Object Storage</a>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>See linked page</td>
    </tr>
  </tbody>
</table>

## Weight-loading performance flags

Top-level arguments that tune how safetensors weights are read, independent of `--load-format`.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "52%"}} />
    <col style={{width: "14%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, backgroundColor: "rgba(255,255,255,0.02)"}}>Flag</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--download-dir</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Directory used to download and cache Hugging Face model files.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>HF default</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.05)"}}><code>--weight-loader-disable-mmap</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Disable mmap while loading safetensors. Can help on filesystems where mmap is slow.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>off</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--weight-loader-prefetch-checkpoints</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Prefetch checkpoint files into the OS page cache before loading. Each rank prefetches a fraction of the shards, cutting total network I/O on shared filesystems (NFS/Lustre) from N×checkpoint to 1×checkpoint. Recommended for models on network storage. When enabled, multi-threaded safetensors loading is disabled by default to avoid I/O oversubscription with the prefetch threads; set <code>enable_multithread_load=true</code> in <code>--model-loader-extra-config</code> to keep multi-threaded loading (e.g. on local NVMe where prefetch is a no-op).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>off</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.05)"}}><code>--weight-loader-prefetch-num-threads</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Threads per rank for checkpoint prefetching.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>4</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--weight-loader-drop-cache-after-load</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Call <code>posix_fadvise(DONTNEED)</code> after successfully loading each shard, freeing page cache. Supported by the standard safetensors and <code>fastsafetensors</code> loaders.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>off</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.05)"}}><code>--custom-weight-loader</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Import path(s) of a custom weight-loading function, e.g. <code>my_package.weight_load_func</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>—</td>
    </tr>
  </tbody>
</table>

## See also

- [Loading Models from Object Storage](./object_storage)
- [Quantization](./quantization)
- [Server Arguments](./server_arguments)

---

### Docs Advanced Features Object Storage (`docs/docs/advanced_features/object_storage.mdx`)

---
title: "Loading Models from Object Storage"
metatags:
    description: "Load SGLang models directly from S3, Google Cloud Storage, Azure Blob, and S3-compatible object storage with runai_streamer."
---

SGLang can load models directly from object storage without a full local download. It uses the `runai_streamer` load format to stream model weights from cloud storage, reducing startup time and local storage requirements.

## Overview

When loading models from object storage, SGLang uses a two-phase approach:

1. **Metadata Download** (once, before process launch): Configuration files and tokenizer files are downloaded to a local cache
2. **Weight Streaming** (lazy, during model loading): Model weights are streamed directly from object storage as needed

## Supported Storage Backends

1. **Amazon S3**: `s3://bucket-name/path/to/model/`
2. **Google Cloud Storage**: `gs://bucket-name/path/to/model/`
3. **Azure Blob**: `az://some-azure-container/path/`
4. **S3 compatible**: `s3://bucket-name/path/to/model/`

## Quick Start

### Basic Usage

Simply provide an object storage URI as the model path:

```bash
# S3
python -m sglang.launch_server \
  --model-path s3://my-bucket/models/llama-3-8b/ \
  --load-format runai_streamer

# Google Cloud Storage
python -m sglang.launch_server \
  --model-path gs://my-bucket/models/llama-3-8b/ \
  --load-format runai_streamer
```

**Note**: The `--load-format runai_streamer` is automatically detected when using object storage URIs, so you can omit it:

```bash
python -m sglang.launch_server \
  --model-path s3://my-bucket/models/llama-3-8b/
```

### With Tensor Parallelism

```bash
python -m sglang.launch_server \
  --model-path gs://my-bucket/models/llama-70b/ \
  --tp 4 \
  --model-loader-extra-config '{"distributed": true}'
```

## Configuration

### Load Format

The `runai_streamer` load format is designed for object storage, SSDs, and shared filesystems.

```bash
python -m sglang.launch_server \
  --model-path s3://bucket/model/ \
  --load-format runai_streamer
```

### Extended Configuration Parameters

Use `--model-loader-extra-config` to pass additional configuration as a JSON string:

```bash
python -m sglang.launch_server \
  --model-path s3://bucket/model/ \
  --model-loader-extra-config '{
    "distributed": true,
    "concurrency": 8,
    "memory_limit": 2147483648
  }'
```

#### Available Parameters

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "22%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "44%"}} />
    <col style={{width: "18%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>distributed</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Enable distributed streaming for multi-GPU setups. Automatically set to <code>true</code> for object storage paths on CUDA-like devices.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Auto-detected</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>concurrency</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Number of concurrent download streams. Higher values can improve throughput for large models.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>4</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>memory_limit</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Memory limit (in bytes) for the streaming buffer.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>System-dependent</td>
    </tr>
  </tbody>
</table>

## Performance Considerations

### Distributed Streaming

For multi-GPU setups, enable distributed streaming to parallelize weight loading across processes:

```bash
python -m sglang.launch_server \
  --model-path s3://bucket/model/ \
  --tp 8 \
  --model-loader-extra-config '{"distributed": true}'
```

## Limitations

- **Supported formats**: Only the `.safetensors` weight format is supported.
- **Supported devices**: Distributed streaming is supported on CUDA-like devices; otherwise it falls back to non-distributed streaming.

## See Also

- [Runai model streamer documentation](https://github.com/run-ai/runai-model-streamer)

---

### Docs Advanced Features Observability (`docs/docs/advanced_features/observability.mdx`)

---
title: "Observability"
metatags:
    description: "SGLang observability: Prometheus metrics, request logging, request dump and replay, crash dump debugging."
---
## Production Metrics
SGLang exposes the following metrics via Prometheus. You can enable them by adding `--enable-metrics` when launching the server.
You can query them by:
```bash Command
curl http://localhost:30000/metrics
```

See [Production Metrics](../references/production_metrics) and [Production Request Tracing](../references/production_request_trace) for more details.

## Logging

By default, SGLang does not log any request contents. You can log them by using `--log-requests`.
You can control the verbosity by using `--log-request-level`.
See [Logging](./server_arguments#logging) for more details.

You can change verbosity at runtime:

```bash Command
python3 -m sglang.srt.managers.configure_logging --url http://localhost:30000 --log-level=debug
```

## Request Dump and Replay

You can dump all requests and replay them later for benchmarking or other purposes.

To start dumping, use the following command to send a request to a server:
```bash Command
python3 -m sglang.srt.managers.configure_logging --url http://localhost:30000 --dump-requests-folder /tmp/sglang_request_dump --dump-requests-threshold 100
```
The server will dump the requests into a pickle file for every 100 requests.

To replay the request dump, use `scripts/playground/replay_request_dump.py`.

## Crash Dump and Replay
Sometimes the server might crash, and you may want to debug the cause of the crash.
SGLang can preserve recent request data for replay and collect CUDA device coredumps for low-level debugging.

Set the crash diagnostics folder with `--crash-dump-folder /tmp/crash_dump`.

When SGLang handles a crash, it writes completed requests retained by the crash-dump buffer plus in-flight requests to `/tmp/crash_dump/<hostname>/crash_dump_<timestamp>.pkl`. The file also contains the server arguments and launch command. Replay it with `scripts/playground/replay_request_dump.py`.

On NVIDIA CUDA, the option also sets default environment variables before CUDA initializes. These defaults enable device coredumps on CUDA exceptions and allow SGLang to trigger device coredumps for live scheduler processes when it handles a crash. CUDA device coredumps are written to `/tmp/crash_dump/<hostname>/core.cuda.<timestamp>.<pid>`. Explicitly configured CUDA coredump environment variables take precedence, including a custom `CUDA_COREDUMP_FILE` path. This option does not configure OS process core dumps.

---

### Docs Advanced Features Paged Experts (`docs/docs/advanced_features/paged_experts.mdx`)

---
title: "Paged Experts"
metatags:
    description: "SGLang Paged Experts: serve an MoE model whose experts do not fit in GPU memory by keeping K of E experts per layer on the GPU and paging the rest from pinned host memory. Computation stays on the GPU."
---

Paged Experts serves a Mixture-of-Experts (MoE) model whose expert weights do not fit in GPU
memory. Each MoE layer keeps **K of its E routed experts in a K-slot table on the GPU** and holds
all E experts in pinned host memory; every step, the experts the step routes to that are not
resident are copied into slots before the expert GEMM runs.

## Why Paged Experts?

Expert weights are most of an MoE model's parameters, yet each token is routed to only `top_k`
of the `E` experts per layer, and consecutive tokens reuse many of the same experts. Paged
Experts keeps a working set of K experts per layer resident and pages the rest in from host
memory as routing requires them, so expert capacity is bounded by host RAM rather than VRAM.

**Computation stays on the GPU.** Only expert *storage* is host-backed: experts are copied to the
GPU and computed there by the model's own fused-MoE kernel. This differs from `--cpu-offload-gb`
and CPU expert offload, which move the computation to the CPU.

**Results are unchanged.** Routing is untouched (E-wide), and the paged layer produces the same
output as the unpaged one: bit-identical for unquantized and block-FP8 experts (with
`--enable-deterministic-inference`), and within the Marlin kernel's own run-to-run noise for
GPTQ. See [Correctness](#correctness).

## Usage

```bash
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-30B-A3B-GPTQ-Int4 \
  --enable-paged-experts \
  --paged-experts-num-resident 92
```

See [Choosing K](#choosing-k) for the value. The default CUDA graphs stay on: decode graphs are captured up to
`K // top_k` concurrent requests, and breakable prefill graphs run the paged MoE layers as eager
breaks.

## Related Parameters

- **`--enable-paged-experts`**: Enable Paged Experts. Off by default.
- **`--paged-experts-num-resident K`**: Routed experts per MoE layer kept on the GPU. Required
  with `--enable-paged-experts`, at least the router's `top_k`; larger values page less but leave
  less memory for the KV cache.

## Supported Configurations and Limitations

- **Quantization:** unquantized (bf16/fp16), block-quantized FP8 (e.g. `weight_block_size`
  `[128, 128]`) on the triton MoE runner, and GPTQ int4/int8 on the Marlin runner. Other
  quantization methods are rejected at startup.
- **Single GPU:** tensor, expert, pipeline and data parallelism, EPLB, fused shared experts
  (use `--disable-shared-experts-fusion`), `--enable-fused-moe-sum-all-reduce` and
  `--load-format dummy` are rejected at startup.
- **Speculative decoding** is rejected at startup.
- **CUDA graphs:** decode graphs may use the `full` backend (the default) or be disabled;
  prefill graphs may use the `breakable` backend (the default on CUDA) or be disabled. Other
  combinations are rejected at startup.
- **Host memory:** the host store holds all E experts of every MoE layer and is page-locked, so
  the host must be able to pin that much memory. Under WSL2, pinned memory is capped at about
  half of system RAM.
- **Startup:** for GPTQ, the Marlin repack runs over the host store K experts at a time at load.

## How It Works

### The K-slot table and the host store

The paged method wraps the layer's own fused-MoE method. It creates the layer's expert tensors
with K rows instead of E, so the GPU holds only the K slots, and allocates a host store holding
all E experts of each per-expert tensor. Each tensor's weight loader is redirected to a one-row
view of the host store, so checkpoint weights are written by SGLang's native per-expert loader
(sharding, gate/up placement, scale layout) and the host rows have exactly the layout the GPU
slots would have.

After loading, the wrapped method's post-load step runs as it would without paging. For methods
that repack their experts (GPTQ's Marlin repack), it runs over the host store K experts at a
time, so the host store holds every expert in the repacked layout.

### A step: waves, page-in, merge

Every forward step of every MoE layer:

1. The distinct experts the step routes to are split into **waves** of at most K, the experts
   already resident first. Decode at
   moderate batch sizes needs one wave; a prefill chunk usually needs several.
2. Each wave makes its experts resident, evicting the least recently used experts outside the
   wave, and copies the missing ones from the host store into their slots.
3. The routed expert ids are remapped to slots and the wrapped fused-MoE kernel runs over the
   wave's own entries **without its final top-k sum**, returning each routed (token, expert)
   output already multiplied by its router weight.
4. Each entry is written into one merged buffer by the one wave that holds its expert, and the
   merged entries go through the same top-k sum the kernel would have performed, so the result
   does not depend on how the experts were split into waves.

### Captured decode

With decode CUDA graphs on, a step whose routed entries fit the K slots (`tokens × top_k ≤ K`,
i.e. decode up to `K // top_k` requests) is served by a single wave decided and paged on the
GPU, with no host synchronization, so the decode graph captures it:

- a JIT kernel makes the LRU decision on the device and writes the page-in plan (experts, slots,
  count) to GPU buffers;
- a second kernel copies the planned experts of every paged tensor from the pinned host store
  into their slots, reading the host memory directly through its unified address and the count
  on the device, so each graph replay moves exactly the experts it decided on.

Decode capture batch sizes are capped at `K // top_k` (logged at startup); larger batches run
without a graph. Prefill steps plan their waves on the host: under a breakable prefill graph the
paged MoE layer is an eager break between graph segments, so the rest of the layer stack stays
captured. Both paths share one LRU state, so residency carries over between captured and
uncaptured steps.

## Choosing K

The K-slot table counts as model weights in SGLang's memory accounting, so K and the KV cache
come out of the same static budget (`--mem-fraction-static`): whatever K does not take becomes KV
cache, as without paging. One resident expert per layer costs `per_expert_bytes × num_moe_layers`
of GPU memory, so K is roughly

```
K ≈ (free_memory × mem_fraction_static − non_expert_bytes − kv_cache_bytes) / (per_expert_bytes × num_moe_layers)
```

For example, Qwen3-30B-A3B-GPTQ-Int4 (2.43 MB per expert, 48 MoE layers, 117 MB per slot) fits
K = 92 of 128 on a 16 GB GPU with `--mem-fraction-static 0.88 --max-total-tokens 10240`.
If the server runs out of memory for the KV cache at startup, lower K; for more concurrency,
lower K or use `--kv-cache-dtype fp8`.

## Correctness

Prompt and greedy decode logprobs are compared with the unpaged server under
`--enable-deterministic-inference --attention-backend triton`, eager and with decode captured:

- **unquantized and block-FP8 experts (triton runner):** bit-identical;
- **GPTQ (Marlin runner):** Marlin's reduction depends on the batch shape, so a paged step (which
  runs the kernel on a different number of experts) differs from the unpaged one within Marlin's
  own batch-to-batch noise.

---

### Docs Advanced Features Pd Disaggregation (`docs/docs/advanced_features/pd_disaggregation.mdx`)

---
title: "PD Disaggregation"
metatags:
    description: "SGLang PD disaggregation: separate prefill and decode phases, Mooncake and NIXL transfer engines, multi-node DeepSeek deployment."
---
## Why and What is PD Disaggregation?

Large Language Model (LLM) inference comprises two distinct phases: **Prefill** and **Decode**. The Prefill phase is computation-intensive, processing the entire input sequence, while the Decode phase is memory-intensive, managing the Key-Value (KV) cache for token generation. Traditionally, these phases are handled within a unified engine, where combined scheduling of prefill and decode batches introduces inefficiencies. To address these challenges, we introduce **Prefill and Decoding (PD) Disaggregation** in SGLang.

### Issues with Unified Scheduling

The conventional unified engine, which processes prefill and decode batches together, results in two significant problems:

1. **Prefill Interruption**: Incoming prefill batches frequently interrupt ongoing decode batches, causing substantial delays in token generation.
2. **DP Attention Imbalance**: In data-parallel (DP) attention, one DP worker may process a prefill batch while another handles a decode batch simultaneously, leading to increased decode latency.

PD Disaggregation resolves these by separating the two stages, enabling tailored optimizations for each.

For the design details, please refer to [link](https://docs.google.com/document/d/1rQXJwKd5b9b1aOzLh98mnyMhBMhlxXA5ATZTHoQrwvc/edit?tab=t.0).

Currently, we support Mooncake and NIXL as the transfer engine.

## Decode allocation policy

By default, decode reserves each request's destination KV slots before prefill
finishes. Long prefills can hold these slots while decode waits for the KV data.
To delay this reservation, set the following flag on **both prefill and decode**:

```bash
--disaggregation-decode-allocation-policy prefill_complete
```

With `prefill_complete`, prefill computes without waiting for destination slots,
then signals readiness after accepting its final prefill result. Decode reserves
slots and starts the existing KV transfer handshake only after that signal.
This changes per-request KV reservation, not the size or creation of the global
KV pool. The default `early` policy preserves the existing behavior.

Deferring allocation can help when long prefills compete with active decode
requests for destination KV capacity. It also retains KV on prefill longer and
removes overlap between chunked prefill and KV transfer. Compare both policies
for your workload; this option is not a general throughput improvement.

This initial implementation requires Mooncake (RDMA or `mooncake_tcp`), the Python
bootstrap registry, and attention TP/CP and pipeline sizes of one. Attention DP
is allowed when each DP rank has attention TP size one. Prefill automatically
resolves `--optimistic-prefill-attempts` from zero to one; configurations that
disable optimistic prefill after model validation are rejected.
Chunked prefill does not yield just because decode has not admitted the request.
Completed requests retain their KV in the existing optimistic-prefill inflight
queue until decode supplies destination indices; readiness alone never starts
a KV write.
After a successful transfer, prefill clears the room's readiness and transfer
state before notifying decode of success. Retraction recovery can then reuse
the same bootstrap room. This notification waits for worker and scheduler
cleanup; failure and cancellation records remain until their timeout expires.
Retries remain eligible for prefill after the optimistic attempt budget is
exhausted and remain subject to the existing cancellation and timeout handling.

On prefill, `SGLANG_DISAGGREGATION_BOOTSTRAP_TIMEOUT` starts after the final
prefill result, giving decode admission its own budget. On decode,
`SGLANG_DISAGGREGATION_WAITING_TIMEOUT` bounds the wait for prefill completion,
then starts afresh for admission and again when destination indices are sent
for transfer.

The option does not support staging buffers, runtime PD role switching, PD
multiplexing, encoder disaggregation, decoupled speculation, HiSparse, decode radix cache, decode
HiCache, or non-DSA auxiliary state pools. Prefill HiCache is limited to L2 with
`write_back` and no storage backend. Unsupported configurations fail validation.

All communicating workers must use the same revision and enable the same policy. This
version of the decode worker rejects policy or peer-layout mismatches before
destination registration. Older decode workers do not enforce this check. Keep
`early` on both sides until every worker has been upgraded, then enable the new
policy on both sides.

## Profiling in PD Disaggregation Mode

When you need to profile prefill or decode workers in PD disaggregation mode, please refer to the [Profile In PD Disaggregation Mode](../developer_guide/benchmark_and_profiling#profile-in-pd-disaggregation-mode) section in the Benchmark and Profiling guide. Due to torch profiler limitations, prefill and decode workers must be profiled separately using dedicated command-line options.

## Router Integration

For deploying PD disaggregation at scale with load balancing and fault tolerance, SGLang provides a router. The router can distribute requests between prefill and decode instances using various routing policies. For detailed information on setting up routing with PD disaggregation, including configuration options and deployment patterns, see the [SGLang Model Gateway (former Router)](./sgl_model_gateway#prefill-decode-disaggregation).

### Responses API under HTTP PD

HTTP PD supports foreground generation through `POST /v1/responses`, including streaming generation with `stream=true` through the HTTP PD router. This requires both the router's Responses dispatch support and serving workers that accept Responses PD routing metadata.

Store-backed and stateful Responses features are **not supported under PD**:

- Response persistence (`store`) and response history.
- Conversation chaining with `previous_response_id`.
- Background Responses (`background=true`), including background streams.
- Retrieval by response ID (`GET /v1/responses/{id}`).
- Cancel-by-ID (`POST /v1/responses/{id}/cancel`).
- Other workflows requiring shared process-local Responses history.

Prefill and decode run in separate serving processes. Their process-local Responses stores cannot provide coherent shared state: both legs need the same conversation history to reconstruct the prompt, and prefill's stored response is not available to decode. Send explicit conversation history in foreground requests instead of relying on stored response IDs.

Built-in tools (`web_search`, `code_interpreter`) are also unsupported under PD: each tool call requires another generation, but the router dispatches exactly one prefill/decode pair per HTTP request.

Serving-side capability enforcement is tracked in [#39122](https://github.com/sgl-project/sglang/pull/39122). That change introduces opt-in standalone storage with `--enable-response-store`, disallows it under PD, and rejects stateful requests with HTTP 400 before generation. These checks require a serving version containing that change; older versions must not be assumed to reject every unsupported workflow at admission. The HTTP PD router also rejects detached background requests because it does not implement their retrieval/cancel lifecycle.


## Mooncake
### Requirements

```bash
uv pip install mooncake-transfer-engine
```

### AWS EFA

#### EFA Docker images

Each published CUDA 13 image has an EFA variant for EFA-enabled AWS EC2 instances, built from the same SGLang commit with `docker/efa.Dockerfile`:

| Base image | EFA image |
|---|---|
| `latest`, `v<version>` | `latest-efa`, `v<version>-efa` |
| `latest-runtime`, `v<version>-runtime` | `latest-runtime-efa`, `v<version>-runtime-efa` |
| `nightly-dev-<date>-<sha>` | `nightly-dev-efa-<date>-<sha>`, plus the moving `dev-efa` |

Each EFA image matches its base and adds:

- The AWS EFA userspace stack: libfabric with the EFA provider, rdma-core, and the aws-ofi-nccl plugin. The host does not need its own EFA userspace install.
- On x86_64, the EFA build of Mooncake with `MOONCAKE_PROTOCOL=efa`. On arm64 the standard Mooncake package is kept and `MOONCAKE_PROTOCOL=tcp` is set, because the EFA build is x86_64-only.
- `SGLANG_DISAGGREGATION_NIXL_BACKEND=LIBFABRIC`, so NIXL transfers use EFA on both architectures.
- `NCCL_NET_PLUGIN=ofi` and `NCCL_TUNER_PLUGIN=ofi`, so NCCL uses aws-ofi-nccl.

To add EFA to another CUDA 13 SGLang image, build `docker/efa.Dockerfile` on top of it:

```bash
docker build -f docker/efa.Dockerfile \
  --build-arg BASE_IMAGE=lmsysorg/sglang:latest-runtime \
  -t sglang:efa docker/
```

The host still needs the EFA kernel driver. Pass the EFA devices into the container and lift the locked-memory limit:

```bash
HF_CACHE_DIR="/path/to/huggingface-cache"
docker run -it --gpus all \
  --network host \
  --ipc=host \
  $(for d in /dev/infiniband/uverbs*; do echo -n "--device $d "; done) \
  --ulimit memlock=-1 \
  -v "$HF_CACHE_DIR:/root/.cache/huggingface" \
  --env HF_TOKEN \
  lmsysorg/sglang:latest-runtime-efa bash
```

Inside the container, `fi_info -p efa -t FI_EP_RDM` lists the EFA devices.

#### Install into your own environment

On an x86_64 AWS EFA instance, replace the standard CUDA 13 Mooncake package with the EFA build. The two packages install the same `mooncake` Python module, so do not install them side by side.

The following commands replace the package in an SGLang CUDA 13 environment while preserving its existing Python dependencies:

```bash
python3 -m pip uninstall -y \
  mooncake-transfer-engine-cuda13 \
  mooncake-transfer-engine-efa-cuda13
python3 -m pip install --no-deps \
  mooncake-transfer-engine-efa-cuda13==0.3.13.post1

export LD_LIBRARY_PATH="/opt/amazon/efa/lib:/opt/amazon/efa/lib64:${LD_LIBRARY_PATH:-}"
export MOONCAKE_PROTOCOL=efa

python3 -c 'from mooncake import engine; assert engine.SUPPORT_EFA'
fi_info -p efa -t FI_EP_RDM
```

The EFA wheel expects a compatible AWS EFA userspace installation on the host and does not bundle `libfabric` or `libefa`. The current wheel is available only for x86_64. It is built without Mooncake EP/PG and the NVLink/MNNVL components, so use the standard Mooncake CUDA package for those features.

#### CUDA VMM limitations

These limitations apply whenever `MOONCAKE_PROTOCOL=efa`, including in the EFA Docker images.

The current libfabric EFA provider cannot transfer CUDA VMM-backed buffers. Until [libfabric issue #12853](https://github.com/ofiwg/libfabric/issues/12853) is resolved, apply these settings to both prefill and decode workers:

- Do not set `SGLANG_MOONCAKE_CUSTOM_MEM_POOL` to `NVLINK` or `BAREX`.
  `INTRA_NODE_NVLINK` is supported because it uses the default CUDA allocator.
- Do not enable `expandable_segments:True` in `PYTORCH_CUDA_ALLOC_CONF` or `PYTORCH_ALLOC_CONF`.
- Post-capture KV sizing is automatically disabled for the EFA protocol because
  its KV cache uses CUDA VMM allocations.
- Do not set `MC_FORCE_MNNVL` or `NCCL_MNNVL_ENABLE`; EFA is not an MNNVL transport.

SGLang validates the first two constraints at startup to avoid a later `fi_read` or `fi_write` failure from libfabric.

### IB Device Configuration

`--disaggregation-ib-device` supports the following formats when using the Mooncake backend:

1. Shared device list for all GPUs: `mlx5_0` or `mlx5_0,mlx5_1`
2. Per-GPU JSON mapping: `{"0": "mlx5_0,mlx5_1", "1": "mlx5_2,mlx5_3"}`
3. Path to a JSON file containing the same per-GPU mapping

Each JSON value uses the same comma-separated device list format as the shared configuration.

### Usage

### Llama Single Node

```bash
python -m sglang.launch_server \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --disaggregation-mode prefill \
  --port 30000 \
  --disaggregation-ib-device mlx5_roce0
python -m sglang.launch_server \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --disaggregation-mode decode \
  --port 30001 \
  --base-gpu-id 1 \
  --disaggregation-ib-device mlx5_roce0
python -m sglang_router.launch_router --pd-disaggregation --prefill http://127.0.0.1:30000 --decode http://127.0.0.1:30001 --host 0.0.0.0 --port 8000
```

### DeepSeek Multi-Node

```
/* Detailed source-code truncated for AI context efficiency. */
```
### Advanced Configuration

PD Disaggregation with Mooncake supports the following environment variables for fine-grained control over system behavior.

#### NVLink Transport Configuration
To enable NVLink transport for KV cache transfers with the mooncake backend (recommended for NVL72 deployments), set the following environment variables. Note that auxiliary data transfer will still use TCP as a temporary workaround.

```bash Command
export SGLANG_MOONCAKE_CUSTOM_MEM_POOL=NVLINK
export MC_FORCE_MNNVL=True
```

To utilize Intra-Node NVLink for KV cache transfers with the Mooncake backend (recommended for A100, H20, H100, etc.), set the following environment variables. Please note that auxiliary data still needs to be transferred via TCP.

```bash
export SGLANG_MOONCAKE_CUSTOM_MEM_POOL=INTRA_NODE_NVLINK
export MC_INTRANODE_NVLINK=true
```
The `SGLANG_MOONCAKE_CUSTOM_MEM_POOL` environment variable enables the custom memory pool. Supported values are `NVLINK` (or `True`), `BAREX`, and `INTRA_NODE_NVLINK`.

#### Prefill Server Configuration
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "33.3%"}} />
    <col style={{width: "33.3%"}} />
    <col style={{width: "33.3%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Variable</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`SGLANG_DISAGGREGATION_THREAD_POOL_SIZE`**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Controls the total number of worker threads for KVCache transfer operations per TP rank</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>A dynamic value calculated by <code>int(0.75 * os.cpu_count()) // 8</code>, which is limited to be larger than 4 and less than 12 to ensure efficiency and prevent thread race conditions</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`SGLANG_DISAGGREGATION_QUEUE_SIZE`**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Sets the number of parallel transfer queues. KVCache transfer requests from multiple decode instances will be sharded into these queues so that they can share the threads and the transfer bandwidth at the same time. If it is set to <code>1</code>, then we transfer requests one by one according to fcfs strategy</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`4`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`SGLANG_MOONCAKE_MAX_TRANSFER_BATCH_INDICES`**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Opt-in limit for the number of KV cache indices represented by one synchronous all-layer Mooncake transfer batch. Set it to a positive value to slice larger index arrays into ordered sub-batches before contiguous address ranges are formed. The custom-memory-pool layerwise path is unchanged.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>0</code> (disabled)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`SGLANG_DISAGGREGATION_BOOTSTRAP_TIMEOUT`**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Timeout (seconds) for receiving destination KV indices during request initialization</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`300`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong><code>SGLANG_DISAGGREGATION_BOOTSTRAP_ENTRY_CLEANUP_INTERVAL</code></strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Interval (seconds) between cleanups of bootstrap entries</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>120</code></td>
    </tr>
</tbody>
</table>

If a greater mean TTFT is acceptable, you can `export SGLANG_DISAGGREGATION_BOOTSTRAP_TIMEOUT=600` (10 minutes) to relax the timeout condition.
Please be aware that this setting will cause prefill instances to take a longer time to clean up the affected memory resources when a running decode node loses connection.

#### Decode Server Configuration
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "33.3%"}} />
    <col style={{width: "33.3%"}} />
    <col style={{width: "33.3%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Variable</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`SGLANG_DISAGGREGATION_HEARTBEAT_INTERVAL`**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Interval (seconds) between health checks to prefill bootstrap servers</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`5.0`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`SGLANG_DISAGGREGATION_HEARTBEAT_MAX_FAILURE`**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Consecutive heartbeat failures before marking prefill server offline</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`2`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**`SGLANG_DISAGGREGATION_WAITING_TIMEOUT`**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Timeout (seconds) for receiving KV Cache after request initialization</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`300`</td>
    </tr>
  </tbody>
</table>

If a greater mean TTFT is acceptable, you can `export SGLANG_DISAGGREGATION_WAITING_TIMEOUT=600` (10 minutes) to relax the timeout condition.


## Heterogeneous TP with GPU Staging Buffer

When prefill and decode use different tensor parallelism (TP) sizes (e.g., prefill TP=4, decode DP attention with TP=1), the KV cache memory layout differs between the two sides. The **GPU staging buffer** solves this by gathering KV head slices into a contiguous buffer on the prefill side, performing bulk RDMA transfer, then scattering into the correct KV cache pages on the decode side. This provides **2–5x throughput improvement** over the default per-token slice approach at high concurrency and matches homogeneous TP baselines within ~5%.

Enable the staging buffer when prefill and decode use **different TP sizes** with the **Mooncake** transfer backend. When both sides use the same TP size, staging is automatically bypassed even if enabled.

> **Note:** The staging buffer is designed for non-MLA models (e.g. GQA, MHA). MLA models (e.g. DeepSeek-V2/V3) should not enable this flag.

> **Note:** The staging buffer also runs on Intel XPU, tested with prefill TP 1 and decode TP 2 on the Mooncake backend. On XPU, Mooncake needs a build with `-DUSE_XPU=ON -DUSE_TENT=ON` and runs with `MC_USE_TENT=1`.

> **Note:** You can use different attention TP sizes for hybrid sliding-window models (e.g. `openai/gpt-oss-120b`) with Mooncake or NIXL. For unequal TP, both backends transfer the sliding-window KV by token and KV-head slice. The staging buffer carries only full-attention KV. Use `--pp-size 1` and leave `--enable-unified-memory` disabled for this configuration. MXFP8 KV cache is not supported for unequal-TP SWA transfer.

### Environment Variables

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "30%"}} />
    <col style={{width: "50%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Variable</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong><code>SGLANG_DISAGG_STAGING_BUFFER</code></strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable GPU staging buffer for heterogeneous TP KV transfer</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>False</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><strong><code>SGLANG_DISAGG_STAGING_POOL_SIZE_MB</code></strong></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Decode-side ring buffer pool total size in MB</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>4096</code></td>
    </tr>
  </tbody>
</table>

### Usage Example

```bash Command
# Set staging buffer environment variables on BOTH prefill and decode
export SGLANG_DISAGG_STAGING_BUFFER=1
export SGLANG_DISAGG_STAGING_POOL_SIZE_MB=4096

# Prefill with TP=4
python -m sglang.launch_server \
  --model-path $MODEL_PATH \
  --disaggregation-mode prefill \
  --port 30000 \
  --tp 4 \
  --trust-remote-code \
  --disaggregation-ib-device mlx5_1,mlx5_2

# Decode with TP=1 (or DP attention with effective attention TP=1)
python -m sglang.launch_server \
  --model-path $MODEL_PATH \
  --disaggregation-mode decode \
  --port 30001 \
  --tp 4 \
  --attn-dp-size 4 \
  --trust-remote-code \
  --disaggregation-ib-device mlx5_3,mlx5_4

# Router
python -m sglang_router.launch_router \
  --pd-disaggregation \
  --prefill http://127.0.0.1:30000 \
  --decode http://127.0.0.1:30001 \
  --host 0.0.0.0 --port 8000
```

## NIXL
### Requirements

Install via pip.

```bash
pip install nixl
```

Or build from source - may be required if you already have UCX installed.

```bash
git clone https://github.com/ai-dynamo/nixl.git
cd nixl
pip install . --config-settings=setup-args="-Ducx_path=/path/to/ucx"
```


### Usage

### Llama Single Node

```bash
python -m sglang.launch_server \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --disaggregation-mode prefill \
  --port 30000 \
  --disaggregation-transfer-backend nixl
python -m sglang.launch_server \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --disaggregation-mode decode \
  --port 30001 \
  --base-gpu-id 1 \
  --disaggregation-transfer-backend nixl
python -m sglang_router.launch_router --pd-disaggregation --prefill http://127.0.0.1:30000 --decode http://127.0.0.1:30001 --host 0.0.0.0 --port 8000
```

### DeepSeek Multi-Node

```
/* Detailed source-code truncated for AI context efficiency. */
```

### Advanced Configuration

#### NIXL Backend Selection

By default, NIXL uses the **UCX** backend for KV cache transfers. You can select a different NIXL plugin backend depending on your infrastructure using the environment variable `SGLANG_DISAGGREGATION_NIXL_BACKEND`.

Example: `export SGLANG_DISAGGREGATION_NIXL_BACKEND=LIBFABRIC`

**Available backends:** UCX (default), LIBFABRIC, or any installed NIXL plugin.

Example usage:
```bash
export SGLANG_DISAGGREGATION_NIXL_BACKEND=LIBFABRIC
python -m sglang.launch_server \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --disaggregation-mode prefill \
  --disaggregation-transfer-backend nixl \
  --port 30000
```

#### UCX device selection

For NVIDIA CUDA and AMD ROCm deployments using NIXL UCX, `--disaggregation-ib-device` accepts a shared HCA list or a per-GPU JSON/file mapping. Mapping keys are process-visible GPU IDs; use HCA names without port suffixes, such as `mlx5_0`.

A non-empty `UCX_NET_DEVICES` takes precedence over this CLI option. SGLang leaves the environment variable unchanged and skips the CLI mapping, including per-GPU mappings, with a warning. This preserves interfaces such as `lo` in an existing configuration like `rdma0:1,rdma4:1,lo`, which some RoCE hosts need for NIXL's self-endpoint.

To use per-GPU CLI selection, unset `UCX_NET_DEVICES`; keep it configured on hosts that require the loopback entry. An explicit `device_list` in `SGLANG_DISAGGREGATION_NIXL_BACKEND_PARAMS` is left unchanged and still overrides `UCX_NET_DEVICES`; do not set it if you rely on the environment's complete device list.

## ASCEND

### Usage

Use ascend backend with [memfabric_hybrid](https://gitcode.com/Ascend/memfabric_hybrid) and ASCEND_MF_STORE_URL being set

```bash Command
pip install memfabric-hybrid==1.0.0
export ASCEND_MF_STORE_URL="tcp://xxx.xx.xxx.xxx:xxxx"
```
Use mooncake backend, more details can be found in mooncake section.
```bash
export ENABLE_ASCEND_TRANSFER_WITH_MOONCAKE=true
```
ASCEND_NPU_PHY_ID need to be set in container env
```bash
export ASCEND_NPU_PHY_ID=xxx
```


### MIMO Single Node

#### prefill

```
/* Detailed source-code truncated for AI context efficiency. */
```

#### decode

```
/* Detailed source-code truncated for AI context efficiency. */
```


#### router

```bash
python -m sglang_router.launch_router \
    --pd-disaggregation \
    --prefill http://127.0.0.1:10000 \
    --decode  http://127.0.0.1:10001 \
    --host 127.0.0.1 \
    --port 9903 \
    --health-check-interval-secs 3600 \
    --mini-lb \
```

### DeepSeek Multi-Node

#### Environment
```bash
echo performance | tee /sys/devices/system/cpu/cpu*/cpufreq/scaling_governor
sysctl -w vm.swappiness=0
sysctl -w kernel.numa_balancing=0
sysctl -w kernel.sched_migration_cost_ns=50000

export SGLANG_SET_CPU_AFFINITY=1

unset https_proxy
unset http_proxy
unset HTTPS_PROXY
unset HTTP_PROXY
unset ASCEND_LAUNCH_BLOCKING

source /usr/local/Ascend/ascend-toolkit/set_env.sh
source /usr/local/Ascend/nnal/atb/set_env.sh
export LD_LIBRARY_PATH=/usr/local/Ascend/ascend-toolkit/latest/opp/vendors/customize/op_api/lib/:${LD_LIBRARY_PATH}
export PATH=/usr/local/Ascend/8.5.0/compiler/bishengir/bin:$PATH

export PYTORCH_NPU_ALLOC_CONF=expandable_segments:True
export STREAMS_PER_DEVICE=32
# IP set to p first node ip
export ASCEND_MF_STORE_URL="tcp://XXXXXX:24670"

# p node IP
P_IP=('XXXXX')
# D node IP
D_IP=('XXXXX')


# enable mlapo
export SGLANG_NPU_USE_MLAPO=1
export SGLANG_USE_FIA_NZ=1
export ENABLE_MOE_NZ=1
#export SGLANG_NPU_USE_MULTI_STREAM=1

LOCAL_HOST1=`hostname -I|awk -F " " '{print$1}'`
LOCAL_HOST2=`hostname -I|awk -F " " '{print$2}'`
echo "${LOCAL_HOST1}"
echo "${LOCAL_HOST2}"
```


#### prefill

```bash
MODEL_PATH=/path/to/deepseekr1_w4a8_pertoken
for i in "${!P_IP[@]}";
do
    if [[ "$LOCAL_HOST1" == "${P_IP[$i]}" || "$LOCAL_HOST2" == "${P_IP[$i]}" ]];
    then
        echo "${P_IP[$i]}"
        export HCCL_BUFFSIZE=2600
        export HCCL_SOCKET_IFNAME=lo
        export GLOO_SOCKET_IFNAME=lo
        python -m sglang.launch_server --model-path ${MODEL_PATH}  --disaggregation-mode prefill --host ${P_IP[$i]} \
        --port 8000 --disaggregation-bootstrap-port $((8998+$i)) --trust-remote-code --nnodes 1 --node-rank 0 \
        --tp-size 16 --mem-fraction-static 0.7 --attention-backend ascend --device npu --quantization modelslim \
        --disaggregation-transfer-backend ascend --max-running-requests 32 --context-length 8192  --disable-radix-cache \
        --chunked-prefill-size -1 --max-prefill-tokens 10240 --moe-a2a-backend deepep --deepep-mode normal \
        --speculative-algorithm NEXTN --speculative-num-steps 1 --speculative-eagle-topk 1 --speculative-num-draft-tokens 2  \
        --attn-dp-size 8 --disable-shared-experts-fusion --dtype bfloat16
        NODE_RANK=$i
        break
    fi
done
```

#### decode

```bash
MODEL_PATH=/path/to/deepseekr1_w4a8_pertoken

for i in "${!D_IP[@]}";
do
    if [[ "$LOCAL_HOST1" == "${D_IP[$i]}" || "$LOCAL_HOST2" == "${D_IP[$i]}" ]];
    then
        echo "${D_IP[$i]}"
        export SGLANG_ENABLE_OVERLAP_PLAN_STREAM=1
        export HCCL_BUFFSIZE=900
        export SGLANG_DEEPEP_NUM_MAX_DISPATCH_TOKENS_PER_RANK=112
        export TASK_QUEUE_ENABLE=1
        export HCCL_SOCKET_IFNAME=data0.3001
        export GLOO_SOCKET_IFNAME=data0.3001
        python -m sglang.launch_server --model-path ${MODEL_PATH} --disaggregation-mode decode --host ${D_IP[$i]} \
        --port 8001 --trust-remote-code --nnodes 1 --node-rank 0 --tp-size 16 --attn-dp-size 16 \
        --mem-fraction-static 0.8 --max-running-requests 448 --attention-backend ascend --device npu --quantization modelslim \
        --moe-a2a-backend deepep --deepep-mode low_latency --enable-dp-lm-head \
        --cuda-graph-bs-decode 2 4 6 8 10 12 14 16 18 20 22 24 26 28 --disaggregation-transfer-backend ascend --watchdog-timeout 9000 --context-length 8192 \
        --speculative-algorithm NEXTN --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4 --disable-shared-experts-fusion --dtype bfloat16 --tokenizer-worker-num 4 \
       	--load-balance-method round_robin
        NODE_RANK=$i
        break
    fi
done
```


#### router

```bash
python -m  sglang_router.launch_router --prefill ${P_IP}:8000 \
--decode ${D_IP}:8001 \
--host ${D_IP} --port 6688 \
--pd-disaggregation \
--health-check-interval-secs 3600 \
```

---

### Docs Advanced Features Pipeline Parallelism (`docs/docs/advanced_features/pipeline_parallelism.mdx`)

---
title: "Pipeline Parallelism for Long Context"
metatags:
    description: "SGLang pipeline parallelism: reduce TTFT for ultra-long sequences, dynamic chunking, async P2P communication, multi-node deployment."
---
## Why Pipeline Parallelism?

As Large Language Models (LLMs) scale toward trillion-parameter architectures and "infinite" context windows, the underlying serving infrastructure must evolve toward more granular, cross-node parallelization strategies. While KV cache techniques effectively mitigate redundant computation, they cannot circumvent the prohibitive Time to First Token (TTFT) inherent in ultra-long sequences with extremely large initial Input Token Length (ITL). Although Tensor Parallelism (TP) remains the conventional approach for intra-node scaling, it frequently encounters communication bottlenecks during multi-node deployments. On the other hand, pipeline parallelism only requires cross-node communication at the boundaries of each pipeline stage, which can achieve better computation-communication overlap compared to a large TP. Therefore, it is also a promising parallelization strategy for improving throughput.

Detailed analysis can be found in this [blog](https://lmsys.org/blog/2026-01-15-chunked-pipeline/).

## Implementation Refactoring based on Async Communication
With Dynamic Chunked Prefill, pipeline parallelism has the potential to reduce the TTFT of long-context inputs. For each request, its input tokens can be partitioned into multiple chunks, each no longer than the chunked prefill size. Different chunks of the same request can be processed simultaneously by different nodes, thus parallelizing the processing and reducing TTFT. SGLang has supported Pipeline Parallelism (#5724) for some time and made it compatible with the PD Disaggregation feature (#8846), but the implementation was not perfect and had significant room for performance improvements.

To eliminate this performance hazard, SGLang implements a Micro-batching Event Loop with non-blocking asynchronous peer-to-peer (P2P) communication to overlap GPU computation with CPU metadata processing and PP communication. This ensures that while one micro-batch is being computed on the GPU, the next one is already being prepared and moved into position effectively, ensuring the pipeline remains as saturated as possible. This approach was first proposed in #7979 and has been redesigned and included in #11852.

The key mechanisms of the implementation include:

* **Decoupled Sync/Async Logic in the Event Loop:** The scheduler uses `async_send` in `_pp_send_pyobj_to_next_stage`. Instead of waiting for a transfer to complete, it returns a `P2PWork` handle. The actual synchronization (`P2PWork.work.wait()`) is deferred until `_pp_commit_comm_work` is called, allowing the CPU to perform other work—like scheduling the next batch or processing metadata—while data is in flight.
* **Multi-Stream Execution:** In addition to the main `default_stream`, which serves as the synchronization stream, SGLang utilizes dedicated `forward_stream` and `copy_stream` to execute forward pass GPU computation and Data-to-Host (D2H) memory transfers separately for better overlapping. While `_pp_launch_batch` is executing the current micro-batch on the GPU for the current stage, the CPU processes the previous micro-batch's results using `_pp_process_batch_result`.

## Guidance about Dynamic Chunking

### Why Dynamic Chunking
Chunked prefill with a fixed size can cause bubbles in the pipeline, especially when the pp size is large. The main reason behind this phenomenon is that the model has a non-uniform running time, even though each chunk size is identical (brought by the Transformer structure). The larger the prefix sequence length, the longer the running time of the chunk. And these bubbles will be propagated to the next stage, and will significantly degrade the scale efficiency of larger pp ranks.

To address this issue, SGLang introduces a dynamic chunking mechanism to predict the optimal size for the next chunk such that it satisfies this condition:

Runtime(L + Next Chunk Size) - Runtime(L) = Runtime(Initial Chunk Size)

where ***L*** denotes the Prefix Sequence Length. By profiling a series of requests with different ITLs, we model the cumulative runtime as a quadratic function of sequence length. Using this model, we solve the optimal next chunk size for any given prefix length ***L***. Since the computation complexity of the Attention mechanism scales with ***L***, the next chunk size will be progressively reduced as ***L*** grows to maintain an aligned chunk execution time across pipeline stages.

Based on this method, the scheduler can predict and dynamically reduce the chunk size during runtime to minimize the bubbles caused by the stage misalignment. To be noticed, the scheduler does not use the raw predicted value. To facilitate efficient KVCache memory management and ensure affinity with hardware execution efficiency, the value is aligned downward to the nearest multiple of max(`--page-size`, 64).


### Chunked Prefill Size and Smoothing Factor

When `--enable-dynamic-chunking` is enabled, each chunk size of a sequence is determined dynamically based on the quadratic model that predicts the next chunk size based on the estimated runtime of the initial chunk length. In this case, we use `--chunked-prefill-size` to set up the initial chunk size. When switching to the dynamic chunking mode, the initial chunk size (`--chunked-prefill-size`) should be set to a larger value comparable to the original chunked prefill size, so that there won't be too many chunks.

**`SGLANG_DYNAMIC_CHUNKING_SMOOTH_FACTOR`** is an environmental variable that controls the smoothing factor for the dynamic chunking algorithm, defaulting to 0.75. It determines how much the chunk size can change during the prefill phase. A larger value means a more aggressive chunk size change, which may lead to better performance but also to greater chunk size changes (the chunk size at the end may become very small, which could lead to performance degradation) and more total chunks. When it is set to 1, the chunk size will be adjusted strictly based on the aforementioned quadratic model that predicts the next chunk size. A smaller value means a more conservative chunk size change, which may lead to smaller chunk size changes and fewer total chunks. When it is set to 0, the chunk size will not be adjusted dynamically, so it is identical to the traditional way with a fixed chunked prefill size.

Due to the variation in hardware, models, and target workloads, a static configuration is seldom optimal across all scenarios. Consequently, achieving peak performance necessitates a degree of hyperparameter tuning when switching to the dynamic chunking mode.

**Tuning Guidance for Dynamic Chunked Prefill**

* **Step 1 \- Iterate to find the optimal fixed chunked prefill size for the targeted PP size**: Different PP sizes for targeted ITL may have different optimal chunked prefill sizes. Therefore, users should iterate to obtain the baseline according to the available resources for scaling.
* **Step 2 \- Initial Chunk Size Selection for Dynamic Chunking**: Set the initial size to 2× or 3× the optimal fixed chunked prefill size. This reduces the total number of chunks and prevents "tail chunks" from underutilizing hardware. To maintain efficiency for extremely large Input Token Lengths (ITL), the dynamic predictor automatically ensures subsequent chunks are at least 1/4 of this initial size. In addition, it is recommended to use a larger initial chunk size (e.g., 4× the optimal fixed chunked prefill size) for such cases as well.
* **Step 3 \- Smooth Factor Adjustment**: This factor controls how strictly the chunk size adjusts the prediction given by the quadratic performance fitting model.
  * 1.0: Follows the model strictly.
  * **0.6 – 0.85 (Recommended)**: Typical range for the best balance between dynamic scaling and hardware stability. Through experiments, we find that a range between 0.6 and 0.85 typically yields the best performance for dynamic chunking.
  * 0: Disables dynamic adjustment, reverting to traditional fixed-size chunking.
* **Another small optimization tip:** Put the larger partition in the higher PP rank when the layers are not evenly divisible across ranks. It can increase the GPU utilization when a larger PP rank is waiting for the previous stage’s result, hence reducing the bubbles on higher PP ranks. If we take DeepSeek-V3.1 as an example, `SGLANG_PP_LAYER_PARTITION=15,15,15,16` usually performs better than `16,15,15,15`.

## Best Practice for Long Context

### Tuning the Chunked Prefill Size
Optimizing the chunked prefill size is crucial for balancing pipeline efficiency and resource utilization. The ideal size depends on factors including model architecture, hardware configuration, and typical input lengths. We recommend starting with a small chunk size, such as 4K, and gradually increasing it until you find the optimal size for your specific use case (Different targeted ITL and PP Sizes may have different optimal chunked prefill sizes. Therefore, users should iterate to obtain the baseline according to the available resources for scaling). Alternatively, you can analyze the hardware capacity and determine the optimal chunk size based on the roofline model.

### Enable Dynamic Chunking and Adjust Smoothing Factor for Ultra-long ITL
SGLang also offers a dynamic chunking solution that could further improve performance. This feature is currently an experimental feature that requires a certain amount of tuning experimentation and may not be suitable for all workloads. In addition, fine-tuning the smoothing factor can help optimize performance for specific workloads and model characteristics.

### Case Study on NVIDIA H20

When evaluating pipeline parallelism with fixed chunked prefill sizes from 2K to 16K, experiment results show that a 4K chunk size delivered optimal prefill TTFT performance for the DeepSeek-V3.1, and a 6K chunk size delivered optimal prefill TTFT performance for the Qwen3-235B-A22B-FP8.

When enabling dynamic chunking, we first scale the optimal fixed chunked prefill size by a factor of 3 as the initial chunk size. Through experimentation, we found that a multiplier of 2-3 provides an appropriate balance—avoiding excessive initial pipeline bubbles while ensuring that subsequent chunks don't become too small as context length increases. With the default dynamic chunking smoothing factor of 0.75, we performed parameter tuning and determined that a value of 0.65 works optimally with the 12K initial chunk size for the DeepSeek-V3.1, while a value of 0.8 works optimally with the 18K initial chunk size for the Qwen3-235B-A22B-FP8.

#### DeepSeek-V3.1 with 128K Input Token Length
```bash Command
# prefill node 0 (fixed chunked prefill size)
python3 -m sglang.launch_server \
  --model-path deepseek-ai/DeepSeek-V3.1 --trust-remote-code \
  --nnodes 4 --node-rank 0 --tp 8 --pp-size 4 \
  --port 30000 --dist-init-addr <MASTER_NODE_IP> \
  --disable-radix-cache --mem-fraction-static 0.8  \
  --attention-backend fa3 --host 0.0.0.0 --watchdog-timeout 3600 \
  --max-running-requests 128 --chunked-prefill-size 4096
```

```bash Command
# prefill node 0 (with dynamic chunking)
export SGLANG_DYNAMIC_CHUNKING_SMOOTH_FACTOR=0.65
python3 -m sglang.launch_server \
  --model-path deepseek-ai/DeepSeek-V3.1 --trust-remote-code \
  --nnodes 4 --node-rank 0 --tp 8 --pp-size 4 \
  --port 30000 --dist-init-addr <MASTER_NODE_IP> \
  --disable-radix-cache --mem-fraction-static 0.8  \
  --attention-backend fa3 --host 0.0.0.0 --watchdog-timeout 3600 \
  --max-running-requests 128 --chunked-prefill-size 12288 --enable-dynamic-chunking
```

#### Qwen3-235B-A22B-FP8 with 128K Input Token Length
```bash Command
# prefill node 0 (fixed chunked prefill size)
python3 -m sglang.launch_server \
  --model-path Qwen/Qwen3-235B-A22B-FP8 --trust-remote-code \
  --nnodes 4 --node-rank 0 --tp 4 --pp-size 8 \
  --port 30000 --dist-init-addr <MASTER_NODE_IP> \
  --disable-radix-cache --mem-fraction-static 0.8  \
  --attention-backend fa3 --host 0.0.0.0 --watchdog-timeout 3600 \
  --max-running-requests 128 --chunked-prefill-size 6144
```

```bash Command
# prefill node 0 (with dynamic chunking)
export SGLANG_DYNAMIC_CHUNKING_SMOOTH_FACTOR=0.8
python3 -m sglang.launch_server \
  --model-path Qwen/Qwen3-235B-A22B-FP8 --trust-remote-code \
  --nnodes 4 --node-rank 0 --tp 4 --pp-size 8 \
  --port 30000 --dist-init-addr <MASTER_NODE_IP> \
  --disable-radix-cache --mem-fraction-static 0.8  \
  --attention-backend fa3 --host 0.0.0.0 --watchdog-timeout 3600 \
  --max-running-requests 128 --chunked-prefill-size 18432 --enable-dynamic-chunking
```

Note: `--disable-radix-cache` is enabled only for reproducible benchmarking purposes. It is not recommended to use it in production.

## Best Practice for Pipeline Parallelism with PD Disaggregation
To be added. Stay tuned for the latest updates on Pipeline Parallelism with PD Disaggregation.

---

### Docs Advanced Features Prefill Cp (`docs/docs/advanced_features/prefill_cp.mdx`)

---
title: "Prefill Context Parallelism"
---

Prefill context parallelism (CP) distributes the tokens of a prompt across an attention CP group. Each rank computes attention and, for models with an indexer, indexer operations for its local queries, while all-gather on the KV cache makes the required keys and values available. This lets multiple GPUs share the work of processing a long prompt.

To compare prefill CP with other common parallelism strategy: Tensor parallelism (TP) splits attention heads and weights, [Decode context parallelism (DCP)](https://docs.sglang.io/docs/advanced_features/dcp) shards the KV cache and its attention workload during decode, while prefill CP (PCP) splits prompt tokens across GPUs. Note that PCP and DCP are independent optimizations for different phases of inference.

## Why prefill context parallelism?

Prefill CP offers three benefits:

- It partitions work that would otherwise be repeated across ranks, such as indexer computation in DSA models and the DeepSeek V4 series.
- It combines naturally with KV-cache sharding to reduce per-rank cache memory. Layer-wise sharding is available through DSA cache LayerSplit; additional sharding techniques are under development.
- Combined with expert parallelism (EP), it can reduce communication time by using all-to-all token dispatch and combine instead of TP all-reduce. The benefit depends on the workload and interconnect.

## Architecture

### Strategy interface

`ContextParallelStrategy` separates token-layout policy from model execution and attention kernels. Server argument resolution initializes one strategy per process. Per-forward state lives in `ForwardBatch.attn_cp_metadata`, rather than in the model's token-layout logic.

### Zigzag strategy

For a CP group of size `C`, split each request's newly extended tokens into `2C` contiguous blocks. Rank `r` receives block `r` and block `2C - 1 - r`. The split restarts for every request in a batch.

For example, with CP=4 and 16 new tokens, each block has two tokens:

```mermaid
flowchart TB
    S["One request, original token order<br/>B0: 0–1 · B1: 2–3 · B2: 4–5 · B3: 6–7<br/>B4: 8–9 · B5: 10–11 · B6: 12–13 · B7: 14–15"]
    S --> R0["Rank 0<br/>B0 + B7<br/>tokens 0–1, 14–15"]
    S --> R1["Rank 1<br/>B1 + B6<br/>tokens 2–3, 12–13"]
    S --> R2["Rank 2<br/>B2 + B5<br/>tokens 4–5, 10–11"]
    S --> R3["Rank 3<br/>B3 + B4<br/>tokens 6–7, 8–9"]
```

Pairing an early, cheaper block with a late, more expensive block balances causal attention work while retaining contiguous query blocks. Lengths need not divide evenly: early blocks receive the remainder, and communication buffers are padded as needed.

The metadata records separate query and KV lengths for the early and late blocks, including any cached prefix. Each block therefore attends to the correct causal history, not just the other tokens assigned to its rank.

### Interleave strategy

For CP size `C`, rank `r` receives flattened token indices `r, r+C, r+2C, ...`. The index runs across the batch's newly extended tokens; it does not reset at request boundaries. Position IDs keep their original values.

With CP=4 and 16 new tokens:

```mermaid
flowchart TB
    S["Flattened new tokens in batch order<br/>0, 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15"]
    S --> R0["Rank 0<br/>0, 4, 8, 12"]
    S --> R1["Rank 1<br/>1, 5, 9, 13"]
    S --> R2["Rank 2<br/>2, 6, 10, 14"]
    S --> R3["Rank 3<br/>3, 7, 11, 15"]
```

This gives each rank queries spread across the context. For a batch containing requests of lengths 5 and 3, rank 0 owns flattened indices 0 and 4, while rank 1 owns indices 1 and 5; index 5 is the first new token of the second request. Per-request sharding metadata preserves those boundaries and each query's causal extent.

### Attention backend integration

| Path | Integration |
| --- | --- |
| Zigzag with FlashAttention | Gather and reorder new KV; execute attention for the early and late query blocks with their respective sequence lengths. |
| Zigzag with `trtllm_mha` | Materialize KV, build zigzag page tables, and execute a combined variable-length attention call. |
| Interleave with DSA | Shard query/indexer metadata by request, gather indexer keys and MLA KV as required, and execute sparse attention in the backend. |
| DeepSeek V4 interleave | Uses model-specific sparse-attention integration; the CP regression suite includes DeepSeek-V4-Flash on B200. Do not infer its backend requirements from the dense zigzag path. |

The CP and attention-backend compatibility matrix is being expanded, with support for more combinations planned.

## Compositions

### Prefill CP × TP, DP, and EP

Attention TP splits heads within each CP partition; attention DP separates request batches. Dense FFNs and MoE layers can use a different layout, bridged by the layer boundaries between stages (see [Layer boundaries](/docs/developer_guide/layer_boundary)). The Qwen3 example in [Usage and Examples](#usage-and-examples) combines CP=2 with attention TP=2 and EP=4. For interleave DSA on DeepSeek V3.2 and the GLM-5 series, keep DP=1 and use the resolved attention CP=TP topology.

### Prefill CP × pipeline parallelism

The eager runner preserves CP-local hidden states between pipeline stages and gathers on the final stage. PP can place stages on different nodes while keeping each DSA attention CP group within one node; it does not remove the single-machine DSA CP restriction.

### Prefill CP × speculative decoding

Prefill CP can coexist with supported speculative-decoding configurations. The CP runner handles aligned speculative hidden-state inputs and gathers supported auxiliary outputs.

### Prefill CP × CUDA graphs

The shared CP breakable-prefill-graph path currently requires `zigzag`, the `trtllm_mha` prefill backend, PP=1, and attention CP size equal to TP size. It uses CP-local static input buffers and selects capture buckets large enough for each rank's padded input. Support for combining other attention backends with prefill CP and Breakable CUDA Graph is under development.

### Prefill CP × PD disaggregation and DSA cache LayerSplit

In supported DSA deployments, `--enable-dsa-cache-layer-split` distributes GPU KV/indexer cache layers across CP ranks to reduce per-rank cache memory. Each rank owns a range of layers and uses scratch storage for remote-layer data. This is layer-wise cache ownership, separate from the interleave token assignment used for computation, and is not applied to draft workers.

LayerSplit requires a PD prefill worker (`--disaggregation-mode prefill`), `--enable-prefill-cp --cp-strategy interleave`, and PP=1. It currently supports the `mooncake` and `mooncake_tcp` transfer backends. Do not enable LayerSplit on decode or non-PD workers; the decode side receives full cache shards through PD transfer. Use the [PD disaggregation guide](https://docs.sglang.io/docs/advanced_features/pd_disaggregation) and model-specific launch recipes to configure both sides of the transfer; enabling prefill CP alone does not configure a PD deployment.

## Usage and Examples

Use NVIDIA CUDA GPUs and select a strategy supported by your model and attention backend. The examples below target a single Linux host with Hopper GPUs and an SGLang version that includes the selected backend.

| Argument | Default | Description |
| --- | --- | --- |
| `--enable-prefill-cp` | `False` | Enable context-parallel prefill. |
| `--cp-strategy` | Unset | Required when enabling prefill CP. Choose `zigzag` or `interleave`. |
| `--attn-cp-size` | `1` | Number of ranks in an attention CP group. Use a value greater than 1 to distribute work; model-specific argument resolution may adjust it. |

CP subdivides the existing TP world; it does not add another GPU multiplier. With attention DP enabled, the attention topology is:

```text
TP world size = attention DP size × attention CP size × attention TP size

Example: --tp 4 --dp 1 --attn-cp-size 2
         → one attention DP group, CP=2, attention TP=2
```

The server requires `--tp` to be divisible by `--dp × --attn-cp-size`. The attention layout does not by itself specify the dense FFN or MoE layout; those use their own parallelism settings.

<Warning>
For DSA models, such as the GLM-5 series and DeepSeek V3.2, use `interleave`; `zigzag` is currently unavailable. Do not use a smaller `--attn-cp-size` to request hybrid attention TP/CP for DSA models. Broader compatibility is planned for future support.
</Warning>

### Zigzag example: GQA with attention TP and CP

This Qwen3 configuration uses four Hopper GPUs, with attention TP=2, CP=2, and EP=4 for the MoE layers. The model is a Hugging Face repository ID passed to `--model-path`.

```bash
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-30B-A3B-FP8 \
  --tp 4 \
  --ep 4 \
  --attn-cp-size 2 \
  --enable-prefill-cp \
  --cp-strategy zigzag \
  --attention-backend fa3
```

### Interleave example: DSA

This GLM-5.2 configuration uses eight H200 GPUs with attention CP=8 and attention TP=1. The DSA backend is selected automatically for this model; the command makes that choice explicit.

```bash
python -m sglang.launch_server \
  --model-path zai-org/GLM-5.2-FP8 \
  --tp 8 \
  --attn-cp-size 8 \
  --enable-prefill-cp \
  --cp-strategy interleave \
  --attention-backend dsa \
  --trust-remote-code \
  --mem-fraction-static 0.85
```

For model-specific deployment combinations, see [context parallelism in the GLM-5.3 cookbook](https://docs.sglang.io/cookbook/autoregressive/GLM/GLM-5.3#3-5-context-parallelism).

## References

- [CP strategies and metadata](https://github.com/sgl-project/sglang/tree/main/python/sglang/srt/layers/cp): strategy interface, zigzag/interleave layouts, padding, and graph helpers.
- [Prefill Context Parallelism Roadmap](https://github.com/sgl-project/sglang/issues/21788).
- [Prefill Context Parallelism Refactor Design](https://github.com/sgl-project/sglang/issues/27252).

---

### Docs Advanced Features Quantization (`docs/docs/advanced_features/quantization.mdx`)

---
title: "Quantization"
metatags:
    description: "SGLang quantization: FP8, FP4, AWQ, GPTQ, ModelOpt. Offline and online quantization methods for efficient LLM inference."
---
SGLang supports various quantization methods, including offline quantization and online dynamic quantization.

Offline quantization loads pre-quantized model weights directly during inference. This is required for quantization methods
such as GPTQ and AWQ, which collect and pre-compute various statistics from the original weights using the calibration dataset.

Online quantization dynamically computes scaling parameters—such as the maximum/minimum values of model weights—during runtime.
Like NVIDIA FP8 training's [delayed scaling](https://docs.nvidia.com/deeplearning/transformer-engine/user-guide/examples/fp8_primer.html#Mixed-precision-training-with-FP8) mechanism, online quantization calculates the appropriate scaling factors
on-the-fly to convert high-precision weights into a lower-precision format.

**Note: For better performance, usability and convenience, offline quantization is recommended over online quantization.**

If you use a pre-quantized model, **do not add `--quantization` to enable online quantization at the same time**.
For popular pre-quantized models, please visit [Unsloth](https://huggingface.co/unsloth), [NVIDIA ModelOpt](https://huggingface.co/collections/nvidia/inference-optimized-checkpoints-with-model-optimizer)
or [NeuralMagic](https://huggingface.co/collections/neuralmagic) collections on HF for some
popular quality validated quantized models. Quantized models must be validated via benchmarks post-quantization
to guard against abnormal quantization loss regressions.

## Platform Compatibility

The following table summarizes quantization method support across NVIDIA and AMD GPUs, Ascend NPUs.

<table>
  <thead>
    <tr>
      <th>Method</th>
      <th>NVIDIA GPUs</th>
      <th>AMD GPUs (MI300X/MI325X/MI350X)</th>
      <th>Ascend NPUs (A2/A3 Series, 950PR/DT Series)</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>fp8</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>WIP</td>
      <td>Aiter or Triton backend on AMD</td>
    </tr>
    <tr>
      <td><code>mxfp4</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>Yes (950PR/DT Series)</td>
      <td>On GPU: requires CDNA3/CDNA4 with MXFP support (uses Aiter). On Ascend NPU (950PR/DT Series): W4A4 MXFP4 for Qwen3 dense and MoE LLMs (MXFP4 weights + activations) — dense models support online dual-level MXFP4; offline <code>W4A4_MXFP4</code> dense and MoE checkpoints (single-level) are auto-detected via <code>modelslim</code>. On Intel GPUs (XPU): W4A16 MoE experts on Xe2/BMG via <code>sgl-kernel-xpu</code>, enabled automatically with <code>--device xpu</code> (see <a href="../hardware-platforms/xpu">Intel GPUs (XPU)</a>)</td>
    </tr>
    <tr>
      <td><code>mxfp8</code></td>
      <td>No</td>
      <td>No</td>
      <td>Yes (950PR/DT Series for Diffusion, LLM Dense Linear and LLM MoE)</td>
      <td>Ascend NPU only; online + offline MXFP8 for Diffusion models (e.g., Wan2.2), LLM Dense Linear, and LLM MoE (FusedMoE, e.g. Qwen3-30B-A3B) on 950PR/DT Series; uses CANN <code>npu_dynamic_mx_quant</code> / <code>npu_quant_matmul</code> (dense) and <code>npu_grouped_matmul_swiglu_quant_v2</code> / <code>npu_grouped_matmul</code> (MoE) kernels</td>
    </tr>
    <tr>
      <td><code>mxfp_w4a8</code></td>
      <td>No</td>
      <td>No</td>
      <td>Yes (950PR/DT Series)</td>
      <td>Ascend NPU only; online W4A8 for Qwen3 dense LLM (MXFP4 weights + MXFP8 activations) on 950PR/DT Series; offline <code>W4A8_MXFP</code> dense and MoE checkpoints are auto-detected via <code>modelslim</code></td>
    </tr>
    <tr>
      <td><code>blockwise_int8</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>No</td>
      <td>Triton-based, works on both platforms</td>
    </tr>
    <tr>
      <td><code>w8a8_int8</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>No</td>
      <td></td>
    </tr>
    <tr>
      <td><code>w8a8_fp8</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>No</td>
      <td>Aiter or Triton FP8 on AMD</td>
    </tr>
    <tr>
      <td><code>awq</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>Yes</td>
      <td>Uses a JIT-compiled CUDA kernel on NVIDIA, Triton dequantize on AMD. Uses CANN kernels on Ascend</td>
    </tr>
    <tr>
      <td><code>gptq</code></td>
      <td>No</td>
      <td>No</td>
      <td>Yes</td>
      <td>Removed on NVIDIA and AMD GPUs — use <code>gptq_marlin</code> instead. Uses CANN kernels on Ascend. Still supported on Intel CPUs with AMX</td>
    </tr>
    <tr>
      <td><code>compressed-tensors</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>Partial</td>
      <td>Aiter paths for FP8/MoE on AMD. Uses CANN kernels on Ascend, <code>FP8</code> not supported yet</td>
    </tr>
    <tr>
      <td><code>quark</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>No</td>
      <td>AMD Quark quantization; Aiter GEMM paths on AMD</td>
    </tr>
    <tr>
      <td><code>auto-round</code></td>
      <td>Yes</td>
      <td>Yes</td>
      <td>Partial</td>
      <td>Platform-agnostic (Intel auto-round). Uses CANN kernels on Ascend</td>
    </tr>
    <tr>
      <td><code>quark_int4fp8_moe</code></td>
      <td>No</td>
      <td>Yes</td>
      <td>No</td>
      <td>AMD-only; online INT4-to-FP8 MoE quantization (CDNA3/CDNA4)</td>
    </tr>
    <tr>
      <td><code>awq_marlin</code></td>
      <td>Yes</td>
      <td>No</td>
      <td>No</td>
      <td>Marlin kernels are CUDA-only</td>
    </tr>
    <tr>
      <td><code>gptq_marlin</code></td>
      <td>Yes</td>
      <td>No</td>
      <td>No</td>
      <td>Marlin kernels are CUDA-only</td>
    </tr>
    <tr>
      <td><code>gguf</code></td>
      <td>Yes</td>
      <td>No</td>
      <td>Yes</td>
      <td>CUDA kernels in sgl-kernel; Ascend uses CPU pre-dequantization at load time</td>
    </tr>
    <tr>
      <td><code>modelopt</code> / <code>modelopt_fp8</code></td>
      <td>Yes (Hopper/SM90+)</td>
      <td>No</td>
      <td>No</td>
      <td><a href="https://github.com/NVIDIA/Model-Optimizer">NVIDIA ModelOpt</a>; requires NVIDIA hardware</td>
    </tr>
    <tr>
      <td><code>modelopt_fp4</code></td>
      <td>Yes (SM80-SM90 via Marlin; SM100+ native FP4)</td>
      <td>No</td>
      <td>No</td>
      <td><a href="https://github.com/NVIDIA/Model-Optimizer">NVIDIA ModelOpt</a>; use Marlin W4A16 fallback on Ampere/Hopper and native FP4 backends on Blackwell; supports load-time BF16/FP16/FP8 MoE conversion with per-tensor FP32 activation scales</td>
    </tr>
    <tr>
      <td><code>nvfp4_online</code></td>
      <td>Yes (Blackwell/SM100 or SM103)</td>
      <td>No</td>
      <td>No</td>
      <td>Online MoE-only NVFP4 weight quantization with per-token FP32 activation scales for BF16/FP16/FP8 checkpoints; use <code>modelopt_fp4</code> for per-tensor FP32 activation scales; requires <code>flashinfer_trtllm</code> or <code>flashinfer_trtllm_routed</code></td>
    </tr>
    <tr>
      <td><code>petit_nvfp4</code></td>
      <td>No</td>
      <td>Yes (MI250/MI300X/MI325X)</td>
      <td>No</td>
      <td>Enables NVFP4 on ROCm via <a href="https://github.com/causalflow-ai/petit-kernel">Petit</a>; use <code>modelopt_fp4</code> on NVIDIA Blackwell. Auto-selected when loading NVFP4 models on AMD. See <a href="https://lmsys.org/blog/2025-09-21-petit-amdgpu/">LMSYS blog</a> and <a href="https://rocm.blogs.amd.com/artificial-intelligence/fp4-mixed-precision/README.html">AMD ROCm blog</a>.</td>
    </tr>
    <tr>
      <td><code>bitsandbytes</code></td>
      <td>Yes</td>
      <td>Experimental</td>
      <td>No</td>
      <td>Depends on bitsandbytes ROCm support</td>
    </tr>
    <tr>
      <td><code>modelslim</code></td>
      <td>No</td>
      <td>No</td>
      <td>Yes</td>
      <td>Ascend quantization; Uses CANN kernels</td>
    </tr>

  </tbody>
</table>

On AMD, several of these methods use [Aiter](https://github.com/ROCm/aiter) for acceleration -- set `SGLANG_USE_AITER=1` where noted. See [AMD GPU setup](../hardware-platforms/amd_gpu) for installation and configuration details.

On Ascend, various layers quantization configurations are supported, see [Ascend NPU quantization](../hardware-platforms/ascend-npus/optimization/quantization) for details.

## GEMM Backends for FP4/FP8 Quantization

<Note>
Backend selection applies to **blockwise FP8**, **MXFP8** (dense linear), and **NVFP4** GEMM. When running offline or online FP8 or FP4 quantized models, you can select the GEMM backend via `--fp8-gemm-backend` and `--fp4-gemm-backend`.
</Note>

### `--fp8-gemm-backend` (Blockwise FP8 GEMM)

<table>
  <thead>
    <tr>
      <th>Backend</th>
      <th>Hardware</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>auto</code></td>
      <td>All</td>
      <td>Auto-selects based on hardware</td>
    </tr>
    <tr>
      <td><code>deep_gemm</code></td>
      <td>SM90, SM100</td>
      <td>JIT-compiled; enabled when DeepGEMM is installed</td>
    </tr>
    <tr>
      <td><code>flashinfer_trtllm</code></td>
      <td>SM100</td>
      <td>FlashInfer TensorRT-LLM backend; optimal for low-latency</td>
    </tr>
    <tr>
      <td><code>flashinfer_cutlass</code></td>
      <td>SM100/120</td>
      <td>FlashInfer CUTLASS groupwise FP8 GEMM</td>
    </tr>
    <tr>
      <td><code>flashinfer_deepgemm</code></td>
      <td>SM90</td>
      <td>Uses swapAB optimization for small M dimensions in decoding</td>
    </tr>
    <tr>
      <td><code>cutlass</code></td>
      <td>SM120</td>
      <td>sgl-kernel CUTLASS</td>
    </tr>
    <tr>
      <td><code>triton</code></td>
      <td>All</td>
      <td>Fallback; widely compatible</td>
    </tr>
    <tr>
      <td><code>aiter</code></td>
      <td>ROCm</td>
      <td>AMD AITER backend</td>
    </tr>
  </tbody>
</table>

**`auto` selection order:** 1) DeepGEMM (SM90/SM100, installed); 2) FlashInfer TRTLLM (SM100, FlashInfer available); 3) CUTLASS (SM120); 4) AITER (AMD); 5) Triton (fallback).

**MXFP8 dense linear:** `auto` uses `flashinfer_cutlass` on SM100 (else `triton`). `flashinfer_cutlass` is fastest on most shapes; `flashinfer_trtllm` is faster only at small M.

### `--fp4-gemm-backend` (NVFP4 GEMM)

<table>
  <thead>
    <tr>
      <th>Backend</th>
      <th>Hardware</th>
      <th>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>auto</code></td>
      <td>SM80+</td>
      <td>Auto-selects: <code>flashinfer_cutedsl</code> on SM100; <code>marlin</code> on SM80-SM90; <code>flashinfer_cutlass</code> otherwise (including SM120)</td>
    </tr>
    <tr>
      <td><code>flashinfer_cutlass</code></td>
      <td>SM100/120</td>
      <td>FlashInfer CUTLASS backend</td>
    </tr>
    <tr>
      <td><code>flashinfer_cudnn</code></td>
      <td>SM100/120 (CUDA 13+, cuDNN 9.15+)</td>
      <td>FlashInfer cuDNN backend</td>
    </tr>
    <tr>
      <td><code>flashinfer_cutedsl</code></td>
      <td>SM100</td>
      <td>FlashInfer CuTe DSL backend</td>
    </tr>
    <tr>
      <td><code>flashinfer_trtllm</code></td>
      <td>SM100</td>
      <td>FlashInfer TensorRT-LLM backend</td>
    </tr>
    <tr>
      <td><code>marlin</code></td>
      <td>SM80-SM90</td>
      <td>Weight-only W4A16 fallback for NVFP4 checkpoints</td>
    </tr>
  </tbody>
</table>

On SM80-SM90, `auto` selects Marlin for NVFP4. NVFP4 GEMM requires FlashInfer to be installed.

## Offline Quantization

To load already quantized models, simply load the model weights and config. **Again, if the model has been quantized offline,
there's no need to add `--quantization` argument when starting the engine. The quantization method will be parsed from the
downloaded Hugging Face or msModelSlim config. For example, DeepSeek V3/R1 models are already in FP8, so do not add redundant parameters.**

```bash Command
python3 -m sglang.launch_server \
    --model-path hugging-quants/Meta-Llama-3.1-8B-Instruct-AWQ-INT4 \
    --port 30000 --host 0.0.0.0
```

Take note, if your model is **per-channel quantized (INT8 or FP8) with per-token dynamic quantization activation**, you can opt to include `--quantization w8a8_int8` or `--quantization w8a8_fp8` to invoke the corresponding CUTLASS int8_kernel or fp8_kernel in sgl-kernel. This action will ignore the Hugging Face config's quantization settings. For instance, with `neuralmagic/Meta-Llama-3.1-8B-Instruct-FP8-dynamic`, if you execute with `--quantization w8a8_fp8`, the system will use the `W8A8Fp8Config` from SGLang to invoke the sgl-kernel, rather than the `CompressedTensorsConfig` for vLLM kernels.

```bash Command
python3 -m sglang.launch_server \
    --model-path neuralmagic/Meta-Llama-3.1-8B-Instruct-FP8-dynamic \
    --quantization w8a8_fp8 \
    --port 30000 --host 0.0.0.0
```

### Examples of Offline Model Quantization

#### Using [Unsloth](https://docs.unsloth.ai/basics/inference-and-deployment/sglang-guide)

We strongly suggest the use of Unsloth to quantize and load the model. Please refer to [SGLang Deployment & Inference Guide with Unsloth](https://docs.unsloth.ai/basics/inference-and-deployment/sglang-guide).

#### Using [auto-round](https://github.com/intel/auto-round)

```bash Command
# Install
pip install auto-round
```

- LLM quantization

```py Example
# for LLM
from auto_round import AutoRound
model_id = "meta-llama/Llama-3.2-1B-Instruct"
quant_path = "Llama-3.2-1B-Instruct-autoround-4bit"
# Scheme examples: "W2A16", "W3A16", "W4A16", "W8A16", "NVFP4", "MXFP4" (no real kernels), "GGUF:Q4_K_M", etc.
scheme = "W4A16"
format = "auto_round"
autoround = AutoRound(model_id, scheme=scheme)
autoround.quantize_and_save(quant_path, format=format) # quantize and save

```

- VLM quantization
```py Example
# for VLMs
from auto_round import AutoRoundMLLM
model_name = "Qwen/Qwen2-VL-2B-Instruct"
quant_path = "Qwen2-VL-2B-Instruct-autoround-4bit"
scheme = "W4A16"
format = "auto_round"
autoround = AutoRoundMLLM(model_name, scheme)
autoround.quantize_and_save(quant_path, format=format) # quantize and save

```

- Command Line Usage (Gaudi/CPU/Intel GPU/CUDA)

```bash Command
auto-round \
    --model meta-llama/Llama-3.2-1B-Instruct \
    --bits 4 \
    --group_size 128 \
    --format "auto_round" \
    --output_dir ./tmp_autoround
```

- SGlang API Usage (CPU/CUDA)

```python Example
from sglang.srt.configs.load_config import LoadConfig
from sglang.srt.configs.model_config import ModelConfig
from sglang.srt.model_loader.loader import get_model_loader
from sglang.srt.configs.device_config import DeviceConfig

# Configure model with inc quantization and saving
model_config = ModelConfig(
    model_path="meta-llama/Llama-3.2-3B-Instruct",
    quantization="auto-round-int8",
    trust_remote_code=True,
)

load_config = LoadConfig(
    inc_save_path="./quantized_model",
)
device_config = DeviceConfig(device="cpu")

# Load and quantize the model
model_loader = get_model_loader(load_config, model_config)
quantized_model = model_loader.load_model(
    model_config=model_config,
    device_config=device_config,
)
```

- known issues

Several limitations currently affect offline quantized model loading in sglang, These issues might be resolved in future updates of sglang. If you experience any problems, consider using Hugging Face Transformers as an alternative.

1. Mixed-bit Quantization Limitations

    Mixed-bit quantization is not fully supported. Due to vLLM's layer fusion (e.g., QKV fusion), applying different bit-widths to components within the same fused layer can lead to compatibility issues.


2. Limited Support for Quantized MoE Models

    Quantized MoE models may encounter inference issues due to kernel limitations (e.g., lack of support for mlp.gate layer quantization). please try to skip quantizing these layers to avoid such errors.


3. Limited Support for Quantized VLMs
    <Accordion title="Details">
        {/* VLM failure cases */}

    Qwen2.5-VL-7B

    auto_round:auto_gptq format:  Accuracy is close to zero.

    GPTQ format:  Fails with:
    ```text Output
    The output size is not aligned with the quantized weight shape
    ```
    auto_round:auto_awq and AWQ format:  These work as expected.
    </Accordion>

4. Limited Support for SGlang API Usage

    SGlang API Usage only supports `auto-round-int8` quantization method now, more quantization methods are on the way.

- CPU serving

    AutoRound INT4 checkpoints (both `auto_round:auto_gptq` and `auto_round:auto_awq` packing formats) can be served on Intel CPUs with AMX support:

    ```bash
    SGLANG_USE_CPU_ENGINE=1 python3 -m sglang.launch_server \
        --model-path OPEA/Qwen2.5-0.5B-Instruct-int4-sym-inc \
        --quantization auto-round \
        --device cpu --trust-remote-code
    ```

    The current SGLang CPU backend supports only 4-bit AutoRound checkpoints on Intel AMX. Other AutoRound bit-widths and non-AMX CPU backends are not supported by this path.


#### Using [GPTQModel](https://github.com/ModelCloud/GPTQModel)

```bash Command
# install
pip install gptqmodel --no-build-isolation -v
```

```py Example
from datasets import load_dataset
from gptqmodel import GPTQModel, QuantizeConfig

model_id = "meta-llama/Llama-3.2-1B-Instruct"
quant_path = "Llama-3.2-1B-Instruct-gptqmodel-4bit"

calibration_dataset = load_dataset(
    "allenai/c4", data_files="en/c4-train.00001-of-01024.json.gz",
    split="train"
  ).select(range(1024))["text"]

quant_config = QuantizeConfig(bits=4, group_size=128) # quantization config
model = GPTQModel.load(model_id, quant_config) # load model

model.quantize(calibration_dataset, batch_size=2) # quantize
model.save(quant_path) # save model
```

#### Using [LLM Compressor](https://github.com/vllm-project/llm-compressor/)

```bash Command
# install
pip install llmcompressor
```

Here, we take quantize `meta-llama/Meta-Llama-3-8B-Instruct` to `FP8` as an example to elaborate on how to do offline quantization.

```python Example
from transformers import AutoTokenizer
from llmcompressor.transformers import SparseAutoModelForCausalLM
from llmcompressor.transformers import oneshot
from llmcompressor.modifiers.quantization import QuantizationModifier

# Step 1: Load the original model.
MODEL_ID = "meta-llama/Meta-Llama-3-8B-Instruct"

model = SparseAutoModelForCausalLM.from_pretrained(
  MODEL_ID, device_map="auto", torch_dtype="auto")
tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)

# Step 2: Perform offline quantization.
# Step 2.1: Configure the simple PTQ quantization.
recipe = QuantizationModifier(
  targets="Linear", scheme="FP8_DYNAMIC", ignore=["lm_head"])

# Step 2.2: Apply the quantization algorithm.
oneshot(model=model, recipe=recipe)

# Step 3: Save the model.
SAVE_DIR = MODEL_ID.split("/")[1] + "-FP8-Dynamic"
model.save_pretrained(SAVE_DIR)
tokenizer.save_pretrained(SAVE_DIR)
```

Then, you can directly use the quantized model with `SGLang`, by using the following command:

```bash Command
python3 -m sglang.launch_server \
    --model-path $PWD/Meta-Llama-3-8B-Instruct-FP8-Dynamic \
    --port 30000 --host 0.0.0.0
```

#### Using [NVIDIA ModelOpt](https://github.com/NVIDIA/Model-Optimizer)

NVIDIA Model Optimizer (ModelOpt) provides advanced quantization techniques optimized for NVIDIA hardware.

**Offline vs. Online Quantization:**

SGLang supports two modes for ModelOpt.

* **Offline Quantization (pre-quantized):**
    * **Usage:** Download a pre-quantized model from Hugging Face or run `hf_ptq.py` once to create a new quantized checkpoint. Then load this quantized checkpoint.
    * **Pros:** Fast server startup, quantization can be validated before deployment, efficient resource usage.
    * **Cons:** Requires an extra preparation step.

* **Online Quantization (quant and serve):**
    * **Usage:** Load a standard BF16/FP16 model and add a flag. The engine applies quantization *on startup*.
    * **Pros:** Convenient (no new checkpoint needed).
    * **Cons:** **High startup time**, increases VRAM usage during initialization (risk of OOM).

The following sections guide you through using the Offline path: loading pre-quantized models or creating your own checkpoints.

##### Using Pre-Quantized Checkpoints

If a model is already quantized (e.g., from Hugging Face), you can load it directly.

* **FP8 Models:**
    Use `--quantization modelopt_fp8`.
    ```bash Command
    python3 -m sglang.launch_server \
        --model-path nvidia/Llama-3.1-8B-Instruct-FP8 \
        --quantization modelopt_fp8 \
        --port 30000
    ```

* **FP4 Models:**
    Use `--quantization modelopt_fp4`.
    ```bash Command
    python3 -m sglang.launch_server \
        --model-path nvidia/Llama-3.3-70B-Instruct-NVFP4 \
        --quantization modelopt_fp4 \
        --port 30000
    ```

##### Creating Your Own Quantized Checkpoints

If a pre-quantized checkpoint is not available for your model, you can create one using NVIDIA Model Optimizer's `hf_ptq.py` script.

**Why quantize?**
- Reduce VRAM usage
- Higher throughput and lower latency
- More flexible deployment (on smaller GPUs)

**What can be quantized?**
- The entire model
- MLP layers only
- KV cache

**Key options in `hf_ptq.py`:**

`--qformat`: Quantization formats `fp8`, `nvfp4`, `nvfp4_mlp_only`

`--kv_cache_qformat`: KV cache quantization format (default: `fp8`)

**Note:** The default `kv_cache_qformat` may not be optimal for all use cases. Consider setting this explicitly.

**Hardware requirements:** Hopper and higher are recommended. Insufficient GPU memory may cause weight offloading, resulting in extremely long quantization time.

For detailed usage and supported model architectures, see [NVIDIA Model Optimizer LLM PTQ](https://github.com/NVIDIA/Model-Optimizer/tree/main/examples/llm_ptq).

SGLang includes a streamlined workflow for quantizing models with ModelOpt and automatically exporting them for deployment.

##### Installation

First, install ModelOpt:

```bash Command
pip install nvidia-modelopt
```

##### Quantization and Export Workflow

SGLang provides an example script that demonstrates the complete ModelOpt quantization and export workflow. Run from the SGLang repository root (see [modelopt_quantize_and_export.py](https://github.com/sgl-project/sglang/blob/main/examples/usage/modelopt_quantize_and_export.py)):

```bash Command
# Quantize and export a model using ModelOpt FP8 quantization
python examples/usage/modelopt_quantize_and_export.py quantize \
    --model-path TinyLlama/TinyLlama-1.1B-Chat-v1.0 \
    --export-dir ./quantized_tinyllama_fp8 \
    --quantization-method modelopt_fp8

# For FP4 quantization (requires Blackwell GPU)
python examples/usage/modelopt_quantize_and_export.py quantize \
    --model-path TinyLlama/TinyLlama-1.1B-Chat-v1.0 \
    --export-dir ./quantized_tinyllama_fp4 \
    --quantization-method modelopt_fp4
```

##### Available Quantization Methods

- `modelopt_fp8`: FP8 quantization with optimal performance on NVIDIA Hopper and Blackwell GPUs
- `modelopt_fp4`: FP4 quantization with optimal performance on Nvidia Blackwell GPUs

##### Python API Usage

You can also use ModelOpt quantization programmatically:

```python Example
import sglang as sgl
from sglang.srt.configs.device_config import DeviceConfig
from sglang.srt.configs.load_config import LoadConfig
from sglang.srt.configs.model_config import ModelConfig
from sglang.srt.model_loader.loader import get_model_loader

# Configure model with ModelOpt quantization and export
model_config = ModelConfig(
    model_path="TinyLlama/TinyLlama-1.1B-Chat-v1.0",
    quantization="modelopt_fp8",  # or "modelopt_fp4"
    trust_remote_code=True,
)

load_config = LoadConfig(
    modelopt_export_path="./exported_model",
    modelopt_checkpoint_save_path="./checkpoint.pth",  # optional, fake quantized checkpoint
)
device_config = DeviceConfig(device="cuda")

# Load and quantize the model (export happens automatically)
model_loader = get_model_loader(load_config, model_config)
quantized_model = model_loader.load_model(
    model_config=model_config,
    device_config=device_config,
)
```

##### Deploying Quantized Models

After quantization and export, you can deploy the model with SGLang:

```bash Command
# Deploy the exported quantized model
python -m sglang.launch_server \
    --model-path ./quantized_tinyllama_fp8 \
    --quantization modelopt \
    --port 30000 --host 0.0.0.0
```

Or using the Python API (use the same path as `modelopt_export_path` from the quantize step):

```python Example
import sglang as sgl

def main():
    # Deploy exported ModelOpt quantized model
    # Path must match modelopt_export_path from quantize step (e.g., ./exported_model)
    llm = sgl.Engine(
        model_path="./exported_model",
        quantization="modelopt",
    )

    # Run inference
    prompts = [
        "Hello, how are you?",
        "What is the capital of France?",
    ]
    sampling_params = {
        "temperature": 0.8,
        "top_p": 0.95,
        "max_new_tokens": 100,
    }

    outputs = llm.generate(prompts, sampling_params)

    for i, output in enumerate(outputs):
        print(f"Prompt: {prompts[i]}")
        print(f"Output: {output['text']}")

if __name__ == "__main__":
    main()

```

##### Advanced Features

**Checkpoint Management**: Save and restore fake quantized checkpoints for reuse:

```bash Command
# Save the fake quantized checkpoint during quantization
python examples/usage/modelopt_quantize_and_export.py quantize \
    --model-path meta-llama/Llama-3.2-1B-Instruct \
    --export-dir ./quantized_model \
    --quantization-method modelopt_fp8 \
    --checkpoint-save-path ./my_checkpoint.pth

# The checkpoint can be reused for future quantization runs and skip calibration
```

**Export-only Workflow**: If you have a pre-existing fake quantized ModelOpt checkpoint, you can export it directly. See [LoadConfig](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/configs/load_config.py) for the full API:

```python Example
from sglang.srt.configs.device_config import DeviceConfig
from sglang.srt.configs.load_config import LoadConfig
from sglang.srt.configs.model_config import ModelConfig
from sglang.srt.model_loader.loader import get_model_loader

model_config = ModelConfig(
    model_path="meta-llama/Llama-3.2-1B-Instruct",
    quantization="modelopt_fp8",
    trust_remote_code=True,
)

load_config = LoadConfig(
    modelopt_checkpoint_restore_path="./my_checkpoint.pth",
    modelopt_export_path="./exported_model",
)

# Load and export the model (DeviceConfig defaults to device="cuda")
model_loader = get_model_loader(load_config, model_config)
model_loader.load_model(model_config=model_config, device_config=DeviceConfig())
```

##### Benefits of ModelOpt

- **Hardware Optimization**: Specifically optimized for NVIDIA GPU architectures
- **Advanced Quantization**: Supports cutting-edge FP8 and FP4 quantization techniques
- **Seamless Integration**: Automatic export to HuggingFace format for easy deployment
- **Calibration-based**: Uses calibration datasets for optimal quantization quality
- **Production Ready**: Enterprise-grade quantization with NVIDIA support

#### Using [ModelSlim](https://gitcode.com/Ascend/msmodelslim)
MindStudio-ModelSlim (msModelSlim) is a model offline quantization compression tool launched by MindStudio and optimized for Ascend hardware.

- **Installation**

    ```bash Command
    # Clone repo and install msmodelslim:
    git clone https://gitcode.com/Ascend/msmodelslim.git
    cd msmodelslim
    bash install.sh
    ```

- **LLM quantization**

    Download the original floating-point weights of the large model. Taking Qwen3-32B as an example, you can go to [Qwen3-32B](https://huggingface.co/Qwen/Qwen3-32B) to obtain the original model weights. Then install other dependencies (related to the model, refer to the huggingface model card).
    > Note: You can find pre-quantized validated models on [modelscope/Eco-Tech](https://modelscope.cn/models/Eco-Tech).

    _Traditional quantification methods require the preparation of calibration data files (```.jsonl``` formats) for calibration in the quantification process._
    ```bash Command
    Qwen3-32B/      # floating-point model downloaded from official HF (or modelscope) repo
    msmodelslim/    # msmodelslim repo
      |----- lab_calib # calibration date folder (put your dataset here in ```.jsonl``` format or use pre-prepared ones)
          |----- some file (such as laos_calib.jsonl)
      |----- lab_practice # best practice folder with configs for quantization
          |----- model folder (such as qwen3_5_moe folder) # folder with quantization configs
              |----- quant_config (such as qwen3_5_moe_w8a8.yaml) # quantization config
      |----- another folders
    output_folder/   # generated by below command
      |----- quant_model_weights-00001-of-0001.safetensors # quantized weights
      |----- quant_model_description.json # file with description of the quantization methods for each layer (```W4A4_DYNAMIC```, etc.)
      |----- another files (such as config.json, tokenizer.json, etc.)
    ```
    Run quantization using one-click quantization (recommended):
    ```bash Command
    msmodelslim quant \
    --model_path ${MODEL_PATH} \
    --save_path ${SAVE_PATH} \
    --device npu:0,1 \
    --model_type Qwen3-32B \
    --quant_type w8a8 \
    --trust_remote_code True
    ```

- **Usage Example**
    ```bash Command
    python3 -m sglang.launch_server \
    --model-path $PWD/Qwen3-32B-w8a8 \
    --port 30000 --host 0.0.0.0
    ```

- **Available Quantization Methods**:
    - [x]  ```W4A4_DYNAMIC``` linear with online quantization of activations
    - [x]  ```W8A8``` linear with offline quantization of activations
    - [x]  ```W8A8_DYNAMIC``` linear with online quantization of activations
    - [x]  ```W4A4_DYNAMIC``` MOE with online quantization of activations
    - [x]  ```W4A4_MXFP4``` MOE with dynamic MXFP4 activation quantization
    - [x]  ```W4A8_DYNAMIC``` MOE with online quantization of activations
    - [x]  ```W4A8_MXFP``` MOE with dynamic MXFP8 activation quantization
    - [x]  ```W8A8_DYNAMIC``` MOE with online quantization of activations
    - [ ]  ```W4A8``` linear TBD
    - [ ]  ```W4A16``` linear TBD
    - [ ]  ```W48A16``` linear TBD
    - [ ]  ```W4A16``` MoE in progress
    - [ ]  ```W8A16``` MoE in progress
    - [ ]  ```KV Cache``` in progress
    - [ ]  ```Attention``` in progress


For more detailed examples of quantization of models, as well as information about their support, see the [examples](https://gitcode.com/Ascend/msmodelslim/blob/master/example/README.md) section in ModelSLim repo.

## Online Quantization

To enable online quantization, you can simply specify `--quantization` in the command line. For example, you can launch the server with the following command to enable `FP8` quantization for model `meta-llama/Meta-Llama-3.1-8B-Instruct`:

```bash Command
python3 -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --quantization fp8 \
    --port 30000 --host 0.0.0.0
```

Our team is working on supporting more online quantization methods. SGLang will soon support methods including but not limited to `["awq", "gptq", "marlin", "gptq_marlin", "awq_marlin", "bitsandbytes", "gguf"]`.

### `nvfp4_online` online quantization method

Use `--quantization nvfp4_online` to convert eligible BF16, FP16, or FP8 MoE expert weights to NVFP4 at load time with per-token FP32 activation scales. Use `modelopt_fp4` for serialized NVFP4 checkpoints or the same load-time conversion with per-tensor FP32 activation scales.

The design separates weight quantization from activation scaling:

- **Weights:** SGLang quantizes each eligible MoE expert weight tensor as it is loaded, using standard 2D NVFP4 weight quantization. The generated NVFP4 weights use static E4M3 block scales plus static per-tensor FP32 scales derived from the weight amax. For gated MoE experts, the w1/w3 pair shares one per-tensor FP32 scale.
- **Activations:** FlashInfer computes and propagates one FP32 scale per token at runtime. Backends that accept one per-tensor FP32 activation scale must use `modelopt_fp4`.
- **FP8 checkpoints:** If an eligible expert weight is stored as FP8, SGLang first dequantizes that tensor with the checkpoint scale and then requantizes it to NVFP4 during loading.
- **Other layers:** Dense linear layers stay in their source checkpoint precision or checkpoint quantization path.

Only `--moe-runner-backend flashinfer_trtllm` and `--moe-runner-backend flashinfer_trtllm_routed` are supported. If `--moe-runner-backend` is omitted, SGLang selects `flashinfer_trtllm`. Tensor parallelism is supported; activation per-token scales are computed locally on each TP rank, while online weight quantization still uses the loaded expert tensor's per-tensor amax-derived FP32 scale.

FlashInfer TRTLLM MoE backends disable shared-expert fusion, so online quantization applies to routed MoE experts while shared experts stay in the checkpoint precision. Both online modes honor `SGLANG_FP4_IGNORED_LAYERS`; for FP8 source checkpoints, listed experts remain FP8 instead of being converted to NVFP4.

```bash Command
python3 -m sglang.launch_server \
    --model-path Qwen/Qwen3-30B-A3B-Instruct-2507 \
    --tp-size 2 \
    --ep-size 2 \
    --quantization nvfp4_online \
    --port 30000 --host 0.0.0.0
```

### `quark_int4fp8_moe` online quantization method

SGLang running on AMD GPUs (CDNA3 or CDNA4 architecture) supports the quantization method `--quantization quark_int4fp8_moe`, that will replace [MoE layers](https://github.com/sgl-project/sglang/blob/v0.4.8/python/sglang/srt/layers/moe/fused_moe_triton/layer.py#L271) originally in high precision (bfloat16, float16 or float32) to use weights dynamically quantized to int4, that are upcasted to float8 during inference to run compute in float8 precision with activations dynamically quantized on the fly to float8.

Other layers (e.g. projections in the attention layers) have their weights quantized online to float8 directly.

### `quark_mxfp4` online quantization method

SGLang running on AMD GPUs with hardware FP4 support (CDNA4 architecture, e.g. MI355x) supports the quantization method `--quantization quark_mxfp4`, that will quantize BF16 or NVFP4 model weights to MXFP4 at load time, use dynamic MXFP4 quantization for activations and MXFP4 GEMMs instead of BF16 GEMMs.

Example (BF16 to MXFP4 requantization):

```bash
sglang serve --model-path Qwen/Qwen3-30B-A3B \
    --tensor-parallel-size 1 \
    --quantization quark_mxfp4
```

#### Online NVFP4 to MXFP4 Requantization

The option `--quantization quark_mxfp4` supports converting NVFP4 checkpoints (e.g. `nvidia/Kimi-K2.6-NVFP4`) to MXFP4 at load time to allow efficient inference using supported AMD hardware (gfx95x+):

- The quantization metadata of the source NVFP4 checkpoint is read from either `config.json` (`quantization_config`) or a standalone `hf_quant_config.json`;
- Producer-declared excluded modules will remain in higher precision;
- NVFP4 checkpoints with mixed precision (`"quant_algo": "MIXED_PRECISION"`, e.g. `nvidia/Qwen3.5-397B-A17B-NVFP4-V2`) are also supported.

Example (NVFP4 to MXFP4 requantization):

```bash
sglang serve --model-path nvidia/Kimi-K2.6-NVFP4 \
    --tensor-parallel-size 4 \
    --quantization quark_mxfp4 \
```
#### Online FP8 to MXFP4 Requantization

The option `--quantization quark_mxfp4` supports converting FP8 dense and MOE models to MXFP4, following this logic:

1. Load an FP8 weight tensor,
2. Dequantize it to BF16,
3. Requantize it to MXFP4

progressively during weight loading.

Example (FP8 to MXFP4 requantization):

```bash
sglang serve --model-path Qwen/Qwen3-30B-A3B-Instruct-2507-FP8 \
    --tensor-parallel-size 1 \
    --quantization quark_mxfp4
```

### Intel® Neural Compressor online quantization method

SGLang supports quantization methods based on the advanced algorithm [auto-round](https://github.com/intel/auto-round) in [Intel® Neural Compressor](https://github.com/intel/neural-compressor). You can simply specify `--quantization auto-round-int8` to use this feature. It will quantize the model on the fly to target format. More online quantization methods are on the way.

##### Available Quantization Methods

| Quantization Method | Schemes | Validated Hardware Environment |
|:--------------------|:--------|:-------------------------------|
| auto-round-int8     |INT8 per-channel quantized weight <br /> INT8 per-token dynamic quantized activation | Intel Xeon Scalable processor <br /> Nvidia A100 GPU |


## Diffusion Model Quantization on Ascend NPU

SGLang-Diffusion supports MXFP8 quantization for diffusion models (such as Wan2.2) on Ascend 950PR/DT Series NPUs, in both online and offline (ModelSlim) modes. This is separate from the LLM serving path and uses the `sglang serve` / `sglang generate` CLI.

**Requirements:** Ascend 950PR/DT Series, CANN ≥ 8.0.RC3

### Online MXFP8

Pass `--quantization mxfp8` to dynamically quantize FP16/BF16 transformer weights to MXFP8 at load time:

```bash
sglang serve \
  --model-path Wan-AI/Wan2.2-T2V-A14B-Diffusers \
  --quantization mxfp8 \
  --num-gpus 4
```

### Offline MXFP8 (ModelSlim)

Pre-quantize with [msModelSlim](https://gitcode.com/Ascend/msmodelslim) and load the checkpoint directly — the quantization scheme is auto-detected from `quant_model_description.json`:

```bash
sglang generate \
  --model-path /path/to/wan2_2_mxfp8_diffusers \
  --prompt "a beautiful sunset" \
  --save-output
```

For the full quantization + format conversion workflow and a complete list of supported schemes, see [Diffusion Quantization on Ascend NPU](../hardware-platforms/ascend-npus/optimization/quantization#diffusion-model-quantization-on-ascend-npu) and [SGLang-Diffusion Quantization](../sglang-diffusion/quantization#modelslim).

## Reference

- [GPTQModel](https://github.com/ModelCloud/GPTQModel)
- [LLM Compressor](https://github.com/vllm-project/llm-compressor/)
- [NVIDIA Model Optimizer (ModelOpt)](https://github.com/NVIDIA/Model-Optimizer)
- [NVIDIA Model Optimizer LLM PTQ](https://github.com/NVIDIA/Model-Optimizer/tree/main/examples/llm_ptq)
- [Petit: NVFP4 on ROCm](https://github.com/causalflow-ai/petit-kernel) — [LMSYS blog](https://lmsys.org/blog/2025-09-21-petit-amdgpu/), [AMD ROCm blog](https://rocm.blogs.amd.com/artificial-intelligence/fp4-mixed-precision/README.html)
- [vLLM Quantization](https://docs.vllm.ai/en/latest/quantization/)
- [auto-round](https://github.com/intel/auto-round)
- [ModelSlim](https://gitcode.com/Ascend/msmodelslim)

---

### Docs Advanced Features Quantized Kv Cache (`docs/docs/advanced_features/quantized_kv_cache.mdx`)

---
title: "Quantized KV Cache"
metatags:
    description: "SGLang quantized KV cache: FP8 E4M3/E5M2 and FP4 E2M1 formats, memory savings up to 3.56x, scaling factors, accuracy benchmarks."
---
Quantized KV cache reduces the memory footprint of key-value cache storage by using lower-precision data types (FP8 or FP4) instead of the default model precision in BF16. During autoregressive generation, LLMs cache previously computed key-value pairs to avoid redundant calculations. The KV cache typically consumes a significant portion of GPU memory, especially for long sequences.

Quantized KV cache is a memory optimization technique that primarily benefits throughput by allowing more tokens to be cached, but may introduce minimal accuracy degradation depending on the quantization format used.

<Warning>
**Performance Warning**: When quantized KV cache must be dequantized before use in attention operations, performance can be extremely slow if dequantization is not fused with the attention kernel. Always verify that your chosen attention backend supports quantized KV cache. Backends without fused support may experience significant throughput degradation, potentially negating the memory benefits.

**Backend Support**: Not all attention backends support quantized KV cache. Refer to [Attention Backend](./attention_backend) for which backends support it.
</Warning>

## Supported Formats

SGLang supports the following quantized KV cache formats:

### FP8 Format

[OCP (Open Compute Project)](https://www.opencompute.org) specifies two common 8-bit floating point formats:

- **E5M2** (5 exponent bits, 2 mantissa bits): Larger dynamic range (±57344.0), lower precision
- **E4M3** (4 exponent bits, 3 mantissa bits): Higher precision, smaller dynamic range (±240.0)

### FP4 Format

<Warning>
FP4 quantization is currently experimental.
</Warning>

[OCP (Open Compute Project)](https://www.opencompute.org) specifies MXFP4 (Microscaling FP4), a 4-bit floating-point format. SGLang exposes two experimental E2M1 KV-cache recipes:

- **`nvfp4`**: NVIDIA FP4 with 16-value blocks, E4M3 block scales, and a per-tensor global scale.
- **`fp4_mx_block16`**: An E2M1 block-size-16 compatibility recipe. It is distinct from the standard OCP MXFP4 block-size-32 format.

## Usage

### Enabling Quantized KV Cache

To enable quantized KV cache, use the `--kv-cache-dtype` argument when launching the server:

```bash Command
# Enable FP8 E5M2 KV cache
python3 -m sglang.launch_server \
    --model-path deepseek-ai/DeepSeek-R1-0528 \
    --kv-cache-dtype fp8_e5m2 \

# Enable FP8 E4M3 KV cache
python3 -m sglang.launch_server \
    --model-path deepseek-ai/DeepSeek-R1-0528 \
    --kv-cache-dtype fp8_e4m3 \

# Enable NVFP4 FP4 E2M1 KV cache
python3 -m sglang.launch_server \
    --model-path nvidia/DeepSeek-R1-0528-NVFP4 \
    --kv-cache-dtype nvfp4 \

# Enable block-size-16 FP4 E2M1 KV cache
python3 -m sglang.launch_server \
    --model-path deepseek-ai/DeepSeek-R1-0528 \
    --kv-cache-dtype fp4_mx_block16 \
```

### SM100 native NVFP4 recipes

On SM100, prefill can either consume packed NVFP4 directly or dequantize it into an FP8 E4M3 workspace. Select the online dequantization dtype with `--prefill-kv-cache-dequant-dtype`; SGLang chooses the corresponding attention implementation.

For native NVFP4 prefill and decode:

```bash Command
python3 -m sglang.launch_server \
    --model-path Qwen/Qwen3.5-35B-A3B-FP8 \
    --tp-size 1 \
    --kv-cache-dtype nvfp4 \
    --prefill-kv-cache-dequant-dtype nvfp4 \
    --page-size 16
```

For FP8 prefill backed by a temporary dequantization workspace, with native NVFP4 decode:

```bash Command
python3 -m sglang.launch_server \
    --model-path Qwen/Qwen3.5-35B-A3B-FP8 \
    --tp-size 1 \
    --kv-cache-dtype nvfp4 \
    --prefill-kv-cache-dequant-dtype fp8_e4m3 \
    --page-size 16
```

`nvfp4` means that prefill consumes the packed native NVFP4 cache directly without any additional dequantization. The default value, `auto`, selects this native NVFP4 mode on SM100 and FP8 E4M3 dequantization on SM120. Decode consumes native NVFP4 in both recipes. The native recipe avoids the FP8 workspace and its token-linear scale copy; the FP8 recipe retains both the linear scales used during prefill and the physical scale layout used during decode. KV data remains stored as packed FP4 either way.

<Note>
Native NVFP4 prefill requires SM100, a page size divisible by 4, and an attention head dimension divisible by 64. TRT-LLM GenMHA uses FP8 query and output buffers internally; SGLang converts the result back to the model activation dtype. Top-k-1 EAGLE/EAGLE3/NEXTN and breadth-1 NGRAM speculative decoding are supported: an EAGLE-family draft worker uses `trtllm_mha`, and target verification consumes the physical NVFP4 cache directly in eager execution and CUDA Graphs. Set `--speculative-ngram-max-bfs-breadth=1` for NGRAM. With the mixed FlashInfer-prefill/TRT-LLM-decode recipe, SGLang resolves `--speculative-attention-mode` to `decode` so verification does not depend on FlashInfer's transient dequantization workspace. Other speculative algorithms, PD disaggregation, hierarchical KV cache, and LMCache are not currently supported by the SM100 native NVFP4 path. SM120 XQA continues to use its architecture-specific linear scale layout and BF16 query/output path.
</Note>

### Scaling Factors

FP8 quantization requires scaling factors to properly quantize and dequantize the KV cache.

<Note>
Currently, only per-tensor (scalar) scaling factors are supported.
</Note>

Scaling factors can be:

- **Loaded from checkpoints**: Pre-quantized models (e.g., ModelOpt) may include `k_scale` and `v_scale` parameters that are automatically loaded
- **Provided via JSON**: Supply scaling factors via `--quantization-param-path`.

The JSON file should follow this format:

```json Config
{
  "kv_cache": {
    "dtype": "float8_e4m3fn",
    "scaling_factor": {
      "0": {
        "0": 1.0,
        "1": 1.0
      }
    }
  }
}
```

Where the outer keys in `scaling_factor` are tensor parallel ranks and inner keys are layer indices.

<Warning>
If scaling factors are not provided and not found in the checkpoint, it will default to 1.0, which may cause accuracy issues.
</Warning>

<Tip>
**FP4 (MXFP4)**: Unlike FP8, FP4 quantization handles scaling factors automatically on-the-fly during quantization and dequantization. No pre-quantized models or external scaling factor files are required—the block-based scaling factors are computed dynamically as needed.
</Tip>

## Performance Considerations

### Memory Savings

Quantized KV cache provides significant memory savings:
- **BF16 → FP4**: Supports approximately 3.56× more tokens than BF16 (accounting for scaling factor overhead)

<Note>
FP4 and FP8 quantization require additional memory for block-based scaling factors, which reduces the effective memory savings compared to the raw bit-width reduction. FP4 with block size 16 supports approximately 1.78× more tokens than FP8, and approximately 3.56× more tokens than BF16. The relative token capacity between FP8 and BF16 can be derived from these ratios.
</Note>

This enables longer context lengths or more concurrent requests within the same memory budget.

For native `nvfp4`, each logical scalar costs 0.5 bytes of packed FP4 data plus 1/16 byte of block-scale storage, compared with 2 bytes for BF16. The resulting theoretical KV-token capacity multiplier is `2 / 0.5625 = 3.56×`. The mixed SM100 recipe owns a second scale layout and a shared one-layer FP8 prefill workspace, so its exact capacity depends on the number of full-attention layers. SGLang includes those auxiliary buffers in its KV-pool sizing calculation.

### Accuracy Impact

#### FP8 Accuracy

FP8 E4M3 quantization typically introduces minimal accuracy degradation. The impact depends on model architecture, sequence length, and quantization format (generally, E4M3 has better accuracy than E5M2).

#### FP4 Accuracy

FP4 (MXFP4) quantization provides significant memory savings with varying accuracy impact depending on model size and dataset complexity. Preliminary accuracy test results from [PR #10078](https://github.com/sgl-project/sglang/pull/10078) (MLA) and [PR #12612](https://github.com/sgl-project/sglang/pull/12612) (MHA) show:

**Large Models (e.g., Qwen3-235B-A22B, DeepSeek-R1-0528)**

On large-scale models, FP4 maintains accuracy close to FP8/BF16, especially on simpler datasets:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Dataset</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>KV16</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>KV8 (FP8 E4M3)</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>KV4 (FP4 E2M1)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen3-235B-A22B</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>gsm8k</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.9168</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.9181</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.9186</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen3-235B-A22B</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>aime25</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.7733</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.7333</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.6000</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen3-235B-A22B</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>gpqa_diamond</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.7010</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.6899</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.6778</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>DeepSeek-R1-0528</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>gsm8k</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.9157</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.9154</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.9124</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>DeepSeek-R1-0528</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>aime25</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.5067</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.4934</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.4000</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>DeepSeek-R1-0528</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>gpqa_diamond</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.7707</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.7697</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.7273</td>
    </tr>
  </tbody>
</table>

**Smaller Models (e.g., GPT-OSS-120B)**

On smaller models, FP4 shows more pronounced accuracy drops, particularly on challenging datasets:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Dataset</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>KV16</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>KV8 (FP8 E4M3)</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>KV4 (FP4 E2M1)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>GPT-OSS-120B</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>gsm8k</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.9161</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.9163</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.9152</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>GPT-OSS-120B</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>aime25</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.7533</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.7667</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.3533</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>GPT-OSS-120B</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>gpqa_diamond</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.5081</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.5434</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>0.3202</td>
    </tr>
  </tbody>
</table>

**Key Observations:**

- **Simple datasets (e.g., gsm8k)**: FP4 maintains accuracy close to FP8/BF16 across model sizes
- **Model size matters**: Large models (200B+ parameters) generally tolerate FP4 quantization better than smaller models
- **Context length**: Accuracy degradation may be more pronounced in long-context scenarios, as the accumulation of the quantization error may become significant.

<Tip>
Evaluate FP4 accuracy on your specific model and workload. Large models on simpler tasks typically show minimal degradation, while smaller models or complex reasoning tasks may require FP8 or BF16 for acceptable accuracy.
</Tip>

## Best Practices

- **Use pre-quantized models**: Prefer models quantized offline with scaling factors included in the checkpoint.
- **Choose the right format**: Use `fp8_e4m3` for better accuracy (recommended), `fp8_e5m2` for larger dynamic range, or `nvfp4` / `fp4_mx_block16` for maximum memory savings (experimental)
- **Check backend compatibility**: Verify that your chosen attention backend supports quantized KV cache

<Note>
See also:
- [Quantization](./quantization)
- [Attention Backend](./attention_backend)
- [Server Arguments](./server_arguments)
</Note>

---

### Docs Advanced Features Radix Eviction Policy (`docs/docs/advanced_features/radix_eviction_policy.mdx`)

---
title: "Radix Cache Eviction Policies"
metatags:
    description: "Choose how the radix cache picks which prefix KV to drop under memory pressure, and tune a policy with --radix-eviction-policy-config."
---

When the KV cache pool is full, the radix cache reclaims space by evicting cached prefixes. The eviction policy decides which prefix goes first. The default, `lru`, is the right choice for most workloads; the others trade recency for hit frequency, reuse history, or request priority.

## How eviction picks a victim

Eviction only ever considers **evictable leaves**: nodes whose KV is present, unlocked (no in-flight request holds them), and not shadowed by a child that still holds KV. The root is never evictable.

The policy scores each candidate and the **lowest score is evicted first**. Once a leaf is evicted, its parent may become a leaf and re-enter the candidate set, so eviction walks a branch from its tip toward the root.

A policy only scores. It does not decide how much to free, and it cannot pin KV in memory — a node protected by the policy is still evicted if reclaiming everything else is not enough.

## Available policies

Select one with `--radix-eviction-policy`. All of them fall back to least-recently-used order within a tie.

| Policy | Evicts first | Use when |
|---|---|---|
| `lru` (default) | The prefix unused for longest. | General serving. Matches how prefix reuse decays with time. |
| `lfu` | The prefix with the fewest cache hits, then the least recent. | A small set of prompts is reused far more than the rest, and you want those to survive bursts of one-off traffic. |
| `slru` | Prefixes still in the probationary segment, then the least recent within a segment. | Like `lfu`, but you want a hard floor on how much a one-off prefix can displace a proven one. See [`slru` parameters](#slru-parameters). |
| `priority` | The prefix belonging to the lowest-priority request, then the least recent. | You run [priority scheduling](/docs/advanced_features/server_arguments) and want cache retention to follow the same ranking as admission. |
| `tlru` | The tail of a conversation beyond what its next prefill needs to meet the TTFT budget ("TEL-safe" tokens), then the least recent. | Agentic / multi-turn workloads where tail TTFT matters more than raw hit rate. See [`tlru` parameters](#tlru-parameters). Requires the unified radix cache (the default tree). |

Notes on the scoring inputs:

- **Hit count** (`lfu`, `slru`) counts how many times a node was matched by a later request. It is not incremented for chunked-prefill steps, for evicted nodes, or under write-back HiCache.
- **Request priority** (`priority`) is the `priority` field of the request that inserted the prefix; a node reached by several requests keeps the highest priority among them. Without priority scheduling every node is priority `0` and this policy is equivalent to `lru`.

`fifo`, `mru`, and `filo` also exist in the policy registry but are not offered on the command line. They are reachable only by out-of-tree code that extends the choice list, and exist for experiments rather than serving.

## Tuning a policy

Some policies take parameters. Pass them as a json object to `--radix-eviction-policy-config`; the keys are the policy's own, so they are only valid for the policy you selected.

```bash Command
python3 -m sglang.launch_server \
  --model-path MODEL_PATH \
  --radix-eviction-policy slru \
  --radix-eviction-policy-config '{"protected_threshold": 4}'
```

Omit the flag to accept every default. An unrecognized key fails at startup rather than being ignored:

```
TypeError: SLRUStrategy.__init__() got an unexpected keyword argument 'protected_treshold'
```

### Policy parameters

`slru` and `tlru` take parameters. `lru`, `lfu`, and `priority` take none, so `--radix-eviction-policy-config` has no effect with them and any key is an error.

#### `slru` parameters

`slru` splits the cache into a **probationary** segment and a **protected** segment. A prefix enters probationary, and is promoted to protected once it has been hit enough times. Everything probationary is evicted before anything protected.

| Key | Type | Default | Meaning |
|---|---|---|---|
| `protected_threshold` | int | `2` | Hit count at which a prefix is promoted to the protected segment. |

Raising it makes promotion harder, so the protected set stays small and closer to your genuinely hot prefixes; a prefix hit three times stays probationary at `4` but is protected at the default `2`. Lowering it to `1` promotes any prefix that is reused even once, which approaches `lru` with a one-hit grace period.

#### `tlru` parameters

`tlru` (Tail-Optimized LRU, [arXiv:2510.15152](https://arxiv.org/abs/2510.15152)) protects only the cached history a conversation's next prefill needs to stay under a TTFT budget; the rest of its tail is evicted first, and eviction continues in plain recency order once the TEL-safe tokens run out.

| Key | Type | Meaning |
|---|---|---|
| `threshold` | int | Tail-latency threshold ξ, in tokens: a conversation only keeps enough cache to hold its next prefill under ξ uncached tokens. Convert from a TTFT target by dividing it by the measured ms per uncached token. The paper states ξ in blocks, so multiply its values by `--page-size`. |
| `next_prompt_estimate` | int | Estimated tokens the next turn of a conversation will add; use the trace's empirical mean. |

Both keys are required in practice: `threshold` must be greater than `next_prompt_estimate` (only the difference affects behaviour), and values at or above it reduce T-LRU to plain LRU, which startup rejects.

```bash Command
python3 -m sglang.launch_server \
  --model-path MODEL_PATH \
  --radix-eviction-policy tlru \
  --radix-eviction-policy-config '{"threshold": 4096, "next_prompt_estimate": 512}'
```

## Which policy to pick

Start with `lru` and change it only against a measured cache hit rate — the counters are exposed under `--enable-metrics`. `lfu` and `slru` help when your traffic has a stable hot set that a recency-only policy keeps flushing; they hurt when prefix popularity shifts over time, because a prefix that earned a high hit count keeps its advantage after it stops being useful.

---

### Docs Advanced Features Reasoning Aware Compression (`docs/docs/advanced_features/reasoning_aware_compression.mdx`)

---
title: "Reasoning-Aware Compression"
metatags:
    description: "Prune reasoning LLMs without breaking them: calibrate SparseGPT on on-policy chain-of-thought activations collected with SGLang, then serve the sparse checkpoint."
---

Pruning a reasoning model with a standard calibration set does more damage than pruning a
conventional LLM — and it can make the model *slower*. Reasoning-Aware Compression (RAC) fixes this
by changing what the pruning solver calibrates on: the model's own chain of thought, generated with
SGLang.

From [*Reasoning Models Can be Accurately Pruned Via Chain-of-Thought Reconstruction*](https://arxiv.org/abs/2509.12464)
(ICLR 2026).

## The problem

One-shot pruning methods such as SparseGPT and Wanda choose which weights to remove by minimizing a
layer-wise reconstruction error against a calibration activation matrix `X`:

```
min_{W'} || W X - W' X ||_F^2    s.t.  ||W'||_0 <= S
```

`X` is conventionally built from **prompt** tokens — a slice of C4, or a set of task prompts. That
is a fair proxy for a typical serving workload, where the prompt dominates the token count.

Reasoning models invert that ratio. They emit thousands of chain-of-thought tokens per query, so
almost every forward pass the pruned model will ever run is over a token it generated itself.
Calibrating only on prompts optimizes the pruned weights for a distribution the model barely visits.

The result is not a graceful accuracy decay. The pruned model starts to ramble: it produces longer
chains of thought *and* answers less accurately, so pruning increases end-to-end latency instead of
reducing it. At 50% sparsity on MATH-500, C4-calibrated DeepSeek-R1-Distill-Qwen-7B takes almost six
times as long to evaluate as the dense model it was meant to accelerate.

## The fix

RAC samples the dense model's own on-policy rollout during calibration and reconstructs the prompt
and decode activations jointly:

```
X_RAC = [ X_prompt , X_decode ]
```

The solver is untouched, so this is a drop-in change to any existing SparseGPT or Wanda workflow.

DeepSeek-R1-Distill-Qwen-7B, MATH-500, SparseGPT at 50% sparsity, 1M calibration tokens:

| Calibration set | acc@1 | Eval wall clock |
| --- | --- | --- |
| Dense (no pruning) | 0.936 | 23.3 min |
| C4 | 0.744 | 135.0 min |
| Task prompts only | 0.812 | 115.6 min |
| **RAC (prompts + on-policy CoT)** | **0.900** | **35.3 min** |

Across DeepSeek-R1-Distill-Qwen (1.5B–32B) and Qwen3 (1.7B–14B), the paper reports that RAC keeps up
to 95% of dense accuracy at 50% sparsity, improving on prompt-only calibration by up to 17 points.

## Using it

SGLang ships the recipe as a runnable example at
[`examples/usage/reasoning_aware_compression`](https://github.com/sgl-project/sglang/tree/main/examples/usage/reasoning_aware_compression),
in three phases:

| Phase | Script | What it does |
| --- | --- | --- |
| I | `rac_collect_traces.py` | `sgl.Engine` samples on-policy CoT traces into a calibration set |
| II | `rac_prune.py` | `llm-compressor` runs SparseGPT/Wanda against those activations |
| III | `rac_serve_and_eval.py` | SGLang serves the sparse checkpoint and scores MATH-500 |

Phase I is the expensive step — the paper's budget is 1M on-policy CoT tokens — and is where SGLang's
batched generation does the work. Phase II delegates the pruning solver to
[`llm-compressor`](https://github.com/vllm-project/llm-compressor), which is **not** an SGLang
dependency; install it separately with `pip install "llmcompressor>=0.12.0"`.

```bash
cd examples/usage/reasoning_aware_compression

python rac_collect_traces.py \
    --model-path deepseek-ai/DeepSeek-R1-Distill-Qwen-1.5B \
    --dataset open-r1/OpenR1-Math-220k --prompt-column problem \
    --target-tokens 1000000 --output-dir ./rac_traces_math

python rac_prune.py \
    --model-path deepseek-ai/DeepSeek-R1-Distill-Qwen-1.5B \
    --calibration ./rac_traces_math/traces.jsonl \
    --sparsity 0.5 --output-dir ./rac_pruned_50

python -m sglang.launch_server --model-path ./rac_pruned_50
```

The example README walks through building the paper's prompt-only baseline from the same prompts so
you can compare calibration strategies head to head.

## Evaluating a pruned reasoning model

Accuracy alone will hide the failure mode described above. Always report **mean completion length**
and **wall clock** alongside accuracy when comparing pruned reasoning checkpoints — a model that
scores two points lower while emitting three times the chain of thought is not a good trade.
`rac_serve_and_eval.py` reports all three.

## Related

- [Quantization](/docs/advanced_features/quantization) — the other axis of model compression, applied
  at serving time.

---

### Docs Advanced Features Rfork (`docs/docs/advanced_features/rfork.mdx`)

---
title: "R-Fork"
metatags:
    description: "SGLang R-Fork: zero-copy GPU-to-GPU weight loading, reduce boot-up time from minutes to seconds. NCCL and TransferEngine backends."
---
R-Fork (Tensor Remote Fork) is a novel weight loading methodology that leverages efficient inter-node GPU-to-GPU data transfer path to load tensors from a running SGLang instance to a new instance with zero-copy. It can significantly optimize the SGLang instance boot-up time by reducing model weights loading from several minutes to mere seconds.

To learn more details about R-Fork, please check **<a href="https://lmsys.org/blog/2025-12-10-rfork/"> R-Fork blog </a>**

## Usage

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Usage</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>load-format</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>set to `remote_instance` to enable R-Fork.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>remote-instance-weight-loader-backend</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>nccl</code>, <code>transfer_engine</code>, or <code>modelexpress</code>. Default is <code>nccl</code>.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>remote-instance-weight-loader-seed-instance-ip</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>IP address of the seed instance who will provide the model weight. Used by <code>nccl</code> and <code>transfer_engine</code> backends.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>remote-instance-weight-loader-seed-instance-service-port</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>the port that the seed instance's HTTP server is listening on. Used by <code>nccl</code> and <code>transfer_engine</code> backends.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>remote-instance-weight-loader-send-weights-group-ports</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>the list of available ports on the seed instance that will be used to build NCCL communication groups between seed and client instance. Only needed by <code>nccl</code> backend.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>remote-instance-weight-loader-start-seed-via-transfer-engine</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>set to start seed service that supports TransferEngine as backend. Needed for seed instances when using <code>transfer_engine</code> as backend.</td>
    </tr>
<tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>modelexpress-config</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>JSON config for <code>modelexpress</code> backend. Keys: <code>"url"</code> (optional gRPC host:port override) and <code>"transport"</code> (<code>"nixl"</code> or <code>"transfer_engine"</code>, defaults to <code>"nixl"</code>).</td>
    </tr>
</tbody>
</table>

### NCCL as backend

seed instance:
```shell Command
python -m sglang.launch_server [args]
```

client instance:
```shell Command
python -m sglang.launch_server [args] \
  --load-format remote_instance \
  --remote-instance-weight-loader-seed-instance-ip [seed_instance_ip] \
  --remote-instance-weight-loader-seed-instance-service-port [seed_instance_service_port] \
  --remote-instance-weight-loader-send-weights-group-ports [send_weights_nccl_group_ports_list]  \
  --remote-instance-weight-loader-backend nccl
```

### TransferEngine as backend

seed instance:
```shell Command
python -m sglang.launch_server [args] \
  --remote-instance-weight-loader-start-seed-via-transfer-engine
```

```shell Command
python -m sglang.launch_server [args] \
  --load-format remote_instance \
  --remote-instance-weight-loader-seed-instance-ip [seed_instance_ip] \
  --remote-instance-weight-loader-seed-instance-service-port [seed_instance_service_port] \
  --remote-instance-weight-loader-backend transfer_engine
```

### ModelExpress as backend

[ModelExpress](https://github.com/ai-dynamo/modelexpress) is a coordination service that manages P2P weight transfer metadata. It removes the need for direct seed IP/port configuration by providing a centralized registry that instances publish to and discover from. The ModelExpress Python package must be installed in the SGLang image.

A running ModelExpress server is required. See the [ModelExpress documentation](https://github.com/ai-dynamo/modelexpress) for setup instructions.

server instance:
```bash Command
python -m sglang.launch_server [args] \
  --load-format remote_instance \
  --remote-instance-weight-loader-backend modelexpress \
  --modelexpress-config '{"url": "[modelexpress_grpc_host:port]", "transport": "nixl"}'
```

All SGLang instances use the same command shape. If no ready source exists, the instance loads weights natively and publishes metadata to ModelExpress. If a compatible source exists, it loads weights through ModelExpress P2P transfer. Set <code>"transport": "transfer_engine"</code> to use Mooncake TransferEngine instead of the default NIXL transport.

---

### Docs Advanced Features Separate Reasoning (`docs/docs/advanced_features/separate_reasoning.mdx`)

---
title: "Reasoning Parser"
metatags:
    description: "SGLang reasoning parser: separate thinking content from output for DeepSeek R1, Qwen3, Kimi K2, GPT-OSS, and Apertus reasoning models."
---
SGLang supports parsing reasoning content out from "normal" content for reasoning models such as [DeepSeek R1](https://huggingface.co/deepseek-ai/DeepSeek-R1).

## Supported Models & Parsers

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Model</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Reasoning tags</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parser</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>[Apertus 2509 models](https://huggingface.co/swiss-ai/Apertus-8B-Instruct-2509)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`<|inner_prefix|>` … `<|inner_suffix|>`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`apertus2509`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Supports `enable_thinking` parameter</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>[DeepSeek‑R1 series](https://huggingface.co/collections/deepseek-ai/deepseek-r1-678e1e131c0169c0bc89728d)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`<think>` … `</think>`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`deepseek-r1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Supports all variants (R1, R1-0528, R1-Distill)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>[DeepSeek‑V3 series](https://huggingface.co/deepseek-ai/DeepSeek-V3.1)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`<think>` … `</think>`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`deepseek-v3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Including [DeepSeek‑V3.2](https://huggingface.co/deepseek-ai/DeepSeek-V3.2-Exp). Supports `thinking` parameter</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>[Standard Qwen3 models](https://huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f653967f)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`<think>` … `</think>`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`qwen3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Supports `enable_thinking` parameter</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>[Qwen3-Thinking models](https://huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`<think>` … `</think>`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`qwen3` or `qwen3-thinking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Always generates thinking content</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>[Kimi K2 Thinking](https://huggingface.co/moonshotai/Kimi-K2-Thinking)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`◁think▷` … `◁/think▷`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`kimi_k2`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Uses special thinking delimiters. Also requires `--tool-call-parser kimi_k2` for tool use.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>[GPT OSS](https://huggingface.co/openai/gpt-oss-120b)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`&lt;|channel|&gt;analysis&lt;|message|&gt;` … `&lt;|end|&gt;`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`gpt-oss`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>N/A</td>
    </tr>
  </tbody>
</table>
### Model-Specific Behaviors

**Apertus 2509:**
- Uses `<|inner_prefix|>` and `<|inner_suffix|>` to delimit reasoning content. For agentic tool use, also specify `--tool-call-parser apertus2509`.

**DeepSeek-R1 Family:**
- DeepSeek-R1: No `<think>` start tag, jumps directly to thinking content
- DeepSeek-R1-0528: Generates both `<think>` start and `</think>` end tags
- Both are handled by the same `deepseek-r1` parser

**DeepSeek-V3 Family:**
- DeepSeek-V3.1/V3.2: Hybrid model supporting both thinking and non-thinking modes, use the `deepseek-v3` parser and `thinking` parameter (NOTE: not `enable_thinking`)

**Qwen3 Family:**
- Standard Qwen3 (e.g., Qwen3-2507): Use `qwen3` parser, supports `enable_thinking` in chat templates
- Qwen3-Thinking (e.g., Qwen3-235B-A22B-Thinking-2507): Use `qwen3` or `qwen3-thinking` parser, always thinks

**Kimi K2:**
- Kimi K2 Thinking: Uses special `◁think▷` and `◁/think▷` tags. For agentic tool use, also specify `--tool-call-parser kimi_k2`.

**GPT OSS:**
- GPT OSS: Uses special `<|channel|>analysis<|message|>` and `<|end|>` tags


## Usage

### Launching the Server


Specify the `--reasoning-parser` option.


```python Example
import requests
from openai import OpenAI
from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process

server_process, port = launch_server_cmd(
    "python3 -m sglang.launch_server --model-path deepseek-ai/DeepSeek-R1-Distill-Qwen-7B --host 0.0.0.0 --reasoning-parser deepseek-r1 --log-level warning"
)

wait_for_server(f"http://localhost:{port}")
```

Note that `--reasoning-parser` defines the parser used to interpret responses.

To cap how many tokens the model spends thinking, see [Thinking Budget](/docs/advanced_features/thinking_budget).


### OpenAI Compatible API

Using the OpenAI compatible API, the contract follows the [DeepSeek API design](https://api-docs.deepseek.com/guides/reasoning_model) established with the release of DeepSeek-R1:

- `reasoning_content`: The content of the CoT.
- `content`: The content of the final answer.


```python Example
# Initialize OpenAI-like client
client = OpenAI(api_key="None", base_url=f"http://0.0.0.0:{port}/v1")
model_name = client.models.list().data[0].id

messages = [
    {
        "role": "user",
        "content": "What is 1+3?",
    }
]
```

#### Non-Streaming Request


```python Example
response_non_stream = client.chat.completions.create(
    model=model_name,
    messages=messages,
    temperature=0.6,
    top_p=0.95,
    stream=False,  # Non-streaming
    extra_body={"separate_reasoning": True},
)
print_highlight("==== Reasoning ====")
print_highlight(response_non_stream.choices[0].message.reasoning_content)

print_highlight("==== Text ====")
print_highlight(response_non_stream.choices[0].message.content)
```

#### Streaming Request


```python Example
response_stream = client.chat.completions.create(
    model=model_name,
    messages=messages,
    temperature=0.6,
    top_p=0.95,
    stream=True,  # Non-streaming
    extra_body={"separate_reasoning": True},
)

reasoning_content = ""
content = ""
for chunk in response_stream:
    if chunk.choices[0].delta.content:
        content += chunk.choices[0].delta.content
    if chunk.choices[0].delta.reasoning_content:
        reasoning_content += chunk.choices[0].delta.reasoning_content

print_highlight("==== Reasoning ====")
print_highlight(reasoning_content)

print_highlight("==== Text ====")
print_highlight(content)
```

Optionally, you can buffer the reasoning content to the last reasoning chunk (or the first chunk after the reasoning content).


```python Example
response_stream = client.chat.completions.create(
    model=model_name,
    messages=messages,
    temperature=0.6,
    top_p=0.95,
    stream=True,  # Non-streaming
    extra_body={"separate_reasoning": True, "stream_reasoning": False},
)

reasoning_content = ""
content = ""
for chunk in response_stream:
    if chunk.choices[0].delta.content:
        content += chunk.choices[0].delta.content
    if chunk.choices[0].delta.reasoning_content:
        reasoning_content += chunk.choices[0].delta.reasoning_content

print_highlight("==== Reasoning ====")
print_highlight(reasoning_content)

print_highlight("==== Text ====")
print_highlight(content)
```

The reasoning separation is enable by default when specify .
**To disable it, set the `separate_reasoning` option to `False` in request.**


```python Example
response_non_stream = client.chat.completions.create(
    model=model_name,
    messages=messages,
    temperature=0.6,
    top_p=0.95,
    stream=False,  # Non-streaming
    extra_body={"separate_reasoning": False},
)

print_highlight("==== Original Output ====")
print_highlight(response_non_stream.choices[0].message.content)
```

### SGLang Native API


```python Example
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("deepseek-ai/DeepSeek-R1-Distill-Qwen-7B")
input = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)

gen_url = f"http://localhost:{port}/generate"
gen_data = {
    "text": input,
    "sampling_params": {
        "skip_special_tokens": False,
        "max_new_tokens": 1024,
        "temperature": 0.6,
        "top_p": 0.95,
    },
}
gen_response = requests.post(gen_url, json=gen_data).json()["text"]

print_highlight("==== Original Output ====")
print_highlight(gen_response)

parse_url = f"http://localhost:{port}/separate_reasoning"
separate_reasoning_data = {
    "text": gen_response,
    "reasoning_parser": "deepseek-r1",
}
separate_reasoning_response_json = requests.post(
    parse_url, json=separate_reasoning_data
).json()
print_highlight("==== Reasoning ====")
print_highlight(separate_reasoning_response_json["reasoning_text"])
print_highlight("==== Text ====")
print_highlight(separate_reasoning_response_json["text"])
```


```python Example
terminate_process(server_process)
```

### Offline Engine API


```python Example
import sglang as sgl
from sglang.srt.parser.reasoning_parser import ReasoningParser
from sglang.utils import print_highlight

llm = sgl.Engine(model_path="deepseek-ai/DeepSeek-R1-Distill-Qwen-7B")
tokenizer = AutoTokenizer.from_pretrained("deepseek-ai/DeepSeek-R1-Distill-Qwen-7B")
input = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
sampling_params = {
    "max_new_tokens": 1024,
    "skip_special_tokens": False,
    "temperature": 0.6,
    "top_p": 0.95,
}
result = llm.generate(prompt=input, sampling_params=sampling_params)

generated_text = result["text"]  # Assume there is only one prompt

print_highlight("==== Original Output ====")
print_highlight(generated_text)

parser = ReasoningParser("deepseek-r1")
reasoning_text, text = parser.parse_non_stream(generated_text)
print_highlight("==== Reasoning ====")
print_highlight(reasoning_text)
print_highlight("==== Text ====")
print_highlight(text)
```


```python Example
llm.shutdown()
```

## Supporting New Reasoning Model Schemas

For future reasoning models, you can implement the reasoning parser as a subclass of `BaseReasoningFormatDetector` in `python/sglang/srt/reasoning_parser.py` and specify the reasoning parser for new reasoning model schemas accordingly.

---

### Docs Advanced Features Server Arguments (`docs/docs/advanced_features/server_arguments.mdx`)

---
title: "Server Arguments"
metatags:
    description: "SGLang server arguments: model selection, TP/DP parallelism, memory management, quantization, logging, and optimization options."
---
This page provides a list of server arguments used in the command line to configure the behavior
and performance of the language model server during deployment. These arguments enable users to
customize key aspects of the server, including model selection, parallelism policies,
memory management, and optimization techniques.
You can find all arguments by `python3 -m sglang.launch_server --help`

## Common launch commands

- To use a configuration file, create a YAML file with your server arguments and specify it with `--config`. CLI arguments will override config file values.

  ```bash Command
  # Create config.yaml
  cat > config.yaml << EOF
  model-path: meta-llama/Meta-Llama-3-8B-Instruct
  host: 0.0.0.0
  port: 30000
  tensor-parallel-size: 2
  enable-metrics: true
  log-requests: true
  EOF

  # Launch server with config file
  python -m sglang.launch_server --config config.yaml
  ```

- To enable multi-GPU tensor parallelism, add `--tp 2`. If it reports the error "peer access is not supported between these two devices", add `--enable-p2p-check` to the server launch command.

  ```bash Command
  python -m sglang.launch_server --model-path meta-llama/Meta-Llama-3-8B-Instruct --tp 2
  ```

- To enable multi-GPU data parallelism, add `--dp 2`. Data parallelism is better for throughput if there is enough memory. It can also be used together with tensor parallelism. The following command uses 4 GPUs in total. We recommend [SGLang Model Gateway (former Router)](../advanced_features/sgl_model_gateway) for data parallelism.

  ```bash Command
  python -m sglang_router.launch_server --model-path meta-llama/Meta-Llama-3-8B-Instruct --dp 2 --tp 2
  ```

- If you see out-of-memory errors during serving, try to reduce the memory usage of the KV cache pool by setting a smaller value of `--mem-fraction-static`.

  ```bash Command
  python -m sglang.launch_server --model-path meta-llama/Meta-Llama-3-8B-Instruct --mem-fraction-static 0.7
  ```

- See [hyperparameter tuning](./hyperparameter_tuning) on tuning hyperparameters for better performance.
- For docker and Kubernetes runs, you need to set up shared memory which is used for communication between processes. See `--shm-size` for docker and `/dev/shm` size update for Kubernetes manifests.
- If you see out-of-memory errors during prefill for long prompts, try to set a smaller chunked prefill size.

  ```bash Command
  python -m sglang.launch_server --model-path meta-llama/Meta-Llama-3-8B-Instruct --chunked-prefill-size 4096
  ```
- To enable fp8 weight quantization, add `--quantization fp8` on a fp16 checkpoint or directly load a fp8 checkpoint without specifying any arguments.
- To enable fp8 kv cache quantization, add `--kv-cache-dtype fp8_e4m3` or `--kv-cache-dtype fp8_e5m2`.
- To enable deterministic inference and batch invariant operations, add `--enable-deterministic-inference`. More details can be found in [deterministic inference document](./deterministic_inference).
- If a multimodal server accepts requests from untrusted clients, restrict remote image, video, and audio URLs with `--allowed-media-domains`. SGLang checks the initial URL and every redirect destination against the exact-hostname allowlist. Remote media downloads are limited to 64 MiB by default; adjust `--media-url-max-file-size-mb` when larger trusted media is required.

  ```bash Command
  python -m sglang.launch_server \
    --model-path Qwen/Qwen2.5-VL-7B-Instruct \
    --allowed-media-domains upload.wikimedia.org raw.githubusercontent.com
  ```

  Without `--allowed-media-domains`, HTTP(S) media from any domain remains allowed for backward compatibility. Do not expose that configuration to untrusted users. Local paths and `data:` URLs are not governed by the domain allowlist.
- To enable decode context parallelism for MLA models, add `--dcp-size N`. See [Decode Context Parallelism](./dcp).
- If the model does not have a chat template in the Hugging Face tokenizer, you can specify a [custom chat template](../references/custom_chat_template). If the tokenizer has multiple named templates (e.g., 'default', 'tool_use'), you can select one using `--hf-chat-template-name tool_use`.
- To run tensor parallelism on multiple nodes, add `--nnodes 2`. If you have two nodes with two GPUs on each node and want to run TP=4, let `sgl-dev-0` be the hostname of the first node and `50000` be an available port, you can use the following commands. If you meet deadlock, please try to add `--disable-cuda-graph`
- (Note: This feature is out of maintenance and might cause error) To enable `torch.compile` acceleration, add `--enable-torch-compile`. It accelerates small models on small batch sizes. By default, the cache path is located at `/tmp/torchinductor_root`, you can customize it using environment variable `TORCHINDUCTOR_CACHE_DIR`. For more details, please refer to [PyTorch official documentation](https://pytorch.org/tutorials/recipes/torch_compile_caching_tutorial.html) and [Enabling cache for torch.compile](../references/torch_compile_cache).
  ```bash Command
  # Node 0
  python -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3-8B-Instruct \
    --tp 4 \
    --dist-init-addr sgl-dev-0:50000 \
    --nnodes 2 \
    --node-rank 0

  # Node 1
  python -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3-8B-Instruct \
    --tp 4 \
    --dist-init-addr sgl-dev-0:50000 \
    --nnodes 2 \
    --node-rank 1
  ```

Please consult the documentation below and [server_args.py](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/server_args.py) to learn more about the arguments you may provide when launching a server.

## Model and tokenizer
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--model-path`<br/>`--model`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the model weights. This can be a local folder or a Hugging Face repo ID.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tokenizer-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the tokenizer.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tokenizer-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Tokenizer mode. 'auto' will use the fast tokenizer if available, and 'slow' will always use the slow tokenizer.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>slow</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tokenizer-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Tokenizer backend. 'huggingface' uses the default HuggingFace tokenizers library; 'fastokens' uses the <a href="https://github.com/crusoecloud/fastokens">fastokens</a> library for faster tokenization. Requires the <code>fastokens</code> package to be installed.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`huggingface`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>huggingface</code>, <code>fastokens</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tokenizer-worker-num`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The worker num of the tokenizer manager.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--skip-tokenizer-init`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If set, skip init tokenizer and pass input_ids in generate request.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--load-format`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The format of the model weights to load. "auto" will try to load the weights in the safetensors format and fall back to the pytorch bin format if safetensors format is not available. "pt" will load the weights in the pytorch bin format. "safetensors" will load the weights in the safetensors format. "instanttensor" will load Safetensors weights using InstantTensor's high-performance distributed loader. "npcache" will load the weights in pytorch format and store a numpy cache to speed up the loading. "dummy" will initialize the weights with random values, which is mainly for profiling."gguf" will load the weights in the gguf format. "bitsandbytes" will load the weights using bitsandbytes quantization."layered" loads weights layer by layer so that one can quantize a layer before loading another to make the peak memory envelope smaller. "flash_rl" will load the weights in flash_rl format. "fastsafetensors" and "private" are also supported. "runai_streamer" enables direct model loading from object storage and shared file systems.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>pt</code>, <code>safetensors</code>, <code>instanttensor</code>, <code>npcache</code>, <code>dummy</code>, <code>sharded_state</code>, <code>gguf</code>, <code>bitsandbytes</code>, <code>mistral</code>, <code>layered</code>, <code>flash_rl</code>, <code>remote</code>, <code>remote_instance</code>, <code>fastsafetensors</code>, <code>private</code>, <code>runai_streamer</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--model-loader-extra-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Extra config for model loader. This will be passed to the model loader corresponding to the chosen load_format.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`{}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--trust-remote-code`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Whether or not to allow for custom models defined on the Hub in their own modeling files.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--context-length`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The model's maximum context length. Defaults to None (will use the value from the model's config.json instead).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--is-embedding`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Whether to use a CausalLM as an embedding model.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-multimodal`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable the multimodal functionality for the served model. If the model being served is not multimodal, nothing will happen.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--revision`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The specific model version to use. It can be a branch name, a tag name, or a commit id. If unspecified, will use the default version.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--model-impl`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Which implementation of the model to use. "auto" will try to use the SGLang implementation if it exists and fall back to the Transformers implementation if no SGLang implementation is available. "sglang" will use the SGLang model implementation. "transformers" will use the Transformers model implementation.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--detokenizer-worker-num`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The worker num of the detokenizer manager.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-only-disable-kv-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Skip the physical KV cache allocation for embedding-mode prefill-only workloads. Currently only valid with --is-embedding, --chunked-prefill-size=-1, --disable-radix-cache, an FA prefill backend, and non-FP4 KV cache so the fa_skip_kv_cache path is active (no layer reads or writes the cache). Other prefill-only workloads such as scoring/MIS may benefit from this later once their attention paths stop using paged KV. Scheduler admission accounting is unchanged; per-layer K/V tensors are sized to (page_size, head_num, head_dim) placeholders so GPU memory is not wasted.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--model-config-parser`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Which model-config parser to use. "auto" picks "mistral" via the is_mistral_model name heuristic, else "hf" (AutoConfig over config.json). Plugins can register additional parsers via @register_model_config_parser.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
</tbody>
</table>

## HTTP server
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--host`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The host of the HTTP server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`127.0.0.1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The port of the HTTP server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`30000`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--fastapi-root-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>App is behind a path based routing proxy.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`""`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--grpc-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If set, use gRPC server instead of HTTP server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--skip-server-warmup`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If set, skip warmup.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--warmups`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Specify custom warmup functions (csv) to run before server starts eg. --warmups=warmup_name1,warmup_name2 will run the functions `warmup_name1` and `warmup_name2` specified in warmup.py before the server starts listening for requests</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--nccl-port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The port for NCCL distributed environment setup. Defaults to a random port.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--checkpoint-engine-wait-weights-before-ready`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If set, the server will wait for initial weights to be loaded via checkpoint-engine or other update methods before serving inference requests.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ssl-keyfile`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The file path to the SSL key file.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ssl-certfile`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The file path to the SSL certificate file.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ssl-ca-certs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The CA certificates file.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ssl-keyfile-password`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The password to decrypt the SSL keyfile.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-ssl-refresh`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable automatic SSL certificate hot-reloading when cert/key files change on disk. Requires --ssl-certfile and --ssl-keyfile.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-http-worker-reuseport`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Give each Uvicorn HTTP worker its own SO_REUSEPORT listener.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-http2`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Use Granian instead of Uvicorn as the ASGI server, enabling HTTP/1.1 and HTTP/2 auto-negotiation. Clients may use h2c (cleartext HTTP/2) or plain HTTP/1.1. Requires 'pip install sglang[http2]'.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--http2-max-concurrent-streams`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum number of concurrent streams advertised on each HTTP/2 connection (1 to 2^32 - 1). Only applies with --enable-http2.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`200`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
</tbody>
</table>

## Quantization and data type
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dtype`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Data type for model weights and activations. * "auto" will use FP16 precision for FP32 and FP16 models, and BF16 precision for BF16 models. * "half" for FP16. Recommended for AWQ quantization. * "float16" is the same as "half". * "bfloat16" for a balance between precision and range. * "float" is shorthand for FP32 precision. * "float32" for FP32 precision.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>half</code>, <code>float16</code>, <code>bfloat16</code>, <code>float</code>, <code>float32</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--quantization`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The quantization method.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>awq</code>, <code>fp8</code>, <code>mxfp8</code>, <code>gptq</code>, <code>marlin</code>, <code>gptq_marlin</code>, <code>awq_marlin</code>, <code>bitsandbytes</code>, <code>gguf</code>, <code>modelopt</code>, <code>modelopt_fp8</code>, <code>modelopt_fp4</code>, <code>nvfp4_online</code>, <code>modelopt_mixed</code>, <code>petit_nvfp4</code>, <code>w8a8_int8</code>, <code>w8a8_fp8</code>, <code>moe_wna16</code>, <code>w4afp8</code>, <code>mxfp4</code>, <code>auto-round</code>, <code>compressed-tensors</code>, <code>modelslim</code>, <code>quark</code>, <code>quark_int4fp8_moe</code>, <code>quark_mxfp4</code>, <code>mlx_q4</code>, <code>mlx_q8</code>, <code>unquant</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--quantization-param-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to the JSON file containing the KV cache scaling factors. This should generally be supplied, when KV cache dtype is FP8. Otherwise, KV cache scaling factors default to 1.0, which may cause accuracy issues.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: Optional[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kv-cache-dtype`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Data type for kv cache storage. "auto" will use model data type. "bf16" or "bfloat16" for BF16 KV cache. "fp8_e5m2" and "fp8_e4m3" are supported for CUDA 11.8+. "nvfp4" selects the NVFP4 FP4 E2M1 KV cache recipe; "fp4_mx_block16" selects the block-size-16 FP4 E2M1 KV cache recipe. Both require CUDA 12.8+ and PyTorch 2.8.0+</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>fp8_e5m2</code>, <code>fp8_e4m3</code>, <code>bf16</code>, <code>bfloat16</code>, <code>nvfp4</code>, <code>fp4_mx_block16</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-fp32-lm-head`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If set, the LM head outputs (logits) are in FP32.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--modelopt-quant`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The ModelOpt quantization configuration. Supported values: 'fp8', 'int4_awq', 'w4a8_awq', 'nvfp4', 'nvfp4_awq'. This requires the NVIDIA Model Optimizer library to be installed: pip install nvidia-modelopt</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--modelopt-checkpoint-restore-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to restore a previously saved ModelOpt quantized checkpoint. If provided, the quantization process will be skipped and the model will be loaded from this checkpoint.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--modelopt-checkpoint-save-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to save the ModelOpt quantized checkpoint after quantization. This allows reusing the quantized model in future runs.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--modelopt-export-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to export the quantized model in HuggingFace format after ModelOpt quantization. The exported model can then be used directly with SGLang for inference. If not provided, the model will not be exported.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--quantize-and-serve`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Quantize the model with ModelOpt and immediately serve it without exporting. This is useful for development and prototyping. For production, it's recommended to use separate quantization and deployment steps.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--rl-quant-profile`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to the FlashRL quantization profile. Required when using --load-format flash_rl.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-quant-communications`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable INT8 quantization of TP communications (Supported only for NPU for Qwen3 series).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-tf32-matmul`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable float32 matmuls to use TensorFloat32 precision for better performance (via torch.set_float32_matmul_precision). CUDA only. Automatically enabled for MiniMax-M2 and GLM-4 models.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
  </tbody>
</table>

## Memory and scheduling
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mem-fraction-static`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The fraction of the memory used for static allocation (model weights and KV cache memory pool). Use a smaller value if you see out-of-memory errors. When unset, it is computed as `(GPU memory - reserved memory) / GPU memory`, defaulting to `0.88` if GPU memory cannot be detected.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-running-requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum number of running requests.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-queued-requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum number of queued requests. This option is ignored when using disaggregation-mode.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-total-tokens`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum number of tokens in the memory pool. If not specified, it will be automatically calculated based on the memory usage fraction. This option is typically used for development and debugging purposes.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--chunked-prefill-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum number of tokens in a chunk for the chunked prefill. Setting this to -1 means disabling chunked prefill.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-decode-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of decode rounds to run after a prefill batch before scheduling the next prefill. By default, this is disabled except for profiled Qwen3-VL serving configurations on Hopper. In data-parallel attention mode, the interval is synchronized across all DP ranks. Set to 0 to disable.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-decode-interval-min-bs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Apply `--prefill-decode-interval` only while the running batch holds at least this many requests. Below it, prefill is admitted every round so the batch fills quickly. In data-parallel attention mode, each rank compares its own running batch. Set to 0 to always apply the interval.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-max-requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum number of requests in a prefill batch. If not specified, there is no limit.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-dynamic-chunking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable dynamic chunk size adjustment for pipeline parallelism. When enabled, chunk sizes are dynamically calculated based on fitted function to maintain consistent execution time across chunks.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-prefill-tokens`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum number of tokens in a prefill batch. The real bound will be the maximum of this value and the model's maximum context length.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`16384`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--schedule-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The scheduling policy of the requests.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`fcfs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>lpm</code>, <code>random</code>, <code>fcfs</code>, <code>dfs-weight</code>, <code>lof</code>, <code>priority</code>, <code>routing-key</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-priority-scheduling`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable priority scheduling. Requests with higher priority integer values will be scheduled first by default.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--abort-on-priority-when-disabled`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If set, abort requests that specify a priority when priority scheduling is disabled.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--schedule-low-priority-values-first`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If specified with --enable-priority-scheduling, the scheduler will schedule requests with lower priority integer values first.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--priority-scheduling-preemption-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Minimum difference in priorities for an incoming request to have to preempt running request(s).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`10`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--schedule-conservativeness`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>How conservative the schedule policy is. A larger value means more conservative scheduling. Use a larger value if you see requests being retracted frequently.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--retraction-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The decode retraction policy to use when the KV cache is full. 'length' preserves the existing behavior and retracts short-output, long-input requests first. 'priority' retracts lower-priority requests first, using the same priority direction as priority scheduling.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`length`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>length</code>, <code>priority</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--page-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of tokens in a page.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-page-major-kv-layout`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Store the Mamba state and full/SWA KV caches as one entry per token slot, holding every layer's state, in a single page-granular buffer instead of one buffer per layer. Implied by `--enable-unified-memory`, and currently supported only with it.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-unified-memory`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>For hybrid Mamba/GDN and hybrid SWA models, replace the statically-partitioned pools (full-attention KV + SWA/Mamba conv/SSM state) with a single byte buffer split dynamically between the sub-pools, so KV-vs-state capacity flexes with the workload instead of being fixed at startup. Implies `--enable-page-major-kv-layout`. Requires stride-aware attention, linear-attention and Mamba backends; the allowed backends and the supported PD-disaggregation and speculative-decoding configurations are validated at startup.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--swa-full-tokens-ratio`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The ratio of SWA layer KV tokens / full layer KV tokens, regardless of the number of swa:full layers. It should be between 0 and 1. E.g. 0.5 means if each swa layer has 50 tokens, then each full layer has 100 tokens.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0.8`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-hybrid-swa-memory`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable the hybrid SWA memory.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--radix-eviction-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The eviction policy of radix trees. 'lru' stands for Least Recently Used, 'lfu' stands for Least Frequently Used.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`lru`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>lru</code>, <code>lfu</code>, <code>slru</code>, <code>priority</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-prefill-delayer`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable prefill delayer for DP attention to reduce idle time.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-delayer-max-delay-passes`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum forward passes to delay prefill.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`30`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-delayer-token-usage-low-watermark`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Token usage low watermark for prefill delayer.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-delayer-queue-min-ratio`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Opt-in to the adaptive queue-based delay trigger (independent of the slot-based one). Defers prefill until the waiting queue reaches `min(running_req * ratio, max_prefill_bs)` so small fragments batch into a larger prefill. Unset keeps the original slot-only behavior. Typical: `0.1`–`0.5`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-delayer-max-delay-ms`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Wall-clock cap (ms) on a single queue-trigger delay; once exceeded, prefill is force-released to bound worst-case TTFT. Only consulted when `--prefill-delayer-queue-min-ratio` is set. Typical: `1000`–`5000`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-delayer-forward-passes-buckets`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Custom buckets for prefill delayer forward passes histogram. 0 and max_delay_passes-1 will be auto-added.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[float]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-delayer-wait-seconds-buckets`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Custom buckets for prefill delayer wait seconds histogram. 0 will be auto-added.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[float]</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-priority-preemption`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable priority scheduling preemption.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--default-priority-value`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Default priority for requests without explicit priority.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
</tbody>
</table>

## Runtime options
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--device`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The device to use ('cuda', 'xpu', 'hpu', 'npu', 'cpu'). Defaults to auto-detection if not specified.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tensor-parallel-size`<br/>`--tp-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The tensor parallelism size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pipeline-parallel-size`<br/>`--pp-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The pipeline parallelism size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--attention-context-parallel-size`<br/>`--attn-cp-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The attention context parallelism size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dcp-size`<br/>`--decode-context-parallel-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The decode context parallelism size. See <a href="/docs/advanced_features/dcp">Decode Context Parallelism</a>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dcp-comm-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Communication backend for the DCP attention reduction: AllGather + ReduceScatter, one All-to-All exchange, or FlashInfer MNNVL All-to-All. Unset resolves to <code>fi_a2a</code> where the DCP group shares an MNNVL domain on Blackwell, else <code>a2a</code> on CUDA/ROCm/XPU, else <code>ag_rs</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>ag_rs</code>, <code>a2a</code>, <code>fi_a2a</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dcp-replicate-q-proj`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>For MLA DCP with the a2a/fi_a2a backend: replicate the Q projection so each DCP rank computes the full-head query locally. Use <code>--no-dcp-replicate-q-proj</code> to disable the model-specific default.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--moe-data-parallel-size`<br/>`--moe-dp-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The moe data parallelism size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pp-max-micro-batch-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum micro batch size in pipeline parallelism.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pp-async-batch-depth`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The async batch depth of pipeline parallelism.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--stream-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The interval (or buffer size) for streaming in terms of the token length. A smaller value makes streaming smoother, while a larger value makes the throughput higher</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--incremental-streaming-output`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Whether to output as a sequence of disjoint segments.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--random-seed`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The random seed.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mlx-enable-sampling`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>MLX backend only: sample decode tokens (temperature / top-k / top-p / min-p) instead of greedy argmax. Sampling runs inside the lazy MLX graph, so it works with the overlap scheduler; first tokens from prefill/extend are sampled too. Greedy requests keep exact argmax behavior. Also enables on the MLX path: grammar vocab masks and custom logit processors (these break decode chaining per step; custom processors run on pure-decode steps only), logit_bias, output logprobs (sampled token / top-k / token_ids; prompt input logprobs are not computed), NaN sanitization (SGLANG_SANITIZE_NAN_LOGITS), and per-request sampling_seed under --enable-deterministic-inference (deterministic within MLX only). Penalties are not applied.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--constrained-json-whitespace-pattern`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>(outlines and llguidance backends only) Regex pattern for syntactic whitespaces allowed in JSON constrained output. For example, to allow the model to generate consecutive whitespaces, set the pattern to [\n\t ]*</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--constrained-json-disable-any-whitespace`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>(xgrammar and llguidance backends only) Enforce compact representation in JSON constrained output.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--watchdog-timeout`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set watchdog timeout in seconds. If a forward batch takes longer than this, the server will crash to prevent hanging.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`300`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--soft-watchdog-timeout`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set soft watchdog timeout in seconds. If a forward batch takes longer than this, the server will dump information for debugging.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dist-timeout`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set timeout for torch.distributed initialization.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--download-dir`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Model download directory for huggingface.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--model-checksum`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Model file integrity verification. If provided without value, uses model-path as HF repo ID. Otherwise, provide checksums JSON file path or HuggingFace repo ID.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--base-gpu-id`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The base GPU ID to start allocating GPUs from. Useful when running multiple instances on the same machine.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--gpu-id-step`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The delta between consecutive GPU IDs that are used. For example, setting it to 2 will use GPU 0,2,4,...</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--sleep-on-idle`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Reduce CPU usage when sglang is idle.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--batch-notify-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of streaming notifications to batch before yielding to the event loop. Reduces asyncio wakeup overhead under high concurrency.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`16`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--stream-response-default-include-usage`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Include usage in every streaming response (even when stream_options is not specified).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-streaming-session`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable streaming session mode and StreamingSession wrapper.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--load-snapshot-publish-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Publish load snapshot to shared memory every N decode iterations. Prefill and idle always publish immediately.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`15`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--use-ray`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Use Ray actors for scheduler process management.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
</tbody>
</table>

## Logging
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--log-level`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The logging level of all loggers.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`info`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--log-level-http`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The logging level of HTTP server. If not set, reuse --log-level by default.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--log-requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Log metadata, inputs, outputs of all requests. The verbosity is decided by --log-requests-level</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--log-requests-level`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0: Log metadata (no sampling parameters). 1: Log metadata and sampling parameters. 2: Log metadata, sampling parameters and partial input/output. 3: Log every input/output.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`2`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>0</code>, <code>1</code>, <code>2</code>, <code>3</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--log-requests-format`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Format for request logging: 'text' (human-readable) or 'json' (structured)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`text`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>text</code>, <code>json</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--log-requests-target`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Target(s) for request logging: 'stdout' and/or directory path(s) for file output. Can specify multiple targets, e.g., '--log-requests-target stdout /my/path'.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--uvicorn-access-log-exclude-prefixes`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Exclude uvicorn access logs whose request path starts with any of these prefixes. Defaults to empty (disabled).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`[]`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--crash-dump-folder`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Folder for crash diagnostics. Stores completed requests retained by the crash-dump buffer plus in-flight requests and, on NVIDIA CUDA, configures device coredumps under this folder. Existing CUDA coredump environment variables take precedence. If not specified, this option does not enable request crash dumping or set CUDA coredump defaults.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--show-time-cost`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Show time cost of custom marks.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-metrics`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable log prometheus metrics.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-mfu-metrics`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable estimated MFU-related prometheus metrics.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-metrics-for-all-schedulers`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable --enable-metrics-for-all-schedulers when you want schedulers on all TP ranks (not just TP 0) to record request metrics separately. This is especially useful when dp_attention is enabled, as otherwise all metrics appear to come from TP 0.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tokenizer-metrics-custom-labels-header`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Specify the HTTP header for passing custom labels for tokenizer metrics.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`x-custom-labels`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tokenizer-metrics-allowed-custom-labels`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The custom labels allowed for tokenizer metrics. The labels are specified via a dict in '--tokenizer-metrics-custom-labels-header' field in HTTP requests, e.g., &#123;'label1': 'value1', 'label2': 'value2'&#125; is allowed if '--tokenizer-metrics-allowed-custom-labels label1 label2' is set.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--bucket-time-to-first-token`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The buckets of time to first token, specified as a list of floats.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[float]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--bucket-inter-token-latency`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The buckets of inter-token latency, specified as a list of floats.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[float]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--bucket-e2e-request-latency`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The buckets of end-to-end request latency, specified as a list of floats.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[float]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prompt-tokens-buckets`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The buckets rule of prompt tokens. Supports 3 rule types: 'default' uses predefined buckets; 'tse &lt;middle&gt; &lt;base&gt; &lt;count&gt;' generates two sides exponential distributed buckets (e.g., 'tse 1000 2 8' generates buckets [984.0, 992.0, 996.0, 998.0, 1000.0, 1002.0, 1004.0, 1008.0, 1016.0]).); 'custom &lt;value1&gt; &lt;value2&gt; ...' uses custom bucket values (e.g., 'custom 10 50 100 500').</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--generation-tokens-buckets`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The buckets rule for generation tokens histogram. Supports 3 rule types: 'default' uses predefined buckets; 'tse &lt;middle&gt; &lt;base&gt; &lt;count&gt;' generates two sides exponential distributed buckets (e.g., 'tse 1000 2 8' generates buckets [984.0, 992.0, 996.0, 998.0, 1000.0, 1002.0, 1004.0, 1008.0, 1016.0]).); 'custom &lt;value1&gt; &lt;value2&gt; ...' uses custom bucket values (e.g., 'custom 10 50 100 500').</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--gc-warning-threshold-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The threshold for long GC warning. If a GC takes longer than this, a warning will be logged. Set to 0 to disable.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--decode-log-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The log interval of decode batch.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`40`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-request-time-stats-logging`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable per request time stats logging</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kv-events-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Config in json format for NVIDIA dynamo KV event publishing. Publishing will be enabled if this flag is used. Runtime-load publishing for load-aware routers is a separate opt-in; see `--load-publish-endpoint`. Set `replay_endpoint` (e.g. `tcp://*:5558`) to let routers re-fetch dropped batches; `/server_info` advertises its port.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--load-publish-endpoint`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Opt in to the runtime-load PUB socket that load-aware routers subscribe to. Off by default (unset or `off`). Use `auto` to reserve the dp_size ports packed after the `--kv-events-config` range, or a wildcard-host TCP address (e.g. `tcp://*:6000`) to place it explicitly; rank r binds port+r and `/server_info` advertises the base under the `kv_events` block. Requires `--kv-events-config`; startup fails if set without one, not bindable, or overlapping the KV range. `auto` reserves 2*dp_size ports from the KV base — space co-hosted engines accordingly. The router-facing update cadence follows `--load-snapshot-publish-interval`, so a large value there also staleness-caps this feed.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-trace`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable opentelemetry trace</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--trace-modules`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select the components to trace. Available options are 'request' and 'mooncake'. Format: &lt;module1 name&gt;,&lt;module2 name&gt;,......</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`request`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--otlp-traces-endpoint`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Config opentelemetry collector endpoint if --enable-trace is set. format: &lt;ip&gt;:&lt;port&gt;</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`localhost:4317`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--grpc-http-sidecar-port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Port for the HTTP sidecar server in gRPC mode (--grpc-mode). Serves Prometheus metrics and profiling endpoints. Defaults to --port + 1. Not used in HTTP mode.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--extra-metric-labels`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The custom labels for metrics. e.g. '&#123;"label1": "value1", "label2": "value2"&#125;'</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-forward-pass-metrics`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable per-iteration forward pass metrics via ZMQ IPC. External consumers (e.g. Dynamo planner) subscribe to the IPC endpoint exposed in server_args.forward_pass_metrics_ipc_name.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--forward-pass-metrics-worker-id`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>—</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`""`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--forward-pass-metrics-ipc-name`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>—</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
</tbody>
</table>

## RequestMetricsExporter configuration
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--export-metrics-to-file`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Export performance metrics for each request to local file (e.g. for forwarding to external systems).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--export-metrics-to-file-dir`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Directory path for writing performance metrics files (required when --export-metrics-to-file is enabled).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

## Responses storage

Responses storage is now disabled by default, including on standalone servers. Add `--enable-response-store` to retain responses for retrieval, `previous_response_id` chaining, and background requests. Storage is process-local and in-memory, has no TTL or size limit, and is lost on restart.

Foreground generation and streaming still accept the API's default `store: true` without retaining responses or message history when server storage is disabled. The response's `store` field echoes the client request; the server flag controls persistence. With storage enabled, `store: false` opts out for the current request while allowing it to read a stored predecessor.

Background requests, including streaming requests, require both `--enable-response-store` and `store: true`. Without the flag, chaining, background requests, retrieval, and cancellation return HTTP 400. Cancellation applies to detached background requests; active streams have no stored response until completion.

Combining `--enable-response-store` with `--disaggregation-mode=prefill` or `decode` fails at startup. PD clients must send explicit conversation history in foreground requests. Built-in web search and code interpreter calls are also unsupported under PD.

## API related
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--api-key`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set API key of the server. It is also used in the OpenAI API compatible server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--admin-api-key`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set <strong>admin API key</strong> for administrative/control endpoints (e.g., weights update, cache flush, <code>/server_info</code>). Endpoints marked as admin-only require <code>Authorization: Bearer &lt;admin_api_key&gt;</code> when this is set.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--served-model-name`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Override the model name returned by the v1/models endpoint in OpenAI API server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--weight-version`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Version identifier for the model weights. Defaults to 'default' if not specified.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`default`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--chat-template`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The builtin chat template name or the path of the chat template file. This is only used for OpenAI-compatible API server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hf-chat-template-name`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>When the HuggingFace tokenizer has multiple chat templates (e.g., 'default', 'tool_use', 'rag'), specify which named template to use. If not set, the first available template is used.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--default-chat-template-kwargs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>A JSON object used as defaults for <code>chat_template_kwargs</code> by Chat Completions, Responses, Anthropic-compatible requests, and chat tokenization. Direct Ollama and embedding paths do not consume these defaults. For ordinary template keys, explicit per-request values take precedence. Keys are specific to the selected model's chat template; <code>reasoning_effort</code> is normalized separately.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON / Dict</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--completion-template`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The builtin completion template name or the path of the completion template file. This is only used for OpenAI-compatible API server. only for code completion currently.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--file-storage-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the file storage in backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`sglang_storage`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-cache-report`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Return number of cached tokens in usage.prompt_tokens_details for each openai request.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--reasoning-parser`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Specify the parser for reasoning models. Use `auto` to detect the parser from the model's chat template.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>apertus2509</code>, <code>deepseek-r1</code>, <code>deepseek-v3</code>, <code>deepseek-v4</code>, <code>dots</code>, <code>glm45</code>, <code>ling3</code>, <code>hunyuan</code>, <code>gpt-oss</code>, <code>k2_horizon</code>, <code>kimi</code>, <code>kimi_k2</code>, <code>kimi_k3</code>, <code>mimo</code>, <code>muse</code>, <code>poolside_v1</code>, <code>qwen3</code>, <code>qwen3-thinking</code>, <code>minimax</code>, <code>minimax-append-think</code>, <code>minimax-m3</code>, <code>step3</code>, <code>step3p5</code>, <code>mistral</code>, <code>nemotron_3</code>, <code>interns1</code>, <code>gemma4</code>, <code>gigachat35</code>, <code>inkling</code>, <code>cohere_command4</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tool-call-parser`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Specify the parser for handling tool-call interactions. Use `auto` to detect the parser from the model's chat template.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>apertus2509</code>, <code>cohere_command4</code>, <code>deepseekv3</code>, <code>deepseekv31</code>, <code>deepseekv32</code>, <code>deepseekv4</code>, <code>dots</code>, <code>glm</code>, <code>glm45</code>, <code>glm47</code>, <code>gpt-oss</code>, <code>k2_horizon</code>, <code>kimi_k2</code>, <code>kimi_k3</code>, <code>lfm2</code>, <code>ling3</code>, <code>llama3</code>, <code>mimo</code>, <code>minicpm5</code>, <code>mistral</code>, <code>muse</code>, <code>poolside_v1</code>, <code>pythonic</code>, <code>qwen</code>, <code>qwen25</code>, <code>qwen3_coder</code>, <code>spark25</code>, <code>step3</code>, <code>step3p5</code>, <code>minimax-m2</code>, <code>minimax-m3</code>, <code>trinity</code>, <code>interns1</code>, <code>hermes</code>, <code>hunyuan</code>, <code>gigachat3</code>, <code>gigachat35</code>, <code>gemma4</code>, <code>inkling</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tool-server`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Either 'demo' or a comma-separated list of tool server urls to use for the model. If not specified, no external tool server will be used. Native GPT-OSS `web_search` can still be enabled with `EXA_API_KEY`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--sampling-defaults`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Where to get default sampling parameters. 'openai' uses SGLang/OpenAI defaults (temperature=1.0, top_p=1.0, etc.). 'model' uses the model's generation_config.json to get the recommended sampling parameters if available. Default is 'model'.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`model`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>openai</code>, <code>model</code></td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--strip-thinking-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Skip caching reasoning-model output (thinking + answer) in the radix tree on finish; keep only the prompt prefix. Opt-in: changes cache contents.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-strict-thinking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable strict token filtering during the thinking phase. Blocks model-specific excluded tokens (e.g., tool call markers) during reasoning. Requires a grammar backend that supports token filtering. See <a href="/docs/advanced_features/thinking_budget">Thinking Budget</a> for per-request thinking caps.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--asr-max-buffer-seconds`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum seconds of PCM audio the streaming ASR WebSocket handler will accumulate before closing the session with a buffer_overflow error. Guards against OOM when a client streams audio faster than inference can consume it. Default 60s.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`60`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--asr-max-concurrent-sessions`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum number of concurrent realtime ASR WebSocket sessions served by /v1/realtime. New connections beyond this cap are accepted, sent an error&#123;code:too_many_sessions&#125; frame, and closed. Default 32.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`32`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
</tbody>
</table>

## Data parallelism
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--data-parallel-size`<br/>`--dp-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of data-parallel replicas of the model.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--attention-data-parallel-size`<br/>`--attn-dp-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The attention data parallelism size: the number of data-parallel attention groups inside the TP group, one scheduler each, while the FFN stays tensor parallel.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--load-balance-method`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The load balancing strategy for data parallelism. The `total_tokens` algorithm can only be used when DP attention is applied. This algorithm performs load balancing based on the real-time token load of the DP workers.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>round_robin</code>, <code>follow_bootstrap_room</code>, <code>total_requests</code>, <code>total_tokens</code></td>
    </tr>
  </tbody>
</table>

## Multi-node distributed serving
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dist-init-addr`<br/>`--nccl-init-addr`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The host address for initializing distributed backend (e.g., `192.168.0.2:25000`).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--nnodes`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of nodes.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--node-rank`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The node rank.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
  </tbody>
</table>

## Model override args
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--json-model-override-args`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>A dictionary in JSON string format used to override default model configurations.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`{}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--preferred-sampling-params`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>json-formatted sampling settings that will be returned in /get_model_info</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

## LoRA
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-lora`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable LoRA support for the model. This argument is automatically set to `True` if `--lora-paths` is provided for backward compatibility.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-lora-overlap-loading`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable asynchronous LoRA weight loading in order to overlap H2D transfers with GPU compute. This should be enabled if you find that your LoRA workloads are bottlenecked by adapter weight loading, for example when frequently loading large LoRA adapters.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-lora-rank`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum LoRA rank that should be supported. If not specified, it will be automatically inferred from the adapters provided in <code>--lora-paths</code>. This argument is needed when you expect to dynamically load adapters of larger LoRA rank after server startup.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lora-target-modules`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The union set of all target modules where LoRA should be applied (e.g., <code>q_proj</code>, <code>k_proj</code>, <code>gate_proj</code>). If not specified, it will be automatically inferred from the adapters provided in <code>--lora-paths</code>. You can also set it to <code>all</code> to enable LoRA for all supported modules; note this may introduce minor performance overhead.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>q_proj</code>, <code>k_proj</code>, <code>v_proj</code>, <code>o_proj</code>, <code>gate_proj</code>, <code>up_proj</code>, <code>down_proj</code>, <code>qkv_proj</code>, <code>gate_up_proj</code>, <code>all</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lora-paths`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The list of LoRA adapters to load. Each adapter must be specified in one of the following formats: <code>&lt;PATH&gt;</code> \| <code>&lt;NAME&gt;=&lt;PATH&gt;</code> \| JSON with schema <code>&#123;"lora_name": str, "lora_path": str, "pinned": bool&#125;</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: List[str] / JSON objects</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-loras-per-batch`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum number of adapters for a running batch, including base-only requests.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`8`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-loaded-loras`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>If specified, limits the maximum number of LoRA adapters loaded in CPU memory at a time. Must be ≥ <code>--max-loras-per-batch</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lora-eviction-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>LoRA adapter eviction policy when the GPU memory pool is full.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`lru`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>lru</code>, <code>fifo</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lora-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the kernel backend for multi-LoRA serving.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`csgmv`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>csgmv</code>, <code>ascend</code>, <code>torch_native</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-lora-chunk-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum chunk size for the ChunkedSGMV LoRA backend. Only used when <code>--lora-backend</code> is <code>csgmv</code>. Larger values may improve performance.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`16`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>16</code>, <code>32</code>, <code>64</code>, <code>128</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lora-drain-wait-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>When any LoRA adapter request waits longer than this threshold (in seconds), the scheduler will selectively drain one running adapter to make room. This mitigates extreme tail latency under high or skewed workloads by preventing a small set of adapters from monopolizing batch slots. Set to 0 to disable draining (default).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--experts-shared-outer-loras`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Force shared outer LoRA mode for MoE models. When set, w1/w3 lora_A and w2 lora_B are shared across experts (expert_dim=1). Use --no-experts-shared-outer-loras to force disable. By default this is auto-detected from adapter weights.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lora-use-virtual-experts`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable virtual expert computation for MoE models. When set, the model will use virtual expert computation.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lora-strict-loading`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable strict loading for LoRA adapters. When set, mismatched or missing keys in the adapter weights will raise an error.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
</tbody>
</table>

## Kernel Backends (Attention, Sampling, Grammar, GEMM)
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--attention-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the kernels for attention layers.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>torch_native</code>, <code>flex_attention</code>, <code>dsa</code>, <code>nsa</code>, <code>dsv4</code>, <code>compressed</code>, <code>fa3</code>, <code>fa4</code>, <code>flashinfer</code>, <code>flashmla</code>, <code>trtllm_mla</code>, <code>cutedsl_mla</code>, <code>tokenspeed_mla</code>, <code>trtllm_mha</code>, <code>aiter</code>, <code>wave</code>, <code>intel_amx</code>, <code>ascend</code>, <code>intel_xpu</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-attention-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the kernels for prefill attention layers (have priority over --attention-backend).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>torch_native</code>, <code>flex_attention</code>, <code>dsa</code>, <code>nsa</code>, <code>dsv4</code>, <code>compressed</code>, <code>fa3</code>, <code>fa4</code>, <code>flashinfer</code>, <code>flashmla</code>, <code>trtllm_mla</code>, <code>cutedsl_mla</code>, <code>tokenspeed_mla</code>, <code>trtllm_mha</code>, <code>aiter</code>, <code>wave</code>, <code>intel_amx</code>, <code>ascend</code>, <code>intel_xpu</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--decode-attention-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the kernels for decode attention layers (have priority over --attention-backend).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>torch_native</code>, <code>flex_attention</code>, <code>dsa</code>, <code>nsa</code>, <code>dsv4</code>, <code>compressed</code>, <code>fa3</code>, <code>fa4</code>, <code>flashinfer</code>, <code>flashmla</code>, <code>trtllm_mla</code>, <code>cutedsl_mla</code>, <code>tokenspeed_mla</code>, <code>trtllm_mha</code>, <code>aiter</code>, <code>wave</code>, <code>intel_amx</code>, <code>ascend</code>, <code>intel_xpu</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-nvidia-megakernel`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable the NVIDIA megakernel from the sgl-nvidia-mega package. Supported decode and verify steps use its fused kernels; other steps use the standard forward. An unsupported startup configuration raises an error listing the reasons. Experimental feature.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--monokernel-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select a registered monokernel backend, e.g. amd from sgl-amd-mono. Supported decode and verify steps use persistent kernels; other steps use the standard forward. An unsupported startup configuration raises an error listing the reasons. Experimental feature.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: Optional[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--sampling-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the kernels for sampling layers.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>flashinfer</code>, <code>pytorch</code>, <code>ascend</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--grammar-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the backend for grammar-guided decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>xgrammar</code>, <code>outlines</code>, <code>llguidance</code>, <code>none</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mm-attention-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set multimodal attention backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>sdpa</code>, <code>fa3</code>, <code>fa4</code>, <code>triton_attn</code>, <code>ascend_attn</code>, <code>aiter_attn</code>, <code>flashinfer_cudnn</code>, <code>amx_attn</code>, <code>xpu_attn</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dsa-prefill-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DSA backend for the prefill stage (overrides `--attention-backend` when running DeepSeek DSA-style attention).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Auto (hardware-dependent)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>flashmla_sparse</code>, <code>flashmla_sparse_q8</code>, <code>triton_sparse_mla</code>, <code>flashmla_kv</code>, <code>flashmla_auto</code>, <code>fa3</code>, <code>tilelang</code>, <code>aiter</code>, <code>trtllm</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dsa-triton-union`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Union group size for `--dsa-prefill-backend triton_sparse_mla`: adjacent query tokens share one gathered index set (exact; an ownership mask restores each token's own softmax). Requires `num_q_heads * union` to be a power of two in [16, 32]; forced off under `--enable-deterministic-inference`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>0</code>, <code>2</code>, <code>4</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dsa-decode-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DSA backend for the decode stage when running DeepSeek DSA-style attention. Overrides `--attention-backend` for decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Auto (hardware-dependent)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>flashmla_sparse</code>, <code>flashmla_kv</code>, <code>flashmla_auto</code>, <code>fa3</code>, <code>tilelang</code>, <code>aiter</code>, <code>trtllm</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dsa-topk-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the DSA indexer top-k backend for the target model. The `torch` backend currently requires `SGLANG_DSA_FUSE_TOPK=false`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`sgl-kernel`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>sgl-kernel</code>, <code>torch</code>, <code>flashinfer</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-deepseek-v4-fp4-indexer`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable the experimental FP4 C4 indexer path for DeepSeek V4. When unset, SGLang keeps the default DeepSeek V4 indexer path. Requires SM100 GPUs with DeepGEMM FP4 indexer support.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--fp8-gemm-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the runner backend for Blockwise FP8 GEMM operations. For MXFP8 dense GEMM, <code>auto</code> selects <code>flashinfer_cutedsl</code> when FlashInfer reports support (currently SM100/SM103), and otherwise selects <code>flashinfer_cutlass</code> on supported Blackwell GPUs. Options also include 'deep_gemm' (JIT-compiled), 'flashinfer_trtllm' (FlashInfer TRTLLM backend; SM100/SM103 only), 'flashinfer_cutlass' (FlashInfer CUTLASS backend), 'flashinfer_cutedsl' (FlashInfer CuTe DSL MXFP8 backend; SM100/SM103 only), 'flashinfer_deepgemm' (Hopper SM90 only, uses swapAB optimization for small M dimensions in decoding), 'cutlass' (optimal for SM120 GPUs), 'triton' (fallback, widely compatible), and 'aiter' (ROCm only).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>deep_gemm</code>, <code>flashinfer_trtllm</code>, <code>flashinfer_cutlass</code>, <code>flashinfer_cutedsl</code>, <code>flashinfer_deepgemm</code>, <code>cutlass</code>, <code>triton</code>, <code>aiter</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--fp4-gemm-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the runner backend for NVFP4 GEMM operations. Options: 'auto' (default; selects <code>flashinfer_cutedsl</code> on SM100, <code>marlin</code> on SM80-SM90, <code>flashinfer_cutlass</code> otherwise (including SM120)), 'flashinfer_cutlass' (FlashInfer CUTLASS backend), 'flashinfer_cudnn' (FlashInfer cuDNN backend, optimal on CUDA 13+ with cuDNN 9.15+), 'flashinfer_cutedsl' (FlashInfer CuTe DSL backend), 'flashinfer_trtllm' (FlashInfer TensorRT-LLM backend, requires different weight preparation with shuffling), 'marlin' (weight-only W4A16 fallback for SM80-SM90). Requires FlashInfer to be installed.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>flashinfer_cudnn</code>, <code>flashinfer_cutedsl</code>, <code>flashinfer_cutlass</code>, <code>flashinfer_trtllm</code>, <code>marlin</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--bf16-gemm-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the backend for unquantized BF16 GEMM operations. Options: <code>auto</code> (default; selects <code>cutedsl</code> on SM10x GPUs, except deterministic inference selects <code>torch</code>; otherwise uses cuBLAS via <code>torch.nn.functional.linear</code>), <code>cutedsl</code> (SGLang JIT CuTe DSL TGV BF16 GEMM on SM10x; dispatches between the CuTe DSL kernel and cuBLAS), <code>torch</code> (always uses cuBLAS via <code>torch.nn.functional.linear</code>).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>cutedsl</code>, <code>torch</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-flashinfer-autotune`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Flashinfer autotune is enabled by default. Set this flag to disable the autotune.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--flashinfer-autotune-skip-ops`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>FlashInfer custom-op identifiers to skip during autotuning. See <a href="https://docs.flashinfer.ai/autotuning.html">FlashInfer's autotuning documentation</a>. Skipped ops use the heuristic fallback. SGLang temporarily skips <code>mxfp8_gemm</code> by default due to an IMA.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>string</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--radix-cache-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Name of a radix-cache backend previously registered via register_radix_cache_backend. Omit this flag to use the built-in default cache selection chain.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
</tbody>
</table>

## Speculative decoding
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-algorithm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Speculative algorithm.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`EAGLE`, `EAGLE3`, `NEXTN`, `STANDALONE`, `NGRAM`</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-draft-model-path`<br/>`--speculative-draft-model`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the draft model weights. This can be a local folder or a Hugging Face repo ID.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>speculative_boundary_reduction</code><br/>Server args field; no CLI flag</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Resolved FFN boundary reduction policy for the speculative draft. Argument processing derives this field from <code>boundary_reduction</code> and the draft model configuration; an independent value is overwritten by resolution. See <a href="#ffn-boundary-reduction">FFN boundary reduction</a>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>rs+rsv</code> before resolution; model-dependent afterward</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>ar</code>, <code>rs</code>, <code>rsv</code>, <code>rs+rsv</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-draft-model-revision`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The specific draft model version to use. It can be a branch name, a tag name, or a commit id. If unspecified, will use the default version.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-draft-load-format`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The format of the draft model weights to load. If not specified, will use the same format as `--load-format`. Use 'dummy' to initialize draft model weights with random values for profiling.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>pt</code>, <code>safetensors</code>, <code>instanttensor</code>, <code>npcache</code>, <code>dummy</code>, <code>sharded_state</code>, <code>gguf</code>, <code>bitsandbytes</code>, <code>mistral</code>, <code>layered</code>, <code>flash_rl</code>, <code>remote</code>, <code>remote_instance</code>, <code>fastsafetensors</code>, <code>private</code>, <code>runai_streamer</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-num-steps`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of steps sampled from draft model in Speculative Decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-eagle-topk`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of tokens sampled from the draft model in eagle2 each step.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-num-draft-tokens`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of tokens sampled from the draft model in Speculative Decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-accept-threshold-single`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Accept a draft token if its probability in the target model is greater than this threshold.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-accept-threshold-acc`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The accept probability of a draft token is raised from its target probability p to min(1, p / threshold_acc).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-use-block-verification`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Use block verification for EAGLE/EAGLE3/NEXTN on CUDA or ROCm (requires topk=1).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-token-map`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the draft model's small vocab table.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-attention-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Attention backend for speculative decoding operations (both target verify and draft extend). Can be one of 'prefill' (default) or 'decode'.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`prefill`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>prefill</code>, <code>decode</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-draft-attention-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Attention backend for speculative decoding drafting.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Same as attention backend options</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-dsa-topk-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the DSA indexer top-k backend for speculative draft workers. The `torch` backend currently requires `SGLANG_DSA_FUSE_TOPK=false`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`sgl-kernel`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>sgl-kernel</code>, <code>torch</code>, <code>flashinfer</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-moe-runner-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>MOE backend for EAGLE speculative decoding, see `--moe-runner-backend` for options. Same as moe runner backend if unset.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>deep_gemm</code>, <code>triton</code>, <code>triton_kernel</code>, <code>flashinfer_trtllm</code>, <code>experimental_sgl_trtllm</code>, <code>flashinfer_trtllm_routed</code>, <code>flashinfer_cutlass</code>, <code>flashinfer_mxfp4</code>, <code>flashinfer_cutedsl</code>, <code>cutlass</code>, <code>aiter</code>, <code>marlin</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-moe-a2a-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>MOE A2A backend for EAGLE speculative decoding, see `--moe-a2a-backend` for options. Same as moe a2a backend if unset.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>none</code>, <code>deepep</code>, <code>mooncake</code>, <code>nixl</code>, <code>mori</code>, <code>ascend_fuseep</code>, <code>flashinfer</code>, <code>megamoe</code>, <code>pplx</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-enable-w4a4-mxfp4-megamoe`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Whether the draft model's MXFP4 MegaMoE layers use the W4A4 `mxf4xmxf4` MMA type. Pass `--no-speculative-enable-w4a4-mxfp4-megamoe` to keep the draft on `fp8xfp4` (W4A8) while the target runs W4A4. Same as `--enable-w4a4-mxfp4-megamoe` if unset. A draft that runs MXFP4 MegaMoE with a different MMA type from the target may allocate an additional MegaMoE symmetric buffer after the KV pool is sized; lower `--mem-fraction-static` if CUDA-graph capture runs out of memory.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-draft-model-quantization`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The quantization method for speculative model.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Same as `--quantization` options</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-dflash-block-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DFLASH only. Block size (verify window length). Alias of --speculative-num-draft-tokens for DFLASH.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-draft-window-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Sliding window size for the draft model. Honored by Llama EAGLE-3 (`LlamaForCausalLMEagle3`) and DFLASH only; other EAGLE-3 backends (e.g. MLA-based drafters) silently ignore it. For Llama EAGLE-3, the drafter only attends to the most recent N keys (verifier hidden states + its own outputs); the verifier is unaffected. For DFLASH, the draft worker keeps a recent target-token window in its local KV cache (paged backends may retain up to one extra page on the left for alignment). Default is full attention/context.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
</tbody>
</table>

## Ngram speculative decoding
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-min-bfs-breadth`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The minimum breadth for BFS (Breadth-First Search) in ngram speculative decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-max-bfs-breadth`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum breadth for BFS (Breadth-First Search) in ngram speculative decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`10`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-match-type`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Ngram tree-building mode. <code>BFS</code> selects recency-based expansion and <code>PROB</code> selects frequency-based expansion. This setting is forwarded to the ngram cache implementation.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`BFS`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>BFS</code>, <code>PROB</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-max-trie-depth`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum suffix length stored and matched by the ngram trie.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`18`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-capacity`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The cache capacity for ngram speculative decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>10000000</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-external-corpus-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to an external JSONL corpus to pre-load into SAM at startup. Additional corpora can be added at runtime via POST /add_external_corpus.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-external-sam-budget`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of draft nodes reserved for the external SAM subtree in ngram speculative decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-ngram-external-corpus-max-tokens`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Fail startup if the tokenized external ngram corpus exceeds this many tokens. Tune this based on your CPU memory budget.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`10000000`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-adaptive`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable adaptive speculative decoding that dynamically adjusts num_steps based on acceptance rate.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--speculative-adaptive-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to a JSON config file for adaptive speculative decoding tuning knobs.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
</tbody>
</table>

## Multi-layer Eagle speculative decoding
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-multi-layer-eagle`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable multi-layer Eagle speculative decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
  </tbody>
</table>

## MoE
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--expert-parallel-size`<br/>`--ep-size`<br/>`--ep`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The expert parallelism size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--moe-a2a-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select the backend for all-to-all communication for expert parallelism.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`none`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>none</code>, <code>deepep</code>, <code>mooncake</code>, <code>nixl</code>, <code>mori</code>, <code>ascend_fuseep</code>, <code>flashinfer</code>, <code>megamoe</code>, <code>pplx</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--moe-runner-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the runner backend for MoE.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>deep_gemm</code>, <code>triton</code>, <code>triton_kernel</code>, <code>flashinfer_trtllm</code>, <code>experimental_sgl_trtllm</code>, <code>flashinfer_trtllm_routed</code>, <code>flashinfer_cutlass</code>, <code>flashinfer_mxfp4</code>, <code>flashinfer_cutedsl</code>, <code>cutlass</code>, <code>aiter</code>, <code>marlin</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--flashinfer-mxfp4-moe-precision`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the computation precision of flashinfer mxfp4 moe. On SM90, `fp8` selects the Humming-style MXFP4-weight x FP8-activation path introduced by FlashInfer #3738 and requires FlashInfer &gt;= 0.6.18.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`default`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>default</code>, <code>bf16</code>, <code>fp8</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-flashinfer-allreduce-fusion`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable FlashInfer allreduce fusion with Residual RMSNorm.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-aiter-allreduce-fusion`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable aiter allreduce fusion with Residual RMSNorm.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--deepep-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select the mode when enable DeepEP MoE, could be <code>normal</code>, <code>low_latency</code> or <code>auto</code>. Default is <code>auto</code>, which means <code>low_latency</code> for decode batch and <code>normal</code> for prefill batch.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>normal</code>, <code>low_latency</code>, <code>auto</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--deepep-dispatcher-output-dtype`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select DeepEP dispatcher output dtype, could be <code>bf16</code>, <code>fp8</code>, <code>int8</code> (only Ascend A2/A3 Series NPUs), <code>nvfp4</code> or <code>auto</code>. Default is <code>auto</code>, which follows a priority order (server argument → deprecated env var → input_global_scale check → dispatcher_output_dtype from quant_config → flashinfer/cutlass backend → NPU BF16 default → GPU FP8 default).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>bf16</code>, <code>fp8</code>, <code>int8</code>, <code>nvfp4</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--flashinfer-a2a-dispatch-type</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select FlashInfer A2A dispatcher activation dtype. When omitted, it falls back to the <code>SGLANG_MOE_NVFP4_DISPATCH</code> environment variable. Explicit <code>auto</code> selects <code>mxfp8</code> for <code>--quantization mxfp8</code>, <code>nvfp4</code> for modelopt FP4 or hybrid NVFP4 MoE checkpoints, and <code>bf16</code> otherwise. The <code>SGLANG_MOE_NVFP4_DISPATCH</code> environment variable cannot be set with this argument.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>bf16</code>, <code>nvfp4</code>, <code>mxfp8</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ep-num-redundant-experts`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Allocate this number of redundant experts in expert parallel.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ep-dispatch-algorithm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The algorithm to choose ranks for redundant experts in expert parallel.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--init-expert-location`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Initial location of EP experts.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`trivial`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-eplb`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable EPLB algorithm</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--eplb-algorithm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Chosen EPLB algorithm</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--eplb-rebalance-num-iterations`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of iterations to automatically trigger a EPLB re-balance.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1000`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--eplb-rebalance-layers-per-chunk`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of layers to rebalance per forward pass.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--eplb-min-rebalancing-utilization-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Minimum threshold for GPU average utilization to trigger EPLB rebalancing. Must be in the range [0.0, 1.0].</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--expert-distribution-recorder-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Mode of expert distribution recorder.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--expert-distribution-recorder-buffer-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Circular buffer size of expert distribution recorder. Set to -1 to denote infinite buffer.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--expert-balancedness-report-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Where to report expert balancedness.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>off</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>off</code>, <code>server_log</code>, <code>prometheus</code>, <code>both</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--deepep-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Tuned DeepEP config suitable for your own cluster. It can be either a string with JSON content or a file path.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--moe-dense-tp-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>TP size for MoE dense MLP layers. This flag is useful when, with large TP size, there are errors caused by weights in MLP layers having dimension smaller than the min dimension GEMM supports.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` none`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--elastic-ep-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Specify the collective communication backend for elastic EP. Currently supports 'mooncake'.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>none</code>, <code>mooncake</code>, <code>nixl</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-elastic-expert-backup`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable elastic EP backend to backup expert weights in DRAM feature. Currently supports 'mooncake'.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mooncake-ib-device`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The InfiniBand devices for Mooncake Backend transfer, accepts multiple comma-separated devices (e.g., --mooncake-ib-device mlx5_0,mlx5_1). Default is None, which triggers automatic device detection when Mooncake Backend is enabled.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>` None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-waterfill`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable Waterfill: dispatch the fused shared expert as an extra routed expert slot to the least-loaded EP rank. Supports DeepEP and MegaMOE MoE A2A backends, implicitly enables shared-expert fusion, and supports `--deepep-mode auto`, `normal`, or `low_latency` when used with DeepEP. Use `auto` or `low_latency` for production DeepEP decode so CUDA graph remains enabled. Supported on DeepSeek-V3/R1 with EP &gt;= 2. By default, Waterfill uses the static local-batch path; set `SGLANG_DISABLE_STATIC_WATERFILL=1` to force dynamic Waterfill with runtime EP all-reduce.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--flashinfer-allreduce-fusion-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable FlashInfer allreduce fusion and choose backend. Defaults to auto. 'auto': choose mnnvl on SM90 single-node systems and SM100/SM103 single-node or multi-node systems; choose trtllm otherwise. 'trtllm': available on single-node systems only. 'mnnvl': available on SM90 single-node systems and SM100/SM103 single-node or multi-node systems via MNNVL fabric. Fuses allreduce with Residual + RMSNorm for supported MoE models.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>trtllm</code>, <code>mnnvl</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enforce-disable-flashinfer-allreduce-fusion`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enforce disable FlashInfer allreduce fusion.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
</tbody>
</table>

## Mamba Cache
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-mamba-cache-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The maximum size of the mamba cache.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mamba-ssm-dtype`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The data type of the SSM states in mamba cache. If not set, read from the model config.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Auto (from model config)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>float32</code>, <code>bfloat16</code>, <code>float16</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-mamba-cache-stochastic-rounding`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable stochastic rounding when writing FP16 Mamba SSM cache states. Requires <code>--mamba-ssm-dtype float16</code> and CUDA. With <code>--mamba-backend triton</code>, requires SM100.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mamba-cache-philox-rounds`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of Philox rounds to use for stochastic rounding of FP16 Mamba SSM cache writes. Triton uses the Triton default when set to 0; FlashInfer uses 10 rounds when set to 0.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mamba-full-memory-ratio`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The ratio of mamba state memory to full kv cache memory.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0.9`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mamba-radix-cache-strategy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The strategy to use for mamba scheduler. <code>auto</code> currently defaults to <code>no_buffer</code>. 1. <code>no_buffer</code> does not support overlap scheduler due to not allocating extra mamba state buffers. Branching point caching support is feasible but not implemented. 2. <code>extra_buffer</code> supports overlap schedule by allocating extra mamba state buffers to track mamba state for caching (mamba state usage per running req becomes <code>2x</code> for non-spec; <code>1+(1/(2+speculative_num_draft_tokens))x</code> for spec dec (e.g. 1.16x if speculative_num_draft_tokens==4)). 2a. <code>extra_buffer</code> is strictly better for non-KV-cache-bound cases; for KV-cache-bound cases, the tradeoff depends on whether enabling overlap outweighs reduced max running requests. 2b. mamba caching at radix cache branching point is strictly better than non-branch but requires kernel support, currently only extra_buffer supports branching. 3. <code>extra_buffer_lazy</code> lowers <code>extra_buffer</code>&apos;s slot cost by allocating one track slot per request instead of two; the second slot is allocated on demand at track-interval boundaries (for speculative decoding it is reserved ahead of each verify window and committed only for accepted boundary crossings). Compatible with speculative decoding (EAGLE/NGRAM/DSPARK/DFLASH); not supported under PD disaggregation.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>no_buffer</code>, <code>extra_buffer</code>, <code>extra_buffer_lazy</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mamba-track-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The interval (in tokens) to track the mamba state during decode. Only used when <code>--mamba-radix-cache-strategy</code> is <code>extra_buffer</code>. Must be divisible by page_size if set, and must be &gt;= speculative_num_draft_tokens when using speculative decoding.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`256`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-int8-mamba-checkpoint`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Store radix-cached linear-attn (mamba) states in int8 (separate checkpoint pool) for ~2x cached-prefix capacity at fixed memory.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--int8-mamba-ckpt-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of int8 mamba checkpoint slots (default: 2x the active mamba pool size).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mamba-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Choose the kernel backend for Mamba SSM operations. Default is 'triton'. Options: 'triton' (default), 'flashinfer' (requires FlashInfer with Mamba support).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`triton`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>flashinfer</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--linear-attn-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The default kernel backend for linear attention (GDN/KDA). Can be overridden per-mode by --linear-attn-decode-backend and --linear-attn-prefill-backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`triton`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>cutedsl</code>, <code>flashinfer</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--linear-attn-decode-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Override the kernel backend for linear attention decode. If not set, uses --linear-attn-backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>cutedsl</code>, <code>flashinfer</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--linear-attn-prefill-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Override the kernel backend for linear attention prefill/extend. If not set, uses --linear-attn-backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>triton</code>, <code>cutedsl</code>, <code>flashinfer</code></td>
    </tr>
</tbody>
</table>

## Hierarchical cache
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-hierarchical-cache`<br/>`--enable-hicache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable hierarchical cache</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-ratio`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The ratio of the size of host KV cache memory pool to the size of device pool.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`2.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The size of host KV cache memory pool in gigabytes, which will override the hicache_ratio if set.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-write-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The write policy of hierarchical cache.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`write_through`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>write_back</code>, <code>write_through</code>, <code>write_through_selective</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-io-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The IO backend for KV cache transfer between CPU and GPU</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`kernel`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>direct</code>, <code>kernel</code>, <code>kernel_ascend</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-mem-layout`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The layout of host memory pool for hierarchical cache.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`page_first`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>layer_first</code>, <code>page_first</code>, <code>page_first_direct</code>, <code>page_first_kv_split</code>, <code>page_head</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-storage-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The storage backend for hierarchical KV cache. Built-in backends: file, mooncake, hf3fs, nixl, aibrix. For dynamic backend, use --hicache-storage-backend-extra-config to specify: backend_name (custom name), module_path (Python module path), class_name (backend class name).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>file</code>, <code>mooncake</code>, <code>hf3fs</code>, <code>nixl</code>, <code>aibrix</code>, <code>dynamic</code>, <code>eic</code>, <code>simm</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-storage-prefetch-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Control when prefetching from the storage backend should stop.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`timeout`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>best_effort</code>, <code>wait_complete</code>, <code>timeout</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hicache-storage-backend-extra-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>A dictionary in JSON string format, or a string starting with a `@` followed by a config file in JSON/YAML/TOML format, containing extra configuration for the storage backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

## Hierarchical sparse attention
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--hisparse-config`<br/>`--hierarchical-sparse-attention-extra-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>A dictionary in JSON string format for hierarchical sparse attention configuration. Required fields: `algorithm` (str), `backend` (str). All other fields are algorithm-specific and passed to the algorithm constructor.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-hisparse`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable hierarchical sparse attention</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
</tbody>
</table>

## LMCache
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-lmcache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Using LMCache as an alternative hierarchical cache solution</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--lmcache-config-file`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to the LMCache YAML configuration file</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

## Paged experts
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-paged-experts`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Keep only `--paged-experts-num-resident` routed experts per MoE layer on the GPU and page the rest from pinned host memory on demand. Unquantized, block-FP8 or GPTQ experts, single GPU. Decode CUDA graphs (full backend) are captured up to K // top_k requests; prefill graphs must be breakable or disabled.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--paged-experts-num-resident`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of routed experts per MoE layer kept resident on the GPU. Required with `--enable-paged-experts`; at least the router's top-k.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
  </tbody>
</table>

## Ktransformers
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kt-weight-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[ktransformers parameter] The path of the quantized expert weights for amx kernel. A local folder.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kt-method`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[ktransformers parameter] Quantization formats for CPU execution.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`AMXINT4`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kt-cpuinfer`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[ktransformers parameter] The number of CPUInfer threads.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kt-threadpool-count`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[ktransformers parameter] One-to-one with the number of NUMA nodes (one thread pool per NUMA).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`2`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kt-num-gpu-experts`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[ktransformers parameter] The number of GPU experts.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kt-max-deferred-experts-per-token`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[ktransformers parameter] Maximum number of experts deferred to CPU per token. All MoE layers except the final one use this value; the final layer always uses 0.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
  </tbody>
</table>

## Diffusion LLM

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dllm-algorithm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The diffusion LLM algorithm, such as LowConfidence.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dllm-algorithm-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The diffusion LLM algorithm configurations. Must be a YAML file.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dllm-fdfo`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>First-Done-First-Out (FDFO) scheduling lets completed requests leave the batch immediately instead of waiting for slower requests, eliminating head-of-line blocking. Enabled by default; pass `--no-dllm-fdfo` to fall back to synchronous lockstep scheduling. Works with any dLLM algorithm.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`True`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
  </tbody>
</table>

## Offloading
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cpu-offload-gb`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>How many GBs of RAM to reserve for CPU offloading.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--offload-group-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of layers per group in offloading.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`-1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ple-offload-embedding`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Keep the Qwen4-Exp PLE n-gram embedding table in host memory instead of device memory; the gather kernel reads it from a host pointer. Enabled by default for BF16 Qwen4-Exp on CUDA; `--no-ple-offload-embedding` disables it.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ple-offload-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Host storage for the offloaded PLE table: `pinned` (CPU pinned memory) or `file` (a sparse file-backed mmap under `--ple-offload-dir`, read directly by the gather kernel). Use `file` on unified-memory devices such as GB10 / DGX Spark, where pinned host memory comes out of the same pool as the weights; it requires a device that reports `cudaDevAttrPageableMemoryAccessUsesHostPageTables`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`pinned`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ple-offload-dir`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Directory for the file-backed PLE table when `--ple-offload-backend` is `file`. The file is sparse and rewritten on every startup; keep it on fast local storage (NVMe). Rewriting an existing table can be much slower than filling a fresh sparse file. Before restarting, stop all servers using that directory and remove its `ple_table_*.bin` files to avoid this startup cost.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`$SGLANG_CACHE_DIR/ple/<model path>`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--offload-num-in-group`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of layers to be offloaded within a group.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--offload-prefetch-step`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Steps to prefetch in offloading.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--offload-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Mode of offloading.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`cpu`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

## Args for multi-item scoring
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>

      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-mis`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable Multi-Item Scoring optimization. Combines query and multiple items into a single sequence for efficient batch processing. Requires --attention-backend flashinfer; auto-disables CUDA graph, radix cache, and chunked prefill.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
</tbody>
</table>

## Optimization/debug options
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-radix-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable RadixAttention for prefix caching.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Canonical per-phase CUDA graph settings as JSON, e.g. <code>{`{"decode":{"backend":"full","max_bs":256},"prefill":{"backend":"breakable"}}`}</code>. JSON wins over the per-phase <code>--cuda-graph-*</code> convenience flags and over the legacy flags. Allowed backends: <code>full</code>, <code>breakable</code>, <code>disabled</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON (dict-of-dicts)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-backend-decode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Backend for the decode phase. Folds into <code>cuda_graph_config[decode].backend</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>full</code>, <code>breakable</code>, <code>disabled</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-backend-prefill`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Backend for the prefill phase. Folds into <code>cuda_graph_config[prefill].backend</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>breakable</code>, <code>disabled</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-max-bs-decode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum batch size captured for the decode CUDA graph.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-max-bs-prefill`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum batch size captured for the prefill CUDA graph.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-max-seq-len-prefill`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Longest sequence a prefill CUDA graph replay admits; longer batches run eager prefill. Folds into `cuda_graph_config[prefill].max_seq_len`.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-bs-decode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Explicit list of batch sizes to capture for the decode CUDA graph.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[int]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cuda-graph-bs-prefill`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Explicit list of batch sizes to capture for the prefill CUDA graph.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[int]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-cuda-graph-padding`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable cuda graph when padding is needed. Still uses cuda graph when padding is not needed.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-profile-cuda-graph`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable profiling of cuda graph capture.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--debug-cuda-graph`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Eager-mode CUDA graph via the breakable backend: graph breaks let every op run eagerly while still going through the capture/replay path. Useful for debugging capture/replay issues.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-cudagraph-gc`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable garbage collection during CUDA graph capture. If disabled (default), GC is frozen during capture to speed up the process.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-layerwise-nvtx-marker`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable layerwise NVTX profiling annotations for the model. This adds NVTX markers to every layer for detailed per-layer performance analysis with Nsight Systems.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-nccl-nvls`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable NCCL NVLS for prefill heavy requests when available.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-symm-mem`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable NCCL symmetric memory for fast collectives.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-flashinfer-cutlass-moe-fp4-allgather`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disables quantize before all-gather for flashinfer cutlass moe.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-tokenizer-batch-encode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable batch tokenization for improved performance when processing multiple text inputs. Do not use with image inputs, pre-tokenized input_ids, or input_embeds.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-tokenizer-batch-decode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable batch decoding when decoding multiple completions.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-outlines-disk-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable disk cache of outlines to avoid possible crashes related to file system or high concurrency.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--boundary-reduction</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select the optional FFN output reduction strategy. Unsupported reduce-scatter paths fall back to all-reduce followed by token redistribution. See <a href="#ffn-boundary-reduction">FFN boundary reduction</a>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>auto</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>auto</code>, <code>ar</code>, <code>rs</code>, <code>rsv</code>, <code>rs+rsv</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-custom-all-reduce`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable the custom all-reduce kernel and fall back to NCCL.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-mscclpp`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable using mscclpp for small messages for all-reduce kernel and fall back to NCCL.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-torch-symm-mem`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable using torch symm mem for all-reduce kernel and fall back to NCCL. Only supports CUDA device SM90 and above. SM90 supports world size 4, 6, 8. SM10 supports world size 6, 8.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-overlap-schedule`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable the overlap scheduler, which overlaps the CPU scheduler with GPU model worker.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-mixed-chunk`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enabling mixing prefill and decode in a batch when using chunked prefill.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-dp-attention`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><strong>Deprecated.</strong> Use <code>--attn-dp-size &lt;dp-size&gt;</code> instead of <code>--dp-size &lt;dp-size&gt; --enable-dp-attention</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>False</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-dp-lm-head`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable vocabulary parallel across the attention TP group to avoid all-gather across DP groups, optimizing performance under DP attention.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-two-batch-overlap`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enabling two micro batches to overlap.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-single-batch-overlap`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Let computation and communication overlap within one micro batch.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tbo-token-distribution-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The threshold of token distribution between two batches in micro-batch-overlap, determines whether to two-batch-overlap or two-chunk-overlap. Set to 0 denote disable two-chunk-overlap.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0.48`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-torch-compile`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Optimize the model with torch.compile. Experimental feature.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-torch-compile-debug-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable debug mode for torch compile.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--torch-compile-max-bs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set the maximum batch size when using torch compile.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`32`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-cuda-graph`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><strong>Deprecated.</strong> Use <code>--cuda-graph-backend-decode=disabled</code> and/or <code>--cuda-graph-backend-prefill=disabled</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>False</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-prefill-cuda-graph`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable the prefill-phase CUDA graph. Convenience for <code>--cuda-graph-backend-prefill=disabled</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-decode-cuda-graph`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable the decode-phase CUDA graph. Convenience for <code>--cuda-graph-backend-decode=disabled</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>

    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-p2p-check`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable P2P check for GPU access, otherwise the p2p access is allowed by default.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--triton-attention-reduce-in-fp32`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Cast the intermediate attention results to fp32 to avoid possible crashes related to fp16. This only affects Triton attention kernels.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--triton-attention-num-kv-splits`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The number of KV splits in flash decoding Triton kernel. Larger value is better in longer context scenarios. The default value is 8.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`8`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--triton-attention-split-tile-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The size of split KV tile in flash decoding Triton kernel. Used for deterministic inference.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--num-continuous-decode-steps`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Run multiple continuous decoding steps to reduce scheduling overhead. This can potentially increase throughput but may also increase time-to-first-token latency. The default value is 1, meaning only run one decoding step at a time.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--delete-ckpt-after-loading`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Delete the model checkpoint after loading the model.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-memory-saver`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Allow saving memory using release_memory_occupation and resume_memory_occupation</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-weights-cpu-backup`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Save model weights to CPU memory during release_weights_occupation and resume_weights_occupation</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-draft-weights-cpu-backup`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Save draft model weights to CPU memory during release_weights_occupation and resume_weights_occupation</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--allow-auto-truncate`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Allow automatically truncating requests that exceed the maximum input length instead of returning an error.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-custom-logit-processor`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable users to pass custom logit processors to the server (disabled by default for security)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-watermark`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable Aaronson-Gumbel text watermarking.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--watermark-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Watermark settings as a JSON file path or an inline JSON object with optional key, key_b, context_window, mixing_probability, max_probability, default_enabled, and enforce_all fields.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: Optional[str]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--flashinfer-mla-disable-ragged`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Not using ragged prefill wrapper when running flashinfer mla</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-shared-experts-fusion`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable shared experts fusion optimization for deepseek v3/r1.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-chunked-prefix-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable chunked prefix cache feature for deepseek, which should save overhead for short sequences.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--image-processor-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Image processor backend. `auto` lets Transformers select the best available backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`auto`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`auto`, `torchvision`, `pil`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-fast-image-processor`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Deprecated. Use `--image-processor-backend=pil` instead.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-return-hidden-states`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable returning hidden states with responses.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--return-hidden-states-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set the maximum hidden-state return mode supported by the server. `last` allows requests with return_hidden_states=False or `last`; `full` also allows return_hidden_states=True.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>last</code>, <code>full</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-return-routed-experts`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable returning routed experts of each layer with responses.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--scheduler-recv-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The interval to poll requests in scheduler. Can be set to &gt;1 to reduce the overhead of this.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--numa-node`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Sets the numa node for the subprocesses. i-th element corresponds to i-th subprocess.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[int]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-deterministic-inference`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable deterministic inference mode with batch invariant ops.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--rl-on-policy-target`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The training system that SGLang needs to match for true on-policy.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>fsdp</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-attn-tp-input-scattered`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Allow input of attention to be scattered when only using tensor parallelism, to reduce the computational load of operations such as qkv latent.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-layernorm-sp`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable sequence parallelism for prefill LayerNorm and residual regions under pure tensor parallelism. Supports Qwen3 dense and Muse Spark. Muse Spark requires TP4/EP4 or TP8/EP8, NVLink/NVSwitch, and <code>--moe-runner-backend flashinfer_trtllm</code>. Use ModelOpt NVFP4 with <code>--moe-a2a-backend flashinfer</code>, or enable MegaMoE for NVFP4 or BF16. Attention DP and pipeline parallelism are unsupported; speculative decoding is supported only for Muse Spark DFLASH.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-megamoe-for-layernorm-sp`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Use MegaMoE for Muse Spark LayerNorm SP prefill, including BF16 excluded layers. Requires <code>--enable-layernorm-sp</code> and DeepGEMM with post-expert normalization (release/v0.2.3). Prefill and decode share TRT-LLM expert weights; decode uses FlashInfer TRT-LLM and all-reduce. FlashInfer A2A is optional. Mixed chunking is unsupported.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-prefill-cp`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable context parallelism for the prefill phase. Select the layout with <code>--cp-strategy</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cp-strategy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Sharding strategy for prefill CP. <code>zigzag</code> assigns each rank one early and one late sequence block; <code>interleave</code> assigns token indices modulo the CP size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>zigzag</code>, <code>interleave</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-kv-cache-sharding`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Shard at-rest KV cache storage at page granularity across the group that currently replicates it (attention-CP ranks for GQA models under prefill CP; attention-TP ranks for MLA models), multiplying the group's unique KV capacity. Prefill workers of PD disaggregation only.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-fused-qk-norm-rope`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Fuse q/k normalization and rope rotary embedding into one kernel. Enabled by default on XPU and disabled elsewhere; `--no-enable-fused-qk-norm-rope` disables it.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-precise-embedding-interpolation`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable corner alignment for resize of embeddings grid to ensure more accurate(but slower) evaluation of interpolated embedding values.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kv-canary`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>KV cache canary mode. 'none' disables the canary (default). 'log' prints them while the server keeps running (production-safe). 'raise' fails the server on the first detected mismatch (CI lane).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`none`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>none</code>, <code>log</code>, <code>raise</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kv-canary-real-data`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Check the real KV-cache in the canary. 'none' (default) disables the feature. 'partial' checks the first 16 bytes of each real-KV slot. 'all' checks the full real-KV slot.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`none`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--kv-canary-sweep-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Every N forward steps, run a full-pool sweep.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pre-warm-nccl`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Pre-warm NCCL/RCCL communicators during startup to reduce P99 TTFT cold-start latency. Default: enabled for AMD/HIP (RCCL), disabled for NVIDIA/CUDA (NCCL).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-dp-attention-local-control-broadcast`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>With DP-attention, send control messages to every DP group leader and broadcast within attn_tp_group instead of the full tp_group. Eliminates a costly all-ranks gloo sync on every scheduler iteration.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enforce-shared-experts-fusion`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enforce shared experts fusion even when it would normally be disabled (e.g. under DeepEP). Mutually exclusive with --disable-shared-experts-fusion.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-return-indexer-topk`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable returning indexer topk indices of layers with indexer with responses.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-attn-tp-gather`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable scheduler-side attn_tp_gather (the upstream SP path that pads num_tokens to attn_tp_size and pre-allocates a gathered buffer). Use for models that manage SP scatter/gather at the model level (e.g., perform their own all_gather/reduce_scatter inside attention) and do not consume the upstream gathered_buffer. Without this, the cuda graph runner pads num_tokens to attn_tp_size, which can cause kernel autotuners to select wrong-sized variants at small batches.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-fused-moe-sum-all-reduce`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable fused moe triton and sum all reduce.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--gc-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Set the garbage collection thresholds (the collection frequency). Accepts 1 to 3 integers.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>—</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int (one or more)</td>
    </tr>
</tbody>
</table>

### FFN boundary reduction

Use `--boundary-reduction` to choose which optional FFN output reductions may combine the sum with token redistribution. The selected policy applies to the dense and MoE FFN stages of decoders built with independently constructed stage boundaries (`declare_ffn` / `append_stages`; see [Layer boundaries](/docs/developer_guide/layer_boundary)). Other models keep their built-in FFN output communication and ignore this option.

| Value | Behavior |
| --- | --- |
| `auto` | Resolve the model default during server-argument processing, before model construction. |
| `ar` | Use all-reduce followed by token redistribution where needed. |
| `rs` | Permit fixed-size reduce-scatter when the layout and backend support it; otherwise use `ar`. |
| `rsv` | Permit variable-size reduce-scatter for eligible attention-DP paths; otherwise use `ar`. |
| `rs+rsv` | Permit both, trying the eligible variable-size path first, then fixed-size, then `ar`. |

`auto` selects `ar` for dense Qwen3 language backbones (including Qwen3-VL wrappers), Moss-VL and MiniCPM-V 4.5; `rsv` for BailingMoELinear/BailingMoeV2_5, LongCat Flash and Step3-VL; and `rs+rsv` otherwise. Qwen3-MoE, Qwen3-Next and Qwen3.5 are not matched by the dense Qwen3 rule and resolve to `rs+rsv`.

With `auto`, a draft loaded from a different path resolves its own model default; a draft on the target's model path (the MTP default) inherits the target policy. An explicit value applies to both target and draft. The result is recorded in the `speculative_boundary_reduction` server args field (`no_cli=True`); it has no separate CLI flag or independent override during resolution.

This option does not disable required attention or MoE collectives, including expert all-to-all, or select the all-reduce fusion backend. For example, `ar` can still use fused all-reduce plus residual normalization; use `--enforce-disable-flashinfer-allreduce-fusion` to disable that FlashInfer fusion.

## Dynamic batch tokenizer
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-dynamic-batch-tokenizer`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable async dynamic batch tokenizer for improved performance when multiple requests arrive concurrently.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dynamic-batch-tokenizer-batch-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[Only used if --enable-dynamic-batch-tokenizer is set] Maximum batch size for dynamic batch tokenizer.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`32`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--dynamic-batch-tokenizer-batch-timeout`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>[Only used if --enable-dynamic-batch-tokenizer is set] Timeout in seconds for batching tokenization requests.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0.002`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: float</td>
    </tr>
  </tbody>
</table>

## Debug tensor dumps
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--debug-tensor-dump-output-folder`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The output folder for dumping tensors.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--debug-tensor-dump-layers`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The layer ids to dump. Dump all layers if not specified.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON list</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--debug-tensor-dump-input-file`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The input filename for dumping tensors</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

## PD disaggregation
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Only used for PD disaggregation. "prefill" for prefill-only server, and "decode" for decode-only server. If not specified, it is not PD disaggregated</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`null`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>null</code>, <code>prefill</code>, <code>decode</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-transfer-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The backend for disaggregation transfer. Default is mooncake.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`mooncake`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>mooncake</code>, <code>nixl</code>, <code>ascend</code>, <code>fake</code>, <code>mori</code>, <code>mooncake_tcp</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-bootstrap-port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Bootstrap server port on the prefill server. Default is 8998.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`8998`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-ib-device`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The InfiniBand devices for disaggregation transfer, accepts single device (e.g., --disaggregation-ib-device mlx5_0) or multiple comma-separated devices (e.g., --disaggregation-ib-device mlx5_0,mlx5_1). Default is None, which triggers automatic device detection when mooncake backend is enabled.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-decode-allocation-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>When to reserve per-request decode KV slots. Set the same policy on prefill and decode. See <a href="/docs/advanced_features/pd_disaggregation#decode-allocation-policy">requirements and tradeoffs</a>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`early`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>early</code>, <code>prefill_complete</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-decode-enable-offload-kvcache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable async KV cache offloading on decode server (PD mode).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--num-reserved-decode-tokens`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of decode tokens that will have memory reserved when adding new request to the running batch.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`512`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-decode-polling-interval`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The interval to poll requests in decode server. Can be set to &gt;1 to reduce the overhead of this.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disaggregation-decode-enable-radix-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable radix cache on decode server (PD mode). Caches KV prefixes to avoid redundant transfers. Incompatible with --enable-hisparse, --disaggregation-transfer-backend fake, and speculative algorithms other than EAGLE, EAGLE3, and DSPARK.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--optimistic-prefill-attempts`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of optimistic prefill forward passes that skip the bootstrap wait.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
</tbody>
</table>

## Encode prefill disaggregation
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--encoder-only`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>For MLLM with an encoder, launch an encoder-only server</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--language-only`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>For VLM, load weights for the language model only.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--language-model-only`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Skip the multimodal encoder entirely: its weights are never loaded and the tower is never built, freeing that GPU memory for KV cache. Multimodal requests are rejected. Unlike --language-only this is a standalone mode, not part of encoder/decoder disaggregation.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--encoder-transfer-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The backend for encoder disaggregation transfer. Default is zmq_to_scheduler.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`zmq_to_scheduler`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>zmq_to_scheduler</code>, <code>zmq_to_tokenizer</code>, <code>mooncake</code></td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--encoder-urls`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List of encoder server urls.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`[]`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON list</td>
    </tr>
      <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--encoder-bootstrap-port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Port for the EncoderBootstrapServer that runs in the language-only tokenizer manager process. Encoders register here, and language-only receivers fetch the current URL list from here.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`8997`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--encoder-register-urls`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>One or more EncoderBootstrapServer URLs to register this encoder with on startup, for dynamic encoder discovery. Example: --encoder-register-urls http://prefill0:8997 http://prefill1:8997. Used with --encoder-only servers.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`[]`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str (one or more)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-adaptive-dispatch-to-encoder`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>When enabled, adaptively dispatch: multi-image requests go to encoder in language_only epd mode, single-image requests are processed locally.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
</tbody>
</table>

## Custom weight loader
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--custom-weight-loader`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The custom dataloader which used to update the model. Should be set with a valid import path, such as my_package.weight_load_func</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List[str]</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--weight-loader-disable-mmap`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Disable mmap while loading weight using safetensors.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--weight-loader-prefetch-checkpoints`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Prefetch checkpoint files into OS page cache before loading. Each rank prefetches a fraction of the shards in a background thread, reducing total network I/O on shared filesystems (NFS/Lustre) from N\*checkpoint to 1\*checkpoint. Recommended for models on network storage. When enabled, multi-threaded safetensors loading is disabled by default to avoid I/O oversubscription with the prefetch threads; set `enable_multithread_load=true` in `--model-loader-extra-config` to keep multi-threaded loading (e.g. on local NVMe where prefetch is a no-op).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--weight-loader-prefetch-num-threads`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of threads per rank for checkpoint prefetching.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`4`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--remote-instance-weight-loader-seed-instance-ip`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The ip of the seed instance for loading weights from remote instance.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--remote-instance-weight-loader-seed-instance-service-port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The service port of the seed instance for loading weights from remote instance.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--remote-instance-weight-loader-send-weights-group-ports`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The communication group ports for loading weights from remote instance.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON list</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--remote-instance-weight-loader-backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The backend for loading weights from remote instance. Can be 'transfer_engine', 'nccl', or 'modelexpress'. Default is 'nccl'.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`nccl`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>transfer_engine</code>, <code>nccl</code>, <code>modelexpress</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--remote-instance-weight-loader-start-seed-via-transfer-engine`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Start seed server via transfer engine backend for remote instance weight loader.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--weight-loader-drop-cache-after-load`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Call posix_fadvise(DONTNEED) on each safetensors shard after loading it.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--engine-info-bootstrap-port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Port for the engine info bootstrap server. Default is 6789. Must be set explicitly when running multiple instances on the same node.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`6789`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--modelexpress-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>JSON config for ModelExpress P2P weight loading. Keys: "url" (optional gRPC host:port override), "transport" ("nixl" or "transfer_engine"). Example: '&#123;"url": "localhost:8001", "transport": "nixl"&#125;'</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
</tbody>
</table>

## For PD-Multiplexing
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-pdmux`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable PD-Multiplexing, PD running on greenctx stream.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pdmux-config-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the PD-Multiplexing config file.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--sm-group-num`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of sm partition groups.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`8`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
  </tbody>
</table>

## Configuration file support
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Read CLI options from a config file. Must be a YAML file with configuration options.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

## For Multi-Modal
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>

    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-broadcast-mm-inputs-process`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable broadcast mm-inputs process in scheduler.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mm-process-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Multimodal preprocessing config, a json config contains keys: <code>image</code>, <code>video</code>, <code>audio</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>&#123;&#125;</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON / Dict</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--allowed-media-domains`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Restrict client-supplied HTTP(S) media URLs and redirect destinations to these exact hostnames.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Unrestricted</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Space-separated hostnames</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--media-url-max-file-size-mb`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum streamed size in MiB for one remote media download. Set to 0 to disable the limit.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`64`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--mm-enable-dp-encoder`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enabling data parallelism for mm encoder. The dp size will be set to the tp size automatically.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--limit-mm-data-per-request`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Limit the number of multimodal inputs per request. e.g. '&#123;"image": 1, "video": 1, "audio": 1&#125;'</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON / Dict</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-mm-global-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable Mooncake-backed global multimodal embedding cache on encoder servers so repeated images can reuse cached ViT embeddings instead of recomputing them.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
</tbody>
</table>

## For checkpoint decryption
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--decrypted-config-file`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the decrypted config file.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--decrypted-draft-config-file`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the decrypted draft config file.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--enable-prefix-mm-cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable prefix multimodal cache. Currently only supports mm-only.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>bool flag (set to enable)</td>
    </tr>
  </tbody>
</table>

## Forward hooks
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--forward-hooks`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>JSON-formatted list of forward hook specifications. Each element must include `target_modules` (list of glob patterns matched against `model.named_modules()` names) and `hook_factory` (Python import path to a factory, e.g. `my_package.hooks:make_hook`). An optional `name` field is used for logging, and an optional `config` object is passed as a `dict` to the factory.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: JSON list</td>
    </tr>
  </tbody>
</table>

## For MindStudio-probe(msProbe) dump
<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
        <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--msprobe-dump-config`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The path of the JSON configuration file for msProbe. If specified, enables msProbe dump.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

---

### Docs Advanced Features Server Arguments Undocumented (`docs/docs/advanced_features/server_arguments_undocumented.txt`)

# Live ServerArgs flags with no row in server_arguments.mdx. One flag per line.
# test/registered/unit/server_args/test_server_args_docs_coverage.py reads this
# list. It may only shrink: when you add a row for a flag, delete it here.
--c128-page-size
--constrained-json-max-whitespace-cnt
--cuda-graph-prefill-max-context
--decoupled-spec-bind-endpoint
--decoupled-spec-connect-endpoints
--decoupled-spec-rank
--decoupled-spec-role
--deepep-v2-mode
--disable-aiter-allreduce-fusion-in-decode
--disable-aiter-allreduce-fusion-in-prefill
--disaggregation-decode-extra-slots
--disaggregation-decode-host-receive-threshold
--disaggregation-decode-retraction-backup
--disaggregation-enable-kv-checksum
--dsa-paged-mqa-logits-backend
--dsv4-attn-backend
--dsv4-prefill-backend
--dwdp-size
--elastic-ep-initial-size
--elastic-ep-join-mode
--elastic-ep-join-rank-offset
--elastic-ep-scale-timeout
--enable-cp-decode-attn-tp
--enable-decoder-swa-bounded-replay
--enable-dense-mlp-attn-tp
--enable-dsa-cache-layer-split
--enable-dsa-fused-indexer
--enable-encoder-swa-bounded-replay
--enable-flexkv
--enable-lean-attention
--enable-linear-replayssm
--enable-linear-replayssm-spec
--enable-linker-mla-dedup
--enable-pd-role-switch
--enable-response-store
--enable-scattered-sconv
--enable-session-radix-cache
--enable-shared-experts-attn-tp
--enable-tp-lm-head-all-to-all
--enable-unified-cache-external-linker
--enable-w4a4-mxfp4-megamoe
--flexkv-config-file
--fuseep-mode
--gated-launch-port
--grpc-port
--grpc-response-timeout-secs
--hicache-host-memory-fraction
--hicache-host-memory-mode
--hicache-storage-prefetch-retry-max-attempts
--hicache-storage-prefetch-retry-poll-interval
--http2-initial-connection-window-size
--linear-attn-verify-backend
--linear-replayssm-cache-len
--mamba-max-states-per-path
--max-ep-size
--min-free-slots-delay
--mm-feature-transport
--mm-global-cache-backend
--mm-io-worker-num
--mm-preprocess-cache-size-mb
--mm-processor-worker-num
--otlp-service-name
--prefill-kv-cache-dequant-dtype
--qsa-indexer-dtype
--radix-eviction-policy-config
--return-input-ids
--return-output-ids
--sampling-mask-max-tokens
--shared-experts-tp-size
--sidecar
--sidecar-args
--smg-grpc-mode
--spec-trace-dir
--speculative-domino-candidate-pool-size
--speculative-draft-kv-cache-dtype
--speculative-draft-sink-size
--speculative-dspark-align-verify-tokens-to-graph-tier
--speculative-dspark-block-size
--speculative-dspark-confidence-sts-path
--speculative-dspark-sps-table-path
--speculative-use-rejection-sampling
--startup-weight-load-mode
--swa-prefix-tails
--trust-mm-content-hashes
--trust-request-chat-template
--unified-cache-external-linker-backend
--uno-lora-path
--weight-cache-mode
--weight-cache-socket
--weight-cache-timeout

---

### Docs Advanced Features Session Radix Cache (`docs/docs/advanced_features/session_radix_cache.mdx`)

---
title: "Session-Aware Radix Cache"
metatags:
    description: "Keep active sessions ahead of unrelated KV in UnifiedRadixCache eviction order."
---

Session-aware radix caching improves cache hits for long-lived, multi-turn workloads under memory pressure. It registers reusable KV to a session and evicts unreferenced KV before KV still referenced by an active session.

Session references are soft protection, not memory pins. Referenced KV can still be evicted when reclaiming unreferenced KV is insufficient.

## Enable the cache

This feature is implemented only by `UnifiedRadixCache`.

```bash Command
python3 -m sglang.launch_server \
  --model-path MODEL_PATH \
  --enable-session-radix-cache
```

## Pass and close the session

Your application must pass the same top-level `session_id` on every request in a session. The ID labels cache references only; it does not append or reconstruct conversation context, so each request must still contain the intended prompt.

```bash Command
curl http://localhost:30000/generate \
  -H "Content-Type: application/json" \
  -d '{
    "text": "FULL_PROMPT_FOR_THIS_TURN",
    "sampling_params": {"max_new_tokens": 128},
    "session_id": "agent-42"
  }'
```

When a request finishes, SGLang automatically registers its reusable cache leaves under the `session_id`. This reference-only workflow does not require an `/open_session` call.

Call `/close_session` when the application session ends, including error and cancellation paths:

```bash Command
curl -X POST http://localhost:30000/close_session \
  -H "Content-Type: application/json" \
  -d '{"session_id": "agent-42"}'
```

Closing removes the session's references but does not immediately free its KV. The KV remains reusable and returns to the normal eviction order.

## Eviction behavior

The cache tracks references independently for each UnifiedRadixCache component. Device and host eviction use the same session preference.

| Component | Referenced data | Eviction order |
| --- | --- | --- |
| Full attention | The reusable prefix path from the registered leaf to the root | Unreferenced nodes first, then referenced nodes with fewer session references, then the configured policy such as LRU |
| Sliding-window attention (SWA) | The reusable tail covering the sliding window plus page-alignment allowance | Two LRU passes: unreferenced nodes first, then referenced nodes if more space is required |
| Mamba | The reusable state on the registered leaf | Two LRU passes: unreferenced nodes first, then referenced nodes if more space is required |

UnifiedRadixCache still applies component cascade rules. Evicting an internal Full node also evicts its SWA and Mamba data; evicting SWA also evicts Mamba data; evicting Mamba affects only Mamba. Evicting a leaf removes all component data on that leaf.

---

### Docs Advanced Features Sgl Model Gateway (`docs/docs/advanced_features/sgl_model_gateway.mdx`)

---
title: "SGLang Model Gateway"
metatags:
    description: "SGLang Model Gateway: load balancing, PD disaggregation, multi-model routing, gRPC support, MCP integration, Kubernetes service discovery."
---
SGLang Model Gateway is a high-performance model-routing gateway for large-scale LLM deployments. It centralizes worker lifecycle management, balances traffic across heterogeneous protocols (HTTP, gRPC, OpenAI-compatible), and provides enterprise-ready control over history storage, MCP tooling, and privacy-sensitive workflows. The gateway is deeply optimized for the SGLang serving runtime, but can route to any OpenAI-compatible backend.

***
## Table of Contents

1. [Overview](#overview)
2. [Architecture](#architecture)
   - [Control Plane](#control-plane)
   - [Data Plane](#data-plane)
   - [Storage and Privacy](#storage-and-privacy)
3. [Installation](#installation)
4. [Quick Start](#quick-start)
5. [Deployment Modes](#deployment-modes)
   - [Co-launch Router and Workers](#co-launch-router-and-workers)
   - [Separate Launch (HTTP)](#separate-launch-http)
   - [gRPC Launch](#grpc-launch)
   - [Prefill-Decode Disaggregation](#prefill-decode-disaggregation)
   - [OpenAI Backend Proxy](#openai-backend-proxy)
   - [Multi-Model Inference Gateway](#multi-model-inference-gateway)
6. [API Reference](#api-reference)
   - [Inference Endpoints](#inference-endpoints)
   - [Tokenization Endpoints](#tokenization-endpoints)
   - [Parser Endpoints](#parser-endpoints)
   - [Classification API](#classification-api)
   - [Conversation and Response APIs](#conversation-and-response-apis)
   - [Worker Management APIs](#worker-management-apis)
   - [Admin and Health Endpoints](#admin-and-health-endpoints)
7. [Load Balancing Policies](#load-balancing-policies)
8. [Reliability and Flow Control](#reliability-and-flow-control)
   - [Retries](#retries)
   - [Circuit Breaker](#circuit-breaker)
   - [Rate Limiting and Queuing](#rate-limiting-and-queuing)
   - [Health Checks](#health-checks)
9. [Reasoning Parser Integration](#reasoning-parser-integration)
10. [Tool Call Parsing](#tool-call-parsing)
11. [Tokenizer Management](#tokenizer-management)
12. [MCP Integration](#mcp-integration)
13. [Service Discovery (Kubernetes)](#service-discovery-kubernetes)
14. [History and Data Connectors](#history-and-data-connectors)
15. [WASM Middleware](#wasm-middleware)
16. [Language Bindings](#language-bindings)
17. [Security and Authentication](#security-and-authentication)
    - [TLS (HTTPS) for Gateway Server](#tls-https-for-gateway-server)
    - [mTLS for Worker Communication](#mtls-for-worker-communication)
18. [Observability](#observability)
    - [Prometheus Metrics](#prometheus-metrics)
    - [OpenTelemetry Tracing](#opentelemetry-tracing)
    - [Logging](#logging)
19. [Production Recommendations](#production-recommendations)
    - [Security Best Practices](#security-best-practices)
    - [High Availability](#high-availability)
    - [Performance](#performance)
    - [Kubernetes Deployment](#kubernetes-deployment)
    - [Monitoring with PromQL](#monitoring-with-promql)
20. [Configuration Reference](#configuration-reference)
21. [Troubleshooting](#troubleshooting)

***
## Overview

- **Unified control plane** for registering, monitoring, and orchestrating regular, prefill, and decode workers across heterogeneous model fleets.
- **Multi-protocol data plane** that routes traffic across HTTP, PD (prefill/decode), gRPC, and OpenAI-compatible backends with shared reliability primitives.
- **Industry-first gRPC pipeline** with native Rust tokenization, reasoning parsers, and tool-call execution for high-throughput, OpenAI-compatible serving; supports both single-stage and PD topologies.
- **Inference Gateway Mode (`--enable-igw`)** dynamically instantiates multiple router stacks (HTTP regular/PD, gRPC) and applies per-model policies for multi-tenant deployments.
- **Conversation & responses connectors** centralize chat history inside the router so the same context can be reused across models and MCP loops without leaking data to upstream vendors (memory, none, Oracle ATP, PostgreSQL).
- **Enterprise privacy**: agentic multi-turn `/v1/responses`, native MCP client (STDIO/HTTP/SSE/Streamable), and history storage all operate within the router boundary.
- **Reliability core**: retries with jitter, worker-scoped circuit breakers, token-bucket rate limiting with queuing, background health checks, and cache-aware load monitoring.
- **Comprehensive observability**: 40+ Prometheus metrics, OpenTelemetry distributed tracing, structured logging, and request ID propagation.

***
## Architecture

### Control Plane

- **Worker Manager** discovers capabilities (`/get_server_info`, `/get_model_info`), tracks load, and registers/removes workers in the shared registry.
- **Job Queue** serializes add/remove requests and exposes status (`/workers/{worker_id}`) so clients can track onboarding progress.
- **Load Monitor** feeds cache-aware and power-of-two policies with live worker load statistics.
- **Health Checker** continuously probes workers and updates readiness, circuit breaker state, and router metrics.
- **Tokenizer Registry** manages dynamically registered tokenizers with async loading from HuggingFace or local paths.

### Data Plane

- **HTTP routers** (regular & PD) implement `/generate`, `/v1/chat/completions`, `/v1/completions`, `/v1/responses`, `/v1/embeddings`, `/v1/rerank`, `/v1/classify`, `/v1/tokenize`, `/v1/detokenize`, and associated admin endpoints.
- **gRPC router** streams tokenized requests directly to SRT gRPC workers, running fully in Rust—tokenizer, reasoning parser, and tool parser all reside in-process. Supports both single-stage and PD routing, including embeddings and classification.
- **OpenAI router** proxies OpenAI-compatible endpoints to external vendors (OpenAI, xAI, etc.) while keeping chat history and multi-turn orchestration local.

### Storage and Privacy

- Conversation and response history is stored at the router tier (memory, none, Oracle ATP, or PostgreSQL). The same history can power multiple models or MCP loops without sending data to upstream vendors.
- `/v1/responses` agentic flows, MCP sessions, and conversation APIs share the same storage layer, enabling compliance for regulated workloads.

***
## Installation

### Docker

Pre-built Docker images are available on Docker Hub with multi-architecture support (x86_64 and ARM64):

```bash Command
docker pull lmsysorg/sgl-model-gateway:latest
```

### Prerequisites

- **Rust and Cargo**
  ```bash Command
  curl --proto '=https' --tlsv1.2 -sSf https://sh.rustup.rs | sh
  source "$HOME/.cargo/env"
  rustc --version
  cargo --version
  ```
- **Python** with `pip` and virtualenv tooling available.

### Rust Binary

```bash Command
cd sgl-model-gateway
cargo build --release
```

### Python Package

```bash Command
pip install maturin

# Fast development mode
cd sgl-model-gateway/bindings/python
maturin develop

# Production build
maturin build --release --out dist --features vendored-openssl
pip install --force-reinstall dist/*.whl
```

***
## Quick Start

### Regular HTTP Routing

```bash Command
# Rust binary
./target/release/sgl-model-gateway \
  --worker-urls http://worker1:8000 http://worker2:8000 \
  --policy cache_aware

# Python launcher
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 http://worker2:8000 \
  --policy cache_aware
```

### gRPC Routing

```bash Command
python -m sglang_router.launch_router \
  --worker-urls grpc://127.0.0.1:20000 \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --reasoning-parser deepseek-r1 \
  --tool-call-parser json \
  --host 0.0.0.0 --port 8080
```

***
## Deployment Modes

### Co-launch Router and Workers

Launch the router and a fleet of SGLang workers in one process:

```bash Command
python -m sglang_router.launch_server \
  --model meta-llama/Meta-Llama-3.1-8B-Instruct \
  --dp-size 4 \
  --host 0.0.0.0 \
  --port 30000
```

Comprehensive example with router arguments (prefixed with `--router-`):

```bash Command
python -m sglang_router.launch_server \
  --host 0.0.0.0 \
  --port 8080 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --tp-size 1 \
  --dp-size 8 \
  --grpc-mode \
  --log-level debug \
  --router-prometheus-port 10001 \
  --router-tool-call-parser llama \
  --router-model-path meta-llama/Llama-3.1-8B-Instruct \
  --router-policy round_robin \
  --router-log-level debug
```

### Separate Launch (HTTP)

Run workers independently and point the router at their HTTP endpoints:

```bash Command
# Worker nodes
python -m sglang.launch_server --model meta-llama/Meta-Llama-3.1-8B-Instruct --port 8000
python -m sglang.launch_server --model meta-llama/Meta-Llama-3.1-8B-Instruct --port 8001

# Router node
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 http://worker2:8001 \
  --policy cache_aware \
  --host 0.0.0.0 --port 30000
```

### gRPC Launch

Use SRT gRPC workers to unlock the highest throughput and access native reasoning/tool pipelines:

```bash Command
# Workers expose gRPC endpoints
python -m sglang.launch_server \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --grpc-mode \
  --port 20000

# Router
python -m sglang_router.launch_router \
  --worker-urls grpc://127.0.0.1:20000 \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --reasoning-parser deepseek-r1 \
  --tool-call-parser json \
  --host 0.0.0.0 --port 8080
```

The gRPC router supports both regular HTTP-equivalent serving and PD (prefill/decode) serving. Provide `--tokenizer-path` or `--model-path` (HuggingFace ID or local directory) whenever connection mode resolves to gRPC.

### Prefill-Decode Disaggregation

Split prefill and decode workers for PD-aware caching and balancing:

```bash Command
python -m sglang_router.launch_router \
  --pd-disaggregation \
  --prefill http://prefill1:30001 9001 \
  --decode http://decode1:30011 \
  --prefill-policy cache_aware \
  --decode-policy power_of_two
```

Prefill entries accept an optional bootstrap port. PD mode merges prefill metadata with decode outputs and streams results back to the client.

### OpenAI Backend Proxy

Proxy OpenAI-compatible endpoints while keeping history and MCP sessions local:

```bash Command
python -m sglang_router.launch_router \
  --backend openai \
  --worker-urls https://api.openai.com \
  --history-backend memory
```

OpenAI backend mode expects exactly one `--worker-urls` entry per router instance.

### Multi-Model Inference Gateway

Enable IGW mode to route multiple models through a single router:

```bash Command
./target/release/sgl-model-gateway \
  --enable-igw \
  --policy cache_aware \
  --max-concurrent-requests 512

# Register workers dynamically
curl -X POST http://localhost:30000/workers \
  -H "Content-Type: application/json" \
  -d '{
        "url": "http://worker-a:8000",
        "model_id": "mistral",
        "priority": 10,
        "labels": {"tier": "gold"}
      }'
```

***
## API Reference

### Inference Endpoints

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Path</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/generate`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>SGLang generate API</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/chat/completions`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>OpenAI-compatible chat completions (streaming/tool calls)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/completions`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>OpenAI-compatible text completions</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/embeddings`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Embedding generation (HTTP and gRPC)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/rerank`, `/rerank`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Reranking requests</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/classify`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Text classification</td>
    </tr>
  </tbody>
</table>

### Tokenization Endpoints

The gateway provides HTTP endpoints for text tokenization with batch support, designed to mirror the SGLang Python tokenization API.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Path</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/tokenize`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Tokenize text to token IDs (single or batch)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/detokenize`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Convert token IDs back to text (single or batch)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/tokenizers`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Register a new tokenizer (async, returns job status)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/tokenizers`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>List all registered tokenizers</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/tokenizers/{id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Get tokenizer info by UUID</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/tokenizers/{id}/status`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Check async tokenizer loading status</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`DELETE`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/tokenizers/{id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Remove a tokenizer from the registry</td>
    </tr>
  </tbody>
</table>

#### Tokenize Request

```json Config
{
  "model": "meta-llama/Llama-3.1-8B-Instruct",
  "prompt": "Hello, world!"
}
```

#### Batch Tokenize Request

```json Config
{
  "model": "meta-llama/Llama-3.1-8B-Instruct",
  "prompt": ["Hello", "World", "How are you?"]
}
```

#### Tokenize Response

```json Config
{
  "tokens": [15339, 11, 1917, 0],
  "count": 4,
  "char_count": 13
}
```

#### Detokenize Request

```json Config
{
  "model": "meta-llama/Llama-3.1-8B-Instruct",
  "tokens": [15339, 11, 1917, 0],
  "skip_special_tokens": true
}
```

#### Detokenize Response

```json Config
{
  "text": "Hello, world!"
}
```

#### Add Tokenizer (Async)

```bash Command
curl -X POST http://localhost:30000/v1/tokenizers \
  -H "Content-Type: application/json" \
  -d '{"name": "llama3", "source": "meta-llama/Llama-3.1-8B-Instruct"}'
```

Response:
```json Config
{
  "id": "550e8400-e29b-41d4-a716-446655440000",
  "status": "pending",
  "message": "Tokenizer registration queued"
}
```

Check status:
```bash Command
curl http://localhost:30000/v1/tokenizers/550e8400-e29b-41d4-a716-446655440000/status
```

### Parser Endpoints

The gateway provides admin endpoints for parsing reasoning content and function calls from LLM outputs.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Path</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/parse/reasoning`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Separate reasoning (`&lt;think&gt;`) from normal text</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/parse/function_call`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Parse function/tool calls from text</td>
    </tr>
  </tbody>
</table>

#### Separate Reasoning Request

```json Config
{
  "text": "&lt;think&gt;Let me analyze this step by step...&lt;/think&gt;The answer is 42.",
  "parser": "deepseek-r1"
}
```

#### Response

```json Config
{
  "normal_text": "The answer is 42.",
  "reasoning_text": "Let me analyze this step by step..."
}
```

#### Function Call Parsing

```json Config
{
  "text": "{\"name\": \"get_weather\", \"arguments\": {\"city\": \"NYC\"}}",
  "parser": "json"
}
```

### Classification API

The `/v1/classify` endpoint provides text classification using sequence classification models (e.g., `Qwen2ForSequenceClassification`, `BertForSequenceClassification`).

#### Request

```bash Command
curl http://localhost:30000/v1/classify \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jason9693/Qwen2.5-1.5B-apeach",
    "input": "I love this product!"
  }'
```

#### Response

```json Config
{
  "id": "classify-a1b2c3d4-5678-90ab-cdef-1234567890ab",
  "object": "list",
  "created": 1767034308,
  "model": "jason9693/Qwen2.5-1.5B-apeach",
  "data": [
    {
      "index": 0,
      "label": "positive",
      "probs": [0.12, 0.88],
      "num_classes": 2
    }
  ],
  "usage": {
    "prompt_tokens": 6,
    "completion_tokens": 0,
    "total_tokens": 6
  }
}
```

#### Response Fields

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`label`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Predicted class label (from model's `id2label` config, or `LABEL_N` fallback)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`probs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Probability distribution over all classes (softmax of logits)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`num_classes`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of classification classes</td>
    </tr>
  </tbody>
</table>

#### Notes

- Classification reuses the embedding backend—the scheduler returns logits which are converted to probabilities via softmax
- Labels come from the model's HuggingFace config (`id2label` field); models without this mapping use generic labels (`LABEL_0`, `LABEL_1`, etc.)
- Both HTTP and gRPC routers support classification

### Conversation and Response APIs

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Path</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/responses`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Create background responses (agentic loops)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/responses/{id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Retrieve stored response</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/responses/{id}/cancel`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Cancel background response</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`DELETE`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/responses/{id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Delete response</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/responses/{id}/input_items`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>List response input items</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Create conversation</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations/{id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Get conversation</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations/{id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Update conversation</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`DELETE`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations/{id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Delete conversation</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations/{id}/items`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>List conversation items</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations/{id}/items`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Add items to conversation</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations/{id}/items/{item_id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Get conversation item</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`DELETE`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/conversations/{id}/items/{item_id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Delete conversation item</td>
    </tr>
  </tbody>
</table>

### Worker Management APIs

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Path</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/workers`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Queue worker registration (returns 202 Accepted)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/workers`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>List workers with health, load, and policy metadata</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/workers/{worker_id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Inspect specific worker or job queue entry</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`PUT`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/workers/{worker_id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Queue worker update</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`DELETE`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/workers/{worker_id}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Queue worker removal</td>
    </tr>
  </tbody>
</table>

#### Add Worker

```bash Command
curl -X POST http://localhost:30000/workers \
  -H "Content-Type: application/json" \
  -d '{"url":"grpc://0.0.0.0:31000","worker_type":"regular"}'
```

#### List Workers

```bash Command
curl http://localhost:30000/workers
```

Response:
```json Config
{
  "workers": [
    {
      "id": "2f3a0c3e-3a7b-4c3f-8c70-1b7d4c3a6e1f",
      "url": "http://0.0.0.0:31378",
      "model_id": "mistral",
      "priority": 50,
      "cost": 1.0,
      "worker_type": "regular",
      "is_healthy": true,
      "load": 0,
      "connection_mode": "Http"
    }
  ],
  "total": 1,
  "stats": {
    "prefill_count": 0,
    "decode_count": 0,
    "regular_count": 1
  }
}
```

### Admin and Health Endpoints

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Path</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/liveness`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Health check (always returns OK)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/readiness`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Readiness check (checks healthy worker availability)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/health`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Alias for liveness</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/health_generate`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Health generate test</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/engine_metrics`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Engine-level metrics from workers</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/v1/models`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>List available models</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/get_model_info`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Get model information</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/get_server_info`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Get server information</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/flush_cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Clear all caches</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/get_loads`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Get all worker loads</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`POST`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/wasm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Upload WASM module</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`GET`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/wasm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>List WASM modules</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`DELETE`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`/wasm/{module_uuid}`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Remove WASM module</td>
    </tr>
  </tbody>
</table>

***
## Load Balancing Policies

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Policy</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Usage</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`random`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Uniform random selection</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--policy random`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`round_robin`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Cycles through workers in order</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--policy round_robin`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`power_of_two`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Samples two workers and picks the lighter one</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--policy power_of_two`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`cache_aware`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Combines cache locality with load balancing (default)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--policy cache_aware`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`bucket`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Divides workers into load buckets with dynamic boundaries</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--policy bucket`</td>
    </tr>
  </tbody>
</table>

### Cache-Aware Policy Tuning

```bash Command
--cache-threshold 0.5 \
--balance-abs-threshold 32 \
--balance-rel-threshold 1.5 \
--eviction-interval-secs 120 \
--max-tree-size 67108864
```

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cache-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.3</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Minimum prefix match ratio for cache hit</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--balance-abs-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>64</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Absolute load difference before rebalancing</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--balance-rel-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>1.5</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Relative load ratio before rebalancing</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--eviction-interval-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>120</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Cache eviction cadence in seconds</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-tree-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>67108864</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Maximum nodes in cache tree</td>
    </tr>
  </tbody>
</table>

***
## Reliability and Flow Control

### HTTP Client

Configure upstream HTTP client connection settings:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pool-idle-timeout-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>50</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Idle timeout in seconds for pooled upstream HTTP connections. Can also be set with `SMG_POOL_IDLE_TIMEOUT_SECS`.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--connect-timeout-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>10</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Timeout in seconds for new upstream HTTP connections. Can also be set with `SMG_CONNECT_TIMEOUT_SECS`.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pool-max-idle-per-host`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>500</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Maximum idle upstream HTTP connections to keep per host. Can also be set with `SMG_POOL_MAX_IDLE_PER_HOST`.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tcp-keepalive-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>30</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>TCP keepalive idle time in seconds for upstream HTTP connections. Can also be set with `SMG_TCP_KEEPALIVE_SECS`.</td>
    </tr>
  </tbody>
</table>

### Retries

Configure exponential backoff retries:

```bash Command
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 http://worker2:8001 \
  --retry-max-retries 5 \
  --retry-initial-backoff-ms 50 \
  --retry-max-backoff-ms 30000 \
  --retry-backoff-multiplier 1.5 \
  --retry-jitter-factor 0.2
```

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--retry-max-retries`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>5</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Maximum retry attempts</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--retry-initial-backoff-ms`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>50</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Initial backoff duration (ms)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--retry-max-backoff-ms`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>5000</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Maximum backoff duration (ms)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--retry-backoff-multiplier`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>2.0</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Exponential backoff multiplier</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--retry-jitter-factor`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>0.1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Random jitter factor (0.0-1.0)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-retries`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>false</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Disable retries entirely</td>
    </tr>
  </tbody>
</table>

**Retryable Status Codes:** 408, 429, 500, 502, 503, 504

### Circuit Breaker

Per-worker circuit breakers prevent cascading failures:

```bash Command
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 http://worker2:8001 \
  --cb-failure-threshold 5 \
  --cb-success-threshold 2 \
  --cb-timeout-duration-secs 30 \
  --cb-window-duration-secs 60
```

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cb-failure-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>5</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Consecutive failures to open circuit</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cb-success-threshold`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>2</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Successes to close from half-open</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cb-timeout-duration-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>30</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Time before half-open attempt</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--cb-window-duration-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>60</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Failure counting window</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--disable-circuit-breaker`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>false</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Disable circuit breaker</td>
    </tr>
  </tbody>
</table>

**Circuit Breaker States:**
- **Closed**: Normal operation, requests allowed
- **Open**: Failing, requests rejected immediately
- **Half-Open**: Testing recovery, limited requests allowed

### Rate Limiting and Queuing

```bash Command
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 http://worker2:8001 \
  --max-concurrent-requests 256 \
  --rate-limit-tokens-per-second 512 \
  --queue-size 128 \
  --queue-timeout-secs 30
```

Requests beyond the concurrency limit wait in a FIFO queue. Returns:
- `429 Too Many Requests` when queue is full
- `408 Request Timeout` when queue timeout expires

### Health Checks

```bash Command
--health-check-interval-secs 30 \
--health-check-timeout-secs 10 \
--health-success-threshold 2 \
--health-failure-threshold 3 \
--health-check-endpoint /health
```

***
## Reasoning Parser Integration

The gateway includes built-in reasoning parsers for models that use Chain-of-Thought (CoT) reasoning with explicit thinking blocks.

### Supported Parsers

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parser ID</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Model Family</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Think Tokens</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`deepseek-r1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepSeek-R1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`&lt;think&gt;...&lt;/think&gt;` (initial reasoning)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`qwen3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Qwen-3</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`&lt;think&gt;...&lt;/think&gt;`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`qwen3-thinking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Qwen-3 Thinking</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`&lt;think&gt;...&lt;/think&gt;` (initial reasoning)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`kimi`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Kimi K2</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Unicode think tokens</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`glm45`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>GLM-4.5/4.6/4.7</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`&lt;think&gt;...&lt;/think&gt;`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`step3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Step-3</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`&lt;think&gt;...&lt;/think&gt;`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`minimax`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>MiniMax</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`&lt;think&gt;...&lt;/think&gt;`</td>
    </tr>
  </tbody>
</table>

### Usage

```bash Command
python -m sglang_router.launch_router \
  --worker-urls grpc://127.0.0.1:20000 \
  --model-path deepseek-ai/DeepSeek-R1 \
  --reasoning-parser deepseek-r1
```

The gRPC router automatically:
1. Detects reasoning blocks in streaming output
2. Separates reasoning content from normal text
3. Applies incremental streaming parsing with buffer management
4. Handles partial token detection for correct streaming behavior

***
## Tool Call Parsing

The gateway supports parsing function/tool calls from LLM outputs in multiple formats.

### Supported Formats

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parser</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Format</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`json`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>JSON</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Standard JSON tool calls</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`python`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Pythonic</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Python function call syntax</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`xml`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>XML</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>XML-formatted tool calls</td>
    </tr>
  </tbody>
</table>

### Usage

```bash Command
python -m sglang_router.launch_router \
  --worker-urls grpc://127.0.0.1:20000 \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --tool-call-parser json
```

***
## Tokenizer Management

### Tokenizer Sources

The gateway supports multiple tokenizer backends:
- **HuggingFace**: Load from HuggingFace Hub by model ID
- **Local**: Load from local `tokenizer.json` or directory
- **Tiktoken**: Auto-detect OpenAI GPT models (gpt-4, davinci, etc.)

### Configuration

```bash Command
# HuggingFace model
--model-path meta-llama/Llama-3.1-8B-Instruct

# Local tokenizer
--tokenizer-path /path/to/tokenizer.json

# With chat template override
--chat-template /path/to/template.jinja
```

### Tokenizer Caching

Two-level caching for optimal performance:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Cache</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>L0</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Exact match</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Whole-string caching for repeated prompts</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>L1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Prefix match</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Prefix boundary matching for incremental prompts</td>
    </tr>
  </tbody>
</table>

```bash Command
--enable-l0-cache \
--l0-max-entries 10000 \
--enable-l1-cache \
--l1-max-memory 52428800  # 50MB
```

***
## MCP Integration

The gateway provides native Model Context Protocol (MCP) client integration for tool execution.

### Supported Transports

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Transport</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>STDIO</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Local process execution</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>SSE</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Server-Sent Events (HTTP)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Streamable</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Bidirectional streaming</td>
    </tr>
  </tbody>
</table>

### Configuration

```bash Command
python -m sglang_router.launch_router \
  --mcp-config-path /path/to/mcp-config.yaml \
  --worker-urls http://worker1:8000
```

### MCP Configuration File

```yaml Config
servers:
  - name: "filesystem"
    command: "npx"
    args: ["-y", "@modelcontextprotocol/server-filesystem", "/tmp"]
    protocol: "stdio"
    required: false

  - name: "github"
    url: "https://api.github.com/mcp"
    token: "ghp_xxxxx"
    protocol: "sse"
    required: false

  - name: "custom-tools"
    url: "https://tools.example.com/mcp"
    protocol: "streamable"
    required: true

pool:
  max_connections: 100
  idle_timeout: 300

proxy:
  http: "http://proxy.internal:8080"
  https: "https://proxy.internal:8443"
  no_proxy: "localhost,127.0.0.1,*.internal"

inventory:
  enable_refresh: true
  tool_ttl: 300
  refresh_interval: 300
```

***
## Service Discovery (Kubernetes)

Enable automatic worker discovery via Kubernetes pod selectors:

```bash Command
python -m sglang_router.launch_router \
  --service-discovery \
  --selector app=sglang-worker role=inference \
  --service-discovery-namespace production \
  --service-discovery-port 8000
```

### PD Mode Discovery

```bash Command
--pd-disaggregation \
--prefill-selector app=sglang component=prefill \
--decode-selector app=sglang component=decode \
--service-discovery
```

Prefill pods can expose bootstrap ports via the `sglang.ai/bootstrap-port` annotation. RBAC must allow `get`, `list`, and `watch` on pods.

***
## History and Data Connectors

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Backend</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Usage</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`memory`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>In-memory storage (default)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--history-backend memory`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`none`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No persistence</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--history-backend none`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`oracle`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Oracle Autonomous Database</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--history-backend oracle`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`postgres`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>PostgreSQL Database</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--history-backend postgres`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`redis`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Redis</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--history-backend redis`</td>
    </tr>
  </tbody>
</table>

### Oracle Configuration

```bash Command
# Connection descriptor
export ATP_DSN="(description=(address=(protocol=tcps)(port=1522)(host=adb.region.oraclecloud.com))(connect_data=(service_name=service_name)))"

# Or TNS alias (requires wallet)
export ATP_TNS_ALIAS="sglroutertestatp_high"
export ATP_WALLET_PATH="/path/to/wallet"

# Credentials
export ATP_USER="admin"
export ATP_PASSWORD="secret"
export ATP_POOL_MIN=4
export ATP_POOL_MAX=32

python -m sglang_router.launch_router \
  --backend openai \
  --worker-urls https://api.openai.com \
  --history-backend oracle
```

### PostgreSQL Configuration

```bash Command
export POSTGRES_DB_URL="postgres://user:password@host:5432/dbname"

python -m sglang_router.launch_router \
  --backend openai \
  --worker-urls https://api.openai.com \
  --history-backend postgres
```

### Redis Configuration

```bash Command
export REDIS_URL="redis://localhost:6379"
export REDIS_POOL_MAX=16
export REDIS_RETENTION_DAYS=30

python -m sglang_router.launch_router \
  --backend openai \
  --worker-urls https://api.openai.com \
  --history-backend redis \
  --redis-retention-days 30
```

Use `--redis-retention-days -1` for persistent storage (default is 30 days).

***
## WASM Middleware

The gateway supports WebAssembly (WASM) middleware modules for custom request/response processing. This enables organization-specific logic for authentication, rate limiting, billing, logging, and more—without modifying or recompiling the gateway.

### Overview

WASM middleware runs in a sandboxed environment with memory isolation, no network/filesystem access, and configurable resource limits.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Attach Point</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>When Executed</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Use Cases</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`OnRequest`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Before forwarding to workers</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Auth, rate limiting, request modification</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`OnResponse`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>After receiving worker response</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Logging, response modification, error handling</td>
    </tr>
  </tbody>
</table>

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Action</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`Continue`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Proceed without modification</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`Reject(status)`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Reject request with HTTP status code</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`Modify(...)`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Modify headers, body, or status</td>
    </tr>
  </tbody>
</table>

### Examples

Complete working examples are available in `examples/wasm/`:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Example</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`auth/`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>API key authentication for protected routes</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`rate_limit/`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Per-client rate limiting (requests/minute)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`logging/`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Request tracking headers and response modification</td>
    </tr>
  </tbody>
</table>

The interface definition is located at `src/wasm/interface`.

### Building Modules

```bash Command
# Prerequisites
rustup target add wasm32-wasip2
cargo install wasm-tools

# Build
cargo build --target wasm32-wasip2 --release

# Convert to component format
wasm-tools component new \
  target/wasm32-wasip2/release/my_middleware.wasm \
  -o my_middleware.component.wasm
```

### Deploying Modules

```bash Command
# Enable WASM support
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 \
  --enable-wasm

# Upload module
curl -X POST http://localhost:30000/wasm \
  -H "Content-Type: application/json" \
  -d '{
    "modules": [{
      "name": "auth-middleware",
      "file_path": "/absolute/path/to/auth.component.wasm",
      "module_type": "Middleware",
      "attach_points": [{"Middleware": "OnRequest"}]
    }]
  }'

# List modules
curl http://localhost:30000/wasm

# Remove module
curl -X DELETE http://localhost:30000/wasm/{module_uuid}
```

### Runtime Configuration

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`max_memory_pages`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>1024 (64MB)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Maximum WASM memory</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`max_execution_time_ms`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>1000</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Execution timeout</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`max_stack_size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>1MB</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Stack size limit</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`module_cache_size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>10</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Cached modules per worker</td>
    </tr>
  </tbody>
</table>

**Note:** Rate limiting state is per-worker thread and not shared across gateway replicas. For production, consider implementing rate limiting at a shared layer (e.g., Redis)

***
## Language Bindings

SGLang Model Gateway provides official language bindings for Python and Go, enabling integration with different technology stacks and organizational requirements.

### Python Bindings

The Python bindings provide a PyO3-based wrapper around the Rust gateway library. This is a straightforward binding that calls the gateway server startup from Python.

#### Installation

```bash Command
# From PyPI
pip install sglang-router

# Development build
cd sgl-model-gateway/bindings/python
pip install maturin && maturin develop --features vendored-openssl
```

#### Usage

The Python bindings are used throughout this documentation. See the [Quick Start](#quick-start) and [Deployment Modes](#deployment-modes) sections for detailed examples.

Key components:
- `RouterArgs` dataclass with 50+ configuration options
- `Router.from_args()` for programmatic startup
- CLI commands: `smg launch`, `smg server`, `python -m sglang_router.launch_router`

### Go Bindings

The Go bindings provide a high-performance gRPC client library for organizations with Go-based infrastructure. This is ideal for:

- Integration with internal Go services and tooling
- High-performance client applications
- Building custom OpenAI-compatible proxy servers

#### Architecture

```text Output
+-------------------------------------------+
|           High-Level Go API               |
|   (client.go - OpenAI-style interface)    |
+-------------------------------------------+
|              gRPC Layer                   |
+-------------------------------------------+
|           Rust FFI Layer                  |
|   (Tokenization, Parsing, Conversion)     |
+-------------------------------------------+
```

**Key Features:**
- Native Rust tokenization via FFI (thread-safe, lock-free)
- Full streaming support with context cancellation
- Configurable channel buffer sizes for high concurrency
- Built-in tool call parsing and chat template application

#### Installation

```bash Command
# Build the FFI library first
cd sgl-model-gateway/bindings/golang
make build && make lib

# Then use in your Go project
go get github.com/sgl-project/sgl-go-sdk
```

**Requirements:** Go 1.24+, Rust toolchain

#### Examples

Complete working examples are available in `bindings/golang/examples/`:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Example</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`simple/`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Non-streaming chat completion</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`streaming/`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Streaming chat completion with SSE</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`oai_server/`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Full OpenAI-compatible HTTP server</td>
    </tr>
  </tbody>
</table>

```bash Command
# Run examples
cd sgl-model-gateway/bindings/golang/examples/simple && ./run.sh
cd sgl-model-gateway/bindings/golang/examples/streaming && ./run.sh
cd sgl-model-gateway/bindings/golang/examples/oai_server && ./run.sh
```

#### Testing

```bash Command
cd sgl-model-gateway/bindings/golang

# Unit tests
go test -v ./...

# Integration tests (requires running SGLang server)
export SGL_GRPC_ENDPOINT=grpc://localhost:20000
export SGL_TOKENIZER_PATH=/path/to/tokenizer
go test -tags=integration -v ./...
```

### Comparison

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Feature</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Python</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Go</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Primary Use**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Gateway server launcher</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>gRPC client library</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**CLI Support**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Full CLI (smg, sglang-router)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Library only</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**K8s Discovery**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Native support</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>N/A (client library)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**PD Mode**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Built-in</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>N/A (client library)</td>
    </tr>
  </tbody>
</table>

**When to Use Python:** Launching and managing the gateway server, service discovery, PD disaggregation.

**When to Use Go:** Building custom client applications, integration with Go microservices, OpenAI-compatible proxy servers

***
## Security and Authentication

### Router API Key

```bash Command
python -m sglang_router.launch_router \
  --api-key "your-router-api-key" \
  --worker-urls http://worker1:8000
```

Clients must supply `Authorization: Bearer <key>` for protected endpoints.

### Worker API Keys

```bash Command
# Add worker with explicit key
curl -H "Authorization: Bearer router-key" \
  -X POST http://localhost:8080/workers \
  -H "Content-Type: application/json" \
  -d '{"url":"http://worker:8000","api_key":"worker-key"}'
```

### Security Configurations

1. **No Authentication** (default): Use only in trusted environments
2. **Router-only Authentication**: Clients authenticate to router
3. **Worker-only Authentication**: Router open, workers require keys
4. **Full Authentication**: Both router and workers protected

### TLS (HTTPS) for Gateway Server

Enable TLS to serve the gateway over HTTPS:

```bash Command
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 \
  --tls-cert-path /path/to/server.crt \
  --tls-key-path /path/to/server.key
```

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tls-cert-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to server certificate (PEM format)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tls-key-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to server private key (PEM format)</td>
    </tr>
  </tbody>
</table>

Both parameters must be provided together. The gateway uses rustls with the ring crypto provider for TLS termination. If TLS is not configured, the gateway falls back to plain HTTP.

### mTLS for Worker Communication

Enable mutual TLS (mTLS) for secure communication with workers in HTTP mode:

```bash Command
python -m sglang_router.launch_router \
  --worker-urls https://worker1:8443 https://worker2:8443 \
  --client-cert-path /path/to/client.crt \
  --client-key-path /path/to/client.key \
  --ca-cert-path /path/to/ca.crt
```

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--client-cert-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to client certificate for mTLS (PEM format)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--client-key-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to client private key for mTLS (PEM format)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ca-cert-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to CA certificate for verifying worker TLS (PEM format, repeatable)</td>
    </tr>
  </tbody>
</table>

**Key Points:**
- Client certificate and key must be provided together
- Multiple CA certificates can be added with multiple `--ca-cert-path` flags
- Uses rustls backend when TLS is configured
- Single HTTP client is created for all workers (assumes single security domain)
- TCP keepalive (30 seconds) is enabled for long-lived connections

### Full TLS Configuration Example

Gateway HTTPS + Worker mTLS + API Key authentication:

```bash Command
python -m sglang_router.launch_router \
  --worker-urls https://worker1:8443 https://worker2:8443 \
  --tls-cert-path /etc/certs/server.crt \
  --tls-key-path /etc/certs/server.key \
  --client-cert-path /etc/certs/client.crt \
  --client-key-path /etc/certs/client.key \
  --ca-cert-path /etc/certs/ca.crt \
  --api-key "secure-api-key" \
  --policy cache_aware
```

***
## Observability

### Prometheus Metrics

Enable with `--prometheus-host`/`--prometheus-port` (defaults to `0.0.0.0:29000`).

#### Metric Categories (40+ metrics)

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Layer</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Prefix</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Metrics</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>HTTP</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_http_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`requests_total`, `request_duration_seconds`, `responses_total`, `connections_active`, `rate_limit_total`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Router</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_router_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`requests_total`, `request_duration_seconds`, `request_errors_total`, `stage_duration_seconds`, `upstream_responses_total`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Inference</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_router_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`ttft_seconds`, `tpot_seconds`, `tokens_total`, `generation_duration_seconds`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Worker</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_worker_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`pool_size`, `connections_active`, `requests_active`, `health_checks_total`, `selection_total`, `errors_total`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Circuit Breaker</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_worker_cb_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`state`, `transitions_total`, `outcomes_total`, `consecutive_failures`, `consecutive_successes`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Retry</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_worker_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`retries_total`, `retries_exhausted_total`, `retry_backoff_seconds`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Discovery</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_discovery_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`registrations_total`, `deregistrations_total`, `sync_duration_seconds`, `workers_discovered`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>MCP</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_mcp_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`tool_calls_total`, `tool_duration_seconds`, `servers_active`, `tool_iterations_total`</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Database</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`smg_db_*`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`operations_total`, `operation_duration_seconds`, `connections_active`, `items_stored`</td>
    </tr>
  </tbody>
</table>

#### Key Inference Metrics (gRPC mode)

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Metric</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`smg_router_ttft_seconds`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Histogram</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Time to first token</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`smg_router_tpot_seconds`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Histogram</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Time per output token</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`smg_router_tokens_total`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Counter</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Total tokens (input/output)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`smg_router_generation_duration_seconds`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Histogram</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>End-to-end generation time</td>
    </tr>
  </tbody>
</table>

#### Duration Buckets

1ms, 5ms, 10ms, 25ms, 50ms, 100ms, 250ms, 500ms, 1s, 2.5s, 5s, 10s, 15s, 30s, 45s, 60s, 90s, 120s, 180s, 240s

### OpenTelemetry Tracing

Enable distributed tracing with OTLP export:

```bash Command
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 \
  --enable-trace \
  --otlp-traces-endpoint localhost:4317
```

#### Features

- OTLP/gRPC exporter (default port 4317)
- W3C Trace Context propagation for HTTP and gRPC
- Batch span processing (500ms delay, 64 span batch size)
- Custom filtering to reduce noise
- Trace context injection into upstream worker requests
- Service name: `sgl-router`

### Logging

```bash Command
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 \
  --log-level debug \
  --log-dir ./router_logs
```

Structured tracing with optional file sink. Log levels: `debug`, `info`, `warn`, `error`.

### Request ID Propagation

```bash Command
--request-id-headers x-request-id x-trace-id x-correlation-id
```

Responses include `x-request-id` header for correlation.

***
## Production Recommendations

This section provides guidance for deploying SGLang Model Gateway in production environments.

### Security Best Practices

**Always enable TLS in production:**

```bash Command
python -m sglang_router.launch_router \
  --worker-urls https://worker1:8443 https://worker2:8443 \
  --tls-cert-path /etc/certs/server.crt \
  --tls-key-path /etc/certs/server.key \
  --client-cert-path /etc/certs/client.crt \
  --client-key-path /etc/certs/client.key \
  --ca-cert-path /etc/certs/ca.crt \
  --api-key "${ROUTER_API_KEY}"
```

**Security Checklist:**
- Enable TLS for gateway HTTPS termination
- Enable mTLS for worker communication when workers are on untrusted networks
- Set `--api-key` to protect router endpoints
- Use Kubernetes Secrets or a secrets manager for credentials
- Rotate certificates and API keys periodically
- Restrict network access with firewalls or network policies

### High Availability

**Scaling Strategy:**

The gateway supports running multiple replicas behind a load balancer for high availability. However, there are important considerations:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Component</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Shared Across Replicas</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Impact</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Worker Registry</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No (independent)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Each replica discovers workers independently</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Radix Cache Tree</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No (independent)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Cache hits may decrease by 10-20%</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Circuit Breaker State</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No (independent)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Each replica tracks failures independently</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Rate Limiting</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No (independent)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Limits apply per-replica, not globally</td>
    </tr>
  </tbody>
</table>

**Recommendations:**

1. **Prefer horizontal scaling over vertical scaling**: Deploy multiple smaller gateway replicas rather than one large instance with excessive CPU and memory. This provides:
   - Better fault tolerance (single replica failure doesn't take down the gateway)
   - More predictable resource usage
   - Easier capacity planning

2. **Use Kubernetes Service Discovery**: Let the gateway automatically discover and manage workers:
   ```bash Command
   python -m sglang_router.launch_router \
     --service-discovery \
     --selector app=sglang-worker \
     --service-discovery-namespace production
   ```

3. **Accept cache efficiency trade-off**: With multiple replicas, the cache-aware routing policy's radix tree is not synchronized across replicas. This means:
   - Each replica builds its own cache tree
   - Requests from the same user may hit different replicas
   - Expected cache hit rate reduction: **10-20%**
   - This is often acceptable given the HA benefits

4. **Configure session affinity (optional)**: If cache efficiency is critical, configure your load balancer for session affinity based on a consistent hash of the request (e.g., user ID or API key).

**Example HA Architecture:**
```text Output
                    +-------------------+
                    |   Load Balancer   |
                    |     (L4/L7)       |
                    +---------+---------+
                              |
          +-------------------+-------------------+
          |                   |                   |
          v                   v                   v
    +-----------+       +-----------+       +-----------+
    |  Gateway  |       |  Gateway  |       |  Gateway  |
    | Replica 1 |       | Replica 2 |       | Replica 3 |
    +-----+-----+       +-----+-----+       +-----+-----+
          |                   |                   |
          +-------------------+-------------------+
                              |
          +-------------------+-------------------+
          |                   |                   |
          v                   v                   v
    +-----------+       +-----------+       +-----------+
    |  Worker   |       |  Worker   |       |  Worker   |
    |   Pod 1   |       |   Pod 2   |       |   Pod N   |
    +-----------+       +-----------+       +-----------+
```

### Performance

**Use gRPC mode for high throughput:**

gRPC mode provides the highest performance for SGLang workers:

```bash Command
# Start workers in gRPC mode
python -m sglang.launch_server \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --grpc-mode \
  --port 20000

# Configure gateway for gRPC
python -m sglang_router.launch_router \
  --worker-urls grpc://worker1:20000 grpc://worker2:20000 \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --policy cache_aware
```

**Performance Benefits of gRPC:**
- Native Rust tokenization (no Python overhead)
- Streaming with lower latency
- Built-in reasoning parser execution
- Tool call parsing in the gateway
- Reduced serialization overhead

**Tuning Recommendations:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Recommendation</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Reason</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`cache_aware`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Best for repeated prompts, ~30% latency reduction</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-concurrent-requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>2-4x worker count</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Prevent overload while maximizing throughput</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--queue-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>2x max-concurrent</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Buffer for burst traffic</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--request-timeout-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Based on max generation length</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Prevent stuck requests</td>
    </tr>
  </tbody>
</table>

### Kubernetes Deployment

**Pod Labeling for Service Discovery:**

For the gateway to discover workers automatically, label your worker pods consistently:

```yaml Config
# Worker Deployment (Regular Mode)
apiVersion: apps/v1
kind: Deployment
metadata:
  name: sglang-worker
  namespace: production
spec:
  replicas: 4
  selector:
    matchLabels:
      app: sglang-worker
      component: inference
  template:
    metadata:
      labels:
        app: sglang-worker
        component: inference
        model: llama-3-8b
    spec:
      containers:
      - name: worker
        image: lmsysorg/sglang:latest
        ports:
        - containerPort: 8000
          name: http
        - containerPort: 20000
          name: grpc
```

**Gateway configuration for discovery:**
```bash Command
python -m sglang_router.launch_router \
  --service-discovery \
  --selector app=sglang-worker component=inference \
  --service-discovery-namespace production \
  --service-discovery-port 8000
```

**PD (Prefill/Decode) Mode Labeling:**

```yaml Config
# Prefill Worker
metadata:
  labels:
    app: sglang-worker
    component: prefill
  annotations:
    sglang.ai/bootstrap-port: "9001"

# Decode Worker
metadata:
  labels:
    app: sglang-worker
    component: decode
```

**Gateway configuration for PD discovery:**
```bash Command
python -m sglang_router.launch_router \
  --service-discovery \
  --pd-disaggregation \
  --prefill-selector app=sglang-worker component=prefill \
  --decode-selector app=sglang-worker component=decode \
  --service-discovery-namespace production
```

**RBAC Requirements:**

The gateway needs permissions to watch pods:

```yaml Config
apiVersion: rbac.authorization.k8s.io/v1
kind: Role
metadata:
  name: sglang-gateway
  namespace: production
rules:
- apiGroups: [""]
  resources: ["pods"]
  verbs: ["get", "list", "watch"]
***
apiVersion: rbac.authorization.k8s.io/v1
kind: RoleBinding
metadata:
  name: sglang-gateway
  namespace: production
subjects:
- kind: ServiceAccount
  name: sglang-gateway
  namespace: production
roleRef:
  kind: Role
  name: sglang-gateway
  apiGroup: rbac.authorization.k8s.io
```

### Monitoring with PromQL

Configure Prometheus to scrape the gateway metrics endpoint (default: `:29000/metrics`).

**Essential Dashboards:**

**1. Request Rate and Latency:**
```sql Example
# Request rate by endpoint
sum(rate(smg_http_requests_total[5m])) by (path, method)

# P50 latency
histogram_quantile(0.50, sum(rate(smg_http_request_duration_seconds_bucket[5m])) by (le))

# P99 latency
histogram_quantile(0.99, sum(rate(smg_http_request_duration_seconds_bucket[5m])) by (le))

# Error rate
sum(rate(smg_http_responses_total{status=~"5.."}[5m])) / sum(rate(smg_http_responses_total[5m]))
```

**2. Worker Health:**
```sql Example
# Healthy workers
sum(smg_worker_pool_size)

# Active connections per worker
smg_worker_connections_active

# Worker health check failures
sum(rate(smg_worker_health_checks_total{result="failure"}[5m])) by (worker_id)
```

**3. Circuit Breaker Status:**
```sql Example
# Circuit breaker states (0=closed, 1=open, 2=half-open)
smg_worker_cb_state

# Circuit breaker transitions
sum(rate(smg_worker_cb_transitions_total[5m])) by (worker_id, from_state, to_state)

# Workers with open circuits
count(smg_worker_cb_state == 1)
```

**4. Inference Performance (gRPC mode):**
```sql Example
# Time to first token (P50)
histogram_quantile(0.50, sum(rate(smg_router_ttft_seconds_bucket[5m])) by (le, model))

# Time per output token (P99)
histogram_quantile(0.99, sum(rate(smg_router_tpot_seconds_bucket[5m])) by (le, model))

# Token throughput
sum(rate(smg_router_tokens_total[5m])) by (model, direction)

# Generation duration P95
histogram_quantile(0.95, sum(rate(smg_router_generation_duration_seconds_bucket[5m])) by (le))
```

**5. Rate Limiting and Queuing:**
```sql Example
# Rate limit rejections
sum(rate(smg_http_rate_limit_total{decision="rejected"}[5m]))

# Queue depth (if using concurrency limiting)
smg_worker_requests_active

# Retry attempts
sum(rate(smg_worker_retries_total[5m])) by (worker_id)

# Exhausted retries (failures after all retries)
sum(rate(smg_worker_retries_exhausted_total[5m]))
```

**6. MCP Tool Execution:**
```sql Example
# Tool call rate
sum(rate(smg_mcp_tool_calls_total[5m])) by (server, tool)

# Tool latency P95
histogram_quantile(0.95, sum(rate(smg_mcp_tool_duration_seconds_bucket[5m])) by (le, tool))

# Active MCP server connections
smg_mcp_servers_active
```

**Alerting Rules Example:**

```yaml Config
groups:
- name: sglang-gateway
  rules:
  - alert: HighErrorRate
    expr: |
      sum(rate(smg_http_responses_total{status=~"5.."}[5m]))
      / sum(rate(smg_http_responses_total[5m])) > 0.05
    for: 5m
    labels:
      severity: critical
    annotations:
      summary: "High error rate on SGLang Gateway"

  - alert: CircuitBreakerOpen
    expr: count(smg_worker_cb_state == 1) > 0
    for: 2m
    labels:
      severity: warning
    annotations:
      summary: "Worker circuit breaker is open"

  - alert: HighLatency
    expr: |
      histogram_quantile(0.99, sum(rate(smg_http_request_duration_seconds_bucket[5m])) by (le)) > 30
    for: 5m
    labels:
      severity: warning
    annotations:
      summary: "P99 latency exceeds 30 seconds"

  - alert: NoHealthyWorkers
    expr: sum(smg_worker_pool_size) == 0
    for: 1m
    labels:
      severity: critical
    annotations:
      summary: "No healthy workers available"
```

***
## Configuration Reference

### Core Settings

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--host`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>127.0.0.1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Router host</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>30000</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Router port</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--worker-urls`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>list</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>[]</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Worker URLs (HTTP or gRPC)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>cache_aware</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Routing policy</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-concurrent-requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>-1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Concurrency limit (-1 disables)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--request-timeout-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>600</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Request timeout</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--max-payload-size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>256MB</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum request payload</td>
    </tr>
  </tbody>
</table>

### Prefill/Decode

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--pd-disaggregation`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>flag</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>false</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable PD mode</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>list</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>[]</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Prefill URLs + optional bootstrap ports</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--decode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>list</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>[]</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Decode URLs</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>None</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Override policy for prefill nodes</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--decode-policy`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>None</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Override policy for decode nodes</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--decode-dispatch-limit`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>None</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Requests per prefill worker sent to decode before decode answers or prefill finishes; the rest pick their decode worker when sent. Needs prefill `--optimistic-prefill-attempts` above 0</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--worker-startup-timeout-secs`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>600</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Worker init timeout</td>
    </tr>
  </tbody>
</table>

### Kubernetes Discovery

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--service-discovery`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>flag</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Enable discovery</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--selector`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>list</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Label selectors (key=value)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--prefill-selector` / `--decode-selector`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>list</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>PD mode selectors</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--service-discovery-namespace`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Namespace to watch</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--service-discovery-port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>int</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Worker port (default 80)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--bootstrap-port-annotation`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Annotation for bootstrap ports</td>
    </tr>
  </tbody>
</table>

### TLS Configuration

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tls-cert-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Server certificate for gateway HTTPS (PEM)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--tls-key-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Server private key for gateway HTTPS (PEM)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--client-cert-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Client certificate for worker mTLS (PEM)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--client-key-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Client private key for worker mTLS (PEM)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`--ca-cert-path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>str</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>CA certificate for verifying workers (PEM, repeatable)</td>
    </tr>
  </tbody>
</table>

***
## Troubleshooting

### Workers Never Ready

Increase `--worker-startup-timeout-secs` or ensure health probes respond before router startup.

### Load Imbalance / Hot Workers

Inspect `smg_router_requests_total` by worker and tune cache-aware thresholds (`--balance-*`, `--cache-threshold`).

### Circuit Breaker Flapping

Increase `--cb-failure-threshold` or extend the timeout/window durations. Consider temporarily disabling retries.

### Queue Overflow (429)

Increase `--queue-size` or reduce client concurrency. Ensure `--max-concurrent-requests` matches downstream capacity.

### Memory Growth

Reduce `--max-tree-size` or lower `--eviction-interval-secs` for more aggressive cache pruning.

### Debugging

```bash Command
python -m sglang_router.launch_router \
  --worker-urls http://worker1:8000 \
  --log-level debug \
  --log-dir ./router_logs
```

### gRPC Connection Issues

Ensure workers are started with `--grpc-mode` and verify `--model-path` or `--tokenizer-path` is provided to the router.

### Tokenizer Loading Failures

Check HuggingFace Hub credentials (`HF_TOKEN` environment variable) for private models. Verify local paths are accessible.

***
SGLang Model Gateway continues to evolve alongside the SGLang runtime. Keep CLI flags, integrations, and documentation aligned when adopting new features or contributing improvements.

---

### Docs Advanced Features Sglang For Rl (`docs/docs/advanced_features/sglang_for_rl.mdx`)

---
title: "SGLang for RL Systems"
metatags:
    description: "SGLang for RL: engine sleep/wake, weight refit, partial rollout, deterministic inference, cache-aware load balancing for RLHF."
---
This document is a practical guide for infrastructure teams integrating SGLang into RL and post-training systems. It focuses on the operational pain points in the loop (rollout, evaluation, training, weight sync) and maps them to concrete SGLang APIs, flags, and integration patterns. The focus is on maximizing rollout efficiency, accuracy and stability while keeping rollout-serving behavior aligned in production environments.

## Why SGLang for RL Lifecycle?

Let's embrace a guiding principle from early DeepMind's RL engineering:

**Be a library, not a framework.**

This philosophy empowers innovation by providing SGLang as flexible tools, not rigid structures. Here are five reasons to use SGLang for your RL lifecycle:

* **Fine-Grained Engine Sleep and Wake Up**: facilitate maximum-powered rollout and training
* **Open-To-Use Refit Functionality**: diverse methods for co-location or disaggregation
* **Easy To Postpone Generation**: enable partial rollout and dedicated rollout control
* **Deterministic Inference**: achieve deterministic inference to enable zero training-inference mismatch
* **Load Balancing Router**: cache-aware load-balancing for high-throughput rollout

The following sections cover these aspects in detail.

## Fine-Grained Engine Sleep and Wake Up

Rollout and training are both memory-intensive, and co-locating them on the same GPUs often leads to memory pressure and slow handoffs. SGLang provides a memory-aware sleep/wake mechanism that releases KV cache and weights while keeping the server process alive, then resumes them for rollout without a full restart. This avoids repeated disk I/O and CUDA graph recapture during each RL step.

Under the hood, the RL team uses CUDA-graph-aware weight offload via [torch_memory_saver](https://github.com/fzyzcjy/torch_memory_saver) to preserve virtual memory addresses for graph replay. For details, see: [Efficient RL Training - Optimizing Memory Usage in verl](https://hebiao064.github.io/rl-memory-management).

### Server flag

Enable memory saver support when launching the server:

```text Output
--enable-memory-saver
```

### Release Memory

**Endpoint:** `POST /release_memory_occupation`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`tags`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Which memory regions to release. If omitted, all are released.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: list[str], values: `kv_cache`, `weights`</td>
    </tr>
  </tbody>
</table>
{/* python/sglang/srt/managers/io_struct.py#L1381 currently only supports `kv_cache`, `weights` */}
**Behavior notes:**

- This call asserts there are no ongoing requests. Ensure the engine is idle before calling it.
- If `kv_cache` is released, SGLang flushes cache; subsequent requests will rebuild KV cache as needed.

### Resume Memory

**Endpoint:** `POST /resume_memory_occupation`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`tags`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Which memory regions to resume. If omitted, all are resumed.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: list[str], values: `kv_cache`, `weights`</td>
    </tr>
  </tbody>
</table>
{/* python/sglang/srt/managers/io_struct.py#L1393 currently only supports `kv_cache`, `weights` */}

## Open-To-Use Refit Functionality

After training completes each step, rollout engines must be refit with new weights. SGLang supports three refit strategies so you can match your infrastructure style (co-located vs disaggregated) and scaling needs. Each strategy maps to a concrete API with clear request schemas. For a deeper dive into SGLang's weight update utilities, see [RL System Deep Thinking: Weight Update Mechanisms](https://github.com/zhaochenyang20/Awesome-ML-SYS-Tutorial/blob/main/rlhf/sys-design/readme-1-EN.md).

**How to choose:**

- **From disk** is simplest and best for elastic rollout scaling and checkpointing.
- **From tensor** is best for co-located training/rollout when you can pass in-memory tensors.
- **From distributed** is best for disaggregated training/rollout with dedicated communication groups (NCCL/IB).

### Update Weights from Disk

**When to use:**

- Save checkpoint to disk and update weights from disk
- Dynamic scaling (new rollout instances can load from the same checkpoint)

**Why it works well:**

This path trades some I/O overhead for simplicity and flexibility. It integrates naturally with checkpointing and makes it trivial to add new rollout engines: point them at the same checkpoint and call the API. It is also the safest option for high availability because the checkpoint itself is the source of truth.

**Endpoint:** `POST /update_weights_from_disk`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`model_path`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The model path with the new weights.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`load_format`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The format to load the weights.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`abort_all_requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Abort all running requests before update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`weight_version`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Optional weight version label tracked by the server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`is_async`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Perform weight load asynchronously.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`torch_empty_cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Empty torch cache.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`keep_pause`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Keep scheduler paused after update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`recapture_cuda_graph`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Recapture CUDA graphs after update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`token_step`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Trainer step id for rollout bookkeeping.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`flush_cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Flush KV cache after update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`True`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
  </tbody>
</table>

**Response body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`success`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Whether the update succeeded.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>-</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`message`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Status / error message.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>-</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`num_paused_requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of paused requests during update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
  </tbody>
</table>

**Python Engine API:** `engine.update_weights_from_disk(model_path, load_format=None)`

**Diffusion engine (SGLang-Diffusion):** The diffusion engine exposes the same `POST /update_weights_from_disk` endpoint with the following behavior:

- **All-or-nothing with rollback:** if any module fails to load, all previously updated modules are rolled back to the original weights by reloading from the original model path. No partial updates are left behind. If rollback itself fails, the exception propagates so the caller knows the model is in an inconsistent state.
- **Offload-aware:** when layerwise offload (`--dit-layerwise-offload`) is enabled, the diffusion offload manager replaces GPU parameters with small `torch.empty((1,))` placeholders while real weights live in consolidated pinned CPU buffers. A naive `param.data.copy_()` would fail with a shape mismatch. Instead, the updater dynamically detects active offload managers and writes new weights directly into their CPU buffers, bypassing the placeholders entirely. For any layer that happens to be prefetched on GPU at update time, the live GPU tensor is also updated so the change takes effect immediately. This requires no extra GPU memory and does not disturb the offload state.
- **DTensor-aware:** parameters distributed via `torch.distributed.tensor` (tensor parallelism) are updated through `distribute_tensor` so that each shard is correctly placed on the right device mesh.

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>model_path</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>The model path with the new weights.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>flush_cache</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Flush TeaCache state after update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>True</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>target_modules</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>List of module names to update (e.g. <code>["transformer"]</code>). If omitted, all <code>nn.Module</code> components are updated.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: list[str]</td>
    </tr>
  </tbody>
</table>

**Response body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>success</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Whether the update succeeded.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>-</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>message</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Status / error message.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>-</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

> **Note:** The diffusion engine (SGLang-Diffusion) does not currently support hot refit (updating weights while inference is in progress). The diffusion scheduler processes one request at a time and completes the entire inference before handling the next request, so weight updates and inference never run concurrently.

### Weight Update Session

`update_weights_from_tensor` and `update_weights_from_distributed` must run inside a weight-update session. The update calls only write checkpoint-format values; `end_weight_update` runs every quantized layer's `process_weights_after_loading` once, turning them into kernel layout (Marlin repack, MXFP8 shuffles, ...), and runs `post_load_weights` if no weights were loaded through the engine during the session (P2P/RDMA writes). `begin_weight_update` first restores the few schemes whose kernel layout changes parameter shapes (today compressed-tensors W4A16 MoE on Marlin) so the checkpoint-format values fit. One session can span many update calls, so the finalize cost is paid once per refit rather than once per bucket. A call outside a session, a second `begin_weight_update`, or an `end_weight_update` without one is rejected with `success: false` (HTTP 400) and leaves the weights untouched.

**Endpoints:** `POST /begin_weight_update`, `POST /end_weight_update`

`begin_weight_update` accepts `selector`: `"target"`, `"draft"`, or `"all"` (default). Under speculative decoding the same selector on the update endpoints picks which model runners receive the weights; `end_weight_update` finalizes the runners the session opened.

```python
engine.begin_weight_update()
for bucket in buckets:
    engine.update_weights_from_tensor(bucket)
engine.end_weight_update()
```

### Update Weights from Tensor

**When to use:**

- Co-located training and rollout, where training can provide tensors directly
- Fast in-memory updates

**Important constraints:**

This strategy requires the training process and rollout engine to share access to the tensors. Co-located setups must keep the model on GPU; moving tensors to CPU will break the update path. For high-performance MoE or specialized attention kernels, co-location may limit some optimizations compared to disaggregated rollouts.

**Endpoint:** `POST /update_weights_from_tensor`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>serialized_named_tensors</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Per-TP serialized tensor payloads.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: list[str|bytes]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>load_format</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Optional load format selector.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>None</code>, <code>direct</code>, <code>flattened_bucket</code>, or a custom loader path string</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>flush_cache</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Flush KV cache after update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>True</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>abort_all_requests</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Abort all running requests before update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>False</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>weight_version</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Optional version label tracked by the server.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

**Note:** The serialized tensor payloads must be created with `MultiprocessingSerializer.serialize(...)` and should be base64-safe strings.

**Python Engine API:** `engine.update_weights_from_tensor(named_tensors, load_format=None, flush_cache=True)`, inside `begin_weight_update()` / `end_weight_update()`.

### Update Weights from Distributed Group

**When to use:**

- Disaggregated training and rollout
- NCCL or IB-backed weight broadcast from training workers to rollout workers

**How it works:**

Training workers gather weights (typically on TP rank 0), broadcast them to the rollout group, and each rollout TP shard loads the parameters it needs. This avoids disk I/O and keeps training and rollout decoupled, at the cost of managing a dedicated communication group.

**Initialize weight update group**

**Endpoint:** `POST /init_weights_update_group`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`master_address`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Group master address.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`master_port`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Group master port.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`rank_offset`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Offset for local rank mapping.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`world_size`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Total world size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: int</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`group_name`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Group name.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`weight_update_group`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`backend`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Communication backend.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`nccl`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

**Update weight**

**Endpoint:** `POST /update_weights_from_distributed`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`names`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Parameter names to update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: list[str]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`dtypes`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Dtype strings for each parameter.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: list[str]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`shapes`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Tensor shapes.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Required</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: list[list[int]]</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`group_name`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Group name.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`weight_update_group`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`flush_cache`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Flush KV cache after update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`True`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`abort_all_requests`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Abort all running requests before update.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: bool</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`weight_version`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Optional version label.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`load_format`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Optional format selector.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`None` or `flattened_bucket`</td>
    </tr>
  </tbody>
</table>

**Destroy weights update group**

**Endpoint:** `POST /destroy_weights_update_group`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`group_name`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Group name.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`weight_update_group`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Type: str</td>
    </tr>
  </tbody>
</table>

**Python Engine APIs:**

- `engine.init_weights_update_group(...)`
- `engine.begin_weight_update(selector="all")`
- `engine.update_weights_from_distributed(names, dtypes, shapes, ...)`
- `engine.end_weight_update()`
- `engine.destroy_weights_update_group(group_name)`

### Per-Token Weight Version Attribution

A request can outlive a version change: the RL flow retracts it with `pause_generation`, refits, and continues it, or `POST /update_weight_version` relabels while it is still generating. `meta_info` then reports which tokens came from which weights:

```json Output
"weight_version": "42",
"weight_versions": [
    {"version": "41", "start": 0, "end": 57},
    {"version": "42", "start": 57, "end": 128}
]
```

- Ranges are half-open `[start, end)` over output-token indices, prompt excluded. The usual case is a single span.

## Easy To Postpone Generation

Multi-turn RL rollouts often suffer from long-tail requests that block the entire batch. A small number of slow interactions can stall all GPUs, and the long-tail behavior makes profiling and monitoring difficult.

SGLang exposes explicit pause/resume APIs so you can pause slow requests and continue them later. This pattern matches systems like [APRIL](https://arxiv.org/abs/2509.18521), terminate once enough responses are collected, and recycle incomplete responses in the next step. The result is higher GPU utilization without discarding partial work.

`pause_generation` ---  update weights --- `continue_generation` is the correct execution flow when updating weights from training. An update can only happen when SGLang is not actively processing inference tasks.

### Pause Generation

**Endpoint:** `POST /pause_generation`

**Request body:**

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Field</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Defaults</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Options</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`mode`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Pause mode.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`abort`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`abort`, `retract`, `in_place`</td>
    </tr>
  </tbody>
</table>

**Modes:**

- `abort`: Default behavior, identical to `abort` endpoint with `abort_all` set. Pending requests from `waiting_queue` and `running_queue` will be returned immediately to the caller.
- `retract`: Put engine in "paused" state.  Move running requests back to waiting queue. KV cache can be flushed and recomputed later.
- `in_place`: Put engine in "paused" state without changing states of the requests. Running requests rely on availability of KV caches to continue, so any subsequent `flush_cache` call will be unsuccessful.

### Continue Generation

**Endpoint:** `POST /continue_generation`

## Deterministic Inference

In many RL stacks, rollout and training are implemented with different kernels or batching behavior. Even when weights are identical, token probabilities can drift, silently breaking the on-policy assumption. This is the training–inference mismatch problem.

SGLang supports a deterministic inference mode that reduces non-determinism across batch shapes. This mitigates variance introduced by runtime batching and kernel selection. To further achieve true on-policy training, you need to modify the training engine to use the same deterministic kernels. For implementation details, see these miles examples: [True On-Policy](https://github.com/radixark/miles/tree/main/examples/true_on_policy) and [True On-Policy for VLM](https://github.com/radixark/miles/tree/main/examples/true_on_policy_vlm). For additional context, see the blog post [Let Speed Be With Stability: All-In-One Solution to Training-Inference Mismatch with Miles](https://github.com/zhaochenyang20/Awesome-ML-SYS-Tutorial/blob/main/rlhf/slime/mismatch/blog-en.md).

**Server flag:**

```text Output
--enable-deterministic-inference
```

For more details, see [Deterministic Inference](./deterministic_inference)

## Load Balancing Router

SGLang Model Gateway is the recommended control plane for large‑scale RL rollouts. It provides async, non‑blocking request handling, cache‑aware load balancing, and fault‑tolerant routing across rollout and reward servers. This lets you keep GPUs saturated while avoiding long‑tail stalls and brittle, engine‑local concurrency logic. It has been deployed in the training of GLM 4.5+ models and proven to be highly efficient in production-level large-scale RL workloads.

Key benefits for RL infrastructure:

- **Async non-blocking efficiency**: SGLang’s native async server/router architecture (HTTPS/gRPC) manages concurrency automatically. This guarantees maximum GPU saturation and effective continuous batching without requiring complex, manual implementation by engineers.
- **Elasticity and fault tolerance**: By encapsulating the reward model and rollout as independent servers, SGLang decouples them logically and physically. This architecture provides robust disaster recovery for large-scale distributed training; if a server fails, the router automatically redirects traffic to healthy nodes, ensuring the training process continues without interruption.
- **Training–Inference alignment**: Using the SGLang Model Gateway for both training and inference ensures "What You See Is What You Get." This eliminates score discrepancies and the painful backend alignment issues often caused by using different engines for training versus deployment.
- **Dynamic load balancing and long-tail mitigation**: Unlike static partitioning, the SGLang Model Gateway enables request-level dynamic dispatching for multi-turn RL. It can distribute different turns of a conversation across different servers to balance workloads and eliminate long-tail latency caused by varying sequence lengths.

For deployment and configuration, see: [SGLang Model Gateway](./sgl_model_gateway)

---

### Docs Advanced Features Sglang Simulator (`docs/docs/advanced_features/sglang_simulator.mdx`)

---
title: "SGLang Simulator"
metatags:
    description: "Run SGLang scheduling and KV-cache simulations without loading model weights or executing GPU kernels."
---

SGLang Simulator reuses SGLang's scheduler, request lifecycle, and KV-cache implementation while replacing model forward execution with a latency predictor. Use it to compare scheduling and cache configurations on timestamped or synthetic workloads without loading model weights.

## Supported scope

SGLang Simulator tracks the current `main` branch and recent SGLang releases. The current integration is validated with `v0.5.16`, `v0.5.17`, `v0.5.18`, and `main`.

The initial upstream scope uses one simulated worker with `tp_size=1`, `ep_size=1`, `dp_size=1`, and `pp_size=1`. A simulator configuration can describe a larger target system for latency prediction, but the SGLang runtime process topology remains single-worker.

The simulator supports:

- synthetic request rates, ShareGPT workloads, and timestamped Autobench traces;
- OFFLINE logical-time simulation and BLOCKING wall-clock replay;
- AIConfigurator, ML, and replay latency predictors;
- SGLang prefix caching and [HiCache](/docs/advanced_features/hicache); and
- serving-compatible TTFT, TPOT, ITL, throughput, and cache-hit metrics.

## Install from the SGLang repository

Use the simulator and SGLang source from the same monorepo checkout:

```bash
python3 -m pip install -e tools/sglang-simulator
export PYTHONPATH="$PWD/tools/sglang-simulator/src:$PWD/python"
```

AIConfigurator is optional. Install the validated extra only when you use an AIConfigurator predictor:

```bash
python3 -m pip install -e "tools/sglang-simulator[aic]"
```

## Start a simulator server

Choose a fresh output directory for every run. The server owns the simulation mode and writes metrics to this directory.

```bash
export SGLANG_USE_CPU_ENGINE=1
export CUDA_VISIBLE_DEVICES=""
export SGLANG_SIMULATOR_OUTPUT_MODE=OFFLINE
export SGLANG_SIMULATOR_OUTPUT_DIR=/tmp/sglang-simulator-quickstart

python3 -m sglang_simulator.simulation.sglang.launch_server \
  --model-path tools/sglang-simulator/test/assets/qwen3-8b \
  --tokenizer-path tools/sglang-simulator/examples/assets/tokenizer \
  --sim-config-path tools/sglang-simulator/examples/sim_configs/replay.json \
  --port 30000
```

`OFFLINE` advances the simulator's logical clock without sleeping. `BLOCKING` also sleeps for predicted forward and cache-load latency, which is useful when a client must observe simulated wall-clock pacing.

## Send a workload

In another terminal, export the same output directory and run the simulator-aware serving benchmark from the repository root:

```bash
export PYTHONPATH="$PWD/tools/sglang-simulator/src:$PWD/python"
export SGLANG_SIMULATOR_OUTPUT_DIR=/tmp/sglang-simulator-quickstart

python3 benchmark/simulator/bench_serving.py \
  --simulator-mode offline \
  --backend sglang \
  --base-url http://127.0.0.1:30000 \
  --model tools/sglang-simulator/test/assets/qwen3-8b \
  --tokenizer tools/sglang-simulator/examples/assets/tokenizer \
  --dataset-name sharegpt \
  --dataset-path tools/sglang-simulator/examples/workloads/sharegpt-example.json \
  --sharegpt-output-len 4 \
  --num-prompts 3 \
  --output-file /tmp/sglang-simulator-quickstart/benchmark.json
```

The benchmark injects logical arrival metadata into each request and displays the server-side simulator metrics. For timestamped traffic, use the simulator-owned Autobench JSONL format and add `--use-trace-timestamps`.

## Read the results

The output directory contains:

- `metrics.json`: aggregate latency, throughput, and cache metrics;
- `request.jsonl`: per-request timing and cache information; and
- `iteration.jsonl`: scheduler batch composition and predicted iteration latency.

Use a unique output directory for each run so metrics from separate experiments are not mixed. See the [SGLang Simulator source README](https://github.com/sgl-project/sglang/tree/main/tools/sglang-simulator) for simulator configuration fields, predictor examples, and maintained tests.

---

### Docs Advanced Features Speculative Decoding (`docs/docs/advanced_features/speculative_decoding.mdx`)

---
title: "Speculative Decoding"
metatags:
    description: "SGLang speculative decoding: EAGLE-2/EAGLE-3, MTP, UNO, DFLASH, draft model configuration, and overlap-scheduler guidance."
---
SGLang provides several speculative decoding options, including EAGLE-2/EAGLE-3, MTP, UNO, DFLASH, classic draft-model decoding, and an NGRAM-based variant. Our implementation aims to maximize speed and efficiency and is considered to be among the fastest in open-source LLM engines.

## Summary

### Jump to sections

- [EAGLE Decoding](#eagle-decoding)
  - [EAGLE-2 Decoding](#eagle-2-decoding)
  - [EAGLE-2 Decoding with torch.compile](#eagle-2-decoding-with-torch-compile)
  - [EAGLE-2 Decoding via Frequency-Ranked Speculative Sampling](#eagle-2-decoding-via-frequency-ranked-speculative-sampling)
  - [EAGLE-3 Decoding](#eagle-3-decoding)
- [Block verification](#block-verification)
- [Multi Token Prediction](#multi-token-prediction)
- [UNO decoding](#uno-decoding)
- [DFlash Decoding](#dflash-decoding)
- [Standalone Speculative Decoding (Small Draft Model)](#standalone-speculative-decoding-small-draft-model)
- [Speculative Decoding V2 (Overlap Scheduler)](#speculative-decoding-v2-overlap-scheduler)
- [Ngram Speculative Decoding](#ngram-speculative-decoding)
- [Full Parameter Reference](#full-parameter-reference)
- [OOM Troubleshooting](#oom-troubleshooting)
- [References](#references)

### Quick guidance

- **Best speed/quality (recommended)**: Use **EAGLE-3** with `--speculative-algorithm EAGLE3`.
- **Strong default / broad compatibility**: Use **EAGLE-2** with `--speculative-algorithm EAGLE`.
- **Workload acceptance changes over time**: Use [**Adaptive speculative decoding**](./adaptive_speculative_decoding) on top of **EAGLE** with `--speculative-eagle-topk 1`.
- **Lower `lm_head` overhead for EAGLE-2**: Enable **FR-Spec** with `--speculative-token-map`.
- **Model is MTP-enabled**: Use **MTP via speculative decoding** (often with small `speculative_num_steps/topk/num_draft_tokens`, see the example section).
- **You have a UNO adapter for the target model**: Use **UNO** with `--speculative-algorithm UNO` and `--uno-lora-path ...`.
- **You have a DFlash draft checkpoint**: Use **DFLASH** with `--speculative-algorithm DFLASH` and `--speculative-draft-model-path ...`.
- **You have a smaller draft LLM**: Use **STANDALONE** (`--speculative-algorithm STANDALONE`).
- **No extra model available**: Use **NGRAM** (`--speculative-algorithm NGRAM`, CUDA-only).

### Method comparison (mini table)

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Draft source</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Separate draft model?</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>How to enable</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Notes / constraints</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>EAGLE-2</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE draft model (feature drafting + tree)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Typically yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>--speculative-algorithm EAGLE</code> + <code>--speculative-draft-model-path ...</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Tune <code>--speculative-num-steps</code>, <code>--speculative-eagle-topk</code>, <code>--speculative-num-draft-tokens</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>EAGLE-2 + <code>torch.compile</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Same as EAGLE-2</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Typically yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Add <code>--enable-torch-compile</code> (optionally <code>--torch-compile-max-bs</code>)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Benefit varies by hardware/model; benchmark to verify</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>EAGLE-2 + FR-Spec</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Same as EAGLE-2 + token subset</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Typically yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Add <code>--speculative-token-map ...</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Reduces <code>lm_head</code> overhead with high-frequency token vocab</td>
    </tr>
<tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>EAGLE-3</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>EAGLE3 draft model</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>--speculative-algorithm EAGLE3</code> + <code>--speculative-draft-model-path ...</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Best throughput in the benchmark below</td>
    </tr>
<tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>MTP</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Built-in multi-token heads (model-specific)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Often no</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>See <strong>Multi Token Prediction</strong> section</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Uses speculative workflow; draft path may be auto-handled for some models</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>UNO</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Target model with a trained UNO LoRA (linear chain or tree)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>--speculative-algorithm UNO</code> + <code>--uno-lora-path ...</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>CUDA and FA3; currently requires TP=PP=1</td>
    </tr>
<tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>DFLASH</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DFlash draft model (linear block verification)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>--speculative-algorithm DFLASH</code> + <code>--speculative-draft-model-path ...</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No DP attention (<code>--attn-dp-size</code> &gt; 1); <code>pp_size == 1</code>; disables overlap scheduler &amp; mixed chunked prefill</td>
    </tr>
<tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>STANDALONE</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Smaller draft LLM (token-level)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Yes</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>--speculative-algorithm STANDALONE</code> + <code>--speculative-draft-model-path ...</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Does <strong>not</strong> support DP attention (<code>--attn-dp-size</code> &gt; 1)</td>
    </tr>
<tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>NGRAM</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Ngram cache from previous tokens</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>No</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>--speculative-algorithm NGRAM</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>CUDA-only; no DP attention (<code>--attn-dp-size</code> &gt; 1); disables overlap scheduler &amp; mixed chunked prefill</td>
    </tr>
</tbody>
</table>

### Performance Highlights

Please see below for the huge improvements on throughput for LLaMA-Instruct 3.1 8B tested on MT bench that can be achieved via EAGLE3 decoding.
For further details please see the [EAGLE3 paper](https://arxiv.org/pdf/2503.01840).

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Throughput (tokens/s)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>SGLang (w/o speculative, 1x H100)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>158.34 tokens/s</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>SGLang + EAGLE-2 (1x H100)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>244.10 tokens/s</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>SGLang + EAGLE-3 (1x H100)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>373.25 tokens/s</td>
    </tr>
  </tbody>
</table>

---

## EAGLE Decoding

To enable EAGLE speculative decoding the following parameters are relevant:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "30%"}} />
    <col style={{width: "50%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-path</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Draft model path/weights. <strong>Typically required</strong> for EAGLE/EAGLE3 and STANDALONE. For some MTP-enabled models, this can be omitted.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-steps</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Depth of autoregressive drafting. Increases speculation range but risks rejection cascades.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Auto (<code>5</code> for Llama/Grok; <code>3</code> for many other models)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-eagle-topk</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Branching factor per step. Improves candidate diversity and acceptance rate, but increases memory/compute consumption.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Auto (<code>4</code> for Llama/Grok; <code>1</code> for many other models)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-draft-tokens</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum parallel verification capacity. Allows deeper tree evaluation but increases GPU memory usage.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Auto (<code>8</code> for Llama/Grok; <code>4</code> for many other models). If <code>topk=1</code>, it is adjusted to <code>num_steps + 1</code>.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-accept-threshold-single</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Acceptance threshold for single-token verification. Lower values accept more aggressively.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>1.0</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-accept-threshold-acc</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Accumulated acceptance threshold across steps.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>1.0</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-attention-mode</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Attention mode for speculative operations (<code>prefill</code> or <code>decode</code>), affecting both target verification and draft extension.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>"prefill"</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-attention-backend</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Override attention backend for the draft model.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code> (same as target)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-dsa-topk-backend</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Select the DSA indexer top-k backend for speculative draft workers independently of <code>--dsa-topk-backend</code>. Options are <code>sgl-kernel</code>, <code>torch</code>, and <code>flashinfer</code>; <code>torch</code> requires <code>SGLANG_DSA_FUSE_TOPK=false</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>sgl-kernel</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-quantization</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Quantization method for the draft model. Use <code>"unquant"</code> to force no quantization even when the target model is quantized.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Same as target model</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-revision</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Specific revision/commit of the draft model to load.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code> (auto-set to <code>"main"</code> when <code>--speculative-draft-model-path</code> is set and revision is omitted)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-load-format</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load format for the draft model weights.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
    </tr>
  </tbody>
</table>

These parameters are mostly the same for EAGLE-2 and EAGLE-3. `--speculative-token-map` is ignored for EAGLE-3 models.
For `--speculative-num-steps`, `--speculative-eagle-topk`, and `--speculative-num-draft-tokens`: leave all three unset to use auto-tuning, or set all three explicitly when tuning.
If you use EAGLE with `--speculative-eagle-topk 1` and your acceptance rate varies across requests, see [Adaptive Speculative Decoding](./adaptive_speculative_decoding).

You can find the best combinations of these parameters with [bench_speculative.py](https://github.com/sgl-project/sglang/blob/main/scripts/playground/bench_speculative.py).


### EAGLE-2 Decoding

You can enable EAGLE-2 Decoding by setting `--speculative-algorithm EAGLE` and choosing an appropriate model.

**Launch the server:**

```bash Command
python3 -m sglang.launch_server \
    --model meta-llama/Llama-2-7b-chat-hf \
    --speculative-algorithm EAGLE \
    --speculative-draft-model-path lmsys/sglang-EAGLE-llama2-chat-7B \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 4 \
    --speculative-num-draft-tokens 16 \
    --mem-fraction-static 0.7 \
    --cuda-graph-max-bs-decode 8 \
    --log-level warning
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="meta-llama/Llama-2-7b-chat-hf",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print(response.choices[0].message.content)
```

---

### EAGLE-2 Decoding with `torch.compile`

You can optionally enable `torch.compile` to apply kernel-level optimizations (operator fusion, autotune) to the draft model. The actual speedup depends on your hardware, model architecture, and batch size. In some configurations (e.g., small draft models on H100 where cuBLAS is already optimal and CUDA graphs are enabled), the benefit may be negligible. We recommend benchmarking with and without this flag on your specific setup to verify whether it helps.

To enable it, add `--enable-torch-compile` and optionally set `--torch-compile-max-bs`:

```bash Command
python3 -m sglang.launch_server \
    --model meta-llama/Llama-2-7b-chat-hf \
    --speculative-algorithm EAGLE \
    --speculative-draft-model-path lmsys/sglang-EAGLE-llama2-chat-7B \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 4 \
    --speculative-num-draft-tokens 16 \
    --mem-fraction-static 0.7 \
    --enable-torch-compile \
    --torch-compile-max-bs 8 \
    --log-level warning
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="meta-llama/Llama-2-7b-chat-hf",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print(response.choices[0].message.content)
```

---

### EAGLE-2 Decoding via Frequency-Ranked Speculative Sampling

By employing a truncated high-frequency token vocabulary in the draft model, EAGLE speculative decoding reduces `lm_head` computational overhead while accelerating the pipeline without quality degradation. For more details, check out [the paper](https://arxiv.org/pdf/2502.14856).

In our implementation, set `--speculative-token-map` to enable the optimization. You can get the high-frequency tokens in FR-Spec from [this model](https://huggingface.co/thunlp/LLaMA3-Instruct-8B-FR-Spec). Or you can obtain high-frequency tokens by directly downloading these tokens from [this repo](https://github.com/thunlp/FR-Spec/tree/main?tab=readme-ov-file#prepare-fr-spec-vocabulary-subset).

Thanks for the contribution from [Weilin Zhao](https://github.com/Achazwl) and [Zhousx](https://github.com/Zhou-sx).

```bash Command
python3 -m sglang.launch_server \
    --model meta-llama/Meta-Llama-3-8B-Instruct \
    --speculative-algorithm EAGLE \
    --speculative-draft-model-path lmsys/sglang-EAGLE-LLaMA3-Instruct-8B \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 4 \
    --speculative-num-draft-tokens 16 \
    --speculative-token-map thunlp/LLaMA3-Instruct-8B-FR-Spec/freq_32768.pt \
    --mem-fraction-static 0.7 \
    --cuda-graph-max-bs-decode 8 \
    --dtype float16 \
    --log-level warning
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3-8B-Instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print(response.choices[0].message.content)
```

---

### EAGLE-3 Decoding

You can enable EAGLE-3 decoding by setting `--speculative-algorithm EAGLE3` and choosing an appropriate model.

```bash Command
python3 -m sglang.launch_server \
    --model meta-llama/Meta-Llama-3.1-8B-Instruct \
    --speculative-algorithm EAGLE3 \
    --speculative-draft-model-path jamesliu1/sglang-EAGLE3-Llama-3.1-Instruct-8B \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 4 \
    --speculative-num-draft-tokens 16 \
    --mem-fraction-static 0.7 \
    --cuda-graph-max-bs-decode 8 \
    --dtype float16 \
    --log-level warning
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3.1-8B-Instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print(response.choices[0].message.content)
```

---

## Block verification

For stochastic EAGLE, EAGLE3, or NEXTN decoding on NVIDIA CUDA or AMD ROCm, add
`--speculative-use-block-verification`
with `--speculative-eagle-topk 1`. The draft model must produce a full target-vocabulary
proposal distribution, as required by the existing rejection sampler.

The same flag applies to the DFlash family (`DFLASH` and `DSPARK`) on CUDA or ROCm
when the draft samples its proposals: DSpark drafts, DFlash checkpoints with a
candidate selector, and [LiLiCorr](#lilicorr-reranked-dflash-drafts) drafts with
`SGLANG_ENABLE_LILICORR_SAMPLING=1`. These paths already publish their proposal
distribution, so `--speculative-use-rejection-sampling` is not needed. A DFlash draft
that proposes greedy tokens is a point mass, where block and token-wise verification
accept the same prefixes; the server warns that the flag has no effect.

[Block verification](https://arxiv.org/abs/2403.10444) checks every draft prefix and
keeps the longest accepted prefix, including when an earlier prefix was rejected.
It uses a corresponding correction distribution to preserve target sampling.
Use `--speculative-use-rejection-sampling` alone for token-wise verification, which
stops at the first rejected token.
Greedy requests keep their existing verification behavior.

Block verification adds vocabulary reductions during verification. Benchmark your
model and workload to measure the effect on latency and throughput.

## Multi Token Prediction

We support [MTP (Multi-Token Prediction)](https://arxiv.org/pdf/2404.19737) in SGLang by using speculative decoding. We use `XiaomiMiMo/MiMo-7B-RL` as an example here (for DeepSeek MTP usage, refer to [DeepSeek-V3.2 cookbook §4.2.3](/cookbook/autoregressive/DeepSeek/DeepSeek-V3_2#4-2-3-multi-token-prediction-eagle-speculative-decoding)).

```bash Command
python3 -m sglang.launch_server \
    --model XiaomiMiMo/MiMo-7B-RL \
    --host 0.0.0.0 \
    --trust-remote-code \
    --speculative-algorithm EAGLE \
    --speculative-num-steps 1 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 2 \
    --mem-fraction-static 0.7 \
    --cuda-graph-max-bs-decode 8 \
    --log-level warning
```

For DSA-based MTP, draft workers default to the `sgl-kernel` top-k backend. Use `--speculative-dsa-topk-backend` to override the draft independently of `--dsa-topk-backend` for the target model.

**Send a request:**

```python Example
import requests

url = "http://localhost:30000/v1/chat/completions"

data = {
    "model": "XiaomiMiMo/MiMo-7B-RL",
    "messages": [{"role": "user", "content": "What is the capital of France?"}],
}

response = requests.post(url, json=data)
print(response.json())
```

---

## UNO decoding

UNO reuses the target transformer for both passes of each speculative decode cycle instead of loading a separate draft model. During the draft forward, the first row of each request uses the base weights and the remaining `B - 1` rows use a trained UNO LoRA. Target verification is entirely base-only.

UNO provides two sampling modes:

- **Linear** constructs and verifies one chain of draft tokens, similar to DFlash's proposal layout.
- **Tree** expands multiple candidates at each draft depth and uses SGLang's EAGLE tree-verification path.

For UNO modes, the three numbers are `B/K/V`: draft-forward width, candidates kept per expansion, and verification width. Thus, `Linear 8/1/8` uses an 8-token draft width, one candidate per expansion, and an 8-token verification width. UNO's `K` controls proposal-tree breadth and is unrelated to the request sampling parameter `top_k`. The command-line mapping depends on the mode:

- In linear mode, `B` and `V` are both `--speculative-num-draft-tokens`; set `--speculative-num-steps 1` and `--speculative-eagle-topk 1`.
- In tree mode, `B` is `--speculative-num-steps + 1`, `K` is `--speculative-eagle-topk`, and `V` is `--speculative-num-draft-tokens`.

Use an adapter trained for the exact target-model checkpoint. The current integration has been validated with `Qwen/Qwen3-8B`; unsupported LoRA target layers are rejected at startup. Set the adapter's local path or Hugging Face repository before starting the server:

### Linear 8/1/8

```bash Command
export UNO_LORA_PATH="s-sahoo/uno-qwen3-8B"

sglang serve \
    --model-path Qwen/Qwen3-8B \
    --speculative-algorithm UNO \
    --uno-lora-path "$UNO_LORA_PATH" \
    --speculative-num-steps 1 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 8 \
    --attention-backend fa3 \
    --tp 1 \
    --host 0.0.0.0 \
    --port 30000
```

### Tree 8/32/8

The following command selects tree mode because `K` is greater than one:

```bash Command
export UNO_LORA_PATH="s-sahoo/uno-qwen3-8B"

sglang serve \
    --model-path Qwen/Qwen3-8B \
    --speculative-algorithm UNO \
    --uno-lora-path "$UNO_LORA_PATH" \
    --speculative-num-steps 7 \
    --speculative-eagle-topk 32 \
    --speculative-num-draft-tokens 8 \
    --attention-backend fa3 \
    --tp 1 \
    --host 0.0.0.0 \
    --port 30000
```

Send requests through the standard OpenAI-compatible API:

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="Qwen/Qwen3-8B",
    messages=[{"role": "user", "content": "Explain speculative decoding."}],
    max_tokens=128,
)

print(response.choices[0].message.content)
```

### Key requirements and limitations

- UNO requires CUDA with FA3 for prefill and decode, tensor and pipeline parallel sizes of 1, and no DP attention or context parallelism.
- `--uno-lora-path` loads UNO's fixed internal adapter and cannot be combined with request-selectable Multi-LoRA serving.
- UNO manages its own stochastic verification; do not set `--speculative-use-rejection-sampling`.
- Grammar decoding, returned logprobs or hidden states, sampling penalties, `min_p`, logit bias, custom logit processors, strict thinking, and deterministic inference are not yet supported.
- In tree mode, both speculative acceptance thresholds must remain at 1.0, `V` must be at least `B` and at most 128, and `V * K` must not exceed 2048. SGLang validates the remaining tree-capacity and EAGLE parent-representation constraints at startup.
- Mixed chunked prefill is disabled for UNO.
- Ordinary overlap scheduling is supported. Tree mode does not yet support PDMux or the separate `--enable-two-batch-overlap` feature.

---

## DFlash Decoding

SGLang also supports **DFLASH** speculative decoding using a dedicated draft model checkpoint. Compared with EAGLE-style tree verification, DFLASH verifies a linear draft block and is configured around a block size / draft window. This path is useful when the target model has a matching DFlash draft checkpoint, such as `meta-llama/Llama-3.1-8B-Instruct` with `z-lab/LLaMA3.1-8B-Instruct-DFlash-UltraChat`.

Relevant parameters:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "30%"}} />
    <col style={{width: "50%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-path</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Required DFlash draft model path/weights.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-draft-tokens</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DFlash verify block size.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Inferred from draft config, otherwise <code>16</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-dflash-block-size</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Alias of <code>--speculative-num-draft-tokens</code> for DFlash.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-window-size</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Draft KV sliding-window size. Must be <code>&gt;= speculative-num-draft-tokens</code> when set.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
    </tr>
  </tbody>
</table>

```bash Command
python3 -m sglang.launch_server \
    --model meta-llama/Llama-3.1-8B-Instruct \
    --speculative-algorithm DFLASH \
    --speculative-draft-model-path z-lab/LLaMA3.1-8B-Instruct-DFlash-UltraChat
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="meta-llama/Llama-3.1-8B-Instruct",
    messages=[
        {"role": "user", "content": "Write a quicksort implementation in Python."},
    ],
    temperature=0,
    max_tokens=128,
)

print(response.choices[0].message.content)
```

### LiLiCorr: reranked DFlash drafts

A DFlash drafter is trained on per-position marginals rather than on the joint block distribution, so its drafted tokens are individually plausible yet jointly incoherent. **LiLiCorr** ([arXiv:2608.20530](https://arxiv.org/abs/2608.20530)) keeps the top-`k` candidates per block position, scores the whole lattice jointly with a small two-layer transformer, and commits a path through it greedily instead of taking the per-slot argmax. Verify is unchanged, so outputs remain distributionally identical to the target model's and only acceptance length moves.

LiLiCorr is **not a separate `--speculative-algorithm`**: it is a property of the draft checkpoint, the same way the DFlash candidate selector is. Serve it with `--speculative-algorithm DFLASH` and a checkpoint whose config declares `architectures: ["LiLiCorrDraftModel"]` and carries the `lilicorr_*` geometry fields inside `dflash_config`. The head is then built, loaded and folded into the draft CUDA graph automatically.

No LiLiCorr drafter is published yet, so the draft path below is a placeholder.

```bash Command
python3 -m sglang.launch_server \
    --model Qwen/Qwen3-8B \
    --attention-backend fa3 \
    --speculative-algorithm DFLASH \
    --speculative-draft-model-path <your-lilicorr-draft-model>
```

**Use a backend that opts out of the host `seq_lens` mirror.** `AttentionBackend.needs_cpu_seq_lens` defaults to `True`; `fa3`, `triton`, `trtllm_mha`, `trtllm_mla`, `flashmla` and `dsa` set it `False`, while `FlashInferAttnBackend` inherits the default. Under a backend that does not opt out the worker publishes `seq_lens_cpu` every step, which is a device-to-host sync per block. The flag is OR-ed over the target and draft runners, so both have to opt out. This is a property of DFlash decoding rather than of LiLiCorr, but it dominates the throughput of a 16-slot block. Backends also differ in attention numerics, so acceptance measured on different backends does not belong in one table.

A checkpoint carrying head weights but declaring `architectures: ["DFlashDraftModel"]` loads as plain DFlash and ignores the head, which reads as a small acceptance loss rather than an error. The reverse, declaring `LiLiCorrDraftModel` without complete head weights, is refused at load.

#### Sampling the committed path

Above temperature 0 the target samples, but a deterministic draft is paid `p(argmax)` per slot because verify is handed a point mass. `SGLANG_ENABLE_LILICORR_SAMPLING=1` draws each slot from `softmax(scores / T)` over that slot's candidates at the request's own temperature and publishes the proposal it drew from, so rejection sampling is paid the overlap of the two distributions instead. Verify stays exact. Greedy requests sharing the batch take the argmax and report a one-hot proposal.

Off by default; with it unset the captured body is `select` itself, so temperature-0 output is unchanged bit for bit. On Qwen3-8B it is worth about 6% acceptance and 6% end-to-end at temperature 1, at under 1% of the per-block wall.

**Only enable it on the folded path.** The eager fallback that serves the steps the draft CUDA graph cannot is correct but costs a large fraction of throughput, and because acceptance is identical either way that regression shows up only in tokens/s. `build_lilicorr_draft_sampler` warns with a reason when it declines to fold, and the worker warns once if a decode step lands on the eager head.

#### Drafters with grouped convolutions

LiLiCorr composes with the grouped dynamic convolutions that wrap each DFlash sublayer, and serving one needs no extra flag: the convolution belongs to the DFlash backbone, so `LiLiCorrDraftModel` inherits the builder and picks it up from `conv_kernel_size` and `conv_group_size` in `dflash_config`.

Both keys default to `0`, so a checkpoint whose config lost them builds no convolution modules and the backbone loader then drops every convolution tensor it cannot resolve. That is correct for rotary caches and the worst case here, because the draft would serve as its convolution-free parent at a lower but entirely believable acceptance length. The loader therefore refuses any checkpoint whose convolution tensors and built modules disagree, in either direction.

---

## Standalone Speculative Decoding (Small Draft Model)

Besides EAGLE/MTP, SGLang also supports **token-level speculative decoding** using a smaller **draft model**. Enable it with `--speculative-algorithm STANDALONE` and provide a draft model via `--speculative-draft-model-path`.

Relevant parameters:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "30%"}} />
    <col style={{width: "50%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-path</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Draft model weights (smaller than the target model).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-steps</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Draft depth (how many steps the draft model runs autoregressively).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>3</code> (auto default for STANDALONE)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-eagle-topk</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Branching factor (token candidates per step).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>1</code> (auto default for STANDALONE)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-draft-tokens</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Verification capacity.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>4</code> (auto default for STANDALONE)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-quantization</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Quantization for the draft model. Use <code>"unquant"</code> to disable quantization on the draft even when the target is quantized.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Same as target</td>
    </tr>
  </tbody>
</table>

> **Note:** Standalone speculative decoding currently **does not support** DP attention (`--attn-dp-size` > 1).

```bash Command
python3 -m sglang.launch_server \
    --model Qwen/Qwen2.5-7B-Instruct \
    --speculative-algorithm STANDALONE \
    --speculative-draft-model-path Qwen/Qwen2.5-1.5B-Instruct \
    --speculative-num-steps 4 \
    --speculative-eagle-topk 2 \
    --speculative-num-draft-tokens 7 \
    --mem-fraction-static 0.7 \
    --cuda-graph-max-bs-decode 8 \
    --log-level warning
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="Qwen/Qwen2.5-7B-Instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print(response.choices[0].message.content)
```

---

## Speculative Decoding V2 (Overlap Scheduler)

Speculative decoding runs the V2 speculative workers (e.g. `StandaloneWorkerV2`, `EAGLEWorkerV2`) with the overlap scheduler enabled by default. Pass `--disable-overlap-schedule` to fall back to the synchronous (non-overlap) path.

Notes:
- The overlap scheduler currently only supports `--speculative-eagle-topk 1`; **set `--speculative-eagle-topk 1` explicitly**.
- If you explicitly set `--speculative-eagle-topk > 1`, the server will error.
- If you omit `--speculative-eagle-topk`, auto-tuning may pick `topk > 1` for some models (e.g. Llama). This is incompatible with the overlap scheduler and may not always trigger an immediate config error, so set `--speculative-eagle-topk 1` explicitly.

```bash Command
python3 -m sglang.launch_server \
    --model Qwen/Qwen2.5-7B-Instruct \
    --speculative-algorithm STANDALONE \
    --speculative-draft-model-path Qwen/Qwen2.5-1.5B-Instruct \
    --speculative-num-steps 4 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 5 \
    --mem-fraction-static 0.7 \
    --cuda-graph-max-bs-decode 8 \
    --log-level warning
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="Qwen/Qwen2.5-7B-Instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print(response.choices[0].message.content)
```

---

## Ngram Speculative Decoding

SGLang also supports **ngram-based speculative decoding** (no separate draft model). It retrieves draft tokens from an ngram cache built from previously generated tokens, and then verifies them with the target model.

Enable it with:
- `--speculative-algorithm NGRAM`

### Ngram-specific parameters

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "30%"}} />
    <col style={{width: "50%"}} />
    <col style={{width: "20%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-draft-tokens</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Number of draft tokens verified per step. If omitted, defaults to <code>min(--speculative-ngram-max-trie-depth, 12)</code>.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>12</code> (with default ngram settings)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-min-bfs-breadth</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Minimum BFS breadth.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>1</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-max-bfs-breadth</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum BFS breadth.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>10</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-match-type</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Ngram tree-building mode: <code>"BFS"</code> for recency-based expansion or <code>"PROB"</code> for frequency-based expansion.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>"BFS"</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-max-trie-depth</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum suffix length stored and matched by the ngram trie.</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>18</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-capacity</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Cache capacity (number of entries).</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>10,000,000</code></td>
    </tr>
  </tbody>
</table>

Notes:
- Ngram speculative decoding **only supports CUDA**.
- It currently **does not support** DP attention (`--attn-dp-size` > 1).
- It disables the overlap scheduler and mixed chunked prefill.
- If `--speculative-ngram-max-bfs-breadth > 1` (thus `speculative_eagle_topk > 1`) and `page_size > 1`, use `--attention-backend flashinfer`; otherwise the server will error.
- Optional: set `SGLANG_NGRAM_FORCE_GREEDY_VERIFY=True` to force greedy verification.

```bash Command
python3 -m sglang.launch_server \
    --model Qwen/Qwen2.5-7B-Instruct \
    --speculative-algorithm NGRAM \
    --speculative-num-draft-tokens 16 \
    --speculative-ngram-max-bfs-breadth 10 \
    --mem-fraction-static 0.7 \
    --cuda-graph-max-bs-decode 8 \
    --log-level warning
```

**Send a request:**

```python Example
import openai

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="Qwen/Qwen2.5-7B-Instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print(response.choices[0].message.content)
```

---

## Full Parameter Reference

Below is a comprehensive list of all speculative decoding parameters available in SGLang:

### Core parameters

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "24%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "44%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-algorithm</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Algorithm to use: <code>UNO</code>, <code>DFLASH</code>, <code>EAGLE</code>, <code>EAGLE3</code>, <code>STANDALONE</code>, <code>NGRAM</code>, <code>NEXTN</code> (alias of <code>EAGLE</code>)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-path</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to the draft model weights</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--uno-lora-path</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>UNO-only path or Hugging Face repository for the draft LoRA checkpoint</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-revision</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Specific revision/commit of the draft model (<code>"main"</code> is auto-used when draft path is set and revision is omitted)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-load-format</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Load format for draft model weights</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-steps</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code> (auto-chosen when omitted)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Autoregressive drafting depth. Some algorithms auto-tune it; tree UNO requires it and uses <code>B = speculative_num_steps + 1</code>.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-eagle-topk</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code> (auto-chosen when omitted)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Branching factor per drafting step. Some algorithms auto-tune it; UNO resolves an omitted value to <code>1</code>, and values greater than one select UNO tree mode.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-num-draft-tokens</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code> (auto-chosen when omitted)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum number of draft tokens for verification. Some algorithms auto-tune it; UNO requires it and uses it as linear width or tree verification width <code>V</code>.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-dflash-block-size</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DFlash-only alias of <code>--speculative-num-draft-tokens</code></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-window-size</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DFlash-only draft KV sliding-window size</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-accept-threshold-single</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>float</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>1.0</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Single-token acceptance threshold</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-accept-threshold-acc</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>float</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>1.0</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Accumulated acceptance threshold</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-token-map</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Path to FR-Spec high-frequency token map</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-attention-mode</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>"prefill"</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Attention mode for speculative operations (<code>"prefill"</code> or <code>"decode"</code>)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-attention-backend</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Override attention backend for the draft model</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-dsa-topk-backend</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>sgl-kernel</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DSA indexer top-k backend for speculative draft workers, independent of <code>--dsa-topk-backend</code> (<code>sgl-kernel</code>, <code>torch</code>, or <code>flashinfer</code>)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-moe-runner-backend</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>MoE runner backend for the draft model</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-moe-a2a-backend</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>None</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>MoE all-to-all backend for the draft model</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-draft-model-quantization</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Same as target</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Quantization for the draft model (<code>"unquant"</code> to disable)</td>
    </tr>
  </tbody>
</table>

### Ngram-specific parameters

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "24%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "16%"}} />
    <col style={{width: "44%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-min-bfs-breadth</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>1</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Minimum BFS breadth</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-max-bfs-breadth</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>10</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum BFS breadth</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-match-type</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>str</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>"BFS"</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Ngram tree-building mode: <code>"BFS"</code> for recency-based expansion or <code>"PROB"</code> for frequency-based expansion</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-max-trie-depth</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>18</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum suffix length stored and matched by the ngram trie</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--speculative-ngram-capacity</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>int</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}><code>10,000,000</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Cache capacity</td>
    </tr>
  </tbody>
</table>

### Environment variables

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
    <col style={{width: "33.33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Variable</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>SGLANG_NGRAM_FORCE_GREEDY_VERIFY</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}><code>False</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Force greedy verification for ngram decoding</td>
    </tr>
  </tbody>
</table>

### Other related flags

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "35%"}} />
    <col style={{width: "65%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--enable-multi-layer-eagle</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable multi-layer EAGLE (auto-enabled for MiMoV2 and Step3p5 models)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--enable-torch-compile</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Enable <code>torch.compile</code> for kernel-level optimizations</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}><code>--torch-compile-max-bs</code></td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Maximum batch size for <code>torch.compile</code></td>
    </tr>
  </tbody>
</table>

---

## OOM Troubleshooting

> [!WARNING]
> **Out of Memory (OOM)?** Speculative decoding may increase GPU memory usage because the draft tree, CUDA graphs, and verification-related buffers consume additional VRAM. If you encounter OOM errors, try the following adjustments.

### Step 1: Lower static memory fraction (most effective)

```bash Command
--mem-fraction-static 0.5   # when omitted, this value is auto-computed
```

- `--mem-fraction-static` controls the memory budget for model weights + KV cache pool.
- Lowering it directly increases dynamic headroom for activations and CUDA graph buffers.
- If omitted, SGLang auto-estimates this value from other settings, and those auto settings can still be too aggressive for some workloads.

### Step 2: Reduce CUDA graph batch size

```bash Command
# Fewer CUDA graph captures = less memory reserved
--cuda-graph-max-bs-decode 4   # or even 2 for tight memory situations
```

- If omitted, `--cuda-graph-max-bs-decode` is auto-selected based on GPU memory and TP size, and can be much larger on high-memory GPUs.

### Step 3: Reduce draft tree size

These three parameters directly control how much memory the draft tree consumes:

```bash Command
# Before (aggressive, high memory)
--speculative-num-steps 5 --speculative-eagle-topk 8 --speculative-num-draft-tokens 64

# After (conservative, lower memory)
--speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4
```

### Step 4: Limit concurrent requests

```bash Command
# Fewer concurrent requests lowers in-flight load and can reduce OOM risk
--max-running-requests 4
```

### Quick OOM recovery recipe

If you're hitting OOM and just want something that works, start with this minimal configuration and scale up:

```bash Command
python3 -m sglang.launch_server \
    --model <your-model> \
    --speculative-algorithm EAGLE \
    --speculative-draft-model-path <your-draft-model> \
    --speculative-num-steps 3 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 4 \
    --cuda-graph-max-bs-decode 2 \
    --mem-fraction-static 0.5 \
    --max-running-requests 4 \
    --log-level warning
```

Then gradually increase `--speculative-num-draft-tokens`, `--speculative-eagle-topk`, and `--cuda-graph-max-bs-decode`. Increase `--mem-fraction-static` last, only after the run is stable.

---

## References

EAGLE process is as follows:

- Within EAGLE the draft model predicts the next feature vector, i.e. the last hidden state of the original LLM, using the feature sequence $(f_1, ..., f_k)$ and the token sequence $(t_2, ..., t_&#123;k+1&#125;)$.
- The next token is then sampled from $p_&#123;k+2&#125;=\text&#123;LMHead&#125;(f_&#123;k+1&#125;)$. Afterwards, the two sequences are extended in a tree style—branching out multiple potential continuations, with the branching factor per step controlled by the `speculative_eagle_topk` parameter—to ensure a more coherent connection of context, and are given as input again.
- In SGLang's EAGLE-2 implementation, the draft tree is expanded for the configured steps and then reranked to select the top `speculative_num_draft_tokens` final nodes as draft tokens.
- EAGLE-3 removes the feature prediction objective, incorporates low and mid-layer features, and is trained in an on-policy manner.

This enhances drafting accuracy by operating on features instead of tokens for more regular inputs and by additionally passing tokens from the next timestep to reduce sampling randomness. For more details, see the [EAGLE-2](https://arxiv.org/abs/2406.16858) and [EAGLE-3](https://arxiv.org/abs/2503.01840) papers.

For guidance on how to train your own EAGLE model please see the [EAGLE repo](https://github.com/SafeAILab/EAGLE/tree/main?tab=readme-ov-file#train). For EAGLE-3 training specifically, check out [SpecForge](https://github.com/sgl-project/SpecForge), the SGLang team's training framework designed for EAGLE-3 speculative decoding models with seamless porting to SGLang serving. See the [SpecForge documentation](https://docs.sglang.ai/SpecForge/) and [blog post](https://lmsys.org/blog/2025-07-25-spec-forge) for details.

---

### Docs Advanced Features Structured Outputs (`docs/docs/advanced_features/structured_outputs.mdx`)

---
title: "Structured Outputs"
metatags:
    description: "SGLang structured outputs: JSON schema, regex, EBNF constraints. XGrammar, Outlines, Llguidance backends for guaranteed output format."
---
You can specify a JSON schema, [regular expression](https://en.wikipedia.org/wiki/Regular_expression) or [EBNF](https://en.wikipedia.org/wiki/Extended_Backus%E2%80%93Naur_form) to constrain the model output. The model output will be guaranteed to follow the given constraints. Only one constraint parameter (`json_schema`, `regex`, or `ebnf`) can be specified for a request.

SGLang supports three grammar backends:

- [XGrammar](https://github.com/mlc-ai/xgrammar)(default): Supports JSON schema, regular expression, and EBNF constraints.
- [Outlines](https://github.com/dottxt-ai/outlines): Supports JSON schema and regular expression constraints.
- [Llguidance](https://github.com/guidance-ai/llguidance): Supports JSON schema, regular expression, and EBNF constraints.

We suggest using XGrammar for its better performance and utility. XGrammar currently uses the [GGML BNF format](https://github.com/ggml-org/llama.cpp/blob/master/grammars/README.md). For more details, see [XGrammar technical overview](https://blog.mlc.ai/2024/11/22/achieving-efficient-flexible-portable-structured-generation-with-xgrammar).

To use Outlines, simply add `--grammar-backend outlines` when launching the server.
To use llguidance, add `--grammar-backend llguidance`  when launching the server.
If no backend is specified, XGrammar will be used as the default.

For better output quality, **It's advisable to explicitly include instructions in the prompt to guide the model to generate the desired format.** For example, you can specify, 'Please generate the output in the following JSON format: ...'.


## OpenAI Compatible API


```python Example
import openai
import os

from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process

os.environ["TOKENIZERS_PARALLELISM"] = "false"


server_process, port = launch_server_cmd(
    "python -m sglang.launch_server --model-path meta-llama/Meta-Llama-3.1-8B-Instruct --host 0.0.0.0 --log-level warning"
)

wait_for_server(f"http://localhost:{port}")
client = openai.Client(base_url=f"http://127.0.0.1:{port}/v1", api_key="None")
```

### JSON

you can directly define a JSON schema or use [Pydantic](https://docs.pydantic.dev/latest/) to define and validate the response.


**Using Pydantic**


```python Example
from pydantic import BaseModel, Field


# Define the schema using Pydantic
class CapitalInfo(BaseModel):
    name: str = Field(..., pattern=r"^\w+$", description="Name of the capital city")
    population: int = Field(..., description="Population of the capital city")


response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3.1-8B-Instruct",
    messages=[
        {
            "role": "user",
            "content": "Please generate the information of the capital of France in the JSON format.",
        },
    ],
    temperature=0,
    max_tokens=128,
    response_format={
        "type": "json_schema",
        "json_schema": {
            "name": "foo",
            # convert the pydantic model to json schema
            "schema": CapitalInfo.model_json_schema(),
        },
    },
)

response_content = response.choices[0].message.content
# validate the JSON response by the pydantic model
capital_info = CapitalInfo.model_validate_json(response_content)
print_highlight(f"Validated response: {capital_info.model_dump_json()}")
```

**JSON Schema Directly**


```python Example
import json

json_schema = json.dumps(
    {
        "type": "object",
        "properties": {
            "name": {"type": "string", "pattern": "^[\\w]+$"},
            "population": {"type": "integer"},
        },
        "required": ["name", "population"],
    }
)

response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3.1-8B-Instruct",
    messages=[
        {
            "role": "user",
            "content": "Give me the information of the capital of France in the JSON format.",
        },
    ],
    temperature=0,
    max_tokens=128,
    response_format={
        "type": "json_schema",
        "json_schema": {"name": "foo", "schema": json.loads(json_schema)},
    },
)

print_highlight(response.choices[0].message.content)
```

### EBNF


```python Example
ebnf_grammar = """
root ::= city | description
city ::= "London" | "Paris" | "Berlin" | "Rome"
description ::= city " is " status
status ::= "the capital of " country
country ::= "England" | "France" | "Germany" | "Italy"
"""

response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3.1-8B-Instruct",
    messages=[
        {"role": "system", "content": "You are a helpful geography bot."},
        {
            "role": "user",
            "content": "Give me the information of the capital of France.",
        },
    ],
    temperature=0,
    max_tokens=32,
    extra_body={"ebnf": ebnf_grammar},
)

print_highlight(response.choices[0].message.content)
```

### Regular expression


```python Example
response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3.1-8B-Instruct",
    messages=[
        {"role": "user", "content": "What is the capital of France?"},
    ],
    temperature=0,
    max_tokens=128,
    extra_body={"regex": "(Paris|London)"},
)

print_highlight(response.choices[0].message.content)
```

### Structural Tag


```
/* Detailed source-code truncated for AI context efficiency. */
```


```python Example
# Support for XGrammar latest structural tag format
# https://xgrammar.mlc.ai/docs/api/python/structural_tag.html

response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3.1-8B-Instruct",
    messages=messages,
    response_format={
        "type": "structural_tag",
        "format": {
            "type": "triggered_tags",
            "triggers": ["<function="],
            "tags": [
                {
                    "begin": "<function=get_current_weather>",
                    "content": {
                        "type": "json_schema",
                        "json_schema": schema_get_current_weather,
                    },
                    "end": "</function>",
                },
                {
                    "begin": "<function=get_current_date>",
                    "content": {
                        "type": "json_schema",
                        "json_schema": schema_get_current_date,
                    },
                    "end": "</function>",
                },
            ],
            "at_least_one": False,
            "stop_after_first": False,
        },
    },
)

print_highlight(response.choices[0].message.content)
```

## Native API and SGLang Runtime (SRT)


### JSON


**Using Pydantic**


```python Example
import requests
import json
from pydantic import BaseModel, Field

from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("meta-llama/Meta-Llama-3.1-8B-Instruct")


# Define the schema using Pydantic
class CapitalInfo(BaseModel):
    name: str = Field(..., pattern=r"^\w+$", description="Name of the capital city")
    population: int = Field(..., description="Population of the capital city")


# Make API request
messages = [
    {
        "role": "user",
        "content": "Here is the information of the capital of France in the JSON format.\n",
    }
]
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": text,
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 64,
            "json_schema": json.dumps(CapitalInfo.model_json_schema()),
        },
    },
)
print_highlight(response.json())


response_data = json.loads(response.json()["text"])
# validate the response by the pydantic model
capital_info = CapitalInfo.model_validate(response_data)
print_highlight(f"Validated response: {capital_info.model_dump_json()}")
```

**JSON Schema Directly**


```python Example
json_schema = json.dumps(
    {
        "type": "object",
        "properties": {
            "name": {"type": "string", "pattern": "^[\\w]+$"},
            "population": {"type": "integer"},
        },
        "required": ["name", "population"],
    }
)

# JSON
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": text,
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 64,
            "json_schema": json_schema,
        },
    },
)

print_highlight(response.json())
```

### EBNF


```python Example
messages = [
    {
        "role": "user",
        "content": "Give me the information of the capital of France.",
    }
]
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": text,
        "sampling_params": {
            "max_new_tokens": 128,
            "temperature": 0,
            "n": 3,
            "ebnf": (
                "root ::= city | description\n"
                'city ::= "London" | "Paris" | "Berlin" | "Rome"\n'
                'description ::= city " is " status\n'
                'status ::= "the capital of " country\n'
                'country ::= "England" | "France" | "Germany" | "Italy"'
            ),
        },
        "stream": False,
        "return_logprob": False,
    },
)

print_highlight(response.json())
```

### Regular expression


```python Example
messages = [
    {
        "role": "user",
        "content": "Paris is the capital of",
    }
]
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": text,
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 64,
            "regex": "(France|England)",
        },
    },
)
print_highlight(response.json())
```

### Structural Tag


```python Example
from transformers import AutoTokenizer

# generate an answer
tokenizer = AutoTokenizer.from_pretrained("meta-llama/Meta-Llama-3.1-8B-Instruct")

text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
payload = {
    "text": text,
    "sampling_params": {
        "structural_tag": json.dumps(
            {
                "type": "structural_tag",
                "structures": [
                    {
                        "begin": "<function=get_current_weather>",
                        "schema": schema_get_current_weather,
                        "end": "</function>",
                    },
                    {
                        "begin": "<function=get_current_date>",
                        "schema": schema_get_current_date,
                        "end": "</function>",
                    },
                ],
                "triggers": ["<function="],
            }
        )
    },
}


# Send POST request to the API endpoint
response = requests.post(f"http://localhost:{port}/generate", json=payload)
print_highlight(response.json())
```


```python Example
# Support for XGrammar latest structural tag format
# https://xgrammar.mlc.ai/docs/api/python/structural_tag.html

payload = {
    "text": text,
    "sampling_params": {
        "structural_tag": json.dumps(
            {
                "type": "structural_tag",
                "format": {
                    "type": "triggered_tags",
                    "triggers": ["<function="],
                    "tags": [
                        {
                            "begin": "<function=get_current_weather>",
                            "content": {
                                "type": "json_schema",
                                "json_schema": schema_get_current_weather,
                            },
                            "end": "</function>",
                        },
                        {
                            "begin": "<function=get_current_date>",
                            "content": {
                                "type": "json_schema",
                                "json_schema": schema_get_current_date,
                            },
                            "end": "</function>",
                        },
                    ],
                    "at_least_one": False,
                    "stop_after_first": False,
                },
            }
        )
    },
}


# Send POST request to the API endpoint
response = requests.post(f"http://localhost:{port}/generate", json=payload)
print_highlight(response.json())
```


```python Example
terminate_process(server_process)
```

## Offline Engine API


```python Example
import sglang as sgl

llm = sgl.Engine(
    model_path="meta-llama/Meta-Llama-3.1-8B-Instruct", grammar_backend="xgrammar"
)
```

### JSON


**Using Pydantic**


```python Example
import json
from pydantic import BaseModel, Field


prompts = [
    "Give me the information of the capital of China in the JSON format.",
    "Give me the information of the capital of France in the JSON format.",
    "Give me the information of the capital of Ireland in the JSON format.",
]


# Define the schema using Pydantic
class CapitalInfo(BaseModel):
    name: str = Field(..., pattern=r"^\w+$", description="Name of the capital city")
    population: int = Field(..., description="Population of the capital city")


sampling_params = {
    "temperature": 0.1,
    "top_p": 0.95,
    "json_schema": json.dumps(CapitalInfo.model_json_schema()),
}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print_highlight("===============================")
    print_highlight(f"Prompt: {prompt}")  # validate the output by the pydantic model
    capital_info = CapitalInfo.model_validate_json(output["text"])
    print_highlight(f"Validated output: {capital_info.model_dump_json()}")
```

**JSON Schema Directly**


```python Example
prompts = [
    "Give me the information of the capital of China in the JSON format.",
    "Give me the information of the capital of France in the JSON format.",
    "Give me the information of the capital of Ireland in the JSON format.",
]

json_schema = json.dumps(
    {
        "type": "object",
        "properties": {
            "name": {"type": "string", "pattern": "^[\\w]+$"},
            "population": {"type": "integer"},
        },
        "required": ["name", "population"],
    }
)

sampling_params = {"temperature": 0.1, "top_p": 0.95, "json_schema": json_schema}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print_highlight("===============================")
    print_highlight(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```

### EBNF


```python Example
prompts = [
    "Give me the information of the capital of France.",
    "Give me the information of the capital of Germany.",
    "Give me the information of the capital of Italy.",
]

sampling_params = {
    "temperature": 0.8,
    "top_p": 0.95,
    "ebnf": (
        "root ::= city | description\n"
        'city ::= "London" | "Paris" | "Berlin" | "Rome"\n'
        'description ::= city " is " status\n'
        'status ::= "the capital of " country\n'
        'country ::= "England" | "France" | "Germany" | "Italy"'
    ),
}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print_highlight("===============================")
    print_highlight(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```

### Regular expression


```python Example
prompts = [
    "Please provide information about London as a major global city:",
    "Please provide information about Paris as a major global city:",
]

sampling_params = {"temperature": 0.8, "top_p": 0.95, "regex": "(France|England)"}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print_highlight("===============================")
    print_highlight(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```

### Structural Tag


```python Example
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
prompts = [text]


sampling_params = {
    "temperature": 0.8,
    "top_p": 0.95,
    "structural_tag": json.dumps(
        {
            "type": "structural_tag",
            "structures": [
                {
                    "begin": "<function=get_current_weather>",
                    "schema": schema_get_current_weather,
                    "end": "</function>",
                },
                {
                    "begin": "<function=get_current_date>",
                    "schema": schema_get_current_date,
                    "end": "</function>",
                },
            ],
            "triggers": ["<function="],
        }
    ),
}


# Send POST request to the API endpoint
outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print_highlight("===============================")
    print_highlight(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```


```python Example
# Support for XGrammar latest structural tag format
# https://xgrammar.mlc.ai/docs/api/python/structural_tag.html

sampling_params = {
    "temperature": 0.8,
    "top_p": 0.95,
    "structural_tag": json.dumps(
        {
            "type": "structural_tag",
            "format": {
                "type": "triggered_tags",
                "triggers": ["<function="],
                "tags": [
                    {
                        "begin": "<function=get_current_weather>",
                        "content": {
                            "type": "json_schema",
                            "json_schema": schema_get_current_weather,
                        },
                        "end": "</function>",
                    },
                    {
                        "begin": "<function=get_current_date>",
                        "content": {
                            "type": "json_schema",
                            "json_schema": schema_get_current_date,
                        },
                        "end": "</function>",
                    },
                ],
                "at_least_one": False,
                "stop_after_first": False,
            },
        }
    ),
}


# Send POST request to the API endpoint
outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print_highlight("===============================")
    print_highlight(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```


```python Example
llm.shutdown()
```

---

### Docs Advanced Features Structured Outputs For Reasoning Models (`docs/docs/advanced_features/structured_outputs_for_reasoning_models.mdx`)

---
title: "Structured Outputs For Reasoning Models"
metatags:
    description: "SGLang structured outputs for reasoning models: free-form thinking with constrained final output for DeepSeek R1, QwQ models."
---
When working with reasoning models that use special tokens like `<think>...</think>` to denote reasoning sections, you might want to allow free-form text within these sections while still enforcing grammar constraints on the rest of the output.

SGLang provides a feature to disable grammar restrictions within reasoning sections. This is particularly useful for models that need to perform complex reasoning steps before providing a structured output.

To enable this feature, use the `--reasoning-parser` flag which decide the think_end_token, such as `</think>`, when launching the server. You can also specify the reasoning parser using the `--reasoning-parser` flag.

## Supported Models

Currently, SGLang supports the following reasoning models:
- [DeepSeek R1 series](https://huggingface.co/collections/deepseek-ai/deepseek-r1-678e1e131c0169c0bc89728d): The reasoning content is wrapped with `<think>` and `</think>` tags.
- [QwQ](https://huggingface.co/Qwen/QwQ-32B): The reasoning content is wrapped with `<think>` and `</think>` tags.


## Usage

## OpenAI Compatible API


Specify the `--grammar-backend`, `--reasoning-parser` option.


```python Example
import openai
import os

from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process

os.environ["TOKENIZERS_PARALLELISM"] = "false"


server_process, port = launch_server_cmd(
    "python -m sglang.launch_server --model-path deepseek-ai/DeepSeek-R1-Distill-Qwen-7B --host 0.0.0.0 --reasoning-parser deepseek-r1 --log-level warning"
)

wait_for_server(f"http://localhost:{port}")
client = openai.Client(base_url=f"http://127.0.0.1:{port}/v1", api_key="None")
```

### JSON

you can directly define a JSON schema or use [Pydantic](https://docs.pydantic.dev/latest/) to define and validate the response.


**Using Pydantic**


```python Example
from pydantic import BaseModel, Field


# Define the schema using Pydantic
class CapitalInfo(BaseModel):
    name: str = Field(..., pattern=r"^\w+$", description="Name of the capital city")
    population: int = Field(..., description="Population of the capital city")


response = client.chat.completions.create(
    model="deepseek-ai/DeepSeek-R1-Distill-Qwen-7B",
    messages=[
        {
            "role": "assistant",
            "content": "Give me the information and population of the capital of France in the JSON format.",
        },
    ],
    temperature=0,
    max_tokens=2048,
    response_format={
        "type": "json_schema",
        "json_schema": {
            "name": "foo",
            # convert the pydantic model to json schema
            "schema": CapitalInfo.model_json_schema(),
        },
    },
)

print_highlight(
    f"reasoing_content: {response.choices[0].message.reasoning_content}\n\ncontent: {response.choices[0].message.content}"
)
```

**JSON Schema Directly**


```python Example
import json

json_schema = json.dumps(
    {
        "type": "object",
        "properties": {
            "name": {"type": "string", "pattern": "^[\\w]+$"},
            "population": {"type": "integer"},
        },
        "required": ["name", "population"],
    }
)

response = client.chat.completions.create(
    model="deepseek-ai/DeepSeek-R1-Distill-Qwen-7B",
    messages=[
        {
            "role": "assistant",
            "content": "Give me the information and population of the capital of France in the JSON format.",
        },
    ],
    temperature=0,
    max_tokens=2048,
    response_format={
        "type": "json_schema",
        "json_schema": {"name": "foo", "schema": json.loads(json_schema)},
    },
)

print_highlight(
    f"reasoing_content: {response.choices[0].message.reasoning_content}\n\ncontent: {response.choices[0].message.content}"
)
```

### EBNF


```python Example
ebnf_grammar = """
root ::= city | description
city ::= "London" | "Paris" | "Berlin" | "Rome"
description ::= city " is " status
status ::= "the capital of " country
country ::= "England" | "France" | "Germany" | "Italy"
"""

response = client.chat.completions.create(
    model="deepseek-ai/DeepSeek-R1-Distill-Qwen-7B",
    messages=[
        {"role": "system", "content": "You are a helpful geography bot."},
        {
            "role": "assistant",
            "content": "Give me the information and population of the capital of France in the JSON format.",
        },
    ],
    temperature=0,
    max_tokens=2048,
    extra_body={"ebnf": ebnf_grammar},
)

print_highlight(
    f"reasoing_content: {response.choices[0].message.reasoning_content}\n\ncontent: {response.choices[0].message.content}"
)
```

### Regular expression


```python Example
response = client.chat.completions.create(
    model="deepseek-ai/DeepSeek-R1-Distill-Qwen-7B",
    messages=[
        {"role": "assistant", "content": "What is the capital of France?"},
    ],
    temperature=0,
    max_tokens=2048,
    extra_body={"regex": "(Paris|London)"},
)

print_highlight(
    f"reasoing_content: {response.choices[0].message.reasoning_content}\n\ncontent: {response.choices[0].message.content}"
)
```

### Structural Tag


```
/* Detailed source-code truncated for AI context efficiency. */
```

## Native API and SGLang Runtime (SRT)


> Note: For native API, as a work-around, you need to set `require_reasoning` argument to `True` to ensure the model will think before generating the structured output. It's not required for chat-completion API.


### JSON


**Using Pydantic**


```python Example
import requests
from pydantic import BaseModel, Field
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("deepseek-ai/DeepSeek-R1-Distill-Qwen-7B")


# Define the schema using Pydantic
class CapitalInfo(BaseModel):
    name: str = Field(..., pattern=r"^\w+$", description="Name of the capital city")
    population: int = Field(..., description="Population of the capital city")


messages = [
    {
        "role": "assistant",
        "content": "Give me the information and population of the capital of France in the JSON format.",
    },
]
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
# Make API request
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": text,
        "require_reasoning": True,
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 2048,
            "json_schema": json.dumps(CapitalInfo.model_json_schema()),
        },
    },
)
print(response.json())


reasoing_content = response.json()["text"].split("</think>")[0]
content = response.json()["text"].split("</think>")[1]
print_highlight(f"reasoing_content: {reasoing_content}\n\ncontent: {content}")
```

**JSON Schema Directly**


```python Example
json_schema = json.dumps(
    {
        "type": "object",
        "properties": {
            "name": {"type": "string", "pattern": "^[\\w]+$"},
            "population": {"type": "integer"},
        },
        "required": ["name", "population"],
    }
)

# JSON
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": text,
        "require_reasoning": True,
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 2048,
            "json_schema": json_schema,
        },
    },
)

print_highlight(response.json())
```

### EBNF


```python Example
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": "Give me the information of the capital of France.",
        "require_reasoning": True,
        "sampling_params": {
            "max_new_tokens": 2048,
            "temperature": 0,
            "n": 3,
            "ebnf": (
                "root ::= city | description\n"
                'city ::= "London" | "Paris" | "Berlin" | "Rome"\n'
                'description ::= city " is " status\n'
                'status ::= "the capital of " country\n'
                'country ::= "England" | "France" | "Germany" | "Italy"'
            ),
        },
        "stream": False,
        "return_logprob": False,
    },
)

print(response.json())
```

### Regular expression


```python Example
response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": "Paris is the capital of",
        "require_reasoning": True,
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 2048,
            "regex": "(France|England)",
        },
    },
)
print(response.json())
```

### Structural Tag


```python Example
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
payload = {
    "text": text,
    "require_reasoning": True,
    "sampling_params": {
        "max_new_tokens": 2048,
        "structural_tag": json.dumps(
            {
                "type": "structural_tag",
                "structures": [
                    {
                        "begin": "<function=get_current_weather>",
                        "schema": schema_get_current_weather,
                        "end": "</function>",
                    },
                    {
                        "begin": "<function=get_current_date>",
                        "schema": schema_get_current_date,
                        "end": "</function>",
                    },
                ],
                "triggers": ["<function="],
            }
        ),
    },
}


# Send POST request to the API endpoint
response = requests.post(f"http://localhost:{port}/generate", json=payload)
print_highlight(response.json())
```


```python Example
terminate_process(server_process)
```

## Offline Engine API


```python Example
import sglang as sgl

llm = sgl.Engine(
    model_path="deepseek-ai/DeepSeek-R1-Distill-Qwen-7B",
    reasoning_parser="deepseek-r1",
    grammar_backend="xgrammar",
)
```

### JSON


**Using Pydantic**


```python Example
import json
from pydantic import BaseModel, Field


prompts = [
    "Give me the information of the capital of China in the JSON format.",
    "Give me the information of the capital of France in the JSON format.",
    "Give me the information of the capital of Ireland in the JSON format.",
]


# Define the schema using Pydantic
class CapitalInfo(BaseModel):
    name: str = Field(..., pattern=r"^\w+$", description="Name of the capital city")
    population: int = Field(..., description="Population of the capital city")


sampling_params = {
    "temperature": 0,
    "top_p": 0.95,
    "max_new_tokens": 2048,
    "json_schema": json.dumps(CapitalInfo.model_json_schema()),
}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print("===============================")
    print(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```

**JSON Schema Directly**


```python Example
prompts = [
    "Give me the information of the capital of China in the JSON format.",
    "Give me the information of the capital of France in the JSON format.",
    "Give me the information of the capital of Ireland in the JSON format.",
]

json_schema = json.dumps(
    {
        "type": "object",
        "properties": {
            "name": {"type": "string", "pattern": "^[\\w]+$"},
            "population": {"type": "integer"},
        },
        "required": ["name", "population"],
    }
)

sampling_params = {"temperature": 0, "max_new_tokens": 2048, "json_schema": json_schema}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print("===============================")
    print(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```

### EBNF


```python Example
prompts = [
    "Give me the information of the capital of France.",
    "Give me the information of the capital of Germany.",
    "Give me the information of the capital of Italy.",
]

sampling_params = {
    "temperature": 0.8,
    "top_p": 0.95,
    "ebnf": (
        "root ::= city | description\n"
        'city ::= "London" | "Paris" | "Berlin" | "Rome"\n'
        'description ::= city " is " status\n'
        'status ::= "the capital of " country\n'
        'country ::= "England" | "France" | "Germany" | "Italy"'
    ),
}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print("===============================")
    print(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```

### Regular expression


```python Example
prompts = [
    "Please provide information about London as a major global city:",
    "Please provide information about Paris as a major global city:",
]

sampling_params = {"temperature": 0.8, "top_p": 0.95, "regex": "(France|England)"}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print("===============================")
    print(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```


```python Example
text = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, return_dict=False
)
prompts = [text]


sampling_params = {
    "temperature": 0.8,
    "top_p": 0.95,
    "max_new_tokens": 2048,
    "structural_tag": json.dumps(
        {
            "type": "structural_tag",
            "structures": [
                {
                    "begin": "<function=get_current_weather>",
                    "schema": schema_get_current_weather,
                    "end": "</function>",
                },
                {
                    "begin": "<function=get_current_date>",
                    "schema": schema_get_current_date,
                    "end": "</function>",
                },
            ],
            "triggers": ["<function="],
        }
    ),
}


# Send POST request to the API endpoint
outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print("===============================")
    print(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```


```python Example
llm.shutdown()
```

---

### Docs Advanced Features Text Watermarking (`docs/docs/advanced_features/text_watermarking.mdx`)

---
title: "Text Watermarking"
metatags:
    description: "Configure Aaronson-Gumbel text watermarking and detect watermarked text."
---

SGLang provides opt-in Aaronson-Gumbel watermarking for sampled text. The watermark replaces random token selection with a keyed, deterministic choice that follows the same output distribution under the ideal independent-uniform hash model, so anyone holding the secret key can later test whether a token sequence carries the watermark. Detection needs only the key and the token IDs; it does not need the model or a GPU.

This feature can support transparency controls such as the machine-readable marking and detectability described in [Article 50 of the EU AI Act](https://eur-lex.europa.eu/eli/reg/2024/1689/oj). It is one technical signal, not a complete compliance program or proof of authorship.

## How it works

### Generation

At each sampling step, SGLang first applies frequency, presence, and repetition penalties, logit bias, and any structured-output grammar mask, followed by the request's temperature and its top-k, top-p, and min-p truncation, then renormalizes. Let `p_i` be the resulting probability of candidate token `i`; grammar-masked and truncated tokens have `p_i = 0` and can never be selected. For each candidate, SGLang hashes the key, the preceding token context, and the token ID into a uniform value `u_i` in `(0, 1)` and selects

```text
argmax over i with p_i > 0 of  log(u_i) / p_i
```

When the `u_i` are independent uniforms, this rule selects token `i` with probability exactly `p_i`, so a single step is distributed like ordinary sampling. Ties go to the lowest token ID.

A position is watermarked only when all of the following hold; otherwise the request samples that position normally:

- The request has watermarking enabled (see [Per-request control](#per-request-control)).
- The request is not greedy. `temperature=0` is normalized to `top_k=1`, and `top_k=1` positions are never watermarked.
- The context is not empty.
- The context has not already been watermarked earlier in the same request. Runtime identifies a context by its 32-bit context hash.
- The request has watermarked fewer than `min(4,096, per-request token-pool capacity)` contexts.
- The largest truncated probability is at most the server's `max_probability`. The default `1.0` disables this gate.

Only a watermarked position enters the request's context history. A position skipped by the probability gate therefore leaves its context eligible for a later, higher-entropy occurrence, and once a request reaches its context budget the remaining tokens use ordinary sampling. The repeated-context rule keeps a repeated context from forcing the same token indefinitely.

The context for a position is the last `h` tokens before it, where `h` is the request's context window, taken from the prompt followed by the tokens generated so far. The first generated token therefore uses the last `h` prompt tokens. A context is shorter than `h` only when fewer than `h` tokens precede the position.

### Hash contract

All arithmetic wraps to unsigned 32 bits. The primitives are the MurmurHash3 x86 32-bit body mix and finalizer:

```text
mix(state, value):
  value = value * 0xcc9e2d51
  value = rotl32(value, 15)
  value = value * 0x1b873593
  state = rotl32(state XOR value, 13)
  return state * 5 + 0xe6546b64

fmix32(value):
  value = value XOR (value >> 16)
  value = value * 0x85ebca6b
  value = value XOR (value >> 13)
  value = value * 0xc2b2ae35
  return value XOR (value >> 16)
```

A key is 1 to 16 hexadecimal digits with an optional `0x` prefix, interpreted as an unsigned 64-bit integer; `key_lo` and `key_hi` are its low and high 32-bit words. For a context of `L` token IDs `c_1 ... c_L` and a candidate token `t`:

```text
context_hash = fmix32(mix(...mix(mix(0, c_1), c_2)..., c_L) XOR (4 * L))
token_hash   = fmix32(mix(mix(mix(mix(0, key_lo), key_hi), context_hash), t) XOR 16)
u            = (token_hash + 0.5) / 2^32
```

The context hash covers only the context tokens; keys enter only through the token hash and, in dual-key mode, through a per-context coin that chooses which key produces the token hash:

```text
coin      = fmix32(mix(mix(mix(mix(mix(0, a_lo), a_hi), b_lo), b_hi), context_hash) XOR 20)
threshold = floor(P * 2^32)
key       = key A if coin < threshold else key B
```

`a_lo`/`a_hi` and `b_lo`/`b_hi` are the words of key A and key B, and `P` is the server's `mixing_probability`.

### Detection

A detector holding the key scores each generated token `t` with `s = -log(1 - u)`, where `u` comes from the hash contract above using that token's context. Without the watermark, each `s` is an independent `Exponential(1)` sample. With the watermark, the generator preferred tokens with large `u`, so the scores are inflated.

Over `n` scored contexts, the score `S = sum(s)` follows `Gamma(shape=n, scale=1)` under the null hypothesis that the text is not watermarked with this key. The detector reports the upper-tail probability `P[Gamma(n, 1) >= S]` as the p-value, its natural logarithm (finite even when the p-value underflows to `0.0`), and the normal approximation `z = (S - n) / sqrt(n)`.

To match generation, a detector must follow these rules:

1. Use the exact prompt token IDs that preceded the completion and the request's context window `h`. With prompt IDs, the first completion token's context is the last `h` prompt tokens. Without prompt IDs, the first `h` completion tokens have unknown contexts and are skipped.
2. Score each distinct context once. The detector compares exact context token tuples, whereas generation compares 32-bit context hashes. After a hash collision, generation skips a later distinct context that the detector still scores. That extra score is an ordinary null sample, so the mismatch can only weaken detection, never create evidence.
3. Stop after the generation request's context budget and report a prefix test. The default detector budget is 4,096 distinct contexts. If the server's per-request token-pool capacity is lower, pass that lower value as `max_contexts`; scoring the unforced tail adds null samples that dilute the statistic without adding evidence. With a maximum-probability gate below `1.0`, the model-free detector cannot identify skipped positions, so this fixed prefix is conservative and may omit signal from later forced positions.

Positions that generation left unforced (greedy positions, and positions skipped by `max_probability`) are indistinguishable from ordinary text to the detector, which scores them as null samples; they dilute the statistic but cannot produce false evidence.

A low p-value is evidence that the text carries the keyed watermark. It is not a calibrated probability that a particular author or model produced the text. Applications must choose a decision threshold and measure false-positive and false-negative rates on their own traffic.

## Server configuration

`--enable-watermark` turns the feature on; every other watermark setting lives in one JSON object passed with `--watermark-config`, either as a file path or inline. Restrict the file to the server account and launch a CUDA server:

```json
{
  "key": "0123456789abcdef",
  "key_b": "fedcba9876543210",
  "context_window": 4,
  "mixing_probability": 0.5,
  "max_probability": 1.0,
  "default_enabled": true,
  "enforce_all": false
}
```

```bash
chmod 600 /run/secrets/sglang-watermark.json
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-8B \
  --enable-watermark \
  --watermark-config /run/secrets/sglang-watermark.json
```

| Field | Default | Behavior |
| --- | --- | --- |
| `key` | unset | Server key (key A), 1 to 16 hex digits, for requests that enable watermarking without their own key. |
| `key_b` | unset | Enables dual-key mode with a second server key. Requires `key`. |
| `context_window` | `4` | Default context window and the maximum that a request may select, from 1 to 64 tokens. |
| `mixing_probability` | `0.5` | In dual-key mode, the probability of selecting key A for each context. Must be strictly between 0 and 1; a non-default value requires `key_b`. |
| `max_probability` | `1.0` | Skips watermarking when the largest truncated probability exceeds this value. Must be greater than 0 and at most 1; `1.0` disables the gate. |
| `default_enabled` | `false` | Watermarks requests that omit the `watermark` field with the server key. Requests may opt out. Requires `key`. |
| `enforce_all` | `false` | Watermarks requests that omit the `watermark` field and rejects `{"enabled": false}`. Requires `key`. |

Every field is optional and any other field is rejected. The config must be a JSON object of at most 4,096 bytes. A value that starts with `{` is parsed as inline JSON; any other value is read as a path to a regular file, and SGLang logs a warning when that file is readable by group or other users. Inline JSON is visible in the process command line, including `/proc/*/cmdline` on Linux, so pass keys through a file. `--watermark-config` requires `--enable-watermark`. A server key alone does not watermark every request; without `default_enabled` or `enforce_all`, requests must opt in.

SGLang redacts the keys and the `--watermark-config` value from the recorded launch command, startup logs, request logs, server information responses, and request crash-dump payloads. Process and GPU core dumps may contain in-memory keys. Protect those artifacts, the configuration file, and the transport used by clients that send per-request keys.

## Per-request control

The native `/generate` API and the OpenAI-compatible `/v1/completions` and `/v1/chat/completions` APIs accept a `watermark` object with three optional fields:

| Field | Type | Meaning |
| --- | --- | --- |
| `enabled` | boolean | `true` enables watermarking with the server key; `false` opts out. |
| `key` | hex string | Watermarks with this key instead of the server key. A key implicitly enables watermarking. |
| `context_window` | integer | Context window for this request, from 1 to the server's `context_window`. |

On `/generate`, pass `watermark` either at the top level of the request or inside `sampling_params`, but not both; a batched request may pass one object per prompt as a list. On the OpenAI-compatible APIs, pass it as a top-level request field:

```bash
curl http://127.0.0.1:30000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "Qwen/Qwen3-8B",
    "messages": [{"role": "user", "content": "Explain photosynthesis."}],
    "temperature": 1.0,
    "top_p": 0.95,
    "return_token_ids": true,
    "watermark": {"enabled": true, "context_window": 4}
  }'
```

The server resolves each request as follows:

| Server mode | No `watermark` field | `{"enabled": false}` | `{"enabled": true}` | `{"key": "HEX"}` |
| --- | --- | --- | --- | --- |
| Watermarking disabled | Off | Off | HTTP 400 | HTTP 400 |
| `--enable-watermark`, no server key | Off | Off | HTTP 400 | Request key |
| `--enable-watermark` with a server key | Off | Off | Server key | Request key |
| Add `default_enabled` | Server key | Off | Server key | Request key |
| Add `enforce_all` | Server key | HTTP 400 | Server key | Request key |

The request also returns HTTP 400 when:

- the `watermark` object sets neither `enabled` nor `key`, or contains an unknown field;
- `key` is combined with `"enabled": false`;
- a key is not 1 to 16 hexadecimal digits;
- `context_window` is not a positive integer or exceeds the server maximum;
- a watermarked request uses beam search.

Request-level keys are credentials carried in the request body. Use an authenticated TLS endpoint whenever they cross a host boundary, and avoid recording request bodies in proxies or application logs.

## Dual-key mode

`key_b` in `--watermark-config` applies dual-key selection to every watermarked request. The request's resolved key, whether the server key or a request key, is key A, and the server's second key is key B. A request key therefore replaces key A while key B stays active. Each eligible context uses key A with probability `mixing_probability` and key B otherwise, according to the coin in the [hash contract](#hash-contract); truncation, repeated-context, and greedy rules are unchanged. Without key B, selection uses the single-key path.

A detector holding both keys splits the distinct contexts by the coin, scores each context with its selected key, and tests the union, which is the strongest statistic; it can also test each partition separately. A detector holding only one key can score every distinct context with that key, but the contexts selected for the other key contribute only null samples and dilute the signal.

## Using the detector

`WatermarkDetector` implements the [detection rules](#detection) above. Construct it with the same key, key B, mixing probability, and context window that generation used:

A minimal [reference detection server](https://github.com/sgl-project/sglang/tree/main/examples/watermark) exposes the in-tree detector over HTTP and reads keys only from `--watermark-config`.

```python
WatermarkDetector(
    key,                      # hex key A
    *,
    key_b=None,               # hex key B for dual-key mode
    mixing_probability=0.5,   # must match the server's mixing_probability
    context_window=4,         # the request's effective window, 1 to 64
    max_contexts=4096,        # prefix-test length, 1 to 4096
)
```

- `detect_tokens(token_ids, *, prompt_token_ids=())` scores completion token IDs.
- `detect_text(text, tokenizer, *, prompt_token_ids=())` first encodes the text with `tokenizer.encode(text, add_special_tokens=False)`. Any object with that method works, including Hugging Face tokenizers.
- `detect(token_ids, *, key, key_b=None, prompt_token_ids=(), mixing_probability=0.5, context_window=4)` is a one-call shortcut.

Token IDs must be unsigned 32-bit integers; any iterable of Python or NumPy integers is accepted.

Every call returns a `WatermarkDetection`:

| Field | Meaning |
| --- | --- |
| `combined` | The test to report. Single-key: every distinct context scored with key A. Dual-key: each context scored with its coin-selected key. |
| `key_a_all_positions` | Every distinct context scored with key A. |
| `key_b_all_positions`, `key_a_partition`, `key_b_partition` | Dual-key only (`None` otherwise): every context scored with key B, and each coin partition scored with its own key. |
| `prefix_limit_reached` | `True` when scoring stopped at `max_contexts` distinct contexts. |
| `tokens_examined` | Completion tokens covered by the test, including repeated and skipped ones. |
| `repeated_contexts` | Positions skipped because their exact context was already scored. |
| `skipped_initial_tokens` | Leading completion tokens skipped because no prompt IDs were given. |

Each statistic is a `WatermarkStatistics` with `num_contexts`, `score`, `z_score`, `p_value`, and `log_p_value`.

Prefer the server's token IDs to re-tokenized text, because re-encoding decoded text does not always reproduce the generated IDs. With `"return_token_ids": true`, non-streaming chat completions return `prompt_token_ids` and `response_token_ids` on each choice, and completions return `prompt_token_ids` and `token_ids`.

### In an SGLang environment

```python
import requests

from sglang.srt.sampling.watermarking import WatermarkDetector

response = requests.post(
    "http://127.0.0.1:30000/v1/chat/completions",
    json={
        "model": "Qwen/Qwen3-8B",
        "messages": [{"role": "user", "content": "Explain photosynthesis."}],
        "temperature": 1.0,
        "top_p": 0.95,
        "return_token_ids": True,
        "watermark": {"enabled": True},
    },
).json()
choice = response["choices"][0]

detector = WatermarkDetector("0123456789abcdef", context_window=4)
result = detector.detect_tokens(
    choice["response_token_ids"],
    prompt_token_ids=choice["prompt_token_ids"],
)
print(result.combined.num_contexts, result.combined.z_score, result.combined.log_p_value)
```

To score text, pass the model's tokenizer and, when available, the prompt IDs:

```python
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen3-8B")
result = detector.detect_text(
    choice["message"]["content"],
    tokenizer,
    prompt_token_ids=choice["prompt_token_ids"],
)
```

For a dual-key server, pass both keys and the server's mixing probability:

```python
detector = WatermarkDetector(
    "0123456789abcdef",
    key_b="fedcba9876543210",
    mixing_probability=0.5,
    context_window=4,
)
result = detector.detect_tokens(completion_ids, prompt_token_ids=prompt_ids)
print(result.combined.p_value, result.key_a_partition.p_value, result.key_b_partition.p_value)
```

### Standalone, without SGLang or PyTorch

`detector.py` and `config.py` import only the Python standard library and `msgspec`, and the package's `__init__.py` imports only the detector. NumPy arrays are accepted as token-ID iterables, but NumPy is not required. To run detection in a separate application, copy the package directory and install `msgspec`:

```bash
mkdir -p detector_app
cp -R python/sglang/srt/sampling/watermarking detector_app/watermarking
python -m pip install msgspec
```

The copy also contains `core.py`, the server runtime, which imports PyTorch; nothing on the detector import path loads it. Run the application with `detector_app` on the import path and import the detector from the copied package:

```python
from watermarking.detector import WatermarkDetector

single = WatermarkDetector("0123456789abcdef", context_window=4)
result = single.detect_tokens(completion_ids, prompt_token_ids=prompt_ids)

dual = WatermarkDetector("0123456789abcdef", key_b="fedcba9876543210")
result = dual.detect_tokens(completion_ids, prompt_token_ids=prompt_ids)
```

Text detection needs only an object with `encode(text, *, add_special_tokens)` that returns a list of IDs. For example, with the lightweight `tokenizers` package:

```python
from tokenizers import Tokenizer

from watermarking.detector import WatermarkDetector


class TokenizerAdapter:
    def __init__(self, name):
        self._tokenizer = Tokenizer.from_pretrained(name)

    def encode(self, text, *, add_special_tokens):
        return self._tokenizer.encode(text, add_special_tokens=add_special_tokens).ids


detector = WatermarkDetector("0123456789abcdef", context_window=4)
result = detector.detect_text(text, TokenizerAdapter("Qwen/Qwen3-8B"), prompt_token_ids=prompt_ids)
```

A detector written from scratch instead of reusing this package must implement the [hash contract](#hash-contract) and all three [detection rules](#detection): prompt alignment, exact-tuple deduplication, and the 4,096-context prefix.

## Compatibility

| Feature | Status | Behavior and validation |
| --- | --- | --- |
| CUDA graphs | Verified | Decode graphs, eager fallback, and fused state updates use the same selector contract. |
| Overlap scheduling | Verified | Prompt initialization is carried with the delayed sampling batch. |
| Tensor parallelism | Verified | TP2 and TP4 ordinary decode, plus NEXTN with TP2, produce detectable output without rank divergence. |
| Mixed enabled and disabled requests | Verified | Keys, context windows, histories, and enablement are resolved per request. |
| JSON schema and regex grammars | Verified | Grammar masking runs before watermark selection; strict outputs remain valid and detectable. |
| Streaming chat completions | Verified | Streaming and non-streaming requests use the same watermark state and token selection. |
| Parallel sampling (`n > 1`) | Verified | Each generated choice owns independent request state and history. |
| Output log probabilities | Verified | Ordinary and speculative decode report the pre-watermark target distribution. Logits are cloned only for requests that ask for log probabilities. |
| Top-k, top-p, and min-p | Verified | The selector reproduces SGLang's combined truncation support before keyed selection. |
| Maximum-probability gate | Verified | Positions above `max_probability` use ordinary sampling and do not consume the repeated-context budget. |
| Logit bias and frequency, presence, and repetition penalties | Verified | These transforms run before watermark selection. |
| Chunked prefill | Verified | Each prefill chunk rebuilds the prompt tail from the request's complete logical fill IDs. |
| Radix-cache prompt reuse | Verified | Prompt-tail initialization uses logical request IDs rather than only newly computed tokens. |
| Decode retraction | Verified | Re-prefill restores the distinct-context history before generation resumes. |
| Request abort and request-slot reuse | Verified | A later prefill resets ring-buffer and context-history state for the reused slot. |
| Multimodal text generation | Verified | Qwen3-VL text tokens use the same watermark path after multimodal prefill. |
| DP attention | Verified | DP2/TP2 normal and NEXTN decoding were verified with Qwen3-8B on two H200 GPUs, including idle-rank batches. |
| NGRAM speculative decoding | Verified | Draft-node contexts are reconstructed before verification sampling. |
| EAGLE and EAGLE3 speculative decoding | Verified | Tree nodes use their own ancestor-derived contexts. |
| NEXTN speculative decoding | Verified | NEXTN resolves to the EAGLE verification path. |
| Pipeline-parallel speculative decoding | Rejected | Startup validation fails closed. |
| Other speculative algorithms | Rejected | Startup validation fails closed. |
| Speculative rejection sampling | Rejected | Startup validation fails closed. |
| Custom logit processors | Rejected | Startup validation fails closed because processor ordering is not defined. |
| Token-oracle sampling backend | Rejected | Startup validation fails closed because oracle-selected tokens bypass the watermark selector. |
| Beam search | Rejected | Request validation rejects watermarked beam-search requests. |
| Diffusion LLM | Rejected | Startup validation fails closed. |
| PD disaggregation | Rejected | Startup validation fails closed because watermark state is not transferred between workers. |
| Embedded Rust API server | Rejected | Startup validation fails closed. |
| Non-CUDA devices | Rejected | Startup validation fails closed. |

In speculative decoding, verification clones the target logits before forcing, so target-model log-probability computation still sees the pre-watermark distribution. Each draft node gets its own context, rebuilt from its ancestors in the verify tree. Repeated-context admission is conservative across the whole tree: once a context hash appears in an earlier row, later rows with the same hash are not forced, even on sibling branches. This keeps duplicate entries out of the history, but reconvergent wide trees may carry less signal.

## Limitations and performance

- Greedy requests carry no signal, and very low-entropy distributions leave few meaningful alternatives for the selector.
- A `max_probability` value below 1 keeps ordinary selection at low-entropy positions and can improve speculative draft acceptance, but the unforced positions dilute the detector statistic.
- Short completions provide few distinct contexts and therefore weak statistical power.
- Paraphrasing, rewriting, translation, and re-tokenization can weaken or remove the signal.
- Detection needs the matching key or keys, mixing probability, context window, and tokenizer, and is strongest with the exact prompt token IDs.
- A request watermarks at most `min(4,096, per-request token-pool capacity)` distinct contexts; later tokens use ordinary sampling.
- The hashes are MurmurHash3, a keyed but non-cryptographic mix. There is no indistinguishability or unforgeability guarantee, and anyone holding the key can both detect and forge the watermark.
- Speculative decoding can accept fewer draft tokens when a draft proposal does not match the watermarked target token. The impact depends on tree width and workload.
- Mixed batches choose the selector path from the batch-wide maximum top-k. A transient unlimited-top-k request can keep that batch on the full-sort path until its sampling metadata is rebuilt.
- Retraction reconstructs a conservative distinct-context history. Repeated retractions can reduce later signal and add scheduler-side replay work.

On one single-GPU node of each type with public `Qwen/Qwen3-8B`, TP1, TRT-LLM MHA, ordinary decoding, temperature 1.0, top-p 0.95, unlimited top-k, and 800-token sampled outputs, the fused selector measured the following mean output throughput over three repetitions per cell:

| Node | Concurrency | Watermark off | Watermark on | Change |
| --- | ---: | ---: | ---: | ---: |
| GB300 | 1 | 270.25 token/s | 260.44 token/s | -3.63% |
| GB300 | 8, per stream | 224.88 token/s | 212.84 token/s | -5.35% |
| B300 | 1 | 258.84 token/s | 247.69 token/s | -4.31% |
| B300 | 8, per stream | 196.26 token/s | 182.04 token/s | -7.24% |

The GB300 concurrency-eight row was remeasured after the score-precision fix on a default-off server by comparing omitted requests with request-level opt-in. These measurements describe one model, GPU, sampling configuration, and output length. Benchmark your deployment before setting capacity targets. Finite-top-k selector latency at batch size one is also hardware-dependent: in one microbenchmark shape (`top_k=20`), the fast path was 58.8% slower than a full sort on H200 with bfloat16 logits and 6.4% faster on GB300 with float32 logits, and at batch size eight it was faster on both.

On a 2x GB300 node with public `Qwen/Qwen3.5-9B`, TP2, NEXTN 3/1/4, concurrency 8, 1,024-token random inputs, 512-token outputs, temperature 0.8, top-p 0.95, and top-k 20, the fused speculative path measured the following means over three repetitions:

| Watermark | Mean TPOT | Aggregate output throughput | Mean accept length |
| --- | ---: | ---: | ---: |
| Off | 2.246 ms | 3,188.9 token/s | 2.759 |
| On | 2.451 ms | 2,922.2 token/s | 2.783 |
| Change | +9.17% | -8.36% | +0.85% |

Each speculative row still requires keyed selection, but tree-context reconstruction, repeated-context admission, accepted-context recording, and ring-buffer append run as fused GPU operations. The reported cost remains workload- and acceptance-dependent.

## See also

The fused Triton selector is adapted from Meta's Apache-2.0 [TextSeal](https://github.com/facebookresearch/textseal) implementation and re-implemented on the hash contract above, so detection follows this page rather than TextSeal's own tooling.

The runtime and reference detector live in `python/sglang/srt/sampling/watermarking/`. Registered coverage lives in `test/registered/kernels/ops/sampling/test_watermark_*.py` and `test/registered/e2e/openai_server/test_watermark.py`.

---

### Docs Advanced Features Thinking Budget (`docs/docs/advanced_features/thinking_budget.mdx`)

---
title: "Thinking Budget"
metatags:
    description: "SGLang thinking budget: control how many tokens a reasoning model spends thinking, from soft chat-template hints to hard per-request caps with strict thinking."
---

Reasoning models can spend an unbounded number of tokens inside the thinking phase. SGLang gives you three ways to control that, from soft hints to hard per-request caps:

1. **Chat-template hints** (`enable_thinking`, `thinking_budget`, `reasoning_effort`): the model's own chat template decides what to do with them. No token guarantee.
2. **Strict thinking** (`--enable-strict-thinking`): a grammar-level token filter that enforces an exact per-request budget. Recommended when you need a guarantee.
3. **Custom logit processor** (`--enable-custom-logit-processor`): a logit processor that forces the thinking phase to end at the budget. Use when the grammar backend cannot be used.

The examples below use [Qwen3](https://huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f653967f), but every mechanism except the built-in logit processors is model-agnostic: strict thinking derives its token ids from the configured reasoning parser, so it works for any model whose parser is set.

## Chat-template hints

The OpenAI chat completions API passes `chat_template_kwargs` through to the model's chat template:

```python Chat-template kwargs
response = client.chat.completions.create(
    model="Qwen/Qwen3-32B",
    messages=[{"role": "user", "content": "What is 1+3?"}],
    extra_body={
        "chat_template_kwargs": {"enable_thinking": True, "thinking_budget": 512}
    },
)
```

Two things to know:

- `enable_thinking` toggles the thinking mode for hybrid models such as Qwen3. It is template-dependent.
- `thinking_budget` only does something if the model's own chat template defines that variable (the official Qwen3 template does). If the template does not define it, the kwarg is silently ignored.

The `reasoning_effort` request field is forwarded into the chat template the same way.

These are hints to the model, not token guarantees. The model can overshoot the budget.

## Hard budget with strict thinking

Launch the server with `--enable-strict-thinking` and a reasoning parser:

```bash Launch with strict thinking
python -m sglang.launch_server \
    --model-path Qwen/Qwen3-32B \
    --host 0.0.0.0 \
    --reasoning-parser qwen3 \
    --enable-strict-thinking
```

Strict thinking requires a grammar backend that supports token filtering. `xgrammar` is the default grammar backend, so no `--grammar-backend` flag is needed. Startup fails if the configured backend cannot filter tokens.

Enable `--reasoning-parser` so responses separate `reasoning_content` from the final answer (see [Reasoning Parser](/docs/advanced_features/separate_reasoning)). Strict thinking derives the thinking-end token ids from the parser's `think_end_token` through the tokenizer, so it is not tied to any hardcoded ids.

### Behavior

- When the budget is spent during thinking, the vocab mask allows only the `</think>` token sequence, so the cap is exact. The model then produces the final answer.
- With strict thinking enabled and no budget set, behavior is unchanged except that model-specific excluded tokens (for Qwen3, `<tool_call>`, `</tool_call>`, `<|im_end|>`, `<|endoftext|>`) are blocked during the thinking phase.
- To apply a server-wide cap to every request, set the environment variable `SGLANG_MAX_THINK_TOKENS` (default `-1`, no cap).

### Native `/generate` API

Set `max_thinking_tokens` per request, and always pair it with `require_reasoning: true`:

```python /generate with a thinking budget
import requests

response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": prompt,
        "require_reasoning": True,
        "max_thinking_tokens": 512,
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 2048,
        },
    },
)
```

<Warning>
Without `require_reasoning: true`, the grammar object starts in the generation state and `max_thinking_tokens` is silently ignored. Sending `max_thinking_tokens` to a server launched without `--enable-strict-thinking` returns a 400 error.
</Warning>

### OpenAI chat completions API

There is no `max_thinking_tokens` field on chat completions. Pass the budget through `custom_params` instead; the runtime picks up the `thinking_budget` key the same way. The chat path sets `require_reasoning` for you based on the thinking mode:

```python Chat completions with a thinking budget
response = client.chat.completions.create(
    model="Qwen/Qwen3-32B",
    messages=[{"role": "user", "content": "What is 1+3?"}],
    extra_body={"custom_params": {"thinking_budget": 512}},
)

print(response.choices[0].message.reasoning_content)
print(response.choices[0].message.content)
```

## Hard budget with a custom logit processor

When the grammar backend cannot be used, a custom logit processor can enforce the budget instead. Launch the server with `--enable-custom-logit-processor`:

```bash Launch with custom logit processors
python -m sglang.launch_server \
    --model-path Qwen/Qwen3-32B \
    --host 0.0.0.0 \
    --reasoning-parser qwen3 \
    --enable-custom-logit-processor
```

Pass a serialized processor class and the budget on each request. This works on both `/generate` and chat completions:

```python Logit processor with a thinking budget
from sglang.srt.sampling.custom_logit_processor import (
    Qwen3ThinkingBudgetLogitProcessor,
)

response = client.chat.completions.create(
    model="Qwen/Qwen3-32B",
    messages=[{"role": "user", "content": "What is 1+3?"}],
    extra_body={
        "custom_logit_processor": Qwen3ThinkingBudgetLogitProcessor.to_str(),
        "custom_params": {"thinking_budget": 512},
    },
)
```

The processor counts the tokens generated after the `<think>` start token. Once the budget is reached, it first forces a newline token, then forces `</think>`. The model may emit its own `</think>` right after the forced one; this is harmless.

### Built-in processors

SGLang ships processors in `python/sglang/srt/sampling/custom_logit_processor.py`, each with hardcoded thinking start / end / newline token ids:

| Processor | Model family |
| --- | --- |
| `Qwen3ThinkingBudgetLogitProcessor` | Qwen3 |
| `Glm4MoeThinkingBudgetLogitProcessor` | GLM-4.5 / GLM-4.6 |
| `DeepSeekR1ThinkingBudgetLogitProcessor` | DeepSeek-R1 |
| `InklingThinkingBudgetLogitProcessor` | Inkling |

These only work for models whose tokenizer produces those exact ids. For any other model, subclass `ThinkingBudgetLogitProcessor` with the model's own ids:

```python Custom thinking-budget processor
from sglang.srt.sampling.custom_logit_processor import (
    ThinkingBudgetLogitProcessor,
)

# Find the ids with your model's tokenizer, e.g.:
# tokenizer.encode("</think>", add_special_tokens=False)
class MyModelThinkingBudgetLogitProcessor(ThinkingBudgetLogitProcessor):
    THINKING_START_TOKEN_ID = 12345
    THINKING_END_TOKEN_ID = 12346
    NEW_LINE_TOKEN_ID = 198
```

## Verify the budget applies

Budget knobs can be silently ignored, so confirm the cap with a deterministic comparison:

1. Run a prompt with `temperature=0` and no budget. Record the thinking length.
2. Run the same prompt with the budget set, again at `temperature=0`.

A working cap ends the thinking exactly at the budget, usually mid-sentence. An ignored knob reproduces the baseline output token for token. Common silent-failure modes:

- Missing `require_reasoning: true` on the native `/generate` API.
- `chat_template_kwargs.thinking_budget` on a model whose chat template does not define the variable.
- A built-in logit processor whose hardcoded token ids do not match the model's tokenizer.

---

### Docs Advanced Features Tool Parser (`docs/docs/advanced_features/tool_parser.mdx`)

---
title: "Tool Parser"
metatags:
    description: "SGLang function calling: tool parsers for DeepSeek, Llama, Qwen, Mistral, GLM, Kimi K2, and Apertus. OpenAI-compatible tool use API."
---
This guide demonstrates how to use SGLang’s [Function calling](https://platform.openai.com/docs/guides/function-calling) functionality.


## Currently supported parsers:

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Parser</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Supported Models</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`apertus2509`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Apertus 2509 (e.g., `swiss-ai/Apertus-{8,70}B-Instruct-2509`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Tool calls are emitted as a JSON list of single-key objects: `<|tools_prefix|>[{"tool": {...}}]<|tools_suffix|>`.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`deepseekv3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepSeek-v3 (e.g., `deepseek-ai/DeepSeek-V3-0324`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Recommend adding `--chat-template ./examples/chat_template/tool_chat_template_deepseekv3.jinja` to launch command.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`deepseekv31`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepSeek-V3.1 and DeepSeek-V3.2-Exp (e.g. `deepseek-ai/DeepSeek-V3.1`, `deepseek-ai/DeepSeek-V3.2-Exp`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Recommend adding `--chat-template ./examples/chat_template/tool_chat_template_deepseekv31.jinja` (Or ..deepseekv32.jinja for DeepSeek-V3.2) to launch command.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`deepseekv32`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>DeepSeek-V3.2 (`deepseek-ai/DeepSeek-V3.2`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`glm`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>GLM series (e.g. `zai-org/GLM-4.6`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`gpt-oss`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>GPT-OSS (e.g., `openai/gpt-oss-120b`, `openai/gpt-oss-20b`, `lmsys/gpt-oss-120b-bf16`, `lmsys/gpt-oss-20b-bf16`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The gpt-oss tool parser filters out analysis channel events and only preserves normal text. This can cause the content to be empty when explanations are in the analysis channel. To work around this, complete the tool round by returning tool results as `role="tool"` messages, which enables the model to generate the final content.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`kimi_k2`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`moonshotai/Kimi-K2-Instruct`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`llama3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Llama 3.1 / 3.2 / 3.3 (e.g. `meta-llama/Llama-3.1-8B-Instruct`, `meta-llama/Llama-3.2-1B-Instruct`, `meta-llama/Llama-3.3-70B-Instruct`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`llama4`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Llama 4 (e.g. `meta-llama/Llama-4-Scout-17B-16E-Instruct`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`mistral`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Mistral (e.g. `mistralai/Mistral-7B-Instruct-v0.3`, `mistralai/Mistral-Nemo-Instruct-2407`, `mistralai/Mistral-7B-v0.3`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`pythonic`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Llama-3.2 / Llama-3.3 / Llama-4</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Model outputs function calls as Python code. Requires `--tool-call-parser pythonic` and is recommended to use with a specific chat template.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`qwen`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Qwen series (e.g. `Qwen/Qwen3-Next-80B-A3B-Instruct`, `Qwen/Qwen3-VL-30B-A3B-Thinking`) except Qwen3-Coder</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`qwen3_coder`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Qwen3-Coder (e.g. `Qwen/Qwen3-Coder-30B-A3B-Instruct`)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`step3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Step-3</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}></td>
    </tr>
  </tbody>
</table>


## OpenAI Compatible API


### Launching the Server


```python Example
import json
from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process
from openai import OpenAI

server_process, port = launch_server_cmd(
    "python3 -m sglang.launch_server --model-path Qwen/Qwen2.5-7B-Instruct --tool-call-parser qwen25 --host 0.0.0.0 --log-level warning"  # qwen25
)
wait_for_server(f"http://localhost:{port}")
```

Note that `--tool-call-parser` defines the parser used to interpret responses.


### Define Tools for Function Call
Below is a Python snippet that shows how to define a tool as a dictionary. The dictionary includes a tool name, a description, and property defined Parameters.


```python Example
# Define tools
tools = [
    {
        "type": "function",
        "function": {
            "name": "get_current_weather",
            "description": "Get the current weather in a given location",
            "parameters": {
                "type": "object",
                "properties": {
                    "city": {
                        "type": "string",
                        "description": "The city to find the weather for, e.g. 'San Francisco'",
                    },
                    "state": {
                        "type": "string",
                        "description": "the two-letter abbreviation for the state that the city is"
                        " in, e.g. 'CA' which would mean 'California'",
                    },
                    "unit": {
                        "type": "string",
                        "description": "The unit to fetch the temperature in",
                        "enum": ["celsius", "fahrenheit"],
                    },
                },
                "required": ["city", "state", "unit"],
            },
        },
    }
]
```

### Define Messages


```python Example
def get_messages():
    return [
        {
            "role": "user",
            "content": "What's the weather like in Boston today? Output a reasoning before act, then use the tools to help you.",
        }
    ]


messages = get_messages()
```

### Initialize the Client


```python Example
# Initialize OpenAI-like client
client = OpenAI(api_key="None", base_url=f"http://0.0.0.0:{port}/v1")
model_name = client.models.list().data[0].id
```

###  Non-Streaming Request


```python Example
# Non-streaming mode test
response_non_stream = client.chat.completions.create(
    model=model_name,
    messages=messages,
    temperature=0,
    top_p=0.95,
    max_tokens=1024,
    stream=False,  # Non-streaming
    tools=tools,
)
print_highlight("Non-stream response:")
print_highlight(response_non_stream)
print_highlight("==== content ====")
print_highlight(response_non_stream.choices[0].message.content)
print_highlight("==== tool_calls ====")
print_highlight(response_non_stream.choices[0].message.tool_calls)
```

#### Handle Tools
When the engine determines it should call a particular tool, it will return arguments or partial arguments through the response. You can parse these arguments and later invoke the tool accordingly.


```python Example
name_non_stream = response_non_stream.choices[0].message.tool_calls[0].function.name
arguments_non_stream = (
    response_non_stream.choices[0].message.tool_calls[0].function.arguments
)

print_highlight(f"Final streamed function call name: {name_non_stream}")
print_highlight(f"Final streamed function call arguments: {arguments_non_stream}")
```

### Streaming Request


```python Example
# Streaming mode test
print_highlight("Streaming response:")
response_stream = client.chat.completions.create(
    model=model_name,
    messages=messages,
    temperature=0,
    top_p=0.95,
    max_tokens=1024,
    stream=True,  # Enable streaming
    tools=tools,
)

texts = ""
tool_calls = []
name = ""
arguments = ""
for chunk in response_stream:
    if chunk.choices[0].delta.content:
        texts += chunk.choices[0].delta.content
    if chunk.choices[0].delta.tool_calls:
        tool_calls.append(chunk.choices[0].delta.tool_calls[0])
print_highlight("==== Text ====")
print_highlight(texts)

print_highlight("==== Tool Call ====")
for tool_call in tool_calls:
    print_highlight(tool_call)
```

#### Handle Tools
When the engine determines it should call a particular tool, it will return arguments or partial arguments through the response. You can parse these arguments and later invoke the tool accordingly.


```python Example
# Parse and combine function call arguments
arguments = []
for tool_call in tool_calls:
    if tool_call.function.name:
        print_highlight(f"Streamed function call name: {tool_call.function.name}")

    if tool_call.function.arguments:
        arguments.append(tool_call.function.arguments)

# Combine all fragments into a single JSON string
full_arguments = "".join(arguments)
print_highlight(f"streamed function call arguments: {full_arguments}")
```

### Define a Tool Function


```python Example
# This is a demonstration, define real function according to your usage.
def get_current_weather(city: str, state: str, unit: "str"):
    return (
        f"The weather in {city}, {state} is 85 degrees {unit}. It is "
        "partly cloudly, with highs in the 90's."
    )


available_tools = {"get_current_weather": get_current_weather}
```


### Execute the Tool


```python Example
messages.append(response_non_stream.choices[0].message)

# Call the corresponding tool function
tool_call = messages[-1].tool_calls[0]
tool_name = tool_call.function.name
tool_to_call = available_tools[tool_name]
result = tool_to_call(**(json.loads(tool_call.function.arguments)))
print_highlight(f"Function call result: {result}")
# messages.append({"role": "tool", "content": result, "name": tool_name})
messages.append(
    {
        "role": "tool",
        "tool_call_id": tool_call.id,
        "content": str(result),
        "name": tool_name,
    }
)

print_highlight(f"Updated message history: {messages}")
```

### Send Results Back to Model


```python Example
final_response = client.chat.completions.create(
    model=model_name,
    messages=messages,
    temperature=0,
    top_p=0.95,
    stream=False,
    tools=tools,
)
print_highlight("Non-stream response:")
print_highlight(final_response)

print_highlight("==== Text ====")
print_highlight(final_response.choices[0].message.content)
```

## Native API and SGLang Runtime (SRT)


```python Example
from transformers import AutoTokenizer
import requests

# generate an answer
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2.5-7B-Instruct")

messages = get_messages()

input = tokenizer.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, tools=tools, return_dict=False
)

gen_url = f"http://localhost:{port}/generate"
gen_data = {
    "text": input,
    "sampling_params": {
        "skip_special_tokens": False,
        "max_new_tokens": 1024,
        "temperature": 0,
        "top_p": 0.95,
    },
}
gen_response = requests.post(gen_url, json=gen_data).json()["text"]
print_highlight("==== Response ====")
print_highlight(gen_response)

# parse the response
parse_url = f"http://localhost:{port}/parse_function_call"

function_call_input = {
    "text": gen_response,
    "tool_call_parser": "qwen25",
    "tools": tools,
}

function_call_response = requests.post(parse_url, json=function_call_input)
function_call_response_json = function_call_response.json()

print_highlight("==== Text ====")
print(function_call_response_json["normal_text"])
print_highlight("==== Calls ====")
print("function name: ", function_call_response_json["calls"][0]["name"])
print("function arguments: ", function_call_response_json["calls"][0]["parameters"])
```


```python Example
terminate_process(server_process)
```

## Offline Engine API


```
/* Detailed source-code truncated for AI context efficiency. */
```


```python Example
llm.shutdown()
```

## Tool Choice Mode

SGLang supports OpenAI's `tool_choice` parameter to control when and which tools the model should call. This feature is implemented using EBNF (Extended Backus-Naur Form) grammar to ensure reliable tool calling behavior.

### Supported Tool Choice Options

- **`tool_choice="required"`**: Forces the model to call at least one tool
- **`tool_choice={"type": "function", "function": {"name": "specific_function"}}`**: Forces the model to call a specific function

### Backend Compatibility

Tool choice is fully supported with the **Xgrammar backend**, which is the default grammar backend (`--grammar-backend xgrammar`). However, it may not be fully supported with other backends such as `outlines`.

### Example: Required Tool Choice


```
/* Detailed source-code truncated for AI context efficiency. */
```

### Example: Specific Function Choice


```python Example
# Example with specific function choice - forces the model to call a specific function
messages_specific = [
    {"role": "user", "content": "What are the most attactive places in France?"}
]

response_specific = client_tool_choice.chat.completions.create(
    model=model_name_tool_choice,
    messages=messages_specific,
    temperature=0,
    max_tokens=1024,
    tools=tools,
    tool_choice={
        "type": "function",
        "function": {"name": "get_current_weather"},
    },  # Force the model to call the specific get_current_weather function
)

print_highlight("Response with specific function choice:")
print("Content:", response_specific.choices[0].message.content)
print("Tool calls:", response_specific.choices[0].message.tool_calls)

if response_specific.choices[0].message.tool_calls:
    tool_call = response_specific.choices[0].message.tool_calls[0]
    print_highlight(f"Called function: {tool_call.function.name}")
    print_highlight(f"Arguments: {tool_call.function.arguments}")
```


```python Example
terminate_process(server_process_tool_choice)
```

## Pythonic Tool Call Format (Llama-3.2 / Llama-3.3 / Llama-4)

Some Llama models (such as Llama-3.2-1B, Llama-3.2-3B, Llama-3.3-70B, and Llama-4) support a "pythonic" tool call format, where the model outputs function calls as Python code, e.g.:

```python Example
[get_current_weather(city="San Francisco", state="CA", unit="celsius")]
```

- The output is a Python list of function calls, with arguments as Python literals (not JSON).
- Multiple tool calls can be returned in the same list:
```python Example
[get_current_weather(city="San Francisco", state="CA", unit="celsius"),
 get_current_weather(city="New York", state="NY", unit="fahrenheit")]
```

For more information, refer to Meta’s documentation on  [Zero shot function calling](https://github.com/meta-llama/llama-models/blob/main/models/llama4/prompt_format.md#zero-shot-function-calling---system-message).

Note that this feature is still under development on Blackwell.

### How to enable
- Launch the server with `--tool-call-parser pythonic`
- You may also specify --chat-template with the improved template for the model (e.g., `--chat-template=examples/chat_template/tool_chat_template_llama4_pythonic.jinja`).
This is recommended because the model expects a special prompt format to reliably produce valid pythonic tool call outputs. The template ensures that the prompt structure (e.g., special tokens, message boundaries like `<|eom|>`, and function call delimiters) matches what the model was trained or fine-tuned on. If you do not use the correct chat template, tool calling may fail or produce inconsistent results.

#### Forcing Pythonic Tool Call Output Without a Chat Template
If you don't want to specify a chat template, you must give the model extremely explicit instructions in your messages to enforce pythonic output. For example, for `Llama-3.2-1B-Instruct`, you need:


```
/* Detailed source-code truncated for AI context efficiency. */
```

> **Note:**
> The model may still default to JSON if it was heavily finetuned on that format. Prompt engineering (including examples) is the only way to increase the chance of pythonic output if you are not using a chat template.


## How to support a new model?
1. Update the TOOLS_TAG_LIST in sglang/srt/function_call_parser.py with the model’s tool tags. Currently supported tags include:
```text Output
	TOOLS_TAG_LIST = [
	    “<|plugin|>“,
	    “<function=“,
	    “<tool_call>“,
	    “<|python_tag|>“,
	    “[TOOL_CALLS]”
	]
```
2. Create a new detector class in sglang/srt/function_call_parser.py that inherits from BaseFormatDetector. The detector should handle the model’s specific function call format. For example:
```text Output
    class NewModelDetector(BaseFormatDetector):
```
3. Add the new detector to the MultiFormatParser class that manages all the format detectors.

---

### Docs Advanced Features Vlm Query (`docs/docs/advanced_features/vlm_query.mdx`)

---
title: "Query VLM with Offline Engine"
metatags:
    description: "SGLang VLM offline engine: raw images, processor output, precomputed embeddings. Qwen2.5-VL and Llama 4 examples."
---
This tutorial demonstrates how to use SGLang's **offline Engine API** to query VLMs. We will demonstrate usage with Qwen2.5-VL and Llama 4. This section demonstrates three different calling approaches:

1. **Basic Call**: Directly pass images and text.
2. **Processor Output**: Use HuggingFace processor for data preprocessing.
3. **Precomputed Embeddings**: Pre-calculate image features to improve inference efficiency.

## Understanding the Three Input Formats

SGLang supports three ways to pass visual data, each optimized for different scenarios:

### 1. **Raw Images** - Simplest approach
- Pass PIL Images, file paths, URLs, or base64 strings directly
- SGLang handles all preprocessing automatically
- Best for: Quick prototyping, simple applications

### 2. **Processor Output** - For custom preprocessing
- Pre-process images with HuggingFace processor
- Pass the complete processor output dict with `format: "processor_output"`
- Best for: Custom image transformations, integration with existing pipelines
- Requirement: Must use `input_ids` instead of text prompt

### 3. **Precomputed Embeddings** - For maximum performance
- Pre-calculate visual embeddings using the vision encoder
- Pass embeddings with `format: "precomputed_embedding"`
- Best for: Repeated queries on same images, caching, high-throughput serving
- Performance gain: Avoids redundant vision encoder computation (30-50% speedup)

**Key Rule**: Within a single request, use only one format for all images. Don't mix formats.

The examples below demonstrate all three approaches with both Qwen2.5-VL and Llama 4 models.

## Querying Qwen2.5-VL Model

```python Example
import nest_asyncio

nest_asyncio.apply()

import sglang.test.doc_patch  # noqa: F401

model_path = "Qwen/Qwen2.5-VL-3B-Instruct"
chat_template = "qwen2-vl"
example_image_url = "https://raw.githubusercontent.com/sgl-project/sglang/main/examples/assets/example_image.png"
```

```python Example
from io import BytesIO
import requests
from PIL import Image

from sglang.srt.parser.conversation import chat_templates

image = Image.open(BytesIO(requests.get(example_image_url).content))

conv = chat_templates[chat_template].copy()
conv.append_message(conv.roles[0], f"What's shown here: {conv.image_token}?")
conv.append_message(conv.roles[1], "")
conv.image_data = [image]

print("Generated prompt text:")
print(conv.get_prompt())
print(f"\nImage size: {image.size}")
image
```

### Basic Offline Engine API Call

```python Example
from sglang import Engine

llm = Engine(model_path=model_path, chat_template=chat_template, log_level="warning")
```

```python Example
out = llm.generate(prompt=conv.get_prompt(), image_data=[image])
print("Model response:")
print(out["text"])
```

### Call with Processor Output

Using a HuggingFace processor to preprocess text and images, and passing the `processor_output` directly into `Engine.generate`.

```python Example
from transformers import AutoProcessor

processor = AutoProcessor.from_pretrained(model_path)
processor_output = processor(
    images=[image], text=conv.get_prompt(), return_tensors="pt"
)

out = llm.generate(
    input_ids=processor_output["input_ids"][0].detach().cpu().tolist(),
    image_data=[dict(processor_output, format="processor_output")],
)
print("Response using processor output:")
print(out["text"])
```

### Call with Precomputed Embeddings

You can pre-calculate image features to avoid repeated visual encoding processes.

```python Example
from transformers import AutoProcessor
from transformers import Qwen2_5_VLForConditionalGeneration

processor = AutoProcessor.from_pretrained(model_path)
model = Qwen2_5_VLForConditionalGeneration.from_pretrained(model_path).eval()
vision = model.model.visual.cuda()
```

```python Example
processor_output = processor(
    images=[image], text=conv.get_prompt(), return_tensors="pt"
)

input_ids = processor_output["input_ids"][0].detach().cpu().tolist()

precomputed_embeddings = vision(
    processor_output["pixel_values"].cuda(), processor_output["image_grid_thw"].cuda()
)
precomputed_embeddings = precomputed_embeddings.pooler_output

multi_modal_item = dict(
    processor_output,
    format="precomputed_embedding",
    feature=precomputed_embeddings,
)

out = llm.generate(input_ids=input_ids, image_data=[multi_modal_item])
print("Response using precomputed embeddings:")
print(out["text"])

llm.shutdown()
```

## Querying Llama 4 Vision Model

```python Example
model_path = "meta-llama/Llama-4-Scout-17B-16E-Instruct"
chat_template = "llama-4"

from io import BytesIO
import requests
from PIL import Image

from sglang.srt.parser.conversation import chat_templates

# Download the same example image
image = Image.open(BytesIO(requests.get(example_image_url).content))

conv = chat_templates[chat_template].copy()
conv.append_message(conv.roles[0], f"What's shown here: {conv.image_token}?")
conv.append_message(conv.roles[1], "")
conv.image_data = [image]

print("Llama 4 generated prompt text:")
print(conv.get_prompt())
print(f"Image size: {image.size}")

image
```

### Llama 4 Basic Call

Llama 4 requires more computational resources, so it's configured with multi-GPU parallelism (tp_size=4) and larger context length.

```python Example
llm = Engine(
    model_path=model_path,
    enable_multimodal=True,
    attention_backend="fa3",
    tp_size=4,
    context_length=65536,
)

out = llm.generate(prompt=conv.get_prompt(), image_data=[image])
print("Llama 4 response:")
print(out["text"])
```

### Call with Processor Output

Using HuggingFace processor to preprocess data can reduce computational overhead during inference.

```python Example
from transformers import AutoProcessor

processor = AutoProcessor.from_pretrained(model_path)
processor_output = processor(
    images=[image], text=conv.get_prompt(), return_tensors="pt"
)

out = llm.generate(
    input_ids=processor_output["input_ids"][0].detach().cpu().tolist(),
    image_data=[dict(processor_output, format="processor_output")],
)
print("Response using processor output:")
print(out)
```

### Call with Precomputed Embeddings

```python Example
from transformers import AutoProcessor
from transformers import Llama4ForConditionalGeneration

processor = AutoProcessor.from_pretrained(model_path)
model = Llama4ForConditionalGeneration.from_pretrained(
    model_path, torch_dtype="auto"
).eval()

vision = model.vision_model.cuda()
multi_modal_projector = model.multi_modal_projector.cuda()

print(f'Image pixel values shape: {processor_output["pixel_values"].shape}')
input_ids = processor_output["input_ids"][0].detach().cpu().tolist()

# Process image through vision encoder
image_outputs = vision(
    processor_output["pixel_values"].to("cuda"),
    aspect_ratio_ids=processor_output["aspect_ratio_ids"].to("cuda"),
    aspect_ratio_mask=processor_output["aspect_ratio_mask"].to("cuda"),
    output_hidden_states=False
)
image_features = image_outputs.last_hidden_state

# Flatten image features and pass through multimodal projector
vision_flat = image_features.view(-1, image_features.size(-1))
precomputed_embeddings = multi_modal_projector(vision_flat)

# Build precomputed embedding data item
mm_item = dict(
    processor_output,
    format="precomputed_embedding",
    feature=precomputed_embeddings
)

# Use precomputed embeddings for efficient inference
out = llm.generate(input_ids=input_ids, image_data=[mm_item])
print("Llama 4 precomputed embedding response:")
print(out["text"])
```

---

### Docs Basic Usage Anthropic Api (`docs/docs/basic_usage/anthropic_api.mdx`)

---
title: "Anthropic-Compatible API"
description: "Use the Anthropic Messages API (/v1/messages) with SGLang, including Claude Code integration and prefix-cache tuning."
---
SGLang ships an Anthropic-compatible `/v1/messages` endpoint so any client built for the Anthropic
Messages API — including the Anthropic SDKs and agentic CLIs such as Claude Code — can talk to a
self-hosted SGLang server without changes. A complete reference for the API is available in the
[Anthropic API Reference](https://docs.anthropic.com/en/api/messages).

The endpoint is registered automatically on every SGLang server; no extra flag is required to enable it.
It reuses the same model, chat template, and reasoning / tool-call parsers as the OpenAI-compatible
endpoint, and supports both non-streaming and streaming responses, tool use, and a `count_tokens` route.

This tutorial covers:

- `POST /v1/messages` (non-streaming and streaming)
- `POST /v1/messages/count_tokens`
- Pointing **Claude Code** at the server, including the `CLAUDE_CODE_ATTRIBUTION_HEADER` setting that is
  required for good prefix-cache reuse.

## Launch A Server

Launch the server in your terminal and wait for it to initialize. The Anthropic `/v1/messages` endpoint
is registered automatically — no extra flag is required beyond the usual server launch. The example below
is a single-node GLM-5.2-FP8 config; see the
[GLM-5.2 cookbook](/cookbook/autoregressive/GLM/GLM-5.2) for verified commands
across hardware and quantizations.

```bash Command
sglang serve \
    --model-path zai-org/GLM-5.2-FP8 \
    --tp 8 \
    --speculative-algorithm EAGLE \
    --speculative-num-steps 5 \
    --speculative-eagle-topk 1 \
    --speculative-num-draft-tokens 6 \
    --reasoning-parser glm45 \
    --tool-call-parser glm47 \
    --host 0.0.0.0 \
    --port 30000
```

<Note>
- **The endpoint is model-agnostic.** The `/v1/messages` route is on by default for any model; GLM-5.2 is
  used here because its reasoning + tool-use output is where Claude Code integration shines, but any model
  works.
- **Model name and `[1m]`.** SGLang does not validate the request `model` field, so Claude Code can send
  any name. The `[1m]` suffix is a **client-side hint**: Claude Code only enables its 1M-context beta when
  the model name ends in `[1m]` — without it, context is capped. Set the same `glm-5.2[1m]` in the
  `ANTHROPIC_DEFAULT_*_MODEL` env vars below.
- **`--reasoning-parser` / `--tool-call-parser` are optional.** Add them when the model emits reasoning
  content (GLM-5.2, Qwen3, DeepSeek-R1, …) or when you want tool calls parsed into structured `tool_use`
  blocks. Without a tool-call parser, tool schemas are still accepted but the model's tool calls come back
  as raw text, and Claude Code cannot execute them.
- **Context length** defaults to the model's own (1M for GLM-5.2); pass `--context-length` only to cap it.
</Note>

## Send A Message

### Non-Streaming

Use the Anthropic Python SDK pointed at the server. Unlike the OpenAI SDK, the Anthropic SDK appends
`/v1/messages` itself, so `base_url` is the server root **without** a `/v1` suffix.

```python Example
from anthropic import Anthropic

client = Anthropic(
    base_url="http://127.0.0.1:30000",
    api_key="EMPTY",  # SGLang does not require a real key by default
)

message = client.messages.create(
    model="zai-org/GLM-5.2-FP8",
    max_tokens=512,
    messages=[{"role": "user", "content": "List 3 countries and their capitals."}],
)
# A reasoning model may emit a `thinking` block before the `text` block —
# pick the text block rather than assuming content[0].
print(next(b.text for b in message.content if b.type == "text"))
```

**Example Output:**
```text Output
Here are 3 countries and their capitals:

1. **France** - Paris
2. **Japan** - Tokyo
3. **Brazil** - Brasília
```

### Streaming

Set `stream=True` to receive Server-Sent Events as they are produced.

```python Example
with client.messages.stream(
    model="zai-org/GLM-5.2-FP8",
    max_tokens=512,
    messages=[{"role": "user", "content": "Say this is a test"}],
) as stream:
    for text in stream.text_stream:
        print(text, end="", flush=True)
```

**Example Output:**
```text Output
This is a test.
```

### System Prompt

The top-level `system` field is accepted as a string or as a list of text blocks, matching the Anthropic
API shape:

```python Example
message = client.messages.create(
    model="zai-org/GLM-5.2-FP8",
    max_tokens=512,
    system="You are a helpful assistant that answers concisely.",
    messages=[{"role": "user", "content": "What is the capital of France?"}],
)
print(next(b.text for b in message.content if b.type == "text"))
```

**Example Output:**
```text Output
The capital of France is Paris.
```

### Tool Use

Tool definitions follow the Anthropic `tools` schema. When the server is launched with a
`--tool-call-parser`, the model's tool calls are returned as `tool_use` content blocks:

```python Example
message = client.messages.create(
    model="zai-org/GLM-5.2-FP8",
    max_tokens=512,
    tools=[
        {
            "name": "get_weather",
            "description": "Get the weather for a city",
            "input_schema": {
                "type": "object",
                "properties": {"city": {"type": "string"}},
                "required": ["city"],
            },
        }
    ],
    messages=[{"role": "user", "content": "What is the weather in Paris?"}],
)
print(message.stop_reason)
print([b for b in message.content if b.type == "tool_use"])
```

**Example Output:**
```text Output
tool_use
[ToolUseBlock(type='tool_use', id='toolu_01XXXX', name='get_weather', input={'city': 'Paris'})]
```

### Counting Tokens

`POST /v1/messages/count_tokens` returns the tokenized length of a request without generating a
response. It reuses the same request conversion as `/v1/messages`, so system prompts, tools, and
multi-turn history are all accounted for.

```python Example
resp = client.messages.count_tokens(
    model="zai-org/GLM-5.2-FP8",
    messages=[{"role": "user", "content": "Hello, world"}],
)
print(resp.input_tokens)
```

**Example Output:**
```text Output
15
```

## Using Claude Code

Claude Code can be pointed at an SGLang server by setting a few env vars in the shell that starts it.
With the server already running on `:30000`, export the full set and launch `claude`:

```bash Command
export ANTHROPIC_BASE_URL="http://127.0.0.1:30000"
export ANTHROPIC_AUTH_TOKEN="dummy"                 # required by Claude Code; any non-empty string works
export API_TIMEOUT_MS="3000000"                     # long timeout — reasoning + 1M-context turns are slow
export CLAUDE_CODE_AUTO_COMPACT_WINDOW="1000000"     # let auto-compact use the full 1M window
export CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC=1   # drop autoupdater/telemetry/error-reporting noise
export CLAUDE_CODE_ATTRIBUTION_HEADER=0             # required for prefix-cache reuse — see below
export ANTHROPIC_DEFAULT_HAIKU_MODEL="glm-5.2[1m]"    # [1m] suffix enables Claude Code's 1M-context beta
export ANTHROPIC_DEFAULT_SONNET_MODEL="glm-5.2[1m]"  # [1m] suffix enables Claude Code's 1M-context beta
export ANTHROPIC_DEFAULT_OPUS_MODEL="glm-5.2[1m]"     # [1m] suffix enables Claude Code's 1M-context beta
claude
```

Each var matters:

- **`ANTHROPIC_BASE_URL`** — points Claude Code at your SGLang server instead of the Anthropic API.
- **`ANTHROPIC_AUTH_TOKEN`** — Claude Code requires a non-empty auth token; SGLang accepts any value
  when launched without `--api-key`.
- **`API_TIMEOUT_MS`** — raise it; reasoning models with long outputs and 1M-context turns routinely
  exceed the default timeout.
- **`ANTHROPIC_DEFAULT_{HAIKU,SONNET,OPUS}_MODEL`** — the model name Claude Code sends for each tier.
  SGLang does not validate this field, so any name works. Use `glm-5.2[1m]`: the `[1m]` suffix is a
  client-side hint that enables Claude Code's 1M-context beta (without it, context is capped).
- **`CLAUDE_CODE_AUTO_COMPACT_WINDOW`** — set to `1000000` so auto-compaction uses the full 1M window
  instead of the default, keeping long sessions alive.

<Tip>
Instead of exporting these in every shell, persist them in `~/.claude/settings.json` under the `env` key
— they apply to all Claude Code sessions:

```json
{
  "env": {
    "ANTHROPIC_BASE_URL": "http://127.0.0.1:30000",
    "ANTHROPIC_AUTH_TOKEN": "dummy",
    "CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC": "1",
    "CLAUDE_CODE_ATTRIBUTION_HEADER": "0",
    "ANTHROPIC_DEFAULT_HAIKU_MODEL": "glm-5.2[1m]",
    "ANTHROPIC_DEFAULT_SONNET_MODEL": "glm-5.2[1m]",
    "ANTHROPIC_DEFAULT_OPUS_MODEL": "glm-5.2[1m]"
  }
}
```
</Tip>

### Required: `CLAUDE_CODE_ATTRIBUTION_HEADER=0` for prefix-cache reuse

<Note>
**Set this whenever Claude Code routes through SGLang (or any non-Anthropic gateway).** Without it,
multi-turn conversations re-prefill the whole history every turn.
</Note>

Claude Code prepends a per-request attribution block to the start of the system prompt, of the form
`x-anthropic-billing-header: cc_version=<ver>.<per-request-hash>; cc_entrypoint=...; cch=<hash>;`. The
per-request hash is the **first token to differ between turns**, so the radix prefix cache can only reuse
the short prefix before that hash and re-prefills the system prompt plus the entire conversation history
on every turn.

Setting `CLAUDE_CODE_ATTRIBUTION_HEADER=0` removes the whole attribution line from the system prompt.
This is a documented Claude Code env var whose explicit purpose is to "improve prompt-cache hit rates when
routing through an [LLM gateway](https://code.claude.com/docs/en/llm-gateway)" (see the [Claude Code env-vars reference](https://code.claude.com/docs/en/env-vars)).

<Note>
`CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC` does **not** remove the attribution block — it only covers
autoupdater/telemetry/error reporting. The attribution header is a separate code path; use
`CLAUDE_CODE_ATTRIBUTION_HEADER=0` for it.
</Note>

## Troubleshooting

**Connection refused / `fetch failed`** — Ensure the server is up and the port in `ANTHROPIC_BASE_URL`
matches `--port` (default 30000). If you set `ANTHROPIC_BASE_URL` to a remote host, confirm it's reachable
and not behind a proxy that blocks the connection.

**`Model not found` / 404 from the server** — SGLang does not validate the request `model` field and
serves whatever model was loaded at startup, so a 404 usually means the request did not reach the
`/v1/messages` route at all. Confirm `ANTHROPIC_BASE_URL` points at the server (not missing the port) and
that the server finished loading.

**Tool calls not working / returned as raw text** — Launch the server with the correct
`--tool-call-parser` for your model (e.g. `glm47`, `qwen3`). Without it the `tools` field is still accepted
but the model's tool calls come back as text instead of `tool_use` blocks, and Claude Code cannot execute
them.

**Slow / re-prefills the whole history every turn** — You are missing
`CLAUDE_CODE_ATTRIBUTION_HEADER=0`. Claude Code's per-request attribution hash in the system prompt
defeats radix prefix-cache reuse; see the section above.

**Context capped below 1M** — The model name must end in `[1m]` for Claude Code to enable its 1M-context
beta. Verify `ANTHROPIC_DEFAULT_*_MODEL` uses the `[1m]` suffix, and that the loaded model's native context
is 1M (GLM-5.2 is 1048576; pass `--context-length` only to cap it, not to extend).

## Parameters

The `/v1/messages` endpoint accepts the standard Anthropic Messages API parameters. Refer to the
[Anthropic Messages API reference](https://docs.anthropic.com/en/api/messages) for the full list.

Reasoning models are supported through the same `--reasoning-parser` mechanism as the OpenAI-compatible
endpoint; pass the model's reasoning kwarg via the request (e.g. `thinking` for DeepSeek-V3-style models,
`enable_thinking` for Qwen3-style models). See [OpenAI APIs - Completions](./openai_api_completions) for
the reasoning-parser / chat-template mapping.

---

### Docs Basic Usage Aws Sagemaker (`docs/docs/basic_usage/aws_sagemaker.mdx`)

---
title: "Amazon SageMaker AI"
description: "Deploy SGLang on Amazon SageMaker AI endpoints using the AWS Deep Learning Container."
---

Deploy SGLang on [Amazon SageMaker AI](https://aws.amazon.com/sagemaker/) endpoints using the
[AWS Deep Learning Container (DLC)](https://aws.github.io/deep-learning-containers/sglang/) for SGLang.
The SageMaker image variant accepts model configuration via environment variables and serves on port 8080.

This guide uses the pre-built DLC image. To build and deploy your own container instead, see
[Method 7: Run on AWS SageMaker](/docs/get-started/install#aws-sagemaker) in the installation guide.

## Container image

AWS publishes pre-built, security-patched SGLang DLCs. The SageMaker GPU image is available from the
Amazon ECR registry (account `763104351884`) in each supported region. For example, in `us-west-2`:

```text
763104351884.dkr.ecr.us-west-2.amazonaws.com/sglang:server-sagemaker-cuda-v1.0
```

For the full list of image tags, see the
[Available DLC Images](https://aws.github.io/deep-learning-containers/reference/available_images/) reference,
and for region-specific account IDs and supported regions, see
[Region Availability](https://aws.github.io/deep-learning-containers/reference/region_availability/).

## Specifying the model

The SageMaker image resolves the model in this order:

1. **`SM_SGLANG_MODEL_PATH` environment variable** — explicit Hugging Face ID or path.
2. **`/opt/ml/model`** — when SageMaker mounts model artifacts via `ModelDataUrl` or `ModelDataSource`,
   the entrypoint uses this path by default.

For gated models, also pass `HF_TOKEN`.

Any `SM_SGLANG_*` environment variable is converted to a `--<name>` SGLang server argument
(for example, `SM_SGLANG_CONTEXT_LENGTH=4096` becomes `--context-length 4096`).

## Deploy with the SageMaker Python SDK

```python
from sagemaker.model import Model
from sagemaker.predictor import Predictor
from sagemaker.serializers import JSONSerializer

model = Model(
    image_uri="763104351884.dkr.ecr.us-west-2.amazonaws.com/sglang:server-sagemaker-cuda-v1.0",
    role="arn:aws:iam::<account_id>:role/<role_name>",
    predictor_cls=Predictor,
    env={"SM_SGLANG_MODEL_PATH": "openai/gpt-oss-20b"},
)

predictor = model.deploy(
    instance_type="ml.g5.2xlarge",
    initial_instance_count=1,
    inference_ami_version="al2023-ami-sagemaker-inference-gpu-4-1",
    serializer=JSONSerializer(),
)

response = predictor.predict({
    "model": "openai/gpt-oss-20b",
    "messages": [{"role": "user", "content": "What is deep learning?"}],
    "max_tokens": 256,
})
print(response)

# Cleanup
predictor.delete_model()
predictor.delete_endpoint(delete_endpoint_config=True)
```

## Deploy with Boto3

```python
import json
import boto3

sm = boto3.client("sagemaker")
smrt = boto3.client("sagemaker-runtime")

sm.create_model(
    ModelName="sglang-model",
    PrimaryContainer={
        "Image": "763104351884.dkr.ecr.us-west-2.amazonaws.com/sglang:server-sagemaker-cuda-v1.0",
        "Environment": {"SM_SGLANG_MODEL_PATH": "openai/gpt-oss-20b"},
    },
    ExecutionRoleArn="arn:aws:iam::<account_id>:role/<role_name>",
)

sm.create_endpoint_config(
    EndpointConfigName="sglang-config",
    ProductionVariants=[{
        "VariantName": "default",
        "ModelName": "sglang-model",
        "InstanceType": "ml.g5.2xlarge",
        "InitialInstanceCount": 1,
        "InferenceAmiVersion": "al2023-ami-sagemaker-inference-gpu-4-1",
    }],
)

sm.create_endpoint(EndpointName="sglang-endpoint", EndpointConfigName="sglang-config")
sm.get_waiter("endpoint_in_service").wait(EndpointName="sglang-endpoint")

resp = smrt.invoke_endpoint(
    EndpointName="sglang-endpoint",
    ContentType="application/json",
    Body=json.dumps({
        "model": "openai/gpt-oss-20b",
        "messages": [{"role": "user", "content": "What is deep learning?"}],
        "max_tokens": 256,
    }),
)
print(json.loads(resp["Body"].read()))

# Cleanup
sm.delete_endpoint(EndpointName="sglang-endpoint")
sm.delete_endpoint_config(EndpointConfigName="sglang-config")
sm.delete_model(ModelName="sglang-model")
```

## Model artifacts

When `ModelDataUrl` (or `ModelDataSource`) points to a tarball or S3 prefix, SageMaker mounts the contents
at `/opt/ml/model`. The entrypoint defaults `--model-path` to that location, so `SM_SGLANG_MODEL_PATH`
can be omitted:

```text
model.tar.gz
├── config.json              # standard model files (Hugging Face layout)
├── tokenizer.json
└── *.safetensors
```

## Notes

- GPU deployments require `inference_ami_version` — the default SageMaker host AMI has incompatible NVIDIA
  drivers for CUDA 13 images. See the
  [ProductionVariant API reference](https://docs.aws.amazon.com/sagemaker/latest/APIReference/API_ProductionVariant.html)
  for valid values.
- The endpoint exposes an OpenAI-compatible API, so the request body matches the SGLang server's
  `/v1/chat/completions` schema.

---

### Docs Basic Usage Native Api (`docs/docs/basic_usage/native_api.mdx`)

---
title: "SGLang Native APIs"
metatags:
    description: "SGLang native server APIs for text generation, embedding, reranking, model info, cache management, and more."
---
Apart from the OpenAI compatible APIs, the SGLang Runtime also provides its native server APIs. We introduce the following APIs:

- `/generate` (text generation model)
- `/get_model_info`
- `/server_info`
- `/health`
- `/health_generate`
- `/flush_cache`
- `/update_weights`
- `/encode`(embedding model)
- `/v1/rerank`(cross encoder rerank model)
- `/v1/score`(decoder-only scoring)
- `/v1/decisions`(typed decisions on a chat model)
- `/classify`(reward model)
- `/start_expert_distribution_record`
- `/stop_expert_distribution_record`
- `/dump_expert_distribution_record`
- `/tokenize`
- `/detokenize`
- A full list of these APIs can be found at [http_server.py](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/entrypoints/http_server.py)

We mainly use `requests` to test these APIs in the following examples. You can also use `curl`.

## Launch A Server

```python Example
from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process

server_process, port = launch_server_cmd(
    "python3 -m sglang.launch_server --model-path qwen/qwen2.5-0.5b-instruct --host 0.0.0.0 --log-level warning"
)

wait_for_server(f"http://localhost:{port}", process=server_process)
```

## Generate (text generation model)
Generate completions. This is similar to the `/v1/completions` in OpenAI API. Detailed parameters can be found in the [sampling parameters](./sampling_params).

```python Example
import requests

url = f"http://localhost:{port}/generate"
data = {"text": "What is the capital of France?"}

response = requests.post(url, json=data)
print_highlight(response.json())
```

## Get Model Info

Get the information of the model.

- `model_path`: The path/name of the model.
- `is_generation`: Whether the model is used as generation model or embedding model.
- `tokenizer_path`: The path/name of the tokenizer.
- `preferred_sampling_params`: The default sampling params specified via `--preferred-sampling-params`. `None` is returned in this example as we did not explicitly configure it in server args.
- `weight_version`: This field contains the version of the model weights. This is often used to track changes or updates to the model’s trained parameters.
- `has_image_understanding`: Whether the model has image-understanding capability.
- `has_audio_understanding`: Whether the model has audio-understanding capability.
- `model_type`: The model type from the HuggingFace config (e.g., "qwen2", "llama").
- `architectures`: The model architectures from the HuggingFace config (e.g., ["Qwen2ForCausalLM"]).
- `embedding`: The resolved embedding-serving plan. It includes pooling, normalization, execution and attention style, Matryoshka dimensions, cache policy, and effective BCG prefill settings. This field is available when the model configuration exposes an embedding capability contract.

```python Example
url = f"http://localhost:{port}/get_model_info"

response = requests.get(url)
response_json = response.json()
print_highlight(response_json)
assert response_json["model_path"] == "qwen/qwen2.5-0.5b-instruct"
assert response_json["is_generation"] is True
assert response_json["tokenizer_path"] == "qwen/qwen2.5-0.5b-instruct"
assert response_json["preferred_sampling_params"] is None
assert response_json.keys() == {
    "model_path",
    "is_generation",
    "tokenizer_path",
    "preferred_sampling_params",
    "weight_version",
    "has_image_understanding",
    "has_audio_understanding",
    "model_type",
    "architectures",
    "embedding",
}
```

## Get Server Info
Gets the server information including CLI arguments, token limits, and memory pool sizes.
- Note: `get_server_info` merges the following deprecated endpoints:
  - `get_server_args`
  - `get_memory_pool_size`
  - `get_max_total_num_tokens`

```python Example
url = f"http://localhost:{port}/server_info"

response = requests.get(url)
print_highlight(response.text)
```

## Health Check
- `/health`: Check the health of the server.
- `/health_generate`: Check the health of the server by generating one token.

```python Example
url = f"http://localhost:{port}/health_generate"

response = requests.get(url)
print_highlight(response.text)
```

```python Example
url = f"http://localhost:{port}/health"

response = requests.get(url)
print_highlight(response.text)
```

## Flush Cache

Flush the radix cache. It will be automatically triggered when the model weights are updated by the `/update_weights` API.

Parameters:
- `timeout` (query, float, default `0`, unit: seconds): Wait time for idle state before flushing. `0` means fail fast if not idle. When HiCache async operations are in-flight, a non-zero timeout allows the server to wait until idle before flushing, avoiding unnecessary 400 errors.

```bash Command
# With timeout (wait up to 30s for idle state)
curl -s -X POST "http://127.0.0.1:30000/flush_cache?timeout=30"
```

```python Example
url = f"http://localhost:{port}/flush_cache"

response = requests.post(url)
print_highlight(response.text)
```

## Update Weights From Disk

Update model weights from disk without restarting the server. Only applicable for models with the same architecture and parameter size.

SGLang support `update_weights_from_disk` API for continuous evaluation during training (save checkpoint to disk and update weights from disk).

```python Example
# successful update with same architecture and size

url = f"http://localhost:{port}/update_weights_from_disk"
data = {"model_path": "qwen/qwen2.5-0.5b-instruct"}

response = requests.post(url, json=data)
print_highlight(response.text)
assert response.json()["success"] is True
assert response.json()["message"] == "Succeeded to update model weights."
```

```python Example
# failed update with different parameter size or wrong name

url = f"http://localhost:{port}/update_weights_from_disk"
data = {"model_path": "qwen/qwen2.5-0.5b-instruct-wrong"}

response = requests.post(url, json=data)
response_json = response.json()
print_highlight(response_json)
assert response_json["success"] is False
assert response_json["message"] == (
    "Failed to get weights iterator: "
    "qwen/qwen2.5-0.5b-instruct-wrong"
    " (repository not found)."
)
```

```python Example
terminate_process(server_process)
```

## Encode (embedding model)

Encode text into embeddings. Note that this API is only available for [embedding models](./openai_api_embeddings) and will raise an error for generation models.
Therefore, we launch a new server to server an embedding model.

```python Example
embedding_process, port = launch_server_cmd("""
python3 -m sglang.launch_server --model-path Alibaba-NLP/gte-Qwen2-1.5B-instruct \
    --host 0.0.0.0 --is-embedding --log-level warning
""")

wait_for_server(f"http://localhost:{port}", process=embedding_process)
```

```python Example
# successful encode for embedding model

url = f"http://localhost:{port}/encode"
data = {"model": "Alibaba-NLP/gte-Qwen2-1.5B-instruct", "text": "Once upon a time"}

response = requests.post(url, json=data)
response_json = response.json()
print_highlight(f"Text embedding (first 10): {response_json['embedding'][:10]}")
```

```python Example
terminate_process(embedding_process)
```

## v1/rerank (cross encoder rerank model)
Rerank a list of documents given a query using a cross-encoder model. Note that this API is only available for cross encoder model like [BAAI/bge-reranker-v2-m3](https://huggingface.co/BAAI/bge-reranker-v2-m3) with `attention-backend` `triton` and `torch_native`.

```python Example
reranker_process, port = launch_server_cmd("""
python3 -m sglang.launch_server --model-path BAAI/bge-reranker-v2-m3 \
    --host 0.0.0.0 --disable-radix-cache --chunked-prefill-size -1 --attention-backend triton --is-embedding --log-level warning
""")

wait_for_server(f"http://localhost:{port}", process=reranker_process)
```

```python Example
# compute rerank scores for query and documents

url = f"http://localhost:{port}/v1/rerank"
data = {
    "model": "BAAI/bge-reranker-v2-m3",
    "query": "what is panda?",
    "documents": [
        "hi",
        "The giant panda (Ailuropoda melanoleuca), sometimes called a panda bear or simply panda, is a bear species endemic to China.",
    ],
}

response = requests.post(url, json=data)
response_json = response.json()
for item in response_json:
    print_highlight(f"Score: {item['score']:.2f} - Document: '{item['document']}'")
```

```python Example
terminate_process(reranker_process)
```

## v1/score (decoder-only scoring)

Compute token probabilities for specified tokens given a query and items. This is useful for classification tasks, scoring responses, or computing log-probabilities.

Parameters:
- `query`: Query text
- `items`: Item text(s) to score
- `label_token_ids`: Token IDs to compute probabilities for
- `apply_softmax`: Whether to apply softmax to get normalized probabilities (default: False)
- `item_first`: Whether items come first in concatenation order (default: False)
- `model`: Model name

`query` and `items` also accept token ids, with `query` set to `[]` when each item is a complete prompt. `label_token_ids` can be one list per item. `temperature` divides the label logits before the softmax and needs `apply_softmax`, and `return_token_logprobs` adds `token_logprobs`, the full-vocabulary log-probabilities of the labels.

The response contains `scores` - a list of probability lists, one per item, each in the order of `label_token_ids`.

```python Example
score_process, port = launch_server_cmd("""
python3 -m sglang.launch_server --model-path qwen/qwen2.5-0.5b-instruct \
    --host 0.0.0.0 --log-level warning
""")

wait_for_server(f"http://localhost:{port}", process=score_process)
```

```python Example
# Score the probability of different completions given a query
query = "The capital of France is"
items = ["Paris", "London", "Berlin"]

url = f"http://localhost:{port}/v1/score"
data = {
    "model": "qwen/qwen2.5-0.5b-instruct",
    "query": query,
    "items": items,
    "label_token_ids": [9454, 2753],  # e.g. "Yes" and "No" token ids
    "apply_softmax": True,  # Normalize probabilities to sum to 1
}

response = requests.post(url, json=data)
response_json = response.json()

# Display scores for each item
for item, scores in zip(items, response_json["scores"]):
    print_highlight(f"Item '{item}': probabilities = {[f'{s:.4f}' for s in scores]}")
```

```python Example
terminate_process(score_process)
```

## v1/decisions (typed decisions on a chat model)

Answer typed questions about an input with per-option probabilities, without generating. The server renders each question with the model's chat template and thinking turned off, assigns one-token answer labels, and scores them through the same path as `v1/score`.

Parameters:
- `input`: Text, object, or array the questions are about
- `questions`: List of questions, each with a unique `id` and a `type` of `choice` (with `options`), `score` (with `levels`), or `yes_no`
- `temperature`: Divides the label logits before the softmax (default: 1)
- `chat_template_kwargs`: Extra chat template arguments
- `prompt_format_version`: Optional pin of the server-owned prompt wording
- `return_prompt_token_ids`: Return the scored prompt and label token ids for replay through `v1/score` (default: False)

The response contains `answers` keyed by question id, each with `type`, `probabilities`, and `label_mass`, plus `choice` for a choice question or `score` for a score question. A yes or no answer is read from `probabilities["yes"]`. See [Decision models](/docs/supported-models/decision_models) for examples, the full reference, and error cases.

## Classify (reward model)

SGLang Runtime also supports reward models. Here we use a reward model to classify the quality of pairwise generations.

```python Example
# Note that SGLang now treats embedding models and reward models as the same type of models.
# This will be updated in the future.

reward_process, port = launch_server_cmd("""
python3 -m sglang.launch_server --model-path Skywork/Skywork-Reward-Llama-3.1-8B-v0.2 --host 0.0.0.0 --is-embedding --log-level warning
""")

wait_for_server(f"http://localhost:{port}", process=reward_process)
```

```python Example
from transformers import AutoTokenizer

PROMPT = (
    "What is the range of the numeric output of a sigmoid node in a neural network?"
)

RESPONSE1 = "The output of a sigmoid node is bounded between -1 and 1."
RESPONSE2 = "The output of a sigmoid node is bounded between 0 and 1."

CONVS = [
    [{"role": "user", "content": PROMPT}, {"role": "assistant", "content": RESPONSE1}],
    [{"role": "user", "content": PROMPT}, {"role": "assistant", "content": RESPONSE2}],
]

tokenizer = AutoTokenizer.from_pretrained("Skywork/Skywork-Reward-Llama-3.1-8B-v0.2")
prompts = tokenizer.apply_chat_template(CONVS, tokenize=False, return_dict=False)

url = f"http://localhost:{port}/classify"
data = {"model": "Skywork/Skywork-Reward-Llama-3.1-8B-v0.2", "text": prompts}

responses = requests.post(url, json=data).json()
for response in responses:
    print_highlight(f"reward: {response['embedding'][0]}")
```

```python Example
terminate_process(reward_process)
```

## Capture expert selection distribution in MoE models

SGLang Runtime supports recording the number of times an expert is selected in a MoE model run for each expert in the model. This is useful when analyzing the throughput of the model and plan for optimization.

*Note: We only print out the first 10 lines of the csv below for better readability. Please adjust accordingly if you want to analyze the results more deeply.*

```python Example
expert_record_server_process, port = launch_server_cmd(
    "python3 -m sglang.launch_server --model-path Qwen/Qwen1.5-MoE-A2.7B --host 0.0.0.0 --expert-distribution-recorder-mode stat --log-level warning"
)

wait_for_server(f"http://localhost:{port}", process=expert_record_server_process)
```

```python Example
response = requests.post(f"http://localhost:{port}/start_expert_distribution_record")
print_highlight(response)

url = f"http://localhost:{port}/generate"
data = {"text": "What is the capital of France?"}

response = requests.post(url, json=data)
print_highlight(response.json())

response = requests.post(f"http://localhost:{port}/stop_expert_distribution_record")
print_highlight(response)

response = requests.post(f"http://localhost:{port}/dump_expert_distribution_record")
print_highlight(response)
```

```python Example
terminate_process(expert_record_server_process)
```

## Tokenize/Detokenize Example (Round Trip)

This example demonstrates how to use the /tokenize and /detokenize endpoints together. We first tokenize a string, then detokenize the resulting IDs to reconstruct the original text. This workflow is useful when you need to handle tokenization externally but still leverage the server for detokenization.

```python Example
tokenizer_free_server_process, port = launch_server_cmd("""
python3 -m sglang.launch_server --model-path qwen/qwen2.5-0.5b-instruct
""")

wait_for_server(f"http://localhost:{port}", process=tokenizer_free_server_process)
```

```
/* Detailed source-code truncated for AI context efficiency. */
```

```python Example
terminate_process(tokenizer_free_server_process)
```

---

### Docs Basic Usage Offline Engine Api (`docs/docs/basic_usage/offline_engine_api.mdx`)

---
title: "Offline Engine API"
metatags:
    description: "Use SGLang's offline engine for direct batch inference without HTTP server overhead. Supports sync/async and streaming modes."
---
SGLang provides a direct inference engine without the need for an HTTP server, especially for use cases where additional HTTP server adds unnecessary complexity or overhead. Here are two general use cases:

- Offline Batch Inference
- Custom Server on Top of the Engine

This document focuses on the offline batch inference, demonstrating four different inference modes:

- Non-streaming synchronous generation
- Streaming synchronous generation
- Non-streaming asynchronous generation
- Streaming asynchronous generation

Additionally, you can easily build a custom server on top of the SGLang offline engine. A detailed example working in a python script can be found in [custom_server](https://github.com/sgl-project/sglang/blob/main/examples/runtime/engine/custom_server.py).

## Nest Asyncio
Note that if you want to use **Offline Engine** in ipython or some other nested loop code, you need to add the following code:
```python Example
import nest_asyncio

nest_asyncio.apply()

```

## Advanced Usage

The engine supports [vlm inference](https://github.com/sgl-project/sglang/blob/main/examples/runtime/engine/offline_batch_inference_vlm.py) as well as [extracting hidden states](https://github.com/sgl-project/sglang/tree/main/examples/runtime/hidden_states).

Please see [the examples](https://github.com/sgl-project/sglang/tree/main/examples/runtime/engine) for further use cases.

## Offline Batch Inference

SGLang offline engine supports batch inference with efficient scheduling.

```python Example
# launch the offline engine
import asyncio

import sglang as sgl
import sglang.test.doc_patch
from sglang.utils import async_stream_and_merge, stream_and_merge

llm = sgl.Engine(model_path="qwen/qwen2.5-0.5b-instruct")
```

### Non-streaming Synchronous Generation

```python Example
prompts = [
    "Hello, my name is",
    "The president of the United States is",
    "The capital of France is",
    "The future of AI is",
]

sampling_params = {"temperature": 0.8, "top_p": 0.95}

outputs = llm.generate(prompts, sampling_params)
for prompt, output in zip(prompts, outputs):
    print("===============================")
    print(f"Prompt: {prompt}\nGenerated text: {output['text']}")
```

### Streaming Synchronous Generation

```python Example
prompts = [
    "Write a short, neutral self-introduction for a fictional character. Hello, my name is",
    "Provide a concise factual statement about France’s capital city. The capital of France is",
    "Explain possible future trends in artificial intelligence. The future of AI is",
]

sampling_params = {
    "temperature": 0.2,
    "top_p": 0.9,
}

print("\n=== Testing synchronous streaming generation with overlap removal ===\n")

for prompt in prompts:
    print(f"Prompt: {prompt}")
    merged_output = stream_and_merge(llm, prompt, sampling_params)
    print("Generated text:", merged_output)
    print()
```

### Non-streaming Asynchronous Generation

```python Example
prompts = [
    "Write a short, neutral self-introduction for a fictional character. Hello, my name is",
    "Provide a concise factual statement about France’s capital city. The capital of France is",
    "Explain possible future trends in artificial intelligence. The future of AI is",
]

sampling_params = {"temperature": 0.8, "top_p": 0.95}

print("\n=== Testing asynchronous batch generation ===")

async def main():
    outputs = await llm.async_generate(prompts, sampling_params)

    for prompt, output in zip(prompts, outputs):
        print(f"\nPrompt: {prompt}")
        print(f"Generated text: {output['text']}")

asyncio.run(main())
```

### Streaming Asynchronous Generation

```python Example
prompts = [
    "Write a short, neutral self-introduction for a fictional character. Hello, my name is",
    "Provide a concise factual statement about France’s capital city. The capital of France is",
    "Explain possible future trends in artificial intelligence. The future of AI is",
]

sampling_params = {"temperature": 0.8, "top_p": 0.95}

print("\n=== Testing asynchronous streaming generation (no repeats) ===")

async def main():
    for prompt in prompts:
        print(f"\nPrompt: {prompt}")
        print("Generated text: ", end="", flush=True)

        # Replace direct calls to async_generate with our custom overlap-aware version
        async for cleaned_chunk in async_stream_and_merge(llm, prompt, sampling_params):
            print(cleaned_chunk, end="", flush=True)

        print()  # New line after each prompt

asyncio.run(main())
```

```python Example
llm.shutdown()
```

---

### Docs Basic Usage Ollama Api (`docs/docs/basic_usage/ollama_api.mdx`)

---
title: "Ollama-Compatible API"
metatags:
    description: "SGLang provides Ollama API compatibility, allowing you to use the Ollama CLI and Python library with SGLang as the inference backend."
---
SGLang provides Ollama API compatibility, allowing you to use the Ollama CLI and Python library with SGLang as the inference backend.

## Prerequisites

<CodeGroup>
```bash Command
# Install the Ollama Python library (for Python client usage)
pip install ollama
```
</CodeGroup>

<Note>You don't need the Ollama server installed - SGLang acts as the backend. You only need the `ollama` CLI or Python library as the client.</Note>

## Endpoints

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Endpoint</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Method</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`/`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>GET, HEAD</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Health check for Ollama CLI</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`/api/tags`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>GET</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>List available models</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`/api/chat`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>POST</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Chat completions (streaming & non-streaming)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`/api/generate`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>POST</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Text generation (streaming & non-streaming)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>`/api/show`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>POST</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Model information</td>
    </tr>
  </tbody>
</table>

## Quick Start

### 1. Launch SGLang Server

<CodeGroup>
```bash Command
python -m sglang.launch_server \
    --model Qwen/Qwen2.5-1.5B-Instruct \
    --port 30001 \
    --host 0.0.0.0
```
</CodeGroup>

<Note>The model name used with `ollama run` must match exactly what you passed to `--model`.</Note>

### 2. Use Ollama CLI

<CodeGroup>
```bash Command
# List available models
OLLAMA_HOST=http://localhost:30001 ollama list

# Interactive chat
OLLAMA_HOST=http://localhost:30001 ollama run "Qwen/Qwen2.5-1.5B-Instruct"
```
</CodeGroup>

If connecting to a remote server behind a firewall:

<CodeGroup>
```bash Command
# SSH tunnel
ssh -L 30001:localhost:30001 user@gpu-server -N &

# Then use Ollama CLI as above
OLLAMA_HOST=http://localhost:30001 ollama list
```
</CodeGroup>

### 3. Use Ollama Python Library

```python Example
import ollama

client = ollama.Client(host='http://localhost:30001')

# Non-streaming
response = client.chat(
    model='Qwen/Qwen2.5-1.5B-Instruct',
    messages=[{'role': 'user', 'content': 'Hello!'}]
)
print(response['message']['content'])

# Streaming
stream = client.chat(
    model='Qwen/Qwen2.5-1.5B-Instruct',
    messages=[{'role': 'user', 'content': 'Tell me a story'}],
    stream=True
)
for chunk in stream:
    print(chunk['message']['content'], end='', flush=True)
```

## Smart Router

For intelligent routing between local Ollama (fast) and remote SGLang (powerful) using an LLM judge, see the [Smart Router documentation](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/entrypoints/ollama/README.md).

## Summary

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "50%"}} />
    <col style={{width: "50%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Component</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Ollama API**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Familiar CLI/API that developers already know</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**SGLang Backend**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>High-performance inference engine</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>**Smart Router**</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Intelligent routing - fast local for simple tasks, powerful remote for complex tasks</td>
    </tr>
  </tbody>
</table>

---

### Docs Basic Usage Openai Api (`docs/docs/basic_usage/openai_api.mdx`)

---
title: "OpenAI-Compatible APIs"
description: "Documentation for OpenAI-Compatible APIs"
---
- [Openai Api Completions](./openai_api_completions)
- [Openai Api Vision](./openai_api_vision)
- [Openai Api Embeddings](./openai_api_embeddings)

For the Anthropic-compatible `/v1/messages` endpoint (including Claude Code integration), see [Anthropic-Compatible API](./anthropic_api).

---

### Docs Basic Usage Openai Api Completions (`docs/docs/basic_usage/openai_api_completions.mdx`)

---
title: "OpenAI APIs - Completions"
metatags:
    description: "This tutorial covers the following popular APIs: 'chat/completions' and 'completions'"
---
SGLang provides OpenAI-compatible APIs to enable a smooth transition from OpenAI services to self-hosted local models.
A complete reference for the API is available in the [OpenAI API Reference](https://platform.openai.com/docs/api-reference).

This tutorial covers the following popular APIs:

- `chat/completions`
- `completions`

Check out other tutorials to learn about [vision APIs](./openai_api_vision) for vision-language models and [embedding APIs](./openai_api_embeddings) for embedding models.

## Launch A Server

Launch the server in your terminal and wait for it to initialize.

```python Example
from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process

server_process, port = launch_server_cmd(
    "python3 -m sglang.launch_server --model-path qwen/qwen2.5-0.5b-instruct --host 0.0.0.0 --log-level warning"
)

wait_for_server(f"http://localhost:{port}")
print(f"Server started on http://localhost:{port}")
```

## Chat Completions

### Usage

The server fully implements the OpenAI API.
It will automatically apply the chat template specified in the Hugging Face tokenizer, if one is available.
You can also specify a custom chat template with `--chat-template` when launching the server.

```python Example
import openai

client = openai.Client(base_url=f"http://127.0.0.1:{port}/v1", api_key="None")

response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)

print_highlight(f"Response: {response}")
```

### Model Thinking/Reasoning Support

Some models support internal reasoning or thinking processes that can be exposed in the API response. SGLang provides unified support for various reasoning models through the `chat_template_kwargs` parameter and compatible reasoning parsers.

#### Supported Models and Configuration

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
    <col style={{width: "25%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Model Family</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Chat Template Parameter</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Reasoning Parser</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>DeepSeek-R1 (R1, R1-0528, R1-Distill)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`enable_thinking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--reasoning-parser deepseek-r1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Standard reasoning models</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>DeepSeek-V3.1</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`thinking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--reasoning-parser deepseek-v3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Hybrid model (thinking/non-thinking modes)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen3 (standard)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`enable_thinking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--reasoning-parser qwen3`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Hybrid model (thinking/non-thinking modes)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Qwen3-Thinking</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>N/A (always enabled)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--reasoning-parser qwen3-thinking`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Always generates reasoning</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Kimi</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>N/A (always enabled)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--reasoning-parser kimi`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Kimi thinking models</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>Gpt-Oss</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>N/A (always enabled)</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>`--reasoning-parser gpt-oss`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>Gpt-Oss thinking models</td>
    </tr>
  </tbody>
</table>

#### Basic Usage

To use reasoning output:
1. Launch the server with the appropriate reasoning parser.
2. Use the model-specific parameter in `chat_template_kwargs` when you need to override the model's chat-template default.
3. Optionally use `separate_reasoning: False` to keep reasoning in the response content instead of returning it separately (defaults to `True`).

<Note>
**Note for Qwen3-Thinking models:** These models always generate thinking content and do not support the `enable_thinking` parameter. Use `--reasoning-parser qwen3-thinking` or `--reasoning-parser qwen3` to parse the thinking content.
</Note>

#### Example: Qwen3 Models

```python Example
# Launch server:
# python3 -m sglang.launch_server --model Qwen/Qwen3-4B --reasoning-parser qwen3

from openai import OpenAI

client = OpenAI(
    api_key="EMPTY",
    base_url=f"http://127.0.0.1:30000/v1",
)

model = "Qwen/Qwen3-4B"
messages = [{"role": "user", "content": "How many r's are in 'strawberry'?"}]

response = client.chat.completions.create(
    model=model,
    messages=messages,
    extra_body={
        "chat_template_kwargs": {"enable_thinking": True},
        "separate_reasoning": True
    }
)

print("Reasoning:", response.choices[0].message.reasoning_content)
print("-"*100)
print("Answer:", response.choices[0].message.content)
```

**ExampleOutput:**
```text Output
Reasoning: Okay, so the user is asking how many 'r's are in the word 'strawberry'. Let me think. First, I need to make sure I have the word spelled correctly. Strawberry... S-T-R-A-W-B-E-R-R-Y. Wait, is that right? Let me break it down.

Starting with 'strawberry', let's write out the letters one by one. S, T, R, A, W, B, E, R, R, Y. Hmm, wait, that's 10 letters. Let me check again. S (1), T (2), R (3), A (4), W (5), B (6), E (7), R (8), R (9), Y (10). So the letters are S-T-R-A-W-B-E-R-R-Y.
...
Therefore, the answer should be three R's in 'strawberry'. But I need to make sure I'm not counting any other letters as R. Let me check again. S, T, R, A, W, B, E, R, R, Y. No other R's. So three in total. Yeah, that seems right.

----------------------------------------------------------------------------------------------------
Answer: The word "strawberry" contains **three** letters 'r'. Here's the breakdown:

1. **S-T-R-A-W-B-E-R-R-Y**
   - The **third letter** is 'R'.
   - The **eighth and ninth letters** are also 'R's.

Thus, the total count is **3**.

**Answer:** 3.
```
<Note>
Setting `"enable_thinking": False` disables reasoning for Qwen3. Omitting the parameter follows the model's chat-template default; Qwen3 enables thinking by default. Qwen3-Thinking models always generate reasoning content and do not support the `enable_thinking` parameter.
</Note>

#### Set a Default for OpenAI Chat Completions

If most OpenAI chat-completion requests should use the same chat-template mode, set a default when launching the server:

```bash Command
python -m sglang.launch_server \
  --model-path Qwen/Qwen3-4B \
  --reasoning-parser qwen3 \
  --default-chat-template-kwargs '{"enable_thinking": false}'
```

`--default-chat-template-kwargs` accepts a JSON object and merges it into each OpenAI chat-completion request's `chat_template_kwargs`. For ordinary template keys such as `enable_thinking`, the precedence is:

1. An explicit value in the request's `chat_template_kwargs`
2. The value in `--default-chat-template-kwargs`
3. The model's chat-template default

`reasoning_effort` follows a separate normalization path, so the precedence list above does not apply to it. Configure `reasoning_effort` in either the server defaults or individual requests, not both.

The accepted keys are model-specific. For example, Qwen3 uses `enable_thinking`, while other model families may use `thinking` or may not expose a reasoning toggle. The reasoning parser controls how reasoning tokens are separated from the response; it does not by itself enable reasoning in the chat template.

#### Logit Bias Support

SGLang supports the `logit_bias` parameter for both chat completions and completions APIs. This parameter allows you to modify the likelihood of specific tokens being generated by adding bias values to their logits. The bias values can range from -100 to 100, where:

- **Positive values** (0 to 100) increase the likelihood of the token being selected
- **Negative values** (-100 to 0) decrease the likelihood of the token being selected
- **-100** effectively prevents the token from being generated

The `logit_bias` parameter accepts a dictionary where keys are token IDs (as strings) and values are the bias amounts (as floats).

#### Getting Token IDs

To use `logit_bias` effectively, you need to know the token IDs for the words you want to bias. Here's how to get token IDs:

```python Example
# Get tokenizer to find token IDs
import tiktoken

# For OpenAI models, use the appropriate encoding
tokenizer = tiktoken.encoding_for_model("gpt-3.5-turbo")  # or your model

# Get token IDs for specific words
word = "sunny"
token_ids = tokenizer.encode(word)
print(f"Token IDs for '{word}': {token_ids}")

# For SGLang models, you can access the tokenizer through the client
# and get token IDs for bias
```
<Tip>
**Important:** The `logit_bias` parameter uses token IDs as string keys, not the actual words.
</Tip>

#### Example: DeepSeek-V3 Models

DeepSeek-V3 models support thinking mode through the `thinking` parameter:

```python Example
# Launch server:
# python3 -m sglang.launch_server --model deepseek-ai/DeepSeek-V3.1 --tp 8  --reasoning-parser deepseek-v3

from openai import OpenAI

client = OpenAI(
    api_key="EMPTY",
    base_url=f"http://127.0.0.1:30000/v1",
)

model = "deepseek-ai/DeepSeek-V3.1"
messages = [{"role": "user", "content": "How many r's are in 'strawberry'?"}]

response = client.chat.completions.create(
    model=model,
    messages=messages,
    extra_body={
        "chat_template_kwargs": {"thinking": True},
        "separate_reasoning": True
    }
)

print("Reasoning:", response.choices[0].message.reasoning_content)
print("-"*100)
print("Answer:", response.choices[0].message.content)
```

**Example Output:**
```text Output
Reasoning: First, the question is: "How many r's are in 'strawberry'?"

I need to count the number of times the letter 'r' appears in the word "strawberry".

Let me write out the word: S-T-R-A-W-B-E-R-R-Y.

Now, I'll go through each letter and count the 'r's.
...
So, I have three 'r's in "strawberry".

I should double-check. The word is spelled S-T-R-A-W-B-E-R-R-Y. The letters are at positions: 3, 8, and 9 are 'r's. Yes, that's correct.

Therefore, the answer should be 3.
----------------------------------------------------------------------------------------------------
Answer: The word "strawberry" contains **3** instances of the letter "r". Here's a breakdown for clarity:

- The word is spelled: S-T-R-A-W-B-E-R-R-Y
- The "r" appears at the 3rd, 8th, and 9th positions.
```
<Note>
DeepSeek-V3 models use the `thinking` parameter (not `enable_thinking`) to control reasoning output.
</Note>

```python Example
# Example with logit_bias parameter
# Note: You need to get the actual token IDs from your tokenizer
# For demonstration, we'll use some example token IDs
response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[
        {"role": "user", "content": "Complete this sentence: The weather today is"}
    ],
    temperature=0.7,
    max_tokens=20,
    logit_bias={
        "12345": 50,  # Increase likelihood of token ID 12345
        "67890": -50,  # Decrease likelihood of token ID 67890
        "11111": 25,  # Slightly increase likelihood of token ID 11111
    },
)

print_highlight(f"Response with logit bias: {response.choices[0].message.content}")
```

### Parameters

The chat completions API accepts OpenAI Chat Completions API's parameters. Refer to [OpenAI Chat Completions API](https://platform.openai.com/docs/api-reference/chat/create) for more details.

SGLang extends the standard API with the `extra_body` parameter, allowing for additional customization. One key option within `extra_body` is `chat_template_kwargs`, which can be used to pass arguments to the chat template processor.

```python Example
response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[
        {
            "role": "system",
            "content": "You are a knowledgeable historian who provides concise responses.",
        },
        {"role": "user", "content": "Tell me about ancient Rome"},
        {
            "role": "assistant",
            "content": "Ancient Rome was a civilization centered in Italy.",
        },
        {"role": "user", "content": "What were their major achievements?"},
    ],
    temperature=0.3,  # Lower temperature for more focused responses
    max_tokens=128,  # Reasonable length for a concise response
    top_p=0.95,  # Slightly higher for better fluency
    presence_penalty=0.2,  # Mild penalty to avoid repetition
    frequency_penalty=0.2,  # Mild penalty for more natural language
    n=1,  # Single response is usually more stable
    seed=42,  # Keep for reproducibility
)

print_highlight(response.choices[0].message.content)
```

Streaming mode is also supported.

#### Logit Bias Support

The completions API also supports the `logit_bias` parameter with the same functionality as described in the chat completions section above.

```python Example
stream = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[{"role": "user", "content": "Say this is a test"}],
    stream=True,
)
for chunk in stream:
    if chunk.choices[0].delta.content is not None:
        print(chunk.choices[0].delta.content, end="")
```

#### Returning Routed Experts (MoE Models)

For MoE models, set `return_routed_experts: true` in `extra_body` to return expert routing data. Requires `--enable-return-routed-experts` server flag. By default, `routed_experts` is returned in the response-level `sglext` object as base64-encoded int32 expert IDs in a flattened array with logical shape `[num_tokens, num_layers, top_k]`. For non-streaming chat responses with `return_meta_info: true`, `routed_experts` is returned only in each choice's `meta_info` object and omitted from response-level `sglext` to avoid duplicating the routing data. Other requested extension fields, such as `cached_tokens_details` and `spec_tokens_details`, remain in response-level `sglext`. By default, routed experts cover `[0, seqlen - 1)`, the full available sequence, because RL workflows need them for the full sequence. Set `routed_experts_start_len` in `extra_body` to an absolute prefix length to return only `[routed_experts_start_len, seqlen - 1)`. For example, in multi-turn RL rollouts, routed experts for tokens from previous turns have already been collected, so setting this value avoids unnecessary transfer that causes bottlenecks.

#### Returning Flat Output Top Logprobs

With `logprobs: true` and `top_logprobs: k`, set `return_flat_raw_output_top_logprobs: true` and `return_meta_info: true` in `extra_body` to receive the output top logprobs as flat arrays in each choice's `meta_info` instead of nested objects. This skips detokenizing every candidate and shrinks the response, which matters for large `k`. The arrays arrive with the finished response only, so `stream: true` is not supported. `choices[].logprobs` still carries the selected-token logprobs, but its `top_logprobs` lists are empty.

`meta_info` then carries `output_top_logprobs_shape` (`[rows, k]`) and `output_top_logprobs_null_prefix`; covered position `i`, rank `j` sits at flat index `(i - null_prefix) * k + j`. On chat completions the arrays are base64 by default: `output_top_logprobs_{val,idx}_flat_b64`, little-endian bytes whose dtypes are given by the `_dtype` fields (float32 and int32), so non-finite logprobs such as `-inf` survive. Set `return_flat_raw_top_logprobs_b64: false` for plain JSON lists in `output_top_logprobs_{val,idx}_flat`. The native `/generate` API takes the same fields, with base64 off by default.

```python
import base64

import numpy as np

response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[{"role": "user", "content": "Say this is a test"}],
    max_tokens=16,
    logprobs=True,
    top_logprobs=5,
    extra_body={"return_meta_info": True, "return_flat_raw_output_top_logprobs": True},
)
meta = response.choices[0].meta_info
shape = meta["output_top_logprobs_shape"]
val = np.frombuffer(
    base64.b64decode(meta["output_top_logprobs_val_flat_b64"]),
    dtype=meta["output_top_logprobs_val_flat_b64_dtype"],
).reshape(shape)
idx = np.frombuffer(
    base64.b64decode(meta["output_top_logprobs_idx_flat_b64"]),
    dtype=meta["output_top_logprobs_idx_flat_b64_dtype"],
).reshape(shape)
```

```python Example
# Example with logit_bias parameter for completions API
# Note: You need to get the actual token IDs from your tokenizer
# For demonstration, we'll use some example token IDs
response = client.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    prompt="The best programming language for AI is",
    temperature=0.7,
    max_tokens=20,
    logit_bias={
        "12345": 75,  # Strongly favor token ID 12345
        "67890": -100,  # Completely avoid token ID 67890
        "11111": -25,  # Slightly discourage token ID 11111
    },
)

print_highlight(f"Response with logit bias: {response.choices[0].text}")
```

## Completions

### Usage
Completions API is similar to Chat Completions API, but without the `messages` parameter or chat templates.

```python Example
response = client.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    prompt="List 3 countries and their capitals.",
    temperature=0,
    max_tokens=64,
    n=1,
    stop=None,
)

print_highlight(f"Response: {response}")
```

### Parameters

The completions API accepts OpenAI Completions API's parameters.  Refer to [OpenAI Completions API](https://platform.openai.com/docs/api-reference/completions/create) for more details.

Here is an example of a detailed completions request:

```python Example
response = client.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    prompt="Write a short story about a space explorer.",
    temperature=0.7,  # Moderate temperature for creative writing
    max_tokens=150,  # Longer response for a story
    top_p=0.9,  # Balanced diversity in word choice
    stop=["\n\n", "THE END"],  # Multiple stop sequences
    presence_penalty=0.3,  # Encourage novel elements
    frequency_penalty=0.3,  # Reduce repetitive phrases
    n=1,  # Generate one completion
    seed=123,  # For reproducible results
)

print_highlight(f"Response: {response}")
```

#### Returning Routed Experts (MoE Models)

For MoE models, set `return_routed_experts: true` in `extra_body` to return expert routing data. Requires `--enable-return-routed-experts` server flag. The `routed_experts` field will be returned in the `sgl_ext` object on each choice, containing base64-encoded int32 expert IDs as a flattened array with logical shape `[num_tokens, num_layers, top_k]`. By default this returns `[0, seqlen - 1)`, the full available sequence, because RL workflows need routed experts for the full sequence. Set `routed_experts_start_len` in `extra_body` to an absolute prefix length to return only `[routed_experts_start_len, seqlen - 1)`. For example, in multi-turn RL rollouts, routed experts for tokens from previous turns have already been collected, so setting this value avoids unnecessary transfer that cause bottlenecks.

## Structured Outputs (JSON, Regex, EBNF)

For OpenAI compatible structured outputs API, refer to [Structured Outputs](../advanced_features/structured_outputs) for more details.

## Using LoRA Adapters

SGLang supports LoRA (Low-Rank Adaptation) adapters with OpenAI-compatible APIs. You can specify which adapter to use directly in the `model` parameter using the `base-model:adapter-name` syntax.

**Server Setup:**
```bash Command
python -m sglang.launch_server \
    --model-path qwen/qwen2.5-0.5b-instruct \
    --enable-lora \
    --lora-paths adapter_a=/path/to/adapter_a adapter_b=/path/to/adapter_b
```

For more details on LoRA serving configuration, see the [LoRA documentation](../advanced_features/lora).

**API Call:**

(Recommended) Use the `model:adapter` syntax to specify which adapter to use:
```python Example
response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct:adapter_a",  # ← base-model:adapter-name
    messages=[{"role": "user", "content": "Convert to SQL: show all users"}],
    max_tokens=50,
)
```

**Backward Compatible: Using `extra_body`**

The old `extra_body` method is still supported for backward compatibility:
```python Example
# Backward compatible method
response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[{"role": "user", "content": "Convert to SQL: show all users"}],
    extra_body={"lora_path": "adapter_a"},  # ← old method
    max_tokens=50,
)
```
**Note:** When both `model:adapter` and `extra_body["lora_path"]` are specified, the `model:adapter` syntax takes precedence.

```python Example
terminate_process(server_process)
```

---

### Docs Basic Usage Openai Api Embeddings (`docs/docs/basic_usage/openai_api_embeddings.mdx`)

---
title: "OpenAI APIs - Embedding"
metatags:
    description: "This tutorial covers the embedding APIs for embedding models."
---
SGLang provides OpenAI-compatible APIs to enable a smooth transition from OpenAI services to self-hosted local models.
A complete reference for the API is available in the [OpenAI API Reference](https://platform.openai.com/docs/guides/embeddings).

This tutorial covers the embedding APIs for embedding models. For a list of the supported models see the [corresponding overview page](../supported-models)


## Launch A Server

Launch the server in your terminal and wait for it to initialize. Native encoder embedding architectures and `google/embeddinggemma-300m` are detected automatically. Decoder-style embedding models still require `--is-embedding`.


```python Example
from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process

embedding_process, port = launch_server_cmd(
    """
sglang serve --model-path Alibaba-NLP/gte-Qwen2-1.5B-instruct \
    --is-embedding --log-level warning
"""
)

wait_for_server(f"http://localhost:{port}")
```

## Using cURL


```python Example
import subprocess, json

text = "Once upon a time"

curl_text = f"""curl -s http://localhost:{port}/v1/embeddings \
  -H "Content-Type: application/json" \
  -d '{{"model": "Alibaba-NLP/gte-Qwen2-1.5B-instruct", "input": "{text}"}}'"""

result = subprocess.check_output(curl_text, shell=True)

print(result)

text_embedding = json.loads(result)["data"][0]["embedding"]

print_highlight(f"Text embedding (first 10): {text_embedding[:10]}")
```

## Using Python Requests


```python Example
import requests

text = "Once upon a time"

response = requests.post(
    f"http://localhost:{port}/v1/embeddings",
    json={"model": "Alibaba-NLP/gte-Qwen2-1.5B-instruct", "input": text},
)

text_embedding = response.json()["data"][0]["embedding"]

print_highlight(f"Text embedding (first 10): {text_embedding[:10]}")
```

## Using OpenAI Python Client


```python Example
import openai

client = openai.Client(base_url=f"http://127.0.0.1:{port}/v1", api_key="None")

# Text embedding example
response = client.embeddings.create(
    model="Alibaba-NLP/gte-Qwen2-1.5B-instruct",
    input=text,
)

embedding = response.data[0].embedding[:10]
print_highlight(f"Text embedding (first 10): {embedding}")
```

## Using Input IDs

SGLang also supports `input_ids` as input to get the embedding.


```python Example
import json
import os
from transformers import AutoTokenizer

os.environ["TOKENIZERS_PARALLELISM"] = "false"

tokenizer = AutoTokenizer.from_pretrained("Alibaba-NLP/gte-Qwen2-1.5B-instruct")
input_ids = tokenizer.encode(text)

curl_ids = f"""curl -s http://localhost:{port}/v1/embeddings \
  -H "Content-Type: application/json" \
  -d '{{"model": "Alibaba-NLP/gte-Qwen2-1.5B-instruct", "input": {json.dumps(input_ids)}}}'"""

input_ids_embedding = json.loads(subprocess.check_output(curl_ids, shell=True))["data"][
    0
]["embedding"]

print_highlight(f"Input IDs embedding (first 10): {input_ids_embedding[:10]}")
```

## Compact Base64 Responses

Set `encoding_format` to `base64` when JSON arrays would dominate response size. The encoded value contains little-endian FP32 values and can be decoded by OpenAI-compatible clients.

```python Example
response = requests.post(
    f"http://localhost:{port}/v1/embeddings",
    json={
        "model": "Alibaba-NLP/gte-Qwen2-1.5B-instruct",
        "input": text,
        "encoding_format": "base64",
    },
)

base64_embedding = response.json()["data"][0]["embedding"]
print_highlight(f"Base64 embedding: {base64_embedding[:20]}...")
```


```python Example
terminate_process(embedding_process)
```

## Multi-Modal Embedding Model
Please refer to [Multi-Modal Embedding Model](../supported-models)

---

### Docs Basic Usage Openai Api Vision (`docs/docs/basic_usage/openai_api_vision.mdx`)

---
title: "OpenAI APIs - Vision"
metatags:
    description: "This tutorial covers the vision APIs for vision language models."
---
SGLang provides OpenAI-compatible APIs to enable a smooth transition from OpenAI services to self-hosted local models.
A complete reference for the API is available in the [OpenAI API Reference](https://platform.openai.com/docs/guides/vision).
This tutorial covers the vision APIs for vision language models.

SGLang supports various vision language models such as Llama 3.2, LLaVA-OneVision, Qwen2.5-VL, Gemma3 and [more](../supported-models/multimodal_language_models).

As an alternative to the OpenAI API, you can also use the [SGLang offline engine](https://github.com/sgl-project/sglang/blob/main/examples/runtime/engine/offline_batch_inference_vlm.py).

## Launch A Server

Launch the server in your terminal and wait for it to initialize.

```python Example
from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, print_highlight, terminate_process

example_image_url = "https://raw.githubusercontent.com/sgl-project/sglang/main/examples/assets/example_image.png"
logo_image_url = (
    "https://raw.githubusercontent.com/sgl-project/sglang/main/assets/logo.png"
)

vision_process, port = launch_server_cmd("""
python3 -m sglang.launch_server --model-path Qwen/Qwen2.5-VL-7B-Instruct --log-level warning
""")

wait_for_server(f"http://localhost:{port}", process=vision_process)
```

## Using cURL

Once the server is up, you can send test requests using curl or requests.

```python Example
import subprocess

curl_command = f"""
curl -s http://localhost:{port}/v1/chat/completions \\
  -H "Content-Type: application/json" \\
  -d '{{
    "model": "Qwen/Qwen2.5-VL-7B-Instruct",
    "messages": [
      {{
        "role": "user",
        "content": [
          {{
            "type": "text",
            "text": "What’s in this image?"
          }},
          {{
            "type": "image_url",
            "image_url": {{
              "url": "{example_image_url}"
            }}
          }}
        ]
      }}
    ],
    "max_tokens": 300
  }}'
"""

response = subprocess.check_output(curl_command, shell=True).decode()
print_highlight(response)


response = subprocess.check_output(curl_command, shell=True).decode()
print_highlight(response)
```

## Using Python Requests

```python Example
import requests

url = f"http://localhost:{port}/v1/chat/completions"

data = {
    "model": "Qwen/Qwen2.5-VL-7B-Instruct",
    "messages": [
        {
            "role": "user",
            "content": [
                {"type": "text", "text": "What’s in this image?"},
                {
                    "type": "image_url",
                    "image_url": {"url": example_image_url},
                },
            ],
        }
    ],
    "max_tokens": 300,
}

response = requests.post(url, json=data)
print_highlight(response.text)
```

## Using OpenAI Python Client

```python Example
from openai import OpenAI

client = OpenAI(base_url=f"http://localhost:{port}/v1", api_key="None")

response = client.chat.completions.create(
    model="Qwen/Qwen2.5-VL-7B-Instruct",
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "text",
                    "text": "What is in this image?",
                },
                {
                    "type": "image_url",
                    "image_url": {"url": example_image_url},
                },
            ],
        }
    ],
    max_tokens=300,
)

print_highlight(response.choices[0].message.content)
```

## Multiple-Image Inputs

The server also supports multiple images and interleaved text and images if the model supports it.

```python Example
from openai import OpenAI

client = OpenAI(base_url=f"http://localhost:{port}/v1", api_key="None")

response = client.chat.completions.create(
    model="Qwen/Qwen2.5-VL-7B-Instruct",
    messages=[
        {
            "role": "user",
            "content": [
                {
                    "type": "image_url",
                    "image_url": {
                        "url": example_image_url,
                    },
                },
                {
                    "type": "image_url",
                    "image_url": {
                        "url": logo_image_url,
                    },
                },
                {
                    "type": "text",
                    "text": "I have two very different images. They are not related at all. "
                    "Please describe the first image in one sentence, and then describe the second image in another sentence.",
                },
            ],
        }
    ],
    temperature=0,
)

print_highlight(response.choices[0].message.content)
```

```python Example
terminate_process(vision_process)
```

---

### Docs Basic Usage Sampling Params (`docs/docs/basic_usage/sampling_params.mdx`)

---
title: "Sampling Parameters"
metatags:
    description: "Complete reference for SGLang sampling parameters: temperature, top_p, top_k, frequency penalty, stop tokens, and more."
---
This doc describes the sampling parameters of the SGLang Runtime. It is the low-level endpoint of the runtime.
If you want a high-level endpoint that can automatically handle chat templates, consider using the [OpenAI Compatible API](./openai_api_completions).

## `/generate` Endpoint

The `/generate` endpoint accepts the following parameters in JSON format. For detailed usage, see the [native API doc](./native_api). The object is defined at `io_struct.py::GenerateReqInput`. You can also read the source code to find more arguments and docs.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type/Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>text</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[str], str]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The input prompt. Can be a single prompt or a batch of prompts.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>input_ids</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[List[int]], List[int]]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The token IDs for text; one can specify either text or input_ids.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>input_embeds</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[List[List[float]]], List[List[float]]]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The embeddings for input_ids; one can specify either text, input_ids, or input_embeds.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>image_data</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[List[ImageDataItem]], List[ImageDataItem], ImageDataItem]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The image input. Supports three formats: (1) **Raw images**: PIL Image, file path, URL, or base64 string; (2) **Processor output**: Dict with `format: "processor_output"` containing HuggingFace processor outputs; (3) **Precomputed embeddings**: Dict with `format: "precomputed_embedding"` and `feature` containing pre-calculated visual embeddings. Can be a single image, list of images, or list of lists of images. See [Multimodal Input Formats](#multimodal) for details.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>audio_data</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[AudioDataItem], AudioDataItem]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The audio input. Can be a file name, URL, or base64 encoded string.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>sampling_params</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[Dict], Dict]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The sampling parameters as described in the sections below.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>rid</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[str], str]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The request ID.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>return_logprob</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[bool], bool]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Whether to return log probabilities for tokens.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>logprob_start_len</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[int], int]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>If return_logprob, the start location in the prompt for returning logprobs. Default is "-1", which returns logprobs for output tokens only.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>top_logprobs_num</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[int], int]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>If return_logprob, the number of top logprobs to return at each position.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>token_ids_logprob</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[List[int]], List[int]]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>If return_logprob, the token IDs to return logprob for.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>return_text_in_logprobs</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`bool = False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Whether to detokenize tokens in text in the returned logprobs.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>stream</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`bool = False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Whether to stream output.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>lora_path</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[Optional[str]], Optional[str]]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The path to the LoRA.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>custom_logit_processor</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[List[Optional[str]], str]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Custom logit processor for advanced sampling control. Must be a serialized instance of `CustomLogitProcessor` using its `to_str()` method. For usage see below.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>return_hidden_states</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Union[List[bool], bool] = False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Whether to return hidden states.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>return_routed_experts</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`bool = False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Whether to return routed experts for MoE models. Requires `--enable-return-routed-experts` server flag. With the default `routed_experts_start_len=0`, returns the full available sequence `[0, seqlen - 1)` because RL workflows need routed experts for the full sequence. The result is base64-encoded int32 expert IDs as a flattened array with logical shape `[num_tokens, num_layers, top_k]`.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>routed_experts_start_len</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`int = 0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>If `return_routed_experts`, the absolute start position for returned routed-experts rows. `0` preserves the default full sequence; set it to an accumulated prefix length to return only `[routed_experts_start_len, seqlen - 1)`. For example, in multi-turn RL rollouts, routed experts for tokens from previous turns have already been collected, so setting this value avoids unnecessary transfer that cause bottlenecks. Must be in `[0, prompt_tokens]`.</td>
    </tr>
  </tbody>
</table>

## Sampling parameters

The object is defined at `sampling_params.py::SamplingParams`. You can also read the source code to find more arguments and docs.

### Note on defaults

By default, SGLang initializes several sampling parameters from the model's `generation_config.json` (when the server is launched with `--sampling-defaults model`, which is the default). To use SGLang/OpenAI constant defaults instead, start the server with `--sampling-defaults openai`. You can always override any parameter per request via `sampling_params`.

```bash Command
# Use model-provided defaults from generation_config.json (default behavior)
python -m sglang.launch_server --model-path <MODEL> --sampling-defaults model

# Use SGLang/OpenAI constant defaults instead
python -m sglang.launch_server --model-path <MODEL> --sampling-defaults openai
```

### Core parameters

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type/Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>max_new_tokens</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`int = 128`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The maximum output length measured in tokens.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>stop</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[str, List[str]]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>One or multiple [stop words](https://platform.openai.com/docs/api-reference/chat/create#chat-create-stop). Generation will stop if one of these words is sampled.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>stop_token_ids</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[List[int]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Provide stop words in the form of token IDs. Generation will stop if one of these token IDs is sampled.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>stop_regex</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[Union[str, List[str]]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Stop when hitting any of the regex patterns in this list</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>temperature</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`float (model default; fallback 1.0)`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>[Temperature](https://platform.openai.com/docs/api-reference/chat/create#chat-create-temperature) when sampling the next token. `temperature = 0` corresponds to greedy sampling, a higher temperature leads to more diversity.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>top_p</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`float (model default; fallback 1.0)`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>[Top-p](https://platform.openai.com/docs/api-reference/chat/create#chat-create-top_p) selects tokens from the smallest sorted set whose cumulative probability exceeds `top_p`. When `top_p = 1`, this reduces to unrestricted sampling from all tokens.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>top_k</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`int (model default; fallback -1)`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>[Top-k](https://developer.nvidia.com/blog/how-to-get-better-outputs-from-your-large-language-model/#predictability_vs_creativity) randomly selects from the `k` highest-probability tokens.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>min_p</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`float (model default; fallback 0.0)`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>[Min-p](https://github.com/huggingface/transformers/issues/27670) samples from tokens with probability larger than `min_p * highest_token_probability`.</td>
    </tr>
  </tbody>
</table>

### Penalizers

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type/Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>frequency_penalty</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`float = 0.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Penalizes tokens based on their frequency in generation so far. Must be between `-2` and `2` where negative numbers encourage repeatment of tokens and positive number encourages sampling of new tokens. The scaling of penalization grows linearly with each appearance of a token.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>presence_penalty</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`float = 0.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Penalizes tokens if they appeared in the generation so far. Must be between `-2` and `2` where negative numbers encourage repeatment of tokens and positive number encourages sampling of new tokens. The scaling of the penalization is constant if a token occurred.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>repetition_penalty</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`float = 1.0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Scales the logits of previously generated tokens to discourage (values > 1) or encourage (values < 1) repetition. Valid range is `(0, 2]`; `1.0` leaves probabilities unchanged.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>min_new_tokens</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`int = 0`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Forces the model to generate at least `min_new_tokens` until a stop word or EOS token is sampled. Note that this might lead to unintended behavior, for example, if the distribution is highly skewed towards these tokens.</td>
    </tr>
  </tbody>
</table>

### Constrained decoding

Please refer to our dedicated guide on [constrained decoding](../advanced_features/structured_outputs) for the following parameters.

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type/Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>json_schema</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[str] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>JSON schema for structured outputs.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>regex</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[str] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Regex for structured outputs.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>ebnf</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[str] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>EBNF for structured outputs.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>structural_tag</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[str] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>The structal tag for structured outputs.</td>
    </tr>
  </tbody>
</table>

### Other options

<table style={{width: "100%", borderCollapse: "collapse", tableLayout: "fixed"}}>
  <colgroup>
    <col style={{width: "34%"}} />
    <col style={{width: "33%"}} />
    <col style={{width: "33%"}} />
  </colgroup>
  <thead>
    <tr style={{borderBottom: "2px solid #d55816"}}>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Argument</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.05)"}}>Type/Default</th>
      <th style={{textAlign: "left", padding: "10px 12px", fontWeight: 700, whiteSpace: "nowrap", backgroundColor: "rgba(255,255,255,0.02)"}}>Description</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>n</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`int = 1`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Specifies the number of output sequences to generate per request. (Generating multiple outputs in one request (n > 1) is discouraged; repeating the same prompts several times offers better control and efficiency.)</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>ignore_eos</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`bool = False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Don't stop generation when EOS token is sampled.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>skip_special_tokens</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`bool = True`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Remove special tokens during decoding.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>spaces_between_special_tokens</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`bool = True`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Whether or not to add spaces between special tokens during detokenization.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>no_stop_trim</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`bool = False`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Don't trim stop words or EOS token from the generated text.</td>
    </tr>
    <tr>
      <td style={{padding: "9px 12px", fontWeight: 500, backgroundColor: "rgba(255,255,255,0.02)"}}>custom_params</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.05)"}}>`Optional[List[Optional[Dict[str, Any]]]] = None`</td>
      <td style={{padding: "9px 12px", backgroundColor: "rgba(255,255,255,0.02)"}}>Used when employing `CustomLogitProcessor`. For usage, see below.</td>
    </tr>
  </tbody>
</table>

## Examples

### Normal

Launch a server:

```bash Command
python -m sglang.launch_server --model-path meta-llama/Meta-Llama-3-8B-Instruct --port 30000
```

Send a request:

```python Example
import requests

response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "The capital of France is",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 32,
        },
    },
)
print(response.json())
```

Detailed example in [send request](./send_request).

### Streaming

Send a request and stream the output:

```python Example
import requests, json

response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "The capital of France is",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 32,
        },
        "stream": True,
    },
    stream=True,
)

prev = 0
for chunk in response.iter_lines(decode_unicode=False):
    chunk = chunk.decode("utf-8")
    if chunk and chunk.startswith("data:"):
        if chunk == "data: [DONE]":
            break
        data = json.loads(chunk[5:].strip("\n"))
        output = data["text"].strip()
        print(output[prev:], end="", flush=True)
        prev = len(output)
print("")
```

Detailed example in [openai compatible api](./openai_api_completions).

### Multimodal

Launch a server:

```bash Command
python3 -m sglang.launch_server --model-path lmms-lab/llava-onevision-qwen2-7b-ov
```

Download an image:

```bash Command
curl -o example_image.png -L https://github.com/sgl-project/sglang/blob/main/examples/assets/example_image.png?raw=true
```

Send a request:

```python Example
import requests

response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n"
                "<|im_start|>user\n<image>\nDescribe this image in a very short sentence.<|im_end|>\n"
                "<|im_start|>assistant\n",
        "image_data": "example_image.png",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 32,
        },
    },
)
print(response.json())
```

The `image_data` can be a file name, a URL, or a base64 encoded string. See also `python/sglang/srt/utils.py:load_image`.

Streaming is supported in a similar manner as [above](#streaming).

Detailed example in [OpenAI API Vision](./openai_api_vision).

### Structured Outputs (JSON, Regex, EBNF)

You can specify a JSON schema, regular expression or [EBNF](https://en.wikipedia.org/wiki/Extended_Backus%E2%80%93Naur_form) to constrain the model output. The model output will be guaranteed to follow the given constraints. Only one constraint parameter (`json_schema`, `regex`, or `ebnf`) can be specified for a request.

SGLang supports two grammar backends:

- [XGrammar](https://github.com/mlc-ai/xgrammar) (default): Supports JSON schema, regular expression, and EBNF constraints.
  - XGrammar currently uses the [GGML BNF format](https://github.com/ggml-org/llama.cpp/blob/master/grammars/README.md).
- [Outlines](https://github.com/dottxt-ai/outlines): Supports JSON schema and regular expression constraints.

If instead you want to initialize the Outlines backend, you can use `--grammar-backend outlines` flag:

```bash Command
python -m sglang.launch_server --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
--port 30000 --host 0.0.0.0 --grammar-backend [xgrammar|outlines] # xgrammar or outlines (default: xgrammar)
```

```python Example
import json
import requests

json_schema = json.dumps({
    "type": "object",
    "properties": {
        "name": {"type": "string", "pattern": "^[\\w]+$"},
        "population": {"type": "integer"},
    },
    "required": ["name", "population"],
})

# JSON (works with both Outlines and XGrammar)
response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "Here is the information of the capital of France in the JSON format.\n",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 64,
            "json_schema": json_schema,
        },
    },
)
print(response.json())

# Regular expression (Outlines backend only)
response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "Paris is the capital of",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 64,
            "regex": "(France|England)",
        },
    },
)
print(response.json())

# EBNF (XGrammar backend only)
response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "Write a greeting.",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 64,
            "ebnf": 'root ::= "Hello" | "Hi" | "Hey"',
        },
    },
)
print(response.json())
```

Detailed example in [structured outputs](../advanced_features/structured_outputs).

### Custom logit processor

Launch a server with `--enable-custom-logit-processor` flag on.

```bash Command
python -m sglang.launch_server \
  --model-path meta-llama/Meta-Llama-3-8B-Instruct \
  --port 30000 \
  --enable-custom-logit-processor
```

Define a custom logit processor that will always sample a specific token id.

```python Example
from sglang.srt.sampling.custom_logit_processor import CustomLogitProcessor

class DeterministicLogitProcessor(CustomLogitProcessor):
    """A dummy logit processor that changes the logits to always
    sample the given token id.
    """

    def __call__(self, logits, custom_param_list):
        # Check that the number of logits matches the number of custom parameters
        assert logits.shape[0] == len(custom_param_list)
        key = "token_id"

        for i, param_dict in enumerate(custom_param_list):
            # Mask all other tokens
            logits[i, :] = -float("inf")
            # Assign highest probability to the specified token
            logits[i, param_dict[key]] = 0.0
        return logits
```

Send a request:

```python Example
import requests

response = requests.post(
    "http://localhost:30000/generate",
    json={
        "text": "The capital of France is",
        "custom_logit_processor": DeterministicLogitProcessor().to_str(),
        "sampling_params": {
            "temperature": 0.0,
            "max_new_tokens": 32,
            "custom_params": {"token_id": 5},
        },
    },
)
print(response.json())
```

Send an OpenAI chat completion request:

```python Example
import openai
from sglang.utils import print_highlight

client = openai.Client(base_url="http://127.0.0.1:30000/v1", api_key="None")

response = client.chat.completions.create(
    model="meta-llama/Meta-Llama-3-8B-Instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0.0,
    max_tokens=32,
    extra_body={
        "custom_logit_processor": DeterministicLogitProcessor().to_str(),
        "custom_params": {"token_id": 5},
    },
)

print_highlight(f"Response: {response}")
```

---

### Docs Basic Usage Send Request (`docs/docs/basic_usage/send_request.mdx`)

---
title: "Tutorial: Sending a request"
metatags:
    description: "This notebook provides a quick-start guide to use SGLang in chat completions after installation. "
---
This notebook provides a quick-start guide to use SGLang in chat completions after installation. Once your server is running, API documentation is available at `http://localhost:30000/docs` (Swagger UI), `http://localhost:30000/redoc` (ReDoc), or `http://localhost:30000/openapi.json` (OpenAPI spec, useful for AI agents). Replace `30000` with your port if using a different one.

- For Vision Language Models, see [OpenAI APIs - Vision](./openai_api_vision).
- For Embedding Models, see [OpenAI APIs - Embedding](./openai_api_embeddings) and [Encode (embedding model)](./native_api#encode-embedding-model).
- For Reward Models, see [Classify (reward model)](./native_api#classify-reward-model).


## Launch A Server


```python Example
from sglang.test.doc_patch import launch_server_cmd
from sglang.utils import wait_for_server, terminate_process

# This is equivalent to running the following command in your terminal
# python3 -m sglang.launch_server --model-path qwen/qwen2.5-0.5b-instruct --host 0.0.0.0

server_process, port = launch_server_cmd(
    """
python3 -m sglang.launch_server --model-path qwen/qwen2.5-0.5b-instruct \
 --host 0.0.0.0 --log-level warning
"""
)

wait_for_server(f"http://localhost:{port}")
```

## Using cURL


```python Example
import subprocess, json

curl_command = f"""
curl -s http://localhost:{port}/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{{"model": "qwen/qwen2.5-0.5b-instruct", "messages": [{{"role": "user", "content": "What is the capital of France?"}}]}}'
"""

response = json.loads(subprocess.check_output(curl_command, shell=True))
print(response)
```

## Using Python Requests


```python Example
import requests

url = f"http://localhost:{port}/v1/chat/completions"

data = {
    "model": "qwen/qwen2.5-0.5b-instruct",
    "messages": [{"role": "user", "content": "What is the capital of France?"}],
}

response = requests.post(url, json=data)
print(response.json())
```

## Using OpenAI Python Client


```python Example
import openai

client = openai.Client(base_url=f"http://127.0.0.1:{port}/v1", api_key="None")

response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
)
print(response)
```

### Streaming


```python Example
import openai

client = openai.Client(base_url=f"http://127.0.0.1:{port}/v1", api_key="None")

# Use stream=True for streaming responses
response = client.chat.completions.create(
    model="qwen/qwen2.5-0.5b-instruct",
    messages=[
        {"role": "user", "content": "List 3 countries and their capitals."},
    ],
    temperature=0,
    max_tokens=64,
    stream=True,
)

# Handle the streaming output
for chunk in response:
    if chunk.choices[0].delta.content:
        print(chunk.choices[0].delta.content, end="", flush=True)
```

## Using Native Generation APIs

You can also use the native `/generate` endpoint with requests, which provides more flexibility. An API reference is available at [Sampling Parameters](./sampling_params).


```python Example
import requests

response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": "The capital of France is",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 32,
        },
    },
)

print(response.json())
```
### Streaming


```python Example
import requests, json

response = requests.post(
    f"http://localhost:{port}/generate",
    json={
        "text": "The capital of France is",
        "sampling_params": {
            "temperature": 0,
            "max_new_tokens": 32,
        },
        "stream": True,
    },
    stream=True,
)

prev = 0
for chunk in response.iter_lines(decode_unicode=False):
    chunk = chunk.decode("utf-8")
    if chunk and chunk.startswith("data:"):
        if chunk == "data: [DONE]":
            break
        data = json.loads(chunk[5:].strip("\n"))
        output = data["text"]
        print(output[prev:], end="", flush=True)
        prev = len(output)
```

```python Example
terminate_process(server_process)
```

---

### Docs Developer Guide Bench Serving (`docs/docs/developer_guide/bench_serving.mdx`)

---
title: "Bench Serving Guide"
metatags:
    description: "SGLang bench_serving: benchmark throughput, TTFT, ITL with random/sharegpt/image datasets. Multi-backend support."
---
This guide explains how to benchmark online serving throughput and latency using `python -m sglang.bench_serving`. It supports multiple inference backends via OpenAI-compatible and native endpoints, and produces both console metrics and optional JSONL outputs.

### What it does

- Generates synthetic or dataset-driven prompts and submits them to a target serving endpoint
- Measures throughput, time-to-first-token (TTFT), inter-token latency (ITL), per-request end-to-end latency, and more
- Supports streaming or non-streaming modes, rate control, and concurrency limits

### Supported backends and endpoints

- `sglang` / `sglang-native`: `POST /generate`
- `sglang-oai`, `vllm`, `lmdeploy`: `POST /v1/completions`
- `sglang-oai-chat`, `vllm-chat`, `lmdeploy-chat`: `POST /v1/chat/completions`
- `sglang-embedding`, `vllm-embedding`: `POST /v1/embeddings`
- `trt` (TensorRT-LLM): `POST /v2/models/ensemble/generate_stream`
- `gserver`: Custom server (Not Implemented yet in this script)
- `truss`: `POST /v1/models/model:predict`

If `--base-url` is provided, requests are sent to it. Otherwise, `--host` and `--port` are used. When `--model` is not provided, the script will attempt to query `GET /v1/models` for an available model ID (OpenAI-compatible endpoints).

### Prerequisites

- Python 3.11+
- Dependencies typically used by this script: `aiohttp`, `numpy`, `requests`, `tqdm`, `transformers`, and for some datasets `datasets`, `pillow`, `pybase64`. Install as needed.
- An inference server running and reachable via the endpoints above
- If your server requires authentication, set environment variable `OPENAI_API_KEY` (used as `Authorization: Bearer <key>`)

### Quick start

Run a basic benchmark against an sglang server exposing `/generate`:

```bash Command
python3 -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct
```

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --num-prompts 1000 \
  --model meta-llama/Llama-3.1-8B-Instruct
```

Or, using an OpenAI-compatible endpoint (completions):

```bash Command
python3 -m sglang.bench_serving \
  --backend vllm \
  --base-url http://127.0.0.1:8000 \
  --num-prompts 1000 \
  --model meta-llama/Llama-3.1-8B-Instruct
```

### Fair embedding comparison

Use the two embedding backends with the same model, tokenizer, input length, prompt count, and concurrency. The benchmark reports input-token throughput and end-to-end latency; embeddings have no decode-side TTFT or TPOT.

```bash Command
# Start either server on the same hardware and precision, then run one at a time.
python3 -m sglang.bench_serving \
  --backend sglang-embedding \
  --model google/embeddinggemma-300m \
  --dataset-name random \
  --random-input-len 2048 \
  --num-prompts 300 \
  --max-concurrency 64 \
  --warmup-requests 3 \
  --flush-cache
```

```bash Command
# vLLM's cache reset endpoint requires VLLM_SERVER_DEV_MODE=1 at server startup.
python3 -m sglang.bench_serving \
  --backend vllm-embedding \
  --model google/embeddinggemma-300m \
  --dataset-name random \
  --random-input-len 2048 \
  --num-prompts 300 \
  --max-concurrency 64 \
  --warmup-requests 3 \
  --flush-cache
```

`--flush-cache` calls `/flush_cache` for SGLang and `/reset_prefix_cache` for vLLM after warmup. For vLLM, start the server with `VLLM_SERVER_DEV_MODE=1`; without it the benchmark fails loudly rather than accidentally measuring warm-cache performance.

### Datasets

Select with `--dataset-name`:

- `sharegpt` (default): loads ShareGPT-style pairs; optionally restrict with `--sharegpt-context-len` and override outputs with `--sharegpt-output-len`
- `random`: random text lengths; sampled from ShareGPT token space
- `random-ids`: random token ids (can lead to gibberish)
- `image`: generates images and wraps them in chat messages; supports custom resolutions, multiple formats, and different content types
- `generated-shared-prefix`: synthetic dataset with shared long system prompts and short questions
- `mmmu`: samples from MMMU (Math split) and includes images
- `speed-bench`: [SPEED-Bench](https://huggingface.co/datasets/nvidia/SPEED-Bench) (**SPEculative Evaluation Dataset**) — a unified benchmark for evaluating [Speculative Decoding (SD)](https://arxiv.org/abs/2604.09557) algorithms. Uses the Throughput split, which provides fixed-length input sequences (1K–32K tokens) grouped into three output-entropy categories (`low_entropy`, `mixed`, `high_entropy`). Requires a pre-downloaded JSONL file passed via `--dataset-path`.
- `agentic-trace`: replays pre-built multi-turn agentic traces (e.g. OpenHands / SWE-smith). Each conversation is replayed round by round, feeding the server's real assistant reply back into the next round's history. Requires a chat backend (`--backend sglang-oai-chat`) and a trace JSON passed via `--dataset-path`.

Common dataset flags:

- `--num-prompts N`: number of requests
- `--random-input-len`, `--random-output-len`, `--random-range-ratio`: for random/random-ids/image
- `--image-count`: Number of images per request (for `image` dataset).

- `--apply-chat-template`: apply tokenizer chat template when constructing prompts
- `--dataset-path PATH`: file path for ShareGPT json; if blank and missing, it will be downloaded and cached

Generated Shared Prefix flags (for `generated-shared-prefix`):

- `--gsp-num-groups`
- `--gsp-prompts-per-group`
- `--gsp-system-prompt-len`
- `--gsp-question-len`
- `--gsp-output-len`
- `--gsp-group-distribution {uniform,zipf}`: per-request prefix-group sampling distribution (default: `uniform`). With `zipf`, each request's group is sampled by rank with `p(rank) = (1/rank**alpha) / sum_k(1/k**alpha)`; rank starts at 1 and group index 0 is the hottest. The on-disk dataset cache uses a distinct key per `(group_distribution, zipf_alpha)`, so uniform-mode caches are never mixed with zipf-mode caches.
- `--gsp-zipf-alpha FLOAT`: Zipf exponent for `--gsp-group-distribution=zipf`. Must be a finite float strictly greater than 0; larger values concentrate requests on lower-ranked (hotter) groups. Required when the distribution is `zipf`; must be omitted otherwise.

Image dataset flags (for `image`):

- `--image-count`: Number of images per request
- `--image-resolution`: Image resolution; supports presets (4k, 1080p, 720p, 360p) or custom 'heightxwidth' format (e.g., 1080x1920, 512x768)
- `--image-format`: Image format (jpeg or png)
- `--image-content`: Image content type (random or blank)

Agentic trace flags (for `agentic-trace`):

- `--dataset-path`: path to the pre-built trace JSON
- `--sharegpt-output-len`: per-turn output length (default: 220)
- `--dataset-offset`: rotate the conversation list by this many entries before sampling, so successive sweep steps start on fresh conversations
- `--agentic-max-turns`: cap each conversation to at most this many turns (useful for small, fast profiling runs)

SPEED-Bench flags (for `speed-bench`):

- `--dataset-path PATH`: path to the pre-downloaded SPEED-Bench Throughput JSONL (e.g., `throughput_1k.jsonl`). Use the [SPEED-Bench measurement framework](https://github.com/NVIDIA/Model-Optimizer/tree/main/examples/specdec_bench) to generate it.
- `--speed-bench-category`: filter to one entropy category: `low_entropy`, `mixed`, or `high_entropy` (default: all)
- `--speed-bench-output-len`: fixed number of output tokens per request (default: 512)

### Examples

1. To benchmark image dataset with 3 images per request, 500 prompts, 512 input length, and 512 output length, you can run:

```bash Command
python -m sglang.launch_server --model-path Qwen/Qwen2.5-VL-3B-Instruct --disable-radix-cache
```

```bash Command
python -m sglang.bench_serving \
    --backend sglang-oai-chat \
    --dataset-name image \
    --num-prompts 500 \
    --image-count 3 \
    --image-resolution 720p \
    --random-input-len 512 \
    --random-output-len 512
```

2. To benchmark random dataset with 3000 prompts, 1024 input length, and 1024 output length, you can run:

```bash Command
python -m sglang.launch_server --model-path Qwen/Qwen2.5-3B-Instruct
```

```bash Command
python3 -m sglang.bench_serving \
    --backend sglang \
    --dataset-name random \
    --num-prompts 3000 \
    --random-input 1024 \
    --random-output 1024 \
    --random-range-ratio 0.5
```

3. To benchmark speculative decoding throughput using SPEED-Bench (mixed-entropy category, 1K ISL), you can run:

```bash Command
python -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct \
    --speculative-algorithm EAGLE --speculative-draft-model-path <draft-model-path>
```

```bash Command
python3 -m sglang.bench_serving \
    --backend sglang \
    --dataset-name speed-bench \
    --dataset-path /path/to/throughput_1k.jsonl \
    --speed-bench-category mixed \
    --speed-bench-output-len 512 \
    --num-prompts 512
```

### Choosing model and tokenizer

- `--model` is required unless the backend exposes `GET /v1/models`, in which case the first model ID is auto-selected.
- `--tokenizer` defaults to `--model`. Both can be HF model IDs or local paths.
- For ModelScope workflows, setting `SGLANG_USE_MODELSCOPE=true` enables fetching via ModelScope (weights are skipped for speed).
- If your tokenizer lacks a chat template, the script warns because token counting can be less robust for gibberish outputs.

### Rate, concurrency, and streaming

- `--request-rate`: requests per second. `inf` sends all immediately (burst). Non-infinite rate uses a Poisson process for arrival times.
- `--max-concurrency`: caps concurrent in-flight requests regardless of arrival rate.
- `--disable-stream`: switch to non-streaming mode when supported; TTFT then equals total latency for chat completions.

### Other key options

- `--output-file FILE.jsonl`: append JSONL results to file; auto-named if unspecified
- `--output-details`: include per-request arrays (generated texts, errors, ttfts, itls, input/output lens)
- `--extra-request-body '&#123;"top_p":0.9,"temperature":0.6&#125;'`: merged into payload (sampling params, etc.)
- `--disable-ignore-eos`: pass through EOS behavior (varies by backend)
- `--warmup-requests N`: run warmup requests with short output first (default 1)
- `--flush-cache`: call `/flush_cache` (sglang) before main run
- `--profile`: call `/start_profile` and `/stop_profile` (requires server to enable profiling, e.g., `SGLANG_TORCH_PROFILER_DIR`)
- `--lora-name name1 name2 ...`: randomly pick one per request and pass to backend (e.g., `lora_path` for sglang)
- `--tokenize-prompt`: send integer IDs instead of text (currently supports `--backend sglang` only)

### Authentication

If your target endpoint requires OpenAI-style auth, set:

```bash Command
export OPENAI_API_KEY=sk-...yourkey...
```

The script will add `Authorization: Bearer $OPENAI_API_KEY` automatically for OpenAI-compatible routes.

### Metrics explained

Printed after each run:

- Request throughput (req/s)
- Input token throughput (tok/s) - includes both text and vision tokens
- Output token throughput (tok/s)
- Total token throughput (tok/s) - includes both text and vision tokens
- Total input text tokens and Total input vision tokens - per-modality breakdown
- Concurrency: aggregate time of all requests divided by wall time
- End-to-End Latency (ms): mean/median/std/p99 per-request total latency
- Time to First Token (TTFT, ms): mean/median/std/p99 for streaming mode
- Inter-Token Latency (ITL, ms): mean/median/std/p95/p99/max between tokens
- TPOT (ms): Token processing time after first token, i.e., `(latency - ttft)/(tokens-1)`
- Accept length (sglang-only, if available): speculative decoding accept length

The script also retokenizes generated text with the configured tokenizer and reports "retokenized" counts.

### Goodput

Throughput counts every completed request, including the ones that came back too late to be useful. Pass service level objectives with `--goodput` to count only the requests that met them:

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang --host 127.0.0.1 --port 30000 \
  --num-prompts 1000 --request-rate 16 \
  --goodput ttft:500 tpot:50 e2el:20000
```

Each entry is `KEY:VALUE` in milliseconds, with `KEY` one of `ttft`, `tpot`, `e2el` (end-to-end latency). A request is good if it succeeded and met every listed SLO; a single-token response has a TPOT of 0. The run then also prints:

- Request goodput (req/s): good requests per second
- SLO attainment (%): good requests over all requests sent, so failed requests count as misses
- One attainment line per listed SLO, which shows which SLO is the binding one

Sweeping `--request-rate` and reading goodput gives the highest rate the deployment sustains within its SLOs: throughput keeps rising or flattens under overload, goodput peaks and then falls.

### JSONL output format

When `--output-file` is set, one JSON object is appended per run. Base fields:

- Arguments summary: backend, dataset, request_rate, max_concurrency, etc.
- Duration and totals: completed, total_input_tokens, total_output_tokens, retokenized totals
- Throughputs and latency statistics as printed in the console
- `accept_length` when available (sglang)
- `goodput_slos_ms`, `request_goodput`, `slo_attainment`, `slo_attainment_by_metric` when `--goodput` is given

With `--output-details`, an extended object also includes arrays:

- `input_lens`, `output_lens`
- `ttfts`, `itls` (per request: ITL arrays)
- `generated_texts`, `errors`

### End-to-end examples

1) sglang native `/generate` (streaming):

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --dataset-name random \
  --random-input-len 1024 --random-output-len 1024 --random-range-ratio 0.5 \
  --num-prompts 2000 \
  --request-rate 100 \
  --max-concurrency 512 \
  --output-file sglang_random.jsonl --output-details
```

2) OpenAI-compatible Completions (e.g., vLLM):

```bash Command
python3 -m sglang.bench_serving \
  --backend vllm \
  --base-url http://127.0.0.1:8000 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --dataset-name sharegpt \
  --num-prompts 1000 \
  --sharegpt-output-len 256
```

3) OpenAI-compatible Chat Completions (streaming):

```bash Command
python3 -m sglang.bench_serving \
  --backend vllm-chat \
  --base-url http://127.0.0.1:8000 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --dataset-name random \
  --num-prompts 500 \
  --apply-chat-template
```

4) Images (VLM) with chat template:

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model your-vlm-model \
  --dataset-name image \
  --image-count 2 \
  --image-resolution 720p \
  --random-input-len 128 --random-output-len 256 \
  --num-prompts 200 \
  --apply-chat-template
```

4a) Images with custom resolution:

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model your-vlm-model \
  --dataset-name image \
  --image-count 1 \
  --image-resolution 512x768 \
  --random-input-len 64 --random-output-len 128 \
  --num-prompts 100 \
  --apply-chat-template
```

4b) 1080p images with PNG format and blank content:

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model your-vlm-model \
  --dataset-name image \
  --image-count 1 \
  --image-resolution 1080p \
  --image-format png \
  --image-content blank \
  --random-input-len 64 --random-output-len 128 \
  --num-prompts 100 \
  --apply-chat-template
```

5) Generated shared prefix (long system prompts + short questions):

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --dataset-name generated-shared-prefix \
  --gsp-num-groups 64 --gsp-prompts-per-group 16 \
  --gsp-system-prompt-len 2048 --gsp-question-len 128 --gsp-output-len 256 \
  --num-prompts 1024
```

Zipfian / power-law prefix popularity (opt-in via `--gsp-group-distribution=zipf`):

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --dataset-name generated-shared-prefix \
  --gsp-num-groups 64 --gsp-prompts-per-group 16 \
  --gsp-system-prompt-len 2048 --gsp-question-len 128 --gsp-output-len 256 \
  --gsp-group-distribution zipf --gsp-zipf-alpha 1.2 \
  --seed 42
```

`zipf` mode samples each request's prefix group from the rank-based distribution `p(rank) = (1/rank**alpha) / sum_k(1/k**alpha)` with rank starting at 1, so group index 0 is the hottest. The total request count stays `num_groups * prompts_per_group` — identical to `uniform` mode — and only the per-request group assignment changes. `alpha` must be a finite float strictly greater than 0; larger values concentrate requests on lower-ranked (hotter) groups.

The on-disk dataset cache at `~/.cache/sglang/benchmark/gen_shared_prefix_*.pkl` includes `group_distribution` and `zipf_alpha` in its key, so uniform-mode and zipf-mode runs (or two zipf runs with different alpha) never share a cache file. Uniform-mode filenames are unchanged from the legacy format, so existing caches remain valid.

This flag controls prefix-popularity shape only. It does not by itself reproduce any production trace or guarantee an observed cache-hit rate for a given engine.

6) Tokenized prompts (ids) for strict length control (sglang only):

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --dataset-name random \
  --tokenize-prompt \
  --random-input-len 2048 --random-output-len 256 --random-range-ratio 0.2
```

7) Profiling and cache flush (sglang):

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --profile \
  --flush-cache
```

8) TensorRT-LLM streaming endpoint:

```bash Command
python3 -m sglang.bench_serving \
  --backend trt \
  --base-url http://127.0.0.1:8000 \
  --model your-trt-llm-model \
  --dataset-name random \
  --num-prompts 100 \
  --disable-ignore-eos
```

9) Evaluating large-scale KVCache sharing with mooncake trace (sglang only):

```bash Command
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30000 \
  --model model-name \
  --dataset-name mooncake \
  --mooncake-slowdown-factor 1.0 \
  --mooncake-num-rounds 1000 \
  --mooncake-workload conversation|mooncake|agent|synthetic
  --use-trace-timestamps true \
  --random-output-len 256
```

10) Fake decode stress testing (PD disaggregation, decode-only):

When benchmarking pure decode performance in a PD disaggregation setup, you can bypass the prefill node entirely by using `--fake-prefill`. This requires the decode server to be started with `--disaggregation-transfer-backend fake`:

```bash Command
# Step 1: Start a decode-only server with fake transfer backend
python -m sglang.launch_server \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --disaggregation-mode decode \
  --disaggregation-transfer-backend fake \
  --port 30001

# Step 2: Run bench_serving with --fake-prefill
python3 -m sglang.bench_serving \
  --backend sglang \
  --host 127.0.0.1 --port 30001 \
  --model meta-llama/Llama-3.1-8B-Instruct \
  --dataset-name random \
  --num-prompts 500 \
  --random-input-len 1024 --random-output-len 256 \
  --fake-prefill
```

Similarly, `bench_one_batch_server` also supports `--fake-prefill`:

```bash Command
python3 -m sglang.bench_one_batch_server \
  --base-url http://127.0.0.1:30001 \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --batch-size 32 --input-len 1024 --output-len 256 \
  --fake-prefill
```

The `--fake-prefill` flag automatically injects special sentinel values into each request, telling the decode server to skip real KV transfer and generate fake KV data locally.

### Troubleshooting

- All requests failed: verify `--backend`, server URL/port, `--model`, and authentication. Check warmup errors printed by the script.
- Throughput seems too low: adjust `--request-rate` and `--max-concurrency`; verify server batch size/scheduling; ensure streaming is enabled if appropriate.
- Token counts look odd: prefer chat/instruct models with proper chat templates; otherwise tokenization of gibberish may be inconsistent.
- Image/MMMU datasets: ensure you installed extra deps (`pillow`, `datasets`, `pybase64`).
- Authentication errors (401/403): set `OPENAI_API_KEY` or disable auth on your server.

### Notes

- The script raises the file descriptor soft limit (`RLIMIT_NOFILE`) to help with many concurrent connections.
- For sglang, `/server_info` is queried post-run to report speculative decoding accept length when available.

---

### Docs Developer Guide Benchmark And Profiling (`docs/docs/developer_guide/benchmark_and_profiling.mdx`)

---
title: "Benchmark and Profiling"
metatags:
    description: "SGLang benchmarking and profiling: PyTorch Profiler, Nsight Systems, layerwise NVTX, PD disaggregation profiling."
---
## Benchmark

SGLang provides four benchmark tools that operate at different levels of the stack. The table below summarizes their key differences:

<table>
  <thead>
    <tr>
      <th>Tool</th>
      <th>HTTP Server</th>
      <th>Scheduler</th>
      <th>Use Case</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>bench_serving</code></td>
      <td>Yes (async HTTP client to a running server)</td>
      <td>Yes (indirectly, via server)</td>
      <td>Realistic online serving benchmarks with latency metrics (TTFT, TPOT, ITL)</td>
    </tr>
    <tr>
      <td><code>bench_one_batch_server</code></td>
      <td>Yes (sends HTTP requests to a running server)</td>
      <td>Yes (indirectly, via server)</td>
      <td>End-to-end single-batch latency including HTTP and scheduler overhead</td>
    </tr>
    <tr>
      <td><code>bench_offline_throughput</code></td>
      <td>No</td>
      <td>Yes (directly uses <code>Engine</code> in-process)</td>
      <td>Maximum throughput measurement without HTTP overhead</td>
    </tr>
    <tr>
      <td><code>bench_one_batch</code></td>
      <td>No</td>
      <td>No (directly calls <code>ModelRunner</code>)</td>
      <td>Kernel-level latency profiling of a single static batch</td>
    </tr>
  </tbody>
</table>

Use `bench_serving` by default unless there are specific needs.

**`bench_serving`** is an async HTTP load-testing client that sends requests at controlled rates with configurable concurrency to a running server. It measures realistic online serving metrics including time-to-first-token (TTFT), time-per-output-token (TPOT), inter-token latency (ITL), and throughput. Use `num-prompts >= 5 * max-concurrency` to measure steady-state performance. Launch a server with `sglang.launch_server` first.

  ```bash Command
  python3 -m sglang.bench_serving --backend sglang --max-concurrency 16 --num-prompts 80 --random-input-len 256 --random-output-len 32 --dataset-name random
  ```

**`bench_one_batch_server`** sends a single batch as one HTTP request to a running server. Due to only having a single batch, the server is never in a steady-state and metrics will be biased. Launch a server with `sglang.launch_server` first.

  ```bash Command
  python3 -m sglang.bench_one_batch_server --base-url http://127.0.0.1:30000 --model-path meta-llama/Meta-Llama-3.1-8B-Instruct --batch-size 32 --input-len 256 --output-len 32
  ```

  - Pass `--enable-multi-batch` and set `--batch-size` to a multiple of the server's `--max-running-requests` to stabilize throughput measurements. Surplus requests are queued by the scheduler and promoted batch-by-batch, amortizing per-request prefill and first-step transients into steady-state decode. Under this flag, only `overall_throughput` is authoritative; `input_throughput`, `output_throughput`, `last_ttft`, and ITL include cross-batch queueing in their denominators and should be treated as informational.
  - Pass `--disable-ignore-eos` when benchmarking with real prompts, where forcing decode past EOS would shift the output distribution toward gibberish. Requests then early-stop, so the whole-run `output_throughput`/ITL include the decaying-batch tail; the report gains steady-state columns measured only over the window where every request is still decoding (from the last request's first token to the first request's finish). Replay recorded traffic with `--dataset-name sharegpt` or `--dataset-name custom --dataset-path <conversations.jsonl>` (recorded completion lens are ignored; `--output-len` is the shared `max_new_tokens` cap). For OpenAI-format traces with per-request parameters, use `bench_serving`.
  - Pass `--lora-name <name>` to route every prompt through a pre-loaded LoRA adapter. Requires the server to be launched with `--enable-lora --lora-paths <name>=<path>`.

**`bench_offline_throughput`** directly instantiates the `Engine` object in-process (no HTTP server) and submits all requests at once via `engine.generate()`. The engine's scheduler handles batching and execution. This measures maximum achievable throughput without any network overhead.

  ```bash Command
  python3 -m sglang.benchmark.offline_throughput --model-path meta-llama/Meta-Llama-3.1-8B-Instruct --num-prompts 10
  ```

**`bench_one_batch`** is the lowest-level tool. It directly instantiates a `ModelRunner` and calls `extend()` / `decode()` on a fixed static batch, bypassing the scheduler entirely. The prefill and decode phases are run separately, making profiling easier but rendering the metrics unrealistic. Because there is no dynamic batching, it may run out of memory for batch sizes that a real server can handle (a real server chunks prefill into smaller batches). This is best suited for profiling individual kernel performance.

  ```bash Command
  python3 -m sglang.benchmark.one_batch --model-path meta-llama/Meta-Llama-3.1-8B-Instruct --batch-size 32 --input-len 256 --output-len 32
  ```

## Profile with PyTorch Profiler

[Pytorch Profiler](https://pytorch.org/tutorials/recipes/recipes/profiler_recipe.html) is a convenient basic tool to inspect kernel execution time, call stack, and kernel overlap and occupancy.

### Profile a server with `sglang.bench_serving`

```bash Command
# set trace path
export SGLANG_TORCH_PROFILER_DIR=/root/sglang/profile_log

# start server
python -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct

# send profiling request from client
python -m sglang.bench_serving --backend sglang --model meta-llama/Llama-3.1-8B-Instruct --num-prompts 10 --sharegpt-output-len 100 --profile
```

For `bench_serving --profile`, the output directory is selected on the client side from `--profile-output-dir` or `SGLANG_TORCH_PROFILER_DIR` (fallback: `/tmp`), then sent in the `/start_profile` request.
If you call `/start_profile` directly and do not provide `output_dir`, the server uses its own `SGLANG_TORCH_PROFILER_DIR` (fallback: `/tmp`).

Setting `SGLANG_TORCH_PROFILER_DIR` on both server and client is still recommended to avoid confusion about where traces are written.

For more details, please refer to [Bench Serving Guide](./bench_serving).

### Profile In PD Disaggregation Mode

When profiling in PD disaggregation mode, prefill and decode workers **must be profiled separately** due to torch profiler limitations. The `bench_serving` command provides dedicated options for this:

#### Profile Prefill Workers

```bash Command
# set trace path
export SGLANG_TORCH_PROFILER_DIR=/root/sglang/profile_log

# start prefill and decode servers (see PD disaggregation docs for setup)
python -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct --disaggregation-mode prefill
python -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct --disaggregation-mode decode --port 30001 --base-gpu-id 1

# start router
python -m sglang_router.launch_router --pd-disaggregation --prefill http://127.0.0.1:30000 --decode http://127.0.0.1:30001 --host 0.0.0.0 --port 8000

# send profiling request targeting prefill workers
python -m sglang.bench_serving --backend sglang --model meta-llama/Llama-3.1-8B-Instruct --num-prompts 10 --sharegpt-output-len 100 --profile --pd-separated --profile-prefill-url http://127.0.0.1:30000
```

#### Profile Decode Workers

```bash Command
# send profiling request targeting decode workers
python -m sglang.bench_serving --backend sglang --model meta-llama/Llama-3.1-8B-Instruct --num-prompts 10 --sharegpt-output-len 100 --profile --pd-separated --profile-decode-url http://127.0.0.1:30001
```

#### Important Notes

- `--profile-prefill-url` and `--profile-decode-url` are **mutually exclusive** - you cannot profile both at the same time
- Both options support multiple worker URLs for multi-instance setups:
  ```bash Command
  # Profile multiple prefill workers
  python -m sglang.bench_serving --backend sglang --model meta-llama/Llama-3.1-8B-Instruct --num-prompts 10 --profile --pd-separated --profile-prefill-url http://127.0.0.1:30000 http://127.0.0.1:30002

  # Profile multiple decode workers
  python -m sglang.bench_serving --backend sglang --model meta-llama/Llama-3.1-8B-Instruct --num-prompts 10 --profile --pd-separated --profile-decode-url http://127.0.0.1:30001 http://127.0.0.1:30003
  ```
- Make sure `SGLANG_TORCH_PROFILER_DIR` is set on all worker nodes before starting the servers
- For more details on setting up PD disaggregation, see [PD Disaggregation Guide](../advanced_features/pd_disaggregation)

### Profile a server with `sglang.benchmark.offline_throughput`
```bash Command
export SGLANG_TORCH_PROFILER_DIR=/root/sglang/profile_log

# profile one batch with bench_one_batch.py
# batch size can be controlled with --batch argument
python3 -m sglang.benchmark.one_batch --model-path meta-llama/Llama-3.1-8B-Instruct --batch 32 --input-len 1024 --output-len 10 --profile

# profile multiple batches with bench_offline_throughput.py
python -m sglang.benchmark.offline_throughput --model-path meta-llama/Llama-3.1-8B-Instruct --dataset-name random --num-prompts 10 --profile --mem-frac=0.8
```

### Profile a server with `sglang.profiler`

When the server is running (e.g., processing a decoding request), you can start live profiling immediately by sending a profile request to the server.

You can do this by running `python3 -m sglang.profiler`. For example:

```text Output
# Terminal 1: Send a generation request
python3 -m sglang.test.send_one

# Terminal 2: Before the above request finishes, quickly launch the following command in a separate terminal.
# It will generate a profile of the above request for several decoding batches.
python3 -m sglang.profiler
```

You can also combine the above operations into a single command

```text Output
python3 -m sglang.test.send_one --profile
```

### Profile a server with HTTP API endpoints

SGLang provides HTTP API endpoints to control profiling on a running server. This allows you to start and stop profiling programmatically, which is useful for capturing specific workload patterns.

#### Using `/start_profile` endpoint

The `/start_profile` endpoint starts profiling on the server. You can control when profiling begins and how long it runs using the following parameters:

**Basic usage:**

```bash Command
# Start profiling immediately for 10 steps
curl -X POST http://127.0.0.1:30000/start_profile \
  -H "Content-Type: application/json" \
  -d '{
    "num_steps": 10
  }'
```

**Parameters:**

- `output_dir` (optional): Directory where profile traces will be saved. If not specified, uses `SGLANG_TORCH_PROFILER_DIR` environment variable, or `/tmp` as the default
- `num_steps` (optional): Number of steps to profile. If not specified, profiling continues until manually stopped with `/stop_profile`
- `start_step` (optional): Step number at which to start profiling (inclusive). Useful for skipping warmup iterations
- `activities` (optional): List of activities to profile, e.g., `["CPU", "GPU"]`. Default is `["CPU", "GPU"]`
- `merge_profiles` (optional): Whether to merge distributed traces. Default is `false`
- `detailed_annotations` (optional): Whether to fold per-iteration request and KV-length aggregates into the trace's `step[...]` markers, for detailed analysis. Default is `false`. See [Detailed annotations](#detailed-annotations) below.

**Note on step ranges:** Profiling starts at `start_step` (inclusive) and continues for `num_steps` iterations. For example, with `start_step=3` and `num_steps=10`, profiling captures steps 3, 4, 5, 6, 7, 8, 9, 10, 11, and 12 (10 steps total, starting from step 3).

**Advanced usage with `start_step`:**

```bash Command
# Wait 5 steps (warmup), then profile for 10 steps
curl -X POST http://127.0.0.1:30000/start_profile \
  -H "Content-Type: application/json" \
  -d '{
    "output_dir": "/tmp/profiles",
    "start_step": 5,
    "num_steps": 10,
    "activities": ["CPU", "GPU"]
  }'
```

**Continuous profiling (manual stop):**

```bash Command
# Start profiling without num_steps - must manually stop with /stop_profile
curl -X POST http://127.0.0.1:30000/start_profile
```

#### Detailed annotations

Set `detailed_annotations` to `true` to fold per-iteration aggregates into SGLang's existing per-forward `step[...]` span. For every execution step that runs while profiling is active, SGLang augments that step's marker on the GPU stream with the request and KV-length distribution of the step, so you can reconstruct compute and memory bounds directly from the trace without per-request details.

All four per-request aggregates are appended, prefixed by phase — `c_` for context (prefill) and `g_` for generation (decode). The per-phase `sq` is always emitted so each `step[...]` label is self-contained for roofline analysis, even where it duplicates the base label's `bs` (decode) or `toks` (prefill):

- `sq`: total query tokens (`Σ N_Q`)
- `sqsq`: sum of squared query tokens per request (`Σ N_Q²`)
- `sqsk`: sum of query·KV tokens per request (`Σ N_Q·N_KV`)
- `sk`: total KV tokens (`Σ N_KV`)

A pure prefill (`EXTEND`) or decode (`DECODE`) forward emits a single group; a mixed forward emits both, with `c=`/`g=` request counts. Example labels:

```text
step[EXTEND bs=1 toks=1025 c_sq=1025 c_sqsq=1050625 c_sqsk=1050625 c_sk=1025]
step[DECODE bs=64 g_sq=64 g_sqsq=64 g_sqsk=100032 g_sk=100032]
step[MIXED bs=66 c=2 g=64 c_sq=2048 c_sk=2048 c_sqsq=2097152 c_sqsk=2097152 g_sq=64 g_sk=65600 g_sqsq=64 g_sqsk=65600]
```

With speculative decoding (EAGLE/MTP) each request contributes multiple query tokens per step, so `sq` no longer equals `bs`. Both draft-decode and target-verify (`TARGET_VERIFY`) steps are emitted in the **generation** group. For example, a verify step with 3 draft tokens across 2 requests (`seq_lens=[10, 20]`):

```text
step[TARGET_VERIFY bs=2 g_sq=6 g_sqsq=18 g_sqsk=90 g_sk=30]
```

```bash Command
# Profile 10 steps with detailed annotations enabled
curl -X POST http://127.0.0.1:30000/start_profile \
  -H "Content-Type: application/json" \
  -d '{
    "output_dir": "/tmp/profiles",
    "num_steps": 10,
    "activities": ["CPU", "GPU"],
    "detailed_annotations": true
  }'
```

The annotations only appear when profiling is active with `detailed_annotations` enabled, so they add no overhead on the normal serving path. The behavior is identical in eager and CUDA graph modes. When viewing the trace (see [View traces](#view-traces)), the augmented `step[...]` markers appear on the GPU stream alongside the kernels for each step.

#### Using `/stop_profile` endpoint

The `/stop_profile` endpoint stops an ongoing profiling session and saves the trace file.

```bash Command
# Stop profiling and save traces
curl -X POST http://127.0.0.1:30000/stop_profile
```

This is only needed when you start profiling without specifying `num_steps`. If `num_steps` is specified, profiling will automatically stop after that many steps.

#### Example workflow

```bash Command
# Terminal 1: Start the server
export SGLANG_TORCH_PROFILER_DIR=/tmp/profiles
python -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct

# Terminal 2: Start continuous profiling
curl -X POST http://127.0.0.1:30000/start_profile \
  -H "Content-Type: application/json" \
  -d '{
    "start_step": 3
  }'

# Terminal 3: Send requests to generate load
python -m sglang.bench_serving --backend sglang --num-prompts 100

# Terminal 2: Stop profiling when done
curl -X POST http://127.0.0.1:30000/stop_profile
```

### Profiler Trace Merger for Distributed Traces

SGLang now supports automatic merging of profiling traces from distributed setups with multiple parallelism types (TP, DP, PP, EP). This feature is particularly useful for analyzing performance across distributed runs.

#### Multi-Node Profiling and Shared Storage Considerations

Single-node profiler output merging is completely supported. When profiling in distributed environments spanning multiple nodes, shared storage (e.g., NFS, Lustre) should be accessible by all nodes for the output directory to enable merging of trace files.

If there is no shared storage accessible across nodes, automatic merging of trace files during profiling is not supported directly as of now.

#### HTTP API Usage

```bash Command
# Start profiling with automatic trace merging enabled
curl -X POST <BASE_URL>/start_profile \
  -H "Content-Type: application/json" \
  -d '{
    "output_dir": "/tmp/profiles", # where to store profile traces
    "num_steps": 10,
    "activities": ["CPU", "GPU"],
    "merge_profiles": true # optional argument to merge profile traces (default=False)
  }'
```

#### Command Line Usage

```bash Command
# Start profiling with merge enabled
python -m sglang.profiler \
  --num-steps 10 \
  --cpu \
  --gpu \
  --output-dir /tmp/profiles \
  --merge-profiles # optional argument to merge profile traces (default=False)
```

#### Output Files

The profile merger generates:
- Individual rank trace files: `&#123;profile_id&#125;-TP-&#123;tp&#125;-DP-&#123;dp&#125;-PP-&#123;pp&#125;-EP-&#123;ep&#125;.trace.json.gz`
- Merged trace file: `merged-&#123;profile_id&#125;.trace.json.gz`

### Profile the CUDA graph capture phase

The tools above profile the steady-state runtime (prefill / decode). To instead profile the **CUDA graph capture phase** that runs once at server startup, launch the server with `--enable-profile-cuda-graph`. This runs a PyTorch Profiler pass over the decode CUDA-graph capture, which is useful for diagnosing slow or memory-heavy graph capture.

`--enable-profile-cuda-graph` (server arg) builds the capture profiler and always emits the per-kernel CPU/CUDA time summary tables and a CUDA memory snapshot. Persisting Chrome traces to disk is opt-in via one of two env vars (both no-ops unless `--enable-profile-cuda-graph` is also set):

- `SGLANG_ENABLE_CUDA_GRAPH_CAPTURE_TRACE=1` — writes **one combined trace per tensor-parallel rank** for the whole capture pass, named `cuda_graph_capture-&#123;runner&#125;-TP-&#123;tp_rank&#125;.json.gz`.
- `SGLANG_GRAPH_BATCH_CAPTURE=1` — writes **one trace per captured batch size per rank**, named `&#123;runner&#125;_bs_&#123;bs&#125;_rank&#123;tp_rank&#125;.json.gz`. The profiler runs on a `wait=2, warmup=0, active=1` schedule (the two dummy runs before each capture are skipped) with `record_shapes`, `with_stack`, `with_flops`, and `profile_memory` enabled, giving per-shape kernel identities, input shapes, FLOPs, and memory.

If both env vars are set, `SGLANG_ENABLE_CUDA_GRAPH_CAPTURE_TRACE` (the single combined trace) takes precedence.

```bash Command
# set trace path
export SGLANG_TORCH_PROFILER_DIR=/root/sglang/profile_log

# opt in to per-batch-size capture traces (or set
# SGLANG_ENABLE_CUDA_GRAPH_CAPTURE_TRACE=1 for a single combined trace per rank)
export SGLANG_GRAPH_BATCH_CAPTURE=1

# launch the server with CUDA graph capture profiling enabled
python -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct --enable-profile-cuda-graph
```

Behavior and output:

- All traces are written to `$&#123;SGLANG_TORCH_PROFILER_DIR&#125;/graph_capture_profile/` (defaults to `/tmp/graph_capture_profile/` if the variable is unset). Files are namespaced by runner class and TP rank so concurrent capture passes (e.g. EAGLE target/draft/draft-extend) and ranks don't collide.
- A CUDA memory snapshot (`cuda_graph_runner_memory_usage.pickle`) and per-kernel CPU/CUDA time summary tables are always emitted for the capture phase (independent of the env vars above).
- Only the decode CUDA-graph runner is profiled.

The capture traces are viewed the same way as other PyTorch Profiler traces (see [View traces](#view-traces)).

### Possible PyTorch bugs
If in any cases you encounter the following error (for example, using qwen 2.5 VL):
```bash Command
RuntimeError: !stack.empty() INTERNAL ASSERT FAILED at "/pytorch/torch/csrc/autograd/profiler_python.cpp":983, please report a bug to PyTorch. Python replay stack is empty.
```
This is likely a PyTorch Bug reported in [Bug: vLLM Profiler](https://github.com/vllm-project/vllm/issues/18240) and [Bug: torch.profiler.profile](https://github.com/pytorch/pytorch/issues/101632). As a workaround, you may disable `with_stack` with an environment variable such as follows:
```bash Command
export SGLANG_PROFILE_WITH_STACK=False
python -m sglang.benchmark.offline_throughput --model-path meta-llama/Llama-3.1-8B-Instruct --dataset-name random --num-prompts 10 --profile --mem-frac=0.8
```

### View traces

Trace files can be loaded and visualized from:

1. https://ui.perfetto.dev/ (any browser)
2. chrome://tracing (Chrome browser only)

If browser cannot open trace file due to its large size,
client can generate a small trace file (&lt;100MB) by controlling number of prompts and lengths of prompt outputs.
For example, when profiling a server,

```bash Command
python -m sglang.bench_serving --backend sglang --model meta-llama/Llama-3.1-8B-Instruct --num-prompts 2 --sharegpt-output-len 100 --profile
```

This command sets the number of prompts to 2 with `--num-prompts` argument and limits the length of output sequences to 100 with `--sharegpt-output-len` argument, which can generate a small trace file for browser to open smoothly.

Additionally, if you want to locate the SGLang Python source code through the cuda kernel in Trace, you need to disable CUDA Graph when starting the service. This can be done by using the `--disable-cuda-graph` parameter in the command to start the service.

## Profile with Nsight

[Nsight systems](https://docs.nvidia.com/nsight-systems/) is an advanced tool that exposes more profiling details, such as register and shared memory usage, annotated code regions and low-level CUDA APIs and events.

1. Prerequisite:

   Install using apt, or run inside a [NVIDIA Docker container](https://catalog.ngc.nvidia.com/orgs/nvidia/containers/pytorch/tags) or [SGLang Docker container](https://github.com/sgl-project/sglang/tree/main/docker).

   ```bash Command
   # install nsys
   # https://docs.nvidia.com/nsight-systems/InstallationGuide/index.html
   apt update
   apt install -y --no-install-recommends gnupg
   echo "deb http://developer.download.nvidia.com/devtools/repos/ubuntu$(source /etc/lsb-release; echo "$DISTRIB_RELEASE" | tr -d .)/$(dpkg --print-architecture) /" | tee /etc/apt/sources.list.d/nvidia-devtools.list
   apt-key adv --fetch-keys http://developer.download.nvidia.com/compute/cuda/repos/ubuntu1804/x86_64/7fa2af80.pub
   apt update
   apt install nsight-systems-cli
   ```

2. To profile a single batch, use

   ```bash Command
   nsys profile --trace-fork-before-exec=true --cuda-graph-trace=node python3 -m sglang.benchmark.one_batch --model meta-llama/Meta-Llama-3-8B --batch-size 64 --input-len 512
   ```

3. To profile a server, e.g.

   ```bash Command
   # launch the server, set the delay and duration times according to needs
   # after the duration time has been used up, server will be killed by nsys

   nsys profile --trace-fork-before-exec=true --cuda-graph-trace=node -o sglang.out --delay 60 --duration 70 python3 -m sglang.launch_server --model-path meta-llama/Llama-3.1-8B-Instruct --disable-radix-cache

   # client
   python3 -m sglang.bench_serving --backend sglang --num-prompts 1000 --dataset-name random --random-input 1024 --random-output 512
   ```

   In practice, we recommend users to set `--duration` argument to a large value. Whenever user wants the server to stop profiling. Firstly run:

   ```bash Command
   nsys sessions list
   ```

   to get the session id in the form of `profile-XXXXX`, then run:

   ```bash Command
   nsys stop --session=profile-XXXXX
   ```

   to manually kill the profiler and generate `nsys-rep` files instantly.

4. Use NVTX to annotate code regions, e.g. to see their execution time.

   ```bash Command
   # install nvtx
   pip install nvtx
   ```

   ```python Example
   # code snippets
   import nvtx
   with nvtx.annotate("description", color="color"):
       # some critical code
   ```

### Layer-wise NVTX Profiling with Nsight Systems

SGLang provides built-in layerwise NVTX annotations that can be combined with the CUDA Profiler for detailed per-layer profiling in Nsight Systems. This is particularly useful for identifying performance bottlenecks at the layer level.

#### Using `--enable-layerwise-nvtx-marker` with Nsight Systems and `/start_profile`

The `--enable-layerwise-nvtx-marker` flag automatically adds NVTX markers to every layer in your model. This is particularly powerful when combined with Nsight Systems profiling to see detailed per-layer performance.

**Method 1: Using `/start_profile` with CUDA_PROFILER (for programmatic control)**

This method allows you to control exactly when profiling starts/stops via HTTP API while Nsight Systems is running.

1. Launch the server with layerwise NVTX enabled under Nsight Systems:

   ```bash Command
   # Terminal 1: Start server with nsys and capture-range option
   nsys profile --trace-fork-before-exec=true \
     --cuda-graph-trace=node \
     --capture-range=cudaProfilerApi \
     --capture-range-end=stop \
     -o layerwise_profile \
     python -m sglang.launch_server \
       --model-path meta-llama/Llama-3.1-8B-Instruct \
       --enable-layerwise-nvtx-marker \
       --disable-cuda-graph
   ```

   Note: NVTX markers are not emitted for kernel launches captured by CUDA graphs. Use `--disable-cuda-graph` to ensure all layerwise NVTX markers are emitted in the trace.

2. In another terminal, control profiling via `/start_profile` with `CUDA_PROFILER` activity:

   ```bash Command
   # Terminal 2: Wait for server to be ready, then start CUDA profiling
   # Wait 3 steps for warmup, then profile for 10 steps
   curl -X POST http://127.0.0.1:30000/start_profile \
     -H "Content-Type: application/json" \
     -d '{
       "start_step": 3,
       "num_steps": 10,
       "activities": ["CUDA_PROFILER"]
     }'
   ```

3. Send requests to generate load:

   ```bash Command
   # Terminal 3: Generate workload
   python -m sglang.bench_serving --backend sglang --num-prompts 100
   ```

4. Profiling will automatically stop after 10 steps (due to `num_steps: 10`). If you hadn't specified `num_steps`, you would need to manually stop it:

   ```bash Command
   # Terminal 2: Only needed if num_steps was not specified
   curl -X POST http://127.0.0.1:30000/stop_profile
   ```

The `--capture-range=cudaProfilerApi` option tells Nsight Systems to only capture data between `cudaProfilerStart()` and `cudaProfilerStop()` calls (triggered by `/start_profile` and `/stop_profile`), reducing overhead and file size. The `start_step` parameter skips the first 3 steps to avoid capturing warmup overhead.

**Method 2: Simpler approach without `/start_profile` API**

For simpler use cases where you don't need fine-grained control over profiling start/stop, you can profile with Nsight Systems capturing the entire workload:

```bash Command
# Terminal 1: Start server with layerwise NVTX
# Note: --disable-cuda-graph ensures all NVTX markers are emitted
python -m sglang.launch_server \
  --model-path meta-llama/Llama-3.1-8B-Instruct \
  --enable-layerwise-nvtx-marker \
  --disable-cuda-graph

# Terminal 2: Profile the benchmarking client
nsys profile --trace-fork-before-exec=true \
  --cuda-graph-trace=node \
  -o layerwise_profile \
  python -m sglang.bench_serving --backend sglang --num-prompts 10
```

This approach profiles the entire client execution, including all server interactions. The layerwise NVTX markers will be visible in the Nsight Systems timeline.

**Viewing the profiling results:**

Open the generated `.qdrep` file with Nsight Systems:

```bash Command
nsys-ui layerwise_profile.qdrep
```

In the Nsight Systems GUI, you'll see:
- **NVTX ranges**: Each layer appears as a labeled range in the timeline with detailed information in the marker metadata
- **CUDA kernels**: All GPU kernels are shown alongside the layer annotations
- **Layer hierarchy**: The full module path (e.g., `meta-llama/Meta-Llama-3.1-8B-Instruct.model.layers.0.self_attn.qkv_proj`) helps identify specific layers. The prefix uses the full model path from `--model-path`.
- **Tensor shapes**: Input/output dimensions and parameter shapes are included in the NVTX marker data

**Benefits of layerwise NVTX profiling:**

- **Granular visibility**: See exactly which layers are taking the most time
- **Memory tracking**: Identify layers with large memory allocations
- **Bottleneck identification**: Quickly locate inefficient operations
- **Communication overhead**: In multi-GPU setups, see per-layer communication costs
- **Development debugging**: Validate that model architecture changes have the expected performance impact

## Other tips

1. You can benchmark a model using dummy weights by only providing the config.json file. This allows for quick testing of model variants without training. To do so, add `--load-format dummy` to the above commands and then you only need a correct `config.json` under the checkpoint folder.
2. You can benchmark a model with modified configs (e.g., less layers) by using `--json-model-override-args`. For example, you can benchmark a model with only 2 layers and 2 kv heads using:

   ```bash Command
   python -m sglang.benchmark.one_batch --model-path meta-llama/Meta-Llama-3.1-8B-Instruct --batch 32 --input-len 256 --output-len 32 --load-format dummy --json-model-override-args '{"num_hidden_layers": 1, "num_key_value_heads": 1}'
   ```

3. You can use `--python-backtrace=cuda` to see python call stack for all CUDA kernels, as in PyTorch Profiler. (Caveat: this can cause inaccurately long kernel runtimes for CUDA event based timing)
4. For more arguments see [Nsight Systems User Guide](https://docs.nvidia.com/nsight-systems/UserGuide/index.html).

---

### Docs Developer Guide Contribution Guide (`docs/docs/developer_guide/contribution_guide.mdx`)

---
title: "Contribution Guide"
mode: wide
metatags:
    description: "SGLang contribution guide: source install, pre-commit, unit tests, CI triggers, code style, sgl-kernel updates."
---
Welcome to **SGLang**! We appreciate your interest in contributing. This guide provides a concise overview of how to set up your environment, run tests, build documentation, and open a Pull Request (PR). Whether you’re fixing a small bug or developing a major feature, we encourage following these steps for a smooth contribution process.

## Install SGLang from Source

### Fork and clone the repository

**Note**: New contributors do **not** have the write permission to push to the official SGLang repo. Please fork the repository under your GitHub account, then clone your fork locally.

```bash
git clone https://github.com/<your_user_name>/sglang.git
```

### Build from source

Refer to [Install SGLang from Source](../get-started/install#method-2-from-source).

## Format code with pre-commit

We use [pre-commit](https://pre-commit.com/) to maintain consistent code style checks. Before pushing your changes, please run:

```bash
pip3 install pre-commit
pre-commit install
pre-commit run --all-files
```

- **`pre-commit run --all-files`** manually runs all configured checks, applying fixes if possible. If it fails the first time, re-run it to ensure lint errors are fully resolved. Make sure your code passes all checks **before** creating a Pull Request.
- **Do not commit** directly to the `main` branch. Always create a new branch (e.g., `feature/my-new-feature`), push your changes, and open a PR from that branch.
- Documentation links and anchors are checked with Mintlify in CI. To run the same version locally, install it with `npm install mint@4.2.559`, then run `cd docs && mint broken-links --check-anchors --check-redirects`.
- The manual `lychee` pre-commit hook checks links in the repository-level `README.md`: `pre-commit run --hook-stage manual lychee --all-files`.

## Run and add unit tests

If you add a feature or fix a bug, add focused regression coverage when the test protects a concrete behavior, invariant, or bookkeeping contract.

### Unit tests (no server required)

Unit tests live under [`test/registered/unit/`](https://github.com/sgl-project/sglang/tree/main/test/registered/unit), organized to mirror the `python/sglang/srt/` source tree. These tests validate component logic **without** launching a server or loading real model weights.
SGLang supports both Python's built-in [unittest](https://docs.python.org/3/library/unittest.html) framework and [pytest](https://docs.pytest.org/). Registered CI tests must use `CustomTestCase` instead of raw `unittest.TestCase`, register themselves with `register_*_ci(...)`, and include a standard `__main__` entry point. CI discovers registrations with `test/run_suite.py` and executes each selected test file directly with fail-fast enabled.

**When to add a unit test:** If you modify a file under `python/sglang/srt/`, check whether a corresponding test exists in `test/registered/unit/` and add coverage for your changes. For example:

```text
srt/mem_cache/radix_cache.py   →  unit/mem_cache/test_radix_cache_unit.py
srt/sampling/sampling_params.py →  unit/sampling/test_sampling_params.py
```

**Run tests locally:**

```bash
# Closest to how CI executes an individual registered test file
python3 test/registered/unit/mem_cache/test_radix_cache_unit.py

# Run a registered CI suite
python3 test/run_suite.py --hw cpu --suite base-a-test-cpu

# Pytest remains useful for local directory-level discovery
pytest test/registered/unit/mem_cache/ -v
```

**Run with coverage:**

```bash Command
pytest test/registered/unit/ --cov --cov-config=.coveragerc -v
```

For conventions on CI registration, test structure, and examples, see [`test/registered/unit/README.md`](https://github.com/sgl-project/sglang/tree/main/test/registered/unit/README.md).

### E2E tests (server required)

For tests that require launching a server, refer to [`test/registered/README.md`](https://github.com/sgl-project/sglang/tree/main/test/registered/README.md) for guidance on where to place your test.

For detailed instructions on running tests and integrating them into CI, refer to [test/README.md](https://github.com/sgl-project/sglang/tree/main/test/README.md).

## Write documentation

Documentation is a good way for new contributors to learn the SGLang codebase. See [docs/README.md](https://github.com/sgl-project/sglang/tree/main/docs/README.md) for the current Mintlify setup and validation commands.

## Test the accuracy
If your code changes model output, run an accuracy evaluation appropriate for the affected model and feature. For example, after launching a server, run the unified GSM8K evaluator:

```bash
# Launch a server
sglang serve --model-path Qwen/Qwen3-8B

# Evaluate
sgl-eval run gsm8k \
  --base-url http://127.0.0.1:30000/v1 \
  --num-examples 200
```

Please note that the above script is primarily a sanity check, not a rigorous accuracy or speed test.
This test can have significant variance (1%–5%) in accuracy due to batching and the non-deterministic nature of the inference engine.
Also, do not rely on the "Latency/Output throughput" from this script, as it is not a proper speed test.

GSM8K is too easy for many state-of-the-art models, so use a more challenging or feature-specific evaluation when appropriate. See [Evaluating New Models with SGLang](/docs/developer_guide/evaluating_new_models) for current MMLU, GSM8K, HellaSwag, GPQA, HumanEval, and MMMU commands. Additional examples are available in [test/manual/eval](https://github.com/sgl-project/sglang/tree/main/test/manual/eval).

## Benchmark the speed
Refer to [Benchmark and Profiling](./benchmark_and_profiling).

## Pull request titles

Use the repository-wide format checked by CI:

```text
[Type] scope: title
[Type] [Hardware] scope: title
```

- **Type**: `Feat`, `Fix`, `Refactor`, `Perf`, `Doc`, `Test`, `CI`, or `Chore`.
- **Scope**: A required module or model name. Use `/` for submodules, such as `diffusion/scheduler`; there is no fixed scope list or letter-case requirement.
- **Hardware**: Optional, for hardware-specific changes only. Use a single uppercase tag, such as `AMD` or `NVIDIA`, except for the canonical spellings `Intel`, `Apple`, `Huawei`, and `Ascend`.
- **Title**: A short, clear description in the imperative mood. Use one space between fields and after the colon, with no leading or trailing whitespace.

For example:

```text
[Fix] attention: Fix KV cache indexing
[Perf] diffusion/scheduler: Reduce scheduling overhead
[Perf] [AMD] diffusion/attention: Optimize decode performance
```

For reverts, keep GitHub's default `Revert "original title"` format. The PR-title check validates PR titles, not individual development commit messages.

## Requesting a review for merge
You can follow the pull request merge process described in [MAINTAINER.md](https://github.com/sgl-project/sglang/blob/main/.github/MAINTAINER.md).
You will need to work with the Merge Oncall, Codeowner, and other reviewers to get their approvals.
Then your PR can be merged.

## How to Trigger CI Tests

We have a lot of open PRs but limited CI machines, so only top and trusted contributors have permission to trigger CI tests.
Users with permission are listed in the [CI_PERMISSIONS.json](https://github.com/sgl-project/sglang/blob/main/.github/CI_PERMISSIONS.json)

**PR authors** can use `/rerun-failed-ci` on their own PRs even if they are not listed in `CI_PERMISSIONS.json`. Selective reruns have additional rules because they execute PR code on self-hosted runners; see the permission table below.

For CI to run on a pull request, it must have the "run-ci" label. Authorized users can add the label or rerun failed tests by commenting on the PR with one of these commands:

- `/tag-run-ci-label`: Adds the "run-ci" label. Only **future** commits trigger CI; the current commit is unaffected. Add the `extra` argument (`/tag-run-ci-label extra`) to additionally apply the "run-ci-extra" label, opting the PR into the extra test workflow (`pr-test-extra.yml`).
- `/rerun-failed-ci`: Reruns workflows from the latest commit with conclusion **failed, skipped, cancelled, or timed out**.
- `/tag-and-rerun-ci`: Runs both. Use this on a fresh PR to kick off CI on the current commit — `/tag-run-ci-label` alone won't. Accepts the same `extra` argument (`/tag-and-rerun-ci extra`).
- `/run-full-ci`: Baseline **and** extra CI. Short form of `/tag-and-rerun-ci extra` — applies both labels, then reruns everything at the current commit that didn't succeed.
- `/run-extra-ci`: Extra CI **only**. Applies both labels, then reruns just `PR Test Extra`, leaving baseline CI runs alone. Use it when baseline is already green and you only need the extra tier.
- `/rerun-test <test-spec> [<test-spec> ...]`: Reruns one or more specific tests directly. A spec may select a file, class, or method using `<file>::<TestClass>[.<test_method>]`. Multiple specs and file globs are supported. `--changed` (short form `-c`) adds every test file the PR itself adds or modifies (under `test/registered/` or the multimodal test directory), so a PR that touches several tests can rerun them all without listing them. Examples: `/rerun-test test_srt_endpoint.py`, `/rerun-test registered/core/test_srt_endpoint.py::TestSRTEndpoint.test_simple_decode`, `/rerun-test test_a.py test_b.py`, `/rerun-test test_*backend*.py`, `/rerun-test --changed`, or `/rerun-test -c`.
- `/rerun-group <group> [<group> ...]`: Expands one or more registered test groups (for example, `/rerun-group rust-server`) and dispatches their tests through the same selective-rerun workflow. Groups are defined in [`scripts/ci/rerun_test_groups.json`](https://github.com/sgl-project/sglang/blob/main/scripts/ci/rerun_test_groups.json).
- `/run-cpu-ci`: Runs only the CPU unit suite (`base-a-test-cpu`) against the PR head, partitioned the same way as in PR CI, without the `run-ci` label or any GPU stage. For a small PR, `/run-cpu-ci` plus `/rerun-group <module>` covers the unit tests and the affected module's tests. Alias: `/rerun-cpu-ci`.

The rerun commands have the following permission rules:

| Command | PR author | Other users | Additional rule for fork PRs |
| --- | --- | --- | --- |
| `/rerun-failed-ci` | Always allowed on their own PR | Must have `can_rerun_failed_ci` in `CI_PERMISSIONS.json` | None |
| `/run-full-ci`, `/run-extra-ci` | Not auto-allowed -- these apply labels, which the PR-author allowance does not cover | Must have both `can_tag_run_ci_label` and `can_rerun_failed_ci` in `CI_PERMISSIONS.json` (every listed user has both) | None |
| `/rerun-test`, `/rerun-group`, `/run-cpu-ci` | No special allowance; judged as any other commenter | Must have `cooldown_interval_minutes: 0` in `CI_PERMISSIONS.json`, or `write`/`admin` repository permission | None -- the same rule applies wherever the PR comes from |

<Warning>
Selective reruns do not build or install a PR-local `sglang-kernel` wheel. If a PR changes `python/sglang/kernels/aot/` or code that depends on that AOT change, use the normal/full PR CI workflow. A `/rerun-test` or `/rerun-group` result may use the pinned released kernel and does not validate the combined change.
</Warning>

If you have permission, the [Slash Command Handler](https://github.com/sgl-project/sglang/actions/workflows/slash-command-handler.yml) will run your command and react with a 👍 to your comment. It may take up to a few minutes for the reaction to appear. Here’s a usage [example](https://github.com/sgl-project/sglang/pull/14253#issuecomment-3599509302).

If a command isn't recognized, the handler reacts 😕 instead, and replies with the closest matching command when there is one. A comment with no reaction at all means the handler never saw it — check the command is spelled as listed above.

To avoid spamming a PR with too many `/rerun-failed-ci` comments, you can also trigger the command by editing an existing comment and adding any suffix (e.g., `/rerun-failed-ci try again`).

If you don’t have permission and you’re not the PR author, please ask maintainers to trigger CI for you.

### CI control labels

Four labels change how a PR's CI runs. Label before you trigger:
`max-concurrency` fixes the shard fan-out when the run is created.

| Label | Effect |
| --- | --- |
| `bypass-fail-fast` | A job failing no longer aborts its siblings; the run continues instead of stopping at the first root-cause failure. A failing `lint` still stops everything. |
| `parallel-stages` | Stages stop waiting on each other. `base-a`, `base-b` and `base-c` dispatch together, the way a scheduled run does. |
| `max-concurrency` | A suite fans out to all of its shards at once rather than a third of them. |
| `highest-priority` | All three of the above, and the PR is also skipped by the batch-cancel workflow, sorted first in the active-runs report, and never closed as stale. |

Each spends extra runner capacity, so they unblock a specific PR rather than
serve as a default.

### CI rate limits

Due to CI scheduling and limited resources, higher-priority PRs may preempt running jobs. In such cases, you may need to rerun the tests.
We apply CI rate limits to prevent abuse and ensure fair usage of our CI resources.

Each CI workflow has a default limit defined in its workflow configuration file. For example, in [pr-gate.yml](https://github.com/sgl-project/sglang/blob/main/.github/workflows/pr-gate.yml), the default cooldown period is 120 minutes, and each workflow can override it via the `cool-down-minutes` input parameter:

```yaml Config
cool-down-minutes:
  description: "Cooldown period in minutes for low-permission users; 0 disables rate limiting"
  type: number
  default: 120
```

Users listed in [CI_PERMISSIONS.json](https://github.com/sgl-project/sglang/blob/main/.github/CI_PERMISSIONS.json) may have a per-user cooldown interval. In practice, we use the minimum of the workflow’s default window and the user-specific interval.

## Code style guidance
- Avoid code duplication. If the same code snippet (more than five lines) appears multiple times, extract it into a shared function.
- Minimize device synchronization. Reduce expensive CPU-GPU synchronization operations, such as `tensor.item()` or `tensor.cpu()`, whenever possible. Use vectorized code.
- Prioritize extreme efficiency. SGLang is a runtime, and most of your code runs on the critical path for every request. Optimize all minor overheads as much as possible, especially in the model forward code.
  - A common pattern is some runtime checks in the model forward pass (e.g., [this](https://github.com/sgl-project/sglang/blob/f1b0eda55c2c4838e8ab90a0fac7fb1e3d7064ab/python/sglang/srt/models/deepseek_v2.py#L486-L491)). These are very likely the same for every layer. Please cache the result as a single boolean value in `__init__` whenever possible.
- Make functions as pure as possible. Avoid in-place modification of arguments.
- Prefer immutable data and compute configuration-derived values once during initialization when their inputs cannot change.
- Keep functions under roughly 100 lines and make orchestration functions read like high-level pseudocode by extracting details into focused helpers.
- Keep files concise. If a file exceeds 2,000 lines of code, split it into cohesive smaller modules.
- Avoid adding mixins; prefer composition or plain functions. Use `msgspec.Struct` for new data containers instead of `dataclasses.dataclass` or `attrs`.
- Prefer keyword arguments for calls with two or more arguments, and pass callees the specific values they need instead of a large state-holding object.
- In a file, put core data structures at the top of the file. Put utility functions at the bottom of the file.
- Keep tests run fast.
  - If a single test file runs longer than 500 seconds, split it into multiple smaller files (e.g., `test_eagle_infer_a.py`, `test_eagle_infer_b.py`).
  - If a single job in a GitHub Actions workflow runs longer than 30 minutes, split it into smaller jobs or steps.
  - Reuse server launches across test methods in E2E test files.
- Never use `pickle.loads()`, `pickle.load()`, or `recv_pyobj()` to deserialize untrusted or network-received data. Python's [pickle module is not secure](https://docs.python.org/3/library/pickle.html) — it can execute arbitrary code during deserialization. Use safe serialization formats such as [msgpack](https://github.com/jcrist/msgspec) or JSON instead.
- When supporting new hardware or features, follow these guidelines:
  - Do not drastically change existing code.
  - Always prefer new files to introduce specific components for your new hardware (e.g., `allocator_ascend.py`).
  - If you write multiple if/else blocks for new features, ensure the common path (e.g., NVIDIA hardware or the existing code path) is the first branch.

## How to update kernels in SGLang

Choose the implementation and release path based on the kernel's dependencies. For a lightweight kernel that does not depend on CUTLASS or another large C++ project, prefer the in-tree JIT kernel path. Use the AOT `sglang-kernel` path for heavyweight kernels, large C++ dependencies, or operations that need wheel packaging and Torch operator registration. FlashInfer-based kernels are an exception and may still use the JIT path. SGLang also consumes separately released custom builds of DeepGEMM and DeepEP; update those in their source repositories as described below.

### Update sglang-kernel

The `sglang-kernel` distribution (formerly `sgl-kernel`) is a separate Python package, but its source now lives in this repository under `python/sglang/kernels/aot/`. Normal PR CI builds and installs a PR-local `sglang-kernel` wheel, so it can test an AOT kernel and its caller together. This does not establish compatibility after merge: installed SGLang and scheduled CI use the released version pinned in `python/pyproject.toml`. If a caller unconditionally requires a new operator or a changed kernel contract, first merge and release the kernel, update the pinned `sglang-kernel` version, and then land the caller. A combined PR is acceptable only when every supported path remains correct with the pinned wheel—for example, when the caller checks operator availability and retains a semantically equivalent fallback until the released wheel includes the change. Selective `/rerun-test` and `/rerun-group` workflows do not install PR-local wheels and cannot validate the combined AOT path.

For an AOT kernel change:

1. Implement the kernel under `python/sglang/kernels/aot/csrc/` and update its declaration, Torch registration, and CMake source list.
2. Expose the Python API under `python/sglang/kernels/aot/python/sgl_kernel/`.
3. Add correctness tests under `python/sglang/kernels/aot/tests/` and a benchmark under `python/sglang/kernels/aot/benchmark/` when applicable.
4. Build and test from `python/sglang/kernels/aot/` following its [README](https://github.com/sgl-project/sglang/tree/main/python/sglang/kernels/aot/README.md). Do not bump the pinned `sglang-kernel` version in `python/pyproject.toml` merely to test a PR-local kernel change.

### Update sgl-deep-gemm

Develop SGLang's customized DeepGEMM package on the [`dev` branch of `sgl-project/DeepGEMM`](https://github.com/sgl-project/DeepGEMM/tree/dev). Rebase incoming changes onto `dev`, place new or modified package tests under `sgl_deep_gemm/tests/`, and follow the [`sgl-deep-gemm` README](https://github.com/sgl-project/DeepGEMM/blob/dev/sgl_deep_gemm/README.md) to build and install a local wheel. After the implementation is merged, ask the SGLang team to run the [sgl-deep-gemm release workflow](https://github.com/sgl-project/sglang/actions/workflows/release-whl-deepgemm.yml) with the new version, CUDA target, and DeepGEMM branch. Once all required wheels are published and verified, update the `sgl-deep-gemm` pin in `python/pyproject.toml` before landing SGLang code that requires the new or changed behavior.

### Update sgl-deep-ep

Develop `sgl-deep-ep` in [`sgl-project/DeepEP`](https://github.com/sgl-project/DeepEP). Use `sgl-deepep` for both implementation and packaging changes for CUDA 13 on x86_64 or aarch64. The [`sgl-deep-ep` README](https://github.com/sgl-project/DeepEP/blob/sgl-deepep/sgl_deep_ep/README.md) describes the platform prerequisites and release matrix.

To validate locally, check out `sgl-deepep` (or your development branch containing both the implementation and `sgl_deep_ep`) as `DeepEP-source`. Install the required build dependencies first. The following example builds a wheel for the host architecture, installs that exact wheel, and verifies that its guarded package import succeeds:

```bash
DEEPEP_OUTPUT_DIR="$(mktemp -d)"
bash DeepEP-source/sgl_deep_ep/build_sgl_deep_ep.sh \
  "${DEEPEP_OUTPUT_DIR}" \
  13.0 \
  "$(uname -m)"
python3 -m pip install --force-reinstall --no-deps \
  "${DEEPEP_OUTPUT_DIR}"/sgl_deep_ep-*.whl
python3 -c "import deep_ep; print(deep_ep.__file__)"
```

The import check validates packaging and binary loading, but not communication correctness. On a configured multi-GPU host, also run:

```bash
python3 DeepEP-source/tests/elastic/test_ep.py --num-processes 8
```

Adjust `--num-processes` to the available GPUs and run the internode or low-latency tests when those transports changed. After local validation, ask the SGLang team to run the [sgl-deep-ep release workflow](https://github.com/sgl-project/sglang/actions/workflows/release-whl-deepep.yml) with the new version and DeepEP ref. The workflow builds the implementation and packaging from that single ref (default: `sgl-deepep`). After verifying the published wheels for the supported Python versions and architectures, update the `sgl-deep-ep` pin in `python/pyproject.toml` before landing dependent SGLang changes.

## Tips for newcomers

If you want to contribute but don’t have a specific idea in mind, pick issues labeled [“good first issue” or “help wanted”](https://github.com/sgl-project/sglang/issues?q=is%3Aissue+label%3A%22good+first+issue%22%2C%22help+wanted%22). These tasks typically have lower complexity and provide an excellent introduction to the codebase.

Also check out the following materials as startup guide:
- [Mini-SGLang](https://github.com/sgl-project/mini-sglang) for a quick overview on the structure of sglang.
- [Code Walk-through](https://github.com/zhaochenyang20/Awesome-ML-SYS-Tutorial/tree/main/sglang/code-walk-through) for a deeper look into SGLang’s workflow.
- [GTC-2026 Training Lab](https://drive.google.com/file/d/1mwOZEtipNLJzrflCTodj34KhuOZEoEw5/view?usp=drive_link) for hands-on practices of how to do optimization, benchmarking, or profiling on a launched SGLang instance.

If you have any questions or want to start a discussion, please feel free to ask in our [Slack channel](https://slack.sglang.io).

Thank you for your interest in SGLang. Happy coding!

---

### Docs Developer Guide Development Guide Using Docker (`docs/docs/developer_guide/development_guide_using_docker.mdx`)

---
title: "Development Guide Using Docker"
sidebarTitle: "Using Docker"
metatags:
    description: "SGLang Docker development: VSCode dev container, remote tunnels, debugger setup, nsys profiling."
---

The `lmsysorg/sglang:dev` image is a nightly build from `main` with additional development tools and dependencies for modifying and testing SGLang. For running models without a development environment, use the stable or nightly images described in the [Installation guide](/docs/get-started/install).

## Setup VSCode on a Remote Host
(Optional - you can skip this step if you plan to run sglang dev container locally)

1. In the remote host, download `code` from [VSCode](https://code.visualstudio.com/download) and run `code tunnel` in a shell.

Example
```bash Command
wget https://vscode.download.prss.microsoft.com/dbazure/download/stable/fabdb6a30b49f79a7aba0f2ad9df9b399473380f/vscode_cli_alpine_x64_cli.tar.gz
tar xf vscode_cli_alpine_x64_cli.tar.gz

# https://code.visualstudio.com/docs/remote/tunnels
./code tunnel
```

2. In your local machine, press F1 in VSCode and choose "Remote Tunnels: Connect to Tunnel".

## Setup Docker Container

### Option 1. Use the default dev container automatically from VSCode
There is a `.devcontainer` folder in the sglang repository root folder to allow VSCode to automatically start up within dev container. You can read more about this VSCode extension in VSCode official document [Developing inside a Container](https://code.visualstudio.com/docs/devcontainers/containers).
<Frame>
  <img src="https://github.com/user-attachments/assets/6a245da8-2d4d-4ea8-8db1-5a05b3a66f6d" alt="VSCode Dev Container Architecture" />
</Frame>

*Figure 1: Diagram from VSCode official documentation [Developing inside a Container](https://code.visualstudio.com/docs/devcontainers/containers).*

To enable this, you only need to:
1. Start Visual Studio Code and install [VSCode dev container extension](https://marketplace.visualstudio.com/items?itemName=ms-vscode-remote.remote-containers).
2. Press F1, type and choose "Dev Container: Open Folder in Container.
3. Input the `sglang` local repo path in your machine and press enter.

The first time you open it in dev container might take longer due to docker pull and build. Once it's successful, you should set on your status bar at the bottom left displaying that you are in a dev container:

<Frame>
  <img src="https://github.com/user-attachments/assets/650bba0b-c023-455f-91f9-ab357340106b" alt="VSCode Dev Container Status Bar" />
</Frame>

Now when you run `sglang.launch_server` in the VSCode terminal or start debugging using F5, sglang server will be started in the dev container with all your local changes applied automatically:

<Frame>
  <img src="https://github.com/user-attachments/assets/748c85ba-7f8c-465e-8599-2bf7a8dde895" alt="SGLang Server Running in Dev Container" />
</Frame>


### Option 2. Start up containers manually (advanced)

The following startup command is an example for internal development by the SGLang team. You can **modify or add directory mappings as needed**, especially for model weight downloads, to prevent repeated downloads by different Docker containers.

❗️ **Note on RDMA**

    1. `--network host` and `--privileged` are required by RDMA. If you don't need RDMA, you can remove them but keeping them there does not harm. Thus, we enable these two flags by default in the commands below.
    2. You may need to set `NCCL_IB_GID_INDEX` if you are using RoCE, for example: `export NCCL_IB_GID_INDEX=3`.

```bash Command
# Change the name to yours
docker run -itd --shm-size 32g --gpus all -v <volumes-to-mount> --ipc=host --network=host --privileged --name sglang_dev lmsysorg/sglang:dev /bin/zsh
docker exec -it sglang_dev /bin/zsh
```
Some useful volumes to mount are:
1. **Huggingface model cache**: mounting model cache can avoid re-download every time docker restarts. Default location on Linux is `~/.cache/huggingface/`.
2. **SGLang repository**: code changes in the SGLang local repository will be automatically synced to the .devcontainer.

Example 1: Monting local cache folder `/opt/dlami/nvme/.cache` but not the SGLang repo. Use this when you prefer to manually transfer local code changes to the devcontainer.
```bash Command
docker run -itd --shm-size 32g --gpus all -v /opt/dlami/nvme/.cache:/root/.cache --ipc=host --network=host --privileged --name sglang_zhyncs lmsysorg/sglang:dev /bin/zsh
docker exec -it sglang_zhyncs /bin/zsh
```
Example 2: Mounting both HuggingFace cache and local SGLang repo. Local code changes are automatically synced to the devcontainer as the SGLang is installed in editable mode in the dev image.
```bash Command
docker run -itd --shm-size 32g --gpus all -v $HOME/.cache/huggingface/:/root/.cache/huggingface -v $HOME/src/sglang:/sgl-workspace/sglang --ipc=host --network=host --privileged --name sglang_zhyncs lmsysorg/sglang:dev /bin/zsh
docker exec -it sglang_zhyncs /bin/zsh
```
## Debug SGLang with VSCode Debugger
1. (Create if not exist) open `launch.json` in VSCode.
2. Add the following config and save. Please note that you can edit the script as needed to apply different parameters or debug a different program (e.g. benchmark script).
     ```JSON Config
       {
          "version": "0.2.0",
          "configurations": [
              {
                  "name": "Python Debugger: launch_server",
                  "type": "debugpy",
                  "request": "launch",
                  "module": "sglang.launch_server",
                  "console": "integratedTerminal",
                  "args": [
                      "--model-path", "meta-llama/Llama-3.2-1B",
                      "--host", "0.0.0.0",
                      "--port", "30000",
                      "--trust-remote-code",
                  ],
                  "justMyCode": false
              }
          ]
      }
    ```

3. Press "F5" to start. VSCode debugger will ensure that the program will pause at the breakpoints even if the program is running at remote SSH/Tunnel host + dev container.

## Profile

```bash Command
# Change batch size, input, output and add `disable-cuda-graph` (for easier analysis)
# e.g. DeepSeek V3
nsys profile -o deepseek_v3 python3 -m sglang.benchmark.one_batch --batch-size 1 --input 128 --output 256 --model deepseek-ai/DeepSeek-V3 --trust-remote-code --tp 8 --disable-cuda-graph
```

## Evaluation

```bash Command
# GSM8K via sgl-eval: all 1319 test questions
sgl-eval run gsm8k \
  --base-url http://127.0.0.1:30000/v1 \
  --num-examples 1319 \
  --num-threads 2000
```

---

### Docs Developer Guide Development Jit Kernel Guide (`docs/docs/developer_guide/development_jit_kernel_guide.mdx`)

---
title: "Development Guide for JIT Kernels"
sidebarTitle: "JIT Kernels"
metatags:
    description: "SGLang JIT kernel development: clangd setup, TensorMatcher, LaunchKernel, add_constant example walkthrough."
---
## Environment Setup

We strongly recommend using `clangd` as the language server for JIT kernel development.
For Ubuntu/Debian, you can download clangd from [apt.llvm.org](https://apt.llvm.org/).
If you are using VS Code, we recommend installing the `clangd` extension for better IDE integration.

All JIT-related files are located in `python/sglang/kernels/jit`.
Unlike `sgl-kernel`, which compiles CUDA/C++ binaries ahead of time (AOT), just-in-time (JIT) kernels are compiled at runtime.
Consequently, a static `compile_commands.json` cannot be generated.
To enable code completion with `clangd`, run `python -m sglang.kernels.jit` to generate a `.clangd` configuration file in your current directory.
After generating the file, restart the clangd language server. It should now recognize all JIT kernel files.

## Code Structure

### C++ Implementation

C++ source code is located in `python/sglang/kernels/jit/csrc`.
Reusable functions should be placed in `python/sglang/kernels/jit/include`.

JIT C++ lives in `namespace sglang`: open it after the include block and close it at the
end of the file, with the device kernels and the host wrapper both inside.
The shared `host::` and `device::` helpers are nested in it as well, so they resolve unqualified
and need no `sglang::` prefix.

We use [tvm-ffi](https://github.com/apache/tvm-ffi) for efficient foreign language bindings.
Refer to the [documentation](https://tvm.apache.org/ffi/) for advanced usage, such as exporting C++ objects.
Typically, `tvm::ffi::TensorView` is sufficient for passing PyTorch Tensors from Python.

### Python Interface

Python interfaces are defined in `python/sglang/kernels/jit`.
The `load_jit` utility function in `python/sglang/kernels/jit/utils/compile.py` loads and returns the compiled module.
To export a C++ function (e.g., `cpp_func`), pass `cuda_wrappers=[("func", "cpp_func")]` to `load_jit`.
The function can then be called in Python as `module.func`.
`load_jit` emits the export wrapper inside `namespace sglang`, so write `cpp_func` without a
`sglang::` prefix.

For caching compiled modules, prefer `sglang.kernels.jit.utils.cache_once` over `functools.lru_cache`.
`functools.lru_cache` is not compatible with `torch.compile`.

### C++ Utilities

The following C++ utilities are available:

#### Integer Range

Similar to PyTorch, we provide an `irange` function to represent an integer range.

```C++ Example
#include <sgl_kernel/utils.h>

void test() {
  for (auto i : host::irange(100)) { // [0, 100)
    // do something
  }
  for (auto i : host::irange(0, 100)) { // [0, 100)
    // do something
  }
}

```

#### Runtime Checking

`CHECK_HOST` is the preferred runtime check: stream-style, and zero overhead when the
check passes — the message expressions are only evaluated on failure.
`RuntimeCheck` is the function-style alternative; note its message arguments are always
evaluated, even when the check passes.
`RuntimeDeviceCheck` verifies the status of the last kernel launch, and `CHECK_CUDA`
is its stream-style equivalent for checking a `cudaError_t` with extra context.

```C++ Example
#include <sgl_kernel/utils.h>
#include <sgl_kernel/utils.cuh>

void test() {
  CHECK_HOST(1 + 1 == 2) << 1 + 1 << " != " << 2;  // preferred
  host::RuntimeCheck(1 + 1 == 2, 1 + 1, " != ", 2);
  host::RuntimeDeviceCheck();
  // check the provided `cudaError_t`
  host::RuntimeDeviceCheck(cudaGetLastError());
  CHECK_CUDA(cudaGetLastError()) << "after my_kernel launch";
}

```

#### Tensor Checking

`TensorMatcher` provides a readable way to validate and extract tensor shape information.

```cpp Example
#include <sgl_kernel/tensor.h>

void test(const tvm::ffi::TensorView k_cache, const tvm::ffi::TensorView v_cache) {
  using namespace host;

  auto D = SymbolicSize{"D"};  // cache dimension
  auto N = SymbolicSize{"N"};  // kvcache stride
  auto dtype = SymbolicDType{};
  auto device = SymbolicDevice{};

  TensorMatcher({-1, D})  //
      .with_strides({N, 1})
      .with_dtype<int32_t, int64_t>(dtype)
      .with_device<kDLCUDA, kDLCPU>(device)
      .verify(k_cache)
      .verify(v_cache);
}
```

Configure the `TensorMatcher` with expected stride, dtype, and device properties before verification.
- If `with_strides` is omitted, the tensor is expected to be contiguous.
- Template arguments in `with_dtype` restrict the allowed data types.
- Template arguments in `with_device` restrict the allowed devices.
- Values passed to `with_xxx` methods enforce equality checks.
- Passing `-1` for size or stride allows matching any value.

A `Symbolic` variable must resolve to the same value across all verifications.
Use `.unwrap()` to retrieve the matched value after verification.

> Note: `TensorMatcher` is a temporary expression and should not be stored in a variable.

> Tip: Add `//` at the end of the `TensorMatcher` chain to enforce proper indentation.

#### Kernel Launching

`LaunchKernel::resolve_device` retrieves the current `cudaStream` from PyTorch.
Kernels can also be launched directly using `LaunchKernel`.

```cpp Example
#include <sgl_kernel/utils.cuh>

#include <dlpack/dlpack.h>

__global__ void kernel() {}

void test() {
  const auto num_blocks = 1;
  const auto num_threads = 32;
  const auto dynamic_smem = 0;

  DLDevice dev;  // suppose this is initialized properly
  host::LaunchKernel(num_blocks, num_threads, dev)(kernel);

  cudaStream_t stream = host::LaunchKernel::resolve_device(dev);
  host::LaunchKernel(num_blocks, num_threads, stream, dynamic_smem)(kernel);
}

```

## Add new kernels

This section walks through a complete, end-to-end example of adding a new JIT kernel to the system.
We use a simple add_constant kernel as a running example, which adds a constant integer value to every element of an input tensor.

Conceptually, the Python interface looks like this:

```python Example
def add_constant(src: torch.Tensor, c: int):
    return src + c
```

### STEP 1: Write the C++ kernel

Write your CUDA kernel in [kernels/jit/csrc/elementwise/add_constant.cuh](https://github.com/sgl-project/sglang/blob/main/python/sglang/kernels/jit/csrc/elementwise/add_constant.cuh). For demonstration purposes, we pass the constant value as a template parameter.

```
/* Detailed source-code truncated for AI context efficiency. */
```

### STEP 2: Create Python Interfaces

Next, expose the kernel through a Python wrapper.
Create a new file at [kernels/ops/elementwise/add_constant.py](https://github.com/sgl-project/sglang/blob/main/python/sglang/kernels/ops/elementwise/add_constant.py) and expose the needed interfaces.

```python Example
from __future__ import annotations
from typing import TYPE_CHECKING

import torch

from sglang.kernels.jit.utils import cache_once, load_jit, make_cpp_args

if TYPE_CHECKING:
    from tvm_ffi.module import Module


@cache_once
def _jit_add_constant_module(constant: int) -> Module:
    args = make_cpp_args(constant)  # pass all the template argument
    return load_jit(
        "add_constant",
        *args,
        cuda_files=["elementwise/add_constant.cuh"],
        cuda_wrappers=[("add_constant", f"add_constant<{args}>")],
    )


def add_constant(src: torch.Tensor, constant: int) -> torch.Tensor:
    if not src.is_cuda:
        raise RuntimeError("src must be a CUDA tensor")
    if src.dtype != torch.int32:
        raise RuntimeError(f"Unsupported dtype {src.dtype}. Supported: int32")
    dst = torch.empty_like(src)
    module = _jit_add_constant_module(constant)
    module.add_constant(dst, src)
    return dst

```

Keep the Python wrapper thin, but still validate the basic invariants such as device and dtype before dispatch. In the current JIT/FFI path, invalid tensors are not always rejected safely before launch.

### STEP 3: Use your kernel

Finally, import and use the kernel like a regular Python function:

```python Example
from sglang.kernels.ops.elementwise.add_constant import add_constant
```

For a complete, runnable example, refer to [test_add_constant.py](https://github.com/sgl-project/sglang/blob/main/test/registered/kernels/ops/elementwise/test_add_constant.py).

## C++ Include Library Reference

The JIT kernel framework provides a set of reusable C++ headers in
`python/sglang/kernels/jit/include/sgl_kernel/`. Each header is designed
to be lightweight and self-contained. Below is a summary of each header
and its key APIs.

### Core Utilities

<table>
  <thead>
    <tr>
      <th>Header</th>
      <th>Namespace</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>utils.h</code></td>
      <td><code>host</code></td>
      <td>Host-side essentials: <code>RuntimeCheck</code>, <code>CHECK_HOST(cond) &lt;&lt; ...</code>, <code>Panic</code>, <code>div_ceil</code>, <code>irange</code></td>
    </tr>
    <tr>
      <td><code>utils.cuh</code></td>
      <td><code>device</code> / <code>host</code></td>
      <td>Type aliases (<code>fp16_t</code>, <code>bf16_t</code>, ...), <code>SGL_DEVICE</code> macro, PDL helpers, <code>LaunchKernel</code>, <code>RuntimeDeviceCheck</code>, <code>CHECK_CUDA(expr) &lt;&lt; ...</code></td>
    </tr>
    <tr>
      <td><code>source_location.h</code></td>
      <td>(global)</td>
      <td>Portable <code>std::source_location</code> wrapper for error reporting</td>
    </tr>
    <tr>
      <td><code>runtime.cuh</code></td>
      <td><code>host::runtime</code></td>
      <td>CUDA runtime queries: <code>get_blocks_per_sm</code>, <code>get_sm_count</code>, <code>get_cc_major</code>, <code>get_runtime_version</code>, <code>get_available_dynamic_smem_per_block</code></td>
    </tr>
  </tbody>
</table>

### Tensor Validation

<table>
  <thead>
    <tr>
      <th>Header</th>
      <th>Namespace</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>tensor.h</code></td>
      <td><code>host</code></td>
      <td><code>TensorMatcher</code>, <code>SymbolicSize</code>, <code>SymbolicDType</code>, <code>SymbolicDevice</code></td>
    </tr>
  </tbody>
</table>

### Math & Type System

<table>
  <thead>
    <tr>
      <th>Header</th>
      <th>Namespace</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>math.cuh</code></td>
      <td><code>device::math</code></td>
      <td><code>max</code>, <code>min</code>, <code>abs</code>, <code>sqrt</code>, <code>rsqrt</code>, <code>exp</code>, <code>sin</code>, <code>cos</code>, constants</td>
    </tr>
    <tr>
      <td><code>type.cuh</code></td>
      <td>(global) / <code>device</code></td>
      <td><code>DTypeTrait&lt;T&gt;</code>, <code>packed_t&lt;T&gt;</code>, <code>device::cast&lt;To&gt;(from)</code></td>
    </tr>
  </tbody>
</table>

### Memory Access

<table>
  <thead>
    <tr>
      <th>Header</th>
      <th>Namespace</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>vec.cuh</code></td>
      <td><code>device</code></td>
      <td><code>AlignedVector&lt;T, N&gt;</code> - vectorized load/store (up to 128-bit; 256-bit requires Blackwell GPUs)</td>
    </tr>
    <tr>
      <td><code>tile.cuh</code></td>
      <td><code>device::tile</code></td>
      <td><code>Memory&lt;T&gt;</code> - cooperative tiled memory I/O (thread/warp/CTA)</td>
    </tr>
  </tbody>
</table>

### Parallel Primitives

<table>
  <thead>
    <tr>
      <th>Header</th>
      <th>Namespace</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>warp.cuh</code></td>
      <td><code>device::warp</code></td>
      <td><code>reduce&lt;Op, kNumThreads, kInner&gt;</code> (SUM/MAX/MIN, grouped or inter-group) and <code>reduce_sum</code> / <code>reduce_max</code> / <code>reduce_min</code> wrappers via <code>__shfl_xor_sync</code></td>
    </tr>
    <tr>
      <td><code>cta.cuh</code></td>
      <td><code>device::cta</code></td>
      <td><code>reduce_max</code> across warps via shared memory</td>
    </tr>
    <tr>
      <td><code>atomic.cuh</code></td>
      <td><code>device::atomic</code></td>
      <td><code>max</code> - atomic float max (CUDA + ROCm fallback)</td>
    </tr>
  </tbody>
</table>

### Reusable Kernel Templates

<table>
  <thead>
    <tr>
      <th>Header</th>
      <th>Namespace</th>
      <th>Purpose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><code>impl/norm.cuh</code></td>
      <td><code>host::norm</code> / <code>device::norm</code></td>
      <td>RMSNorm building blocks (warp &amp; CTA paths, <code>StorageType</code>)</td>
    </tr>
  </tbody>
</table>

---

### Docs Developer Guide Evaluating New Models (`docs/docs/developer_guide/evaluating_new_models.mdx`)

---
title: "Evaluating New Models with SGLang"
metatags:
    description: "SGLang model evaluation: MMLU, GSM8K, GPQA, HumanEval, MMMU benchmarks. Latency and throughput testing commands."
---
This document provides commands for evaluating models' accuracy and performance. Before open-sourcing new models, we strongly suggest running these commands to verify whether the score matches your internal benchmark results.

**For cross verification, please submit commands for installation, server launching, and benchmark running with all the scores and hardware requirements when open-sourcing your models.**

[Reference: MiniMax M2](https://github.com/sgl-project/sglang/pull/12129)

## Accuracy

### LLMs

SGLang provides built-in scripts to evaluate common benchmarks.

**MMLU**

```bash Command
sgl-eval run mmlu \
  --base-url http://127.0.0.1:30000/v1 \
  --num-examples 1000 \
  --max-tokens 8192
```

**GSM8K**

```bash Command
sgl-eval run gsm8k \
  --base-url http://127.0.0.1:30000/v1 \
  --num-examples 200
```

**HellaSwag**

```bash Command
python benchmark/hellaswag/bench_sglang.py \
  --host 127.0.0.1 \
  --port 30000 \
  --num-questions 200 \
  --num-shots 20
```

**GPQA**

```bash Command
sgl-eval run gpqa \
  --base-url http://127.0.0.1:30000/v1 \
  --num-examples 198 \
  --max-tokens 120000 \
  --n-repeats 8
```

<Tip>
For reasoning models, add `--thinking` (DeepSeek-V3 / Kimi-K2 style `thinking` key) or `--chat-template-kwarg enable_thinking=true` (Qwen3 / GLM style). You may skip it if the model has forced thinking enabled.
</Tip>

**HumanEval**

```bash Command
pip install human_eval

python -m sglang.test.run_eval \
  --eval-name humaneval \
  --num-examples 10 \
  --port 30000
```

### VLMs

**MMMU**

```bash Command
python benchmark/mmmu/bench_sglang.py \
  --port 30000 \
  --concurrency 64
```

<Tip>
You can set max tokens by passing `--extra-request-body '{"max_tokens": 4096}'`.
</Tip>

For models capable of processing video, we recommend extending the evaluation to include `VideoMME`, `MVBench`, and other relevant benchmarks.

## Performance

Performance benchmarks measure **Latency** (Time To First Token - TTFT) and **Throughput** (tokens/second).

### LLMs

**Latency-Sensitive Benchmark**

This simulates a scenario with low concurrency (e.g., single user) to measure latency.

```bash Command
python -m sglang.bench_serving \
  --backend sglang \
  --host 0.0.0.0 \
  --port 30000 \
  --dataset-name random \
  --num-prompts 10 \
  --max-concurrency 1
```

**Throughput-Sensitive Benchmark**

This simulates a high-traffic scenario to measure maximum system throughput.

```bash Command
python -m sglang.bench_serving \
  --backend sglang \
  --host 0.0.0.0 \
  --port 30000 \
  --dataset-name random \
  --num-prompts 1000 \
  --max-concurrency 100
```

**Single Batch Performance**

You can also benchmark the performance of processing a single batch offline.

```bash Command
python -m sglang.bench_one_batch_server \
  --model <model-path> \
  --batch-size 8 \
  --input-len 1024 \
  --output-len 1024
```

You can run more granular benchmarks:

- **Low Concurrency**: `--num-prompts 10 --max-concurrency 1`
- **Medium Concurrency**: `--num-prompts 80 --max-concurrency 16`
- **High Concurrency**: `--num-prompts 500 --max-concurrency 100`

## Reporting Results

For each evaluation, please report:

1.  **Metric Score**: Accuracy % (LLMs and VLMs); Latency (ms) and Throughput (tok/s) (LLMs only).
2.  **Environment settings**: GPU type/count, SGLang commit hash.
3.  **Launch configuration**: Model path, TP size, and any special flags.
4.  **Evaluation parameters**: Number of shots, examples, max tokens.

---

### Docs Developer Guide Layer Boundary (`docs/docs/developer_guide/layer_boundary.mdx`)

---
title: "Layer boundaries"
description: "Declare stage inputs and outputs, bind communication and residual operations, and integrate model computation with layer boundaries."
---

The `sglang.srt.layers.layer_boundary` package manages the transition between compute stages. It completes outstanding reductions, moves token rows, applies the producer's residual update, and prepares the consumer's normalized or quantized input. The model continues to run attention, dense FFNs, and MoE computation.

Use this guide when integrating a model or changing a boundary implementation. The first part explains the concepts, the second shows how to integrate a model, and the last describes the internals you touch when you extend the package. It documents the current internal interfaces; they are not a versioned plugin API. For model development setup, see the [contribution guide](/docs/developer_guide/contribution_guide).

## Scope and ownership

A boundary connects a **producer output** to a **consumer input**. An attention-to-FFN transition and an FFN-to-attention transition use the same contracts. A model can also have consecutive mixers, consecutive FFNs, or a branch containing three or more stages. Here a mixer is a token-mixing stage, such as attention or the Mamba block in Nemotron-H.

| Responsibility | Owner |
| --- | --- |
| Attention, projections, activation functions, expert routing, EP dispatch/combine | Model compute modules |
| How a producer contributes to the residual | Producer's `ResidualUpdate` |
| How a consumer reads the residual | Consumer's `ResidualReadout` and norm |
| Supported row transitions and reduction ordering | Bound boundary paths |
| Actual outstanding work and residual tensors | Per-forward `ResidualStream` |
| Hardware-specific fused completion | Fusion providers |
| Retention of auxiliary tensors | Auxiliary-output collector |

EP all-to-all is an operation inside MoE computation, not an input preparation step. The boundary does describe the MoE's input/output rows and any output reduction that compute delegates to it.

## Core concepts

### Token layouts and sums

`Layout.sharded` describes which supported token axes partition a rank's rows:

- `ATTN_DP`: different attention data-parallel token sets.
- `ATTN_CP`: context-parallel (CP) token partitions for an active CP batch.
- `ATTN_TP`: token slices distributed across attention-TP ranks.

Size-one axes are omitted. Layout is not a `DTensor` placement or a general cross-mesh redistribution engine. It does not describe arbitrary hidden-dimension sharding. The actual row ordering, padding, and per-rank counts come from batch metadata and the paired movement operations.

A sum is described separately by `SumGroup`: attention TP, full TP, or the MoE output reduction group. Separating rows from sums lets the boundary express both an unreduced contribution and the rows on which its completion must land.

### Producer contracts and output state

A declaration states how its compute cooperates with the boundary's reduction decision:

| Contract or state | Meaning |
| --- | --- |
| `ProducerReduction.ALWAYS_PARTIAL` | Attention only (the `declare_attn()` default): compute always returns a contribution requiring a sum and publishes it with `finish()`; the next stage's input completes the sum. Build its output projection so that it never reduces (for example `reduce_results=False`) |
| `ProducerReduction.EXIT_SCOPED` | The exit completes the sum or carries it to the next stage's input: every FFN, and `declare_attn(reduction=ProducerReduction.EXIT_SCOPED)` for a mixer |
| `OutputContract.may_*` | Construction-time permission to leave the sum to a particular later step |
| `Contribution.owed` | Work this specific output still requires |
| `OwedOutput` | Model-facing handle preventing ordinary tensor use of that unfinished output |

`UnreducedOutput` is an internal adapter form. `ResidualStream.record()` converts it into an owned contribution and an opaque model handle. `DeferredFinalize` represents producer-specific work such as a deferred MoE finalize; its `complete()` supplies an unfused completion path. A handoff is consumed by the next layer's input or, at the end of the stack, by a final norm that accepts it.

### Residual stream

`ForwardBatch.residual_stream` carries the residual and the producer's actual contribution from one boundary to the next. A stream has three states:

| State | Stored data | Next preparation |
| --- | --- | --- |
| Initial | Neither residual nor contribution | Initialize residual through the consumer's `init_residual` |
| Written | Residual, no pending contribution | Read input without applying another update |
| Pending | Contribution, optionally an existing residual | Complete owed work, apply the producer update, then read |

The model keeps the tensor or handle that each boundary call returns, and passes exactly that value to the next call. Rebinding a layer's output to a different object, or passing another microbatch's output, raises an error instead of applying the wrong pending work. The check compares object identity, so an in-place change to a complete tensor is not detected; do not modify layer outputs in place, and add extra contributions through `add_to_output()`.

Communication completion and residual update are distinct steps. The `residual.batch` helpers expose them:

| Helper | Effect |
| --- | --- |
| `complete_output(hidden_states, forward_batch)` | Finishes outstanding communication/finalize work and leaves the update pending |
| `fold(hidden_states, forward_batch)` | Completes a plain contribution and folds it into the residual, leaving a written stream |
| `set_written(hidden_states, forward_batch)` | Replaces the stream with a written one whose residual is `hidden_states`. Use it after compute that produced the full residual itself. It discards any pending contribution, so call `fold()` first when one may be pending |
| `take_output(hidden_states, forward_batch)` | Releases the stream at a terminal exit whose output is already written, such as Nemotron-H MTP after its internal fold and norm. It rejects a pending contribution |

Always retain the returned tensor or handle after each of these calls. A stack-entry boundary accepts a written stream and skips its `init_residual` operation.

### Residual update and input read

The producer owns `ResidualUpdate`; the consumer owns `ResidualReadout` and its norm. The actual update travels with the contribution. Bound paths use declared update capabilities to select valid ordering:

- A plain add can participate in compatible fused add+norm kernels or add the residual on one rank before summation.
- A nonlinear update cannot generally move before reduction. The post operation of manifold-constrained hyper-connections (MHC) is one such case.
- `applied_at_exit` requests an update at the producer exit. A deferred update must guarantee that its parameters and state outlive that producer.
- `ResidualReadout.reads_before_dp_gather` preserves reads that must execute on the source rows before a DP gather.
- A read that needs every row of the attention's, such as one that adds a contribution computed for every row, declares `reads_after_attn_tp_gather`. A producer that would leave its output on this rank's attention-TP slice then returns it to the attention's rows; Qwen4-exp's per-layer embedding read and Kimi K3's attention-residual bank declare it.

A read returns `(compute_input, residual)`. `update_and_read()` receives the producer's update together with the read, so an implementation can fuse them: the plain add+norm read does, and keeps its FP32 accumulation instead of normalizing a separately rounded snapshot. Fusion is not guaranteed. An implementation such as MHC may run the update and the read as separate steps, provided it preserves its existing rounding order.

The MHC adapter implements the expanded residual and coefficient state used by its integrated models. Do not assume every MHC model uses it: DeepSeek V4 retains its model-specific MHC path.

## Integrate a model

### Declare a standard attention and FFN layer

A `StageDeclaration` is the model-facing description. It contains read/update operations, dense versus sparse compute facts, reduction cooperation, and optional source declarations. It does not own a norm or an execution plan.

The following constructor fragment assumes the model has already initialized its compute modules and norms, and the worker's runtime parallel configuration is available. It follows the dense Qwen3 integration:

```python
from sglang.srt.layers.layer_boundary import (
    append_stages,
    declare_attn,
    declare_ffn,
)

self.attn_boundary, self.ffn_boundary = append_stages(
    (declare_attn(), self.input_layernorm),
    (declare_ffn(), self.post_attention_layernorm),
)
```

`append_stages()` extends the open layer stack: the stack records the last stage appended, and the next append takes it as its producer, so a layer needs no description of its neighbours. `make_layers()` (and `make_pp_layers()`, which calls it) opens a stack around the layers it builds. A model that builds its layers another way, such as a hand-written `nn.ModuleList` or a NextN/multi-token-prediction (MTP) draft, opens the stack itself; appending outside an open stack raises:

```python
from sglang.srt.layers.layer_boundary import layer_stack

with layer_stack():
    self.layers = nn.ModuleList(
        DecoderLayer(config, layer_id) for layer_id in range(config.num_hidden_layers)
    )
```

Every stage binds when the stack closes, once its producer and its consumer are known: the stage appended before it and the one appended after it. The last stage ends the model's layer stack and is marked terminal, unless a later layer declares a stage. A boundary's `declaration` is usable at once; when the stack closes, it is replaced by the declaration with its place in the stack (its `previous` and `terminal`), and the plan is bound. An error raised while binding carries a note naming the `append_stages()` call it came from. A terminal stage leaves no work for a following layer, except the final-norm finalize handoff described in [Enter and leave the layer stack](#enter-and-leave-the-layer-stack). A NextN/MTP draft module is its own stack: its layer enters the stack and ends it, even when it reuses the target's decoder class.

Pipeline parallelism splits one layer stack across ranks, so the first and last local stages have neighbours that another rank builds. The model gives `make_layers()` (or `make_pp_layers()`) its shared declaration function, `stage_facts`: given a global layer index, it returns the stages that layer declares, in order (an empty tuple for a layer that declares none), from the config, the layer index, construction options known before the layer is built, and the fixed parallel topology, never from built modules or provider state. The layer declares its own stages with the same function, so both ranks derive a boundary from one source; under pipeline parallelism `make_layers()` also checks each layer it builds against the function. When the stack closes, it asks the function for the stages next to it, nearest layer first, passing over a layer that declares none, and keeps only what binding reads of them (`facts_of()`: the capabilities a read, update and output transform declare, not the objects). A model whose layers declare stages must give the function to run under pipeline parallelism; no rank builds a layer another rank holds.

Each item may include a third element containing constructor options: an attention stage accepts `qkv_latent_func` (for example `{"qkv_latent_func": self.self_attn.prepare_qkv_latent}`) and `fusions`; an FFN stage accepts only `fusions` (see [Fusion providers](#fusion-providers-and-output-decisions)). An option a stage does not take is rejected when appended. Pass declarations fresh from `declare_attn()` / `declare_ffn()`: one taken from a bound boundary already has its place in a stack, and is rejected.

### Single-stage mixers and heterogeneous stacks

For heterogeneous layer stacks, append the actual stages in order; the framework does not require an alternating attention/FFN pattern, and a layer may append a single stage.

A single-stage `ProducerReduction.EXIT_SCOPED` mixer's consumer decides whether the mixer leaves its attention-TP sum to the next stage: always before an FFN, and per batch before another mixer. The stack binds the mixer only once its consumer is known, so the two stages always agree, across a pipeline boundary too: there the consumer is the next rank's first stage, which `make_layers()` reads from the neighbouring layer. At a pipeline boundary `to_pp()` completes the sum before the handoff, and the receiving FFN takes the completed path its entry binds beside the one for the declared sum.

`models/nemotron_h_utils.py` (used by `models/nemotron_h.py`) builds each Nemotron-H stage as `append_stages((decl, norm))`, with mixers declared as `declare_attn(reduction=ProducerReduction.EXIT_SCOPED, gathers_attn_tp_input=False)`.

### More than two stages and branches

There is no two-stage limit. For example, LongCat constructs a dense FFN, attention, and another dense FFN from an input already prepared for its MoE branch:

```python
first_ffn, second_attn, second_ffn = append_stages(
    (declare_ffn(), first_ffn_norm),
    (declare_attn(), second_attn_norm),
    (declare_ffn(), second_ffn_norm),
    prepared_from=moe_boundary.declaration,
)
```

This fragment assumes the source boundary and the three norms already exist. `prepared_from` means the source has already performed its read. A branch is a side path that the model merges back explicitly: it neither extends the stack nor waits for a consumer, so the next append still follows the source. Enter through `branch_input(source, hidden_states, forward_batch)`, not `prepare()`, to move that input and fork the residual stream without normalizing twice. The first stage's norm is therefore never applied; LongCat passes the MoE stage's norm there.

The branch adapter also provides `branch_output()` to complete the sum a branch's contribution owes and place it on the branch's exit rows and `merge_branch()` to combine it with another branch's output. These methods encode row movement and residual ownership; the model still determines its compute schedule. Branch transport currently supports only ordinary token rows: construction rejects context-parallel, input-scattered, and sequence-parallel variants. See `python/sglang/srt/models/longcat_flash.py` for a complete integration.

### Execute a layer

The corresponding forward fragment keeps computation in the model:

```python
hidden_states = self.attn_boundary.prepare(hidden_states, forward_batch)
if hidden_states.shape[0] != 0:
    hidden_states = self.self_attn(
        positions=positions,
        hidden_states=hidden_states,
        forward_batch=forward_batch,
    )
hidden_states = self.attn_boundary.finish(hidden_states, forward_batch)

hidden_states = self.ffn_boundary.prepare(hidden_states, forward_batch)
hidden_states = self.mlp(hidden_states, forward_batch=forward_batch)
hidden_states = self.ffn_boundary.finish(hidden_states, forward_batch)
```

This example uses Qwen3's compute member name `mlp`; boundary construction does not require renaming compute classes or checkpoint parameters.

`prepare()` returns input in the consumer read's format, which can include quantized tensors. An attention with an `ALWAYS_PARTIAL` output contract uses `finish()` to register its contribution, and an FFN or single-stage mixer uses `finish()` to complete or carry on the sum its output owes. An FFN whose boundary has fusions, which may take a MoE finalize handoff, runs its compute under `exit()` instead and calls the returned object's `finish()` once (`finish()` on the boundary rejects it); the exit context restores the previous runtime flags even when compute raises, so do not call `finish()` on a failed computation.

Compute never sums a stage's output: build every output projection, MLP and MoE block of a stage with `reduce_results=False`, and leave the sum the output owes to the boundary. The boundary completes it at the exit, or carries it to the next stage's input, where a fused all-reduce + add + norm may take it:

- `FfnExit` decides before compute runs whether the exit completes the sum, a reduce-scatter on the way back completes it, or the next input does. It publishes only `defer_moe_finalize` on `get_forward()`: a MoE may then return a `DeferredFinalize`.
- `MixerExit`: before an FFN, the mixer always leaves its attention-TP sum to the FFN's input, including under attention DP. Before another mixer the exit may carry the sum to that mixer's input, but never under attention DP; otherwise it completes the sum itself.

One exception: when an FFN's output sum is fused with a reduction its computation needs anyway, so the two cannot be separated without an extra collective, the computation completes it and the stage declares `declare_ffn(output_complete=True)`; the exit then owes no sum. Kimi K3's latent MoE reduces its latent before the latent norm and completes the shared experts' sum beside it.

A component every TP rank computes in full (a shared expert replicated with `tp_size=1`, LoRA-B on a partial sum) is added on TP rank 0 only, so that the one sum counts it once. Model loading fails if a module under a stage boundary is built with `reduce_results=True`. Returning a handoff while `defer_moe_finalize` is false fails in `finish()`.

A complete tensor after `finish()` can still have a pending **residual update**. An incomplete reduction is exposed to the model as an opaque `OwedOutput`; pass it to the next boundary or a supported access method. Do not inspect it as a tensor, slice it, or unwrap its contribution in model code.

### Enter and leave the layer stack

Initialize a fresh stream once on the embedding path, and leave the stack through the final norm:

```python
from sglang.srt.layers.layer_boundary.residual import batch as residual_batch

residual_batch.start(forward_batch)
hidden_states = self.embed_tokens(input_ids)
for layer in self.layers:
    hidden_states = layer(positions, hidden_states, forward_batch)
hidden_states = residual_batch.final_norm(
    hidden_states, forward_batch, self.norm, skip_empty=True
)
```

`skip_empty=True` still completes owed work on an empty batch, which may be a collective that other ranks join, and skips only the norm kernel. `final_norm()` and `to_pp()` release the batch's stream after they hand on its output.

When the final read is more than a norm, pass it to `make_layers(final_read=...)` (or `layer_stack(final_read=...)`): it is then the last stage's consumer. Its `attn_tp_gather` gathers the rows the last FFN leaves on this rank's attention-TP slice, and with `reads_attn_tp_slices` it reads that slice itself and the last FFN leaves its output there. Kimi K3's `AttnBankOutputRead` is such a read.

This is a non-pipeline stack fragment. Pipeline reception uses the first boundary's `from_pp(tensors, forward_batch)` to reconstruct a stream; the sender uses `residual_batch.to_pp()`. A stream the producer already wrote travels as `hidden_states` alone and arrives written: MHC's expanded streams, and the output of an FFN on its own rows (its attention-TP slice, or an unpadded batch's rows), which writes it at its exit before a pipeline handoff. The receiver knows this from the producer's declaration, not from which tensors arrive, since a captured CUDA graph's input buffers hold every key. `to_pp()` completes every sum the output owes before transport, a declared one too: the pipeline sends each tensor as one slice per attention-TP rank and gathers the slices back on the next rank, which reassembles only a tensor every attention-TP rank holds alike. The receiving stage's entry then takes the path for a sum already completed, which it binds beside the one for a sum its own producer leaves.

A terminal FFN normally completes its output before the final norm. The exception is a MoE finalize handoff. When the stage's fusion provider can defer the finalize at the terminal layer (for CuteDSL, `install_cutedsl_fusion(..., terminal_finalize=True)`), the exit may leave a `DeferredFinalize` for the final norm. Pass the handle straight to `residual_batch.final_norm(hidden_states, forward_batch, self.norm, finalize_norm=service)`, where `service` is the object `install_cutedsl_fusion()` returned; its `finalize(handoff, residual, gamma)` fuses finalize, all-reduce, residual add, and norm. The fused path reads `layernorm.gemma_weight`, so it currently expects a `GemmaRMSNorm` final norm. Without `finalize_norm`, `final_norm()` first completes the handoff unfused, and `capture` is then allowed. With `finalize_norm`, `final_norm()` rejects `capture` when a handoff arrives. Calling `complete_output()` first runs the producer's unfused finalize, and `snapshot()` raises on a handoff. See `python/sglang/srt/models/qwen3_5.py`.

`model_forward_stages()` in `python/sglang/srt/batch_overlap/two_batch_overlap.py` gives each TBO microbatch its own stream: it splits with `ResidualStream.from_handoff()` and merges the results afterwards. Do not share one mutable stream between interleaved microbatches or hold an `exit()` scope open across a TBO yield point.

In the operation-scheduled TBO path, the FFN runs without an `exit()` scope and returns its partial output. `boundary.complete_now(hidden_states, forward_batch)` completes the sum it owes, applies any output transform, moves that output back to the layer's exit rows (a plain scatter under attention DP), and leaves nothing owed.

### Auxiliary capture and extra contributions

Choose the access method according to what the consumer needs:

| Operation | Effect on main output |
| --- | --- |
| `residual_batch.snapshot()` | Produces an owned plain residual snapshot; a sum can run on a copy without consuming the main contribution |
| Attention `boundary.prepare(..., capture=collector.capture)` | Completes the main output's owed communication (unfused; the add+norm kernel still runs), then captures the updated residual this read produces, moved back to the producer's rows. At stack entry it captures the input before `init_residual`; with `post_residual_addition` it captures output plus residual before the addition. FFN `prepare()` does not accept it |
| Attention `boundary.prepare(..., capture_gathered=collector)` | Captures the same updated residual on the attention's compute-input rows, after its input gather |
| `boundary.capture_output()` | Preserves its explicit capture convention: completes dynamic work on the main contribution, but snapshots a statically declared sum on a copy; returns both updated handle and snapshot |
| `residual_batch.add_to_output(..., extra)` | Completes the contribution before adding extra once, keeping the residual update pending |
| `residual_batch.final_norm(..., capture=collector.capture)` | Final norm and capture of its updated residual |

Snapshots currently require a plain residual update. Producer-specific finalize handoffs need an explicit main-output capture adapter.

A separate BF16 snapshot followed by norm can change results relative to a fused add+norm kernel's FP32 accumulation. Capture from the existing update/read operation when that ordering matters.

A capture callback has the signature `capture(value, *, owned=False)`, as `AuxHiddenStateList.capture` does. With `owned=False` the value may alias the mutable residual or a reusable communication buffer, and the collector must copy it before retaining it. The boundary passes `owned=True` only for storage nothing else will write: a capture move that gathers rows (`EntryPath.capture_move_allocates`), a residual sum computed only for the capture, or a residual that the following local stage's input path certifies it leaves untouched. `append_stages()` copies that certificate into the producer's entry at construction; no plan is consulted during forward. `residual_batch.final_norm(..., capture=...)` always passes a borrowed value.

### Choose a reduction policy

The `--boundary-reduction` option controls optional FFN output transport choices for decoders built with these boundaries; other models ignore it:

| Value | Permitted optional path |
| --- | --- |
| `ar` | All-reduce path |
| `rs` | Fixed-size reduce-scatter where eligible |
| `rsv` | Variable-size attention-DP reduce-scatter (RSv) where eligible |
| `rs+rsv` | Both scatter choices where eligible, with RSv tried first |
| `auto` | Default. Resolves a per-architecture policy during server-argument processing; a separate draft checkpoint resolves its own `speculative_boundary_reduction`. See [FFN boundary reduction](/docs/advanced_features/server_arguments#ffn-boundary-reduction) |

Required attention and MoE collectives are unaffected. These are permissions, not commands to force unsupported collectives; an ineligible optional scatter falls back to the all-reduce path. Shape, topology, producer behavior, and required token movement still constrain the selected path. The resolved policy must be available before model construction. Model defaults are defined in `python/sglang/srt/arg_groups/boundary_reduction.py`. Reduction fusion has its own backend enablement and eligibility checks; selecting `ar` alone does not disable all-reduce fusion.

### Integration checklist and common errors

Before you open a pull request for a new model, check each item:

- Every decoder layer appends its stages inside a layer stack: `make_layers()`, or `layer_stack()` around any other construction, including a NextN/MTP draft's own layer.
- The model gives `make_layers()` its shared declaration function (`stage_facts`), and each layer declares its stages with it: another pipeline rank binds the stages next to its own from that function alone.
- The model forward calls `residual_batch.start()` before the first layer, and leaves the stack through `residual_batch.final_norm()`, `to_pp()`, or `take_output()`.
- Pipeline reception calls `from_pp(tensors, forward_batch)` on the first local boundary.
- Split prefill starts the stream only in the segment that runs the first layer and completes it only in the final segment.
- Extra contributions such as deepstack embeddings go through `residual_batch.add_to_output()`, never an in-place add on the layer output.
- Auxiliary capture uses `prepare(..., capture=...)` or `final_norm(..., capture=...)` with a callback that honours `owned`.

Common errors and their usual cause:

| Error | Usual cause |
| --- | --- |
| `start the layer stack before entering a stage` | The forward path, a split-prefill segment, or an MTP head skipped `residual_batch.start()` |
| `output does not belong to this residual stream; change layer outputs through boundary accessors` | The model replaced a layer's output object (for example rebinding it to a new tensor) or passed another microbatch's output. This check compares object identity, so it does not catch in-place changes; the interface still forbids modifying layer outputs in place |
| `write the residual update before taking the final output` | `take_output()` ran while a contribution was still pending; fold or norm it first |
| `no stage boundary path for the active <VARIANT> batch` | The active batch variant (CP, input-scattered, sequence parallel, unpadded) is not supported by this stage; add a server-argument check that rejects the configuration |
| `append_stages needs an open layer stack` | The layers are built outside `make_layers()`; wrap their construction in `layer_stack()` |
| `a prepared branch must enter through branch_input, not prepare` | A `prepared_from` stage was entered with `prepare()` |
| `snapshot requires a plain residual update` | A snapshot was taken on a nonlinear (for example MHC) update |

## Boundary internals

### Architecture

```mermaid
flowchart TD
    D["Stage<br/>declarations"] --> C["Connections<br/>per batch<br/>variant"]
    C --> P["StagePlan<br/>entry and<br/>exit paths"]
    P --> B["StageBoundary"]
    F["ForwardBatch<br/>runtime facts"] --> B
    S["ResidualStream<br/>residual and<br/>pending work"] <--> B
    B --> I["prepare()<br/>complete,<br/>update, read,<br/>move rows"]
    I -->|"FFN or mixer"| X["exit()<br/>choose<br/>completion"]
    X --> M["Model<br/>computation"]
    I -->|"ALWAYS_PARTIAL"| M
    M --> O["finish()<br/>record the<br/>contribution"]
    O --> S
```

Construction and execution have different lifetimes:

1. **At model initialization**, `declare_attn()` and `declare_ffn()` describe compute behavior. `append_stages()` connects those declarations in stack order and binds each stage's own norm and hooks.
2. **During construction**, factories resolve token rows and reduction contracts for supported batch variants. `bind_entry()` binds consumer work; `bind_exit()` binds output transport. `StagePlan` retains those paths.
3. **At each forward**, batch facts select an existing path. An exit can make a batch-dependent completion decision, but it does not rebuild the declarations. The decision supplies the matching completion action; the only flag it publishes to compute is `defer_moe_finalize`, for a MoE that may hand off its finalize.
4. **Across stages**, `ForwardBatch.residual_stream` carries residual state and the producer's actual contribution. Stages do not store forward tensors on their reusable plans.

The resolved `StageContract` is a lower-level type than `StageDeclaration`: one `InputContract` and one `OutputContract` after topology and batch variant have been applied. An `EdgeContract` combines a producer output, consumer requirement, and the residual's source/destination layouts.

### Module map

Paths in this table are relative to `python/sglang/srt/layers/layer_boundary/`.

| Module | Role |
| --- | --- |
| `factories.py` | Model declarations, local sequence assembly, and stage factories |
| `contracts.py` | Resolved input/output contracts, edge declarations, batch variants, and bound step records |
| `layout.py` | Token axes, layouts, named sum groups, and topology/batch facts |
| `construction.py` | Build a `StagePlan` and select its batch variant |
| `boundary.py` | Select and bind producer/consumer boundary operations from contracts; for prefill CP, one `CpMoves` (`contracts.py`) pairs the FFN-input gather, the take-back of a complete output, and, where there is one, the reduce-scatter that completes a sum |
| `prepare.py` | Execute completion, update, read, and input movement in the selected order |
| `ops.py` | Collective and token-row movement primitives |
| `stage.py` | Model-facing `StageBoundary` methods |
| `exit.py` | Select output completion and publish scoped compute flags |
| `output.py` | Unreduced outputs, deferred finalizes and output transforms |
| `facts.py` | What binding keeps of a stage it does not run (`facts_of()`): a stack's neighbours on other pipeline ranks and a bound stage's producer |
| `row_transport.py` | Row transports that run a stage's compute on token rows other than its residual's (`RowTransport`, `ComputeTransport`) |
| `residual/__init__.py` | `ResidualUpdate`/`ResidualReadout` protocols and `LayerResidualOps` |
| `residual/stream.py` | Per-forward state and ownership of outstanding work |
| `residual/batch.py` | Model-stack entry, final norm, pipeline-parallel (PP) transport, snapshots, and extra contributions |
| `residual/access.py` | Tensor access and materialization helpers |
| `residual/add_norm.py`, `residual/mhc.py` | Plain add/norm and MHC read/update implementations |
| `residual/ihc.py`, `residual/gated.py` | Gated and gated-injection hyper-connection read/update implementations |
| `residual/post_norm.py` | Post-norm residual: each stage's output is normalized before it is added |
| `residual/attn_bank.py` | A residual read that aggregates a bank of residual snapshots |
| `residual/short_conv.py` | Deferred channelwise convolution followed by residual add and normalization |
| `adapters/` | Attention input, TBO, branches, and LoRA integration |
| `fusions/` | Consumer all-reduce fusion and CuteDSL integration |

Models normally use factories, `StageBoundary`, and `residual.batch`. Keep row arithmetic, process-group selection, and calls such as `token_axis_sizes()` inside the boundary implementation.

### Batch variants

`StagePlan` preconstructs ordinary, CP, input-scattered, sequence-parallel, and unpadded variants when supported by the configured topology. The unpadded variant serves batches whose rows do not divide over attention TP, which `--disable-attn-tp-gather` lets through without attention DP: an FFN that would run on this rank's attention-TP slice stays on the attention's rows instead. A forward selects a path from active runtime facts. An absent active variant raises an error rather than silently using ordinary token rows.

Configuration validation rejects unsupported model/parallel combinations. Boundary construction also rejects transitions without a correct implementation. Adding an enum value or a layout does not by itself provide a new collective path.

### Fusion providers and output decisions

Each exit has its own policy, and what it decides from fixed facts (the parallel configuration, the declarations and the bound path) is decided when the plan is built and recorded on the path as `ExitFacts`; only what depends on the batch is decided for it:

| Exit | Entry point | May decide |
|---|---|---|
| FFN | `exit()` or `finish()` | Complete the sum now, possibly in an attention-DP or CP / input-scattered reduce-scatter on the way back; leave it to the next input (an all-reduce, or under attention DP the scatter back to this rank's tokens); hand a MoE finalize to the next input |
| Operation-scheduled (TBO) | `complete_now()` | Only complete it now: under attention DP the move back is a plain scatter; never defers or hands off |
| Mixer | `finish()` | Leave its declared sum to the next stage's input (before an FFN); carry it to the next mixer's input (without attention DP); or complete it |
| Stack end | `exit()` or `finish()` | Complete it now; a MoE finalize handoff may reach a final norm that accepts it |
| Pipeline handoff | `exit()` or `finish()`, then `to_pp()` | Complete it now; an FFN on its own rows also writes it into the residual |

Fixed per path: whether an FFN may leave its sum to the next input at all, whether a reduce-scatter completes it without an attention-DP one, which sum an input-scattered batch's next input completes, whether the attention-DP return is the reduce-scatterv, whether the post-expert sum is one all-reduce, and whether a mixer carries its sum. Decided per batch: its padding, whether the attention-DP reduce-scatter is usable (an elastic EP scale-up changes the DP group), whether it has tokens, and whether a fused consumer takes the sum.

An output decision is made once. Its flags control whether compute performs reduction/finalize work; the matching completion action either executes that work or records exactly what the next boundary owes. Do not set a skip flag independently of a completion action.

A backend fusion provider is passed per stage as the `fusions` option, `(declaration, norm, {"fusions": provider})`; give a layer's attention and FFN stages the same provider. The boundary calls it as follows:

- `attn_input_fusions(plan)` and `ffn_input_fusions(plan)` return ordered consumer candidates, tried before the built-in all-reduce fusion.
- `can_defer_finalize(plan, forward_batch)` decides whether an FFN may return a `DeferredFinalize`. It is called on every FFN exit that has a provider.
- `can_defer_all_reduce(plan, forward_batch)` lets a LoRA or `SGLANG_SHARED_EXPERT_TP1` FFN leave its all-reduce to the next input. Such an FFN defers only without an expert all-to-all backend or quantized communication, when its sum is over the TP group, and when the provider, FlashInfer fusion, or AITER fusion accepts the batch. Other FFNs defer when the post-expert sum is a single all-reduce.

`install_cutedsl_fusion()` and `prepare_cutedsl_fusion()` find providers through the decoder layer's `attn_boundary` and `ffn_boundary` attributes.

Consumer fusion candidates are ordered. A candidate returning `None` must do so before modifying inputs or starting a collective, so fallback remains valid. `FfnInputFusion` declares the sum group it completes with residual add and norm. A residual read may supply its own candidates as `completing_fusions`: each `ReadoutFusion` completes a sum with the residual add, ahead of the read, and is tried before the built-in collective; one with `reads=True` also does the read. Where a stage reads its input on this rank's attention-TP slice and then gathers it, a read's `gathering_reads` may do both in one kernel. A stage may declare its own implementation of the gather over attention TP that brings rows into it (`declare_attn(attn_tp_gather=...)`), tried on every batch before the built-in gather: at its own entry, or at its producer's exit, since an exit runs its consumer's gather. Across a pipeline boundary the producer's rank takes that gather from the neighbouring stage's declaration, so the gather may use only the communication state of the rank it runs on, not the declaring layer's weights or buffers. The consumer only tries compatible candidates for the declared update/read capabilities.

An `OutputTransform` declares contribution processing before residual update. Its explicit `before_reduce_scatter` setting preserves a supported implementation's order; it is not permission to commute arbitrary operations across a reduction.

Producer GEMM plus reduce-scatter fusion is not a generic implemented API here. When adding such a backend, its output contract and actual completion must describe both the finished sum and returned token rows; do not leave the next boundary believing it still owes either operation.

### Special adapters

- **Attention/DeepSeek Sparse Attention (DSA) adapters:** retain `AttnTpContext` and its input-scattered/latent-input hooks. They are not a general asynchronous dependency scheduler.
- **LoRA adapter:** publishes the selected compute input's rows for LoRA execution.
- **TBO and branch adapters:** manage layer exits and entries that cannot be represented as a normal sequential prepare call.

### Extend and validate the module

Place changes according to their responsibility:

1. Add model compute facts to a declaration only when they describe compute behavior. Put user policy and unsupported configuration checks in server-argument handling.
2. Add new update/read semantics in `residual/`; declare only capabilities the implementation really supports.
3. Add a token transition in boundary selection and movement primitives, with its padding and row-order contract. Do not duplicate that logic in each model.
4. Put backend completion in `fusions/` and specialized exit and entry behavior in `adapters/`.
5. Keep models on stage factories and boundary methods. Avoid reading a neighbour's execution plan or reconstructing a collective decision during forward.

Focused tests live in `test/registered/unit/layer_boundary/`. Cover numerical output and residual state, collective group/row correctness, and supported fallback behavior for the changed path. Relevant examples include `test_ffn_exit.py`, `test_reduction_fusion.py`, and `test_append_stages.py`. A declaration-only assertion cannot establish that a new parallel path moves and reduces the correct values.

---

### Docs Developer Guide Msprobe Debugging Guide (`docs/docs/developer_guide/msprobe_debugging_guide.mdx`)

---
title: "MSProbe Debugging Guide"
metatags:
    description: "Debugging AI model accuracy anomalies and numerical errors during inference using MSProbe in SGLang."
---
MSProbe is a debugging tool for AI models that diagnoses accuracy anomalies and
numerical errors during model training and inference. It captures and monitors intermediate data (feature maps, weights,
activations, layer outputs) and contextual metadata (prompts, tensor dtypes, hardware configuration), and supports
visual analysis to systematically trace the root cause of accuracy degradation or numerical errors (e.g., NaN/Inf,
output drift, mismatched predictions).

## Basic Details

### Background Concepts: MSProbe Dumping Levels

MSProbe supports three accuracy levels for data dumping, each for different debugging needs:

- **L0**: Dumps tensors/statistics at the **module level** and generates `construct.json` (for network structure
  reconstruction in visualization). Requires passing a model/submodule handle.
- **L1**: Dumps tensors/statistics at the **torch API level**, suitable for fine-grained API-level numerical checking.
- **mix**: Combines L0 + L1, ideal for scenarios that require both **graph reconstruction** and **numerical comparison**.

### Prerequisites: Install MSProbe

Install MSProbe with pip:

```shell
pip install mindstudio-probe --pre
```

### Key Configuration Parameters

MSProbe uses a JSON configuration file for customized data dumping. All core parameters are listed in the table below,
with the default JSON configuration provided for reference.

#### Configuration Parameter Table

|    Field     | Description                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                              | Required |
|:------------:|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|:--------:|
|    `task`    | Type of dump task. Common PyTorch values include `"statistics"` and `"tensor"`. A statistics task collects tensor statistics (mean, variance, max, min, etc.) while a tensor task captures arbitrary tensors.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                            |   Yes    |
| `dump_path`  | Directory where dump results are stored. When omitted, `MSProbe` uses its default path.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                  |    No    |
|    `rank`    | Ranks to sample. An empty list collects every rank. For single-card tasks you must set this field to `[]`.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                               |    No    |
|    `step`    | Token iteration(s) to sample. An empty list means every iteration.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                       |    No    |
|   `level`    | Dump level string (`"L0"`, `"L1"`, or `"mix"`). `L0` targets `nn.Module`, `L1` targets `torch.api`, and `mix` collects both.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                             |   Yes    |
| `async_dump` | Whether to enable asynchronous dump (supported for PyTorch `statistics`/`tensor` tasks). Defaults to `false`.                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                                            |    No    |
|   `scope`    | Customize the scope of dump. Provide two module or API names that follow the tool's naming convention to lock a range, only data between the two names will be dumped. An empty list dumps every module or torch API.<br/><br/>Examples:<br/>`"scope": ["Module.conv1.Conv2d.forward.0", "Module.fc2.Linear.forward.0"]`<br/>`"scope": ["Tensor.add.0.forward", "Functional.square.2.forward"]`<br/><br/>The `level` setting determines what can be provided—modules when `level=L0`, APIs when `level=L1`, and either modules or APIs when `level=mix`.                                                                                                                                                                                                                                 |    No    |
|    `list`    | Customize dump list, only dumps elements from the list. An empty list dumps every module or torch API. Options include:<br/><br/>&#8226;Supply the full names of specific APIs in PyTorch eager mode to only dump those APIs. Example: `"list": ["Tensor.permute.1.forward", "Tensor.transpose.2.forward", "Torch.relu.3.backward"]`.<br/>&#8226;When `level=mix`, you can provide module names so that the dump expands to everything produced while the module is running. Example: `"list": ["Module.module.language_model.encoder.layers.0.mlp.ParallelMlp.forward.0"]`.<br/>&#8226;Provide a substring such as `"list": ["relu"]` to dump every API whose name contains the substring. When `level=mix`, modules whose names contain the substring are also expanded. |    No    |

#### Default configuration

```json
{
  "task": "statistics",
  "dump_path": "./dump_path",
  "rank": [],
  "step": [],
  "level": "L1",
  "async_dump": false,
  "statistics": {
    "scope": [],
    "list": [],
    "data_mode": [
      "all"
    ],
    "summary_mode": "statistics"
  },
  "tensor": {
    "scope": [],
    "list": [],
    "data_mode": [
      "all"
    ],
    "file_format": "npy"
  },
  "acc_check": {
    "white_list": [],
    "black_list": [],
    "error_data_path": "./"
  }
}
```

#### Outputs

Dump files are written into `dump_path` you defined. They usually contain:

- `dump.json`, which records metadata such as dtype, shape, min, max, mean, L2 norm, and `requires_grad`.
- `construct.json`, hierarchical structure description, when `level` is `L0` or `mix` (required for visualization), its
  content is not empty.
- `stack.json`, record the call stack information of API/Module.
- `dump_tensor_data`, generated when `task` is `tensor` and save the collected tensor data.

See [dump directory description](#dump-directory-description) for details.

> **Note**: When MSProbe is enabled, cuda graph is disabled (disable_cuda_graph=True) because MSProbe only supports dump
> in eager mode, warmup is disabled (skip_server_warmup=True) because there is no need to dump data for this stage.

## End-to-End Examples

MSProbe’s full debugging workflow follows **Enable → Collect Data → Visualize → Analyze Root Cause**. Below is a common
E2E example for SGLang-based model inference debugging.

### Example : Advanced Debugging with Custom Configuration

Suitable for targeted debugging (e.g., only collect statistics data for specific ranks/steps, enable mix level for graph
reconstruction + numerical comparison) and root cause analysis via **problem vs. benchmark comparison**.

#### Step 1: Enable
##### Prepare Custom Configuration JSON

Create `msprobe-config.json` (dump statistics data for rank0/1, step0/1, mix level):

```json
{
  "task": "statistics",
  "dump_path": "./problem_dump",
  "rank": [
    0,
    1
  ],
  "step": [
    0,
    1
  ],
  "level": "mix",
  "async_dump": false,
  "statistics": {
    "scope": [],
    "list": [],
    "data_mode": [
      "all"
    ],
    "summary_mode": "statistics"
  }
}
```

##### Enable MSProbe with Custom Configuration in SGLang

Launch the SGLang server and specify the configuration file path with `--msprobe-dump-config`:

```bash
python3 -m sglang.launch_server \
 --model-path Qwen/Qwen2.5-0.5B-Instruct \
 --host 127.0.0.1 \
 --port 1027 \
 --msprobe-dump-config /home/msprobe-config.json
```
#### Step 2: Collect Data
##### Collect Dump Data for Problem & Benchmark Sides

Send normal inference requests to trigger model running (MSProbe automatically collects data during request processing):

```bash
curl -H "Content-type: application/json" \
 -X POST \
 -d '{
     "model": "Qwen/Qwen2.5-0.5B-Instruct",
     "messages": [
         {
             "role": "user",
             "content": "Hello, my name is"
         }
     ],
     "max_tokens": 10
 }' \
 http://127.0.0.1:1027/v1/chat/completions
```

- **Problem side**: Run the above SGLang server (with the accuracy/numerical issue) and send inference request; dump
  data is saved to `./problem_dump`.
- **Benchmark side**: Launch a normal SGLang server (without the issue, e.g., stable framework version/operator) with
  the **same custom configuration** and send the **same inference request**; rename the dump directory
  to `./bench_dump`.

> **Key Requirement**: Problem and benchmark dumps must use the same inputs and sampling points (rank/step)
> for valid comparison.

##### Check Generated Dump Files

Dump files are saved to `./problem_dump` and `./bench_dump` you defined and include core files for subsequent analysis:

- `dump.json`: Records tensor metadata of APIs and modules (dtype, shape, min/max/mean, L2 norm, `requires_grad`, etc.).
- `stack.json`: Logs call stack information of APIs and modules.
- `construct.json`: hierarchical structure description, required for visualization, its content is not empty.

#### Step 3: Visualize
##### Visualize Problem vs. Benchmark Comparison (Multi-Rank)

Generate a multi-rank comparison visualization file (mix level generates `construct.json` for graph reconstruction):

```shell
msprobe graph_visualize -tp ./problem_dump/step0 -gp ./bench_dump/step0 -o ./graph_output
```

- `-tp`: Path to problem-side dump data
- `-gp`: Path to benchmark-side dump data
- `-o`: Output directory for visualization files

If you want overflow check (for NaN/Inf detection), please specify the parameter `-oc`

```shell
msprobe graph_visualize -tp ./problem_dump/step0 -gp ./bench_dump/step0 -o ./graph_output -oc
```

After the comparison or build task finishes, a `compare_{timestamp}.vis.db` file is created under `graph_output`.

The dumped data can be used to visualize and analyze differences using tables or charts generated with visualization tools such as Matplotlib and Excel.

##### Launch TensorBoard

Start TensorBoard:
```bash
tensorboard --logdir ./graph_output --bind_all --port 6006
```
#### Step 4: Analyze Root Cause
##### Locate Root Cause

Root Cause Analysis in TensorBoard:
- Divergent nodes (with accuracy/numerical differences) are highlighted in **red** (darker red = larger difference).
- Click on divergent nodes to view detailed tensor data (inputs/outputs, parameters) and API/module call stacks.
- Use the **search/filter** function to quickly locate key layers/APIs (e.g., "relu", "conv").
- Switch between ranks/steps via the UI to check cross-rank/cross-step divergence.
- Check the **overflow check** tab for NaN/Inf values in specific nodes (the direct cause of numerical instability).

##### Verify the Root Cause

After locating the divergent node (e.g., a specific Conv layer or torch API with abnormal tensor values), verify by:

- Narrowing the dump scope to this node (via `scope`/`list` in the configuration file) for fine-grained data collection.
- Modifying the problematic layer/API (e.g., replacing the operator, adjusting the dtype) and re-running the debugging
  workflow to confirm the issue is resolved.

## Troubleshooting

### No Dump Files Generated

1. To confirm if MSProbe is installed, use `pip show mindstudio-probe` to troubleshoot. If it is installed, the MSProbe
   version information will be printed. If it is confirmed that it has not been installed, please
   use `pip install mindstudio-probe --pre` for installation;
2. Confirm the `--msprobe-dump-config` parameter points to the **correct JSON file path**.

### Dump Files Are Too Large (Excessive Data)

1. Start with `task: "statistics"` instead of `"tensor"` to collect only tensor statistics (avoids raw tensor dump);
2. Narrow the dump range with the `scope` field (specify start/end module/API);
3. Filter dump targets with the `list` field (only dump specific modules/APIs or substrings);
4. Sample specific `rank` and `step` (avoid dumping all ranks/iterations).

### TensorBoard Visualization Fails

1. Confirm `construct.json` is not empty (requires `level: L0` or `mix` – L1 does not generate graph files);
2. Check that the `-tp` (problem dump) and `-gp` (benchmark dump) paths point to **valid rank/step subdirectories** (
   e.g., `step0/rank0`);
3. Ensure the MSProbe version is up-to-date (reinstall with `pip install mindstudio-probe --pre --upgrade`);
4. Verify TensorBoard is installed and the `--logdir` parameter points to the directory containing `.vis.db` files (not
   the file itself).

### Numerical Comparison Shows No Divergence But Model Accuracy Is Low

1. Expand the dump `step` range (check more token iterations for late-stage divergence);
2. Switch to `task: "tensor"` (statistics may mask subtle numerical differences in raw tensor data);
3. Ensure the problem and benchmark dumps use **the same input data/hardware configuration** (different inputs lead to
   invalid comparisons);
4. Use the `manual mapping` feature in TensorBoard (automatic mapping may miss some nodes for custom models).

---

## Appendix

### Dump directory description

```
/* Detailed source-code truncated for AI context efficiency. */
```

- `rank`: Device ID. Each card writes its data to the corresponding `rank{ID}` directory. In non-distributed scenarios
  the directory is simply named `rank`.
- `dump_tensor_data`: Save the collected tensor data.
- `dump.json`: Statistics for the forward data of each API or module, including names, dtype, shape, max, min, mean, L2
  norm (square root of the L2 variance), and CRC-32 when `summary_mode="md5"`.
  See [dump.json file description](#dump-json-file-description) for details.
- `dump_error_info.log`: Present only when the dump tool encountered an error and records the failure log.
- `stack.json`: Call stacks for APIs/modules.
- `construct.json`: Hierarchical structure description. Empty when `level=L1`.

### dump.json file description

#### L0 level

An L0 `dump.json` contains forward/backward I/O for modules together with parameters and parameter gradients. Using
PyTorch's `Conv2d` as an example, the network code looks like:

`output = self.conv2(input)  # self.conv2 = torch.nn.Conv2d(64, 128, 5, padding=2, bias=True)`

`dump.json` contains the following entries:

- `Module.conv2.Conv2d.forward.0`: Forward data of the module. `input_args` represents positional inputs, `input_kwargs`
  represents keyword inputs, `output` stores forward outputs, and `parameters` stores weights/biases.
- `Module.conv2.Conv2d.parameters_grad`: Parameter gradients (weight and bias).
- `Module.conv2.Conv2d.backward.0`: Backward data of the module. `input` represents gradients that flow into the
  module (gradients of the forward outputs) and `output` represents gradients that flow out (gradients of the module
  inputs).

**Note**: When the `model` parameter passed to the dump API is `List[torch.nn.Module]` or `Tuple[torch.nn.Module]`,
module-level names include the index inside the list (`{Module}.{index}.*`). Example: `Module.0.conv1.Conv2d.forward.0`.

<details>

<summary>L0 dump.json</summary>

```
/* Detailed source-code truncated for AI context efficiency. */
```

</details>

#### L1 level

An L1 `dump.json` records forward/backward I/O for APIs. Using PyTorch's `relu` function as an
example (`output = torch.nn.functional.relu(input)`), the file contains:

- `Functional.relu.0.forward`: Forward data of the API. `input_args` are positional inputs, `input_kwargs` are keyword
  inputs, and `output` stores the forward outputs.
- `Functional.relu.0.backward`: Backward data of the API. `input` represents the gradients of the forward outputs,
  and `output` represents the gradients that flow back to the forward inputs.

<details>

<summary>L1 dump.json</summary>

```
/* Detailed source-code truncated for AI context efficiency. */
```

</details>

#### mix level

A `mix` dump.json contains both L0 and L1 level data; the file format is the same as the examples above.

---

### Docs Developer Guide Quantization Contribution Guide (`docs/docs/developer_guide/quantization_contribution_guide.mdx`)

---
title: "Quantization Contribution Guide"
metatags:
    description: "Guidance for contributing SGLang quantization methods, schemes, backend kernels, tests, and validation results."
---

This guide describes how to add or refactor quantization support in SGLang. It focuses on the common structure used by weight-only and weight-activation quantization methods such as AWQ, GPTQ, compressed-tensors, ModelSlim, Quark, and related backend kernels.

## Design Goals

Quantization code should keep the quantization format semantics separate from hardware-specific execution. This makes it easier to add new formats, reuse kernels across formats, and review platform-specific changes independently.

Follow the architecture proposed in [Quantization Modifications](https://github.com/sgl-project/sglang/issues/15194):

- **Config**: parses model and runtime quantization parameters, validates supported options, and selects the proper scheme.
- **Scheme**: owns quantized weight creation, weight loading, post-processing, and quantized layer wiring for Linear, MoE, embedding, or other module types.
- **Backend kernel**: wraps hardware-specific execution, layout conversion, kernel selection, and kernel calls for GPU (CUDA/HIP/XPU), NPU, or other backends.

Avoid putting config parsing, weight loading, and backend kernel calls in a single monolithic file. If a method needs multiple formats or backends, add a package under `python/sglang/srt/layers/quantization/<method>/` and split schemes into `schemes/`.

## Recommended File Layout

Use this layout for a quantization method that has multiple schemes or backend-specific execution paths:

```text
python/sglang/srt/layers/quantization/<method>/
  __init__.py
  <method>.py
  schemes/
    __init__.py
    <method>_scheme.py
    <method>_linear.py
    <method>_moe.py
    <method>_<variant>.py
```

Backend kernels should live under the hardware backend they target:

```text
python/sglang/srt/hardware_backend/gpu/quantization/<method>_kernels.py
python/sglang/srt/hardware_backend/npu/quantization/<method>_kernels.py
```

Keep shared method selection in the quantization package and keep backend imports narrow. This prevents circular imports and keeps non-target platforms from importing unavailable kernel dependencies.

## Adding or Refactoring a Quantization Method

1. Define the config entry point and register it through `python/sglang/srt/layers/quantization/__init__.py` when needed.
2. Add explicit scheme selection helpers such as `get_linear_scheme` and `get_moe_scheme`.
3. Move layer-specific weight creation and weight loading into scheme classes.
4. Move GPU (CUDA/HIP/XPU), NPU, or other hardware kernel calls into backend kernel modules.
5. Keep Linear, MoE, embedding, and non-linear module handling explicit. Do not assign a Linear quantization method to a module type that needs different semantics.
6. Preserve compatibility for existing quantized checkpoints and runtime flags.
7. Add tests that cover both config parsing and execution paths touched by the change.

For examples, see the AWQ and GPTQ refactors:

- [PR #21126](https://github.com/sgl-project/sglang/pull/21126): splits AWQ schemes, weight initialization, and backend kernel calls.
- [PR #26402](https://github.com/sgl-project/sglang/pull/26402): applies the same scheme/kernel split to GPTQ.

## Tests and Validation

Quantization changes can affect both accuracy and performance. Include validation that matches the blast radius of the change.

For Python-only structure changes:

```bash
ruff check <changed-python-files>
git diff --check
```

For quantized model behavior:

- Launch at least one representative model for each touched quantization method.
- Send a `/generate` request and confirm the output path succeeds.
- Run an accuracy sanity test if the change can affect numerics.
- Include warmup-aware benchmark results when the change affects kernel calls, layout conversion, or dispatch.

For backend-specific changes:

- Validate GPU changes on a supported GPU environment (NVIDIA, AMD, or Intel).
- Validate NPU changes on a supported Ascend environment.
- Include the exact model, quantization flag, backend flag, hardware, and command used in the PR description.

## PR Checklist

Before requesting review, make sure the PR description includes:

- The quantization method and backend paths changed.
- The issue, design proposal, or roadmap item the PR follows.
- Any compatibility notes for existing checkpoints or flags.
- Accuracy results when model outputs can change.
- Benchmark or profiling results when runtime performance can change.
- The exact local checks and model launch tests that were run.

Use the general [Contribution Guide](./contribution_guide) for source setup, formatting, unit tests, CI triggering, and review process details.

---

### Docs Developer Guide Release Process (`docs/docs/developer_guide/release_process.mdx`)

---
title: "PyPI Package Release Process"
metatags:
    description: "SGLang PyPI release: version update, upload_pypi.sh script, GitHub release creation."
---
## Update the version in code
Update the package version in `python/pyproject.toml` and `python/sglang/__init__.py`.

## Upload the PyPI package

```text Output
pip install build twine
```

```text Output
cd python
bash upload_pypi.sh
```

## Make a release in GitHub
Make a new release https://github.com/sgl-project/sglang/releases/new.

---

### Docs Developer Guide Serve Backend Plugins (`docs/docs/developer_guide/serve_backend_plugins.mdx`)

---
title: "Add an out-of-tree serve backend"
description: "Connect an ecosystem runtime to sglang serve through the versioned serve backend plugin API."
---

A serve backend plugin connects an out-of-tree runtime to the SGLang-owned CLI:

```bash
sglang serve MODEL_PATH --model-type BACKEND_NAME [BACKEND_OPTIONS]
```

The extension retains its own argument parser, process topology, API endpoints, hardware requirements, and release cycle. The core CLI owns backend selection and common child-process cleanup.

## Prerequisites

- Install your extension and a compatible SGLang version in the same Python 3.11+ environment.
- Declare the SGLang version range tested by your extension in its package dependencies.
- Keep the backend factory and detector independent of GPU initialization and model loading.

The plugin API itself is platform-independent. Your backend defines its supported operating systems, accelerators, parallelism options, and authentication requirements.

## Keep one owner for the executable

Only the `sglang` distribution should publish a console script named `sglang`. Your extension registers package metadata under `sglang.serve_backends`; it must not publish another `sglang` script.

This prevents installation order from replacing the command and ensures uninstalling an extension does not remove the core executable. You can retain a project-specific executable as a compatibility alias:

```bash
my-runtime serve MODEL_PATH
sglang serve MODEL_PATH --model-type my_runtime
```

Both commands should call the same backend implementation.

## Register a backend factory

Add a zero-argument factory to your extension's `pyproject.toml`:

```toml
[project]
name = "my-sglang-runtime"
version = "0.1.0"
dependencies = ["sglang"]

[project.entry-points."sglang.serve_backends"]
my_runtime = "my_sglang_runtime.sglang_backend:create_backend"
```

The entry point name, `my_runtime`, becomes an accepted `--model-type` value. Choose a distinctive name. `auto` and SGLang's in-tree backend names are reserved.

## Implement the backend

Create `my_sglang_runtime/sglang_backend.py`:

```python
import argparse

from sglang.cli.serve_backends import (
    ServeBackend,
    ServeBackendDetection,
    ServeRequest,
)


def detect(request: ServeRequest) -> ServeBackendDetection:
    if request.model_path is None:
        return ServeBackendDetection.UNKNOWN
    if supports_model(request.model_path):
        return ServeBackendDetection.MATCH
    return ServeBackendDetection.NO_MATCH


def run(request: ServeRequest) -> None:
    parser = argparse.ArgumentParser(prog="sglang serve")
    parser.add_argument("--model-path", required=True)
    parser.add_argument("--pipeline-parallel", type=int, default=1)
    args, remaining = parser.parse_known_args(request.argv)
    launch_runtime(args, remaining)


def create_backend() -> ServeBackend:
    return ServeBackend(api_version=1, run=run, detect=detect)
```

Replace `supports_model()` and `launch_runtime()` with your extension's lightweight metadata check and blocking server launcher. A real `run()` call should block for the server lifetime. It must also honor `-h` and `--help` without launching a server; `argparse` does this automatically.

Among serve backend entry points, explicit selection imports only the selected provider. Automatic selection loads installed backend factories and invokes their detectors, so importing this module and calling `detect()` must not initialize accelerators, import model weights, or start workers.

## Handle forwarded arguments

SGLang removes `--model-type` and normalizes a positional Hugging Face model ID or local model directory before dispatch. For example:

```bash
sglang serve org/model --model-type my_runtime --pipeline-parallel 2
```

Your backend receives:

```python
("--model-path", "org/model", "--pipeline-parallel", "2")
```

The selected backend owns all remaining argument parsing and validation. Target backend-specific help with:

```bash
sglang serve --model-type my_runtime --help
```

## Support config-only runtimes

SGLang requires a model path by default. If your runtime resolves its model and parallelism settings from a configuration file, disable that validation:

```python
def create_backend() -> ServeBackend:
    return ServeBackend(
        api_version=1,
        run=run,
        detect=detect,
        requires_model_path=False,
    )
```

You can then accept commands such as:

```bash
sglang serve --model-type my_runtime --config pipeline.yaml
```

Config-only requests generally require explicit `--model-type` unless your detector can identify the backend from the remaining arguments.

## Understand automatic routing

The default `--model-type auto` follows these rules:

1. Backends without a detector remain explicit-only.
2. One `MATCH` selects that backend.
3. Multiple matches fail and require an explicit `--model-type`.
4. `UNKNOWN` and detector failures do not claim the request.
5. No matches preserve the existing LLM fallback.

The registry does not resolve overlap by package installation order or a hidden priority. A backend can opt out of automatic routing by omitting its detector:

```python
ServeBackend(api_version=1, run=run, requires_model_path=False)
```

## Maintain compatibility

Declare the API version implemented by your extension as a literal. Do not copy SGLang's current version constant at runtime; a fixed value lets a future SGLang release detect an older plugin contract. SGLang rejects incompatible, duplicate, and reserved backend registrations with an actionable error.

The public extension contract consists of:

- `ServeRequest`: normalized backend arguments and the optional model path
- `ServeBackend`: the runner, optional detector, and model-path requirement
- `ServeBackendDetection`: `MATCH`, `NO_MATCH`, or `UNKNOWN`

Test explicit selection, backend-specific help, automatic detection, ambiguous models, and installation or removal alongside the core `sglang` package.

---

### Docs Developer Guide Setup Github Runner (`docs/docs/developer_guide/setup_github_runner.mdx`)

---
title: "Set Up Self-Hosted Runners for GitHub Action"
metatags:
    description: "SGLang GitHub Actions self-hosted runner: Docker setup for NVIDIA/AMD GPUs, config.sh and run.sh."
---
## Add a Runner

### Step 1: Start a docker container.

**You can mount a folder for the shared huggingface model weights cache. **
The command below uses `/tmp/huggingface` as an example.

```
docker pull nvidia/cuda:13.0.3-devel-ubuntu22.04
# Nvidia
docker run --shm-size 128g -it -v /tmp/huggingface:/hf_home --gpus all nvidia/cuda:13.0.3-devel-ubuntu22.04 /bin/bash
# AMD
docker run --rm --device=/dev/kfd --device=/dev/dri --group-add video --shm-size 128g -it -v /tmp/huggingface:/hf_home lmsysorg/sglang:v0.5.8-rocm700-mi30x /bin/bash
# AMD just the last 2 GPUs
docker run --rm --device=/dev/kfd --device=/dev/dri/renderD176 --device=/dev/dri/renderD184 --group-add video --shm-size 128g -it -v /tmp/huggingface:/hf_home lmsysorg/sglang:v0.5.8-rocm700-mi30x /bin/bash
```

### Step 2: Configure the runner by `config.sh`

Run these commands inside the container.

```text Output
apt update && apt install -y curl python3-pip git
pip install --upgrade pip
export RUNNER_ALLOW_RUNASROOT=1
```

Then follow https://docs.github.com/en/actions/hosting-your-own-runners/managing-self-hosted-runners/adding-self-hosted-runners to run `config.sh`

**Notes**
- Do not need to specify the runner group
- Give it a name (e.g., `test-sgl-gpu-0`) and some labels (e.g., `1-gpu-h100`). The labels can be edited later in Github Settings.
- Do not need to change the work folder.

### Step 3: Run the runner by `run.sh`

- Set up environment variables
```text Output
export HF_HOME=/hf_home
export SGLANG_IS_IN_CI=true
export HF_TOKEN=hf_xxx
export OPENAI_API_KEY=sk-xxx
export CUDA_VISIBLE_DEVICES=0
```

- Run it forever
```text Output
while true; do ./run.sh; echo "Restarting..."; sleep 2; done
```

---

### Docs Get Started Examples (`docs/docs/get-started/examples.mdx`)

---
title: "Examples"
description: "Run a model locally, add chat to an application, process a batch of texts, or build a tool-using assistant."
---

Choose an example for what you want to do:

| I want to… | Example |
| --- | --- |
| Run a model on my own computer | [Local inference](#run-a-model-locally) on an NVIDIA GPU or Apple Silicon Mac. |
| Serve a larger model on a GPU server | [Deploy Qwen3.8-27B](#serve-qwen3-8-27b) on an NVIDIA H200. |
| Add chat to an application | [Stream a reply](#stream-a-reply) through the OpenAI-compatible API. |
| Process a collection of documents | [Summarize multiple texts](#process-multiple-prompts) concurrently. |
| Build an agent that uses tools | [Look up an order](#build-a-customer-support-agent) and answer a customer’s question. |

## Run a model locally

Run `Qwen/Qwen3-0.6B` on your own computer and ask it a question. This small model is useful for trying the workflow; choose a larger model for more demanding tasks.

<Tabs>
<Tab title="NVIDIA GPU (Linux)">

This example uses one CUDA 13-compatible NVIDIA GPU, Linux, Docker, and NVIDIA Container Toolkit. For setup, see [Installation](/docs/get-started/install).

Run this command on your computer. Docker pulls the image if needed, and SGLang downloads the model on first use:

```bash
docker run --rm --gpus all --ipc=host \
  -p 127.0.0.1:30000:30000 \
  lmsysorg/sglang:latest \
  sglang serve Qwen/Qwen3-0.6B \
    --host 0.0.0.0 --port 30000
```

If you already installed SGLang with uv, run this in that Python environment instead:

```bash
sglang serve Qwen/Qwen3-0.6B --host 127.0.0.1 --port 30000
```

</Tab>
<Tab title="Apple Silicon Mac">

On an Apple Silicon Mac with macOS 14 or newer, first follow the [Apple Silicon installation instructions](/docs/hardware-platforms/apple_metal#install-sglang) to install SGLang with its MLX dependencies. Use that Python environment to launch the model with 4-bit quantization:

```bash
SGLANG_USE_MLX=1 python -m sglang.launch_server \
  --model-path Qwen/Qwen3-0.6B \
  --quantization mlx_q4 \
  --disable-cuda-graph \
  --host 127.0.0.1 --port 30000
```

The model runs on your Mac through MLX. It downloads the weights on first use and quantizes them in memory when loading.

</Tab>
</Tabs>

Keep the server running. Once you see `The server is fired up and ready to roll!`, open another terminal on the same computer and send a request:

```bash
curl http://localhost:30000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Qwen/Qwen3-0.6B",
    "messages": [{"role": "user", "content": "What is the capital of France? /no_think"}],
    "max_tokens": 128
  }'
```

Look for the answer in `choices[0].message.content`. Both the model and the API server are running locally. Press `Ctrl+C` in the server terminal when you are done, or leave it running for the chat and batch examples below.

<a id="serve-qwen3-8-27b" />

## Serve Qwen3.8-27B

This configuration runs `Qwen/Qwen3.8-27B-FP8` on one NVIDIA H200. It requires Linux, a CUDA 13-compatible driver, Docker, and NVIDIA Container Toolkit configured for GPU access. For environment setup, see [Installation](/docs/get-started/install). For other hardware configurations, see the [Qwen3.8-27B Cookbook](/cookbook/autoregressive/Qwen/Qwen3.8-27B).

Set `HF_CACHE_DIR` to an absolute directory on the host for downloaded model weights, replacing the placeholder below. Run this command on the GPU host:

```bash
HF_CACHE_DIR="/path/to/huggingface-cache"
docker run --rm --gpus all \
  --shm-size 32g \
  -p 30000:30000 \
  -v "$HF_CACHE_DIR:/root/.cache/huggingface" \
  --ipc=host \
  lmsysorg/sglang:latest \
  sglang serve \
    --trust-remote-code \
    --model-path Qwen/Qwen3.8-27B-FP8 \
    --kv-cache-dtype fp8_e4m3 \
    --mem-fraction-static 0.85 \
    --attention-backend flashinfer \
    --chunked-prefill-size 32768 \
    --max-prefill-tokens 32768 \
    --reasoning-parser qwen3 \
    --tool-call-parser qwen3_coder \
    --mamba-full-memory-ratio 4.59 \
    --host 0.0.0.0 \
    --port 30000 \
    --mamba-radix-cache-strategy extra_buffer \
    --mamba-ssm-dtype float32
```

Docker downloads the image if needed. SGLang downloads the model on first use and starts the server. Keep this terminal open and wait for `The server is fired up and ready to roll!` before sending a request.

<Accordion title="Already installed with uv?">

Run this command in the activated Python environment where you installed SGLang. It starts the same server without Docker:

```bash
sglang serve \
  --trust-remote-code \
  --model-path Qwen/Qwen3.8-27B-FP8 \
  --kv-cache-dtype fp8_e4m3 \
  --mem-fraction-static 0.85 \
  --attention-backend flashinfer \
  --chunked-prefill-size 32768 \
  --max-prefill-tokens 32768 \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_coder \
  --mamba-full-memory-ratio 4.59 \
  --host 0.0.0.0 \
  --port 30000 \
  --mamba-radix-cache-strategy extra_buffer \
  --mamba-ssm-dtype float32
```

For Python environment setup, see [Install with uv](/docs/get-started/install#method-1-with-pip-or-uv).

</Accordion>

Verify the running server with the [Quickstart request](/docs/get-started/quickstart#send-a-request), using `Qwen/Qwen3.8-27B-FP8` as the model name.

## Connect to a model

The following Python examples connect to the local server above. You can also use a remote SGLang server; only the server needs hardware that can run the model.

Install the Python client in your activated environment:

```bash
uv pip install openai
```

Run this setup before each example in the same Python session:

```python
from openai import OpenAI

client = OpenAI(
    base_url="http://localhost:30000/v1",
    api_key="EMPTY",
)
model = "Qwen/Qwen3-0.6B"
```

These settings match the local Qwen3-0.6B server above. For a remote server, replace `localhost` with its reachable address, use its model name, and supply an API key if authentication is enabled.

## Stream a reply

Ask a question and print the answer as it arrives:

```python
stream = client.chat.completions.create(
    model=model,
    messages=[{"role": "user", "content": "Explain prefix caching in two sentences."}],
    stream=True,
)

for chunk in stream:
    if chunk.choices:
        print(chunk.choices[0].delta.content or "", end="", flush=True)
print()
```

The terminal displays the model's explanation incrementally. You can use the same stream to update a chat interface.

See the [API guide](/docs/basic_usage/openai_api_completions) for more request options.

## Process multiple prompts

Send several independent requests concurrently, for example to summarize customer feedback:

```python
from concurrent.futures import ThreadPoolExecutor

feedback = [
    "Setup was quick, but I could not find the export button.",
    "The new search is faster and finds the documents I need.",
    "Please add a way to share saved reports with my team.",
]

def summarize(text):
    response = client.chat.completions.create(
        model=model,
        messages=[{"role": "user", "content": f"Summarize in one sentence: {text}"}],
    )
    return response.choices[0].message.content

with ThreadPoolExecutor(max_workers=3) as pool:
    for summary in pool.map(summarize, feedback):
        print(summary)
```

You get one summary per input, in the original order. For batch processing inside a Python process without an HTTP server, see the [offline engine API](/docs/basic_usage/offline_engine_api).

<a id="request-a-tool-call" />

## Build a customer support agent

Let an agent answer “Where is my order?” by looking up order data. The model chooses a tool, your application executes it, and the model uses the returned data to answer the customer.

Use the [Qwen3.8-27B server above](#serve-qwen3-8-27b), which enables a tool parser, or configure another model with the [tool-calling guide](/docs/advanced_features/tool_parser). The small local example does not configure tool calling. This script uses the OpenAI client installed above; update the endpoint and model ID to match your server.

Save this as `order_agent.py` and run `python order_agent.py`. The order data is a local fixture, so no external service or API key is needed for the lookup.

```
/* Detailed source-code truncated for AI context efficiency. */
```

You should see the lookup result followed by an answer that the order has shipped and is expected on Friday. The wording can vary. SGLang serves the model; the Python application runs the tools and manages the conversation. Replace `lookup_order` with an authorized order-system query to use real data.

---

### Docs Get Started Install (`docs/docs/get-started/install.mdx`)

---
title: Installation
description: Install SGLang with pip/uv, source, Docker, Kubernetes, and cloud deployment options.
keywords:
  - installation
  - sglang
  - pip
  - docker
---
Choose one installation method below. These instructions target Linux with NVIDIA GPUs; for other devices, see [Hardware platforms](/docs/hardware-platforms/overview).

## Install SGLang

<Tabs>
<Tab title="Docker" id="method-3-using-docker">

Docker includes Python, SGLang, and its dependencies; no separate host Python installation is required.

The docker images are available on Docker Hub at [lmsysorg/sglang](https://hub.docker.com/r/lmsysorg/sglang/tags), built from [Dockerfile](https://github.com/sgl-project/sglang/tree/main/docker).
Use Linux with a supported NVIDIA GPU, a CUDA 13-compatible driver, [Docker Engine](https://docs.docker.com/engine/install/), and [NVIDIA Container Toolkit](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html). Complete the Toolkit guide's Docker runtime configuration before starting a GPU container.

SGLang images ship a CUDA 13 environment. CUDA 12 images (`-cu12` / `-cu129`) are no longer published; `lmsysorg/sglang:v0.5.19-cu129` is the last CUDA 12 tag.

**Pull the image**

`latest` contains the newest stable release:


```bash
docker pull lmsysorg/sglang:latest
```

**Image options**

The examples use `latest`. To use another image, replace the tag in the pull and run commands:

- Nightly: Built daily from the latest `main`, including changes not yet in a stable release. Choose a tag from the [nightly image list](https://hub.docker.com/r/lmsysorg/sglang/tags?name=nightly).
- Runtime: A smaller image of the same stable release, with inference dependencies and fewer development utilities. Use the `latest-runtime` tag.
- AWS EFA: Any of the images above plus the AWS EFA userspace stack, for EFA-enabled EC2 instances. Add `-efa` to the tag: `latest-efa`, `latest-runtime-efa`, or the dated `nightly-dev-efa-<date>-<sha>` (moving tag `dev-efa`). See [AWS EFA](/docs/advanced_features/pd_disaggregation#aws-efa) for what the images include and how to run them.

For reproducible deployments, use a specific release or dated nightly tag from [Docker Hub](https://hub.docker.com/r/lmsysorg/sglang/tags).

**Start a container**

Set `HF_CACHE_DIR` to an absolute directory path on the host for downloaded model weights, replacing the placeholder below.

For gated or private models, export your [Hugging Face token](https://huggingface.co/docs/hub/en/security-tokens) as `HF_TOKEN` on the host and add `--env HF_TOKEN` before the image name in this command.


```bash
HF_CACHE_DIR="/path/to/huggingface-cache"
docker run -it --gpus all \
  --shm-size 32g \
  -p 30000:30000 \
  -v "$HF_CACHE_DIR:/root/.cache/huggingface" \
  --ipc=host \
  lmsysorg/sglang:latest bash
```

The container shell is ready for `sglang serve`.

</Tab>
<Tab title="pip / uv" id="method-1-with-pip-or-uv">

Use Python 3.11 or higher and a compatible CUDA 13 environment.

<Accordion title="CUDA version compatibility">

SGLang requires CUDA 13. CUDA 12 (`cu129`) wheels and images were retired with the upgrade to PyTorch 2.14, which publishes no CUDA 12.9 builds. SGLang 0.5.19 is the last release with a CUDA 12 lane (PyTorch 2.13).

</Accordion>

**Prepare the environment**

Use uv for faster installation. Install it with pip, or follow the [uv installation instructions](https://docs.astral.sh/uv/getting-started/installation/):

```bash
pip install --upgrade pip
pip install uv
```

Create and activate a virtual environment:

```bash Command
uv venv --python 3.12
source .venv/bin/activate
```

**Install SGLang**

```bash
uv pip install --prerelease=allow sglang
```

<Accordion title="Why --prerelease=allow?">

Some of SGLang's dependencies only publish pre-releases on PyPI, so without `--prerelease=allow` uv older than 0.12.0 silently installs SGLang 0.5.9. On [uv 0.12.0](https://github.com/astral-sh/uv/releases/tag/0.12.0) and newer the flag is a harmless no-op.
</Accordion>

<Accordion title="Nightly builds" id="nightly-builds">

To pick up the latest features and fixes before the next stable release, install a nightly build. Nightly wheels are built from the latest `main` and published to the SGLang wheel index. Add that index with `--extra-index-url`, and combine `--prerelease=allow` with `--index-strategy unsafe-best-match` so uv considers the nightly (pre-release) version alongside PyPI:

```bash Command
uv pip install --prerelease=allow --index-strategy unsafe-best-match --extra-index-url https://docs.sglang.ai/whl/cu130/ sglang
```

</Accordion>

For `CUDA_HOME` errors, see [Troubleshooting](#cuda_home).

</Tab>
<Tab title="From source" id="method-2-from-source">

Use Python 3.11 or higher in an activated Python environment, with CUDA dependencies appropriate for the version you build.

**Get the source**

Clone a release tag (the example below pins one); choose another from [GitHub releases](https://github.com/sgl-project/sglang/releases) as needed:

```bash
git clone -b v0.5.21 https://github.com/sgl-project/sglang.git
cd sglang
```

**Install SGLang**

Install the Python package in editable mode so local source changes are reflected in your environment:

```bash
pip install --upgrade pip
pip install -e "python"
```

<Accordion title="Development environment">

For contributing to SGLang, follow the [development environment guide](/docs/developer_guide/development_guide_using_docker#setup-docker-container), which covers a container with development tools and dependencies installed.

</Accordion>

For `CUDA_HOME` errors, see [Troubleshooting](#cuda_home).

</Tab>
</Tabs>

## Start a model server

Start a model server inside your Docker container or activated Python environment. Replace `MODEL_PATH` with a Hugging Face model ID or a local model directory:

```bash
sglang serve MODEL_PATH --host 0.0.0.0 --port 30000
```

Additional launch arguments depend on the model and your hardware.

- [Quickstart](/docs/get-started/quickstart): Launch a model and send a request to verify the server.
- [Cookbook](/cookbook/intro): Find model-specific launch arguments for your hardware.

## Deployment options

Choose how to run SGLang as a service. Expand an option for setup instructions.

<AccordionGroup>

<a id="method-4-using-kubernetes" />

<Accordion title="Kubernetes" id="kubernetes" description="Serve models on a Kubernetes cluster, on one node or across multiple nodes.">

Please check out [OME](https://github.com/sgl-project/ome), a Kubernetes operator for enterprise-grade management and serving of large language models (LLMs).

1. Option 1: For single node serving (typically when the model size fits into GPUs on one node)

   Execute command `kubectl apply -f docker/k8s-sglang-service.yaml`, to create k8s deployment and service, with llama-31-8b as example.

2. Option 2: For multi-node serving (usually when a large model requires more than one GPU node, such as `DeepSeek-R1`)

   Modify the LLM model path and arguments as necessary, then execute command `kubectl apply -f docker/k8s-sglang-distributed-sts.yaml`, to create two nodes k8s statefulset and serving service.

</Accordion>

<a id="method-5-using-docker-compose" />

<Accordion title="Docker Compose" id="docker-compose" description="Run a model service on a single Docker host with a Compose configuration.">

> This method is recommended if you plan to serve it as a service.
> A better approach is to use the [k8s-sglang-service.yaml](https://github.com/sgl-project/sglang/blob/main/docker/k8s-sglang-service.yaml).

1. Copy the [compose.yml](https://github.com/sgl-project/sglang/blob/main/docker/compose.yaml) to your local machine
2. Execute the command `docker compose up -d` in your terminal.

</Accordion>

<a id="method-6-run-on-kubernetes-or-clouds-with-skypilot" />

<Accordion title="SkyPilot" id="skypilot" description="Deploy on Kubernetes or across cloud providers from one YAML configuration.">

To deploy on Kubernetes or 12+ clouds, you can use [SkyPilot](https://github.com/skypilot-org/skypilot).

1. Install SkyPilot and set up Kubernetes cluster or cloud access: see [SkyPilot's documentation](https://skypilot.readthedocs.io/en/latest/getting-started/installation.html).
2. Deploy on your own infra with a single command and get the HTTP API endpoint:

<Accordion title="SkyPilot YAML: sglang.yaml">

```yaml Config
# sglang.yaml
envs:
  HF_TOKEN: null

resources:
  image_id: docker:lmsysorg/sglang:latest
  accelerators: A100
  ports: 30000

run: |
  conda deactivate
  python3 -m sglang.launch_server \
    --model-path meta-llama/Llama-3.1-8B-Instruct \
    --host 0.0.0.0 \
    --port 30000
```

</Accordion>

```bash Command
# Deploy on any cloud or Kubernetes cluster. Use --cloud <cloud> to select a specific cloud provider.
HF_TOKEN=<secret> sky launch -c sglang --env HF_TOKEN sglang.yaml

# Get the HTTP API endpoint
sky status --endpoint 30000 sglang
```

3. To further scale up your deployment with autoscaling and failure recovery, check out the [SkyServe + SGLang guide](https://github.com/skypilot-org/skypilot/tree/master/llm/sglang#serving-llama-2-with-sglang-for-more-traffic-using-skyserve).

</Accordion>

<a id="method-7-run-on-aws-sagemaker" />

<Accordion title="AWS SageMaker" id="aws-sagemaker" description="Deploy on SageMaker with a pre-built SGLang image or your own container.">

To deploy on SGLang on AWS SageMaker, check out [AWS SageMaker Inference](https://aws.amazon.com/sagemaker/ai/deploy)

Amazon Web Services provide supports for SGLang containers along with routine security patching. For available SGLang containers, check out [AWS SGLang DLCs](https://aws.github.io/deep-learning-containers/reference/available_images/#sglang).

To deploy a pre-built SGLang Deep Learning Container without building your own image, see [Amazon SageMaker AI](/docs/basic_usage/aws_sagemaker).

To host a model with your own container, follow the following steps:

1. Build a docker container with [sagemaker.Dockerfile](https://github.com/sgl-project/sglang/blob/main/docker/sagemaker.Dockerfile) alongside the [serve](https://github.com/sgl-project/sglang/blob/main/docker/serve) script.
2. Push your container onto AWS ECR.

<Accordion title="Build script: build-and-push.sh">

```bash Command
#!/bin/bash
AWS_ACCOUNT="<YOUR_AWS_ACCOUNT>"
AWS_REGION="<YOUR_AWS_REGION>"
REPOSITORY_NAME="<YOUR_REPOSITORY_NAME>"
IMAGE_TAG="<YOUR_IMAGE_TAG>"

ECR_REGISTRY="${AWS_ACCOUNT}.dkr.ecr.${AWS_REGION}.amazonaws.com"
IMAGE_URI="${ECR_REGISTRY}/${REPOSITORY_NAME}:${IMAGE_TAG}"

echo "Starting build and push process..."

# Login to ECR
echo "Logging into ECR..."
aws ecr get-login-password --region ${AWS_REGION} | docker login --username AWS --password-stdin ${ECR_REGISTRY}

# Build the image
echo "Building Docker image..."
docker build -t ${IMAGE_URI} -f sagemaker.Dockerfile .

echo "Pushing ${IMAGE_URI}"
docker push ${IMAGE_URI}

echo "Build and push completed successfully!"
```

</Accordion>

3. Deploy a model for serving on AWS Sagemaker, refer to [deploy_and_serve_endpoint.py](https://github.com/sgl-project/sglang/blob/main/examples/sagemaker/deploy_and_serve_endpoint.py). For more information, check out [sagemaker-python-sdk](https://github.com/aws/sagemaker-python-sdk).
   1. By default, the model server on SageMaker will run with the following command: `python3 -m sglang.launch_server --model-path opt/ml/model --host 0.0.0.0 --port 8080`. This is optimal for hosting your own model with SageMaker.
   2. To modify your model serving parameters, the [serve](https://github.com/sgl-project/sglang/blob/main/docker/serve) script allows for all available options within `python3 -m sglang.launch_server --help` cli by specifying environment variables with prefix `SM_SGLANG_`.
   3. The serve script will automatically convert all environment variables with prefix `SM_SGLANG_` from `SM_SGLANG_INPUT_ARGUMENT` into `--input-argument` to be parsed into `python3 -m sglang.launch_server` cli.
   4. For example, to run [Qwen/Qwen3-0.6B](https://huggingface.co/Qwen/Qwen3-0.6B) with reasoning parser, simply add additional environment variables `SM_SGLANG_MODEL_PATH=Qwen/Qwen3-0.6B` and `SM_SGLANG_REASONING_PARSER=qwen3`.

</Accordion>

</AccordionGroup>

<a id="common-notes" />

## Troubleshooting

### CUDA_HOME

If installation fails with `OSError: CUDA_HOME environment variable is not set`, set `CUDA_HOME` to your CUDA Toolkit installation directory. Replace the path below with the actual path on your machine:

```bash
export CUDA_HOME="/path/to/cuda"
```

For a versioned installation, this is typically `/usr/local/cuda-VERSION`. Alternatively, install FlashInfer first using the [FlashInfer installation instructions](https://docs.flashinfer.ai/installation.html), then retry the SGLang installation.

### FlashInfer

- [FlashInfer](https://github.com/flashinfer-ai/flashinfer) is the default attention kernel backend. It only supports sm75 and above. If you encounter any FlashInfer-related issues on sm75+ devices (e.g., T4, A10, A100, L4, L40S, H100), please switch to other kernels by adding `--attention-backend triton --sampling-backend pytorch` and open an issue on GitHub.
- To reinstall flashinfer locally, use the following command: `pip3 install --upgrade flashinfer-python --force-reinstall --no-deps` and then delete the cache with `rm -rf ~/.cache/flashinfer`.

---

### Docs Hardware Platforms Amd Gpu (`docs/docs/hardware-platforms/amd_gpu.mdx`)

---
title: "AMD GPUs"
---
This document describes how to run SGLang on AMD GPUs. If you encounter issues or have questions, please [open an issue](https://github.com/sgl-project/sglang/issues).

## System Configuration

When using AMD GPUs (such as MI300X), certain system-level optimizations help ensure stable performance. Here we take MI300X as an example. AMD provides official documentation for MI300X optimization and system tuning:

- [AMD MI300X Tuning Guides](https://rocm.docs.amd.com/en/latest/how-to/tuning-guides/mi300x/index.html)
- [LLM inference performance validation on AMD Instinct MI300X](https://rocm.docs.amd.com/en/latest/how-to/rocm-for-ai/inference/vllm-benchmark.html)
- [AMD Instinct MI300X System Optimization](https://rocm.docs.amd.com/en/latest/how-to/system-optimization/mi300x.html)
- [AMD Instinct MI300X Workload Optimization](https://rocm.docs.amd.com/en/latest/how-to/rocm-for-ai/inference-optimization/workload.html)
- [Supercharge DeepSeek-R1 Inference on AMD Instinct MI300X](https://rocm.blogs.amd.com/artificial-intelligence/DeepSeekR1-Part2/README.html)

**NOTE:** We strongly recommend reading these docs and guides entirely to fully utilize your system.

Below are a few key settings to confirm or enable for SGLang:

### Update GRUB Settings

In `/etc/default/grub`, append the following to `GRUB_CMDLINE_LINUX`:

```text GRUB Configuration
pci=realloc=off iommu=pt
```

Afterward, run `sudo update-grub` (or your distro’s equivalent) and reboot.

### Disable NUMA Auto-Balancing

```bash Disable NUMA
sudo sh -c 'echo 0 > /proc/sys/kernel/numa_balancing'
```

You can automate or verify this change using [this helpful script](https://github.com/ROCm/triton/blob/rocm_env/scripts/amd/env_check.sh).

Again, please go through the entire documentation to confirm your system is using the recommended configuration.

## Install SGLang

You can install SGLang using one of the methods below.

### Install from Source

```bash Command
# Use the last release branch
git clone -b v0.5.21 https://github.com/sgl-project/sglang.git
cd sglang

# Compile sgl-kernel
pip install --upgrade pip
cd python/sglang/kernels/aot
python setup_rocm.py install

# Install sglang python package along with diffusion support
cd ../../../..
rm -rf python/pyproject.toml && mv python/pyproject_other.toml python/pyproject.toml
pip install -e "python[all_hip]"
```

### Install Using Docker (Recommended)

The docker images are available on Docker Hub at [lmsysorg/sglang](https://hub.docker.com/r/lmsysorg/sglang/tags), built from [rocm.Dockerfile](https://github.com/sgl-project/sglang/tree/main/docker).

The steps below show how to build and use an image.

1. Build the docker image.
   If you use pre-built images, you can skip this step and replace `sglang_image` with the pre-built image names in the steps below.

   ```bash Command
   docker build -t sglang_image -f rocm.Dockerfile .
   ```

2. Create a convenient alias.

   ```bash Command
   alias drun='docker run -it --rm --network=host --privileged --device=/dev/kfd --device=/dev/dri \
       --ipc=host --shm-size 16G --group-add video --cap-add=SYS_PTRACE \
       --security-opt seccomp=unconfined \
       -v $HOME/dockerx:/dockerx \
       -v /data:/data'
   ```

   If you are using RDMA, please note that:
     - `--network host` and `--privileged` are required by RDMA. If you don't need RDMA, you can remove them.
     - You may need to set `NCCL_IB_GID_INDEX` if you are using RoCE, for example: `export NCCL_IB_GID_INDEX=3`.

3. Launch the server.

   **NOTE:** Replace `<secret>` below with your [huggingface hub token](https://huggingface.co/docs/hub/en/security-tokens).

   ```bash Command
   drun -p 30000:30000 \
       -v ~/.cache/huggingface:/root/.cache/huggingface \
       --env "HF_TOKEN=<secret>" \
       sglang_image \
       python3 -m sglang.launch_server \
       --model-path NousResearch/Meta-Llama-3.1-8B \
       --host 0.0.0.0 \
       --port 30000
   ```

4. To verify the utility, you can run a benchmark in another terminal or refer to [other docs](../basic_usage/openai_api_completions) to send requests to the engine.

   ```bash Command
   drun sglang_image \
       python3 -m sglang.bench_serving \
       --backend sglang \
       --dataset-name random \
       --num-prompts 4000 \
       --random-input 128 \
       --random-output 128
   ```

With your AMD system properly configured and SGLang installed, you can now fully leverage AMD hardware to power SGLang’s machine learning capabilities.

## Quantization on AMD GPUs

The [Quantization documentation](../advanced_features/quantization#platform-compatibility) has a full compatibility matrix. The short version: FP8, AWQ, MXFP4, W8A8, GPTQ, compressed-tensors, Quark, and **petit_nvfp4** (NVFP4 on ROCm via [Petit](https://github.com/causalflow-ai/petit-kernel)) all work on AMD. Methods that depend on Marlin or NVIDIA-specific kernels (`awq_marlin`, `gptq_marlin`, `gguf`, `modelopt_fp8`, `modelopt_fp4`) do not.

A few things to keep in mind:

- FP8 works via Aiter or Triton. Pre-quantized FP8 models like DeepSeek-V3/R1 work out of the box.
- AWQ uses Triton dequantization kernels on AMD. The faster Marlin path is not available.
- MXFP4 requires CDNA3/CDNA4 and `SGLANG_USE_AITER=1`.
- `petit_nvfp4` enables NVFP4 models (e.g., [Llama 3.3 70B FP4](https://huggingface.co/nvidia/Llama-3.3-70B-Instruct-FP4)) on MI250/MI300X via [Petit](https://github.com/causalflow-ai/petit-kernel). Install with `pip install petit-kernel`; no `--quantization` flag needed when loading pre-quantized NVFP4 models.
- `quark_int4fp8_moe` is an AMD-only online quantization method for MoE models on CDNA3/CDNA4.

Several of these backends are accelerated by [Aiter](https://github.com/ROCm/aiter). Enable it with:

```bash Command
export SGLANG_USE_AITER=1
```

Example -- serving an AWQ model:

```bash Command
python3 -m sglang.launch_server \
    --model-path hugging-quants/Mixtral-8x7B-Instruct-v0.1-AWQ-INT4 \
    --trust-remote-code \
    --port 30000 --host 0.0.0.0
```

Example -- FP8 online quantization:

```bash Command
python3 -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \
    --quantization fp8 \
    --port 30000 --host 0.0.0.0
```

## Examples

### Running DeepSeek-V3

The only difference when running DeepSeek-V3 is in how you start the server. Here's an example command:

```bash Command
drun -p 30000:30000 \
    -v ~/.cache/huggingface:/root/.cache/huggingface \
    --ipc=host \
    --env "HF_TOKEN=<secret>" \
    sglang_image \
    python3 -m sglang.launch_server \
    --model-path deepseek-ai/DeepSeek-V3 \ # <- here
    --tp 8 \
    --trust-remote-code \
    --host 0.0.0.0 \
    --port 30000
```

[Running DeepSeek-R1 on a single NDv5 MI300X VM](https://techcommunity.microsoft.com/blog/azurehighperformancecomputingblog/running-deepseek-r1-on-a-single-ndv5-mi300x-vm/4372726) could also be a good reference.

### Running Llama3.1

Running Llama3.1 is nearly identical to running DeepSeek-V3. The only difference is in the model specified when starting the server, shown by the following example command:

```bash Command
drun -p 30000:30000 \
    -v ~/.cache/huggingface:/root/.cache/huggingface \
    --ipc=host \
    --env "HF_TOKEN=<secret>" \
    sglang_image \
    python3 -m sglang.launch_server \
    --model-path meta-llama/Meta-Llama-3.1-8B-Instruct \ # <- here
    --tp 8 \
    --trust-remote-code \
    --host 0.0.0.0 \
    --port 30000
```

### Warmup Step

When the server displays `The server is fired up and ready to roll!`, it means the startup is successful.

## Strix Halo / gfx1151 (RDNA3.5 iGPU)

AMD Ryzen AI MAX+ / Strix Halo (`gfx1151`) and Strix Point (`gfx1150`) are wave32 RDNA3.5 iGPUs. They are **not** covered by the Instinct/CDNA `rocm.Dockerfile` image. Use the dedicated gfx1151 image instead.

**Official image tag pattern** (nightly on Docker Hub [`rocm/sgl-dev`](https://hub.docker.com/r/rocm/sgl-dev/tags)):

```bash
rocm/sgl-dev:*-gfx1151*
# example: rocm/sgl-dev:v0.5.20-rocm724-gfx1151-20260924
```

The image sets `SGLANG_USE_AITER=0` (see `docker/rocm-gfx1151.Dockerfile`). AITER kernels are CDNA/wave64-oriented and are unsafe as defaults on gfx115x.

**Host requirements**: expose `/dev/kfd` and `/dev/dri`, and add the container to the `video` and `render` groups. Strix Halo has no discrete VRAM — the GPU carves memory from system RAM (configure GTT / BIOS aperture as needed on the host).

```bash
docker run -it --rm \
  --device=/dev/kfd --device=/dev/dri \
  --group-add video --group-add render \
  --security-opt seccomp=unconfined \
  --ipc=host --shm-size 16g \
  -p 30000:30000 \
  -v ~/.cache/huggingface:/root/.cache/huggingface \
  rocm/sgl-dev:v0.5.20-rocm724-gfx1151-20260924 \
  bash
```

**Serving defaults on gfx1151**:

- LLM / SRT: `--attention-backend triton` (or rely on the gfx115 auto-default), `--num-gpus 1`
- Diffusion / DiT (e.g. Wan2.2): `--attention-backend torch_sdpa`, `--num-gpus 1`
- Keep `SGLANG_USE_AITER=0` (already set in the official image)

---

### Docs Hardware Platforms Apple Metal (`docs/docs/hardware-platforms/apple_metal.mdx`)

---
title: "Apple Silicon with Metal"
metatags:
    description: "Run SGLang on Apple Silicon using the Metal backend."
---

This document describes how to run the SGLang serving runtime on Apple Silicon
using [MLX](https://opensource.apple.com/projects/mlx/). SGLang Diffusion uses
PyTorch MPS instead; see its [installation guide](/docs/sglang-diffusion/installation#platform-specific-apple-mps).
If you encounter issues or have questions, please [open an issue](https://github.com/sgl-project/sglang/issues).

## Prerequisites

The MLX runtime requires Apple Silicon with macOS 14 or newer, stable PyTorch
2.13.x, and stable MLX 0.32.0 or newer. The `srt_mps` extra installs PyTorch
2.13.0 and MLX 0.32.0 or newer; startup accepts stable PyTorch 2.13 patch
releases and newer stable MLX releases.

With `SGLANG_USE_MLX=1`, SGLang validates both framework versions and Metal
availability during argument initialization and stops before resolving or
downloading a model when the runtime is incompatible.

Building the optional native Metal kernels in `sgl-kernel` requires the Metal
shader compiler from the full Xcode application. The standalone Xcode Command
Line Tools are not sufficient. After installing Xcode, select it with:

```bash
sudo xcode-select -s /Applications/Xcode.app/Contents/Developer
```

Verify the compiler with `xcrun -sdk macosx metal --version`.

## Install SGLang

You can install SGLang using one of the methods below.

### Install from Source

```bash
# Use the default branch
git clone https://github.com/sgl-project/sglang.git
cd sglang

# Create and activate a virtual environment
uv venv -p 3.12 sglang-metal
source sglang-metal/bin/activate

# (Optional) Compile sgl-kernel
uv pip install --upgrade pip
uv run python/sglang/kernels/aot/setup_metal.py install

# Install sglang python package along with diffusion support
rm -f python/pyproject.toml && mv python/pyproject_other.toml python/pyproject.toml
uv pip install -e "python[all_mps]"
```

## Launch of the Serving Engine

Launch the server with:

```bash
SGLANG_USE_MLX=1 python -m sglang.launch_server \
  --model <MODEL_ID_OR_PATH> \
  --disable-cuda-graph \
  --host 0.0.0.0
```

**Key Parameters Explained:**

1. `SGLANG_USE_MLX=1` - Enables the use of MLX as the SGLang runtime backend (if disabled, SGLang will fall back to `torch.mps`, which has less support)
2. `--disable-cuda-graph` - Disables usage of CUDA graph, which is not relevant for Apple Metal.
3. `--disable-overlap-schedule` - Disables overlap scheduling (enabled/not present by default) achieved using MLX's `async_eval()`
4. `SGLANG_MLX_USE_CUSTOM_ROPE=1` - Enables the optional custom Metal RoPE kernel. It is disabled by default, so the MLX backend uses the standard RoPE path unless you opt in for A/B testing.
5. `SGLANG_MLX_FUSE_SWIGLU=1` - Enables the use of fused Swish-Gated Linear Unit kernel (disabled by default)
6. `SGLANG_MLX_CLEAR_CACHE_STEPS=256` - Sets the number of decode steps before clearing the MLX cache (256 by default)

## Quantization

The MLX backend supports two quantization paths on Apple Silicon:

1. **Pre-quantized HF repos.** Any `mlx-community/<model>-4bit` (or `-8bit`) repo loads directly through `mlx_lm.load(...)` — no extra flag needed.
   ```bash
   SGLANG_USE_MLX=1 python -m sglang.launch_server \
     --model-path mlx-community/Qwen3-0.6B-4bit \
     --disable-cuda-graph
   ```
2. **On-the-fly quantization.** For any fp16 model, pass `--quantization mlx_q4` or `--quantization mlx_q8` to have sglang quantize the weights at load time via `mlx_lm.utils.quantize_model` (group size 64, the mlx-community default). The quantized weights stay in process memory; the on-disk model is untouched.
   ```bash
   SGLANG_USE_MLX=1 python -m sglang.launch_server \
     --model-path Qwen/Qwen3-0.6B \
     --quantization mlx_q4 \
     --disable-cuda-graph
   ```
   Expected log line:
   ```
   Quantizing MLX model on-the-fly: bits=4 group_size=64 (preset=mlx_q4)
   Quantization complete in 0.13s — active mem: 1.11 GB -> 0.31 GB (71.9% reduction)
   ```
   The MLX backend silently ignores `--quantization mlx_q4` when the model is already quantized in its HF config (path 1), so the same flag is safe to pass either way.

## Benchmarking with Requests

`sglang.benchmark.one_batch` calls the synchronous prefill/decode methods directly without going through the scheduler and the overlap code path.

`sglang.benchmark.offline_throughput` can toggle overlap scheduling as it uses the scheduler and the overlap code path by using the flag `--disable-overlap-schedule`.

### Throughput Testing

Basic synchronous one batch throughput:
```bash
SGLANG_USE_MLX=1 python -m sglang.benchmark.one_batch \
  --model-path <MODEL_ID_OR_PATH> \
  --disable-cuda-graph \
  --tp-size 1 \
  --batch-size 1 \
  --input-len 60 \
  --output-len 10
```

Synchronous offline throughput:
```bash
SGLANG_USE_MLX=1 python -m sglang.benchmark.offline_throughput \
  --model-path <MODEL_ID_OR_PATH> \
  --disable-cuda-graph \
  --num-prompts 1 \
  --disable-overlap-schedule
```

Asynchronous offline throughput:
```bash
SGLANG_USE_MLX=1 python -m sglang.benchmark.offline_throughput \
  --model-path <MODEL_ID_OR_PATH> \
  --disable-cuda-graph \
  --num-prompts 1
```

---

### Docs Hardware Platforms Cpu Server (`docs/docs/hardware-platforms/cpu_server.mdx`)

---
title: "CPU Servers"
---
The document addresses how to set up the [SGLang](https://github.com/sgl-project/sglang) environment and run LLM inference on CPU servers.
SGLang is enabled and optimized on the CPUs equipped with Intel® AMX® Instructions,
which are 4th generation or newer Intel® Xeon® Scalable Processors.

A number of popular LLMs are optimized and run efficiently on CPU,
including the most notable open-source models like Llama series, Qwen series,
and DeepSeek series like DeepSeek-R1 and DeepSeek-V3.1-Terminus.
Please check the [SGLang Cookbook pages](https://docs.sglang.io/cookbook/intro)
in which the support status and example commands can be found.

## Installation

### Install Using Docker

It is recommended to use Docker for setting up the SGLang environment.

#### Pull from Docker Hub

Pull the prebuilt docker image of SGLang package releases from `lmsysorg/sglang` repository.
The [CPU image tags](https://hub.docker.com/r/lmsysorg/sglang/tags?name=xeon) end with `xeon` suffix.
The image pulling command is like:

```bash Command
docker pull lmsysorg/sglang:v0.5.13-xeon
```

#### Build from Dockerfile

A [Dockerfile](https://github.com/sgl-project/sglang/blob/main/docker/xeon.Dockerfile) is provided to facilitate the installation from latest source code.
Replace `<secret>` below with your [HuggingFace access token](https://huggingface.co/docs/hub/en/security-tokens).

```bash Command
# Clone the SGLang repository
git clone https://github.com/sgl-project/sglang.git
cd sglang/docker

# Build the docker image
docker build -t sglang-cpu:latest -f xeon.Dockerfile .

# Initiate a docker container
docker run \
    -it \
    --privileged \
    --ipc=host \
    --network=host \
    -v /dev/shm:/dev/shm \
    -v ~/.cache/huggingface:/root/.cache/huggingface \
    -p 30000:30000 \
    -e "HF_TOKEN=<secret>" \
    sglang-cpu:latest /bin/bash
```

### Install From Source

If you prefer to install SGLang in a bare metal environment,
the setup process is as follows:

Please install the required packages and libraries beforehand if
they are not already present on your system.
You can refer to the Ubuntu-based installation commands in
[the Dockerfile](https://github.com/sgl-project/sglang/blob/main/docker/xeon.Dockerfile#L7)
for guidance.

1. Install `uv` package manager, then create and activate a virtual environment:

```bash Command
# Taking '/opt' as the example uv env folder, feel free to change it as needed
cd /opt
curl -LsSf https://astral.sh/uv/install.sh | sh
source $HOME/.local/bin/env
uv venv --python 3.12
source .venv/bin/activate
```

2. Create a config file to direct the installation channel
    (a.k.a. index-url) of `torch` related packages:

```bash Command
vim .venv/uv.toml
```

Press 'a' to enter insert mode of `vim`, paste the following content into the created file

```file
[[index]]
name = "torch"
url = "https://download.pytorch.org/whl/cpu"

[[index]]
name = "torchvision"
url = "https://download.pytorch.org/whl/cpu"

[[index]]
name = "torchaudio"
url = "https://download.pytorch.org/whl/cpu"

[[index]]
name = "triton"
url = "https://download.pytorch.org/whl/cpu"

```

Save the file (in `vim`, press 'esc' to exit insert mode, then ':x+Enter'),
and set it as the default `uv` config.

```bash Command
export UV_CONFIG_FILE=/opt/.venv/uv.toml
```

3. Clone the `sglang` source code and build the packages

```bash Command
# Clone the SGLang code
git clone https://github.com/sgl-project/sglang.git
cd sglang
git checkout <YOUR-DESIRED-VERSION>

# Use dedicated toml file
cd python
cp pyproject_cpu.toml pyproject.toml
# Install SGLang dependent libs, and build SGLang main package
uv pip install --upgrade pip setuptools
uv pip install .

# Build the CPU backend kernels
cd sglang/kernels/aot
cp pyproject_cpu.toml pyproject.toml
uv pip install .
```

4. Set the required environment variables

```bash Command
export SGLANG_USE_CPU_ENGINE=1

# Set 'LD_LIBRARY_PATH' and 'LD_PRELOAD' to ensure the libs can be loaded by sglang processes
export LD_LIBRARY_PATH=/usr/lib/x86_64-linux-gnu
export LD_PRELOAD=${LD_PRELOAD}:/opt/.venv/lib/libiomp5.so:${LD_LIBRARY_PATH}/libtcmalloc.so.4:${LD_LIBRARY_PATH}/libtbbmalloc.so.2
```

Notes:

- Note that the environment variable `SGLANG_USE_CPU_ENGINE=1`
    is required to enable the SGLang service with the CPU engine.

- If you encounter code compilation issues during the `sgl-kernel` building process,
    please check your `gcc` and `g++` versions and upgrade them if they are outdated.
    It is recommended to use `gcc-13` and `g++-13` as they have been verified
    in the official Docker container.

- The system library path is typically located in one of the following directories:
    `~/.local/lib/`, `/usr/local/lib/`, `/usr/local/lib64/`, `/usr/lib/`, `/usr/lib64/`
    and `/usr/lib/x86_64-linux-gnu/`. In the above example commands, `/usr/lib/x86_64-linux-gnu`
    is used. Please adjust the path according to your server configuration.

- It is recommended to add the following to your `~/.bashrc` file to
    avoid setting these variables every time you open a new terminal:

    ```bash Command
    source .venv/bin/activate
    export SGLANG_USE_CPU_ENGINE=1
    export LD_LIBRARY_PATH=<YOUR-SYSTEM-LIBRARY-FOLDER>
    export LD_PRELOAD=<YOUR-LIBS-PATHS>
    ```

## Launch of the Serving Engine

Example command to launch SGLang serving:

```bash Launch Server
sglang serve                          \
    --model-path <MODEL_ID_OR_PATH>   \
    --trust-remote-code               \
    --disable-overlap-schedule        \
    --device cpu                      \
    --host 0.0.0.0                    \
    --tp 6
```

Notes:

1. For running W8A8 quantized models, please add the flag `--quantization w8a8_int8`.

2. The flag `--tp 6` specifies that tensor parallelism will be applied using 6 ranks (TP6).
    The number of TP specified is how many TP ranks will be used during the execution.
    On a CPU platform, a TP rank means a sub-NUMA cluster (SNC).
    Usually we can get the SNC information (How many available) from the Operating System with e.g. `lscpu` command.

    If the specified TP rank number differs from the total SNC count,
    the system will automatically utilize the first `n` SNCs.
    Note that `n` cannot exceed the total SNC number, doing so will result in an error.

    `SGLANG_CPU_OMP_THREADS_BIND` allows explicit control of CPU cores for each tensor parallel (TP) rank.

    **example 1**: Run SGLang service with TP=6, using the first 40 cores of each SNC on a Xeon® 6980P server,
    which has 43-43-42 cores on the 3 SNCs of a socket, we should set:

    ```bash Command
    export SGLANG_CPU_OMP_THREADS_BIND="0-39|43-82|86-125|128-167|171-210|214-253"
    ```
    This configuration is equivalent to:
    - rank 0: `numactl -C 0-39 -m 0`
    - rank 1: `numactl -C 43-82 -m 1`
    - rank 2: `numactl -C 86-125 -m 2`
    - rank 3: `numactl -C 128-167 -m 3`
    - rank 4: `numactl -C 171-210 -m 4`
    - rank 5: `numactl -C 214-253 -m 5`


    **example 2**: Run SGLang service with TP=2, using 96 cores cross 3 SNCs on a Xeon® 6972P server,
    which has 32-32-32 cores on the 3 SNCs in a socket, we should set:
    ```bash Command
    export SGLANG_CPU_OMP_THREADS_BIND="0-95|96-191"
    ```
    This configuration is equivalent to:
    - rank 0: `numactl -C 0-95 -m 0-2`
    - rank 1: `numactl -C 96-191 -m 3-5`

    Please beware that with SGLANG_CPU_OMP_THREADS_BIND set,
    the available memory amounts of the ranks may not be determined in prior.
    You may need to set proper `--max-total-tokens` to avoid the out-of-memory error.

3. For optimizing decoding with torch.compile, please add the flag `--enable-torch-compile`.
    To specify the maximum batch size when using `torch.compile`, set the flag `--torch-compile-max-bs`.
    For example, `--enable-torch-compile --torch-compile-max-bs 4` means using `torch.compile`
    and setting the maximum batch size to 4.

4. A warmup step is automatically triggered when the service is started.
    The server is ready when you see the log `The server is fired up and ready to roll!`.

## Benchmarking with Requests

You can benchmark the performance via the `bench_serving` script.
Run the command in another terminal. An example command would be:

```bash Run Benchmark
python -m sglang.bench_serving   \
    --dataset-name random        \
    --random-input-len 1024      \
    --random-output-len 1024     \
    --num-prompts 1              \
    --request-rate inf           \
    --random-range-ratio 1.0
```

Detailed parameter descriptions are available via the command:

```bash Benchmark Help
python -m sglang.bench_serving -h
```

Additionally, requests can be formatted using
[the OpenAI Completions API](../basic_usage/openai_api_completions)
and sent via the command line (e.g., using `curl`) or through your own scripts.

## Example Usage Commands

Large Language Models can range from fewer than 1 billion to several hundred billion parameters.
Dense models larger than 20B are expected to run on flagship 6th Gen Intel® Xeon® processors
with dual sockets and a total of 6 sub-NUMA clusters. Dense models of approximately 10B parameters or fewer,
or MoE (Mixture of Experts) models with fewer than 10B activated parameters, can run on more common
4th generation or newer Intel® Xeon® processors, or utilize a single socket of the flagship 6th Gen Intel® Xeon® processors.

### Example: Running DeepSeek-V3.1-Terminus

An example command to launch service of W8A8_INT8 DeepSeek-V3.1-Terminus on a Xeon® 6980P server:

```bash W8A8_INT8
sglang serve                                                        \
    --model-path IntervitensInc/DeepSeek-V3.1-Terminus-Channel-int8 \
    --trust-remote-code                                             \
    --disable-overlap-schedule                                      \
    --device cpu                                                    \
    --quantization w8a8_int8                                        \
    --enable-torch-compile                                          \
    --torch-compile-max-bs 4                                        \
    --host 0.0.0.0                                                  \
    --tp 6
```

Similarly, an example command to launch service of FP8 DeepSeek-V3.1-Terminus would be:

```bash FP8
sglang serve                                         \
    --model-path deepseek-ai/DeepSeek-V3.1-Terminus  \
    --trust-remote-code                              \
    --disable-overlap-schedule                       \
    --device cpu                                     \
    --enable-torch-compile                           \
    --torch-compile-max-bs 4                         \
    --host 0.0.0.0                                   \
    --tp 6
```

Note: Please set `--torch-compile-max-bs` to the maximum desired batch size for your deployment.
The value `4` in the examples is illustrative.

### Example: Running Llama-3.2-3B

An example command to launch service of Llama-3.2-3B with BF16 precision:

```bash BF16
sglang serve                                         \
    --model-path meta-llama/Llama-3.2-3B-Instruct    \
    --trust-remote-code                              \
    --disable-overlap-schedule                       \
    --device cpu                                     \
    --enable-torch-compile                           \
    --torch-compile-max-bs 16                        \
    --host 0.0.0.0                                   \
    --tp 3
```

The example command to launch service of W8A8_INT8 version of Llama-3.2-3B:

```bash W8A8_INT8
sglang serve                                            \
    --model-path RedHatAI/Llama-3.2-3B-quantized.w8a8   \
    --trust-remote-code                                 \
    --disable-overlap-schedule                          \
    --device cpu                                        \
    --quantization w8a8_int8                            \
    --enable-torch-compile                              \
    --torch-compile-max-bs 16                           \
    --host 0.0.0.0                                      \
    --tp 3
```

Note: The `--torch-compile-max-bs` and `--tp` settings are examples that should be adjusted for your setup.
For instance, use `--tp 3` to utilize 1 socket with 3 sub-NUMA clusters on an Intel® Xeon® 6980P server.

Once the server have been launched, you can test it using the `bench_serving` command or create
your own commands or scripts following [the benchmarking example](#benchmarking-with-requests).

---

### Docs Hardware Platforms Mthreads Gpu (`docs/docs/hardware-platforms/mthreads_gpu.mdx`)

---
title: "Moore Threads GPUs"
metatags:
    description: "Run SGLang on Moore Threads GPUs."
---

This document describes how to run SGLang on Moore Threads GPUs. If you
encounter issues or have questions, please [open an issue](https://github.com/sgl-project/sglang/issues).

SGLang uses the MUSA runtime through
[`torch_musa`](https://github.com/MooreThreads/torch_musa) and
[`torchada`](https://github.com/MooreThreads/torchada). The
`python[all_musa]` extra installs the MUSA torch, Triton, TileLang, MATE, and
runtime Python stack from the Moore Threads package index, with public PyPI as
the fallback for common Python dependencies.

## Prerequisites

Install the Moore Threads driver and MUSA toolkit before installing SGLang. For
MTT S5000, follow the [official driver installation guide](https://docs.mthreads.com/driver-linux-server/driver-linux-server-doc-online/MTT_S5000/install_guide).

## Install SGLang

You can install SGLang using one of the methods below.

### Install from Source

Start from an environment with the prerequisites above installed.

```bash Command
git clone https://github.com/sgl-project/sglang.git
cd sglang

python -m pip install --upgrade pip "setuptools<82" wheel
cp python/pyproject_other.toml python/pyproject.toml
python -m pip install -e "python[all_musa]" \
  --index-url https://dl.mthreads.com/repo/api/pypi/pypi/simple \
  --extra-index-url https://pypi.org/simple \
  --trusted-host dl.mthreads.com \
  --no-build-isolation

# Ensure the MUSA Triton wheel (with triton.backends.mtgpu) is installed.
python -m pip install --no-cache-dir --force-reinstall --no-deps \
  --index-url https://dl.mthreads.com/repo/api/pypi/pypi/simple \
  --trusted-host dl.mthreads.com \
  triton==3.2.0
python -c 'import triton.backends.mtgpu'

cd python/sglang/kernels/aot
cp pyproject_musa.toml pyproject.toml
MTGPU_TARGET=mp_31 python setup_musa.py install
```

### Install Using Docker

The Dockerfile installs the MUSA runtime and Python stack declared by
`python/pyproject_other.toml`.

```bash Command
git clone https://github.com/sgl-project/sglang.git
cd sglang

docker build -f docker/musa.Dockerfile -t sglang:main-musa .
```

Run the image with MUSA devices exposed by the host container toolkit.

```bash Command
alias drun='docker run -it --rm --network=host \
  --env MTHREADS_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 \
  --env MTHREADS_DRIVER_CAPABILITIES=all \
  --shm-size=32g \
  -v ~/.cache/huggingface:/root/.cache/huggingface'

drun sglang:main-musa \
  python3 -c 'import triton.backends.mtgpu; print("MUSA Triton backend OK")'
```

Launch the server:

```bash Command
drun sglang:main-musa \
  python3 -m sglang.launch_server \
  --model-path Qwen/Qwen3-8B \
  --host 0.0.0.0 \
  --port 30000
```

When the server displays `The server is fired up and ready to roll!`, startup is
successful.

## Verify

You can send an OpenAI-compatible request to the engine:

```bash Command
curl http://127.0.0.1:30000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "Qwen/Qwen3-8B",
    "messages": [{"role": "user", "content": "Hello!"}],
    "max_tokens": 32
  }'
```

Or run a benchmark:

```bash Command
drun sglang:main-musa \
  python3 -m sglang.bench_serving \
  --backend sglang \
  --dataset-name random \
  --num-prompts 4000 \
  --random-input 128 \
  --random-output 128
```

---

### Docs Hardware Platforms Nvidia Gpus (`docs/docs/hardware-platforms/nvidia-gpus.mdx`)

---
title: NVIDIA GPUs
---

Please refer to the [Installation Guide](../get-started/install) to get started with SGLang on NVIDIA GPUs.

---

### Docs Hardware Platforms Nvidia Jetson (`docs/docs/hardware-platforms/nvidia_jetson.mdx`)

---
title: NVIDIA Jetson Orin
description: Guide for installing and running SGLang on NVIDIA Jetson Orin devices.
---
## Prerequisites

Before starting, ensure the following:

- [**NVIDIA Jetson AGX Orin Devkit**](https://www.nvidia.com/en-us/autonomous-machines/embedded-systems/jetson-orin/) is set up with **JetPack 6.1** or later.
- **CUDA Toolkit** and **cuDNN** are installed.
- Verify that the Jetson AGX Orin is in **high-performance mode**:
```bash
sudo nvpmodel -m 0
```
* * * * *
## Installing and running SGLang with Jetson Containers
Clone the jetson-containers github repository:
```bash
git clone https://github.com/dusty-nv/jetson-containers.git
```
Run the installation script:
```bash
bash jetson-containers/install.sh
```
Build the container image:
```bash
jetson-containers build sglang
```
Run the container:
```
jetson-containers run $(autotag sglang)
```
Or you can also manually run a container with this command:
```
docker run --runtime nvidia -it --rm --network=host IMAGE_NAME
```
* * * * *

Running Inference
-----------------------------------------

Launch the server:
```bash
python -m sglang.launch_server \
  --model-path deepseek-ai/DeepSeek-R1-Distill-Llama-8B \
  --device cuda \
  --dtype half \
  --attention-backend flashinfer \
  --mem-fraction-static 0.8 \
  --context-length 8192
```
The quantization and limited context length (`--dtype half --context-length 8192`) are due to the limited computational resources in [Nvidia jetson kit](https://www.nvidia.com/en-us/autonomous-machines/embedded-systems/jetson-orin/). A detailed explanation can be found in [Server Arguments](../advanced_features/server_arguments).

After launching the engine, refer to [Chat completions](../basic_usage/openai_api_completions#usage) to test the usability.
* * * * *
Structured output with XGrammar
-------------------------------
Please refer to [SGLang doc structured output](../advanced_features/structured_outputs).
* * * * *

Thanks to the support from [Nurgaliyev Shakhizat](https://github.com/shahizat), [Dustin Franklin](https://github.com/dusty-nv) and [Johnny Núñez Cano](https://github.com/johnnynunez).

References
----------
-   [NVIDIA Jetson AGX Orin Documentation](https://developer.nvidia.com/embedded/jetson-agx-orin)

---

--- METRICS ---
- Files Extracted: 101
- Estimated Token Budget: ~379731 tokens
- Canonical Reference: https://codewiki.google/github.com/sgl-project/sglang