.
## Architecture
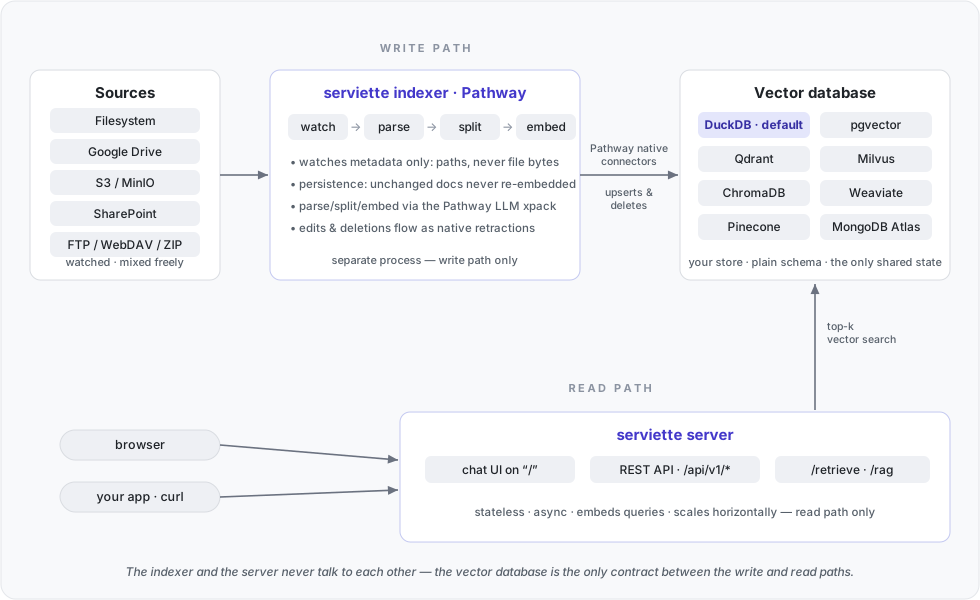
**The two halves are fully decoupled.** The indexer (write path) and the
server (read path) are separate processes — different executables that never
talk to each other. Their only contract is the vector database itself:
- **Independent scaling.** The server is stateless and read-only — run any
number of instances behind a load balancer; each also serves the chat UI at
zero cost. The indexer scales separately: Pathway shards it across worker
processes (`indexer.workers: 8` is how the benchmarks below run), so every
part of the stack scales independently. Bulk re-indexing never slows down
query serving, and query spikes never stall indexing.
- **Failure isolation.** If the indexer is down, serving continues over the
last-synced data; if the server is down, indexing keeps the database fresh.
Either side can be restarted or upgraded independently (the indexer resumes
from its persistence without re-embedding).
- **The database stays yours.** Vectors live in *your* store in a plain,
documented schema — other consumers (BI, other apps, a different retrieval
stack) can read the same collection; serviette doesn't hold it hostage. And
since the default store is an embedded DuckDB file, trying this out costs
nothing to set up.
- **Optional third tier.** For split deployments (UI on a different host than
the API) a standalone `serviette frontend` serves the same chat page and
proxies to the API server-side.
The one deliberate exception: the embedded DuckDB backend trades this
distribution for zero setup — one local file, single-writer, ideal for
laptops and demos (see [docs](https://github.com/pathwaycom/serviette/blob/main/docs/README.md) for its concurrency note).
## Benchmarks
Two self-contained benchmarks, one per axis: what indexing costs in time
and memory, and how accurate the retrieval is.
### Indexing resources
Self-contained benchmark (docker-compose: Qdrant + indexer + server, fully
local embeddings, zero API cost) over a Wikipedia corpus of plain text —
every byte below is extracted text (a PDF collection with the same text
content would weigh several times more) —
see [benchmarks/realtime-data-indexing](https://github.com/pathwaycom/serviette/tree/main/benchmarks/realtime-data-indexing):
| corpus target | ≈ pages | files | chunks (approx.) | indexing time | peak memory (PSS, GiB) | in Qdrant (GiB) |
|---|---|---|---|---|---|---|
| 100 MB | 52 431 | 12 969 | 53 651 | 44 s | 6.86 | 0.61 |
| 1 GB | 524 288 | 240 516 | 604 299 | 4.9 min | 6.82 | 1.85 |
| 3 GB | 1 572 864 | 841 890 | 1 888 846 | 15.4 min | 7.18 | 4.89 |
| 10 GB | 5 242 884 | 3 423 359 | 6 761 214 | 1.0 h | 8.16 | 16.07 |
| 30 GB | 15 728 646 | 9 202 620 | 20 933 962 | 3.1 h | 10.40 | 48.57 |
| 50 GB | 26 214 382 | 17 083 603 | 37 472 786 | 6.0 h | 14.65 | 84.45 |
The table and both figures come from the same six runs. Raw summaries,
memory samples, per-process snapshots and resolved configurations are in
[results](benchmarks/realtime-data-indexing/results/README.md).
One final run per size is published; run-to-run variability was not measured.
Memory and disk sizes use GiB; input labels are nominal targets
(1 GB = 1,000 MiB of extracted text). A page is approximately 2,000 bytes.
Chunks are Qdrant's approximate count at completion; the per-size curves
retain the maximum observed count used by the completion detector.
Documents flow through the pipeline rather than accumulating in it.
The file-watch index retains metadata per watched file to detect edits and
deletions, so its cost depends on file count. The right panel estimates this
cost from the connector worker's extra private memory: the fitted slope is
**~361 bytes per file**. This proxy also includes unequal worker
buffers; it does not isolate individual allocations.
The embedding runtime, engine and working buffers account for the worker
baseline. The curves show how total memory evolves during indexing,
including any steps as file-watch metadata and buffers grow.
Parsed-text cache, persistence snapshots and stored embeddings live on disk.
Across these runs a **500× larger input target costs 2.1× the peak PSS**.
Both file count and text volume change between sizes; this comparison does
not establish constant memory usage.

All curves and table values come from the same runs with allocator background purging enabled. File-watch memory is estimated from rank-0 private-memory excess over the median of the other workers.

Attribution at the sampled 10 GB peak. Local-embedder memory is estimated from a separate eight-process initialization diagnostic and library mappings; libraries already needed without the embedder remain in the residual. The 3.27 GiB estimate without the local embedder is calculated by subtraction, not measured in an external-embedder indexing run. It excludes the embedding service and does not measure client overhead or changes in working buffers. Shared pages are accounted for proportionally through PSS.
Setup: 96-logical-CPU host (see the saved CPU model),
streaming mode, 8 worker processes with 12 OpenMP threads each,
local `static-retrieval-mrl-en-v1` embeddings, Matryoshka-truncated to 256 dims,
512-token chunks, Qdrant, and jemalloc `background_thread:true`.
No embedding API calls. Installed versions: serviette 0.1.7,
Pathway 0.33.0, PyTorch 2.14.1,
sentence-transformers 6.1.0.
Peak memory is the maximum sampled PSS summed over the indexer container.
Qdrant and API-server memory, unmapped filesystem cache and kernel memory
are outside that measurement; it is not a RAM requirement for the whole stack.
Brief peaks between samples may be missed.
Indexing time is an estimate ending at the last increase in the running
maximum of Qdrant's approximate chunk count. That moment can precede the
final write; output-completeness checks do not revise the timestamp or
measure when the backend's search index is ready. The recorded environment,
cache conditions and limits on reproducing it are described in
[the measurement notes](benchmarks/realtime-data-indexing/results/README.md).
### Retrieval accuracy (FRAMES)
End-to-end evaluation on [FRAMES](https://arxiv.org/abs/2409.12941)
(Google, 2024): 824 multi-hop questions whose answers must be assembled
from 2–15 English Wikipedia articles — see
[benchmarks/frames](https://github.com/pathwaycom/serviette/tree/main/benchmarks/frames), full technical report in
[REPORT.md](https://github.com/pathwaycom/serviette/blob/main/benchmarks/frames/REPORT.md):
| measurement | result |
|---|---|
| gold-article recall — the paper's metric, on the paper's corpus | **0.50** vs 0.15 published for the paper's BM25 baseline (0.21 for our reproduction of it) |
| paired gain from adding serviette to gpt-5, paper's protocol | **+5.2 pp** over the same model without retrieval (McNemar z = 4.1, 824 questions) |
| adaptive retrieval in the grounded (context-only) regime | **41.3% → 52.8%** (z = 7.5) — the largest single effect measured |
| absolute accuracy (permissive, gpt-5) | **73.7%** — above every number in the paper, including its 5-step agent (66.0%) and oracle (72.9%) |
The setup reproduces the paper wherever technically possible: the identical
Wikipedia dump (TFDS `wikipedia/20230601.en`, 5.22M articles → 12.07M
chunks) indexed in full by serviette with the free local `e5-small-v2`
embedder — so the recall row costs nothing in API fees — plus the paper's
own retrieval metric and its verbatim autorater prompt. Comparisons are
paired and internal (identical corpus, generator, judge; only the retrieval
layer varies — the opt-in strategies described under
[Retrieval quality](#retrieval-quality) below), because the absolute score
is dominated by the 2026
generator — its no-retrieval baseline alone reaches 68.5% — which is why
the headline is the paired delta, not 73.7%. The grounded rows measure
serviette as it ships for private corpora: answers strictly from retrieved
documents, a deliberately stricter regime than the paper's. Methodology,
statistics, limitations and raw per-question outputs:
[REPORT.md](https://github.com/pathwaycom/serviette/blob/main/benchmarks/frames/REPORT.md).
## Multimodality
Every file type is enabled by default. serviette routes each file to the best
parser that works **without an API key**, and turns on key-requiring
modalities automatically when their key is present:
| format | parsed by default with | notes |
|---|---|---|
| text / Markdown | as-is | |
| PDF | pypdf — **built in**; `serviette[docling]` upgrades to Docling (layout-aware, tables) | local, free |
| Office (DOCX, PPTX, XLSX, HTML, EML…) | Unstructured — **built in**; `serviette[docling]` widens coverage (EPUB, legacy formats) | local, free |
| scanned images (PNG, JPG, TIFF…) | PaddleOCR | local, free; install `serviette[ocr]` |
| audio (MP3, WAV…) | Whisper | when `OPENAI_API_KEY` is set |
| video (MP4, WebM, MOV…) | TwelveLabs Pegasus — a searchable text description of the video | when `TWELVELABS_API_KEY` is set |
A modality whose only parser needs an absent key is skipped with a clear
warning — never a crash. Everything stays live: drop a recording of
yesterday's meeting into the watched folder and ask about it minutes later;
expensive parses (video) are cached on disk, so restarts cost nothing.
The routing is configurable per file pattern (`parser:` section — pick a
vision model for images instead of OCR, set a custom video prompt); see
[docs](https://github.com/pathwaycom/serviette/blob/main/docs/README.md). Embeddings work the same for every modality: parsed
content is text, so any of the embedder families — including the local
credential-free default — covers a multimodal corpus.
## Retrieval quality
Retrieval and answering are pure-vector by default; five opt-in strategies
improve accuracy, each a few lines of config. They compose freely — decompose
widens *what* is retrieved, hybrid and reranking reorder *which* chunks win,
MMR *diversifies* them, and adaptive RAG *retries* with more context when the
answer is not found.
- **Hybrid (BM25 + vector).** Fuses vector similarity with an in-process BM25
keyword index (reciprocal-rank fusion). The two signals fail differently —
embeddings match paraphrases, BM25's IDF makes rare exact tokens (names,
dates, IDs) dominate — so their fusion beats either alone on entity-heavy
corpora. Enable with `hybrid: true` on the vector-db section.
- **Reranker.** A second stage rescoring a shortlist of candidates: a local,
keyless cross-encoder (`reranker: {type: cross_encoder}`) or pointwise LLM
scoring (`type: llm`). Best for precise, single-hop questions.
- **Adaptive RAG.** Answers from `k` chunks first, then grows the context and
re-asks while the LLM reports the answer is not present (`rag.adaptive`).
Your `llm.system_prompt` stays in force; the mode only appends the
"reply with this marker when the context is insufficient" instruction it
needs to decide when to fetch more.
- **Query decomposition.** One LLM call splits a multi-hop question into
sub-queries, retrieves for each, and fuses — so chunks of different hops
stop competing for the same top-k slots (`rag.decompose`).
- **MMR.** Diversifies the result set, trading relevance against redundancy
(`rag.mmr`).
- **Document questions.** "How many documents do you have?", "What does
`journal.pdf` say?", "What changed between `law_2023.txt` and
`law_2024.txt`?" are questions about documents, not about a passage, and
chunk retrieval cannot answer them. `rag.documents` (on by default) answers
them from the document catalog and from whole files: a question naming a
file goes straight to that file; any other question is searched as usual,
and only if that finds nothing does one short LLM call decide between a
wider search and the catalog or the named documents. Two files that share
most of their text are compared as a line-level diff computed by the
server, so the model reads only what changed — however the files were
chunked. Every step has a fixed context budget and the request as a whole
a ceiling (`max_request_chars`); when a file cannot be identified the
answer says which names were close.
Not available on Pinecone, which cannot enumerate documents.
The reranker and the multi-step strategies (adaptive, decompose) are
backend-independent — they work on every vector DB. Hybrid and MMR read from
the store, so support depends on the backend:
| Backend | Vector | Reranker · Adaptive · Decompose | MMR | Hybrid (BM25) |
|----------|:------:|:-------------------------------:|:---:|:-------------:|
| DuckDB | ✅ | ✅ | ✅ | ✅ in-process |
| Qdrant | ✅ | ✅ | ✅ | ✅ in-process |
| pgvector | ✅ | ✅ | ✅ | ✅ in-process |
| Milvus | ✅ | ✅ | ✅ | ✅ in-process |
| Weaviate | ✅ | ✅ | ✅ | ✅ in-process |
| ChromaDB | ✅ | ✅ | ✅ | ✅ in-process |
| MongoDB | ✅ | ✅ | ✅ | ✅ in-process |
| Pinecone | ✅ | ✅ | ✅ | ❌ — no scan-all API; native sparse-index hybrid is planned |
The in-process index follows the store: it is rebuilt as soon as the backend
reports a change (the row count; on DuckDB and pgvector also the newest
`seen_at`, which catches in-place edits) and refreshed in the background every
`hybrid_refresh_seconds` (default 30) as a bound on staleness for whatever
that cheap signal misses. In-process BM25 targets corpora up to a few million
chunks; above `hybrid_max_chunks` the keyword leg is skipped with a warning and
retrieval stays pure-vector. **Pinecone** cannot enumerate its vectors, so it has no
in-process hybrid — `hybrid: true` there fails fast at startup with that
explanation; native hybrid (a second sparse index) is planned. Native
server-side BM25 for the client-server backends (replacing the in-process
leg at larger scale) is planned as well.
## Observability
Three layers, all on by default or one config line away:
**In the chat UI.** The header shows *"indexed N s ago"* — the age of the
most recent write into the vector store. When you edit a source document,
you can watch the counter reset as the change lands.
**`GET /api/v1/stats`** on the API server: the backend in use, the number of
indexed chunks, and index freshness — a JSON one-liner for dashboards and
health checks, served without touching the indexer (it reads the vector
store, like every other query).
**Engine metrics (Prometheus).** The Pathway engine ships its own
observability server; serviette exposes it with one config line:
```yaml
indexer:
monitoring_http_port: 20000
```
Every worker process then serves `GET /metrics` on
`127.0.0.1:(20000 + worker index)` — input/output latency gauges (i.e. the
indexing lag behind the sources) and per-operator row counters, straight
from the engine's dataflow. Point a Prometheus scrape at the worker ports
and you get per-stage throughput and freshness graphs with no extra code.
Logs from both processes go to stdout/stderr in plain text; `serviette up`
interleaves them with per-process prefixes.
## Security
The server listens on **localhost only** by default and ships no built-in
authentication — exposing it is an explicit decision: set `server.host:
0.0.0.0` and put an authenticating reverse proxy in front (a five-line
Caddy example lives in [docs](https://github.com/pathwaycom/serviette/blob/main/docs/README.md#security--exposing-the-server)).
## Requirements
- Python ≥ 3.10 (the minimum supported by Pathway).
- A free Pathway license key in `PATHWAY_LICENSE_KEY` —
.
## Documentation
Full installation, the config wizard, configuration reference, persistence,
architecture and scaling notes live in **[docs/README.md](https://github.com/pathwaycom/serviette/blob/main/docs/README.md)**.
## Development
To report a problem or propose a change, see [CONTRIBUTING.md](CONTRIBUTING.md)
for the contribution policy and PR requirements.
serviette runs on the released Pathway from PyPI (≥ 0.32.1 — the first
release with the vector-database connectors). From-scratch setup on a
fresh machine:
```bash
# 0. Prerequisites: Python >= 3.10 (3.12 recommended) and git.
# 1. serviette in its own virtualenv
git clone https://github.com/pathwaycom/serviette.git && cd serviette
python3.12 -m venv .venv
source .venv/bin/activate
pip install -e ".[dev,local]"
# 2. A (free) Pathway license: https://pathway.com/framework/get-license
export PATHWAY_LICENSE_KEY=...
# 3. Sanity check: zero-to-chat on the bundled corpus
serviette demo # -> http://localhost:8989
```
Notes:
- `serviette demo` materializes everything in a visible working directory:
`./serviette-demo/docs` holds the corpus — a **toy example**, a handful of
documents about a fictional company (Lumina Coffee Systems). Drop your own
files there (PDF, DOCX, scans, …) while it runs and they are answerable
within seconds.
- The demo indexes with one of two embedders — pick your trade-off:
- **default, free & local** — needs `serviette[local]`, which pulls the
PyTorch stack. Install it with
`--extra-index-url https://download.pytorch.org/whl/cpu` to get the CPU
build (~0.8 GB); without the flag pip takes PyTorch's default Linux
wheel, which ships CUDA libraries whether or not you have an NVIDIA GPU
(**~5 GB**, and the install is the slow part of the first run). Free at
any corpus size afterwards.
- **`--embedder openai`** — nothing to install, starts immediately, but
every indexed token is billed to your `OPENAI_API_KEY`. Fine for the toy
corpus and small folders; for a large collection, sit out the
`serviette[local]` install and use the free embedder instead.
- Independently of the embedder, export `OPENAI_API_KEY` if you want real
generated answers in `/rag` — without it the demo answers by quoting the
retrieved snippets.
Running the test suites:
```bash
pytest -m "not slow" # fast unit tests (no Pathway, no services)
pytest -m "slow and not integration" # end-to-end indexer tests (spin up Pathway)
pytest -m integration # real-database tests (see below)
pytest # everything
```
Per-backend clients install as extras — pick what you use:
```bash
pip install "serviette[qdrant]" # also: pgvector, milvus, chroma, weaviate,
# pinecone, mongodb, local, gemini, all
```
### Integration tests (real databases)
**Every claimed backend has an integration test** running the same scenario
end-to-end against a real instance: index two documents with the real indexer,
retrieve through the production accessor (exact-text query must rank first
with cosine ~1.0), delete a file, re-index, and verify its vectors are gone
(snapshot semantics). The shared driver lives in `tests/integration_common.py`.
| Backend | Test | Real instance |
|---|---|---|
| DuckDB | `test_integration_duckdb.py` | embedded — runs everywhere |
| pgvector | `test_integration_pgvector.py` | `pgvector/pgvector` Docker container |
| Milvus | `test_integration_milvus.py` | embedded Milvus Lite engine; set `SERVIETTE_TEST_MILVUS_URI=http://host:19530` to run the same tests against a Milvus server (Lite has no growing/sealed segments, so it cannot catch stats-counting bugs) |
| Qdrant | `test_integration_qdrant.py` | `qdrant/qdrant` Docker container |
| ChromaDB | `test_integration_chroma.py` | `chromadb/chroma` Docker container |
| Weaviate | `test_integration_weaviate.py` | `semitechnologies/weaviate` Docker container |
| Pinecone | `test_integration_pinecone.py` | official `pinecone-local` emulator (Docker) |
| MongoDB | `test_integration_mongodb.py` | `mongodb-atlas-local` (mongod + mongot, real `$vectorSearch`) |
Containers are throwaway (`tests/dockerutil.py`, Docker CLI via subprocess, no
extra dependency) and host ports are **allocated dynamically** — tests never
assume a fixed localhost port is free or that a service is already running.
Each test skips automatically when Docker or its client library is missing.
## License
See [LICENSE](https://github.com/pathwaycom/serviette/blob/main/LICENSE).
---
### Overview (`docs/README.md`)
# serviette
**A universal, no-code, always up-to-date RAG server for any vector database
— powered by the [Pathway](https://pathway.com) Live Data Framework.**
serviette stands up Retrieval-Augmented Generation over your own documents —
text, Office files, PDFs, scans, and (with API keys) audio and video —
without writing code. Point it at a folder, choose a vector database and an
embedder in a YAML file (or generate one with the wizard), and run one
command (`serviette up`) or the two components separately:
- **`serviette indexer`** — a Pathway streaming pipeline that watches your files,
parses and chunks them, embeds the chunks and keeps your vector DB in sync
(additions, modifications and deletions) in real time.
- **`serviette server`** — a FastAPI service that embeds incoming queries and
retrieves the most relevant chunks (and, optionally, answers them with an
LLM). It also serves the web chat UI on `/` (same port, same origin) unless
`server.serve_frontend` is disabled; the REST API lives under `/api/v1`.
The indexer and the server are fully decoupled: they share only the vector
database, so you can scale them independently.
---
## 1. Installation
serviette requires **Python ≥ 3.10** (the minimum supported by Pathway).
```bash
pip install "serviette[local]" --extra-index-url https://download.pytorch.org/whl/cpu
```
The `local` extra brings sentence-transformers — the free, credential-free
embedder that `serviette wizard` selects by default. It pulls the PyTorch
stack, and the `--extra-index-url` flag makes pip take PyTorch's CPU build
(~0.8 GB). Without it, PyTorch's default Linux wheel is installed, which
carries the CUDA libraries (~5 GB) whether or not the machine has an NVIDIA
GPU — leave the flag out only if you want to embed on such a GPU. (With
`uv`, add `--index-strategy unsafe-best-match` as well.) If you intend to
embed with OpenAI instead, a plain `pip install serviette` is enough (pick
`openai` in the wizard).
From a checkout, `pip install -e ".[dev,local]"` — see the README's
[Development](../README.md#development) section for the full walkthrough.
OpenAI support (the default `/rag` LLM and the OpenAI embedder) is built
in — just set `OPENAI_API_KEY`.
Optional extras: `docling` (layout-aware PDF + Office parsing), `ocr` (scanned images),
`pyfilesystem` (FTP/SFTP/WebDAV/ZIP sources), `gdrive`, `sharepoint`, plus
one extra per vector-DB client (`qdrant`, `pgvector`, …, or `all`).
---
## 2. Config wizard
The fastest way to a chat is `serviette demo` (see the README); the fastest
way to a config for *your* documents is the interactive wizard:
```bash
serviette wizard
```
It asks only what it must (the DuckDB + local-embeddings happy path is seven
questions) and writes a YAML file; everything else — port, persistence,
chunking, parser routing — gets silent, documented defaults you can edit
later. You only *have* to provide document paths, vector-DB connection
details (for client-server backends), API keys for keyed providers, and your
Pathway license key.
Then run the two components (in separate terminals or on separate machines):
```bash
# One command: indexer + server supervised together (dev/demo convenience)
serviette up --config config.yaml # open http://localhost:8989
# ... or run the components separately (how production deploys them):
# 1. Index your documents into the vector DB and keep it live
serviette indexer --config config.yaml
# 2. Serve the chat UI + retrieval / RAG API on one port
serviette server --config config.yaml # open http://localhost:8989
# (optional, split deployments only) standalone UI tier on another host
serviette frontend --config config.yaml # open http://localhost:3000
```
`indexer`, `server` and `up` check the obvious mistakes before starting
anything: a source folder that does not exist, a `${VAR}` in the config that
is not exported, an `openai`-typed embedder or `llm` with no key in the config
or in `OPENAI_API_KEY`, a backend that cannot be shared by two processes. Each
stops with a one-paragraph message, not a traceback. If the indexer or the
server dies later, `serviette up` ends with a framed `serviette up STOPPED`
block that names the cause when it recognises it (missing or rejected API
key, OpenAI rate limit or quota, a port already in use, an unreachable
database) and what to do.
By default `serviette up` shows only its own progress, warnings, errors and
the URL to open; the indexer's and the server's routine INFO lines (the
engine's persistence and connector monitoring, one line per HTTP request)
are hidden. `serviette up --verbose` passes them all through. The hidden
lines are still kept for the `STOPPED` report, so a diagnosis never depends
on the flag.
Query the API (versioned under `/api/v1`; the pre-versioning `/retrieve`,
`/rag` and `/health` paths still work as deprecated aliases):
```bash
curl -X POST http://localhost:8989/api/v1/retrieve \
-H 'Content-Type: application/json' \
-d '{"query": "how does persistence work?", "k": 5}'
```
```jsonc
{
"results": [
{"text": "...", "metadata": {"path": "/data/docs/guide.pdf", ...}, "score": 0.95}
]
}
```
If you configured an `llm` section, the `/rag` endpoint also answers questions:
```bash
curl -X POST http://localhost:8989/api/v1/rag \
-H 'Content-Type: application/json' \
-d '{"query": "summarize the onboarding guide", "k": 5}'
```
```jsonc
{ "answer": "...", "sources": [ {"text": "...", "metadata": {...}, "score": 0.91} ] }
```
`GET /api/v1/documents` lists the indexed documents whose name or path
contains `q` (`case_sensitive=true` to match case; the default ignores it).
The chat page's **Documents** panel is built on it and asks only when a
search is submitted, never on load — an index may hold tens of thousands of
files. Over `limit` matches (default 100, at most 1000) only the counts are
returned and the page asks to narrow the search:
```bash
curl 'http://localhost:8989/api/v1/documents?q=report&case_sensitive=false'
```
```jsonc
{ "total": 1240, "matched": 2, "truncated": false,
"documents": [ {"id": "/data/docs/report_2026.pdf", "name": "report_2026.pdf",
"metadata": {"path": "...", "modified_at": 1790000000, "size": 12345}, "chunks": 41}, ... ] }
```
`name` is what a person calls the document — the file name for folder, S3
and SharePoint sources, the Drive title for Google Drive — and `id` is the
full identity the source reports (path or Drive id). Pinecone cannot
enumerate documents; there the endpoint answers 501.
---
## 3. Pathway License Key
Pathway requires a **free** license key. Get yours in one click at
**** (email or LinkedIn sign-in).
Provide it either via the config file:
```yaml
pathway_license_key: ${PATHWAY_LICENSE_KEY}
```
or directly as a string. Using the `${PATHWAY_LICENSE_KEY}` form keeps the key
out of the file — set it in the environment:
```bash
export PATHWAY_LICENSE_KEY="your-key-here"
```
`serviette wizard` notices an exported `PATHWAY_LICENSE_KEY` and offers to
write the `${PATHWAY_LICENSE_KEY}` reference instead of asking for the key;
`serviette demo` uses the variable the same way.
The key is applied when the indexing graph is initialized.
---
## 4. Config reference
A single YAML file can configure both the indexer and the server (a *universal*
config), or you can split it into an indexer-only and a server-only file. Any
string value supports `${ENV_VAR}` interpolation, so credentials never need to be
hardcoded. A reference to a variable that is not set is a startup error naming
the variable and the config key using it (it does not silently become an empty
string, which would only surface later as a provider 401).
| Field | Type | Default | Used by | Description |
|---|---|---|---|---|
| `pathway_license_key` | str | — | indexer | Free Pathway license key (or `${ENV}`). |
| `sources` | list | — (required) | indexer | One or more sources to index (mixed types allowed). |
| `sources[].type` | `fs`\|`gdrive`\|`s3`\|`sharepoint`\|`pyfilesystem` | `fs` | indexer | Source type — see [Sources](#sources) below. |
| `sources[].mode` | `streaming`\|`static` | `streaming` | indexer | `streaming` watches continuously; `static` indexes once and exits. |
| `sources[].max_backlog_size` | int\|null | `1000` | indexer | **Advanced.** Backpressure bound on in-flight entries per connector (fs/gdrive/s3). Keeps memory flat during bulk backfills; the default suits virtually everyone — not offered by the wizard, edit the YAML to change. `null` disables. |
| **fs** `sources[].path` | str | — (required) | indexer | Directory to watch (`~` is expanded). Must exist when the indexer starts — a missing folder is an error, not an empty index. |
| **fs** `sources[].glob` | str | `**/*` | indexer | Glob of files to include. |
| **gdrive** `sources[].object_id` | str | — (required) | indexer | Drive folder or file id (folders scanned recursively). |
| **gdrive** `sources[].service_user_credentials_file` | str | — (required) | indexer | Path to a Google service-account JSON credentials file. |
| **gdrive** `sources[].file_name_pattern` | str\|list | — | indexer | Optional file-name glob(s), e.g. `*.pdf`. |
| **gdrive** `sources[].object_size_limit` | int | — | indexer | Optional max object size in bytes. |
| **s3** `sources[].bucket` | str | — (required) | indexer | S3 bucket name. |
| **s3** `sources[].path` | str | `""` | indexer | Key prefix to index (`""` = whole bucket). |
| **s3** `sources[].access_key` / `.secret_access_key` | str | AWS chain | indexer | Credentials (or `${ENV}`). |
| **s3** `sources[].region` / `.endpoint` | str | — | indexer | Region; custom endpoint for MinIO etc. |
| **s3** `sources[].with_path_style` | bool | `false` | indexer | Path-style addressing (MinIO and most self-hosted). |
| **sharepoint** `sources[].url` | str | — (required) | indexer | Site URL, e.g. `https://co.sharepoint.com/sites/X`. |
| **sharepoint** `sources[].tenant` / `.client_id` | str | — (required) | indexer | App registration (certificate auth). |
| **sharepoint** `sources[].cert_path` / `.thumbprint` | str | — (required) | indexer | Certificate .pem and its thumbprint. |
| **sharepoint** `sources[].root_path` | str | — (required) | indexer | Directory/file to index. |
| **sharepoint** `sources[].recursive` | bool | `true` | indexer | Scan nested directories. |
| **sharepoint** `sources[].refresh_interval` | int | `30` | indexer | Polling period, seconds. |
| **pyfilesystem** `sources[].fs_url` | str | — (required) | indexer | Any PyFilesystem URL: `ftp://…`, `ssh://…`, `webdav://…`, `zip://…`, `osfs://…` (extra: `serviette[pyfilesystem]`; some protocols need a driver package). |
| **pyfilesystem** `sources[].path` | str | `""` | indexer | Path inside the opened filesystem (recursive). |
| **pyfilesystem** `sources[].refresh_interval` | float | `30.0` | indexer | Seconds between scans (streaming mode). |
| `parser` | list of rules | keyless-first defaults | indexer | Routing rules `{match: ["*.pdf"], type: docling, options: {...}}` — globs are tried against the file name and its path as the source reports it (`*` matches `/`, so `*/scans/*.png` selects a folder), first match wins; unmatched files use built-in defaults (text→utf8, pdf→docling/pypdf, office→unstructured, images→paddle_ocr, audio→whisper if `OPENAI_API_KEY`, video→twelvelabs_video if `TWELVELABS_API_KEY`, else skip+warn). Types: `utf8`, `pypdf`, `docling`, `unstructured`, `paddle_ocr`, `vision_image`, `vision_slide`, `whisper`, `twelvelabs_video`, `skip`. Changing routing is fingerprint-guarded. |
| `vector_db.type` | `duckdb`\|`pgvector`\|`milvus`\|`qdrant`\|`chroma`\|`weaviate`\|`pinecone`\|`mongodb` | — (required) | both | Vector database backend (see [Backends](#vector-database-backends)). |
| **duckdb** `vector_db.path` | str | — (required) | both | Path to the DuckDB database file. |
| **duckdb** `vector_db.table` | str | `serviette_embeddings` | both | Target table. |
| **pgvector** `vector_db.connection_string` | str | — (required) | both | `postgresql://user:pass@host/db`. |
| **pgvector** `vector_db.table` | str | `serviette_embeddings` | both | Target table. |
| **milvus** `vector_db.uri` | str | — | both | Milvus URI, e.g. `http://localhost:19530`. |
| **milvus** `vector_db.host` / `.port` | str / int | `localhost` / `19530` | both | Used if `uri` is omitted. |
| **milvus** `vector_db.collection` | str | `serviette_embeddings` | both | Milvus collection. |
| **qdrant** `vector_db.host` | str | `localhost` | both | Qdrant host. |
| **qdrant** `vector_db.rest_port` / `.grpc_port` | int | `6333` / `6334` | server / indexer | REST (server) and gRPC (indexer) ports. |
| **qdrant** `vector_db.api_key` | str | — | both | Qdrant Cloud API key. |
| **qdrant** `vector_db.collection` | str | `serviette_embeddings` | both | Auto-created (cosine) if missing. |
| **chroma** `vector_db.host` / `.port` | str / int | `localhost` / `8000` | both | Chroma server address. |
| **chroma** `vector_db.tenant` / `.database` | str | Chroma defaults | both | Multi-tenant selectors. |
| **chroma** `vector_db.collection` | str | `serviette_embeddings` | both | Auto-created (cosine `hnsw:space`). |
| **weaviate** `vector_db.http_host` / `.http_port` | str / int | `localhost` / `8080` | both | HTTP endpoint. |
| **weaviate** `vector_db.grpc_host` / `.grpc_port` | str / int | http_host / `50051` | server | gRPC endpoint (v4 client). |
| **weaviate** `vector_db.api_key` | str | — | both | API key. |
| **weaviate** `vector_db.collection` | str | `ServietteEmbeddings` | both | Auto-created (capitalized name). |
| **pinecone** `vector_db.index_name` | str | — (required) | both | Auto-created (serverless, embedder's dimension, cosine). |
| **pinecone** `vector_db.api_key` | str | `${PINECONE_API_KEY}` | both | Pinecone API key. |
| **pinecone** `vector_db.namespace` | str | `""` | both | Optional namespace. |
| **mongodb** `vector_db.connection_string` | str | — (required) | both | `mongodb+srv://...` for Atlas. |
| **mongodb** `vector_db.database` / `.collection` | str | — / `serviette_embeddings` | both | Target collection (auto-created). |
| **mongodb** `vector_db.vector_index` | str | `vector_index` | server | Atlas `vectorSearch` index name. |
| `embedder.type` | str | `openai` | both | Embedder family (see below). |
| `embedder.model` | str | provider default | both | Model name. |
| `embedder.api_key` | str | — | both | API key (or `${ENV}`). |
| `splitter.type` | `token_count`\|`recursive`\|`null` | `token_count` | indexer | Chunking strategy. `null` disables splitting — the whole document is one chunk (short, self-contained documents such as FAQ entries or product cards); written as `type: null` or `type: "null"`, both work. |
| `splitter.chunk_size` | int | `512` | indexer | Max chunk size (tokens). |
| `splitter.chunk_overlap` | int | `50` | indexer | Overlap (used by `recursive`). |
| `indexer.fetch_retries` | int | `3` | indexer | Retries (exponential backoff from 1s) of a document's byte fetch before it is given up on: indexed as empty and ERROR-logged. Remote sources fail transiently under bulk backfills. |
| `indexer.workers` | int | `1` | indexer | Worker **processes** (sharded via `pathway spawn`). Raise for large backfills — each worker carries its own local embedding stack; memory depends on the model, and library pages may be shared. The benchmarks run with `8`. |
| `workdir_path` | str | `./serviette-workdir` | indexer | serviette's working directory — everything it keeps between runs: the configuration fingerprint at its top level, the Pathway persistence state (and the parse cache, `runtime_calls/`) under `persistence/`. Relative to the process's working directory. Silent default — the wizard does not ask. |
| `persistence.enabled` | bool | `true` | indexer | See [Persistence](#5-persistence). |
| `persistence.backend` | `filesystem` | `filesystem` | indexer | Persistence backend. |
| `server.host` / `server.port` | str / int | `127.0.0.1` / `8989` | server | Bind address. Loopback by default; set `0.0.0.0` explicitly to listen on all interfaces (containers, remote access) — see [Security](#security--exposing-the-server). |
| `server.serve_frontend` | bool | `true` | server | Serve the chat UI on `/` from the same port (API stays under `/api/v1`). |
| `server.cors_origins` | list[str] | `[]` (disabled) | server | Opt-in CORS allowlist for third-party browser frontends calling the API directly from another origin. serviette's own UIs never need it. Prefer exact origins over `*`. |
| `up.index_wait_timeout` | float\|null | `120` | up | Seconds of indexer *inactivity* after which `serviette up` stops holding the server back waiting for the first indexed chunks. Counted from the indexer's last sign of work in its log (a document being parsed, input reaching the engine, embedding progress), so a few large PDFs that take minutes to parse do not trip it. A folder whose documents all yield no text (scans without the `ocr` extra, audio without its API key, parser failures) never produces a chunk and goes quiet right after parsing, so after this long the server starts over the empty index with a warning; `null` waits forever. |
| `llm.type` | str | `openai` | server | LLM for `/rag` (omit to disable `/rag`). |
| `llm.model` | str | `gpt-4o-mini` | server | Chat model. |
| `llm.api_key` | str | — | server | API key (or `${ENV}`). |
| `llm.system_prompt` | str | built-in grounded prompt | server | Answering policy for `/rag`. The default tells the model to answer only from the provided context; override to let it blend in its own knowledge (e.g. public-domain corpora). Kept under `rag.adaptive`, which appends its no-answer instruction to it. |
| `rag.adaptive` | `{factor, max_iterations, no_answer_string}` | — (off) | server | Adaptive RAG: answer from `k` chunks, then grow the context by `factor` and re-ask (up to `max_iterations` rounds) while the reply contains `no_answer_string` (default `No information found`). The system prompt is the `llm.system_prompt` policy plus an appended instruction to reply with that marker when the context is insufficient; a policy that allows answers from the model's own knowledge rarely triggers the marker, so the context then rarely grows. |
| `rag.documents` | `{enabled, corpus_card, source_labels, max_context_chars, max_request_chars, max_listed_documents}` | on | server | Document-level questions on `/rag` (counts and listings, a named file as a whole, comparing files). A question that names a file with its extension is answered from that file without a search. Otherwise the ordinary attempt runs first; when its reply contains the no-answer marker, one short routing call (the question and up to `max_listed_documents` file names, never the retrieved context) chooses between continuing the search (`rag.adaptive`, if configured) and answering from the catalog or from the named documents — at most once per request, and one-way. `max_context_chars` (default `24000`) caps what any such answer reads: a document that does not fit is cut to its parts closest to the question, and a comparison shows only the differences — found line by line (ignoring spacing, hyphenation, punctuation and running page headers), so it does not depend on how the files were chunked; when there are more than fit, the ones closest to the question are shown and `notice` says how many of how many. `max_request_chars` (default `100000`) caps everything one request sends to the LLM across all its calls, the adaptive loop included: a call that no longer fits is cut down or not made, and `notice` says so. While enabled, the system prompt carries the no-answer instruction and, with `corpus_card`, one line stating the number of indexed documents; with `source_labels`, every context chunk is prefixed with its file name (`[file: pricing.md]`), which lets the model tell apart documents that disagree. Set `enabled: false` to keep the prompt and context untouched. The response gains `mode` (`search`, `catalog`, `document`, `compare`, `unresolved`), `documents` and `notice`. Counts cover indexed documents only — files that produced no text are not in the store. Ignored on Pinecone. |
| `frontend.host` / `frontend.port` | str / int | `127.0.0.1` / `3000` | frontend (standalone) | Bind address for the split-deployment chat UI. |
| `frontend.api_url` | str | `http://localhost:8989` | frontend (standalone) | Base URL of the API the standalone frontend proxies to — point it at the backend host in split deployments (frontend fleet / backend fleet). The browser sends requests to the frontend's same-origin proxy; the upstream address is shown in the UI for information. |
| `frontend.title` | str | `serviette` | both | Title shown in the chat UI (embedded and standalone). |
**Supported embedders** (from `pathway.xpacks.llm.embedders`): `openai`,
`litellm` (≈100 providers), `sentence_transformer` (fully local, no
credentials — install `serviette[local]`), `gemini` (`serviette[gemini]`),
`bedrock` (`serviette[bedrock]` for the server side). Every family has a
matching async client on the server side, so one `embedder` section serves both
components; make sure the indexer and server use the **same** model so vectors
are comparable.
**Which local model.** The `sentence_transformer` default,
`sentence-transformers/all-MiniLM-L6-v2`, is an **English-only** model: with
French, German or Polish documents retrieval degrades to "the context does not
contain the information" even though the files were indexed. For non-English
or mixed corpora set `model: intfloat/multilingual-e5-small` (~100 languages,
same size and speed) together with the prefixes it was trained with,
`query_prefix: "query: "` and `document_prefix: "passage: "`; for the highest
quality and long chunks, `BAAI/bge-m3` (1024-dim, ~2.3 GB, several times slower
on CPU). `serviette wizard` asks this as its "Embedding model" step and writes
the prefixes for you. Changing the model means re-indexing (the fingerprint
check will say so).
### Sources
serviette only supports sources that offer Pathway's **`only_metadata`** read mode —
the graph holds just paths/identifiers and metadata (never the file bytes), and
the bytes are fetched on demand during parsing. That keeps the memory footprint
tiny (1 GB of PDFs stays a few KB in the pipeline). Today that means:
- **`fs`** — a local directory, watched recursively per `glob`.
- **`gdrive`** — a Google Drive folder or file. Create a Google **service
account**, download its JSON key, share the target folder with the service
account's email, and point `service_user_credentials_file` at the key. See the
[Pathway Google Drive connector guide](https://pathway.com/developers/user-guide/connect/connectors/gdrive-connector/).
Install the extra: `pip install "serviette[gdrive]"`.
- **`s3`** — an S3 bucket or key prefix, including S3-compatible stores
(MinIO, DigitalOcean, Wasabi) via `endpoint` + `with_path_style: true`.
Credentials fall back to the standard AWS chain when omitted. Install the
extra: `pip install "serviette[s3]"`.
- **`sharepoint`** — a SharePoint directory or file, authenticated with an
app-registration certificate (`tenant`, `client_id`, `cert_path`,
`thumbprint`). Requires a Pathway **Scale** license and
`pip install "serviette[sharepoint]"`.
- **`pyfilesystem`** — anything the
[PyFilesystem2](https://docs.pyfilesystem.org) library opens: FTP, SFTP,
WebDAV, even ZIP/TAR archives — selected by `fs_url` (e.g.
`ftp://user:pass@host/dir`, `zip://./docs.zip`). Install
`pip install "serviette[pyfilesystem]"`; some protocols need their own driver
package (`fs.sshfs`, `fs.webdavfs`).
You can list several sources of mixed types in one config.
### Vector database backends
Every backend is written through Pathway's **native `pw.io.*` output
connector** in snapshot/upsert mode keyed by the chunk id, so file additions,
edits and deletions become real inserts/updates/deletes in the store. The
server retrieves through each database's own vector-search API — there are no
linear scans in Python anywhere.
**Targets are created for you.** At startup the indexer runs
`prepare_backend`: it creates the missing table / collection / index for
every backend (pgvector table + HNSW index, Milvus collection, Chroma and
Weaviate collections, the Pinecone serverless index, the MongoDB Atlas
`vectorSearch` index), sizing the vector dimension from
`vector_db.embedding_dimension` when set, or by introspecting the configured
embedder otherwise. The schemas below are shown for reference — e.g. when a
DBA manages the database — not as required manual steps.
#### DuckDB (embedded — the zero-setup default)
```yaml
vector_db:
type: duckdb
path: ./embeddings.duckdb
table: serviette_embeddings
```
No external service and no setup: the file and table are created automatically
(`pw.io.duckdb`, snapshot mode). Embeddings are stored as native `DOUBLE[]`
columns and queried **inside DuckDB** with `list_cosine_similarity` — a
vectorized, columnar scan that answers in milliseconds for local corpora.
Concurrency: DuckDB allows one read-write process *or* several read-only
processes per file — never both. serviette resolves this with Pathway's
`detach_between_batches`: the streaming indexer releases the file lock
between minibatches, and the server's short-lived read-only connections query
it concurrently — live indexing and serving work on one file. A request that
arrives while a batch is being committed waits for the lock (up to 30 s; the
first commit of a large corpus can hold it for ~10 s), and only past that
answers `503` with "the index is being updated — try again in a few seconds"
(the chat shows the same text). On older Pathway builds without the flag, serviette
warns and falls back to the hold-the-lock behavior (use `mode: static`
there).
#### pgvector
Auto-created (extension, table, HNSW index). Reference schema, e.g. for
`text-embedding-3-small` (1536 dims):
```sql
CREATE EXTENSION IF NOT EXISTS vector;
CREATE TABLE serviette_embeddings (
chunk_id text PRIMARY KEY,
text text,
metadata jsonb,
embedding vector(1536)
);
```
(The indexer writes the chunk primary key to the `chunk_id` column.)
#### Milvus
Auto-created: a collection with a VARCHAR primary key, `text` (VARCHAR),
`metadata` (JSON) and an `embedding` (FLOAT_VECTOR) field of the embedder's
dimension, AUTOINDEX with the `COSINE` metric.
**Milvus Lite** (`uri: ./milvus.db`, a local file) is an embedded,
single-process database: the process that opens the file locks it. It works
for the one-process-at-a-time flow — `serviette indexer` with `mode: static`
sources, then `serviette server` — but not with `serviette up`, which runs
the indexer and the server as two processes against one store; `up` refuses
such a config up front. For `up`, a live chat over a changing folder, or
scaling the server, use a Milvus server (`uri: http://host:19530`, e.g. the
`milvus run standalone` docker image).
#### Qdrant
Nothing to create: the indexer (`pw.io.qdrant`, gRPC) auto-creates the
collection with the cosine metric on first write. The chunk's `text` and
`metadata` travel in the point payload; the server queries over REST.
Set `api_key` for Qdrant Cloud.
#### ChromaDB
Auto-created with the cosine distance (`hnsw:space`). The chunk text is
stored as the Chroma document and the source metadata as a JSON string
(Chroma metadata values must be scalars).
#### Weaviate
Auto-created (capitalized name, e.g. `ServietteEmbeddings`; vectorizer `none`).
The chunk vector is stored as the object vector; `text` / `metadata` (JSON
string) / `chunk_id` become properties. The server's v4 client needs both the
HTTP and gRPC ports.
#### Pinecone
Auto-created: a serverless index (`vector_db.cloud` / `.region`) with the
embedder's dimension and the cosine metric. The `text` and JSON-string
`metadata` are stored as record metadata. The API key comes from `api_key`
or `$PINECONE_API_KEY`.
#### MongoDB Atlas Vector Search
The indexer writes one document per chunk (`pw.io.mongodb`, snapshot mode).
The collection and the Atlas `vectorSearch` index (default name
`vector_index`, cosine, `numDimensions` from the embedder) are auto-created;
on Atlas Local the indexer rides out the search service's slow boot with
retries. The server retrieves with `$vectorSearch`.
---
## 5. Persistence
When `persistence.enabled: true`, the indexer uses Pathway's built-in
persistence backend plus a `DefaultCache` UDF call-cache on the embedder. On
restart, Pathway replays its persisted state and re-emits only the *diffs* since
the last run, so:
- **unchanged documents are not re-embedded** (the embedder cache and operator
state are restored), and
- **documents removed while the indexer was down are correctly retracted** from
the vector DB on the next run.
The engine's state lives under `/persistence/` (the top level of
the working directory is reserved for serviette's own files, such as the
configuration fingerprint — the engine logs an ERROR for every foreign entry
in the directory it is given, so the two never share a folder); the same
`persistence/` also hosts the **parse cache** (`runtime_calls/`, via
`pw.udfs.DefaultCache` — diskcache, LRU-bounded by
`indexer.parse_cache_size_gb`, default 8): extracted document text stays warm
across restarts, so unchanged documents are neither re-downloaded nor
re-parsed. Disabling persistence also disables the parse cache.
The **configuration fingerprint** (`/serviette-fingerprint.json`)
records the chunking-relevant settings the working directory was indexed with
(splitter, parser routing, embedder identity, library versions, chunk-id
scheme). A change is reported as a diff on startup and the indexer refuses to
run unless confirmed (interactively, or with
`SERVIETTE_ACCEPT_FINGERPRINT_CHANGES=1`), because rows already in the vector
DB keep their old chunk ids and would be left behind as orphans. The check
runs with persistence on or off: a restart without persistence re-indexes
everything, but does not remove those rows either.
A document whose bytes cannot be fetched (after `indexer.fetch_retries`
retries) or parsed does not stop the indexer: it is indexed as **empty** and
logged at ERROR level with its path. That result sticks for this version of
the object — a restart alone does not retry it — so fix the cause and then
touch the file (or re-upload the object) to have the source re-emit it.
Disabling persistence still produces identical vectors for a given set of files;
it only forgoes the cross-restart diffing and caching.
---
## 6. Parsing & modalities
serviette never implements its own parsers — each file is routed by extension to
a `pathway.xpacks.llm.parsers` parser. Every format is enabled by default,
preferring parsers that need **no API key**, and modalities whose only parser
requires an absent key are skipped with a single clear warning (never a
crash):
- text / Markdown → as-is;
- `.pdf` → `DoclingParser` (layout-aware, tables — `serviette[docling]`), falling
back to `PypdfParser`;
- Office & co. (DOCX, PPTX, XLSX, HTML, EML, CSV, RTF, EPUB, …) →
`UnstructuredParser`;
- scanned images (PNG, JPG, TIFF, …) → `PaddleOCRParser` (`serviette[ocr]`);
- audio (MP3, WAV, …) → Whisper, enabled when `OPENAI_API_KEY` is set;
- video (MP4, WebM, MOV, …) → TwelveLabs Pegasus (a searchable text
description), enabled when `TWELVELABS_API_KEY` is set.
The routing is overridable per file pattern via the `parser:` config section
(first matching rule wins; unmatched files use the defaults above) — e.g.
route images to a vision model instead of OCR, or set a custom video prompt.
Routing changes are fingerprint-guarded like splitter changes. Expensive
parses (video) are cached on disk, so restarts cost nothing.
Still not supported: encrypted / password-protected PDFs; Google-native files
(Docs/Sheets/Slides) from a `gdrive` source — they have no binary download
and would need an export step (TODO); any format the installed `unstructured`
version cannot handle. Unsupported files are skipped and produce no chunks.
---
## 7. Architecture

Inside the indexer, documents move through a Pathway dataflow — every stage
below is an incremental operator, so a change to one file re-runs only that
file's slice of the graph:

**Why `only_metadata`?** The filesystem connector only ever puts *paths and
metadata* into the graph, never file contents — so 1 GB of PDFs costs a few KB in
the pipeline. Text is extracted on demand inside the parse UDF.
**Deletion handling.** The parse UDF is non-deterministic, so Pathway memoizes
its output and, when a file is removed, re-emits that stored text *negated*
without re-reading the (now gone) file; the retraction flows through chunking and
embedding and the sink deletes exactly the matching vectors.
---
## 8. Scaling
The indexer and the server are **separate processes that share only the vector
database**:
- **Server.** Stateless and read-only against the vector DB — run as many
instances as you like behind a load balancer, across machines or availability
zones. Because it is fully async (coroutines, not a thread pool), each instance
handles many concurrent network-bound retrieval calls efficiently. Each
instance also serves the chat UI (static, zero overhead), so the UI scales
with the API for free.
- **Frontend (optional split tier).** When the UI must live on a different
host than the API, `serviette frontend` is a separate, stateless web tier that
serves the same chat page and proxies to the API at `frontend.api_url`
server-side (the browser connects to the frontend, which calls the API).
- **Indexer.** Runs as its own long-lived process and shards across worker
processes with one config line (`indexer.workers`, via `pathway spawn`) —
the published benchmarks run with 8; its persistence lets it resume
without re-embedding.
- **Vector database.** Scaling and replicating the vector DB itself is the
user's responsibility and follows that database's own guidance. (The embedded
DuckDB backend is the exception: it lives in one file next to the indexer and
is meant for local / single-node setups.)
Engine observability: with `indexer.monitoring_http_port` set, every worker
process serves the Pathway engine's built-in endpoints on
`127.0.0.1:(port + worker index)` — `GET /metrics` (Prometheus: input/output
latency gauges, per-operator row counters) and `GET /status`.
---
## Security & exposing the server
The API server binds to **127.0.0.1 by default**: on a laptop, `serviette up`
serves only you. It deliberately ships **no built-in authentication** —
that is a perimeter concern, and a reverse proxy does it better than any
hand-rolled API key (TLS, key rotation, SSO, rate limits, audit logs come
for free). This is the norm for tools of this class: Qdrant self-hosted
ships with auth off, Ollama has none at all — and internet scans keep
finding thousands of Ollama instances exposed by a careless `0.0.0.0`.
Don't join them.
To serve beyond localhost:
1. Set the bind address explicitly — it is an intentional decision:
```yaml
server:
host: 0.0.0.0 # containers / remote access; keep 127.0.0.1 otherwise
port: 8989
```
2. Put an authenticating reverse proxy in front. A complete example with
[Caddy](https://caddyserver.com) (TLS is automatic):
```
rag.example.com {
basic_auth {
# generate the hash with: caddy hash-password
alice $2a$14$...bcrypt-hash...
}
reverse_proxy 127.0.0.1:8989
}
```
With this in place serviette itself can stay on 127.0.0.1 — only the proxy
is exposed. Any equivalent (nginx + auth_basic, oauth2-proxy, Cloudflare
Access, a VPN like Tailscale) works the same way.
**CORS** is deliberately not emitted by default: serviette's own UIs never
need it (the embedded chat is same-origin; the standalone frontend proxies
server-side, so `frontend.api_url` may point at a backend on another host —
or another fleet — without any browser-visible cross-origin traffic), and
the absence of CORS headers is what stops arbitrary web pages from reading
responses off localhost instances. If you build your own browser frontend
that calls the API directly from another origin, opt in with an explicit
allowlist:
```yaml
server:
cors_origins: ["https://app.example.com"] # never "*" unless you truly mean it
```
The engine's monitoring endpoints (`indexer.monitoring_http_port`) are
loopback-only by construction and cannot be exposed directly.
---
## Appendix: regenerating the demo GIF
The README demo GIF is rendered with Pillow (no terminal recorder or browser
needed), so it regenerates deterministically anywhere:
```bash
pip install pillow
python docs/generate_demos.py # -> docs/assets/demo.gif
```
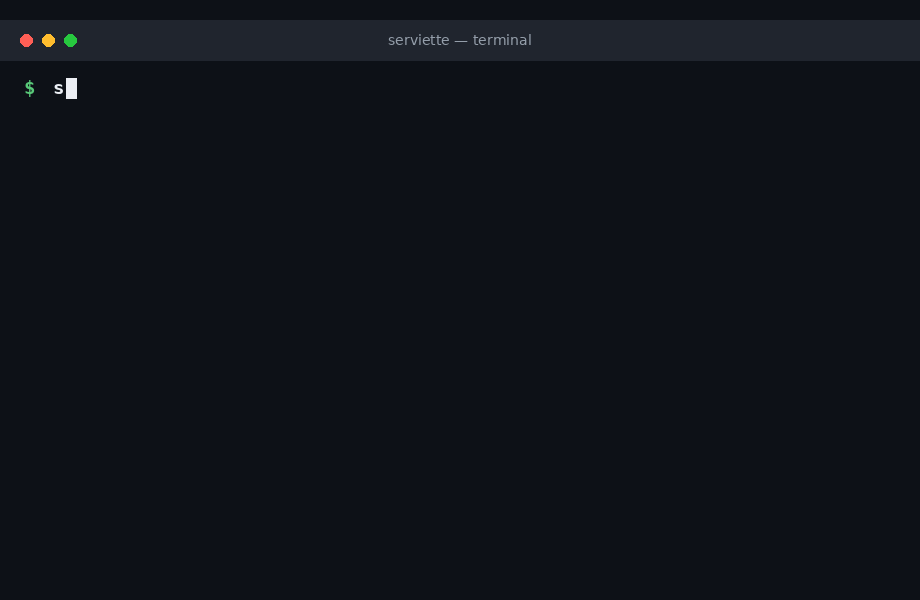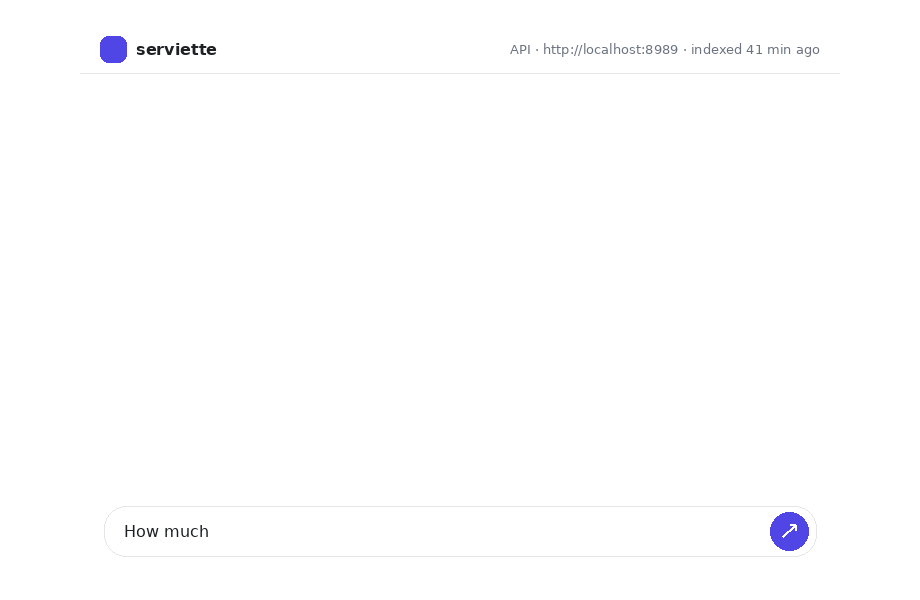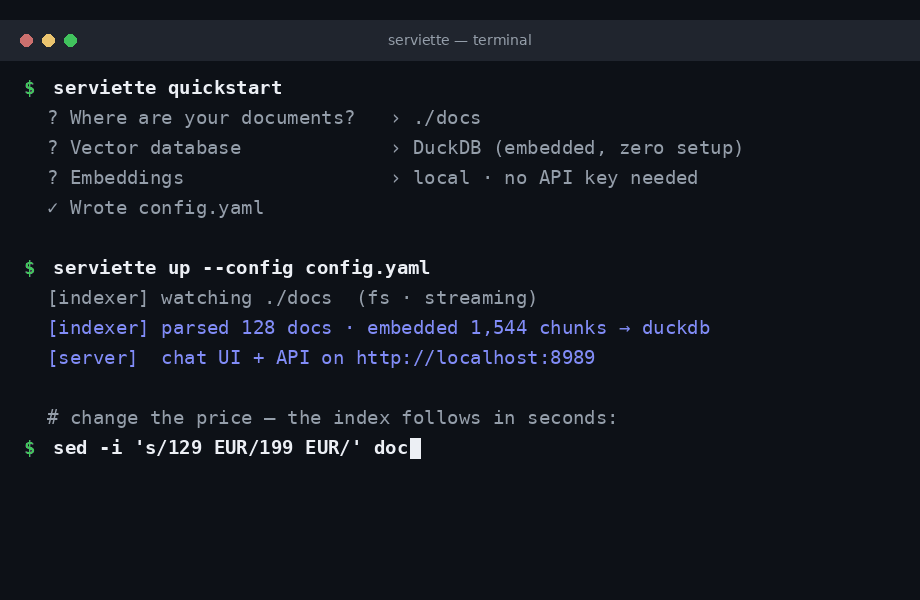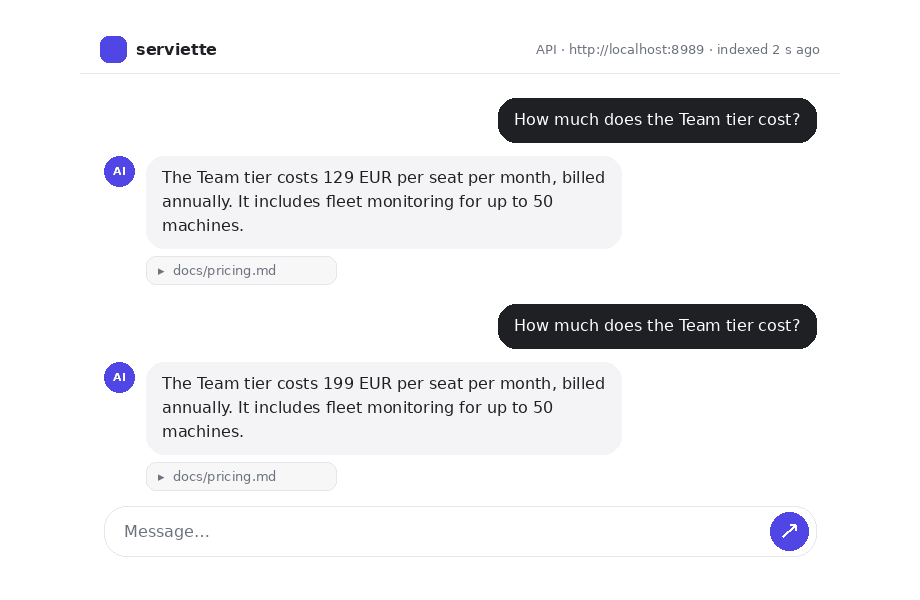
The frames show real output: the terminal lines are those of a recorded
`serviette demo` run (heartbeats thinned), the answers are what the model
produced on the bundled corpus before and after the `sed` edit, and the header
statistics are the real `/api/v1/stats` values. They live as constants in the
script (`SCRIPT_UP`, `SCRIPT_EDIT`, `ANSWER_*`, `STATS_*`) — when the output
of `demo`/`up` or the chat UI changes, re-record and update them rather than
inventing lines.
---
### Overview (`benchmarks/frames/README.md`)
# FRAMES benchmark
End-to-end evaluation of serviette's retrieval quality on
[FRAMES](https://arxiv.org/abs/2409.12941) (Google, 2024): 824 multi-hop
questions whose answers must be assembled from 2–15 English Wikipedia
articles.
> **Start with [REPORT.md](REPORT.md)** — the full technical report:
> methodology, statistics, analysis, limitations. This README is the
> operational companion (fidelity summary, headline numbers, how to run);
> [results/RESULTS.md](results/RESULTS.md) holds the raw data tables.
The methodology tracks the paper wherever technically possible and
documents every deviation below.
## Fidelity to the paper
| Aspect | Paper | This benchmark |
|---|---|---|
| Questions | 824, `google/frames-benchmark` | Same dataset, revision pinned in `fetch_dataset.py` |
| Corpus | Full English Wikipedia, TFDS `wikipedia/20230601.en` | **Same dump, indexed in full**: 5.22M articles → 12.07M chunks — every headline number is measured against it. A small working corpus (the ~2.5k gold articles + a deterministic ~78k distractor sample) exists alongside for fast feature ablations only. Gold articles whose canonical dump title differs from the link (redirects) are fetched via the Wikipedia API **at the snapshot date**; a handful of gold links point at articles created *after* the snapshot — absent here exactly as they were absent in the paper's corpus |
| Retrieval unit | Whole articles, BM25, n_docs ∈ {2, 4} | 512-token chunks; k=8 chunks ≈ the same context budget as BM25\@4 short articles |
| Retrieval metric | Gold-article recall in context (0.12–0.15 for their BM25) | Same metric, `run_retrieval_eval.py` — directly comparable, and free of LLM cost |
| Headline metric | Accuracy via LLM autorater | Same |
| Judge | Gemini-Pro-1.5, prompt in paper Appendix B (0.96 acc. vs humans) | **Same prompt** (`judge_prompt.txt`), gpt-4o-mini at temperature 0 (validated at 94% agreement with gpt-4o) — Gemini-Pro-1.5 is retired |
| Generator | Gemini-Pro-1.5-0514 | Configurable (retired model can't be reproduced). Every run reports its generator; the controlled baseline below anchors comparisons |
| Multi-step baseline | 5 steps × 5 queries × 10 docs → 0.66 | serviette's `rag.adaptive` + `rag.decompose` are the single-shot analogue (documented as *analogous, not identical*) |
**The controlled baseline:** because the paper's generator is unavailable,
cross-paper numbers are context, not conclusions. The primary comparison is
internal and fully controlled — serviette with all retrieval features off vs.
feature configurations, on the identical corpus, generator, judge, and
prompts. Only the retrieval layer varies.
## Results
Headlines, measured on the paper's full Wikipedia dump under the paper's
permissive protocol (full analysis and statistics in
[REPORT.md](REPORT.md)):
- **Adding serviette to gpt-5 yields a paired +5.2 pp over the same model
without retrieval** (z = 4.1 on 824 shared questions); under grounding,
the adaptive-retrieval flag adds **+11.5 pp** (z = 7.5). For context, the
absolute score (73.7%) exceeds every number in the paper, including its
5-step agent (66.0%) and oracle (72.9%) — a comparison dominated by
generator strength, which the report isolates.
- **Retrieval recall on the identical corpus: 0.50 vs 0.15** for the
paper's BM25 (0.21 for our reproduction of it) — measured with the
paper's own metric, no generator involved.
- A stricter **grounded** regime (answers only from documents — how
serviette ships for private corpora) is reported separately in
RESULTS.md and is deliberately not compared against the paper's numbers.
## Layout
```
fetch_dataset.py questions.jsonl from HF (revision-pinned)
extract_corpus.py corpora from the TFDS 2023-06-01 dump (run in a TF venv)
fetch_gold_fallback.py the few redirect-titled gold articles, at snapshot date
configs/ indexing + evaluation configurations
run_retrieval_eval.py phase 0: article recall, zero LLM cost
run_bench.py end-to-end: /rag + Appendix-B judge
results/ one jsonl per run: summary line + per-question rows
```
## Runbook
```bash
export FRAMES_DATA=/path/to/data # big; keep outside the repo
python fetch_dataset.py --out $FRAMES_DATA
# corpus (TF venv: pip install tensorflow-cpu tensorflow-datasets)
python extract_corpus.py --questions $FRAMES_DATA/questions.jsonl --out $FRAMES_DATA
python fetch_gold_fallback.py --missing $FRAMES_DATA/gold-missing.txt \
--out $FRAMES_DATA/corpus-gold
# long-lived Qdrant (index survives restarts; re-runs never re-embed)
docker run -d --name frames-qdrant -p 6343:6333 -p 6344:6334 \
-v $FRAMES_DATA/qdrant:/qdrant/storage qdrant/qdrant
serviette indexer --config configs/base-e5small.yaml # working corpus (~1.5 h)
serviette indexer --config configs/base-e5small-full.yaml # full dump (~75 h)
serviette server --config # per configuration
python run_retrieval_eval.py --questions $FRAMES_DATA/questions.jsonl \
--k 8 --label # free
OPENAI_API_KEY=... python run_bench.py \
--questions $FRAMES_DATA/questions.jsonl --k 8 --label
```
Re-runs are cheap by construction: corpora and the Qdrant index persist, so
changing a server-side setting (hybrid, reranker, `rag.*`) and re-evaluating
takes minutes, not hours. Only changing the embedder or the chunking requires
re-indexing (into a fresh collection, so the old one stays usable).
## Evaluation protocol
1. **Phase 0 — retrieval ablations, free.** Rank all retrieval
configurations by article recall\@k. No generation, no judge.
2. **Phase 1 — cheap generation sweep.** The shortlist runs end-to-end with
an inexpensive generator to rank configurations by accuracy.
3. **Phase 2 — headline runs.** The best configuration and the
features-off baseline run with the strongest generator; the judge stays
fixed. Reported: accuracy, article recall, generator, cost.
```
---
### Overview (`benchmarks/realtime-data-indexing/README.md`)
# Real-time data indexing benchmark
Measures two aspects of the serviette indexer:
1. **Indexing speed** — estimated wall-clock time for the indexing pipeline
(parse → chunk → embed → write to the vector DB), using the approximate
output-counter timing described below.
2. **Memory scaling** — document bytes flow through the pipeline, while
file-watch metadata grows with the number of files. The output is a
memory-over-time plot and sampled peak PSS (shared pages counted once).
Everything runs locally and costs nothing: embeddings are computed by a local
sentence-transformers model (`static-retrieval-mrl-en-v1`,
Matryoshka-truncated to 256 dims) — **no external API calls**.
## Setup
Three containers via docker-compose:
- **qdrant** — the vector store. Chosen deliberately: HNSW builds
incrementally on upsert (fast indexing), it is designed for concurrent
search-while-writing, and the Pathway sink keys points internally (no user
primary key), so writes parallelize across Pathway workers.
- **indexer** — `serviette indexer` in streaming mode. Completion uses the
chunk-count, parsing-progress and CPU-idleness checks in `run_bench.py`.
Published indexing time ends at the last increase in the running maximum
of Qdrant's approximate chunk count.
- **server** — `serviette server`; used after indexing to replay the accuracy
questions through `/api/v1/retrieve`.
Memory sampling starts after server readiness, with a three-second sleep
between iterations; collecting memory and querying progress adds to that
interval. Samples cover the indexer container's processes: RSS from
`/proc//status`, PSS and private-page counts from
`/proc//smaps_rollup`. Peak PSS is the maximum sampled sum. Shared pages
are counted once through PSS. Summed `VmHWM` is retained in CSV as an upper
bound on RSS, since different processes can peak at different times.
Per-process samples include the Pathway worker rank, excluding the sampler.
Qdrant and API-server memory, unmapped filesystem cache and kernel memory
are outside this PSS measurement. It is not a RAM requirement for the whole
stack, and sampling can miss brief peaks.
The current completion detector also requires successful parsing of every input
file. A chunk-rich subset can exceed the total file count and remain quiet
while the source is still being enumerated; this must not end sampling.
For a frozen corpus, `--expected-chunks N` additionally requires an exact
Qdrant count of N before accepting completion. This validates complete
output; the published approximate counter, 180-second quiet window,
30-core activity threshold and last-counter-increase time formula remain
the same. The saved results distinguish the checks available for each run.
The timer starts before launching the indexer and server; dataset preparation,
model downloads and Qdrant startup are outside it. Approximate counts can
overshoot and later fall during segment optimization, so the last new maximum
need not coincide with the final write. An exact-count check validates output
completeness when performed, but does not change the published time estimate
or establish when the backend finished building its search index.
`count_expected_chunks.py` independently counts the frozen `.txt` inputs
using UTF-8 decoding and the product's configured 512-token splitter.
Run it in the same immutable benchmark image, outside measured indexing,
and save its `-expected-output.json` files alongside the raw results.
## Dataset
`prepare_dataset.py` downloads Wikipedia parquet shards from Hugging Face
(public, fast CDN) and writes one `.txt` file per article until the target
size is reached. It also samples distinctive articles into `questions.json`;
each question must retrieve its own article (top-k accuracy sanity check).
Sources continue in this order: English, German, French, Spanish, Italian,
Portuguese, Dutch. The last two are needed to reach the published 50 GB
target. Preparation records actual bytes and file count in `preparation.json`
and fails if sources run out before the target; publication also checks the
measured corpus size.
The current product splitter merges trailing fragments shorter than 100
characters into the preceding chunk. Older published measurements used the
splitter without this merge, so old and new chunk counts, storage sizes and
timings do not isolate the effect of allocator tuning.
## Running
The serviette image is built from the repo checkout with the released
Pathway from PyPI (`docker compose build`, run automatically on first use);
`run_bench.py` pre-warms the local embedding-model cache, so the containers
themselves never touch the network.
```bash
python prepare_dataset.py --size-mb 100 # also: 1000, 3000, 10000
BENCH_JEMALLOC_CONF=background_thread:true python run_bench.py --size 100mb
```
Outputs land in `results/`: `-memory.png` (memory over time),
`-memory.csv`, `-summary.json` (duration, MB/min, chunk count,
peak RSS/PSS, retrieval accuracy). Each run also saves per-process samples,
the process snapshot at peak PSS, a redacted resolved compose configuration,
and compressed indexer logs. CSV measurements, JSON results and the two
published figures in `docs/assets/` are committed. Raw `*.txt.gz` logs,
per-size `-memory.png` plots, the generated `table.md` and the
`consistency-check.json` audit report stay local and are ignored by Git.
To regenerate the entire publication from a single series of runs:
```bash
export BENCH_DATA_ROOT=/path/on/a/large/disk/serviette-bench-datasets
export BENCH_JEMALLOC_CONF=background_thread:true
export BENCH_OMP_THREADS=12
export COMPOSE_PROJECT_NAME=serviette-consistency-bench
# PATHWAY_LICENSE_KEY must already be set. Build once for the full series.
docker compose build
python rerun_all.py
```
This runs 100mb → 1gb → 3gb → 10gb → 30gb → 50gb sequentially, records
an eight-process local-embedder initialization diagnostic, and then
calls `plot_results.py --update-readme`. Run it under nohup or tmux for the
multi-hour sizes. Datasets remain on the chosen disk after completion;
remove only this run's datasets when they are no longer needed.
Completed datasets (with `questions.json`) are reused, preserving historical
corpus boundaries. Missing datasets are prepared to the full nominal target;
nonempty incomplete datasets are rejected. Before each measured run, the driver
independently counts chunks in that corpus using the recorded image and passes
`--expected-chunks` to require an exact Qdrant count at completion. The audit
may download tokenizer data; it does not embed text or call an embedding API.
Reading the corpus for this audit can warm the filesystem cache. Containers
start with fresh database and persistence state, but the workflow does not
control the operating system's cache state or measure cold-cache I/O.
`plot_results.py` reads all six CSVs and summaries, validates their agreement,
and generates both README images and the table. It also saves `derived.json`
with the fitted file-watch estimate and peak-memory ratio. The pie separates
estimated local-embedder private memory, estimated shared embedding-library
PSS, estimated file-watch memory, remaining private memory and other shared
pages. It estimates what remains in the indexer with an external embedder,
excluding the embedding service itself. Anonymous-memory attribution uses
the separate diagnostic and remains an estimate; shared library pages come
from the main run's mappings.
See `results/README.md` for the recorded setup and attribution formula.
The publication contains one final run per corpus size, with no estimate of
run-to-run variability. Its memory scaling describes this configuration and
these corpora; file count and text volume both change between sizes. The
saved image IDs and package versions identify the measured environment, but
the build recipe uses floating image tags and dependency versions, and model
and dataset downloads have no pinned revision. A future rebuild can therefore
use a different environment or inputs.
Run `python verify_results.py` directly from a checkout to independently check
every aggregate sample against its per-process snapshot, recompute peaks
and indexing times, compare all published tables, and verify the pie sum
and complete 50 GB output. No benchmark rerun or plot regeneration is needed.
The command prints its report and writes a local `results/consistency-check.json`
with the checks and hashes of both published figures. `plot_results.py` can
regenerate the per-size plots and standalone table from the saved measurements.
---
### Overview (`benchmarks/frames/configs/README.md`)
# Bench configurations
`base-e5small.yaml` indexes both corpora into the long-lived Qdrant container.
Evaluation configs are the same file plus a **server-side overlay**: retrieval
features live in the `vector_db` / `reranker` / `rag` sections and need no
re-indexing — restart only `serviette server` with a different config to
switch configurations. Overlays used by the sweep (append to the base):
| Label | Overlay |
|---|---|
| `vector` | — (base as is) |
| `hybrid` | `vector_db.hybrid: true` |
| `hybrid-mmr` | + `rag: {mmr: {candidates: 24, diversity: 0.3}}` |
| `hybrid-ce-rerank` | + `reranker: {type: cross_encoder, candidates: 30}` |
| `hybrid-decompose` | + `rag: {decompose: {max_subqueries: 4}}` (needs `llm`) |
| `best-adaptive` | best of the above + `rag.adaptive` (e2e phases only) |
Generation phases add an `llm` section (e.g. `type: openai`, `model: gpt-4o`,
`temperature: 0`). The `e5base` variant swaps the embedder model to
`intfloat/e5-base-v2` and the collection to `frames_e5base` (separate
collection = both embedders stay indexed side by side).
---
### Overview (`benchmarks/realtime-data-indexing/results/README.md`)
# Indexing benchmark results
Measured from 2026-10-12T19:00:22.529304+00:00, on 96 logical CPUs.
Exact CPU description, RAM, kernel, image ID and installed package versions:
`run-environment.json`. Resolved compose configurations redact the license key.
The workload, 180-second quiet window, 30-core activity threshold and
approximate-counter timing formula are retained. The current completion
detector also requires all input files to be parsed and, when an expected
count is supplied, verifies the exact output count. Independent splitter
counts match the saved final counts for all six sizes. The saved 50 GB run
additionally records complete parsing progress and an exact Qdrant count;
the five smaller runs record approximate backend counts.
The separate 50 GB audit scanned 17,083,603 frozen input files (52,428,765,709
bytes) in the original immutable benchmark image and produced exactly
37,472,786 chunks, matching the saved run and exact Qdrant count.
It ran outside the measured indexing workload; memory and timing results
are unchanged. `50gb-expected-output.json` records this independent audit.
| corpus target | ≈ pages | files | chunks (approx.) | indexing time | peak memory (PSS, GiB) | in Qdrant (GiB) |
|---|---|---|---|---|---|---|
| 100 MB | 52 431 | 12 969 | 53 651 | 44 s | 6.86 | 0.61 |
| 1 GB | 524 288 | 240 516 | 604 299 | 4.9 min | 6.82 | 1.85 |
| 3 GB | 1 572 864 | 841 890 | 1 888 846 | 15.4 min | 7.18 | 4.89 |
| 10 GB | 5 242 884 | 3 423 359 | 6 761 214 | 1.0 h | 8.16 | 16.07 |
| 30 GB | 15 728 646 | 9 202 620 | 20 933 962 | 3.1 h | 10.40 | 48.57 |
| 50 GB | 26 214 382 | 17 083 603 | 37 472 786 | 6.0 h | 14.65 | 84.45 |
Input labels retain the published nominal sizes: 1 GB means a target of
1,000 MiB of text; 100 MB means 100 MiB. Memory and disk columns use GiB;
CSV columns ending in `_mb` contain MiB. Pages use 2,000 bytes per page.
The 50 GB input restores the historical Portuguese/Dutch continuation and
matches the archived file count and approximate page count. Strictly filling
the nominal byte target adds 20 trailing Dutch articles (35,697 bytes);
these are preserved outside the input to reproduce the published cutoff.
`50gb-preparation.json` records the final boundary and the trimmed bytes
and document count.
Peaks are the maximum sampled total PSS, not kernel high-water marks.
Sampling continues through the existing completion window.
Only indexer processes are included: Qdrant and API-server memory, unmapped
filesystem cache and kernel memory are outside this measurement. It is not
a RAM requirement for the whole stack. Sampling starts after server readiness;
each iteration includes a three-second sleep plus collection and polling
overhead, so brief peaks may be missed.
The chunk-count methodology is unchanged: the summary uses Qdrant's
approximate count at completion, while CSV `chunks` retains the maximum
observed count used by the completion detector. Segment optimization can
reduce approximate counts, so these two fields need not be identical;
`max_observed_chunks` records the CSV's value in the summary explicitly.
Published indexing time is an estimate: elapsed time from before launching
the indexer and server to the last increase in the running maximum of the
approximate chunk count. Preparation, model downloads and Qdrant startup are
outside this interval. A temporary overcount can make the last new maximum
precede the final write. Checking the exact output count at completion does
not revise that timestamp or measure when the backend's search index is ready.
The saved timing values retain this definition.
`*-memory.csv` and `*-processes.jsonl.gz` record aggregate and per-process
measurements at the same times; `*-summary.json` includes the process snapshot
at peak PSS. `*-indexer.txt.gz` contains the local container log and is
excluded from Git. Measurements, derived values, this report and the two
published figures in `docs/assets/` are committed. Per-size `*-memory.png`
plots, the standalone `table.md` and `consistency-check.json` stay local and
are ignored by Git; they can be regenerated from the saved measurements.
One final run per corpus size is published, without an estimate of run-to-run
variability. File count and text volume both change across sizes, so these
measurements do not establish constant memory at a fixed file count. They
describe this local static-embedding model, plain-text workload and configuration.
The product splitter merges trailing fragments shorter than 100 characters
into the preceding chunk; older published measurements predate that behavior.
Differences in chunk counts, disk usage and timing therefore cannot be
attributed to allocator tuning alone.
The saved runs do not establish a controlled cold-cache result. Fresh database
and persistence state do not imply a cold operating-system cache. The current
rerun driver reads the entire corpus to count expected chunks before indexing,
which can warm that cache. Saved image IDs and key package versions identify
the measured environment; the build recipe still uses floating image tags
and dependency versions, and model and dataset downloads have no pinned
revision. A future rebuild can use different software or inputs.
The right panel estimates file-watch memory as rank 0's private-page excess
over the median of the seven other workers at the final sample. It includes
any other unequal worker allocations; it is not an allocation-level measurement.
The line is a least-squares fit with an intercept (~361 bytes per file;
fixed overhead estimate 45.9 MiB).
The pie attributes local-embedding private memory using an eight-process
controlled diagnostic in the same image: graph imports before the embedder,
UTF-8 parser and configured splitter initialized and warmed, embedding
runtime imported, model loaded and warmed on three 2,048-text batches, then
model released. `embedder-calibration.json` records all stages. The private
increment after warming estimates the local stack's private cost across eight
workers. This is capped at the observed non-file-watch worker private memory
minus the calibrated pre-embedder baseline, since live and diagnostic buffers
have different lifetimes. Supervisor private pages are left in the residual;
any embedding allocations there are not subtracted speculatively.
Shared embedding-library PSS starts from mapping samples at the 10 GB peak
and is capped by the diagnostic's shared-library increment, so libraries
already needed by the parser are retained in the residual. Other shared
pages are separated. Anonymous attribution
and the indexer-without-local-embedder figure are estimates, not an actual
external-service benchmark; client overhead and changes in working buffers
are not measured. The embedding service's own memory is outside that figure.
Derived values are saved in `derived.json`.
Regenerate with `python plot_results.py --update-readme`.
The script checks CSV peaks, chunk counts and process snapshots against summaries
and requires all six sizes before updating the publication.
Run `python verify_results.py` directly from a checkout to audit every process
sample, both published tables and the pie sum. It does not require a benchmark
rerun or regenerated per-size plots. It prints the result and writes a local
`consistency-check.json` with hashes of both published figures.
---
--- METRICS ---
- Files Extracted: 6
- Estimated Token Budget: ~22941 tokens
- Canonical Reference: https://codewiki.google/github.com/pathwaycom/llm-app