# Technical Documentation: huggingface/transformers
> ℹ️ **Provenance:** Multi-Tier Ingestion · [CodeWiki Reference](https://codewiki.google/github.com/huggingface/transformers)
### Overview (`README.md`)
English |
简体中文 |
繁體中文 |
한국어 |
Español |
日本語 |
हिन्दी |
मराठी |
Русский |
Português |
తెలుగు |
Français |
Deutsch |
Italiano |
Tiếng Việt |
العربية |
اردو |
বাংলা |
فارسی |
Română |
Türkçe
State-of-the-art pretrained models for inference and training
Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer
vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be
simple, customizable, and efficient.
There are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.co/models) you can use.
Explore the [Hub](https://huggingface.co/) today to find a model and use Transformers to help you get started right away.
## Installation
Transformers works with Python 3.11+, and [PyTorch](https://pytorch.org/get-started/locally/) 2.6+.
Create and activate a virtual environment with [venv](https://docs.python.org/3/library/venv.html) or [uv](https://docs.astral.sh/uv/), a fast Rust-based Python package and project manager.
```py
# venv
python -m venv .my-env
source .my-env/bin/activate
# uv
uv venv .my-env
source .my-env/bin/activate
```
Install Transformers in your virtual environment.
```py
# pip
pip install "transformers[torch]"
# uv
uv pip install "transformers[torch]"
```
Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the *latest* version may not be stable. Feel free to open an [issue](https://github.com/huggingface/transformers/issues) if you encounter an error.
```shell
git clone https://github.com/huggingface/transformers.git
cd transformers
# pip
pip install '.[torch]'
# uv
uv pip install '.[torch]'
```
## Quickstart
Get started with Transformers right away with the [Pipeline](https://huggingface.co/docs/transformers/pipeline_tutorial) API. The `Pipeline` is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
```py
from transformers import pipeline
pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
```
To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to `Pipeline`) between you and the system.
> [!TIP]
> You can also chat with a model directly from the command line, as long as [`transformers serve` is running](https://huggingface.co/docs/transformers/main/en/serving).
> ```shell
> transformers chat Qwen/Qwen2.5-0.5B-Instruct
> ```
```py
import torch
from transformers import pipeline
chat = [
{"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
{"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]
pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])
```
Expand the examples below to see how `Pipeline` works for different modalities and tasks.
Automatic speech recognition
```py
from transformers import pipeline
pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
```
Image classification
```py
from transformers import pipeline
pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
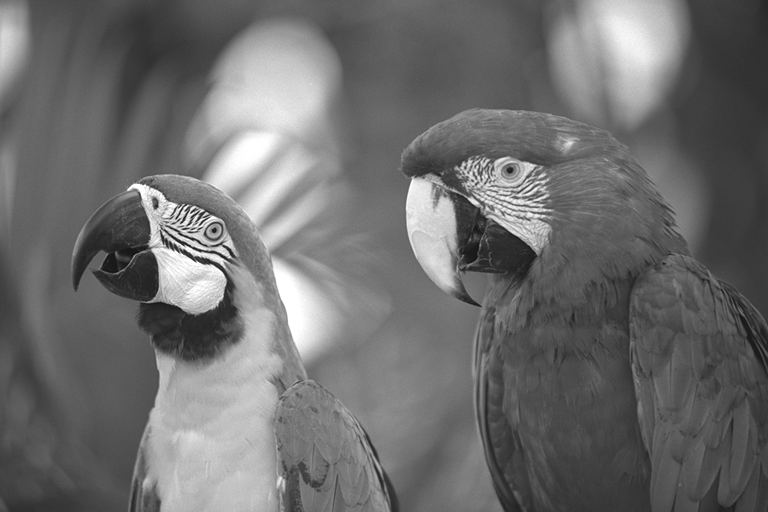
pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
[{'label': 'macaw', 'score': 0.997848391532898},
{'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
'score': 0.0016551691805943847},
{'label': 'lorikeet', 'score': 0.00018523589824326336},
{'label': 'African grey, African gray, Psittacus erithacus',
'score': 7.85409429227002e-05},
{'label': 'quail', 'score': 5.502637941390276e-05}]
```
Visual question answering
```py
from transformers import pipeline
pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
question="What is in the image?",
)
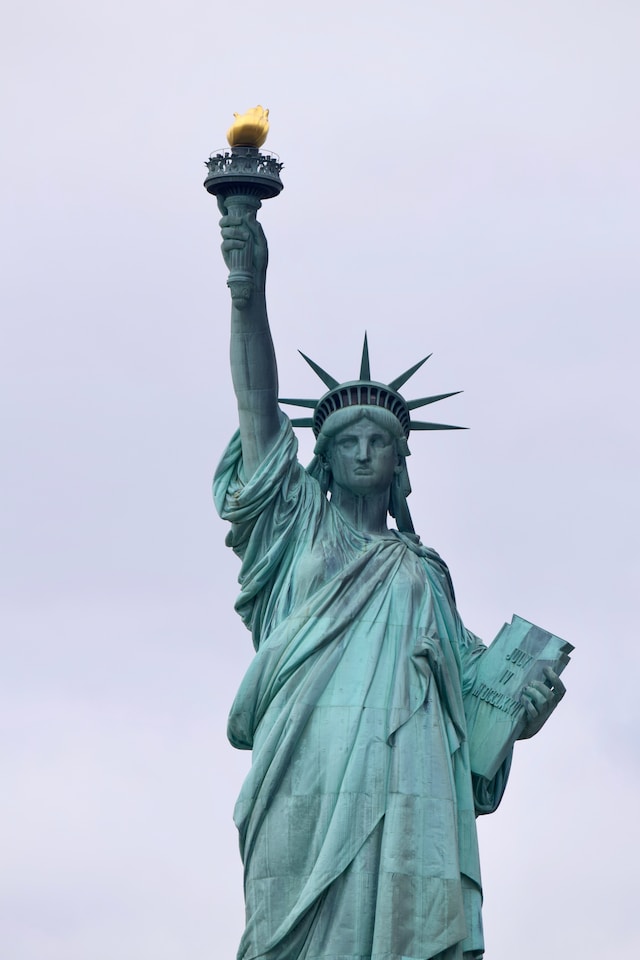
[{'answer': 'statue of liberty'}]
```
## Why should I use Transformers?
1. Easy-to-use state-of-the-art models:
- High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
- Low barrier to entry for researchers, engineers, and developers.
- Few user-facing abstractions with just three classes to learn.
- A unified API for using all our pretrained models.
1. Lower compute costs, smaller carbon footprint:
- Share trained models instead of training from scratch.
- Reduce compute time and production costs.
- Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.
1. Choose the right framework for every part of a model's lifetime:
- Train state-of-the-art models in 3 lines of code.
- Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
- Pick the right framework for training, evaluation, and production.
1. Easily customize a model or an example to your needs:
- We provide examples for each architecture to reproduce the results published by its original authors.
- Model internals are exposed as consistently as possible.
- Model files can be used independently of the library for quick experiments.
Audio
- Audio classification with [CLAP](https://huggingface.co/laion/clap-htsat-fused)
- Automatic speech recognition with [Parakeet](https://huggingface.co/nvidia/parakeet-ctc-1.1b#transcribing-using-transformers-%F0%9F%A4%97), [Whisper](https://huggingface.co/openai/whisper-large-v3-turbo), [GLM-ASR](https://huggingface.co/zai-org/GLM-ASR-Nano-2512) and [Moonshine-Streaming](https://huggingface.co/UsefulSensors/moonshine-streaming-medium)
- Keyword spotting with [Wav2Vec2](https://huggingface.co/superb/wav2vec2-base-superb-ks)
- Speech to speech generation with [Moshi](https://huggingface.co/kyutai/moshiko-pytorch-bf16)
- Text to audio with [MusicGen](https://huggingface.co/facebook/musicgen-large)
- Text to speech with [CSM](https://huggingface.co/sesame/csm-1b)
Computer vision
- Automatic mask generation with [SAM](https://huggingface.co/facebook/sam-vit-base)
- Depth estimation with [DepthPro](https://huggingface.co/apple/DepthPro-hf)
- Image classification with [DINO v2](https://huggingface.co/facebook/dinov2-base)
- Keypoint detection with [SuperPoint](https://huggingface.co/magic-leap-community/superpoint)
- Keypoint matching with [SuperGlue](https://huggingface.co/magic-leap-community/superglue_outdoor)
- Object detection with [RT-DETRv2](https://huggingface.co/PekingU/rtdetr_v2_r50vd)
- Pose Estimation with [VitPose](https://huggingface.co/usyd-community/vitpose-base-simple)
- Universal segmentation with [OneFormer](https://huggingface.co/shi-labs/oneformer_ade20k_swin_large)
- Video classification with [VideoMAE](https://huggingface.co/MCG-NJU/videomae-large)
Multimodal
- Audio or text to text with [Voxtral](https://huggingface.co/mistralai/Voxtral-Mini-3B-2507), [Audio Flamingo](https://huggingface.co/nvidia/audio-flamingo-3-hf)
- Document question answering with [LayoutLMv3](https://huggingface.co/microsoft/layoutlmv3-base)
- Image or text to text with [Qwen-VL](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct)
- Image captioning [BLIP-2](https://huggingface.co/Salesforce/blip2-opt-2.7b)
- OCR-based document understanding with [GOT-OCR2](https://huggingface.co/stepfun-ai/GOT-OCR-2.0-hf)
- Table question answering with [TAPAS](https://huggingface.co/google/tapas-base)
- Unified multimodal understanding and generation with [Emu3](https://huggingface.co/BAAI/Emu3-Gen)
- Vision to text with [Llava-OneVision](https://huggingface.co/llava-hf/llava-onevision-qwen2-0.5b-ov-hf)
- Visual question answering with [Llava](https://huggingface.co/llava-hf/llava-1.5-7b-hf)
- Visual referring expression segmentation with [Kosmos-2](https://huggingface.co/microsoft/kosmos-2-patch14-224)
NLP
- Masked word completion with [ModernBERT](https://huggingface.co/answerdotai/ModernBERT-base)
- Named entity recognition with [Gemma](https://huggingface.co/google/gemma-2-2b)
- Question answering with [Mixtral](https://huggingface.co/mistralai/Mixtral-8x7B-v0.1)
- Summarization with [BART](https://huggingface.co/facebook/bart-large-cnn)
- Translation with [T5](https://huggingface.co/google-t5/t5-base)
- Text generation with [Llama](https://huggingface.co/meta-llama/Llama-3.2-1B)
- Text classification with [Qwen](https://huggingface.co/Qwen/Qwen2.5-0.5B)
## Citation
We now have a [paper](https://aclanthology.org/2020.emnlp-demos.6/) you can cite for the 🤗 Transformers library:
```bibtex
@inproceedings{wolf-etal-2020-transformers,
title = "Transformers: State-of-the-Art Natural Language Processing",
author = "Thomas Wolf and Lysandre Debut and Victor Sanh and Julien Chaumond and Clement Delangue and Anthony Moi and Pierric Cistac and Tim Rault and Rémi Louf and Morgan Funtowicz and Joe Davison and Sam Shleifer and Patrick von Platen and Clara Ma and Yacine Jernite and Julien Plu and Canwen Xu and Teven Le Scao and Sylvain Gugger and Mariama Drame and Quentin Lhoest and Alexander M. Rush",
booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
month = oct,
year = "2020",
address = "Online",
publisher = "Association for Computational Linguistics",
url = "https://aclanthology.org/2020.emnlp-demos.6/",
pages = "38--45"
}
```
---
### Overview (`benchmark/README.md`)
# Benchmarks
You might want to add new benchmarks.
You will need to define a python function named `run_benchmark` in your python file and the file must be located in this `benchmark/` directory.
The expected function signature is the following:
```py
def run_benchmark(logger: Logger, branch: str, commit_id: str, commit_msg: str, num_tokens_to_generate=100):
```
## Writing metrics to the database
`MetricsRecorder` is thread-safe, in the sense of the python [`Thread`](https://docs.python.org/3/library/threading.html#threading.Thread). This means you can start a background thread to do the readings on the device measurements while not blocking the main thread to execute the model measurements.
cf [`llama.py`](./llama.py) to see an example of this in practice.
```
/* Detailed source-code truncated for AI context efficiency. */
```
---
### Overview (`benchmark_v2/README.md`)
# Benchmarking v2
A comprehensive benchmarking framework for transformer models that supports multiple execution modes (eager, compiled, kernelized), detailed performance metrics collection, and structured output format.
## Quick Start
### Running All Benchmarks
```bash
# Run all benchmarks with default settings
python run_benchmarks.py
# Specify output directory
python run_benchmarks.py --output-dir my_results
# Run with custom parameters
python run_benchmarks.py \
--warmup-iterations 5 \
--measurement-iterations 10 \
--num-tokens-to-generate 200
```
### Uploading Results to HuggingFace Dataset
You can automatically upload benchmark results to a HuggingFace Dataset for tracking and analysis:
```bash
# Upload to a public dataset with auto-generated run ID
python run_benchmarks.py --upload-to-hub username/benchmark-results
# Upload with a custom run ID for easy identification
python run_benchmarks.py --upload-to-hub username/benchmark-results --run-id experiment_v1
# Upload with custom HuggingFace token (if not set in environment)
python run_benchmarks.py --upload-to-hub username/benchmark-results --token hf_your_token_here
```
**Dataset Directory Structure:**
```
dataset_name/
├── 2025-01-15/
│ ├── runs/ # Non-scheduled runs (manual, PR, etc.)
│ │ └── 123-1245151651/ # GitHub run number and ID
│ │ └── benchmark_results/
│ │ ├── benchmark_summary_20250115_143022.json
│ │ └── model-name/
│ │ └── model-name_benchmark_20250115_143022.json
│ └── benchmark_results_abc123de/ # Scheduled runs (daily CI)
│ ├── benchmark_summary_20250115_143022.json
│ └── model-name/
│ └── model-name_benchmark_20250115_143022.json
└── 2025-01-16/
└── ...
```
**Authentication for Uploads:**
For uploading results, you need a HuggingFace token with write permissions to the target dataset. You can provide the token in several ways (in order of precedence):
1. Command line: `--token hf_your_token_here`
3. Environment variable: `HF_TOKEN`
### Running Specific Benchmarks
```bash
# Include only specific benchmarks
python run_benchmarks.py --include llama
# Exclude specific benchmarks
python run_benchmarks.py --exclude old_benchmark
## Output Format
Results are saved as JSON files with the following structure:
```json
{
"model_name": "llama_2_7b",
"benchmark_scenarios": [
{
"scenario_name": "eager_variant",
"metadata": {
"timestamp": "2025-01-XX...",
"commit_id": "abc123...",
"hardware_info": {
"gpu_name": "NVIDIA A100",
"gpu_memory_total": 40960,
"cpu_count": 64
},
"config": {
"variant": "eager",
"warmup_iterations": 3,
"measurement_iterations": 5
}
},
"measurements": {
"latency": {
"mean": 2.45,
"median": 2.43,
"std": 0.12,
"min": 2.31,
"max": 2.67,
"p95": 2.61,
"p99": 2.65
},
"time_to_first_token": {
"mean": 0.15,
"std": 0.02
},
"tokens_per_second": {
"mean": 87.3,
"unit": "tokens/sec"
}
},
"gpu_metrics": {
"gpu_utilization_mean": 85.2,
"gpu_memory_used_mean": 12450
}
}
]
}
```
### Debug Mode
```bash
python run_benchmarks.py --log-level DEBUG
```
## Contributing
To add new benchmarks:
1. Create a new file in `benches/`
2. Implement the `ModelBenchmark` interface
3. Add a runner function (`run_` or `run_benchmark`)
4. run_benchmarks.py
---
### Overview (`docker/README.md`)
# Dockers for `transformers`
In this folder you will find various docker files, and some subfolders.
- dockerfiles (ex: `consistency.dockerfile`) present under `~/docker` are used for our "fast" CIs. You should be able to use them for tasks that only need CPU. For example `torch-light` is a very light weights container (703MiB).
They all build on top of `ci-base.dockerfile`, using the Python version from the repo's `.python-version`. Build them with `docker buildx bake` from the repository root, e.g. `PYTHON_VERSION=$(cat .python-version) docker buildx bake -f docker/docker-bake.hcl torch-light` (a plain `docker build` won't resolve the `ci-base` stage).
- subfolders contain dockerfiles used for our `slow` CIs, which *can* be used for GPU tasks, but they are **BIG** as they were not specifically designed for a single model / single task. Thus the `~/docker/transformers-pytorch-gpu` includes additional dependencies to allow us to run ALL model tests (say `librosa` or `tesseract`, which you do not need to run LLMs)
The GPU ones share the steps in `gpu-common/` (Python from the repo's `.python-version`, finishing the `transformers` install, checking the pinned torch) through a named build context, e.g. `docker build --build-context gpu-common=docker/gpu-common --build-arg PYTHON_VERSION=$(cat .python-version) docker/transformers-all-latest-gpu`.
Note that in both case, you need to run `uv pip install -e .`, which should take around 5 seconds. We do it outside the dockerfile for the need of our CI: we checkout a new branch each time, and the `transformers` code is thus updated.
We are open to contribution, and invite the community to create dockerfiles with potential arguments that properly choose extras depending on the model's dependencies! :hugs:
---
### Overview (`docs/README.md`)
# Writing docs
The Transformers docs live under `docs/source//` and are built with [doc-builder](https://github.com/huggingface/doc-builder).
> [!TIP]
> You usually don't need to build the docs locally. When you open a PR that touches files under `docs/`, a bot builds a preview and posts the link as a comment on the PR.
Build locally for a faster iteration loop, or while drafting changes before you open a PR.
## Building and previewing locally
Install the quality dependencies and [doc-builder](https://github.com/huggingface/doc-builder) from the root of the repository. The `[quality]` extra is enough for docs-only work. Use `[dev]` if your change also needs the full development dependency set.
```bash
pip install -e ".[quality]"
pip install git+https://github.com/huggingface/doc-builder
```
To build the Markdown files into a temporary folder you can inspect in any Markdown editor:
```bash
doc-builder build transformers docs/source/en/ --build_dir ~/tmp/test-build
```
To live-preview the docs in a browser at [http://localhost:5173](http://localhost:5173), install [watchdog](https://github.com/gorakhargosh/watchdog) and run `preview`:
```bash
pip install watchdog
doc-builder preview transformers docs/source/en/
```
> [!WARNING]
> `preview` only picks up files that exist when it starts. After you add a brand-new page, update `_toctree.yml` and restart `preview`.
Don't commit the built output. Only changes under `docs/source/` are reviewed.
## Adding a new file to the docs
Pages live in `docs/source//` as Markdown (`.md`) files. The sidebar navigation lives in [_toctree.yml](https://github.com/huggingface/transformers/blob/main/docs/source/en/_toctree.yml), and a new page only shows up in the sidebar after you add it there.
1. Create the Markdown file under `docs/source/en/` (or the appropriate language directory). Match the file naming and license header of an existing page. Copying a similar page is the fastest way to start.
2. Add an entry to `docs/source/en/_toctree.yml` that points to the filename without the `.md` extension.
Each entry has two fields:
- `local`: the file path relative to `docs/source//`, without the extension.
- `title`: the human-readable label that appears in the sidebar.
For a page nested inside a subsection, add it to the inner `sections` list:
```yaml
- isExpanded: false
sections:
- local: contributing
title: Contribute to Transformers
- local: my_new_contributor_guide
title: My new contributor guide
title: Contribute
```
## Keeping code snippets device agnostic
Readers run our snippets on NVIDIA GPUs, AMD ROCm, Intel XPU, Apple MPS, Ascend NPU and CPU, so avoid hard-coding `"cuda"`.
- Use `device_map="auto"` only when automatic dispatch is intended. Keep explicit `cuda` in CUDA-specific examples.
- Move inputs with `inputs.to(model.device)` instead of `.to("cuda")` or `.cuda()`.
- Use `torch.accelerator.synchronize()` for synchronization and and `torch.Event(enable_timing=True)` for timing. Memory helpers live under `torch.accelerator.memory`, for example `torch.accelerator.memory.empty_cache()` and `torch.accelerator.memory.max_memory_allocated()`.
- If you really need a device string, use `device = torch.accelerator.current_accelerator().type if torch.accelerator.is_available() else "cpu"`.
- Keep `cuda` only where it is genuinely CUDA-specific: toolchain instructions (`nvcc`, `nvidia-smi`), NVIDIA-only backends, PyTorch API names such as `use_cuda_graph`, and sample outputs copied from a real run.
## doc-builder syntax
doc-builder accepts standard Markdown plus a few extensions you'll see across our docs. For the full set of supported syntax (inference snippets, file-include blocks, redirects, multilingual builds, etc.), see the [doc-builder README](https://github.com/huggingface/doc-builder#writing-documentation-for-hugging-face-libraries).
### Tips and warnings
Use GitHub-style blockquote callouts for notes, tips, and warnings:
```md
> [!TIP]
> Use `device_map="auto"` to let Transformers place model shards across available devices.
> [!WARNING]
> `from_pretrained` downloads the full checkpoint on first use. Set `cache_dir` to control where it lands.
```
Older pages may use the legacy `` component. Prefer blockquotes for new content.
### Internal links to classes and functions
Wrap a class, function, or method name in square brackets and backticks to link to its doc page. doc-builder resolves the link automatically:
```md
Use [`AutoModel`] to load a model from a checkpoint, then call [`~PreTrainedModel.from_pretrained`].
```
A few variations:
- Prefix the name with `~` to render only the last component (`from_pretrained`) instead of the full path (`PreTrainedModel.from_pretrained`).
- For objects nested in a submodule, include the path inside the backticks, like `utils.ModelOutput`.
- The same syntax links to objects in other Hugging Face libraries, e.g. `accelerate.Accelerator`.
### Tabbed options
To show alternative snippets (CLI vs. Python, different backends, etc.) as tabs, use ``:
````md
```bash
pip install transformers
```
```bash
uv pip install transformers
```
````
### Auto-generated API reference
> [!IMPORTANT]
> Always leave a blank line after `[[autodoc]]` so the CI checks pass.
Use `[[autodoc]]` to render the docstring of a class or function. The marker pulls the description, arguments, and (for classes) every public method:
```md
## AutoModel
[[autodoc]] AutoModel
```
To restrict the output to specific methods, list them as a bulleted sub-list:
```md
[[autodoc]] BertTokenizer
- build_inputs_with_special_tokens
- get_special_tokens_mask
```
To pull in a method that isn't documented by default (for example, `__call__`), start the list with `all` and then add the extras:
```md
[[autodoc]] BertTokenizer
- all
- __call__
```
### Testable code blocks
Tag Python fences with `runnable` (optionally followed by `:`) to mark them as testable examples. doc-builder strips the annotation from the rendered output:
````md
```py runnable:quickstart
from transformers import pipeline
pipe = pipeline("sentiment-analysis")
print(pipe("I love this!"))
```
````
## Writing docstrings
Most docstrings are automatically generated in the library source code, especially `modeling_*.py`, `configuration_*.py`, processing, and tokenizer files. For model classes and forward methods, use the [@auto_docstring](./source/en/auto_docstring.md) decorator when it applies. It keeps shared arguments and returns consistent docstrings without repeating full `Args:` blocks in every model file.
Use hand-written docstrings, following the [Google Python Style Guide](https://google.github.io/styleguide/pyguide.html), for objects that are not covered by `@auto_docstring`, or when a method needs model-specific behavior documented.
### Styling
Run `make style` to format docstrings and code examples with [Ruff](https://docs.astral.sh/ruff/).
The script can fail on syntax errors. Commit before running `make style` so you can revert if something goes wrong.
## Adding an image
Don't commit images, videos, or other binary assets to the repository because they bloat the repository. Host them on the Hub instead and reference them by URL. The standard home for documentation media is the [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images) dataset. For external PRs, attach the images to the PR and ask a Hugging Face maintainer to migrate them to the dataset.
---
### Overview (`notebooks/README.md`)
# 🤗 Transformers Notebooks
You can find here a list of the official notebooks provided by Hugging Face.
Also, we would like to list here interesting content created by the community.
If you wrote some notebook(s) leveraging 🤗 Transformers and would like to be listed here, please open a
Pull Request so it can be included under the Community notebooks.
## Hugging Face's notebooks 🤗
### Documentation notebooks
You can open any page of the documentation as a notebook in Colab (there is a button directly on said pages) but they are also listed here if you need them:
| Notebook | Description | | | |
|:----------|:-------------|:-------------|:------------|------:|
| [Quicktour of the library](https://github.com/huggingface/notebooks/blob/main/transformers_doc/en/quicktour.ipynb) | A presentation of the various APIs in Transformers |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/quicktour.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/en/transformers_doc/quicktour.ipynb)| |
| [Summary of the tasks](https://github.com/huggingface/notebooks/blob/main/transformers_doc/en/task_summary.ipynb) | How to run the models of the Transformers library task by task |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/task_summary.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/transformers_doc/en/task_summary.ipynb)| |
| [Preprocessing data](https://github.com/huggingface/notebooks/blob/main/transformers_doc/en/preprocessing.ipynb) | How to use a tokenizer to preprocess your data |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/preprocessing.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/transformers_doc/en/preprocessing.ipynb)||
| [Fine-tuning a pretrained model](https://github.com/huggingface/notebooks/blob/main/transformers_doc/en/training.ipynb) | How to use the Trainer to fine-tune a pretrained model |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/training.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/transformers_doc/en/training.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/transformers_doc/en/training.ipynb)|
| [Summary of the tokenizers](https://github.com/huggingface/notebooks/blob/main/transformers_doc/en/tokenizer_summary.ipynb) | The differences between the tokenizers algorithm |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/tokenizer_summary.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/transformers_doc/en/tokenizer_summary.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/transformers_doc/en/tokenizer_summary.ipynb )|
| [Multilingual models](https://github.com/huggingface/notebooks/blob/main/transformers_doc/en/multilingual.ipynb) | How to use the multilingual models of the library |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/transformers_doc/en/multilingual.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/transformers_doc/en/multilingual.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/transformers_doc/en/multilingual.ipynb)|
### PyTorch Examples
#### Natural Language Processing[[pytorch-nlp]]
| Notebook | Description | | | |
|:----------|:-------------|:-------------|:-------------|------:|
| [Train your tokenizer](https://github.com/huggingface/notebooks/blob/main/examples/tokenizer_training.ipynb) | How to train and use your very own tokenizer |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tokenizer_training.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/tokenizer_training.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/tokenizer_training.ipynb)|
| [Train your language model](https://github.com/huggingface/notebooks/blob/main/examples/language_modeling_from_scratch.ipynb) | How to easily start using transformers |[](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling_from_scratch.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/language_modeling_from_scratch.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/language_modeling_from_scratch.ipynb)|
| [How to fine-tune a model on text classification](https://github.com/huggingface/notebooks/blob/main/examples/text_classification.ipynb)| Show how to preprocess the data and fine-tune a pretrained model on any GLUE task. | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)| |
| [How to fine-tune a model on language modeling](https://github.com/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)| Show how to preprocess the data and fine-tune a pretrained model on a causal or masked LM task. | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)| [](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)|
| [How to fine-tune a model on token classification](https://github.com/huggingface/notebooks/blob/main/examples/token_classification.ipynb)| Show how to preprocess the data and fine-tune a pretrained model on a token classification task (NER, PoS). | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)|
| [How to fine-tune a model on question answering](https://github.com/huggingface/notebooks/blob/main/examples/question_answering.ipynb)| Show how to preprocess the data and fine-tune a pretrained model on SQUAD. | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)|
| [How to fine-tune a model on multiple choice](https://github.com/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)| Show how to preprocess the data and fine-tune a pretrained model on SWAG. | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)|
| [How to fine-tune a model on translation](https://github.com/huggingface/notebooks/blob/main/examples/translation.ipynb)| Show how to preprocess the data and fine-tune a pretrained model on WMT. | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/translation.ipynb)|[](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/translation.ipynb)|
| [How to fine-tune a model on summarization](https://github.com/huggingface/notebooks/blob/main/examples/summarization.ipynb)| Show how to preprocess the data and fine-tune a pretrained model on XSUM. | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)| |
| [How to train a language model from scratch](https://github.com/huggingface/blog/blob/main/notebooks/01_how_to_train.ipynb)| Highlight all the steps to effectively train Transformer model on custom data | [](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/01_how_to_train.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/blog/blob/main/notebooks/01_how_to_train.ipynb)| |
| [How to generate text](https://github.com/huggingface/blog/blob/main/notebooks/02_how_to_generate.ipynb)| How to use different decoding methods for language generation with transformers | [](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/02_how_to_generate.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/blog/blob/main/notebooks/02_how_to_generate.ipynb)| |
| [Reformer](https://github.com/huggingface/blog/blob/main/notebooks/03_reformer.ipynb)| How Reformer pushes the limits of language modeling | [](https://colab.research.google.com/github/patrickvonplaten/blog/blob/main/notebooks/03_reformer.ipynb)| [](https://studiolab.sagemaker.aws/import/github/patrickvonplaten/blog/blob/main/notebooks/03_reformer.ipynb)| |
#### Computer Vision[[pytorch-cv]]
| Notebook | Description | | | |
|:---------------------------------------------------------------------------------------------------------------------------------------------------------------------------|:-----------------------------------------------------------------------------------------------------------------------|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|:------|------:|
| [How to fine-tune a model on image classification (Torchvision)](https://github.com/huggingface/notebooks/blob/main/examples/image_classification.ipynb) | Show how to preprocess the data using Torchvision and fine-tune any pretrained Vision model on Image Classification | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)| [](https://oneclickamd.ai/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)|
| [How to fine-tune a model on image classification (Albumentations)](https://github.com/huggingface/notebooks/blob/main/examples/image_classification_albumentations.ipynb) | Show how to preprocess the data using Albumentations and fine-tune any pretrained Vision model on Image Classification | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification_albumentations.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/image_classification_albumentations.ipynb)| |
| [How to fine-tune a model on image classification (Kornia)](https://github.com/huggingface/notebooks/blob/main/examples/image_classification_kornia.ipynb) | Show how to preprocess the data using Kornia and fine-tune any pretrained Vision model on Image Classification | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification_kornia.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/image_classification_kornia.ipynb)| |
| [How to perform zero-shot object detection with OWL-ViT](https://github.com/huggingface/notebooks/blob/main/examples/zeroshot_object_detection_with_owlvit.ipynb) | Show how to perform zero-shot object detection on images with text queries | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/zeroshot_object_detection_with_owlvit.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/zeroshot_object_detection_with_owlvit.ipynb)| |
| [How to fine-tune an image captioning model](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_blip.ipynb) | Show how to fine-tune BLIP for image captioning on a custom dataset | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_captioning_blip.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/image_captioning_blip.ipynb)| |
| [How to build an image similarity system with Transformers](https://github.com/huggingface/notebooks/blob/main/examples/image_similarity.ipynb) | Show how to build an image similarity system | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_similarity.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/image_similarity.ipynb)| |
| [How to fine-tune a SegFormer model on semantic segmentation](https://github.com/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb) | Show how to preprocess the data and fine-tune a pretrained SegFormer model on Semantic Segmentation | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb)| |
| [How to fine-tune a VideoMAE model on video classification](https://github.com/huggingface/notebooks/blob/main/examples/video_classification.ipynb) | Show how to preprocess the data and fine-tune a pretrained VideoMAE model on Video Classification | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/video_classification.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/video_classification.ipynb)| |
#### Audio[[pytorch-audio]]
| Notebook | Description | | |
|:----------|:-------------|:-------------|------:|
| [How to fine-tune a speech recognition model in English](https://github.com/huggingface/notebooks/blob/main/examples/speech_recognition.ipynb)| Show how to preprocess the data and fine-tune a pretrained Speech model on TIMIT | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/speech_recognition.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/speech_recognition.ipynb)|
| [How to fine-tune a speech recognition model in any language](https://github.com/huggingface/notebooks/blob/main/examples/multi_lingual_speech_recognition.ipynb)| Show how to preprocess the data and fine-tune a multi-lingually pretrained speech model on Common Voice | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multi_lingual_speech_recognition.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/multi_lingual_speech_recognition.ipynb)|
| [How to fine-tune a model on audio classification](https://github.com/huggingface/notebooks/blob/main/examples/audio_classification.ipynb)| Show how to preprocess the data and fine-tune a pretrained Speech model on Keyword Spotting | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb)|
#### Biological Sequences[[pytorch-bio]]
| Notebook | Description | | |
|:----------|:----------------------------------------------------------------------------------------|:-------------|------:|
| [How to fine-tune a pre-trained protein model](https://github.com/huggingface/notebooks/blob/main/examples/protein_language_modeling.ipynb) | See how to tokenize proteins and fine-tune a large pre-trained protein "language" model | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/protein_language_modeling.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/protein_language_modeling.ipynb) |
| [How to generate protein folds](https://github.com/huggingface/notebooks/blob/main/examples/protein_folding.ipynb) | See how to go from protein sequence to a full protein model and PDB file | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/protein_folding.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/protein_folding.ipynb) |
| [How to fine-tune a Nucleotide Transformer model](https://github.com/huggingface/notebooks/blob/main/examples/nucleotide_transformer_dna_sequence_modelling.ipynb) | See how to tokenize DNA and fine-tune a large pre-trained DNA "language" model | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/nucleotide_transformer_dna_sequence_modelling.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/nucleotide_transformer_dna_sequence_modelling.ipynb) |
| [Fine-tune a Nucleotide Transformer model with LoRA](https://github.com/huggingface/notebooks/blob/main/examples/nucleotide_transformer_dna_sequence_modelling_with_peft.ipynb) | Train even larger DNA models in a memory-efficient way | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/nucleotide_transformer_dna_sequence_modelling_with_peft.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/nucleotide_transformer_dna_sequence_modelling_with_peft.ipynb) |
#### Other modalities[[pytorch-other]]
| Notebook | Description | | |
|:----------|:----------------------------------------------------------------------------------------|:-------------|------:|
| [Probabilistic Time Series Forecasting](https://github.com/huggingface/notebooks/blob/main/examples/time-series-transformers.ipynb) | See how to train Time Series Transformer on a custom dataset | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/time-series-transformers.ipynb) | [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/time-series-transformers.ipynb) |
#### Utility notebooks[[pytorch-utility]]
| Notebook | Description | | |
|:----------|:-------------|:-------------|------:|
| [How to export model to ONNX](https://github.com/huggingface/notebooks/blob/main/examples/onnx-export.ipynb)| Highlight how to export and run inference workloads through ONNX | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/onnx-export.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/onnx-export.ipynb)|
### Optimum notebooks
🤗 [Optimum](https://github.com/huggingface/optimum) is an extension of 🤗 Transformers, providing a set of performance optimization tools enabling maximum efficiency to train and run models on targeted hardware.
| Notebook | Description | | |
|:----------|:-------------|:-------------|------:|
| [How to quantize a model with ONNX Runtime for text classification](https://github.com/huggingface/notebooks/blob/main/examples/text_classification_quantization_ort.ipynb)| Show how to apply static and dynamic quantization on a model using [ONNX Runtime](https://github.com/microsoft/onnxruntime) for any GLUE task. | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification_quantization_ort.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/text_classification_quantization_ort.ipynb)|
| [How to fine-tune a model on text classification with ONNX Runtime](https://github.com/huggingface/notebooks/blob/main/examples/text_classification_ort.ipynb)| Show how to preprocess the data and fine-tune a model on any GLUE task using [ONNX Runtime](https://github.com/microsoft/onnxruntime). | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification_ort.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/text_classification_ort.ipynb)|
| [How to fine-tune a model on summarization with ONNX Runtime](https://github.com/huggingface/notebooks/blob/main/examples/summarization_ort.ipynb)| Show how to preprocess the data and fine-tune a model on XSUM using [ONNX Runtime](https://github.com/microsoft/onnxruntime). | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization_ort.ipynb)| [](https://studiolab.sagemaker.aws/import/github/huggingface/notebooks/blob/main/examples/summarization_ort.ipynb)|
## Community notebooks
More notebooks developed by the community are available [here](https://hf.co/docs/transformers/community#community-notebooks).
---
### Overview (`examples/modular-transformers/README.md`)
# Using the `modular_converter` linter
`pip install libcst` is a must!
# `sh examples/modular-transformers/convert_examples.sh` to get the converted outputs
The modular converter is a new `linter` specific to `transformers`. It allows us to unpack inheritance in python to convert a modular file like `modular_gemma.py` into a `single model single file`.
Examples of possible usage are available in the `examples/modular-transformers`, or `modular_gemma` for a full model usage.
`python utils/modular_model_converter.py --files_to_parse "/Users/arthurzucker/Work/transformers/examples/modular-transformers/modular_my_new_model2.py"`
## How it works
We use the `libcst` parser to produce an AST representation of the `modular_xxx.py` file. For any imports that are made from `transformers.models.modeling_xxxx` we parse the source code of that module, and build a class dependency mapping, which allows us to unpack the modularerence dependencies.
The code from the `modular` file and the class dependency mapping are "merged" to produce the single model single file.
We use ruff to automatically remove the potential duplicate imports.
## Why we use libcst instead of the native AST?
AST is super powerful, but it does not keep the `docstring`, `comment` or code formatting. Thus we decided to go with `libcst`
---
### Overview (`examples/scheduler/README.md`)
# GreedyLR: Adaptive Learning Rate Scheduler
GreedyLR monitors training metrics and adaptively adjusts the learning rate -- increasing when improving, decreasing when plateauing. It works for both pre-training and fine-tuning.
## Paper
> **GreedyLR: A Novel Adaptive Learning Rate Scheduler**
>
> Despite significant advances in optimizers for training, most research works use common scheduler choices like Cosine or exponential decay. In this paper, we study GreedyLR, a novel scheduler that adaptively adjusts the learning rate during training based on the current loss. To validate the effectiveness of our proposed scheduler, we conduct experiments on several NLP, CV, and LLM tasks with up to 7B parameters, including both fine-tuning and pretraining experiments. The results show that our approach outperforms several state-of-the-art schedulers in terms of accuracy, speed, and convergence.
arXiv: https://arxiv.org/abs/2512.14527
## How It Works
```
+-------------------------------------------------------------+
| GreedyLR Decision Flow |
| |
| Metrics Improving? --Yes--> Increase LR (/ factor) |
| | | |
| No Enter Warmup |
| | | |
| v v |
| Metrics Plateau? --Yes--> Decrease LR (* factor) |
| | | |
| No Enter Cooldown |
| | | |
| v v |
| Continue Training Continue Training |
+-------------------------------------------------------------+
```
### Key Parameters
| Parameter | Default | Description |
|-----------|---------|-------------|
| `patience` | 10 | Steps to wait before adjusting LR |
| `factor` | 0.95 | Multiplicative factor for LR adjustment |
| `min_lr` | 1e-3 | Minimum learning rate bound |
| `smooth` | False | Apply streaming average to metrics |
## Quick Start
### Fine-tuning LLaMA 3.2 1B on simpleCoT
Fine-tuning runs on a single GPU. This example uses [w601sxs/simpleCoT](https://huggingface.co/datasets/w601sxs/simpleCoT), a chain-of-thought reasoning dataset:
```
/* Detailed source-code truncated for AI context efficiency. */
```
### Pre-training LLaMA 3.2 1B on RedPajama (multi-GPU)
Pre-training a 1B+ parameter model requires multiple GPUs. This example uses a subset of [RedPajama-Data-V2](https://huggingface.co/datasets/togethercomputer/RedPajama-Data-V2) with DeepSpeed ZeRO-3 across 4 GPUs. The dataset should be pre-tokenized with 2048-token sequences.
Create a DeepSpeed config (`ds_config.json`):
```json
{
"bf16": {"enabled": true},
"zero_optimization": {
"stage": 3,
"offload_optimizer": {"device": "none"},
"offload_param": {"device": "none"},
"overlap_comm": true,
"contiguous_gradients": true,
"stage3_gather_16bit_weights_on_model_save": true
},
"gradient_accumulation_steps": "auto",
"gradient_clipping": 1.0,
"train_batch_size": "auto",
"train_micro_batch_size_per_gpu": "auto"
}
```
Training script (`pretrain_greedy.py`):
```python
import os
os.environ["PYTORCH_CUDA_ALLOC_CONF"] = "expandable_segments:True"
from transformers import (
AutoConfig,
AutoModelForCausalLM,
AutoTokenizer,
DataCollatorForLanguageModeling,
Trainer,
TrainingArguments,
)
from datasets import load_from_disk
config = AutoConfig.from_pretrained("meta-llama/Llama-3.2-1B")
model = AutoModelForCausalLM.from_config(config)
tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.2-1B")
tokenizer.pad_token = tokenizer.eos_token
tokenized_datasets = load_from_disk("./datasets/redpajama")
training_args = TrainingArguments(
output_dir="./output",
per_device_train_batch_size=1,
per_device_eval_batch_size=1,
gradient_accumulation_steps=32,
learning_rate=2e-4,
weight_decay=0.1,
max_grad_norm=1.0,
lr_scheduler_type="greedy",
lr_scheduler_kwargs={"patience": 2, "factor": 0.95, "min_lr": 1e-5},
max_steps=2000,
eval_strategy="steps",
eval_steps=500,
bf16=True,
gradient_checkpointing=True,
dataloader_drop_last=True,
deepspeed="ds_config.json",
)
trainer = Trainer(
model=model,
args=training_args,
train_dataset=tokenized_datasets["train"],
eval_dataset=tokenized_datasets["valid"],
data_collator=DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False),
)
trainer.train()
```
Launch with `torchrun`:
```bash
torchrun --nproc_per_node=4 pretrain_greedy.py
```
### Standalone Usage (without Trainer)
```python
import torch
from transformers import GreedyLR
optimizer = torch.optim.AdamW(model.parameters(), lr=2e-4)
scheduler = GreedyLR(
optimizer,
mode="min",
factor=0.99,
patience=10,
min_lr=1e-5,
smooth=True,
window_size=50,
)
for epoch in range(num_epochs):
train_loss = train_one_epoch(model, train_loader, optimizer)
val_loss = evaluate(model, val_loader)
scheduler.step(val_loss)
```
## Comparison with Other Schedulers
| Feature | Cosine | ReduceLROnPlateau | GreedyLR |
|---------|--------|-------------------|----------|
| Adaptive to metrics | No | Yes (decrease only) | Yes (increase and decrease) |
| LR increase | No | No | Yes |
| Warmup after increase | No | No | Yes |
| Metric smoothing | No | No | Yes (optional) |
| Auto-reset | No | No | Yes |
## Using with Other Models
GreedyLR is model-agnostic. The `run_greedy.py` script pre-trains or fine-tunes a causal language model on WikiText-2:
```bash
# Pre-train with GreedyLR (default)
python examples/scheduler/run_greedy.py
# Compare with cosine scheduler
python examples/scheduler/run_greedy.py --lr_scheduler_type cosine
# Use a different model
python examples/scheduler/run_greedy.py --model_name_or_path Qwen/Qwen3-0.6B
# Fine-tune from pretrained weights
python examples/scheduler/run_greedy.py --finetune
```
## Citation
```bibtex
@article{greedylr2025,
title={GreedyLR: A Novel Adaptive Learning Rate Scheduler},
author={Subramanian, Shreyas and Krishnamoorthy, Bala and Murthy, Pranav},
journal={arXiv preprint arXiv:2512.14527},
year={2025}
}
```
---
### Overview (`tests/contracts/README.md`)
# Model integration contracts
Model integration contracts (MICs) check model behavior against reviewed baselines
using small, fast model fixtures. PR CI selects relevant cases from changes to
model and processor code and reports differences in logs, summaries and OpenTelemetry.
Baseline failures are observational and do not fail the CI job.
The fleet locks in this directory pin model repositories and revisions in the
[`huggingface-mic`](https://huggingface.co/huggingface-mic) Hub organization.
Each repository contains model weights, `integration.json`, usage examples and
framework expectations under
`integrations//expectations//[.].json`.
The runner is maintained in
[`transformers-ci`](https://github.com/huggingface/transformers-ci).
To run MICs locally from the Transformers checkout:
```bash
pip install "transformers-ci[contracts,otel] @ git+https://github.com/huggingface/transformers-ci@main"
run-model-contracts --fixtures-only --lock tests/contracts/prototype-fleet.lock --variant bfloat16
run-model-contracts --fixtures-only --lock tests/contracts/fleet-lock.json \
--contract SmolLM --target mic-SmolLM-slim
```
CI compares outputs against the pinned expectations; it never records new baselines.
Review measured behavior changes before updating expectations or lock revisions.
---
### Overview (`tests/sagemaker/README.md`)
# Testing new Hugging Face Deep Learning Container.
This document explains the testing strategy for releasing the new Hugging Face Deep Learning Container. AWS maintains 14 days of currency with framework releases. Besides framework releases, AWS release train is bi-weekly on Monday. Code cutoff date for any changes is the Wednesday before release-Monday.
## Test Case 1: Releasing a New Version (Minor/Major) of 🤗 Transformers
### Requirements: Test should run on Release Candidate for new `transformers` release to validate the new release is compatible with the DLCs. To run these tests you need credentials for the HF SageMaker AWS Account. You can ask @philschmid or @n1t0 to get access.
### Run Tests:
Before we can run the tests we need to adjust the `requirements.txt` for PyTorch. We adjust the branch to the new RC-tag.
```
git+https://github.com/huggingface/transformers.git@v4.5.0.rc0 # install main or adjust it with vX.X.X for installing version specific-transforms
```
After we adjusted the `requirements.txt` we can run Amazon SageMaker tests with:
```bash
AWS_PROFILE= make test-sagemaker
```
These tests take around 10-15 minutes to finish. Preferably make a screenshot of the successfully ran tests.
### After Transformers Release:
After we have released the Release Candidate we need to create a PR at the [Deep Learning Container Repository](https://github.com/aws/deep-learning-containers).
**Creating the update PR:**
1. Update the latest `buildspec.yaml` config for [PyTorch](https://github.com/aws/deep-learning-containers/tree/master/huggingface/pytorch). The two latest `buildspec.yaml` are the `buildspec.yaml` without a version tag and the one with the highest framework version, e.g. `buildspec-1-7-1.yml` and not `buildspec-1-6.yml`.
To update the `buildspec.yaml` we need to adjust either the `transformers_version` or the `datasets_version` or both. Example for upgrading to `transformers 4.5.0` and `datasets 1.6.0`.
```
/* Detailed source-code truncated for AI context efficiency. */
```
2. In the PR comment describe what test, we ran and with which package versions. Here you can copy the table from [Current Tests](#current-tests).
2. In the PR comment describe what test we ran and with which framework versions. Here you can copy the table from [Current Tests](#current-tests). You can take a look at this [PR](https://github.com/aws/deep-learning-containers/pull/1016), which information are needed.
## Test Case 2: Releasing a New AWS Framework DLC
## Execute Tests
### Requirements:
AWS is going to release new DLCs for PyTorch. The Tests should run on the new framework versions with current `transformers` release to validate the new framework release is compatible with the `transformers` version. To run these tests you need credentials for the HF SageMaker AWS Account. You can ask @philschmid or @n1t0 to get access. AWS will notify us with a new issue in the repository pointing to their framework upgrade PR.
### Run Tests:
Before we can run the tests we need to adjust the `requirements.txt` for Pytorch under `/tests/sagemaker/scripts/pytorch`. We add the new framework version to it.
```bash
torch==1.8.1 # for pytorch
```
After we adjusted the `requirements.txt` we can run Amazon SageMaker tests with.
```bash
AWS_PROFILE= make test-sagemaker
```
These tests take around 10-15 minutes to finish. Preferably make a screenshot of the successfully ran tests.
### After successful Tests:
After we have successfully run tests for the new framework version we need to create a PR at the [Deep Learning Container Repository](https://github.com/aws/deep-learning-containers).
**Creating the update PR:**
1. Create a new `buildspec.yaml` config for [PyTorch](https://github.com/aws/deep-learning-containers/tree/master/huggingface/pytorch) and rename the old `buildspec.yaml` to `buildespec-x.x.x`, where `x.x.x` is the base framework version, e.g. if pytorch 1.6.0 is the latest version in `buildspec.yaml` the file should be renamed to `buildspec-yaml-1-6.yaml`.
To create the new `buildspec.yaml` we need to adjust the `version` and the `short_version`. Example for upgrading to `pytorch 1.7.1`.
```
/* Detailed source-code truncated for AI context efficiency. */
```
2. In the PR comment describe what test we ran and with which framework versions. Here you can copy the table from [Current Tests](#current-tests). You can take a look at this [PR](https://github.com/aws/deep-learning-containers/pull/1025), which information are needed.
## Current Tests
| ID | Description | Platform | #GPUs | Collected & evaluated metrics |
|-------------------------------------|-------------------------------------------------------------------|-----------------------------|-------|------------------------------------------|
| pytorch-transformers-test-single | test bert finetuning using BERT fromtransformerlib+PT | SageMaker createTrainingJob | 1 | train_runtime, eval_accuracy & eval_loss |
| pytorch-transformers-test-2-ddp | test bert finetuning using BERT from transformer lib+ PT DPP | SageMaker createTrainingJob | 16 | train_runtime, eval_accuracy & eval_loss |
| pytorch-transformers-test-2-smd | test bert finetuning using BERT from transformer lib+ PT SM DDP | SageMaker createTrainingJob | 16 | train_runtime, eval_accuracy & eval_loss |
| pytorch-transformers-test-1-smp | test roberta finetuning using BERT from transformer lib+ PT SM MP | SageMaker createTrainingJob | 8 | train_runtime, eval_accuracy & eval_loss |
---
### Overview (`tests/quantization/bnb/README.md`)
# Testing mixed int8 quantization
The following is the recipe on how to effectively debug `bitsandbytes` integration on Hugging Face `transformers`.
## Library requirements
+ `transformers>=4.22.0`
+ `accelerate>=0.12.0`
+ `bitsandbytes>=0.31.5`.
## Hardware requirements
The following instructions are tested with 2 NVIDIA-Tesla T4 GPUs. To run successfully `bitsandbytes` you would need a 8-bit core tensor supported GPU. Note that Turing, Ampere or newer architectures - e.g. T4, RTX20s RTX30s, A40-A100, A6000 should be supported.
## Virtual envs
```bash
conda create --name int8-testing python==3.8
pip install bitsandbytes>=0.31.5
pip install accelerate>=0.12.0
pip install transformers>=4.23.0
```
if `transformers>=4.23.0` is not released yet, then use:
```bash
pip install git+https://github.com/huggingface/transformers.git
```
## Troubleshooting
A list of common errors:
### Torch does not correctly do the operations on GPU
First check that:
```py
import torch
vec = torch.randn(1, 2, 3).to(0)
```
Works without any error. If not, install torch using `conda` like:
```bash
conda create --name int8-testing python==3.8
conda install pytorch torchvision torchaudio cudatoolkit=11.6 -c pytorch -c conda-forge
pip install bitsandbytes>=0.31.5
pip install accelerate>=0.12.0
pip install transformers>=4.23.0
```
For the latest pytorch instructions please see [this](https://pytorch.org/get-started/locally/)
and the snippet above should work.
### ` bitsandbytes operations are not supported under CPU!`
This happens when some Linear weights are set to the CPU when using `accelerate`. Please check carefully `model.hf_device_map` and make sure that there is no `Linear` module that is assigned to CPU. It is fine to have the last module (usually the Lm_head) set on CPU.
### `To use the type as a Parameter, please correct the detach() semantics defined by __torch_dispatch__() implementation.`
Use the latest version of `accelerate` with a command such as: `pip install -U accelerate` and the problem should be solved.
### `Parameter has no attribute .CB`
Same solution as above.
### `RuntimeError: CUDA error: an illegal memory access was encountered ... consider passing CUDA_LAUNCH_BLOCKING=1`
Run your script by prepending `CUDA_LAUNCH_BLOCKING=1` and you should observe an error as described in the next section.
### `CUDA illegal memory error: an illegal memory access at line...`:
Check the CUDA versions with:
```bash
nvcc --version
```
and confirm it is the same version as the one detected by `bitsandbytes`. If not, run:
```bash
ls -l $CONDA_PREFIX/lib/libcudart.so
```
or
```bash
ls -l $LD_LIBRARY_PATH
```
Check if `libcudart.so` has a correct symlink that is set. Sometimes `nvcc` detects the correct CUDA version but `bitsandbytes` doesn't. You have to make sure that the symlink that is set for the file `libcudart.so` is redirected to the correct CUDA file.
Here is an example of a badly configured CUDA installation:
`nvcc --version` gives:
which means that the detected CUDA version is 11.3 but `bitsandbytes` outputs:
First check:
```bash
echo $LD_LIBRARY_PATH
```
If this contains multiple paths separated by `:`. Then you have to make sure that the correct CUDA version is set. By doing:
```bash
ls -l $path/libcudart.so
```
On each path (`$path`) separated by `:`.
If not, simply run
```bash
ls -l $LD_LIBRARY_PATH/libcudart.so
```
and you can see
If you see that the file is linked to the wrong CUDA version (here 10.2), find the correct location for `libcudart.so` (`find --name libcudart.so`) and replace the environment variable `LD_LIBRARY_PATH` with the one containing the correct `libcudart.so` file.
---
### Source Ar Index (`docs/source/ar/index.md`)
# 🤗 Transformers: لمحة عامة
أحدث ما في مجال التعلم الآلي لـ [PyTorch](https://pytorch.org/) و [TensorFlow](https://www.tensorflow.org/) و [JAX](https://jax.readthedocs.io/en/latest/)
توفر 🤗 Transformers واجهات برمجة التطبيقات (APIs) والأدوات اللازمة لتنزيل وتدريب أحدث النماذج المسبقة التدريب بسهولة. ويمكن أن يقلل استخدام النماذج المسبقة التدريب من تكاليف الحوسبة والحد من الأثر البيئي، وتوفّر الوقت والموارد اللازمين لتدريب نموذج من الصفر. وتدعم هذه النماذج المهام الشائعة في مجالات مختلفة، مثل:
📝 **معالجة اللغات الطبيعية**: تصنيف النصوص، وتعريف الكيانات المسماة، والإجابة على الأسئلة، ونمذجة اللغة، والتلخيص، والترجمة، والاختيار من متعدد، وتوليد النصوص.
## المحتويات
ينقسم التوثيق إلى خمسة أقسام:
- **ابدأ** تقدم جولة سريعة في المكتبة وتعليمات التثبيت للبدء.
- **الدروس التعليمية** هي مكان رائع للبدء إذا كنت مبتدئًا. سيساعدك هذا القسم على اكتساب المهارات الأساسية التي تحتاجها للبدء في استخدام المكتبة.
- **أدلة كيفية الاستخدام** تُظهر لك كيفية تحقيق هدف محدد، مثل ضبط نموذج مسبق التدريب لنمذجة اللغة أو كيفية كتابة ومشاركة نموذج مخصص.
- **الأدلة المفاهيمية** تقدم مناقشة وتفسيرًا أكثر للأفكار والمفاهيم الأساسية وراء النماذج والمهام وفلسفة التصميم في 🤗 Transformers.
- **واجهة برمجة التطبيقات (API)** تصف جميع الفئات والوظائف:
- **الفئات الرئيسية** تشرح الفئات الأكثر أهمية مثل التكوين والنمذجة والتحليل النصي وخط الأنابيب.
- **النماذج** تشرح الفئات والوظائف المتعلقة بكل نموذج يتم تنفيذه في المكتبة.
- **المساعدون الداخليون** يشرحون فئات ووظائف المساعدة التي يتم استخدامها داخليًا.
## النماذج والأطر المدعومة
يمثل الجدول أدناه الدعم الحالي في المكتبة لكل من هذه النماذج، وما إذا كان لديها محلل نحوي Python (يُسمى "بطيء"). محلل نحوي "سريع" مدعوم بمكتبة 🤗 Tokenizers، وما إذا كان لديها دعم في Jax (عبر Flax) و/أو PyTorch و/أو TensorFlow.
| Model | PyTorch support | TensorFlow support | Flax Support |
|:------------------------------------------------------------------------:|:---------------:|:------------------:|:------------:|
| [ALBERT](model_doc/albert) | ✅ | ✅ | ✅ |
| [ALIGN](model_doc/align) | ✅ | ❌ | ❌ |
| [AltCLIP](model_doc/altclip) | ✅ | ❌ | ❌ |
| [Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer) | ✅ | ❌ | ❌ |
| [Autoformer](model_doc/autoformer) | ✅ | ❌ | ❌ |
| [Bark](model_doc/bark) | ✅ | ❌ | ❌ |
| [BART](model_doc/bart) | ✅ | ✅ | ✅ |
| [BARThez](model_doc/barthez) | ✅ | ✅ | ✅ |
| [BARTpho](model_doc/bartpho) | ✅ | ✅ | ✅ |
| [BEiT](model_doc/beit) | ✅ | ❌ | ✅ |
| [BERT](model_doc/bert) | ✅ | ✅ | ✅ |
| [Bert Generation](model_doc/bert-generation) | ✅ | ❌ | ❌ |
| [BertJapanese](model_doc/bert-japanese) | ✅ | ✅ | ✅ |
| [BERTweet](model_doc/bertweet) | ✅ | ✅ | ✅ |
| [BigBird](model_doc/big_bird) | ✅ | ❌ | ✅ |
| [BigBird-Pegasus](model_doc/bigbird_pegasus) | ✅ | ❌ | ❌ |
| [BioGpt](model_doc/biogpt) | ✅ | ❌ | ❌ |
| [BiT](model_doc/bit) | ✅ | ❌ | ❌ |
| [Blenderbot](model_doc/blenderbot) | ✅ | ✅ | ✅ |
| [BlenderbotSmall](model_doc/blenderbot-small) | ✅ | ✅ | ✅ |
| [BLIP](model_doc/blip) | ✅ | ✅ | ❌ |
| [BLIP-2](model_doc/blip-2) | ✅ | ❌ | ❌ |
| [BLOOM](model_doc/bloom) | ✅ | ❌ | ✅ |
| [BORT](model_doc/bort) | ✅ | ✅ | ✅ |
| [BridgeTower](model_doc/bridgetower) | ✅ | ❌ | ❌ |
| [BROS](model_doc/bros) | ✅ | ❌ | ❌ |
| [ByT5](model_doc/byt5) | ✅ | ✅ | ✅ |
| [CamemBERT](model_doc/camembert) | ✅ | ✅ | ❌ |
| [CANINE](model_doc/canine) | ✅ | ❌ | ❌ |
| [Chameleon](model_doc/chameleon) | ✅ | ❌ | ❌ |
| [Chinese-CLIP](model_doc/chinese_clip) | ✅ | ❌ | ❌ |
| [CLAP](model_doc/clap) | ✅ | ❌ | ❌ |
| [CLIP](model_doc/clip) | ✅ | ✅ | ✅ |
| [CLIPSeg](model_doc/clipseg) | ✅ | ❌ | ❌ |
| [CLVP](model_doc/clvp) | ✅ | ❌ | ❌ |
| [CodeGen](model_doc/codegen) | ✅ | ❌ | ❌ |
| [CodeLlama](model_doc/code_llama) | ✅ | ❌ | ✅ |
| [Cohere](model_doc/cohere) | ✅ | ❌ | ❌ |
| [Conditional DETR](model_doc/conditional_detr) | ✅ | ❌ | ❌ |
| [ConvBERT](model_doc/convbert) | ✅ | ✅ | ❌ |
| [ConvNeXT](model_doc/convnext) | ✅ | ✅ | ❌ |
| [ConvNeXTV2](model_doc/convnextv2) | ✅ | ✅ | ❌ |
| [CPM](model_doc/cpm) | ✅ | ✅ | ✅ |
| [CPM-Ant](model_doc/cpmant) | ✅ | ❌ | ❌ |
| [CTRL](model_doc/ctrl) | ✅ | ✅ | ❌ |
| [CvT](model_doc/cvt) | ✅ | ✅ | ❌ |
| [DAC](model_doc/dac) | ✅ | ❌ | ❌ |
| [Data2VecAudio](model_doc/data2vec) | ✅ | ❌ | ❌ |
| [Data2VecText](model_doc/data2vec) | ✅ | ❌ | ❌ |
| [Data2VecVision](model_doc/data2vec) | ✅ | ✅ | ❌ |
| [DBRX](model_doc/dbrx) | ✅ | ❌ | ❌ |
| [DeBERTa](model_doc/deberta) | ✅ | ✅ | ❌ |
| [DeBERTa-v2](model_doc/deberta-v2) | ✅ | ✅ | ❌ |
| [Decision Transformer](model_doc/decision_transformer) | ✅ | ❌ | ❌ |
| [Deformable DETR](model_doc/deformable_detr) | ✅ | ❌ | ❌ |
| [DeiT](model_doc/deit) | ✅ | ✅ | ❌ |
| [DePlot](model_doc/deplot) | ✅ | ❌ | ❌ |
| [Depth Anything](model_doc/depth_anything) | ✅ | ❌ | ❌ |
| [DETA](model_doc/deta) | ✅ | ❌ | ❌ |
| [DETR](model_doc/detr) | ✅ | ❌ | ❌ |
| [DialoGPT](model_doc/dialogpt) | ✅ | ✅ | ✅ |
| [DiNAT](model_doc/dinat) | ✅ | ❌ | ❌ |
| [DINOv2](model_doc/dinov2) | ✅ | ❌ | ✅ |
| [DistilBERT](model_doc/distilbert) | ✅ | ✅ | ✅ |
| [DiT](model_doc/dit) | ✅ | ❌ | ✅ |
| [DonutSwin](model_doc/donut) | ✅ | ❌ | ❌ |
| [DPR](model_doc/dpr) | ✅ | ✅ | ❌ |
| [DPT](model_doc/dpt) | ✅ | ❌ | ❌ |
| [EfficientFormer](model_doc/efficientformer) | ✅ | ✅ | ❌ |
| [EfficientNet](model_doc/efficientnet) | ✅ | ❌ | ❌ |
| [ELECTRA](model_doc/electra) | ✅ | ✅ | ✅ |
| [EnCodec](model_doc/encodec) | ✅ | ❌ | ❌ |
| [Encoder decoder](model_doc/encoder-decoder) | ✅ | ✅ | ✅ |
| [ERNIE](model_doc/ernie) | ✅ | ❌ | ❌ |
| [ErnieM](model_doc/ernie_m) | ✅ | ❌ | ❌ |
| [ESM](model_doc/esm) | ✅ | ✅ | ❌ |
| [FairSeq Machine-Translation](model_doc/fsmt) | ✅ | ❌ | ❌ |
| [Falcon](model_doc/falcon) | ✅ | ❌ | ❌ |
| [FalconMamba](model_doc/falcon_mamba) | ✅ | ❌ | ❌ |
| [FastSpeech2Conformer](model_doc/fastspeech2_conformer) | ✅ | ❌ | ❌ |
| [FLAN-T5](model_doc/flan-t5) | ✅ | ✅ | ✅ |
| [FLAN-UL2](model_doc/flan-ul2) | ✅ | ✅ | ✅ |
| [FlauBERT](model_doc/flaubert) | ✅ | ✅ | ❌ |
| [FLAVA](model_doc/flava) | ✅ | ❌ | ❌ |
| [FNet](model_doc/fnet) | ✅ | ❌ | ❌ |
| [FocalNet](model_doc/focalnet) | ✅ | ❌ | ❌ |
| [Funnel Transformer](model_doc/funnel) | ✅ | ✅ | ❌ |
| [Fuyu](model_doc/fuyu) | ✅ | ❌ | ❌ |
| [Gemma](model_doc/gemma) | ✅ | ❌ | ✅ |
| [Gemma2](model_doc/gemma2) | ✅ | ❌ | ❌ |
| [GIT](model_doc/git) | ✅ | ❌ | ❌ |
| [GLPN](model_doc/glpn) | ✅ | ❌ | ❌ |
| [GPT Neo](model_doc/gpt_neo) | ✅ | ❌ | ✅ |
| [GPT NeoX](model_doc/gpt_neox) | ✅ | ❌ | ❌ |
| [GPT NeoX Japanese](model_doc/gpt_neox_japanese) | ✅ | ❌ | ❌ |
| [GPT-J](model_doc/gptj) | ✅ | ✅ | ✅ |
| [GPT-Sw3](model_doc/gpt-sw3) | ✅ | ✅ | ✅ |
| [GPTBigCode](model_doc/gpt_bigcode) | ✅ | ❌ | ❌ |
| [GPTSAN-japanese](model_doc/gptsan-japanese) | ✅ | ❌ | ❌ |
| [Granite](model_doc/granite) | ✅ | ❌ | ❌ |
| [Graphormer](model_doc/graphormer) | ✅ | ❌ | ❌ |
| [Grounding DINO](model_doc/grounding-dino) | ✅ | ❌ | ❌ |
| [GroupViT](model_doc/groupvit) | ✅ | ✅ | ❌ |
| [HerBERT](model_doc/herbert) | ✅ | ✅ | ✅ |
| [Hiera](model_doc/hiera) | ✅ | ❌ | ❌ |
| [Hubert](model_doc/hubert) | ✅ | ✅ | ❌ |
| [I-BERT](model_doc/ibert) | ✅ | ❌ | ❌ |
| [IDEFICS](model_doc/idefics) | ✅ | ✅ | ❌ |
| [Idefics2](model_doc/idefics2) | ✅ | ❌ | ❌ |
| [ImageGPT](model_doc/imagegpt) | ✅ | ❌ | ❌ |
| [Informer](model_doc/informer) | ✅ | ❌ | ❌ |
| [InstructBLIP](model_doc/instructblip) | ✅ | ❌ | ❌ |
| [InstructBlipVideo](model_doc/instructblipvideo) | ✅ | ❌ | ❌ |
| [Jamba](model_doc/jamba) | ✅ | ❌ | ❌ |
| [JetMoe](model_doc/jetmoe) | ✅ | ❌ | ❌ |
| [Jukebox](model_doc/jukebox) | ✅ | ❌ | ❌ |
| [KOSMOS-2](model_doc/kosmos-2) | ✅ | ❌ | ❌ |
| [LayoutLM](model_doc/layoutlm) | ✅ | ✅ | ❌ |
| [LayoutLMv2](model_doc/layoutlmv2) | ✅ | ❌ | ❌ |
| [LayoutLMv3](model_doc/layoutlmv3) | ✅ | ✅ | ❌ |
| [LayoutXLM](model_doc/layoutxlm) | ✅ | ❌ | ❌ |
| [LED](model_doc/led) | ✅ | ✅ | ❌ |
| [LeViT](model_doc/levit) | ✅ | ❌ | ❌ |
| [LiLT](model_doc/lilt) | ✅ | ❌ | ❌ |
| [LLaMA](model_doc/llama) | ✅ | ❌ | ✅ |
| [Llama2](model_doc/llama2) | ✅ | ❌ | ✅ |
| [Llama3](model_doc/llama3) | ✅ | ❌ | ✅ |
| [LLaVa](model_doc/llava) | ✅ | ❌ | ❌ |
| [LLaVA-NeXT](model_doc/llava_next) | ✅ | ❌ | ❌ |
| [LLaVa-NeXT-Video](model_doc/llava_next_video) | ✅ | ❌ | ❌ |
| [Longformer](model_doc/longformer) | ✅ | ✅ | ❌ |
| [LongT5](model_doc/longt5) | ✅ | ❌ | ✅ |
| [LUKE](model_doc/luke) | ✅ | ❌ | ❌ |
| [LXMERT](model_doc/lxmert) | ✅ | ✅ | ❌ |
| [M-CTC-T](model_doc/mctct) | ✅ | ❌ | ❌ |
| [M2M100](model_doc/m2m_100) | ✅ | ❌ | ❌ |
| [MADLAD-400](model_doc/madlad-400) | ✅ | ✅ | ✅ |
| [Mamba](model_doc/mamba) | ✅ | ❌ | ❌ |
| [mamba2](model_doc/mamba2) | ✅ | ❌ | ❌ |
| [Marian](model_doc/marian) | ✅ | ✅ | ✅ |
| [MarkupLM](model_doc/markuplm) | ✅ | ❌ | ❌ |
| [Mask2Former](model_doc/mask2former) | ✅ | ❌ | ❌ |
| [MaskFormer](model_doc/maskformer) | ✅ | ❌ | ❌ |
| [MatCha](model_doc/matcha) | ✅ | ❌ | ❌ |
| [mBART](model_doc/mbart) | ✅ | ✅ | ✅ |
| [mBART-50](model_doc/mbart50) | ✅ | ✅ | ✅ |
| [MEGA](model_doc/mega) | ✅ | ❌ | ❌ |
| [Megatron-BERT](model_doc/megatron-bert) | ✅ | ❌ | ❌ |
| [Megatron-GPT2](model_doc/megatron_gpt2) | ✅ | ✅ | ✅ |
| [MGP-STR](model_doc/mgp-str) | ✅ | ❌ | ❌ |
| [Mistral](model_doc/mistral) | ✅ | ✅ | ✅ |
| [Mixtral](model_doc/mixtral) | ✅ | ❌ | ❌ |
| [mLUKE](model_doc/mluke) | ✅ | ❌ | ❌ |
| [MMS](model_doc/mms) | ✅ | ✅ | ✅ |
| [MobileBERT](model_doc/mobilebert) | ✅ | ✅ | ❌ |
| [MobileNetV1](model_doc/mobilenet_v1) | ✅ | ❌ | ❌ |
| [MobileNetV2](model_doc/mobilenet_v2) | ✅ | ❌ | ❌ |
| [MobileViT](model_doc/mobilevit) | ✅ | ✅ | ❌ |
| [MobileViTV2](model_doc/mobilevitv2) | ✅ | ❌ | ❌ |
| [MPNet](model_doc/mpnet) | ✅ | ✅ | ❌ |
| [MPT](model_doc/mpt) | ✅ | ❌ | ❌ |
| [MRA](model_doc/mra) | ✅ | ❌ | ❌ |
| [MT5](model_doc/mt5) | ✅ | ✅ | ✅ |
| [MusicGen](model_doc/musicgen) | ✅ | ❌ | ❌ |
| [MusicGen Melody](model_doc/musicgen_melody) | ✅ | ❌ | ❌ |
| [MVP](model_doc/mvp) | ✅ | ❌ | ❌ |
| [NAT](model_doc/nat) | ✅ | ❌ | ❌ |
| [Nemotron](model_doc/nemotron) | ✅ | ❌ | ❌ |
| [Nezha](model_doc/nezha) | ✅ | ❌ | ❌ |
| [NLLB](model_doc/nllb) | ✅ | ❌ | ❌ |
| [NLLB-MOE](model_doc/nllb-moe) | ✅ | ❌ | ❌ |
| [Nougat](model_doc/nougat) | ✅ | ✅ | ✅ |
| [Nyströmformer](model_doc/nystromformer) | ✅ | ❌ | ❌ |
| [OLMo](model_doc/olmo) | ✅ | ❌ | ❌ |
| [OneFormer](model_doc/oneformer) | ✅ | ❌ | ❌ |
| [OpenAI GPT](model_doc/openai-gpt) | ✅ | ✅ | ❌ |
| [OpenAI GPT-2](model_doc/gpt2) | ✅ | ✅ | ✅ |
| [OpenLlama](model_doc/open-llama) | ✅ | ❌ | ❌ |
| [OPT](model_doc/opt) | ✅ | ✅ | ✅ |
| [OWL-ViT](model_doc/owlvit) | ✅ | ❌ | ❌ |
| [OWLv2](model_doc/owlv2) | ✅ | ❌ | ❌ |
| [PaliGemma](model_doc/paligemma) | ✅ | ❌ | ❌ |
| [PatchTSMixer](model_doc/patchtsmixer) | ✅ | ❌ | ❌ |
| [PatchTST](model_doc/patchtst) | ✅ | ❌ | ❌ |
| [Pegasus](model_doc/pegasus) | ✅ | ✅ | ✅ |
| [PEGASUS-X](model_doc/pegasus_x) | ✅ | ❌ | ❌ |
| [Perceiver](model_doc/perceiver) | ✅ | ❌ | ❌ |
| [Persimmon](model_doc/persimmon) | ✅ | ❌ | ❌ |
| [Phi](model_doc/phi) | ✅ | ❌ | ❌ |
| [Phi3](model_doc/phi3) | ✅ | ❌ | ❌ |
| [PhoBERT](model_doc/phobert) | ✅ | ✅ | ✅ |
| [Pix2Struct](model_doc/pix2struct) | ✅ | ❌ | ❌ |
| [PLBart](model_doc/plbart) | ✅ | ❌ | ❌ |
| [PoolFormer](model_doc/poolformer) | ✅ | ❌ | ❌ |
| [Pop2Piano](model_doc/pop2piano) | ✅ | ❌ | ❌ |
| [ProphetNet](model_doc/prophetnet) | ✅ | ❌ | ❌ |
| [PVT](model_doc/pvt) | ✅ | ❌ | ❌ |
| [PVTv2](model_doc/pvt_v2) | ✅ | ❌ | ❌ |
| [QDQBert](model_doc/qdqbert) | ✅ | ❌ | ❌ |
| [Qwen2](model_doc/qwen2) | ✅ | ❌ | ❌ |
| [Qwen2Audio](model_doc/qwen2_audio) | ✅ | ❌ | ❌ |
| [Qwen2MoE](model_doc/qwen2_moe) | ✅ | ❌ | ❌ |
| [Qwen2VL](model_doc/qwen2_vl) | ✅ | ❌ | ❌ |
| [RAG](model_doc/rag) | ✅ | ✅ | ❌ |
| [REALM](model_doc/realm) | ✅ | ❌ | ❌ |
| [RecurrentGemma](model_doc/recurrent_gemma) | ✅ | ❌ | ❌ |
| [Reformer](model_doc/reformer) | ✅ | ❌ | ❌ |
| [RegNet](model_doc/regnet) | ✅ | ✅ | ✅ |
| [RemBERT](model_doc/rembert) | ✅ | ✅ | ❌ |
| [ResNet](model_doc/resnet) | ✅ | ✅ | ✅ |
| [RetriBERT](model_doc/retribert) | ✅ | ❌ | ❌ |
| [RoBERTa](model_doc/roberta) | ✅ | ✅ | ✅ |
| [RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm) | ✅ | ✅ | ✅ |
| [RoCBert](model_doc/roc_bert) | ✅ | ❌ | ❌ |
| [RoFormer](model_doc/roformer) | ✅ | ✅ | ✅ |
| [RT-DETR](model_doc/rt_detr) | ✅ | ❌ | ❌ |
| [RT-DETR-ResNet](model_doc/rt_detr_resnet) | ✅ | ❌ | ❌ |
| [RWKV](model_doc/rwkv) | ✅ | ❌ | ❌ |
| [SAM](model_doc/sam) | ✅ | ✅ | ❌ |
| [SeamlessM4T](model_doc/seamless_m4t) | ✅ | ❌ | ❌ |
| [SeamlessM4Tv2](model_doc/seamless_m4t_v2) | ✅ | ❌ | ❌ |
| [SegFormer](model_doc/segformer) | ✅ | ✅ | ❌ |
| [SegGPT](model_doc/seggpt) | ✅ | ❌ | ❌ |
| [SEW](model_doc/sew) | ✅ | ❌ | ❌ |
| [SEW-D](model_doc/sew-d) | ✅ | ❌ | ❌ |
| [SigLIP](model_doc/siglip) | ✅ | ❌ | ❌ |
| [Speech Encoder decoder](model_doc/speech-encoder-decoder) | ✅ | ❌ | ✅ |
| [Speech2Text](model_doc/speech_to_text) | ✅ | ✅ | ❌ |
| [SpeechT5](model_doc/speecht5) | ✅ | ❌ | ❌ |
| [Splinter](model_doc/splinter) | ✅ | ❌ | ❌ |
| [SqueezeBERT](model_doc/squeezebert) | ✅ | ❌ | ❌ |
| [StableLm](model_doc/stablelm) | ✅ | ❌ | ❌ |
| [Starcoder2](model_doc/starcoder2) | ✅ | ❌ | ❌ |
| [SuperPoint](model_doc/superpoint) | ✅ | ❌ | ❌ |
| [SwiftFormer](model_doc/swiftformer) | ✅ | ✅ | ❌ |
| [Swin Transformer](model_doc/swin) | ✅ | ✅ | ❌ |
| [Swin Transformer V2](model_doc/swinv2) | ✅ | ❌ | ❌ |
| [Swin2SR](model_doc/swin2sr) | ✅ | ❌ | ❌ |
| [SwitchTransformers](model_doc/switch_transformers) | ✅ | ❌ | ❌ |
| [T5](model_doc/t5) | ✅ | ✅ | ✅ |
| [T5v1.1](model_doc/t5v1.1) | ✅ | ✅ | ✅ |
| [Table Transformer](model_doc/table-transformer) | ✅ | ❌ | ❌ |
| [TAPAS](model_doc/tapas) | ✅ | ✅ | ❌ |
| [TAPEX](model_doc/tapex) | ✅ | ✅ | ✅ |
| [Time Series Transformer](model_doc/time_series_transformer) | ✅ | ❌ | ❌ |
| [TimeSformer](model_doc/timesformer) | ✅ | ❌ | ❌ |
| [Trajectory Transformer](model_doc/trajectory_transformer) | ✅ | ❌ | ❌ |
| [Transformer-XL](model_doc/transfo-xl) | ✅ | ✅ | ❌ |
| [TrOCR](model_doc/trocr) | ✅ | ❌ | ❌ |
| [TVLT](model_doc/tvlt) | ✅ | ❌ | ❌ |
| [TVP](model_doc/tvp) | ✅ | ❌ | ❌ |
| [UDOP](model_doc/udop) | ✅ | ❌ | ❌ |
| [UL2](model_doc/ul2) | ✅ | ✅ | ✅ |
| [UMT5](model_doc/umt5) | ✅ | ❌ | ❌ |
| [UniSpeech](model_doc/unispeech) | ✅ | ❌ | ❌ |
| [UniSpeechSat](model_doc/unispeech-sat) | ✅ | ❌ | ❌ |
| [UnivNet](model_doc/univnet) | ✅ | ❌ | ❌ |
| [UPerNet](model_doc/upernet) | ✅ | ❌ | ❌ |
| [VAN](model_doc/van) | ✅ | ❌ | ❌ |
| [VideoLlava](model_doc/video_llava) | ✅ | ❌ | ❌ |
| [VideoMAE](model_doc/videomae) | ✅ | ❌ | ❌ |
| [ViLT](model_doc/vilt) | ✅ | ❌ | ❌ |
| [VipLlava](model_doc/vipllava) | ✅ | ❌ | ❌ |
| [Vision Encoder decoder](model_doc/vision-encoder-decoder) | ✅ | ✅ | ✅ |
| [VisionTextDualEncoder](model_doc/vision-text-dual-encoder) | ✅ | ✅ | ✅ |
| [VisualBERT](model_doc/visual_bert) | ✅ | ❌ | ❌ |
| [ViT](model_doc/vit) | ✅ | ✅ | ✅ |
| [ViT Hybrid](model_doc/vit_hybrid) | ✅ | ❌ | ❌ |
| [VitDet](model_doc/vitdet) | ✅ | ❌ | ❌ |
| [ViTMAE](model_doc/vit_mae) | ✅ | ✅ | ❌ |
| [ViTMatte](model_doc/vitmatte) | ✅ | ❌ | ❌ |
| [ViTMSN](model_doc/vit_msn) | ✅ | ❌ | ❌ |
| [VITS](model_doc/vits) | ✅ | ❌ | ❌ |
| [ViViT](model_doc/vivit) | ✅ | ❌ | ❌ |
| [Wav2Vec2](model_doc/wav2vec2) | ✅ | ✅ | ✅ |
| [Wav2Vec2-BERT](model_doc/wav2vec2-bert) | ✅ | ❌ | ❌ |
| [Wav2Vec2-Conformer](model_doc/wav2vec2-conformer) | ✅ | ❌ | ❌ |
| [Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme) | ✅ | ✅ | ✅ |
| [WavLM](model_doc/wavlm) | ✅ | ❌ | ❌ |
| [Whisper](model_doc/whisper) | ✅ | ✅ | ✅ |
| [X-CLIP](model_doc/xclip) | ✅ | ❌ | ❌ |
| [X-MOD](model_doc/xmod) | ✅ | ❌ | ❌ |
| [XGLM](model_doc/xglm) | ✅ | ✅ | ✅ |
| [XLM](model_doc/xlm) | ✅ | ✅ | ❌ |
| [XLM-ProphetNet](model_doc/xlm-prophetnet) | ✅ | ❌ | ❌ |
| [XLM-RoBERTa](model_doc/xlm-roberta) | ✅ | ✅ | ✅ |
| [XLM-RoBERTa-XL](model_doc/xlm-roberta-xl) | ✅ | ❌ | ❌ |
| [XLM-V](model_doc/xlm-v) | ✅ | ✅ | ✅ |
| [XLNet](model_doc/xlnet) | ✅ | ✅ | ❌ |
| [XLS-R](model_doc/xls_r) | ✅ | ✅ | ✅ |
| [XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2) | ✅ | ✅ | ✅ |
| [YOLOS](model_doc/yolos) | ✅ | ❌ | ❌ |
| [YOSO](model_doc/yoso) | ✅ | ❌ | ❌ |
| [ZoeDepth](model_doc/zoedepth) | ✅ | ❌ | ❌ |
---
### Source De Index (`docs/source/de/index.md`)
# 🤗 Transformers
Maschinelles Lernen auf dem neuesten Stand der Technik für PyTorch, TensorFlow und JAX.
🤗 Transformers bietet APIs zum einfachen Herunterladen und Trainieren von vortrainierten Modellen auf dem neuesten Stand der Technik. Die Verwendung von vortrainierten Modellen kann Rechenkosten sparen und den CO2-Fußabdruck reduzieren und Zeit sparen, die für das Training eines Modells von Grund auf benötigt wird. Die Modelle können für verschiedene Modalitäten verwendet werden, wie z. B.:
* 📝 Text: Textklassifizierung, Informationsextrahierung, Beantwortung von Fragen, Zusammenfassung, Übersetzung und Texterstellung in über 100 Sprachen.
* 🖼️ Bilder: Bildklassifizierung, Objekterkennung und Segmentierung.
* 🗣️ Audio: Spracherkennung und Audioklassifizierung.
* 🐙 Multimodal: Beantwortung von Tabellenfragen, optische Zeichenerkennung, Informationsextraktion aus gescannten Dokumenten, Videoklassifizierung und Beantwortung visueller Fragen.
Unsere Bibliothek unterstützt die nahtlose Integration von drei der beliebtesten Deep-Learning-Bibliotheken: [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) und [JAX](https://jax.readthedocs.io/en/latest/). Trainieren Sie Ihr Modell in drei Codezeilen in einem Framework und laden Sie es zur Inferenz mit einem anderen.
Jede 🤗 Transformers-Architektur ist in einem eigenständigen Python-Modul definiert, so dass sie leicht für Forschung und Experimente angepasst werden kann.
## Wenn Sie auf der Suche nach individueller Unterstützung durch das Hugging Face-Team sind
## Inhalt
Die Dokumentation ist in fünf Teile gegliedert:
- **GET STARTED** enthält eine kurze Tour und Installationsanweisungen, um mit 🤗 Transformers loszulegen.
- **TUTORIALS** sind ein hervorragender Ausgangspunkt, wenn Sie neu in unserer Bibliothek sind. Dieser Abschnitt hilft Ihnen, die grundlegenden Fähigkeiten zu erlangen, die Sie benötigen, um mit 🤗 Transformers zu arbeiten.
- **HOW-TO GUIDES** zeigen Ihnen, wie Sie ein bestimmtes Ziel erreichen können, z. B. die Feinabstimmung eines vortrainierten Modells für die Sprachmodellierung oder die Erstellung eines benutzerdefinierten Modellkopfs.
- **KONZEPTUELLE ANLEITUNGEN** bietet weitere Diskussionen und Erklärungen zu den zugrunde liegenden Konzepten und Ideen hinter Modellen, Aufgaben und der Designphilosophie von 🤗 Transformers.
- **API** beschreibt jede Klasse und Funktion, gruppiert in:
- **MAIN CLASSES** für die Hauptklassen, die die wichtigsten APIs der Bibliothek darstellen.
- MODELLE** für die Klassen und Funktionen, die zu jedem in der Bibliothek implementierten Modell gehören.
- **INTERNAL HELPERS** für die Klassen und Funktionen, die wir intern verwenden.
Die Bibliothek enthält derzeit JAX-, PyTorch- und TensorFlow-Implementierungen, vortrainierte Modellgewichte, Nutzungsskripte und Konvertierungsprogramme für die folgenden Modelle.
### Unterstütze Modelle
1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://huggingface.co/papers/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
1. **[ALIGN](model_doc/align)** (from Google Research) released with the paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://huggingface.co/papers/2102.05918) by Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://huggingface.co/papers/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://huggingface.co/papers/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://huggingface.co/papers/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://huggingface.co/papers/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://huggingface.co/papers/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://huggingface.co/papers/2010.10499) by Adrian de Wynter and Daniel J. Perry.
1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://huggingface.co/papers/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://huggingface.co/papers/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://huggingface.co/papers/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://huggingface.co/papers/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://huggingface.co/papers/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://huggingface.co/papers/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://huggingface.co/papers/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://huggingface.co/papers/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://huggingface.co/papers/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://huggingface.co/papers/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://huggingface.co/papers/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://huggingface.co/papers/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://huggingface.co/papers/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://huggingface.co/papers/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://huggingface.co/papers/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://huggingface.co/papers/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://huggingface.co/papers/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers-research-projects/tree/main/distillation) and a German version of DistilBERT.
1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://huggingface.co/papers/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://huggingface.co/papers/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://huggingface.co/papers/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://huggingface.co/papers/1905.11946) by Mingxing Tan and Quoc V. Le.
1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://huggingface.co/papers/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://huggingface.co/papers/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://huggingface.co/papers/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://huggingface.co/papers/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://huggingface.co/papers/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://huggingface.co/papers/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://huggingface.co/papers/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://huggingface.co/papers/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://huggingface.co/papers/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://huggingface.co/papers/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://huggingface.co/papers/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://huggingface.co/papers/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://huggingface.co/papers/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://huggingface.co/papers/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://huggingface.co/papers/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://huggingface.co/papers/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://huggingface.co/papers/1908.07490) by Hao Tan and Mohit Bansal.
1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://huggingface.co/papers/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://huggingface.co/papers/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://huggingface.co/papers/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://huggingface.co/papers/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://huggingface.co/papers/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://huggingface.co/papers/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://huggingface.co/papers/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://huggingface.co/papers/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://huggingface.co/papers/2110.02178) by Sachin Mehta and Mohammad Rastegari.
1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://huggingface.co/papers/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://huggingface.co/papers/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://huggingface.co/papers/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://huggingface.co/papers/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://huggingface.co/papers/2207.04672) by the NLLB team.
1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://huggingface.co/papers/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://huggingface.co/papers/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://huggingface.co/papers/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://huggingface.co/papers/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://huggingface.co/papers/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://huggingface.co/papers/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://huggingface.co/papers/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://huggingface.co/papers/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://huggingface.co/papers/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://huggingface.co/papers/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://huggingface.co/papers/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://huggingface.co/papers/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://huggingface.co/papers/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://huggingface.co/papers/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://huggingface.co/papers/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://huggingface.co/papers/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://huggingface.co/papers/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://huggingface.co/papers/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://huggingface.co/papers/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://huggingface.co/papers/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://huggingface.co/papers/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://huggingface.co/papers/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://huggingface.co/papers/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://huggingface.co/papers/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://huggingface.co/papers/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://huggingface.co/papers/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://huggingface.co/papers/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://huggingface.co/papers/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://huggingface.co/papers/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://huggingface.co/papers/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://huggingface.co/papers/2205.05131) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
1. **[UMT5](model_doc/umt5)** (from Google Research) released with the paper [UniMax: Fairer and More Effective Language Sampling for Large-Scale Multilingual Pretraining](https://openreview.net/forum?id=kXwdL1cWOAi) by Hyung Won Chung, Xavier Garcia, Adam Roberts, Yi Tay, Orhan Firat, Sharan Narang, Noah Constant.
1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://huggingface.co/papers/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://huggingface.co/papers/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://huggingface.co/papers/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://huggingface.co/papers/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://huggingface.co/papers/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://huggingface.co/papers/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://huggingface.co/papers/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://huggingface.co/papers/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://huggingface.co/papers/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://huggingface.co/papers/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://huggingface.co/papers/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://huggingface.co/papers/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://huggingface.co/papers/1901.07291) by Guillaume Lample and Alexis Conneau.
1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://huggingface.co/papers/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://huggingface.co/papers/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
1. **[XLM-V](model_doc/xlm-v)** (from Meta AI) released with the paper [XLM-V: Overcoming the Vocabulary Bottleneck in Multilingual Masked Language Models](https://huggingface.co/papers/2301.10472) by Davis Liang, Hila Gonen, Yuning Mao, Rui Hou, Naman Goyal, Marjan Ghazvininejad, Luke Zettlemoyer, Madian Khabsa.
1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://huggingface.co/papers/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://huggingface.co/papers/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://huggingface.co/papers/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://huggingface.co/papers/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://huggingface.co/papers/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
### Unterstützte Frameworks
Die folgende Tabelle zeigt die derzeitige Unterstützung in der Bibliothek für jedes dieser Modelle, unabhängig davon, ob sie einen Python
Tokenizer haben (als "langsam" bezeichnet), ein "schneller" Tokenizer, der von der 🤗 Tokenizers Bibliothek unterstützt wird, ob sie Unterstützung in Jax (via
Flax), PyTorch, und/oder TensorFlow haben.
| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
| BLOOM | ❌ | ✅ | ✅ | ❌ | ✅ |
| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
| CvT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
| GroupViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
| LayoutLMv3 | ✅ | ✅ | ✅ | ❌ | ❌ |
| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| MobileViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
---
### Source En Index (`docs/source/en/index.md`)
# Transformers
Transformers acts as the model-definition framework for state-of-the-art machine learning models in text, computer
vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. `transformers` is the
pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training
frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...),
and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from `transformers`.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be
simple, customizable, and efficient.
There are over 1M+ Transformers [model checkpoints](https://huggingface.co/models?library=transformers&sort=trending) on the [Hugging Face Hub](https://huggingface.com/models) you can use.
Explore the [Hub](https://huggingface.com/) today to find a model and use Transformers to help you get started right away.
Explore the [Models Timeline](./models_timeline) to discover the latest text, vision, audio and multimodal model architectures in Transformers.
## Features
Transformers provides everything you need for inference or training with state-of-the-art pretrained models. Some of the main features include:
- [Pipeline](./pipeline_tutorial): Simple and optimized inference class for many machine learning tasks like text generation, image segmentation, automatic speech recognition, document question answering, and more.
- [Trainer](./trainer): A comprehensive trainer that supports features such as mixed precision, torch.compile, and FlashAttention for training and distributed training for PyTorch models.
- [generate](./llm_tutorial): Fast text generation with large language models (LLMs) and vision language models (VLMs), including support for streaming and multiple decoding strategies.
## Design
> [!TIP]
> Read our [Philosophy](./philosophy) to learn more about Transformers' design principles.
Transformers is designed for developers and machine learning engineers and researchers. Its main design principles are:
1. Fast and easy to use: Every model is implemented from only three main classes (configuration, model, and preprocessor) and can be quickly used for inference or training with [`Pipeline`] or [`Trainer`].
2. Pretrained models: Reduce your carbon footprint, compute cost and time by using a pretrained model instead of training an entirely new one. Each pretrained model is reproduced as closely as possible to the original model and offers state-of-the-art performance.
## Learn
If you're new to Transformers or want to learn more about transformer models, we recommend starting with the [LLM course](https://huggingface.co/learn/llm-course/chapter1/1?fw=pt). This comprehensive course covers everything from the fundamentals of how transformer models work to practical applications across various tasks. You'll learn the complete workflow, from curating high-quality datasets to fine-tuning large language models and implementing reasoning capabilities. The course contains both theoretical and hands-on exercises to build a solid foundational knowledge of transformer models as you learn.
---
### Source En Optimization Overview (`docs/source/en/optimization_overview.md`)
# Overview
Transformers provides multiple inference optimization techniques to make models fast, affordable, and accessible. Options include alternative attention mechanisms for reduced memory traffic, code compilation for faster execution, and optimized kernels for throughput. Stack these techniques for maximum performance.
For device setup and hardware-specific configuration, see the [Hardware](./hardware) guides. Check which techniques are supported on your hardware before applying the optimizations below.
> [!NOTE]
> Memory and speed are closely related but not the same. Shrinking your memory footprint makes a model "faster" because there is less data to move around. Pure speed optimizations don't always reduce memory and sometimes increase usage. Choose the appropriate optimization based on your use case and hardware.
Use the table below to pick an optimization technique.
| Technique | Speed | Memory |
|---|:---:|:---:|
| [Compilation](#compilation) | ✅ | |
| [Attention backends](#attention-backends) | ✅ | ✅ |
| [Kernels](#kernels) | ✅ | ✅ |
| [Quantization](#quantization) | ✅ | ✅ |
| [Caching](#caching) | ✅ | ✅ |
| [Parallelism](#parallelism) | ✅ | |
| [Continuous batching](#continuous-batching) | ✅ | |
This guide gives you a quick start on Transformers optimizations.
## Compilation
[torch.compile](./perf_torch_compile) reduces Python overhead, fuses operations, and creates kernels tuned for your shapes and hardware. The first run warms it up and subsequent runs use the faster compiled path.
Pass a [fixed size cache](./kv_cache#fixed-size-cache) to [`~GenerationMixin.generate`] to trigger `torch.compile` automatically.
```py
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen3-0.6B")
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen3-0.6B", dtype=torch.float16, device_map="auto")
input = tokenizer("The French Bread Law states", return_tensors="pt").to(model.device)
output = model.generate(**input, do_sample=False, max_new_tokens=20, cache_implementation="static")
tokenizer.batch_decode(output, skip_special_tokens=True)[0]
```
> [!WARNING]
> Avoid calling `torch.compile(model)` outside of [`~GenerationMixin.generate`] to prevent the model from recompiling every step.
## Attention backends
Alternative [attention backends](./attention_interface) lower memory traffic. For example, FlashAttention tiles attention computations and avoids large intermediate tensors to reduce memory footprint.
Set `attn_implementation` in [`~PreTrainedModel.from_pretrained`] to load an optimized attention backend.
```py
from transformers import AutoModelForCausalLM
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen3-0.6B", attn_implementation="flash_attention_2")
```
## Kernels
Kernels fuse operations to boost throughput and reduce memory usage. The [Kernels](https://huggingface.co/docs/kernels/en/index) library loads optimized compute kernels from the [Hub](https://huggingface.co/kernels-community) in a flexible and version-safe way.
The example below loads an optimized FlashAttention-2 kernel without installing the package.
```py
import torch
from transformers import AutoModelForCausalLM
model = AutoModelForCausalLM.from_pretrained(
"Qwen/Qwen3-0.6B", attn_implementation="kernels-community/flash-attn2"
)
```
## Quantization
[Quantization](./quantization/overview) shrinks the size of every parameter which lowers memory footprint and increases speed because you can do more operations.
Pass a quantization config to the `quantization_config` argument in [`~PreTrainedModel.from_pretrained`]. Each quantization backend has a different config with different arguments. The example below quantizes a model to 4-bits and configures the computation dtype with the [bitsandbytes](./quantization/bitsandbytes) backend.
```py
import torch
from transformers import AutoModelForCausalLM, BitsAndBytesConfig
bnb_config = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16)
model = AutoModelForCausalLM.from_pretrained(
"allenai/Olmo-3-7B-Think", quantization_config=bnb_config
)
```
## Caching
[Caching](./kv_cache) speeds up generation by reusing past keys and values instead of recomputing them for every token. To offset and reduce the memory cost of storing past keys and values, Transformers
supports offloading the cache to the CPU. Only the current layer remains on the GPU.
Use the `cache_implementation` argument in [`~GenerationMixin.generate`] to set a cache strategy.
```py
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen3-0.6B")
model = AutoModelForCausalLM.from_pretrained(
"Qwen/Qwen3-0.6B", attn_implementation="kernels-community/flash-attn2"
)
inputs = tokenizer("The Le Décret Pain states that a baguette must,", return_tensors="pt")
outputs = model.generate(**inputs, do_sample=False, max_new_tokens=50, cache_implementation="offloaded")
```
## Parallelism
[Parallelism](./perf_infer_gpu_multi) distributes a model across devices so models too big for one device run fast. This approach uses more memory due to sharding overhead and communication to sync results.
[Tensor parallelism](./perf_infer_gpu_multi) splits a model layer across devices. Set the number of devices with `DistributedConfig(tp_size=N)` and pass it to [`~PreTrainedModel.from_pretrained`] to enable it.
```py
from transformers import AutoModelForCausalLM, DistributedConfig
distributed_config = DistributedConfig(tp_size=4)
model = AutoModelForCausalLM.from_pretrained(
"meta-llama/Meta-Llama-3-8B-Instruct",
distributed_config=distributed_config,
)
print(model._tp_plan)
```
## Continuous batching
[Continuous batching](./continuous_batching) maximizes throughput by keeping the GPU busy with dynamic scheduling and chunked prefill. [Serving](./serve-cli/serving) applications use it to process multiple incoming requests concurrently.
Use [`~ContinuousMixin.generate_batch`] to enable continuous batching.
```py
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer
from transformers.generation import ContinuousBatchingConfig, GenerationConfig
model = AutoModelForCausalLM.from_pretrained(
"Qwen/Qwen3-0.6B",
attn_implementation="sdpa",
device_map="auto",
torch_dtype=torch.bfloat16,
)
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen3-0.6B")
prompts = [
"The Le Décret Pain states that a baguette must",
"Explain gravity in one sentence.",
"Name the capital of France.",
]
inputs = [tokenizer.encode(p) for p in prompts]
generation_config = GenerationConfig(
max_new_tokens=32,
eos_token_id=tokenizer.eos_token_id,
pad_token_id=tokenizer.pad_token_id,
do_sample=False,
)
continuous_batching_config = ContinuousBatchingConfig(max_batch_tokens=512)
outputs = model.generate_batch(
inputs=inputs,
generation_config=generation_config,
continuous_batching_config=continuous_batching_config,
)
for request_id, output in outputs.items():
text = tokenizer.decode(output.generated_tokens, skip_special_tokens=True)
print(f"[{request_id}] {text}")
```
---
### Source Es Index (`docs/source/es/index.md`)
# 🤗 Transformers
Machine Learning de última generación para PyTorch, TensorFlow y JAX.
🤗 Transformers proporciona APIs para descargar y entrenar fácilmente modelos preentrenados de última generación. El uso de modelos preentrenados puede reducir tus costos de cómputo, tu huella de carbono y ahorrarte tiempo al entrenar un modelo desde cero. Los modelos se pueden utilizar en diferentes modalidades, tales como:
* 📝 Texto: clasificación de texto, extracción de información, respuesta a preguntas, resumir, traducción y generación de texto en más de 100 idiomas.
* 🖼️ Imágenes: clasificación de imágenes, detección de objetos y segmentación.
* 🗣️ Audio: reconocimiento de voz y clasificación de audio.
* 🐙 Multimodal: respuesta a preguntas en tablas, reconocimiento óptico de caracteres, extracción de información de documentos escaneados, clasificación de videos y respuesta visual a preguntas.
Nuestra biblioteca admite una integración perfecta entre tres de las bibliotecas de deep learning más populares: [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) y [JAX](https://jax.readthedocs.io/en/latest/). Entrena tu modelo con tres líneas de código en un framework y cárgalo para inferencia con otro.
Cada arquitectura de 🤗 Transformers se define en un módulo de Python independiente para que se puedan personalizar fácilmente para investigación y experimentos.
## Si estás buscando soporte personalizado del equipo de Hugging Face
## Contenidos
La documentación está organizada en cuatro partes:
- **EMPEZAR** contiene un recorrido rápido e instrucciones de instalación para comenzar a usar 🤗 Transformers.
- **TUTORIALES** es un excelente lugar para comenzar. Esta sección te ayudará a obtener las habilidades básicas que necesitas para comenzar a usar 🤗 Transformers.
- **GUÍAS PRÁCTICAS** te mostrará cómo lograr un objetivo específico, cómo hacer fine-tuning a un modelo preentrenado para el modelado de lenguaje o cómo crear un cabezal para un modelo personalizado.
- **GUÍAS CONCEPTUALES** proporciona más discusión y explicación de los conceptos e ideas subyacentes detrás de los modelos, las tareas y la filosofía de diseño de 🤗 Transformers.
La biblioteca actualmente contiene implementaciones de JAX, PyTorch y TensorFlow, pesos de modelos preentrenados, scripts de uso y utilidades de conversión para los siguientes modelos.
### Modelos compatibles
1. **[ALBERT](model_doc/albert)** (de Google Research y el Instituto Tecnológico de Toyota en Chicago) publicado con el paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://huggingface.co/papers/1909.11942), por Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
1. **[ALIGN](model_doc/align)** (de Google Research) publicado con el paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://huggingface.co/papers/2102.05918) por Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
1. **[BART](model_doc/bart)** (de Facebook) publicado con el paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://huggingface.co/papers/1910.13461) por Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov y Luke Zettlemoyer.
1. **[BARThez](model_doc/barthez)** (de École polytechnique) publicado con el paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://huggingface.co/papers/2010.12321) por Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
1. **[BARTpho](model_doc/bartpho)** (de VinAI Research) publicado con el paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://huggingface.co/papers/2109.09701) por Nguyen Luong Tran, Duong Minh Le y Dat Quoc Nguyen.
1. **[BEiT](model_doc/beit)** (de Microsoft) publicado con el paper [BEiT: BERT Pre-Training of Image Transformers](https://huggingface.co/papers/2106.08254) por Hangbo Bao, Li Dong, Furu Wei.
1. **[BERT](model_doc/bert)** (de Google) publicado con el paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://huggingface.co/papers/1810.04805) por Jacob Devlin, Ming-Wei Chang, Kenton Lee y Kristina Toutanova.
1. **[BERTweet](model_doc/bertweet)** (de VinAI Research) publicado con el paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) por Dat Quoc Nguyen, Thanh Vu y Anh Tuan Nguyen.
1. **[BERT For Sequence Generation](model_doc/bert-generation)** (de Google) publicado con el paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) por Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[BigBird-RoBERTa](model_doc/big_bird)** (de Google Research) publicado con el paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) por Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (de Google Research) publicado con el paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) por Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[Blenderbot](model_doc/blenderbot)** (de Facebook) publicado con el paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) por Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BlenderbotSmall](model_doc/blenderbot-small)** (de Facebook) publicado con el paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) por Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BORT](model_doc/bort)** (de Alexa) publicado con el paper [Optimal Subarchitecture Extraction For BERT](https://huggingface.co/papers/2010.10499) por Adrian de Wynter y Daniel J. Perry.
1. **[ByT5](model_doc/byt5)** (de Google Research) publicado con el paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://huggingface.co/papers/2105.13626) por Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
1. **[CamemBERT](model_doc/camembert)** (de Inria/Facebook/Sorbonne) publicado con el paper [CamemBERT: a Tasty French Language Model](https://huggingface.co/papers/1911.03894) por Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah y Benoît Sagot.
1. **[CANINE](model_doc/canine)** (de Google Research) publicado con el paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://huggingface.co/papers/2103.06874) por Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
1. **[ConvNeXT](model_doc/convnext)** (de Facebook AI) publicado con el paper [A ConvNet for the 2020s](https://huggingface.co/papers/2201.03545) por Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
1. **[ConvNeXTV2](model_doc/convnextv2)** (de Facebook AI) publicado con el paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://huggingface.co/papers/2301.00808) por Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
1. **[CLIP](model_doc/clip)** (de OpenAI) publicado con el paper [Learning Transferable Visual Models From Natural Language Supervision](https://huggingface.co/papers/2103.00020) por Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
1. **[ConvBERT](model_doc/convbert)** (de YituTech) publicado con el paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://huggingface.co/papers/2008.02496) por Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
1. **[CPM](model_doc/cpm)** (de Universidad de Tsinghua) publicado con el paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://huggingface.co/papers/2012.00413) por Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
1. **[CTRL](model_doc/ctrl)** (de Salesforce) publicado con el paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://huggingface.co/papers/1909.05858) por Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong y Richard Socher.
1. **[Data2Vec](model_doc/data2vec)** (de Facebook) publicado con el paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://huggingface.co/papers/2202.03555) por Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
1. **[DeBERTa](model_doc/deberta)** (de Microsoft) publicado con el paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) por Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[DeBERTa-v2](model_doc/deberta-v2)** (de Microsoft) publicado con el paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) por Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[Decision Transformer](model_doc/decision_transformer)** (de Berkeley/Facebook/Google) publicado con el paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://huggingface.co/papers/2106.01345) por Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
1. **[DiT](model_doc/dit)** (de Microsoft Research) publicado con el paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://huggingface.co/papers/2203.02378) por Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
1. **[DeiT](model_doc/deit)** (de Facebook) publicado con el paper [Training data-efficient image transformers & distillation through attention](https://huggingface.co/papers/2012.12877) por Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
1. **[DETR](model_doc/detr)** (de Facebook) publicado con el paper [End-to-End Object Detection with Transformers](https://huggingface.co/papers/2005.12872) por Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
1. **[DialoGPT](model_doc/dialogpt)** (de Microsoft Research) publicado con el paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://huggingface.co/papers/1911.00536) por Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
1. **[DistilBERT](model_doc/distilbert)** (de HuggingFace), publicado junto con el paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://huggingface.co/papers/1910.01108) por Victor Sanh, Lysandre Debut y Thomas Wolf. Se ha aplicado el mismo método para comprimir GPT2 en [DistilGPT2](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), RoBERTa en [DistilRoBERTa](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), BERT multilingüe en [DistilmBERT](https://github.com/huggingface/transformers-research-projects/tree/main/distillation) y una versión alemana de DistilBERT.
1. **[DPR](model_doc/dpr)** (de Facebook) publicado con el paper [Dense Passage Retrieval for Open-Domain Question Answering](https://huggingface.co/papers/2004.04906) por Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, y Wen-tau Yih.
1. **[DPT](master/model_doc/dpt)** (de Intel Labs) publicado con el paper [Vision Transformers for Dense Prediction](https://huggingface.co/papers/2103.13413) por René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://huggingface.co/papers/1905.11946) by Mingxing Tan and Quoc V. Le.
1. **[EncoderDecoder](model_doc/encoder-decoder)** (de Google Research) publicado con el paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) por Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[ELECTRA](model_doc/electra)** (de Google Research/Universidad de Stanford) publicado con el paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://huggingface.co/papers/2003.10555) por Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
1. **[FlauBERT](model_doc/flaubert)** (de CNRS) publicado con el paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://huggingface.co/papers/1912.05372) por Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
1. **[FNet](model_doc/fnet)** (de Google Research) publicado con el paper [FNet: Mixing Tokens with Fourier Transforms](https://huggingface.co/papers/2105.03824) por James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
1. **[Funnel Transformer](model_doc/funnel)** (de CMU/Google Brain) publicado con el paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://huggingface.co/papers/2006.03236) por Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
1. **[GLPN](model_doc/glpn)** (de KAIST) publicado con el paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436) por Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
1. **[GPT](model_doc/openai-gpt)** (de OpenAI) publicado con el paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) por Alec Radford, Karthik Narasimhan, Tim Salimans y Ilya Sutskever.
1. **[GPT-2](model_doc/gpt2)** (de OpenAI) publicado con el paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) por Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei y Ilya Sutskever.
1. **[GPT-J](model_doc/gptj)** (de EleutherAI) publicado con el repositorio [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) por Ben Wang y Aran Komatsuzaki.
1. **[GPT Neo](model_doc/gpt_neo)** (de EleutherAI) publicado en el paper [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) por Sid Black, Stella Biderman, Leo Gao, Phil Wang y Connor Leahy.
1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released with [GPTSAN](https://github.com/tanreinama/GPTSAN) by Toshiyuki Sakamoto (tanreinama).
1. **[Hubert](model_doc/hubert)** (de Facebook) publicado con el paper [HuBERT: Self-Supervised Speech Representation Learning por Masked Prediction of Hidden Units](https://huggingface.co/papers/2106.07447) por Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
1. **[I-BERT](model_doc/ibert)** (de Berkeley) publicado con el paper [I-BERT: Integer-only BERT Quantization](https://huggingface.co/papers/2101.01321) por Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
1. **[ImageGPT](model_doc/imagegpt)** (de OpenAI) publicado con el paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) por Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
1. **[LayoutLM](model_doc/layoutlm)** (de Microsoft Research Asia) publicado con el paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://huggingface.co/papers/1912.13318) por Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
1. **[LayoutLMv2](model_doc/layoutlmv2)** (de Microsoft Research Asia) publicado con el paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://huggingface.co/papers/2012.14740) por Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
1. **[LayoutXLM](model_doc/layoutxlm)** (de Microsoft Research Asia) publicado con el paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://huggingface.co/papers/2104.08836) por Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
1. **[LED](model_doc/led)** (de AllenAI) publicado con el paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) por Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[Longformer](model_doc/longformer)** (de AllenAI) publicado con el paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) por Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LUKE](model_doc/luke)** (de Studio Ousia) publicado con el paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://huggingface.co/papers/2010.01057) por Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
1. **[mLUKE](model_doc/mluke)** (de Studio Ousia) publicado con el paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://huggingface.co/papers/2110.08151) por Ryokan Ri, Ikuya Yamada, y Yoshimasa Tsuruoka.
1. **[LXMERT](model_doc/lxmert)** (de UNC Chapel Hill) publicado con el paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://huggingface.co/papers/1908.07490) por Hao Tan y Mohit Bansal.
1. **[M2M100](model_doc/m2m_100)** (de Facebook) publicado con el paper [Beyond English-Centric Multilingual Machine Translation](https://huggingface.co/papers/2010.11125) por Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
1. **[MarianMT](model_doc/marian)** Modelos de traducción automática entrenados usando [OPUS](http://opus.nlpl.eu/) data por Jörg Tiedemann. El [Marian Framework](https://marian-nmt.github.io/) está siendo desarrollado por el equipo de traductores de Microsoft.
1. **[Mask2Former](model_doc/mask2former)** (de FAIR y UIUC) publicado con el paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://huggingface.co/papers/2112.01527) por Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
1. **[MaskFormer](model_doc/maskformer)** (de Meta y UIUC) publicado con el paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://huggingface.co/papers/2107.06278) por Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
1. **[MBart](model_doc/mbart)** (de Facebook) publicado con el paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://huggingface.co/papers/2001.08210) por Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
1. **[MBart-50](model_doc/mbart)** (de Facebook) publicado con el paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://huggingface.co/papers/2008.00401) por Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
1. **[Megatron-BERT](model_doc/megatron-bert)** (de NVIDIA) publicado con el paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) por Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper y Bryan Catanzaro.
1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (de NVIDIA) publicado con el paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) por Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper y Bryan Catanzaro.
1. **[MPNet](model_doc/mpnet)** (de Microsoft Research) publicado con el paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://huggingface.co/papers/2004.09297) por Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
1. **[MT5](model_doc/mt5)** (de Google AI) publicado con el paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://huggingface.co/papers/2010.11934) por Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
1. **[Nyströmformer](model_doc/nystromformer)** (de la Universidad de Wisconsin - Madison) publicado con el paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://huggingface.co/papers/2102.03902) por Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
1. **[OneFormer](model_doc/oneformer)** (de la SHI Labs) publicado con el paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://huggingface.co/papers/2211.06220) por Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
1. **[Pegasus](model_doc/pegasus)** (de Google) publicado con el paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://huggingface.co/papers/1912.08777) por Jingqing Zhang, Yao Zhao, Mohammad Saleh y Peter J. Liu.
1. **[Perceiver IO](model_doc/perceiver)** (de Deepmind) publicado con el paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://huggingface.co/papers/2107.14795) por Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
1. **[PhoBERT](model_doc/phobert)** (de VinAI Research) publicado con el paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) por Dat Quoc Nguyen y Anh Tuan Nguyen.
1. **[PLBart](model_doc/plbart)** (de UCLA NLP) publicado con el paper [Unified Pre-training for Program Understanding and Generation](https://huggingface.co/papers/2103.06333) por Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
1. **[PoolFormer](model_doc/poolformer)** (de Sea AI Labs) publicado con el paper [MetaFormer is Actually What You Need for Vision](https://huggingface.co/papers/2111.11418) por Yu, Weihao y Luo, Mi y Zhou, Pan y Si, Chenyang y Zhou, Yichen y Wang, Xinchao y Feng, Jiashi y Yan, Shuicheng.
1. **[ProphetNet](model_doc/prophetnet)** (de Microsoft Research) publicado con el paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) por Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang y Ming Zhou.
1. **[QDQBert](model_doc/qdqbert)** (de NVIDIA) publicado con el paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://huggingface.co/papers/2004.09602) por Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev y Paulius Micikevicius.
1. **[REALM](model_doc/realm.html)** (de Google Research) publicado con el paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://huggingface.co/papers/2002.08909) por Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat y Ming-Wei Chang.
1. **[Reformer](model_doc/reformer)** (de Google Research) publicado con el paper [Reformer: The Efficient Transformer](https://huggingface.co/papers/2001.04451) por Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
1. **[RemBERT](model_doc/rembert)** (de Google Research) publicado con el paper [Rethinking embedding coupling in pre-trained language models](https://huggingface.co/papers/2010.12821) por Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
1. **[RegNet](model_doc/regnet)** (de META Platforms) publicado con el paper [Designing Network Design Space](https://huggingface.co/papers/2003.13678) por Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
1. **[ResNet](model_doc/resnet)** (de Microsoft Research) publicado con el paper [Deep Residual Learning for Image Recognition](https://huggingface.co/papers/1512.03385) por Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
1. **[RoBERTa](model_doc/roberta)** (de Facebook), publicado junto con el paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://huggingface.co/papers/1907.11692) por Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
1. **[RoFormer](model_doc/roformer)** (de ZhuiyiTechnology), publicado junto con el paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://huggingface.co/papers/2104.09864) por Jianlin Su y Yu Lu y Shengfeng Pan y Bo Wen y Yunfeng Liu.
1. **[SegFormer](model_doc/segformer)** (de NVIDIA) publicado con el paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://huggingface.co/papers/2105.15203) por Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
1. **[SEW](model_doc/sew)** (de ASAPP) publicado con el paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) por Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SEW-D](model_doc/sew_d)** (de ASAPP) publicado con el paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) por Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (de Facebook), publicado junto con el paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://huggingface.co/papers/2010.05171) por Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (de Facebook), publicado junto con el paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://huggingface.co/papers/2104.06678) por Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
1. **[Splinter](model_doc/splinter)** (de Universidad de Tel Aviv), publicado junto con el paper [Few-Shot Question Answering by Pretraining Span Selection](https://huggingface.co/papers/2101.00438) pory Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
1. **[SqueezeBert](model_doc/squeezebert)** (de Berkeley) publicado con el paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://huggingface.co/papers/2006.11316) por Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, y Kurt W. Keutzer.
1. **[Swin Transformer](model_doc/swin)** (de Microsoft) publicado con el paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://huggingface.co/papers/2103.14030) por Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
1. **[T5](model_doc/t5)** (de Google AI) publicado con el paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://huggingface.co/papers/1910.10683) por Colin Raffel y Noam Shazeer y Adam Roberts y Katherine Lee y Sharan Narang y Michael Matena y Yanqi Zhou y Wei Li y Peter J. Liu.
1. **[T5v1.1](model_doc/t5v1.1)** (de Google AI) publicado en el repositorio [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) por Colin Raffel y Noam Shazeer y Adam Roberts y Katherine Lee y Sharan Narang y Michael Matena y Yanqi Zhou y Wei Li y Peter J. Liu.
1. **[TAPAS](model_doc/tapas)** (de Google AI) publicado con el paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://huggingface.co/papers/2004.02349) por Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno y Julian Martin Eisenschlos.
1. **[TAPEX](model_doc/tapex)** (de Microsoft Research) publicado con el paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://huggingface.co/papers/2107.07653) por Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
1. **[Transformer-XL](model_doc/transfo-xl)** (de Google/CMU) publicado con el paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://huggingface.co/papers/1901.02860) por Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
1. **[TrOCR](model_doc/trocr)** (de Microsoft), publicado junto con el paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://huggingface.co/papers/2109.10282) por Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
1. **[UniSpeech](model_doc/unispeech)** (de Microsoft Research) publicado con el paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://huggingface.co/papers/2101.07597) por Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
1. **[UniSpeechSat](model_doc/unispeech-sat)** (de Microsoft Research) publicado con el paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://huggingface.co/papers/2110.05752) por Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
1. **[VAN](model_doc/van)** (de la Universidad de Tsinghua y la Universidad de Nankai) publicado con el paper [Visual Attention Network](https://huggingface.co/papers/2202.09741) por Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
1. **[ViLT](model_doc/vilt)** (de NAVER AI Lab/Kakao Enterprise/Kakao Brain) publicado con el paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://huggingface.co/papers/2102.03334) por Wonjae Kim, Bokyung Son, Ildoo Kim.
1. **[Vision Transformer (ViT)](model_doc/vit)** (de Google AI) publicado con el paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929) por Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
1. **[ViTMAE](model_doc/vit_mae)** (de Meta AI) publicado con el paper [Masked Autoencoders Are Scalable Vision Learners](https://huggingface.co/papers/2111.06377) por Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
1. **[VisualBERT](model_doc/visual_bert)** (de UCLA NLP) publicado con el paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://huggingface.co/papers/1908.03557) por Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
1. **[WavLM](model_doc/wavlm)** (de Microsoft Research) publicado con el paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://huggingface.co/papers/2110.13900) por Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
1. **[Wav2Vec2](model_doc/wav2vec2)** (de Facebook AI) publicado con el paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://huggingface.co/papers/2006.11477) por Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (de Facebook AI) publicado con el paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://huggingface.co/papers/2109.11680) por Qiantong Xu, Alexei Baevski, Michael Auli.
1. **[XGLM](model_doc/xglm)** (de Facebook AI) publicado con el paper [Few-shot Learning with Multilingual Language Models](https://huggingface.co/papers/2112.10668) por Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
1. **[XLM](model_doc/xlm)** (de Facebook) publicado junto con el paper [Cross-lingual Language Model Pretraining](https://huggingface.co/papers/1901.07291) por Guillaume Lample y Alexis Conneau.
1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (de Microsoft Research) publicado con el paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) por Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang y Ming Zhou.
1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (de Facebook AI), publicado junto con el paper [Unsupervised Cross-lingual Representation Learning at Scale](https://huggingface.co/papers/1911.02116) por Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer y Veselin Stoyanov.
1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (de Facebook AI), publicado junto con el paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://huggingface.co/papers/2105.00572) por Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
1. **[XLNet](model_doc/xlnet)** (de Google/CMU) publicado con el paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://huggingface.co/papers/1906.08237) por Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (de Facebook AI) publicado con el paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://huggingface.co/papers/2006.13979) por Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
1. **[XLS-R](model_doc/xls_r)** (de Facebook AI) publicado con el paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://huggingface.co/papers/2111.09296) por Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
1. **[YOSO](model_doc/yoso)** (de la Universidad de Wisconsin-Madison) publicado con el paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://huggingface.co/papers/2111.09714) por Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
### Frameworks compatibles
La siguiente tabla representa el soporte actual en la biblioteca para cada uno de esos modelos, ya sea que tengan un tokenizador de Python (llamado "slow"). Un tokenizador "fast" respaldado por la biblioteca 🤗 Tokenizers, ya sea que tengan soporte en Jax (a través de
Flax), PyTorch y/o TensorFlow.
| Modelo | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
| DeBERTa-v2 | ✅ | ❌ | ✅ | ✅ | ❌ |
| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ResNet | ❌ | ❌ | ✅ | ❌ | ✅ |
| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| Swin | ❌ | ❌ | ✅ | ❌ | ❌ |
| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
| TAPEX | ✅ | ✅ | ✅ | ✅ | ✅ |
| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
---
### Source Fr Index (`docs/source/fr/index.md`)
# 🤗 Transformers
Apprentissage automatique de pointe pour [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), et [JAX](https://jax.readthedocs.io/en/latest/).
🤗 Transformers fournit des API et des outils pour télécharger et entraîner facilement des modèles pré-entraînés de pointe. L'utilisation de modèles pré-entraînés peut réduire vos coûts de calcul, votre empreinte carbone, et vous faire économiser le temps et les ressources nécessaires pour entraîner un modèle à partir de zéro. Ces modèles prennent en charge des tâches courantes dans différentes modalités, telles que :
📝 **Traitement automatique des langues**: classification de texte, reconnaissance d'entités, système de question-réponse, modèle de langage, génération de résumé, traduction, question à choix multiples et génération de texte.
## Contenu
La documentation est organisée en 5 parties:
- **DEMARRER** propose une visite rapide de la bibliothèque et des instructions d'installation pour être opérationnel.
- **TUTORIELS** excellent point de départ pour les débutants. Cette section vous aidera à acquérir les compétences de base dont vous avez besoin pour commencer à utiliser la bibliothèque.
- **GUIDES D'UTILISATION** pour différentes tâches comme par exemple le finetuning d'un modèle pré-entraîné pour la classification de texte ou comment créer et partager votre propre modèle.
- **GUIDES CONCEPTUELS** pour plus de discussions et d'explications sur les concepts et les idées sous-jacentes aux modèles, aux tâches et à la philosophie de conception de 🤗 Transformers.
- **API** décrit toutes les classes et fonctions :
- **CLASSES PRINCIPALES** détaille les classes les plus importantes comme la configuration, le modèle, le tokenizer et le pipeline..
- **MODELES** détaille les classes et les fonctions propres à chaque modèle de la bibliothèque.
- **UTILITAIRES INTERNES** détaille les classes et fonctions utilitaires utilisées en interne.
### Modèles supportés
1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://huggingface.co/papers/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
1. **[ALIGN](model_doc/align)** (from Google Research) released with the paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://huggingface.co/papers/2102.05918) by Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
1. **[AltCLIP](model_doc/altclip)** (from BAAI) released with the paper [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://huggingface.co/papers/2211.06679) by Chen, Zhongzhi and Liu, Guang and Zhang, Bo-Wen and Ye, Fulong and Yang, Qinghong and Wu, Ledell.
1. **[Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer)** (from MIT) released with the paper [AST: Audio Spectrogram Transformer](https://huggingface.co/papers/2104.01778) by Yuan Gong, Yu-An Chung, James Glass.
1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://huggingface.co/papers/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://huggingface.co/papers/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://huggingface.co/papers/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://huggingface.co/papers/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://huggingface.co/papers/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[BioGpt](model_doc/biogpt)** (from Microsoft Research AI4Science) released with the paper [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) by Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon and Tie-Yan Liu.
1. **[BiT](model_doc/bit)** (from Google AI) released with the paper [Big Transfer (BiT): General Visual Representation Learning](https://huggingface.co/papers/1912.11370) by Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, Neil Houlsby.
1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BLIP](model_doc/blip)** (from Salesforce) released with the paper [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://huggingface.co/papers/2201.12086) by Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi.
1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://huggingface.co/papers/2010.10499) by Adrian de Wynter and Daniel J. Perry.
1. **[BridgeTower](model_doc/bridgetower)** (from Harbin Institute of Technology/Microsoft Research Asia/Intel Labs) released with the paper [BridgeTower: Building Bridges Between Encoders in Vision-Language Representation Learning](https://huggingface.co/papers/2206.08657) by Xiao Xu, Chenfei Wu, Shachar Rosenman, Vasudev Lal, Wanxiang Che, Nan Duan.
1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://huggingface.co/papers/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://huggingface.co/papers/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://huggingface.co/papers/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
1. **[Chinese-CLIP](model_doc/chinese_clip)** (from OFA-Sys) released with the paper [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://huggingface.co/papers/2211.01335) by An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou.
1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://huggingface.co/papers/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://huggingface.co/papers/2112.10003) by Timo Lüddecke and Alexander Ecker.
1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://huggingface.co/papers/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://huggingface.co/papers/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://huggingface.co/papers/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://huggingface.co/papers/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://huggingface.co/papers/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://huggingface.co/papers/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://huggingface.co/papers/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://huggingface.co/papers/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://huggingface.co/papers/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://huggingface.co/papers/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://huggingface.co/papers/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://huggingface.co/papers/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
1. **[DETA](model_doc/deta)** (from The University of Texas at Austin) released with the paper [NMS Strikes Back](https://huggingface.co/papers/2212.06137) by Jeffrey Ouyang-Zhang, Jang Hyun Cho, Xingyi Zhou, Philipp Krähenbühl.
1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://huggingface.co/papers/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://huggingface.co/papers/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
1. **[DiNAT](model_doc/dinat)** (from SHI Labs) released with the paper [Dilated Neighborhood Attention Transformer](https://huggingface.co/papers/2209.15001) by Ali Hassani and Humphrey Shi.
1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://huggingface.co/papers/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers-research-projects/tree/main/distillation) and a German version of DistilBERT.
1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://huggingface.co/papers/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://huggingface.co/papers/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://huggingface.co/papers/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://huggingface.co/papers/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
1. **[EfficientFormer](model_doc/efficientformer)** (from Snap Research) released with the paper [EfficientFormer: Vision Transformers at MobileNetSpeed](https://huggingface.co/papers/2206.01191) by Yanyu Li, Geng Yuan, Yang Wen, Ju Hu, Georgios Evangelidis, Sergey Tulyakov, Yanzhi Wang, Jian Ren.
1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://huggingface.co/papers/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://huggingface.co/papers/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
1. **[FastSpeech2Conformer](model_doc/fastspeech2_conformer)** (from ESPnet) released with the paper [Recent Developments On Espnet Toolkit Boosted By Conformer](https://huggingface.co/papers/2010.13956) by Pengcheng Guo, Florian Boyer, Xuankai Chang, Tomoki Hayashi, Yosuke Higuchi, Hirofumi Inaguma, Naoyuki Kamo, Chenda Li, Daniel Garcia-Romero, Jiatong Shi, Jing Shi, Shinji Watanabe, Kun Wei, Wangyou Zhang, and Yuekai Zhang.
1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://huggingface.co/papers/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://huggingface.co/papers/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://huggingface.co/papers/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://huggingface.co/papers/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
1. **[GIT](model_doc/git)** (from Microsoft Research) released with the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://huggingface.co/papers/2205.14100) by Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang.
1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://huggingface.co/papers/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
1. **[GPT-Sw3](model_doc/gpt-sw3)** (from AI-Sweden) released with the paper [Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf) by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman, Fredrik Carlsson, Magnus Sahlgren.
1. **[Graphormer](model_doc/graphormer)** (from Microsoft) released with the paper [Do Transformers Really Perform Bad for Graph Representation?](https://huggingface.co/papers/2106.05234) by Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen, Tie-Yan Liu.
1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://huggingface.co/papers/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://huggingface.co/papers/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://huggingface.co/papers/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://huggingface.co/papers/2005.00341) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://huggingface.co/papers/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://huggingface.co/papers/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://huggingface.co/papers/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://huggingface.co/papers/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://huggingface.co/papers/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://huggingface.co/papers/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://huggingface.co/papers/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://huggingface.co/papers/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://huggingface.co/papers/1908.07490) by Hao Tan and Mohit Bansal.
1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://huggingface.co/papers/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://huggingface.co/papers/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://huggingface.co/papers/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://huggingface.co/papers/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://huggingface.co/papers/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://huggingface.co/papers/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://huggingface.co/papers/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://huggingface.co/papers/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://huggingface.co/papers/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
1. **[MobileNetV1](model_doc/mobilenet_v1)** (from Google Inc.) released with the paper [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://huggingface.co/papers/1704.04861) by Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam.
1. **[MobileNetV2](model_doc/mobilenet_v2)** (from Google Inc.) released with the paper [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://huggingface.co/papers/1801.04381) by Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen.
1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://huggingface.co/papers/2110.02178) by Sachin Mehta and Mohammad Rastegari.
1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://huggingface.co/papers/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://huggingface.co/papers/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://huggingface.co/papers/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
1. **[NAT](model_doc/nat)** (from SHI Labs) released with the paper [Neighborhood Attention Transformer](https://huggingface.co/papers/2204.07143) by Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi.
1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://huggingface.co/papers/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://huggingface.co/papers/2207.04672) by the NLLB team.
1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://huggingface.co/papers/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://huggingface.co/papers/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://huggingface.co/papers/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://huggingface.co/papers/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://huggingface.co/papers/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://huggingface.co/papers/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://huggingface.co/papers/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://huggingface.co/papers/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://huggingface.co/papers/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://huggingface.co/papers/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://huggingface.co/papers/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://huggingface.co/papers/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://huggingface.co/papers/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://huggingface.co/papers/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://huggingface.co/papers/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://huggingface.co/papers/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://huggingface.co/papers/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
1. **[RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm)** (from Facebook) released with the paper [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://huggingface.co/papers/1904.01038) by Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli.
1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://huggingface.co/papers/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://huggingface.co/papers/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SpeechT5](model_doc/speecht5)** (from Microsoft Research) released with the paper [SpeechT5: Unified-Modal Encoder-Decoder Pre-Training for Spoken Language Processing](https://huggingface.co/papers/2110.07205) by Junyi Ao, Rui Wang, Long Zhou, Chengyi Wang, Shuo Ren, Yu Wu, Shujie Liu, Tom Ko, Qing Li, Yu Zhang, Zhihua Wei, Yao Qian, Jinyu Li, Furu Wei.
1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://huggingface.co/papers/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://huggingface.co/papers/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://huggingface.co/papers/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://huggingface.co/papers/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://huggingface.co/papers/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://huggingface.co/papers/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
1. **[Swin2SR](model_doc/swin2sr)** (from University of Würzburg) released with the paper [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://huggingface.co/papers/2209.11345) by Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte.
1. **[SwitchTransformers](model_doc/switch_transformers)** (from Google) released with the paper [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://huggingface.co/papers/2101.03961) by William Fedus, Barret Zoph, Noam Shazeer.
1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://huggingface.co/papers/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://huggingface.co/papers/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://huggingface.co/papers/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://huggingface.co/papers/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
1. **[TimeSformer](model_doc/timesformer)** (from Facebook) released with the paper [Is Space-Time Attention All You Need for Video Understanding?](https://huggingface.co/papers/2102.05095) by Gedas Bertasius, Heng Wang, Lorenzo Torresani.
1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://huggingface.co/papers/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://huggingface.co/papers/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://huggingface.co/papers/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://huggingface.co/papers/2205.05131) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://huggingface.co/papers/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://huggingface.co/papers/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
1. **[UPerNet](model_doc/upernet)** (from Peking University) released with the paper [Unified Perceptual Parsing for Scene Understanding](https://huggingface.co/papers/1807.10221) by Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun.
1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://huggingface.co/papers/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://huggingface.co/papers/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://huggingface.co/papers/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://huggingface.co/papers/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
1. **[ViT Hybrid](model_doc/vit_hybrid)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://huggingface.co/papers/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://huggingface.co/papers/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://huggingface.co/papers/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://huggingface.co/papers/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://huggingface.co/papers/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://huggingface.co/papers/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://huggingface.co/papers/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://huggingface.co/papers/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://huggingface.co/papers/1901.07291) by Guillaume Lample and Alexis Conneau.
1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://huggingface.co/papers/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://huggingface.co/papers/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://huggingface.co/papers/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://huggingface.co/papers/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://huggingface.co/papers/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://huggingface.co/papers/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://huggingface.co/papers/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
### Frameworks compatibles
Le tableau ci-dessous représente la prise en charge actuelle dans la bibliothèque pour chacun de ces modèles, qu'ils aient ou non un tokenizer Python (appelé "slow"). Un tokenizer rapide ("fast") soutenu par la bibliothèque 🤗 Tokenizers, qu'ils aient un support en Jax (via Flax), PyTorch, et/ou TensorFlow.
| Modèle | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
|:-----------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| AltCLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| Audio Spectrogram Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
| BioGpt | ✅ | ❌ | ✅ | ❌ | ❌ |
| BiT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
| BLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
| BridgeTower | ❌ | ❌ | ✅ | ❌ | ❌ |
| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
| Chinese-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
| DETA | ❌ | ❌ | ✅ | ❌ | ❌ |
| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DiNAT | ❌ | ❌ | ✅ | ❌ | ❌ |
| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| EfficientFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
| FastSpeech2Conformer | ✅ | ❌ | ✅ | ❌ | ❌ |
| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| GIT | ❌ | ❌ | ✅ | ❌ | ❌ |
| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
| GPT-Sw3 | ✅ | ✅ | ✅ | ✅ | ✅ |
| Graphormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
| Mask2Former | ❌ | ❌ | ✅ | ❌ | ❌ |
| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| MaskFormerSwin | ❌ | ❌ | ❌ | ❌ | ❌ |
| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| MobileNetV1 | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileNetV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
| NAT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| OneFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ResNet | ❌ | ❌ | ✅ | ✅ | ❌ |
| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| RoBERTa-PreLayerNorm | ❌ | ❌ | ✅ | ✅ | ✅ |
| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
| SpeechT5 | ✅ | ❌ | ✅ | ❌ | ❌ |
| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
| Swin2SR | ❌ | ❌ | ✅ | ❌ | ❌ |
| SwitchTransformers | ❌ | ❌ | ✅ | ❌ | ❌ |
| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| TimeSformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
| UPerNet | ❌ | ❌ | ✅ | ❌ | ❌ |
| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
| ViT Hybrid | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
---
### Source It Index (`docs/source/it/index.md`)
# 🤗 Transformers
Machine Learning allo stato dell'arte per PyTorch, TensorFlow e JAX.
🤗 Transformers fornisce delle API per scaricare in modo semplice e allenare modelli pre-allenati allo stato dell'arte. L'utilizzo di modelli pre-allenati può ridurre i tuoi costi computazionali, l'impatto ambientale, e farti risparmiare il tempo che utilizzeresti per allenare un modello da zero. I modelli possono essere utilizzati in diverse modalità come ad esempio:
* 📝 Testo: classificazione del testo, estrazione delle informazioni, rispondere a domande, riassumere, traduzione e generazione del testo in più di 100 lingue.
* 🖼️ Immagini: classificazione di immagini, rilevazione di oggetti e segmentazione.
* 🗣️ Audio: riconoscimento vocale e classificazione dell'audio.
* 🐙 Multimodale: rispondere a domande inerenti dati tabulari, riconoscimento ottico dei caratteri, estrazione di informazioni a partire da documenti scannerizzati, classificazione di video e risposta visuale a domande.
La nostra libreria supporta un'integrazione perfetta tra tre delle librerie per il deep learning più popolari: [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) e [JAX](https://jax.readthedocs.io/en/latest/). Allena il tuo modello in tre righe di codice in un framework, e caricalo per l'inferenza in un altro.
Ogni architettura di 🤗 Transformers è definita in un modulo Python indipendente così da poter essere personalizzata in modo semplice per la ricerca e gli esperimenti.
## Se stai cercando supporto personalizzato dal team di Hugging Face
## Contenuti
La documentazione è organizzata in cinque parti:
- **INIZIARE** contiene un tour rapido e le istruzioni di installazione per cominciare ad utilizzare 🤗 Transformers.
- **TUTORIALS** è un buon posto da cui iniziare se per te la nostra libreria è nuova. Questa sezione ti aiuterà ad acquisire le competenze basilari di cui hai bisogno per iniziare ad utilizzare 🤗 Transformers.
- **GUIDE PRATICHE** ti mostrerà come raggiungere obiettivi specifici come fare fine-tuning di un modello pre-allenato per la modellizzazione del linguaggio o come creare una testa per un modello personalizzato.
- **GUIDE CONCETTUALI** fornisce discussioni e spiegazioni dei concetti sottostanti alle idee dietro ai modelli, compiti, e la filosofia di progettazione di 🤗 Transformers.
- **API** descrive ogni classe e funzione, raggruppate in:
- **CLASSI PRINCIPALI** per le classi principali che espongono le API importanti della libreria.
- **MODELLI** per le classi e le funzioni relative ad ogni modello implementato all'interno della libreria.
- **HELPERS INTERNI** per le classi e le funzioni che utilizziamo internamente.
La libreria attualmente contiene implementazioni in JAX, PyTorch e TensorFlow, pesi di modelli pre-allenati, script di utilizzo e strumenti di conversione per i seguenti modelli.
### Modelli supportati
1. **[ALBERT](model_doc/albert)** (da Google Research e l'Istituto Tecnologico di Chicago) rilasciato con il paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://huggingface.co/papers/1909.11942), da Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
1. **[ALIGN](model_doc/align)** (from Google Research) rilasciato con il paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://huggingface.co/papers/2102.05918) da Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
1. **[BART](model_doc/bart)** (da Facebook) rilasciato con il paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://huggingface.co/papers/1910.13461) da Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov e Luke Zettlemoyer.
1. **[BARThez](model_doc/barthez)** (da politecnico di École) rilasciato con il paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://huggingface.co/papers/2010.12321) da Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
1. **[BARTpho](model_doc/bartpho)** (da VinAI Research) rilasciato con il paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://huggingface.co/papers/2109.09701) da Nguyen Luong Tran, Duong Minh Le e Dat Quoc Nguyen.
1. **[BEiT](model_doc/beit)** (da Microsoft) rilasciato con il paper [BEiT: BERT Pre-Training of Image Transformers](https://huggingface.co/papers/2106.08254) da Hangbo Bao, Li Dong, Furu Wei.
1. **[BERT](model_doc/bert)** (da Google) rilasciato con il paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://huggingface.co/papers/1810.04805) da Jacob Devlin, Ming-Wei Chang, Kenton Lee e Kristina Toutanova.
1. **[BERTweet](model_doc/bertweet)** (da VinAI Research) rilasciato con il paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) da Dat Quoc Nguyen, Thanh Vu e Anh Tuan Nguyen.
1. **[BERT For Sequence Generation](model_doc/bert-generation)** (da Google) rilasciato con il paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) da Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[BigBird-RoBERTa](model_doc/big_bird)** (da Google Research) rilasciato con il paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) da Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (v Google Research) rilasciato con il paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) da Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[Blenderbot](model_doc/blenderbot)** (da Facebook) rilasciato con il paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) da Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BlenderbotSmall](model_doc/blenderbot-small)** (da Facebook) rilasciato con il paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) da Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BORT](model_doc/bort)** (da Alexa) rilasciato con il paper [Optimal Subarchitecture Extraction For BERT](https://huggingface.co/papers/2010.10499) da Adrian de Wynter e Daniel J. Perry.
1. **[ByT5](model_doc/byt5)** (da Google Research) rilasciato con il paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://huggingface.co/papers/2105.13626) da Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
1. **[CamemBERT](model_doc/camembert)** (da Inria/Facebook/Sorbonne) rilasciato con il paper [CamemBERT: a Tasty French Language Model](https://huggingface.co/papers/1911.03894) da Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah e Benoît Sagot.
1. **[CANINE](model_doc/canine)** (da Google Research) rilasciato con il paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://huggingface.co/papers/2103.06874) da Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
1. **[ConvNeXT](model_doc/convnext)** (da Facebook AI) rilasciato con il paper [A ConvNet for the 2020s](https://huggingface.co/papers/2201.03545) da Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
1. **[ConvNeXTV2](model_doc/convnextv2)** (da Facebook AI) rilasciato con il paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://huggingface.co/papers/2301.00808) da Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
1. **[CLIP](model_doc/clip)** (da OpenAI) rilasciato con il paper [Learning Transferable Visual Models From Natural Language Supervision](https://huggingface.co/papers/2103.00020) da Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
1. **[ConvBERT](model_doc/convbert)** (da YituTech) rilasciato con il paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://huggingface.co/papers/2008.02496) da Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
1. **[CPM](model_doc/cpm)** (dalla Università di Tsinghua) rilasciato con il paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://huggingface.co/papers/2012.00413) da Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
1. **[CTRL](model_doc/ctrl)** (da Salesforce) rilasciato con il paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://huggingface.co/papers/1909.05858) da Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong e Richard Socher.
1. **[CvT](model_doc/cvt)** (da Microsoft) rilasciato con il paper [CvT: Introducing Convolutions to Vision Transformers](https://huggingface.co/papers/2103.15808) da Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
1. **[Data2Vec](model_doc/data2vec)** (da Facebook) rilasciato con il paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://huggingface.co/papers/2202.03555) da Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
1. **[DeBERTa](model_doc/deberta)** (da Microsoft) rilasciato con il paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) da Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[DeBERTa-v2](model_doc/deberta-v2)** (da Microsoft) rilasciato con il paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) da Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[Decision Transformer](model_doc/decision_transformer)** (da Berkeley/Facebook/Google) rilasciato con il paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://huggingface.co/papers/2106.01345) da Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
1. **[DiT](model_doc/dit)** (da Microsoft Research) rilasciato con il paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://huggingface.co/papers/2203.02378) da Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
1. **[DeiT](model_doc/deit)** (da Facebook) rilasciato con il paper [Training data-efficient image transformers & distillation through attention](https://huggingface.co/papers/2012.12877) da Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
1. **[DETR](model_doc/detr)** (da Facebook) rilasciato con il paper [End-to-End Object Detection with Transformers](https://huggingface.co/papers/2005.12872) da Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
1. **[DialoGPT](model_doc/dialogpt)** (da Microsoft Research) rilasciato con il paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://huggingface.co/papers/1911.00536) da Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
1. **[DistilBERT](model_doc/distilbert)** (da HuggingFace), rilasciato assieme al paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://huggingface.co/papers/1910.01108) da Victor Sanh, Lysandre Debut e Thomas Wolf. La stessa tecnica è stata applicata per comprimere GPT2 in [DistilGPT2](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), RoBERTa in [DistilRoBERTa](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), Multilingual BERT in [DistilmBERT](https://github.com/huggingface/transformers-research-projects/tree/main/distillation) and a German version of DistilBERT.
1. **[DPR](model_doc/dpr)** (da Facebook) rilasciato con il paper [Dense Passage Retrieval for Open-Domain Question Answering](https://huggingface.co/papers/2004.04906) da Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, e Wen-tau Yih.
1. **[DPT](master/model_doc/dpt)** (da Intel Labs) rilasciato con il paper [Vision Transformers for Dense Prediction](https://huggingface.co/papers/2103.13413) da René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://huggingface.co/papers/1905.11946) by Mingxing Tan and Quoc V. Le.
1. **[EncoderDecoder](model_doc/encoder-decoder)** (da Google Research) rilasciato con il paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) da Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[ELECTRA](model_doc/electra)** (da Google Research/Stanford University) rilasciato con il paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://huggingface.co/papers/2003.10555) da Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
1. **[FlauBERT](model_doc/flaubert)** (da CNRS) rilasciato con il paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://huggingface.co/papers/1912.05372) da Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
1. **[FLAVA](model_doc/flava)** (da Facebook AI) rilasciato con il paper [FLAVA: A Foundational Language And Vision Alignment Model](https://huggingface.co/papers/2112.04482) da Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, e Douwe Kiela.
1. **[FNet](model_doc/fnet)** (da Google Research) rilasciato con il paper [FNet: Mixing Tokens with Fourier Transforms](https://huggingface.co/papers/2105.03824) da James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
1. **[Funnel Transformer](model_doc/funnel)** (da CMU/Google Brain) rilasciato con il paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://huggingface.co/papers/2006.03236) da Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
1. **[GLPN](model_doc/glpn)** (da KAIST) rilasciato con il paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436) da Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
1. **[GPT](model_doc/openai-gpt)** (da OpenAI) rilasciato con il paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) da Alec Radford, Karthik Narasimhan, Tim Salimans e Ilya Sutskever.
1. **[GPT-2](model_doc/gpt2)** (da OpenAI) rilasciato con il paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) da Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei e Ilya Sutskever.
1. **[GPT-J](model_doc/gptj)** (da EleutherAI) rilasciato nel repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) da Ben Wang e Aran Komatsuzaki.
1. **[GPT Neo](model_doc/gpt_neo)** (da EleutherAI) rilasciato nel repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) da Sid Black, Stella Biderman, Leo Gao, Phil Wang e Connor Leahy.
1. **[GPT NeoX](model_doc/gpt_neox)** (da EleutherAI) rilasciato con il paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://huggingface.co/papers/2204.06745) da Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
1. **[Hubert](model_doc/hubert)** (da Facebook) rilasciato con il paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://huggingface.co/papers/2106.07447) da Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
1. **[I-BERT](model_doc/ibert)** (da Berkeley) rilasciato con il paper [I-BERT: Integer-only BERT Quantization](https://huggingface.co/papers/2101.01321) da Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
1. **[ImageGPT](model_doc/imagegpt)** (da OpenAI) rilasciato con il paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) da Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
1. **[LayoutLM](model_doc/layoutlm)** (da Microsoft Research Asia) rilasciato con il paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://huggingface.co/papers/1912.13318) da Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
1. **[LayoutLMv2](model_doc/layoutlmv2)** (da Microsoft Research Asia) rilasciato con il paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://huggingface.co/papers/2012.14740) da Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
1. **[LayoutLMv3](model_doc/layoutlmv3)** (da Microsoft Research Asia) rilasciato con il paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://huggingface.co/papers/2204.08387) da Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
1. **[LayoutXLM](model_doc/layoutlxlm)** (da Microsoft Research Asia) rilasciato con il paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://huggingface.co/papers/2104.08836) da Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
1. **[LED](model_doc/led)** (da AllenAI) rilasciato con il paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) da Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[Longformer](model_doc/longformer)** (da AllenAI) rilasciato con il paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) da Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LUKE](model_doc/luke)** (da Studio Ousia) rilasciato con il paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://huggingface.co/papers/2010.01057) da Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
1. **[mLUKE](model_doc/mluke)** (da Studio Ousia) rilasciato con il paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://huggingface.co/papers/2110.08151) da Ryokan Ri, Ikuya Yamada, e Yoshimasa Tsuruoka.
1. **[LXMERT](model_doc/lxmert)** (da UNC Chapel Hill) rilasciato con il paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://huggingface.co/papers/1908.07490) da Hao Tan e Mohit Bansal.
1. **[M2M100](model_doc/m2m_100)** (da Facebook) rilasciato con il paper [Beyond English-Centric Multilingual Machine Translation](https://huggingface.co/papers/2010.11125) da Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
1. **[MarianMT](model_doc/marian)** Modello di machine learning per le traduzioni allenato utilizzando i dati [OPUS](http://opus.nlpl.eu/) di Jörg Tiedemann. Il [Framework Marian](https://marian-nmt.github.io/) è stato sviluppato dal Microsoft Translator Team.
1. **[Mask2Former](model_doc/mask2former)** (da FAIR e UIUC) rilasciato con il paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://huggingface.co/papers/2112.01527) da Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
1. **[MaskFormer](model_doc/maskformer)** (da Meta e UIUC) rilasciato con il paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://huggingface.co/papers/2107.06278) da Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
1. **[MBart](model_doc/mbart)** (da Facebook) rilasciato con il paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://huggingface.co/papers/2001.08210) da Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
1. **[MBart-50](model_doc/mbart)** (da Facebook) rilasciato con il paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://huggingface.co/papers/2008.00401) da Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
1. **[Megatron-BERT](model_doc/megatron-bert)** (da NVIDIA) rilasciato con il paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) da Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper e Bryan Catanzaro.
1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (da NVIDIA) rilasciato con il paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) da Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper e Bryan Catanzaro.
1. **[MPNet](model_doc/mpnet)** (da Microsoft Research) rilasciato con il paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://huggingface.co/papers/2004.09297) da Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
1. **[MT5](model_doc/mt5)** (da Google AI) rilasciato con il paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://huggingface.co/papers/2010.11934) da Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
1. **[Nyströmformer](model_doc/nystromformer)** (dalla Università del Wisconsin - Madison) rilasciato con il paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://huggingface.co/papers/2102.03902) da Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
1. **[OneFormer](model_doc/oneformer)** (da SHI Labs) rilasciato con il paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://huggingface.co/papers/2211.06220) da Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
1. **[OPT](master/model_doc/opt)** (da Meta AI) rilasciato con il paper [OPT: Open Pre-trained Transformer Language Models](https://huggingface.co/papers/2205.01068) da Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
1. **[Pegasus](model_doc/pegasus)** (da Google) rilasciato con il paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://huggingface.co/papers/1912.08777) da Jingqing Zhang, Yao Zhao, Mohammad Saleh e Peter J. Liu.
1. **[Perceiver IO](model_doc/perceiver)** (da Deepmind) rilasciato con il paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://huggingface.co/papers/2107.14795) da Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
1. **[PhoBERT](model_doc/phobert)** (da VinAI Research) rilasciato con il paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) da Dat Quoc Nguyen e Anh Tuan Nguyen.
1. **[PLBart](model_doc/plbart)** (da UCLA NLP) rilasciato con il paper [Unified Pre-training for Program Understanding and Generation](https://huggingface.co/papers/2103.06333) da Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
1. **[PoolFormer](model_doc/poolformer)** (da Sea AI Labs) rilasciato con il paper [MetaFormer is Actually What You Need for Vision](https://huggingface.co/papers/2111.11418) da Yu, Weihao e Luo, Mi e Zhou, Pan e Si, Chenyang e Zhou, Yichen e Wang, Xinchao e Feng, Jiashi e Yan, Shuicheng.
1. **[ProphetNet](model_doc/prophetnet)** (da Microsoft Research) rilasciato con il paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) da Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang e Ming Zhou.
1. **[QDQBert](model_doc/qdqbert)** (da NVIDIA) rilasciato con il paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://huggingface.co/papers/2004.09602) da Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev e Paulius Micikevicius.
1. **[REALM](model_doc/realm.html)** (da Google Research) rilasciato con il paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://huggingface.co/papers/2002.08909) da Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat e Ming-Wei Chang.
1. **[Reformer](model_doc/reformer)** (da Google Research) rilasciato con il paper [Reformer: The Efficient Transformer](https://huggingface.co/papers/2001.04451) da Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
1. **[RemBERT](model_doc/rembert)** (da Google Research) rilasciato con il paper [Rethinking embedding coupling in pre-trained language models](https://huggingface.co/papers/2010.12821) da Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
1. **[RegNet](model_doc/regnet)** (da META Platforms) rilasciato con il paper [Designing Network Design Space](https://huggingface.co/papers/2003.13678) da Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
1. **[ResNet](model_doc/resnet)** (da Microsoft Research) rilasciato con il paper [Deep Residual Learning for Image Recognition](https://huggingface.co/papers/1512.03385) da Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
1. **[RoBERTa](model_doc/roberta)** (da Facebook), rilasciato assieme al paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://huggingface.co/papers/1907.11692) da Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
1. **[RoFormer](model_doc/roformer)** (da ZhuiyiTechnology), rilasciato assieme al paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://huggingface.co/papers/2104.09864) da Jianlin Su e Yu Lu e Shengfeng Pan e Bo Wen e Yunfeng Liu.
1. **[SegFormer](model_doc/segformer)** (da NVIDIA) rilasciato con il paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://huggingface.co/papers/2105.15203) da Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
1. **[SEW](model_doc/sew)** (da ASAPP) rilasciato con il paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) da Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SEW-D](model_doc/sew_d)** (da ASAPP) rilasciato con il paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) da Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (da Facebook), rilasciato assieme al paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://huggingface.co/papers/2010.05171) da Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (da Facebook), rilasciato assieme al paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://huggingface.co/papers/2104.06678) da Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
1. **[Splinter](model_doc/splinter)** (dalla Università di Tel Aviv), rilasciato assieme al paper [Few-Shot Question Answering by Pretraining Span Selection](https://huggingface.co/papers/2101.00438) da Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
1. **[SqueezeBert](model_doc/squeezebert)** (da Berkeley) rilasciato con il paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://huggingface.co/papers/2006.11316) da Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, e Kurt W. Keutzer.
1. **[Swin Transformer](model_doc/swin)** (da Microsoft) rilasciato con il paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://huggingface.co/papers/2103.14030) da Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
1. **[T5](model_doc/t5)** (da Google AI) rilasciato con il paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://huggingface.co/papers/1910.10683) da Colin Raffel e Noam Shazeer e Adam Roberts e Katherine Lee e Sharan Narang e Michael Matena e Yanqi Zhou e Wei Li e Peter J. Liu.
1. **[T5v1.1](model_doc/t5v1.1)** (da Google AI) rilasciato nel repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) da Colin Raffel e Noam Shazeer e Adam Roberts e Katherine Lee e Sharan Narang e Michael Matena e Yanqi Zhou e Wei Li e Peter J. Liu.
1. **[TAPAS](model_doc/tapas)** (da Google AI) rilasciato con il paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://huggingface.co/papers/2004.02349) da Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno e Julian Martin Eisenschlos.
1. **[TAPEX](model_doc/tapex)** (da Microsoft Research) rilasciato con il paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://huggingface.co/papers/2107.07653) da Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (dall'Università della California a Berkeley) rilasciato con il paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://huggingface.co/papers/2106.02039) da Michael Janner, Qiyang Li, Sergey Levine
1. **[Transformer-XL](model_doc/transfo-xl)** (da Google/CMU) rilasciato con il paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://huggingface.co/papers/1901.02860) da Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
1. **[TrOCR](model_doc/trocr)** (da Microsoft), rilasciato assieme al paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://huggingface.co/papers/2109.10282) da Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
1. **[UniSpeech](model_doc/unispeech)** (da Microsoft Research) rilasciato con il paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://huggingface.co/papers/2101.07597) da Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
1. **[UniSpeechSat](model_doc/unispeech-sat)** (da Microsoft Research) rilasciato con il paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://huggingface.co/papers/2110.05752) da Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
1. **[VAN](model_doc/van)** (dalle Università di Tsinghua e Nankai) rilasciato con il paper [Visual Attention Network](https://huggingface.co/papers/2202.09741) da Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
1. **[ViLT](model_doc/vilt)** (da NAVER AI Lab/Kakao Enterprise/Kakao Brain) rilasciato con il paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://huggingface.co/papers/2102.03334) da Wonjae Kim, Bokyung Son, Ildoo Kim.
1. **[Vision Transformer (ViT)](model_doc/vit)** (da Google AI) rilasciato con il paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929) da Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
1. **[ViTMAE](model_doc/vit_mae)** (da Meta AI) rilasciato con il paper [Masked Autoencoders Are Scalable Vision Learners](https://huggingface.co/papers/2111.06377) da Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
1. **[VisualBERT](model_doc/visual_bert)** (da UCLA NLP) rilasciato con il paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://huggingface.co/papers/1908.03557) da Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
1. **[WavLM](model_doc/wavlm)** (da Microsoft Research) rilasciato con il paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://huggingface.co/papers/2110.13900) da Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
1. **[Wav2Vec2](model_doc/wav2vec2)** (da Facebook AI) rilasciato con il paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://huggingface.co/papers/2006.11477) da Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (da Facebook AI) rilasciato con il paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://huggingface.co/papers/2109.11680) da Qiantong Xu, Alexei Baevski, Michael Auli.
1. **[XGLM](model_doc/xglm)** (da Facebook AI) rilasciato con il paper [Few-shot Learning with Multilingual Language Models](https://huggingface.co/papers/2112.10668) da Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
1. **[XLM](model_doc/xlm)** (v Facebook) rilasciato assieme al paper [Cross-lingual Language Model Pretraining](https://huggingface.co/papers/1901.07291) da Guillaume Lample e Alexis Conneau.
1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (da Microsoft Research) rilasciato con il paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) da Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang e Ming Zhou.
1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (da Facebook AI), rilasciato assieme al paper [Unsupervised Cross-lingual Representation Learning at Scale](https://huggingface.co/papers/1911.02116) da Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer e Veselin Stoyanov.
1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (da Facebook AI), rilasciato assieme al paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://huggingface.co/papers/2105.00572) da Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
1. **[XLNet](model_doc/xlnet)** (da Google/CMU) rilasciato con il paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://huggingface.co/papers/1906.08237) da Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (da Facebook AI) rilasciato con il paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://huggingface.co/papers/2006.13979) da Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
1. **[XLS-R](model_doc/xls_r)** (da Facebook AI) rilasciato con il paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://huggingface.co/papers/2111.09296) da Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
1. **[YOLOS](model_doc/yolos)** (dalla Università della scienza e tecnologia di Huazhong) rilasciato con il paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://huggingface.co/papers/2106.00666) da Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
1. **[YOSO](model_doc/yoso)** (dall'Università del Wisconsin - Madison) rilasciato con il paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://huggingface.co/papers/2111.09714) da Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
### Framework supportati
La tabella seguente rappresenta il supporto attuale nella libreria per ognuno di questi modelli, si può identificare se questi hanno un Python
tokenizer (chiamato "slow"). Un tokenizer "fast" supportato dalla libreria 🤗 Tokenizers, e se hanno supporto in Jax (via Flax), PyTorch, e/o TensorFlow.
| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
| CvT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
| Flava | ❌ | ❌ | ✅ | ❌ | ❌ |
| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
| OPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| Swin | ❌ | ❌ | ✅ | ✅ | ❌ |
| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
---
### Source Ja Index (`docs/source/ja/index.md`)
# 🤗 Transformers
[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), [JAX](https://jax.readthedocs.io/en/latest/)のための最先端機械学習。
🤗 Transformers は最先端の学習済みモデルを簡単にダウンロードして学習するAPIとツールを提供します。学習済みモデルを使用することで計算コストと二酸化炭素の排出量を削減でき、またゼロからモデルを学習するために要求される時間とリソースを節約することができます。 これらのモデルは以下のような異なるモダリティにおける一般的なタスクをサポートします:
📝 **自然言語処理**: テキスト分類、 固有表現抽出、 質問応答、 言語モデリング、 文章要約、 機械翻訳、 複数選択、テキスト生成。
## 目次
ドキュメントは以下の5つのセクションで構成されています:
- **はじめに** は、ライブラリのクイックツアーとライブラリを使い始めるためのインストール手順を提供しています。
- **チュートリアル** は、初心者が始めるのに最適な場所です。このセクションでは、ライブラリを使い始めるために必要な基本的なスキルを習得できます。
- **HOW-TOガイド** は、言語モデリングのために学習済みモデルをfinetuningすることやカスタムモデルの作成と共有の方法などといった特定の目標を達成するための方法を示しています。
- **コンセプトガイド** は、モデルやタスク、そして 🤗 Transformersの設計思想の背景にある基本的にコンセプトや考え方についてより深く考察し解説しています。
- **API** 全てのクラスと関数を説明します:
- **MAIN CLASSES** は、configuration, model, tokenizer, pipelineといった最も重要なクラスについて詳細に説明しています。
- **MODELS** は、ライブラリで実装されているそれぞれのモデルに関連したクラスと関数を詳細に説明しています。
- **INTERNAL HELPERS** は、内部で使用されているユーティリティクラスや関数を詳細に説明しています。
### サポートされているモデル
1. **[ALBERT](https://huggingface.co/docs/transformers/model_doc/albert)** (Google Research and the Toyota Technological Institute at Chicago から) Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut から公開された研究論文: [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://huggingface.co/papers/1909.11942)
1. **[AltCLIP](https://huggingface.co/docs/transformers/main/model_doc/altclip)** (BAAI から) Chen, Zhongzhi and Liu, Guang and Zhang, Bo-Wen and Ye, Fulong and Yang, Qinghong and Wu, Ledell から公開された研究論文: [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://huggingface.co/papers/2211.06679)
1. **[Audio Spectrogram Transformer](https://huggingface.co/docs/transformers/model_doc/audio-spectrogram-transformer)** (MIT から) Yuan Gong, Yu-An Chung, James Glass から公開された研究論文: [AST: Audio Spectrogram Transformer](https://huggingface.co/papers/2104.01778)
1. **[BART](https://huggingface.co/docs/transformers/model_doc/bart)** (Facebook から) Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer から公開された研究論文: [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://huggingface.co/papers/1910.13461)
1. **[BARThez](https://huggingface.co/docs/transformers/model_doc/barthez)** (École polytechnique から) Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis から公開された研究論文: [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://huggingface.co/papers/2010.12321)
1. **[BARTpho](https://huggingface.co/docs/transformers/model_doc/bartpho)** (VinAI Research から) Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen から公開された研究論文: [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://huggingface.co/papers/2109.09701)
1. **[BEiT](https://huggingface.co/docs/transformers/model_doc/beit)** (Microsoft から) Hangbo Bao, Li Dong, Furu Wei から公開された研究論文: [BEiT: BERT Pre-Training of Image Transformers](https://huggingface.co/papers/2106.08254)
1. **[BERT](https://huggingface.co/docs/transformers/model_doc/bert)** (Google から) Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova から公開された研究論文: [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://huggingface.co/papers/1810.04805)
1. **[BERT For Sequence Generation](https://huggingface.co/docs/transformers/model_doc/bert-generation)** (Google から) Sascha Rothe, Shashi Narayan, Aliaksei Severyn から公開された研究論文: [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461)
1. **[BERTweet](https://huggingface.co/docs/transformers/model_doc/bertweet)** (VinAI Research から) Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen から公開された研究論文: [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/)
1. **[BigBird-Pegasus](https://huggingface.co/docs/transformers/model_doc/bigbird_pegasus)** (Google Research から) Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed から公開された研究論文: [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062)
1. **[BigBird-RoBERTa](https://huggingface.co/docs/transformers/model_doc/big_bird)** (Google Research から) Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed から公開された研究論文: [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062)
1. **[BioGpt](https://huggingface.co/docs/transformers/main/model_doc/biogpt)** (Microsoft Research AI4Science から) Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon and Tie-Yan Liu から公開された研究論文: [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9)
1. **[BiT](https://huggingface.co/docs/transformers/main/model_doc/bit)** (Google AI から) Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, Neil から公開された研究論文: [Big Transfer (BiT)](https://huggingface.co/papers/1912.11370)Houlsby.
1. **[Blenderbot](https://huggingface.co/docs/transformers/model_doc/blenderbot)** (Facebook から) Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston から公開された研究論文: [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637)
1. **[BlenderbotSmall](https://huggingface.co/docs/transformers/model_doc/blenderbot-small)** (Facebook から) Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston から公開された研究論文: [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637)
1. **[BLIP](https://huggingface.co/docs/transformers/main/model_doc/blip)** (Salesforce から) Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi から公開された研究論文: [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://huggingface.co/papers/2201.12086)
1. **[BLOOM](https://huggingface.co/docs/transformers/model_doc/bloom)** (BigScience workshop から) [BigScience Workshop](https://bigscience.huggingface.co/) から公開されました.
1. **[BORT](https://huggingface.co/docs/transformers/model_doc/bort)** (Alexa から) Adrian de Wynter and Daniel J. Perry から公開された研究論文: [Optimal Subarchitecture Extraction For BERT](https://huggingface.co/papers/2010.10499)
1. **[ByT5](https://huggingface.co/docs/transformers/model_doc/byt5)** (Google Research から) Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel から公開された研究論文: [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://huggingface.co/papers/2105.13626)
1. **[CamemBERT](https://huggingface.co/docs/transformers/model_doc/camembert)** (Inria/Facebook/Sorbonne から) Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot から公開された研究論文: [CamemBERT: a Tasty French Language Model](https://huggingface.co/papers/1911.03894)
1. **[CANINE](https://huggingface.co/docs/transformers/model_doc/canine)** (Google Research から) Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting から公開された研究論文: [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://huggingface.co/papers/2103.06874)
1. **[Chinese-CLIP](https://huggingface.co/docs/transformers/model_doc/chinese_clip)** (OFA-Sys から) An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou から公開された研究論文: [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://huggingface.co/papers/2211.01335)
1. **[CLIP](https://huggingface.co/docs/transformers/model_doc/clip)** (OpenAI から) Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever から公開された研究論文: [Learning Transferable Visual Models From Natural Language Supervision](https://huggingface.co/papers/2103.00020)
1. **[CLIPSeg](https://huggingface.co/docs/transformers/model_doc/clipseg)** (University of Göttingen から) Timo Lüddecke and Alexander Ecker から公開された研究論文: [Image Segmentation Using Text and Image Prompts](https://huggingface.co/papers/2112.10003)
1. **[CodeGen](https://huggingface.co/docs/transformers/model_doc/codegen)** (Salesforce から) Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong から公開された研究論文: [A Conversational Paradigm for Program Synthesis](https://huggingface.co/papers/2203.13474)
1. **[Conditional DETR](https://huggingface.co/docs/transformers/model_doc/conditional_detr)** (Microsoft Research Asia から) Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang から公開された研究論文: [Conditional DETR for Fast Training Convergence](https://huggingface.co/papers/2108.06152)
1. **[ConvBERT](https://huggingface.co/docs/transformers/model_doc/convbert)** (YituTech から) Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan から公開された研究論文: [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://huggingface.co/papers/2008.02496)
1. **[ConvNeXT](https://huggingface.co/docs/transformers/model_doc/convnext)** (Facebook AI から) Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie から公開された研究論文: [A ConvNet for the 2020s](https://huggingface.co/papers/2201.03545)
1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://huggingface.co/papers/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
1. **[CPM](https://huggingface.co/docs/transformers/model_doc/cpm)** (Tsinghua University から) Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun から公開された研究論文: [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://huggingface.co/papers/2012.00413)
1. **[CTRL](https://huggingface.co/docs/transformers/model_doc/ctrl)** (Salesforce から) Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher から公開された研究論文: [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://huggingface.co/papers/1909.05858)
1. **[CvT](https://huggingface.co/docs/transformers/model_doc/cvt)** (Microsoft から) Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang から公開された研究論文: [CvT: Introducing Convolutions to Vision Transformers](https://huggingface.co/papers/2103.15808)
1. **[Data2Vec](https://huggingface.co/docs/transformers/model_doc/data2vec)** (Facebook から) Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli から公開された研究論文: [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://huggingface.co/papers/2202.03555)
1. **[DeBERTa](https://huggingface.co/docs/transformers/model_doc/deberta)** (Microsoft から) Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen から公開された研究論文: [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654)
1. **[DeBERTa-v2](https://huggingface.co/docs/transformers/model_doc/deberta-v2)** (Microsoft から) Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen から公開された研究論文: [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654)
1. **[Decision Transformer](https://huggingface.co/docs/transformers/model_doc/decision_transformer)** (Berkeley/Facebook/Google から) Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch から公開された研究論文: [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://huggingface.co/papers/2106.01345)
1. **[Deformable DETR](https://huggingface.co/docs/transformers/model_doc/deformable_detr)** (SenseTime Research から) Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai から公開された研究論文: [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://huggingface.co/papers/2010.04159)
1. **[DeiT](https://huggingface.co/docs/transformers/model_doc/deit)** (Facebook から) Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou から公開された研究論文: [Training data-efficient image transformers & distillation through attention](https://huggingface.co/papers/2012.12877)
1. **[DETR](https://huggingface.co/docs/transformers/model_doc/detr)** (Facebook から) Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko から公開された研究論文: [End-to-End Object Detection with Transformers](https://huggingface.co/papers/2005.12872)
1. **[DialoGPT](https://huggingface.co/docs/transformers/model_doc/dialogpt)** (Microsoft Research から) Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan から公開された研究論文: [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://huggingface.co/papers/1911.00536)
1. **[DiNAT](https://huggingface.co/docs/transformers/model_doc/dinat)** (SHI Labs から) Ali Hassani and Humphrey Shi から公開された研究論文: [Dilated Neighborhood Attention Transformer](https://huggingface.co/papers/2209.15001)
1. **[DistilBERT](https://huggingface.co/docs/transformers/model_doc/distilbert)** (HuggingFace から), Victor Sanh, Lysandre Debut and Thomas Wolf. 同じ手法で GPT2, RoBERTa と Multilingual BERT の圧縮を行いました.圧縮されたモデルはそれぞれ [DistilGPT2](https://github.com/huggingface/transformers-research-projects/tree/main/distillation)、[DistilRoBERTa](https://github.com/huggingface/transformers-research-projects/tree/main/distillation)、[DistilmBERT](https://github.com/huggingface/transformers-research-projects/tree/main/distillation) と名付けられました. 公開された研究論文: [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://huggingface.co/papers/1910.01108)
1. **[DiT](https://huggingface.co/docs/transformers/model_doc/dit)** (Microsoft Research から) Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei から公開された研究論文: [DiT: Self-supervised Pre-training for Document Image Transformer](https://huggingface.co/papers/2203.02378)
1. **[Donut](https://huggingface.co/docs/transformers/model_doc/donut)** (NAVER から), Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park から公開された研究論文: [OCR-free Document Understanding Transformer](https://huggingface.co/papers/2111.15664)
1. **[DPR](https://huggingface.co/docs/transformers/model_doc/dpr)** (Facebook から) Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih から公開された研究論文: [Dense Passage Retrieval for Open-Domain Question Answering](https://huggingface.co/papers/2004.04906)
1. **[DPT](https://huggingface.co/docs/transformers/master/model_doc/dpt)** (Intel Labs から) René Ranftl, Alexey Bochkovskiy, Vladlen Koltun から公開された研究論文: [Vision Transformers for Dense Prediction](https://huggingface.co/papers/2103.13413)
1. **[EfficientNet](https://huggingface.co/docs/transformers/model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://huggingface.co/papers/1905.11946) by Mingxing Tan and Quoc V. Le.
1. **[ELECTRA](https://huggingface.co/docs/transformers/model_doc/electra)** (Google Research/Stanford University から) Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning から公開された研究論文: [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://huggingface.co/papers/2003.10555)
1. **[EncoderDecoder](https://huggingface.co/docs/transformers/model_doc/encoder-decoder)** (Google Research から) Sascha Rothe, Shashi Narayan, Aliaksei Severyn から公開された研究論文: [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461)
1. **[ERNIE](https://huggingface.co/docs/transformers/model_doc/ernie)** (Baidu から) Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu から公開された研究論文: [ERNIE: Enhanced Representation through Knowledge Integration](https://huggingface.co/papers/1904.09223)
1. **[ESM](https://huggingface.co/docs/transformers/model_doc/esm)** (Meta AI から) はトランスフォーマープロテイン言語モデルです. **ESM-1b** は Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus から公開された研究論文: [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118). **ESM-1v** は Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives から公開された研究論文: [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648). **ESM-2** と **ESMFold** は Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives から公開された研究論文: [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902)
1. **[FLAN-T5](https://huggingface.co/docs/transformers/model_doc/flan-t5)** (Google AI から) Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V から公開されたレポジトリー [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) Le, and Jason Wei
1. **[FlauBERT](https://huggingface.co/docs/transformers/model_doc/flaubert)** (CNRS から) Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab から公開された研究論文: [FlauBERT: Unsupervised Language Model Pre-training for French](https://huggingface.co/papers/1912.05372)
1. **[FLAVA](https://huggingface.co/docs/transformers/model_doc/flava)** (Facebook AI から) Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela から公開された研究論文: [FLAVA: A Foundational Language And Vision Alignment Model](https://huggingface.co/papers/2112.04482)
1. **[FNet](https://huggingface.co/docs/transformers/model_doc/fnet)** (Google Research から) James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon から公開された研究論文: [FNet: Mixing Tokens with Fourier Transforms](https://huggingface.co/papers/2105.03824)
1. **[Funnel Transformer](https://huggingface.co/docs/transformers/model_doc/funnel)** (CMU/Google Brain から) Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le から公開された研究論文: [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://huggingface.co/papers/2006.03236)
1. **[GIT](https://huggingface.co/docs/transformers/main/model_doc/git)** (Microsoft Research から) Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang. から公開された研究論文 [GIT: A Generative Image-to-text Transformer for Vision and Language](https://huggingface.co/papers/2205.14100)
1. **[GLPN](https://huggingface.co/docs/transformers/model_doc/glpn)** (KAIST から) Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim から公開された研究論文: [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436)
1. **[GPT](https://huggingface.co/docs/transformers/model_doc/openai-gpt)** (OpenAI から) Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever から公開された研究論文: [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/)
1. **[GPT Neo](https://huggingface.co/docs/transformers/model_doc/gpt_neo)** (EleutherAI から) Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy から公開されたレポジトリー : [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo)
1. **[GPT NeoX](https://huggingface.co/docs/transformers/model_doc/gpt_neox)** (EleutherAI から) Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach から公開された研究論文: [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://huggingface.co/papers/2204.06745)
1. **[GPT NeoX Japanese](https://huggingface.co/docs/transformers/model_doc/gpt_neox_japanese)** (ABEJA から) Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori からリリース.
1. **[GPT-2](https://huggingface.co/docs/transformers/model_doc/gpt2)** (OpenAI から) Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever から公開された研究論文: [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/)
1. **[GPT-J](https://huggingface.co/docs/transformers/model_doc/gptj)** (EleutherAI から) Ben Wang and Aran Komatsuzaki から公開されたレポジトリー [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/)
1. **[GPT-Sw3](https://huggingface.co/docs/transformers/main/model_doc/gpt-sw3)** (AI-Sweden から) Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman, Fredrik Carlsson, Magnus Sahlgren から公開された研究論文: [Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf)
1. **[GroupViT](https://huggingface.co/docs/transformers/model_doc/groupvit)** (UCSD, NVIDIA から) Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang から公開された研究論文: [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://huggingface.co/papers/2202.11094)
1. **[Hubert](https://huggingface.co/docs/transformers/model_doc/hubert)** (Facebook から) Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed から公開された研究論文: [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://huggingface.co/papers/2106.07447)
1. **[I-BERT](https://huggingface.co/docs/transformers/model_doc/ibert)** (Berkeley から) Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer から公開された研究論文: [I-BERT: Integer-only BERT Quantization](https://huggingface.co/papers/2101.01321)
1. **[ImageGPT](https://huggingface.co/docs/transformers/model_doc/imagegpt)** (OpenAI から) Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever から公開された研究論文: [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/)
1. **[Jukebox](https://huggingface.co/docs/transformers/model_doc/jukebox)** (OpenAI から) Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever から公開された研究論文: [Jukebox: A Generative Model for Music](https://huggingface.co/papers/2005.00341)
1. **[LayoutLM](https://huggingface.co/docs/transformers/model_doc/layoutlm)** (Microsoft Research Asia から) Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou から公開された研究論文: [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://huggingface.co/papers/1912.13318)
1. **[LayoutLMv2](https://huggingface.co/docs/transformers/model_doc/layoutlmv2)** (Microsoft Research Asia から) Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou から公開された研究論文: [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://huggingface.co/papers/2012.14740)
1. **[LayoutLMv3](https://huggingface.co/docs/transformers/model_doc/layoutlmv3)** (Microsoft Research Asia から) Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei から公開された研究論文: [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://huggingface.co/papers/2204.08387)
1. **[LayoutXLM](https://huggingface.co/docs/transformers/model_doc/layoutxlm)** (Microsoft Research Asia から) Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei から公開された研究論文: [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://huggingface.co/papers/2104.08836)
1. **[LED](https://huggingface.co/docs/transformers/model_doc/led)** (AllenAI から) Iz Beltagy, Matthew E. Peters, Arman Cohan から公開された研究論文: [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150)
1. **[LeViT](https://huggingface.co/docs/transformers/model_doc/levit)** (Meta AI から) Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze から公開された研究論文: [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://huggingface.co/papers/2104.01136)
1. **[LiLT](https://huggingface.co/docs/transformers/model_doc/lilt)** (South China University of Technology から) Jiapeng Wang, Lianwen Jin, Kai Ding から公開された研究論文: [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://huggingface.co/papers/2202.13669)
1. **[Longformer](https://huggingface.co/docs/transformers/model_doc/longformer)** (AllenAI から) Iz Beltagy, Matthew E. Peters, Arman Cohan から公開された研究論文: [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150)
1. **[LongT5](https://huggingface.co/docs/transformers/model_doc/longt5)** (Google AI から) Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang から公開された研究論文: [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://huggingface.co/papers/2112.07916)
1. **[LUKE](https://huggingface.co/docs/transformers/model_doc/luke)** (Studio Ousia から) Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto から公開された研究論文: [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://huggingface.co/papers/2010.01057)
1. **[LXMERT](https://huggingface.co/docs/transformers/model_doc/lxmert)** (UNC Chapel Hill から) Hao Tan and Mohit Bansal から公開された研究論文: [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://huggingface.co/papers/1908.07490)
1. **[M-CTC-T](https://huggingface.co/docs/transformers/model_doc/mctct)** (Facebook から) Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert から公開された研究論文: [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://huggingface.co/papers/2111.00161)
1. **[M2M100](https://huggingface.co/docs/transformers/model_doc/m2m_100)** (Facebook から) Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin から公開された研究論文: [Beyond English-Centric Multilingual Machine Translation](https://huggingface.co/papers/2010.11125)
1. **[MarianMT](https://huggingface.co/docs/transformers/model_doc/marian)** Jörg Tiedemann から. [OPUS](http://opus.nlpl.eu/) を使いながら学習された "Machine translation" (マシントランスレーション) モデル. [Marian Framework](https://marian-nmt.github.io/) はMicrosoft Translator Team が現在開発中です.
1. **[MarkupLM](https://huggingface.co/docs/transformers/model_doc/markuplm)** (Microsoft Research Asia から) Junlong Li, Yiheng Xu, Lei Cui, Furu Wei から公開された研究論文: [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://huggingface.co/papers/2110.08518)
1. **[Mask2Former](https://huggingface.co/docs/transformers/main/model_doc/mask2former)** (FAIR and UIUC から) Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar. から公開された研究論文 [Masked-attention Mask Transformer for Universal Image Segmentation](https://huggingface.co/papers/2112.01527)
1. **[MaskFormer](https://huggingface.co/docs/transformers/model_doc/maskformer)** (Meta and UIUC から) Bowen Cheng, Alexander G. Schwing, Alexander Kirillov から公開された研究論文: [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://huggingface.co/papers/2107.06278)
1. **[mBART](https://huggingface.co/docs/transformers/model_doc/mbart)** (Facebook から) Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer から公開された研究論文: [Multilingual Denoising Pre-training for Neural Machine Translation](https://huggingface.co/papers/2001.08210)
1. **[mBART-50](https://huggingface.co/docs/transformers/model_doc/mbart)** (Facebook から) Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan から公開された研究論文: [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://huggingface.co/papers/2008.00401)
1. **[Megatron-BERT](https://huggingface.co/docs/transformers/model_doc/megatron-bert)** (NVIDIA から) Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro から公開された研究論文: [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053)
1. **[Megatron-GPT2](https://huggingface.co/docs/transformers/model_doc/megatron_gpt2)** (NVIDIA から) Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro から公開された研究論文: [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053)
1. **[mLUKE](https://huggingface.co/docs/transformers/model_doc/mluke)** (Studio Ousia から) Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka から公開された研究論文: [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://huggingface.co/papers/2110.08151)
1. **[MobileBERT](https://huggingface.co/docs/transformers/model_doc/mobilebert)** (CMU/Google Brain から) Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou から公開された研究論文: [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://huggingface.co/papers/2004.02984)
1. **[MobileNetV1](https://huggingface.co/docs/transformers/model_doc/mobilenet_v1)** (Google Inc. から) Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam から公開された研究論文: [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://huggingface.co/papers/1704.04861)
1. **[MobileNetV2](https://huggingface.co/docs/transformers/model_doc/mobilenet_v2)** (Google Inc. から) Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen から公開された研究論文: [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://huggingface.co/papers/1801.04381)
1. **[MobileViT](https://huggingface.co/docs/transformers/model_doc/mobilevit)** (Apple から) Sachin Mehta and Mohammad Rastegari から公開された研究論文: [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://huggingface.co/papers/2110.02178)
1. **[MPNet](https://huggingface.co/docs/transformers/model_doc/mpnet)** (Microsoft Research から) Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu から公開された研究論文: [MPNet: Masked and Permuted Pre-training for Language Understanding](https://huggingface.co/papers/2004.09297)
1. **[MT5](https://huggingface.co/docs/transformers/model_doc/mt5)** (Google AI から) Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel から公開された研究論文: [mT5: A massively multilingual pre-trained text-to-text transformer](https://huggingface.co/papers/2010.11934)
1. **[MVP](https://huggingface.co/docs/transformers/model_doc/mvp)** (RUC AI Box から) Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen から公開された研究論文: [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://huggingface.co/papers/2206.12131)
1. **[NAT](https://huggingface.co/docs/transformers/model_doc/nat)** (SHI Labs から) Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi から公開された研究論文: [Neighborhood Attention Transformer](https://huggingface.co/papers/2204.07143)
1. **[Nezha](https://huggingface.co/docs/transformers/model_doc/nezha)** (Huawei Noah’s Ark Lab から) Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu から公開された研究論文: [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://huggingface.co/papers/1909.00204)
1. **[NLLB](https://huggingface.co/docs/transformers/model_doc/nllb)** (Meta から) the NLLB team から公開された研究論文: [No Language Left Behind: Scaling Human-Centered Machine Translation](https://huggingface.co/papers/2207.04672)
1. **[Nyströmformer](https://huggingface.co/docs/transformers/model_doc/nystromformer)** (the University of Wisconsin - Madison から) Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh から公開された研究論文: [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://huggingface.co/papers/2102.03902)
1. **[OneFormer](https://huggingface.co/docs/transformers/main/model_doc/oneformer)** (SHI Labs から) Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi から公開された研究論文: [OneFormer: One Transformer to Rule Universal Image Segmentation](https://huggingface.co/papers/2211.06220)
1. **[OPT](https://huggingface.co/docs/transformers/master/model_doc/opt)** (Meta AI から) Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al から公開された研究論文: [OPT: Open Pre-trained Transformer Language Models](https://huggingface.co/papers/2205.01068)
1. **[OWL-ViT](https://huggingface.co/docs/transformers/model_doc/owlvit)** (Google AI から) Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby から公開された研究論文: [Simple Open-Vocabulary Object Detection with Vision Transformers](https://huggingface.co/papers/2205.06230)
1. **[Pegasus](https://huggingface.co/docs/transformers/model_doc/pegasus)** (Google から) Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu から公開された研究論文: [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://huggingface.co/papers/1912.08777)
1. **[PEGASUS-X](https://huggingface.co/docs/transformers/model_doc/pegasus_x)** (Google から) Jason Phang, Yao Zhao, and Peter J. Liu から公開された研究論文: [Investigating Efficiently Extending Transformers for Long Input Summarization](https://huggingface.co/papers/2208.04347)
1. **[Perceiver IO](https://huggingface.co/docs/transformers/model_doc/perceiver)** (Deepmind から) Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira から公開された研究論文: [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://huggingface.co/papers/2107.14795)
1. **[PhoBERT](https://huggingface.co/docs/transformers/model_doc/phobert)** (VinAI Research から) Dat Quoc Nguyen and Anh Tuan Nguyen から公開された研究論文: [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/)
1. **[PLBart](https://huggingface.co/docs/transformers/model_doc/plbart)** (UCLA NLP から) Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang から公開された研究論文: [Unified Pre-training for Program Understanding and Generation](https://huggingface.co/papers/2103.06333)
1. **[PoolFormer](https://huggingface.co/docs/transformers/model_doc/poolformer)** (Sea AI Labs から) Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng から公開された研究論文: [MetaFormer is Actually What You Need for Vision](https://huggingface.co/papers/2111.11418)
1. **[ProphetNet](https://huggingface.co/docs/transformers/model_doc/prophetnet)** (Microsoft Research から) Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou から公開された研究論文: [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063)
1. **[QDQBert](https://huggingface.co/docs/transformers/model_doc/qdqbert)** (NVIDIA から) Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius から公開された研究論文: [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://huggingface.co/papers/2004.09602)
1. **[RAG](https://huggingface.co/docs/transformers/model_doc/rag)** (Facebook から) Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela から公開された研究論文: [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://huggingface.co/papers/2005.11401)
1. **[REALM](https://huggingface.co/docs/transformers/model_doc/realm.html)** (Google Research から) Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang から公開された研究論文: [REALM: Retrieval-Augmented Language Model Pre-Training](https://huggingface.co/papers/2002.08909)
1. **[Reformer](https://huggingface.co/docs/transformers/model_doc/reformer)** (Google Research から) Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya から公開された研究論文: [Reformer: The Efficient Transformer](https://huggingface.co/papers/2001.04451)
1. **[RegNet](https://huggingface.co/docs/transformers/model_doc/regnet)** (META Platforms から) Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár から公開された研究論文: [Designing Network Design Space](https://huggingface.co/papers/2003.13678)
1. **[RemBERT](https://huggingface.co/docs/transformers/model_doc/rembert)** (Google Research から) Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder から公開された研究論文: [Rethinking embedding coupling in pre-trained language models](https://huggingface.co/papers/2010.12821)
1. **[ResNet](https://huggingface.co/docs/transformers/model_doc/resnet)** (Microsoft Research から) Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun から公開された研究論文: [Deep Residual Learning for Image Recognition](https://huggingface.co/papers/1512.03385)
1. **[RoBERTa](https://huggingface.co/docs/transformers/model_doc/roberta)** (Facebook から), Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov から公開された研究論文: [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://huggingface.co/papers/1907.11692)
1. **[RoBERTa-PreLayerNorm](https://huggingface.co/docs/transformers/main/model_doc/roberta-prelayernorm)** (Facebook から) Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli から公開された研究論文: [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://huggingface.co/papers/1904.01038)
1. **[RoCBert](https://huggingface.co/docs/transformers/main/model_doc/roc_bert)** (WeChatAI から) HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou から公開された研究論文: [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf)
1. **[RoFormer](https://huggingface.co/docs/transformers/model_doc/roformer)** (ZhuiyiTechnology から), Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu から公開された研究論文: [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://huggingface.co/papers/2104.09864)
1. **[SegFormer](https://huggingface.co/docs/transformers/model_doc/segformer)** (NVIDIA から) Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo から公開された研究論文: [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://huggingface.co/papers/2105.15203)
1. **[SEW](https://huggingface.co/docs/transformers/model_doc/sew)** (ASAPP から) Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi から公開された研究論文: [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870)
1. **[SEW-D](https://huggingface.co/docs/transformers/model_doc/sew_d)** (ASAPP から) Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi から公開された研究論文: [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870)
1. **[SpeechToTextTransformer](https://huggingface.co/docs/transformers/model_doc/speech_to_text)** (Facebook から), Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino から公開された研究論文: [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://huggingface.co/papers/2010.05171)
1. **[SpeechToTextTransformer2](https://huggingface.co/docs/transformers/model_doc/speech_to_text_2)** (Facebook から), Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau から公開された研究論文: [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://huggingface.co/papers/2104.06678)
1. **[Splinter](https://huggingface.co/docs/transformers/model_doc/splinter)** (Tel Aviv University から), Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy から公開された研究論文: [Few-Shot Question Answering by Pretraining Span Selection](https://huggingface.co/papers/2101.00438)
1. **[SqueezeBERT](https://huggingface.co/docs/transformers/model_doc/squeezebert)** (Berkeley から) Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer から公開された研究論文: [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://huggingface.co/papers/2006.11316)
1. **[Swin Transformer](https://huggingface.co/docs/transformers/model_doc/swin)** (Microsoft から) Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo から公開された研究論文: [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://huggingface.co/papers/2103.14030)
1. **[Swin Transformer V2](https://huggingface.co/docs/transformers/model_doc/swinv2)** (Microsoft から) Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo から公開された研究論文: [Swin Transformer V2: Scaling Up Capacity and Resolution](https://huggingface.co/papers/2111.09883)
1. **[Swin2SR](https://huggingface.co/docs/transformers/main/model_doc/swin2sr)** (University of Würzburg から) Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte から公開された研究論文: [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://huggingface.co/papers/2209.11345)
1. **[SwitchTransformers](https://huggingface.co/docs/transformers/main/model_doc/switch_transformers)** (Google から) William Fedus, Barret Zoph, Noam Shazeer から公開された研究論文: [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://huggingface.co/papers/2101.03961)
1. **[T5](https://huggingface.co/docs/transformers/model_doc/t5)** (Google AI から) Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu から公開された研究論文: [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://huggingface.co/papers/1910.10683)
1. **[T5v1.1](https://huggingface.co/docs/transformers/model_doc/t5v1.1)** (Google AI から) Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu から公開されたレポジトリー [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511)
1. **[Table Transformer](https://huggingface.co/docs/transformers/model_doc/table-transformer)** (Microsoft Research から) Brandon Smock, Rohith Pesala, Robin Abraham から公開された研究論文: [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://huggingface.co/papers/2110.00061)
1. **[TAPAS](https://huggingface.co/docs/transformers/model_doc/tapas)** (Google AI から) Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos から公開された研究論文: [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://huggingface.co/papers/2004.02349)
1. **[TAPEX](https://huggingface.co/docs/transformers/model_doc/tapex)** (Microsoft Research から) Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou から公開された研究論文: [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://huggingface.co/papers/2107.07653)
1. **[Time Series Transformer](https://huggingface.co/docs/transformers/model_doc/time_series_transformer)** (HuggingFace から).
1. **[TimeSformer](https://huggingface.co/docs/transformers/main/model_doc/timesformer)** (Facebook から) Gedas Bertasius, Heng Wang, Lorenzo Torresani から公開された研究論文: [Is Space-Time Attention All You Need for Video Understanding?](https://huggingface.co/papers/2102.05095)
1. **[Trajectory Transformer](https://huggingface.co/docs/transformers/model_doc/trajectory_transformers)** (the University of California at Berkeley から) Michael Janner, Qiyang Li, Sergey Levine から公開された研究論文: [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://huggingface.co/papers/2106.02039)
1. **[Transformer-XL](https://huggingface.co/docs/transformers/model_doc/transfo-xl)** (Google/CMU から) Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov から公開された研究論文: [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://huggingface.co/papers/1901.02860)
1. **[TrOCR](https://huggingface.co/docs/transformers/model_doc/trocr)** (Microsoft から), Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei から公開された研究論文: [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://huggingface.co/papers/2109.10282)
1. **[UL2](https://huggingface.co/docs/transformers/model_doc/ul2)** (Google Research から) Yi Tay, Mostafa Dehghani, Vinh Q から公開された研究論文: [Unifying Language Learning Paradigms](https://huggingface.co/papers/2205.05131) Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
1. **[UniSpeech](https://huggingface.co/docs/transformers/model_doc/unispeech)** (Microsoft Research から) Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang から公開された研究論文: [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://huggingface.co/papers/2101.07597)
1. **[UniSpeechSat](https://huggingface.co/docs/transformers/model_doc/unispeech-sat)** (Microsoft Research から) Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu から公開された研究論文: [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://huggingface.co/papers/2110.05752)
1. **[UPerNet](https://huggingface.co/docs/transformers/main/model_doc/upernet)** (Peking University から) Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun. から公開された研究論文 [Unified Perceptual Parsing for Scene Understanding](https://huggingface.co/papers/1807.10221)
1. **[VAN](https://huggingface.co/docs/transformers/model_doc/van)** (Tsinghua University and Nankai University から) Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu から公開された研究論文: [Visual Attention Network](https://huggingface.co/papers/2202.09741)
1. **[VideoMAE](https://huggingface.co/docs/transformers/model_doc/videomae)** (Multimedia Computing Group, Nanjing University から) Zhan Tong, Yibing Song, Jue Wang, Limin Wang から公開された研究論文: [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://huggingface.co/papers/2203.12602)
1. **[ViLT](https://huggingface.co/docs/transformers/model_doc/vilt)** (NAVER AI Lab/Kakao Enterprise/Kakao Brain から) Wonjae Kim, Bokyung Son, Ildoo Kim から公開された研究論文: [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://huggingface.co/papers/2102.03334)
1. **[Vision Transformer (ViT)](https://huggingface.co/docs/transformers/model_doc/vit)** (Google AI から) Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby から公開された研究論文: [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929)
1. **[VisualBERT](https://huggingface.co/docs/transformers/model_doc/visual_bert)** (UCLA NLP から) Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang から公開された研究論文: [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://huggingface.co/papers/1908.03557)
1. **[ViT Hybrid](https://huggingface.co/docs/transformers/main/model_doc/vit_hybrid)** (Google AI から) Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby から公開された研究論文: [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929)
1. **[ViTMAE](https://huggingface.co/docs/transformers/model_doc/vit_mae)** (Meta AI から) Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick から公開された研究論文: [Masked Autoencoders Are Scalable Vision Learners](https://huggingface.co/papers/2111.06377)
1. **[ViTMSN](https://huggingface.co/docs/transformers/model_doc/vit_msn)** (Meta AI から) Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas から公開された研究論文: [Masked Siamese Networks for Label-Efficient Learning](https://huggingface.co/papers/2204.07141)
1. **[Wav2Vec2](https://huggingface.co/docs/transformers/model_doc/wav2vec2)** (Facebook AI から) Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli から公開された研究論文: [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://huggingface.co/papers/2006.11477)
1. **[Wav2Vec2-Conformer](https://huggingface.co/docs/transformers/model_doc/wav2vec2-conformer)** (Facebook AI から) Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino から公開された研究論文: [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://huggingface.co/papers/2010.05171)
1. **[Wav2Vec2Phoneme](https://huggingface.co/docs/transformers/model_doc/wav2vec2_phoneme)** (Facebook AI から) Qiantong Xu, Alexei Baevski, Michael Auli から公開された研究論文: [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://huggingface.co/papers/2109.11680)
1. **[WavLM](https://huggingface.co/docs/transformers/model_doc/wavlm)** (Microsoft Research から) Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei から公開された研究論文: [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://huggingface.co/papers/2110.13900)
1. **[Whisper](https://huggingface.co/docs/transformers/model_doc/whisper)** (OpenAI から) Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever から公開された研究論文: [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf)
1. **[X-CLIP](https://huggingface.co/docs/transformers/model_doc/xclip)** (Microsoft Research から) Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling から公開された研究論文: [Expanding Language-Image Pretrained Models for General Video Recognition](https://huggingface.co/papers/2208.02816)
1. **[XGLM](https://huggingface.co/docs/transformers/model_doc/xglm)** (From Facebook AI) Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li から公開された研究論文: [Few-shot Learning with Multilingual Language Models](https://huggingface.co/papers/2112.10668)
1. **[XLM](https://huggingface.co/docs/transformers/model_doc/xlm)** (Facebook から) Guillaume Lample and Alexis Conneau から公開された研究論文: [Cross-lingual Language Model Pretraining](https://huggingface.co/papers/1901.07291)
1. **[XLM-ProphetNet](https://huggingface.co/docs/transformers/model_doc/xlm-prophetnet)** (Microsoft Research から) Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou から公開された研究論文: [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063)
1. **[XLM-RoBERTa](https://huggingface.co/docs/transformers/model_doc/xlm-roberta)** (Facebook AI から), Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov から公開された研究論文: [Unsupervised Cross-lingual Representation Learning at Scale](https://huggingface.co/papers/1911.02116)
1. **[XLM-RoBERTa-XL](https://huggingface.co/docs/transformers/model_doc/xlm-roberta-xl)** (Facebook AI から), Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau から公開された研究論文: [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://huggingface.co/papers/2105.00572)
1. **[XLNet](https://huggingface.co/docs/transformers/model_doc/xlnet)** (Google/CMU から) Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le から公開された研究論文: [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://huggingface.co/papers/1906.08237)
1. **[XLS-R](https://huggingface.co/docs/transformers/model_doc/xls_r)** (Facebook AI から) Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli から公開された研究論文: [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://huggingface.co/papers/2111.09296)
1. **[XLSR-Wav2Vec2](https://huggingface.co/docs/transformers/model_doc/xlsr_wav2vec2)** (Facebook AI から) Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli から公開された研究論文: [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://huggingface.co/papers/2006.13979)
1. **[YOLOS](https://huggingface.co/docs/transformers/model_doc/yolos)** (Huazhong University of Science & Technology から) Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu から公開された研究論文: [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://huggingface.co/papers/2106.00666)
1. **[YOSO](https://huggingface.co/docs/transformers/model_doc/yoso)** (the University of Wisconsin - Madison から) Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh から公開された研究論文: [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://huggingface.co/papers/2111.09714)
### サポートされているフレームワーク
以下のテーブルはそれぞれのモデルでサポートされているライブラリを示しています。"slow"と呼ばれるPythonトークナイザー、🤗 Tokenizers ライブラリによる"fast"トークナイザー、PyTorch, TensorFlow, Flaxの5つのそれぞれがサポートされているかを示しています。
| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
|:-----------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| AltCLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| Audio Spectrogram Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
| BioGpt | ✅ | ❌ | ✅ | ❌ | ❌ |
| BiT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
| BLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
| Chinese-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DiNAT | ❌ | ❌ | ✅ | ❌ | ❌ |
| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| GIT | ❌ | ❌ | ✅ | ❌ | ❌ |
| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
| GPT-Sw3 | ✅ | ✅ | ✅ | ✅ | ✅ |
| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
| Mask2Former | ❌ | ❌ | ✅ | ❌ | ❌ |
| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| MaskFormerSwin | ❌ | ❌ | ❌ | ❌ | ❌ |
| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| MobileNetV1 | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileNetV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
| NAT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| RoBERTa-PreLayerNorm | ❌ | ❌ | ✅ | ✅ | ✅ |
| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
| Swin2SR | ❌ | ❌ | ✅ | ❌ | ❌ |
| SwitchTransformers | ❌ | ❌ | ✅ | ❌ | ❌ |
| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| TimeSformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
| UPerNet | ❌ | ❌ | ✅ | ❌ | ❌ |
| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
| ViT Hybrid | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
---
### Source Ko Index (`docs/source/ko/index.md`)
# 🤗 Transformers
[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), [JAX](https://jax.readthedocs.io/en/latest/)를 위한 최첨단 머신러닝
🤗 Transformers는 사전학습된 최첨단 모델들을 쉽게 다운로드하고 훈련시킬 수 있는 API와 도구를 제공합니다. 사전학습된 모델을 쓰면 컴퓨팅 비용과 탄소 배출량이 줄고, 모델을 처음부터 훈련시키는 데 필요한 시간과 리소스를 절약할 수 있습니다. 저희 모델들은 다양한 분야의 태스크를 지원합니다.
📝 **자연어 처리**: 텍스트 분류, 개체명 인식, 질의응답, 언어 모델링, 요약, 번역, 객관식 질의응답, 텍스트 생성
## 콘텐츠[[contents]]
저희 기술문서는 크게 5개 섹션으로 나눌 수 있습니다:
- **시작하기**에서 라이브러리를 간단히 훑어보고, 본격적으로 뛰어들 수 있게 설치 방법을 안내합니다.
- **튜토리얼**에서 라이브러리에 익숙해질 수 있도록 자세하고도 쉽게 기본적인 부분을 안내합니다.
- **How-to 가이드**에서 언어 모델링을 위해 사전학습된 모델을 파인 튜닝하는 방법이나, 직접 모델을 작성하고 공유하는 방법과 같이 특정 목표를 달성하는 방법을 안내합니다.
- **개념 가이드**에서 🤗 Transformers의 설계 철학과 함께 모델이나 태스크 뒤에 숨겨진 개념들과 아이디어를 탐구하고 설명을 덧붙입니다.
- **API**에서 모든 클래스와 함수를 설명합니다.
- **메인 클래스**에서 configuration, model, tokenizer, pipeline과 같이 제일 중요한 클래스들을 자세히 설명합니다.
- **모델**에서 라이브러리 속 구현된 각 모델과 연관된 클래스와 함수를 자세히 설명합니다.
- **내부 유틸리티**에서 내부적으로 사용되는 유틸리티 클래스와 함수를 자세히 설명합니다.
### 지원 모델[[supported-models]]
1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://huggingface.co/papers/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://huggingface.co/papers/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://huggingface.co/papers/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://huggingface.co/papers/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://huggingface.co/papers/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://huggingface.co/papers/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://huggingface.co/papers/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://huggingface.co/papers/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://huggingface.co/papers/2010.10499) by Adrian de Wynter and Daniel J. Perry.
1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://huggingface.co/papers/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://huggingface.co/papers/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://huggingface.co/papers/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://huggingface.co/papers/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://huggingface.co/papers/2112.10003) by Timo Lüddecke and Alexander Ecker.
1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://huggingface.co/papers/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://huggingface.co/papers/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://huggingface.co/papers/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://huggingface.co/papers/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://huggingface.co/papers/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://huggingface.co/papers/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://huggingface.co/papers/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://huggingface.co/papers/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://huggingface.co/papers/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://huggingface.co/papers/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://huggingface.co/papers/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://huggingface.co/papers/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://huggingface.co/papers/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://huggingface.co/papers/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://huggingface.co/papers/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://huggingface.co/papers/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers-research-projects/tree/main/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers-research-projects/tree/main/distillation) and a German version of DistilBERT.
1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://huggingface.co/papers/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://huggingface.co/papers/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://huggingface.co/papers/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://huggingface.co/papers/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://huggingface.co/papers/1905.11946) by Mingxing Tan and Quoc V. Le.
1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://huggingface.co/papers/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://huggingface.co/papers/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://huggingface.co/papers/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://huggingface.co/papers/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://huggingface.co/papers/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://huggingface.co/papers/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://huggingface.co/papers/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://huggingface.co/papers/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://huggingface.co/papers/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://huggingface.co/papers/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://huggingface.co/papers/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://huggingface.co/papers/2005.00341) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://huggingface.co/papers/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://huggingface.co/papers/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://huggingface.co/papers/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://huggingface.co/papers/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://huggingface.co/papers/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://huggingface.co/papers/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://huggingface.co/papers/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://huggingface.co/papers/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://huggingface.co/papers/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://huggingface.co/papers/1908.07490) by Hao Tan and Mohit Bansal.
1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://huggingface.co/papers/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://huggingface.co/papers/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://huggingface.co/papers/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://huggingface.co/papers/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://huggingface.co/papers/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://huggingface.co/papers/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://huggingface.co/papers/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://huggingface.co/papers/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://huggingface.co/papers/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://huggingface.co/papers/2110.02178) by Sachin Mehta and Mohammad Rastegari.
1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://huggingface.co/papers/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://huggingface.co/papers/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://huggingface.co/papers/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://huggingface.co/papers/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://huggingface.co/papers/2207.04672) by the NLLB team.
1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://huggingface.co/papers/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://huggingface.co/papers/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://huggingface.co/papers/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://huggingface.co/papers/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://huggingface.co/papers/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://huggingface.co/papers/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://huggingface.co/papers/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://huggingface.co/papers/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://huggingface.co/papers/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://huggingface.co/papers/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://huggingface.co/papers/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://huggingface.co/papers/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://huggingface.co/papers/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://huggingface.co/papers/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://huggingface.co/papers/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://huggingface.co/papers/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://huggingface.co/papers/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://huggingface.co/papers/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://huggingface.co/papers/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://huggingface.co/papers/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://huggingface.co/papers/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://huggingface.co/papers/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://huggingface.co/papers/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://huggingface.co/papers/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://huggingface.co/papers/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://huggingface.co/papers/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://huggingface.co/papers/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://huggingface.co/papers/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://huggingface.co/papers/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://huggingface.co/papers/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://huggingface.co/papers/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://huggingface.co/papers/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://huggingface.co/papers/2205.05131) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://huggingface.co/papers/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://huggingface.co/papers/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://huggingface.co/papers/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://huggingface.co/papers/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://huggingface.co/papers/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://huggingface.co/papers/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://huggingface.co/papers/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://huggingface.co/papers/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://huggingface.co/papers/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://huggingface.co/papers/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://huggingface.co/papers/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://huggingface.co/papers/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://huggingface.co/papers/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://huggingface.co/papers/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://huggingface.co/papers/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://huggingface.co/papers/1901.07291) by Guillaume Lample and Alexis Conneau.
1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://huggingface.co/papers/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://huggingface.co/papers/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://huggingface.co/papers/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://huggingface.co/papers/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://huggingface.co/papers/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://huggingface.co/papers/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://huggingface.co/papers/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://huggingface.co/papers/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
### 지원 프레임워크[[supported-framework]]
아래 표는 라이브러리 속 각 모델의 지원 현황을 나타냅니다. 토큰화를 파이썬 (별칭 "slow") 또는 🤗 Tokenizers (별칭 "fast") 라이브러리로 하는지; (Flax를 통한) Jax, PyTorch, TensorFlow 중 어떤 프레임워크를 지원하는지 표시되어 있습니다.
| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
---
--- METRICS ---
- Files Extracted: 20
- Estimated Token Budget: ~125775 tokens
- Canonical Reference: https://codewiki.google/github.com/huggingface/transformers