# LangExtract
[](https://pypi.org/project/langextract/)
[](https://github.com/google/langextract)
[](https://doi.org/10.5281/zenodo.17015089)
[](https://google-langextract.hf.space/)
## Table of Contents
- [Introduction](#introduction)
- [Why LangExtract?](#why-langextract)
- [Quick Start](#quick-start)
- [Installation](#installation)
- [API Key Setup for Cloud Models](#api-key-setup-for-cloud-models)
- [Adding Custom Model Providers](#adding-custom-model-providers)
- [Using OpenAI Models](#using-openai-models)
- [Using Local LLMs with Ollama](#using-local-llms-with-ollama)
- [More Examples](#more-examples)
- [*Romeo and Juliet* Full Text Extraction](#romeo-and-juliet-full-text-extraction)
- [Medication Extraction](#medication-extraction)
- [Radiology Report Structuring: RadExtract](#radiology-report-structuring-radextract)
- [Community Providers](#community-providers)
- [Contributing](#contributing)
- [Testing](#testing)
- [How to Cite](#how-to-cite)
- [Disclaimer](#disclaimer)
## Introduction
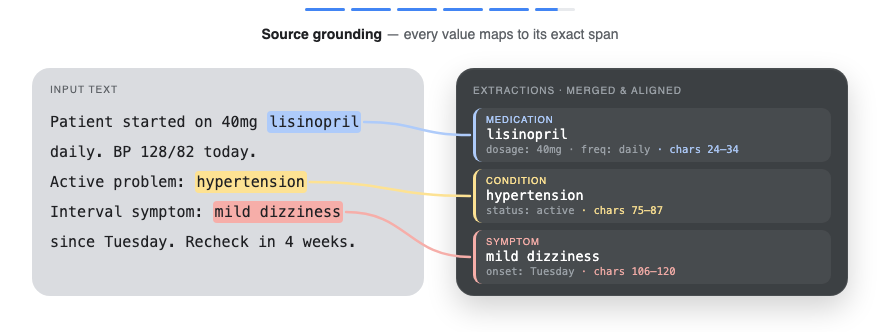
LangExtract is a Python library that uses LLMs to extract structured information from unstructured text documents based on user-defined instructions. It processes materials such as clinical notes or reports, identifying and organizing key details while ensuring the extracted data corresponds to the source text.
Try the live demo → Run grounded extraction on Romeo and Juliet in your browser, no install required.
## Why LangExtract?
1. **Precise Source Grounding:** Maps every extraction to its exact location in the source text, enabling visual highlighting for easy traceability and verification.
2. **Reliable Structured Outputs:** Enforces a consistent output schema based on your few-shot examples, leveraging controlled generation in supported models like Gemini to guarantee robust, structured results.
3. **Optimized for Long Documents:** Overcomes the "needle-in-a-haystack" challenge of large document extraction by using an optimized strategy of text chunking, parallel processing, and multiple passes for higher recall.
4. **Interactive Visualization:** Instantly generates a self-contained, interactive HTML file to visualize and review thousands of extracted entities in their original context.
5. **Flexible LLM Support:** Supports your preferred models, from cloud-based LLMs like the Google Gemini family to local open-source models via the built-in Ollama interface.
6. **Adaptable to Any Domain:** Define extraction tasks for any domain using just a few examples. LangExtract adapts to your needs without requiring any model fine-tuning.
7. **Leverages LLM World Knowledge:** Utilize precise prompt wording and few-shot examples to influence how the extraction task may utilize LLM knowledge. The accuracy of any inferred information and its adherence to the task specification are contingent upon the selected LLM, the complexity of the task, the clarity of the prompt instructions, and the nature of the prompt examples.
## Quick Start
> **Note:** Using cloud-hosted models like Gemini requires an API key. See the [API Key Setup](#api-key-setup-for-cloud-models) section for instructions on how to get and configure your key.
Extract structured information with just a few lines of code.
### 1. Define Your Extraction Task
First, create a prompt that clearly describes what you want to extract. Then, provide a high-quality example to guide the model.
```python
import langextract as lx
import textwrap
# 1. Define the prompt and extraction rules
prompt = textwrap.dedent("""\
Extract characters, emotions, and relationships in order of appearance.
Use exact text for extractions. Do not paraphrase or overlap entities.
Provide meaningful attributes for each entity to add context.""")
# 2. Provide a high-quality example to guide the model
examples = [
lx.data.ExampleData(
text="ROMEO. But soft! What light through yonder window breaks? It is the east, and Juliet is the sun.",
extractions=[
lx.data.Extraction(
extraction_class="character",
extraction_text="ROMEO",
attributes={"emotional_state": "wonder"}
),
lx.data.Extraction(
extraction_class="emotion",
extraction_text="But soft!",
attributes={"feeling": "gentle awe"}
),
lx.data.Extraction(
extraction_class="relationship",
extraction_text="Juliet is the sun",
attributes={"type": "metaphor"}
),
]
)
]
```
> **Note:** Examples drive model behavior. Each `extraction_text` should ideally be verbatim from the example's `text` (no paraphrasing), listed in order of appearance. LangExtract raises `Prompt alignment` warnings by default if examples don't follow this pattern—resolve these for best results.
>
> **Grounding:** LLMs may occasionally extract content from few-shot examples rather than the input text. LangExtract automatically detects this: extractions that cannot be located in the source text will have `char_interval = None`. Filter these out with `[e for e in result.extractions if e.char_interval]` to keep only grounded results.
### 2. Run the Extraction
Provide your input text and the prompt materials to the `lx.extract` function.
```python
# The input text to be processed
input_text = "Lady Juliet gazed longingly at the stars, her heart aching for Romeo"
# Run the extraction
result = lx.extract(
text_or_documents=input_text,
prompt_description=prompt,
examples=examples,
model_id="gemini-3.5-flash",
)
```
For advanced constraints beyond examples, such as enum values on extraction
attributes, Gemini and OpenAI support `output_schema` with or without
few-shot examples. See
[Custom output schemas](docs/examples/output_schema.md).
> **Model Selection**: `gemini-3.5-flash` is the recommended default, offering strong extraction quality for LangExtract's schema-constrained workflows. For high-volume or cost-sensitive workloads, consider the current stable Flash-Lite model, `gemini-3.1-flash-lite`; for highly complex tasks requiring deeper reasoning, evaluate a current Gemini Pro model from the official model documentation. For large-scale or production use, a paid Gemini tier is suggested to increase throughput and avoid rate limits. See the [rate-limit documentation](https://ai.google.dev/gemini-api/docs/rate-limits#usage-tiers) for details.
>
> **Model Lifecycle**: Note that Gemini models have a lifecycle with defined retirement dates. Users should consult the [official model version documentation](https://cloud.google.com/vertex-ai/generative-ai/docs/learn/model-versions) to stay informed about the latest stable and legacy versions.
### 3. Visualize the Results
The extractions can be saved to a `.jsonl` file, a popular format for working with language model data. LangExtract can then generate an interactive HTML visualization from this file to review the entities in context.
```python
# Save the results to a JSONL file
lx.io.save_annotated_documents([result], output_name="extraction_results.jsonl", output_dir=".")
# Generate the visualization from the file
html_content = lx.visualize("extraction_results.jsonl")
with open("visualization.html", "w", encoding="utf-8") as f:
if hasattr(html_content, 'data'):
f.write(html_content.data) # For Jupyter/Colab
else:
f.write(html_content)
```
This creates an animated and interactive HTML file:
> **Note on LLM Knowledge Utilization:** This example demonstrates extractions that stay close to the text evidence - extracting "longing" for Lady Juliet's emotional state and identifying "yearning" from "gazed longingly at the stars." The task could be modified to generate attributes that draw more heavily from the LLM's world knowledge (e.g., adding `"identity": "Capulet family daughter"` or `"literary_context": "tragic heroine"`). The balance between text-evidence and knowledge-inference is controlled by your prompt instructions and example attributes.
### Scaling to Longer Documents
For larger texts, you can process entire documents directly from URLs with parallel processing and enhanced sensitivity:
```python
# Process Romeo & Juliet directly from Project Gutenberg
result = lx.extract(
text_or_documents="https://www.gutenberg.org/files/1513/1513-0.txt",
fetch_urls=True,
prompt_description=prompt,
examples=examples,
model_id="gemini-3.5-flash",
extraction_passes=3, # Improves recall through multiple passes
max_workers=20, # Parallel processing for speed
max_char_buffer=1000 # Smaller contexts for better accuracy
)
```
This approach can extract hundreds of entities from full novels while maintaining high accuracy. The interactive visualization seamlessly handles large result sets, making it easy to explore hundreds of entities from the output JSONL file. **[See the full *Romeo and Juliet* extraction example →](https://github.com/google/langextract/blob/main/docs/examples/longer_text_example.md)** for detailed results and performance insights.
### Vertex AI Batch Processing
Save costs on large-scale tasks by enabling Vertex AI Batch API with
`language_model_params` that include `vertexai=True`, `project`, `location`,
and a `batch` config.
See an example of the Vertex AI Batch API usage in [this example](docs/examples/batch_api_example.md).
## Installation
### From PyPI
```bash
pip install langextract
```
*Recommended for most users. For isolated environments, consider using a virtual environment:*
```bash
python -m venv langextract_env
source langextract_env/bin/activate # On Windows: langextract_env\Scripts\activate
pip install langextract
```
### From Source
LangExtract uses modern Python packaging with `pyproject.toml` for dependency management:
*Installing with `-e` puts the package in development mode, allowing you to modify the code without reinstalling.*
```bash
git clone https://github.com/google/langextract.git
cd langextract
# For basic installation:
pip install -e .
# For development (includes linting tools):
pip install -e ".[dev]"
# For testing (includes pytest):
pip install -e ".[test]"
```
### Docker
```bash
docker build -t langextract .
docker run --rm -e LANGEXTRACT_API_KEY="your-api-key" langextract python your_script.py
```
## API Key Setup for Cloud Models
When using LangExtract with cloud-hosted models (like Gemini or OpenAI), you'll need to
set up an API key. On-device models don't require an API key. For developers
using local LLMs, LangExtract offers built-in support for Ollama and can be
extended to other third-party APIs by updating the inference endpoints.
### API Key Sources
Get API keys from:
* [AI Studio](https://aistudio.google.com/app/apikey) for Gemini models
* [Vertex AI](https://cloud.google.com/vertex-ai/generative-ai/docs/sdks/overview) for enterprise use
* [OpenAI Platform](https://platform.openai.com/api-keys) for OpenAI models
### Setting up API key in your environment
**Option 1: Environment Variable**
```bash
export LANGEXTRACT_API_KEY="your-api-key-here"
```
**Option 2: .env File (Recommended)**
Add your API key to a `.env` file:
```bash
# Add API key to .env file
cat >> .env << 'EOF'
LANGEXTRACT_API_KEY=your-api-key-here
EOF
# Keep your API key secure
echo '.env' >> .gitignore
```
In your Python code:
```python
import langextract as lx
result = lx.extract(
text_or_documents=input_text,
prompt_description="Extract information...",
examples=[...],
model_id="gemini-3.5-flash"
)
```
**Option 3: Direct API Key (Not Recommended for Production)**
You can also provide the API key directly in your code, though this is not recommended for production use:
```python
result = lx.extract(
text_or_documents=input_text,
prompt_description="Extract information...",
examples=[...],
model_id="gemini-3.5-flash",
api_key="your-api-key-here" # Only use this for testing/development
)
```
**Option 4: Vertex AI (Service Accounts)**
Use [Vertex AI](https://cloud.google.com/vertex-ai/docs/start/introduction-unified-platform) for authentication with service accounts:
```python
result = lx.extract(
text_or_documents=input_text,
prompt_description="Extract information...",
examples=[...],
model_id="gemini-3.5-flash",
language_model_params={
"vertexai": True,
"project": "your-project-id",
"location": "global" # or regional endpoint
}
)
```
## Adding Custom Model Providers
LangExtract supports custom LLM providers via a lightweight plugin system. You can add support for new models without changing core code.
- Add new model support independently of the core library
- Distribute your provider as a separate Python package
- Keep custom dependencies isolated
- Override or extend built-in providers via priority-based resolution
See the detailed guide in [Provider System Documentation](langextract/providers/README.md) to learn how to:
- Register a provider with `@router.register(...)` from `langextract.providers`
- Publish an entry point for discovery
- Optionally provide a schema with `get_schema_class()` for structured output
- Integrate with the factory via `create_model(...)`
## Using OpenAI Models
LangExtract supports OpenAI models (requires optional dependency: `pip install langextract[openai]`):
```python
import langextract as lx
# OPENAI_API_KEY in the environment is picked up automatically; pass
# api_key=... explicitly only if you need to override it.
result = lx.extract(
text_or_documents=input_text,
prompt_description=prompt,
examples=examples,
model_id="gpt-4o", # Automatically selects OpenAI provider
)
```
The OpenAI provider uses structured outputs or JSON mode and auto-determines
fence behavior — leave `fence_output` and `use_schema_constraints` unset.
`output_schema` is also supported for OpenAI models that support structured
outputs; provide a LangExtract output-envelope JSON schema, preferably with the
`lx.schema` helpers.
For large, non-latency-sensitive OpenAI workloads, enable the OpenAI Batch API
with `language_model_params`. Batch mode is opt-in and falls back to realtime
calls when the prompt count is below the configured threshold.
```python
result = lx.extract(
text_or_documents=documents,
prompt_description=prompt,
examples=examples,
model_id="gpt-4o-mini",
language_model_params={
"batch": {
"enabled": True,
"threshold": 50,
"poll_interval": 10,
}
},
)
```
For OpenAI-compatible endpoints or non-GPT model IDs (which skip auto-routing), use `ModelConfig` with an explicit provider:
```python
from langextract.factory import ModelConfig
result = lx.extract(
text_or_documents=input_text,
prompt_description=prompt,
examples=examples,
config=ModelConfig(
model_id="my-openai-compatible-model",
provider="openai",
provider_kwargs={"api_key": "sk-...", "base_url": "https://..."},
),
)
```
## Using Local LLMs with Ollama
LangExtract supports local inference using Ollama, allowing you to run models without API keys:
```python
import langextract as lx
result = lx.extract(
text_or_documents=input_text,
prompt_description=prompt,
examples=examples,
model_id="gemma2:2b", # Automatically selects Ollama provider
model_url="http://localhost:11434",
)
```
The Ollama provider exposes `FormatModeSchema` for JSON mode. Leave `fence_output`
and `use_schema_constraints` unset so the factory auto-configures from the provider's
schema. Ollama does not currently support `output_schema`.
**Quick setup:** Install Ollama from [ollama.com](https://ollama.com/), run `ollama pull gemma2:2b`, then `ollama serve`.
For detailed installation, Docker setup, and examples, see [`examples/ollama/`](examples/ollama/).
## More Examples
Additional examples of LangExtract in action:
### *Romeo and Juliet* Full Text Extraction
LangExtract can process complete documents directly from URLs. This example demonstrates extraction from the full text of *Romeo and Juliet* from Project Gutenberg (147,843 characters), showing parallel processing, sequential extraction passes, and performance optimization for long document processing.
**[View *Romeo and Juliet* Full Text Example →](https://github.com/google/langextract/blob/main/docs/examples/longer_text_example.md)**
### Medication Extraction
> **Disclaimer:** This demonstration is for illustrative purposes of LangExtract's baseline capability only. It does not represent a finished or approved product, is not intended to diagnose or suggest treatment of any disease or condition, and should not be used for medical advice.
LangExtract excels at extracting structured medical information from clinical text. These examples demonstrate both basic entity recognition (medication names, dosages, routes) and relationship extraction (connecting medications to their attributes), showing LangExtract's effectiveness for healthcare applications.
**[View Medication Examples →](https://github.com/google/langextract/blob/main/docs/examples/medication_examples.md)**
### Radiology Report Structuring: RadExtract
Explore RadExtract, a live interactive demo on HuggingFace Spaces that shows how LangExtract can automatically structure radiology reports. Try it directly in your browser with no setup required.
**[View RadExtract Demo →](https://google-radextract.hf.space/)**
## Community Providers
Extend LangExtract with custom model providers! Check out our [Community Provider Plugins](COMMUNITY_PROVIDERS.md) registry to discover providers created by the community or add your own.
For detailed instructions on creating a provider plugin, see the [Custom Provider Plugin Example](examples/custom_provider_plugin/).
## Contributing
Contributions are welcome! See [CONTRIBUTING.md](https://github.com/google/langextract/blob/main/CONTRIBUTING.md) to get started
with development, testing, and pull requests. You must sign a
[Contributor License Agreement](https://cla.developers.google.com/about)
before submitting patches.
Thanks to everyone who has [contributed](https://github.com/google/langextract/graphs/contributors).
## Testing
To run tests locally from the source:
```bash
# Clone the repository
git clone https://github.com/google/langextract.git
cd langextract
# Install with test dependencies
pip install -e ".[test]"
# Run all tests
pytest tests
```
Or reproduce the full CI matrix locally with tox:
```bash
tox # runs pylint + pytest on Python 3.10 and 3.11
```
### Ollama Integration Testing
If you have Ollama installed locally, you can run integration tests:
```bash
# Test Ollama integration (requires Ollama running with gemma2:2b model)
tox -e ollama-integration
```
This test will automatically detect if Ollama is available and run real inference tests.
## Development
### Code Formatting
This project uses automated formatting tools to maintain consistent code style:
```bash
# Auto-format all code
./autoformat.sh
# Or run formatters separately
isort langextract tests --profile google --line-length 80
pyink langextract tests --config pyproject.toml
```
### Pre-commit Hooks
For automatic formatting checks:
```bash
pre-commit install # One-time setup
pre-commit run --all-files # Manual run
```
### Linting
Run linting before submitting PRs:
```bash
pylint --rcfile=.pylintrc langextract tests
```
See [CONTRIBUTING.md](CONTRIBUTING.md) for full development guidelines.
## How to Cite
If you use LangExtract in your research, please cite it:
```bibtex
@software{goel_langextract,
author = {Goel, Akshay},
title = {{LangExtract}},
year = {2026},
version = {1.6.0},
doi = {10.5281/zenodo.21126643},
url = {https://github.com/google/langextract}
}
```
Cite the version you used — each release has its own DOI on
[Zenodo](https://doi.org/10.5281/zenodo.17015089). If your style rejects
`@software`, use `@misc`.
## Disclaimer
This is not an officially supported Google product. If you use
LangExtract in production or publications, please cite accordingly and
acknowledge usage. Use is subject to the [Apache 2.0 License](https://github.com/google/langextract/blob/main/LICENSE).
For health-related applications, use of LangExtract is also subject to the
[Health AI Developer Foundations Terms of Use](https://developers.google.com/health-ai-developer-foundations/terms).
---
**Happy Extracting!**
---
### Overview (`examples/custom_provider_plugin/README.md`)
# Custom Provider Plugin Example
This example demonstrates how to create a custom provider plugin that extends LangExtract with your own model backend.
**Note**: This is an example included in the LangExtract repository for reference. It is not part of the LangExtract package and won't be installed when you `pip install langextract`.
**Automated Creation**: Instead of manually copying this example, use the [provider plugin generator script](../../scripts/create_provider_plugin.py):
```bash
python scripts/create_provider_plugin.py MyProvider --with-schema
```
This will create a complete plugin structure with all boilerplate code ready for customization.
## Structure
```
custom_provider_plugin/
├── pyproject.toml # Package configuration and metadata
├── README.md # This file
├── langextract_provider_example/ # Package directory
│ ├── __init__.py # Package initialization
│ ├── provider.py # Custom provider implementation
│ └── schema.py # Custom schema implementation (optional)
└── test_example_provider.py # Test script
```
## Key Components
### Provider Implementation (`provider.py`)
```python
from langextract.core import base_model
from langextract.providers import router
@router.register(
r'^gemini', # Pattern for model IDs this provider handles
)
class CustomGeminiProvider(base_model.BaseLanguageModel):
def __init__(self, model_id: str, **kwargs):
# Initialize your backend client
def infer(self, batch_prompts, **kwargs):
# Call your backend API and return results
```
### Package Configuration (`pyproject.toml`)
```toml
[project.entry-points."langextract.providers"]
custom_gemini = "langextract_provider_example:CustomGeminiProvider"
```
This entry point allows LangExtract to automatically discover your provider.
### Custom Schema Support (`schema.py`)
Providers can optionally implement custom schemas for structured output:
**Flow:** Examples → `from_examples()` → `to_provider_config()` → Provider kwargs → Inference
```python
from langextract.core import schema as core_schema
class CustomProviderSchema(core_schema.BaseSchema):
@classmethod
def from_examples(cls, examples_data, attribute_suffix="_attributes"):
# Analyze examples to find patterns
# Build schema based on extraction classes and attributes seen
return cls(schema_dict)
def to_provider_config(self):
# Convert schema to provider kwargs
return {
"response_schema": self._schema_dict,
"enable_structured_output": True
}
@property
def requires_raw_output(self):
# True = provider emits raw JSON, no markdown fences needed
return True
```
Then in your provider:
```python
class CustomProvider(base_model.BaseLanguageModel):
@classmethod
def get_schema_class(cls):
return CustomProviderSchema # Tell LangExtract about your schema
def __init__(self, **kwargs):
# Receive schema config in kwargs when use_schema_constraints=True
self.response_schema = kwargs.get('response_schema')
def infer(self, batch_prompts, **kwargs):
# Use schema during API calls
if self.response_schema:
config['response_schema'] = self.response_schema
```
## Installation
```bash
# Navigate to this example directory first
cd examples/custom_provider_plugin
# Install in development mode
pip install -e .
# Test the provider (must be run from this directory)
python test_example_provider.py
```
## Usage
Since this example registers the same pattern as the default Gemini provider, you must explicitly specify it:
```python
import langextract as lx
# Option A: build a model explicitly and pass it to extract()
config = lx.factory.ModelConfig(
model_id="gemini-3.5-flash",
provider="CustomGeminiProvider",
provider_kwargs={"api_key": "your-api-key"},
)
model = lx.factory.create_model(config)
result = lx.extract(
text_or_documents="Your text here",
model=model,
prompt_description="Extract key information",
examples=[...],
)
# Option B: let extract() build the model from a ModelConfig
result = lx.extract(
text_or_documents="Your text here",
config=lx.factory.ModelConfig(
model_id="gemini-3.5-flash",
provider="CustomGeminiProvider",
provider_kwargs={"api_key": "your-api-key"},
),
prompt_description="Extract key information",
examples=[...],
)
```
## Creating Your Own Provider - Step by Step
### 1. Copy and Rename
```bash
# Copy this example directory
cp -r examples/custom_provider_plugin/ ~/langextract-myprovider/
# Rename the package directory
cd ~/langextract-myprovider/
mv langextract_provider_example langextract_myprovider
```
### 2. Update Package Configuration
Edit `pyproject.toml`:
- Change `name = "langextract-myprovider"`
- Update description and author information
- Change entry point: `myprovider = "langextract_myprovider:MyProvider"`
### 3. Modify Provider Implementation
Edit `provider.py`:
- Change class name from `CustomGeminiProvider` to `MyProvider`
- Update `@router.register(...)` patterns to match your model IDs
- Replace Gemini API calls with your backend
- Add any provider-specific parameters
### 4. Add Schema Support (Optional)
Edit `schema.py`:
- Rename to `MyProviderSchema`
- Customize `from_examples()` for your extraction format
- Update `to_provider_config()` for your API requirements
- Implement `requires_raw_output` (abstract in `BaseSchema`) based on whether your provider emits raw JSON/YAML or fenced output
### 5. Install and Test
```bash
# Install in development mode
pip install -e .
# Test your provider
python -c "
from langextract.providers import load_plugins_once, router
load_plugins_once()
print('Provider registered:', any('myprovider' in str(e) for e in router.list_entries()))
"
```
### 6. Write Tests
- Test that your provider loads and handles basic inference
- Verify schema support works (if implemented)
- Test error handling for your specific API
### 7. Publish to PyPI and Share with Community
```bash
# Build package
python -m build
# Upload to PyPI
twine upload dist/*
```
**Share with the community:**
- Submit a PR to add your provider to the [Community Providers Registry](../../COMMUNITY_PROVIDERS.md)
- Open an issue on [LangExtract GitHub](https://github.com/google/langextract/issues) to announce your provider and get feedback
## Common Pitfalls to Avoid
1. **Forgetting to trigger plugin loading** - Plugins load lazily, use `load_plugins_once()` in tests
2. **Pattern conflicts** - Avoid patterns that conflict with built-in providers
3. **Missing dependencies** - List all requirements in `pyproject.toml`
4. **Schema mismatches** - Test schema generation with real examples
5. **Not handling None schema** - Provider must clear schema when `apply_schema(None)` is called (see provider.py for implementation)
## License
Apache License 2.0
---
### Overview (`examples/ollama/README.md`)
# Ollama Examples
This directory contains examples for using LangExtract with Ollama for local LLM inference.
For setup instructions and documentation, see the [main README's Ollama section](../../README.md#using-local-llms-with-ollama).
## Quick Reference
**Option 1: Run locally**
```bash
# Install and start Ollama
ollama pull gemma2:2b
ollama serve # Keep this running in a separate terminal
# Run the demo
python demo_ollama.py
```
**Option 2: Run with Docker**
```bash
# Runs both Ollama and the demo in containers
docker-compose up
```
## Files
- `demo_ollama.py` - Comprehensive extraction examples demonstrating Ollama on README examples
- `docker-compose.yml` - Production-ready Docker setup with health checks
- `Dockerfile` - Container definition for LangExtract
## Configuration Options
### Timeout Settings
For slower models or large prompts, you may need to increase the timeout (default: 120 seconds):
```python
import langextract as lx
result = lx.extract(
text_or_documents=input_text,
prompt_description=prompt,
examples=examples,
model_id="llama3.1:70b", # Larger model may need more time
timeout=300, # 5 minutes
model_url="http://localhost:11434",
)
```
Or using ModelConfig:
```python
config = lx.factory.ModelConfig(
model_id="llama3.1:70b",
provider_kwargs={
"model_url": "http://localhost:11434",
"timeout": 300, # 5 minutes
}
)
```
## Model License
Ollama models come with their own licenses. For example:
- Gemma models: [Gemma Terms of Use](https://ai.google.dev/gemma/terms)
- Llama models: [Meta Llama License](https://llama.meta.com/llama-downloads/)
Please review the license for any model you use.
---
### Overview (`langextract/_compat/README.md`)
# Backward Compatibility Layer
This directory contains backward compatibility shims for deprecated imports.
## Deprecation Timeline
All code in this directory will be removed in LangExtract v2.0.0.
## Migration Guide
The following imports are deprecated and should be updated:
### Inference Module
- `from langextract.inference import BaseLanguageModel` → `from langextract.core.base_model import BaseLanguageModel`
- `from langextract.inference import ScoredOutput` → `from langextract.core.types import ScoredOutput`
- `from langextract.inference import InferenceOutputError` → `from langextract.core.exceptions import InferenceOutputError`
- `from langextract.inference import GeminiLanguageModel` → `from langextract.providers.gemini import GeminiLanguageModel`
- `from langextract.inference import OpenAILanguageModel` → `from langextract.providers.openai import OpenAILanguageModel`
- `from langextract.inference import OllamaLanguageModel` → `from langextract.providers.ollama import OllamaLanguageModel`
### Schema Module
- `from langextract.schema import BaseSchema` → `from langextract.core.schema import BaseSchema`
- `from langextract.schema import Constraint` → `from langextract.core.schema import Constraint`
- `from langextract.schema import ConstraintType` → `from langextract.core.schema import ConstraintType`
- `from langextract.schema import EXTRACTIONS_KEY` → `from langextract.core.schema import EXTRACTIONS_KEY`
- `from langextract.schema import GeminiSchema` → `from langextract.providers.schemas.gemini import GeminiSchema`
### Exceptions Module
- All exceptions: `from langextract.exceptions import *` → `from langextract.core.exceptions import *`
### Registry Module
- `from langextract.registry import *` → `from langextract.plugins import *`
- `from langextract.providers.registry import *` → `from langextract.providers.router import *`
## For Contributors
Do not add new code to this directory. All new development should use the canonical imports from `core/` and `providers/`.
---
### Overview (`langextract/providers/README.md`)
# LangExtract Provider System
This directory contains the provider system for LangExtract, which enables support for different Large Language Model (LLM) backends.
**Quick Start**: Use the [provider plugin generator script](../../scripts/create_provider_plugin.py) to create a new provider in minutes:
```bash
python scripts/create_provider_plugin.py MyProvider --with-schema
```
## Architecture Overview
The provider system uses a **router pattern** with **automatic discovery**:
1. **Router** (`router.py`): Maps model ID patterns to provider classes. A legacy `registry.py` alias still imports — new code should use `router` directly.
2. **Factory** (`../factory.py`): Creates provider instances based on model IDs
3. **Providers**: Implement the `BaseLanguageModel` interface (from `langextract.core.base_model`)
### Provider Resolution Flow
```
User Code LangExtract Provider
───────── ─────────── ────────
| | |
| lx.extract( | |
| model_id="gemini-3.5-flash") |
|─────────────────────────────> |
| | |
| factory.create_model() |
| | |
| router.resolve("gemini-3.5-flash") |
| Pattern match: ^gemini |
| ↓ |
| GeminiLanguageModel |
| | |
| Instantiate provider |
| |─────────────────────────────>|
| | |
| | Provider API calls |
| |<─────────────────────────────|
| | |
|<──────────────────────────── |
| AnnotatedDocument | |
```
### Explicit Provider Selection
When multiple providers might support the same model ID, or when you want to use a specific provider, you can explicitly specify the provider:
```python
import langextract as lx
# Method 1: Using factory directly with provider parameter
config = lx.factory.ModelConfig(
model_id="gpt-4",
provider="OpenAILanguageModel", # Explicit provider
provider_kwargs={"api_key": "..."}
)
model = lx.factory.create_model(config)
# Method 2: Using provider without model_id (uses provider's default)
config = lx.factory.ModelConfig(
provider="GeminiLanguageModel", # Will use default gemini-3.5-flash
provider_kwargs={"api_key": "..."}
)
model = lx.factory.create_model(config)
# Method 3: Auto-detection (when no conflicts exist)
config = lx.factory.ModelConfig(
model_id="gemini-3.5-flash" # Provider auto-detected
)
model = lx.factory.create_model(config)
```
Provider names can be:
- Full class name: `"GeminiLanguageModel"`, `"OpenAILanguageModel"`, `"OllamaLanguageModel"`
- Partial match: `"gemini"`, `"openai"`, `"ollama"` (case-insensitive)
## Provider Types
### 1. Core Providers (Always Available)
Ships with langextract, dependencies included:
- **Gemini** (`gemini.py`): Google's Gemini models
- **Ollama** (`ollama.py`): Local models via Ollama
### 2. Built-in Provider with Optional Dependencies
Ships with langextract, but requires extra installation:
- **OpenAI** (`openai.py`): OpenAI's GPT models
- Code included in package
- Requires: `pip install langextract[openai]` to install OpenAI SDK
- Future: May be moved to external plugin package
### 3. External Plugins (Third-party)
Separate packages that extend LangExtract with new providers:
- **Installed separately**: `pip install langextract-yourprovider`
- **Auto-discovered**: Uses Python entry points for automatic registration
- **Zero configuration**: Import langextract and the provider is available
- **Independent updates**: Update providers without touching core
```python
# Install a third-party provider
pip install langextract-yourprovider
# Use it immediately - no imports needed!
import langextract as lx
result = lx.extract(
text_or_documents="...",
prompt_description="Extract key information",
examples=[...],
model_id="yourmodel-latest", # Automatically finds the provider
)
```
#### How Plugin Discovery Works
```
1. pip install langextract-yourprovider
└── Installs package containing:
• Provider class with @router.register decorator
• Python entry point pointing to this class
2. import langextract
└── Loads providers/__init__.py
└── Plugin loading is lazy (on-demand)
3. lx.extract(model_id="yourmodel-latest")
└── Triggers plugin discovery via entry points
└── @router.register decorator fires
└── Provider patterns added to router
└── Router matches pattern and uses your provider
```
**Important Notes:**
- Plugin loading is **lazy** - plugins are discovered when first needed
- To manually trigger plugin loading: `lx.providers.load_plugins_once()`
- Set `LANGEXTRACT_DISABLE_PLUGINS=1` to disable plugin loading
- Registry entries are tuples: `(patterns_list, priority_int)`
## How Provider Selection Works
When you call `lx.extract(model_id="gemini-3.5-flash", ...)`, here's what happens:
1. **Factory receives model_id**: "gemini-3.5-flash"
2. **Router searches patterns**: Each provider registers regex patterns
3. **First match wins**: Returns the matching provider class
4. **Provider instantiated**: With model_id and any kwargs
5. **Inference runs**: Using the selected provider
### Pattern Registration Example
```python
from langextract.core import base_model
from langextract.providers import router
# Gemini provider registration:
@router.register(
r'^GeminiLanguageModel$', # Explicit: model_id="GeminiLanguageModel"
r'^gemini', # Prefix: model_id="gemini-3.5-flash"
r'^palm' # Legacy: model_id="palm-2"
)
class GeminiLanguageModel(base_model.BaseLanguageModel):
def __init__(self, model_id: str, api_key: str = None, **kwargs):
# Initialize Gemini client
...
def infer(self, batch_prompts, **kwargs):
# Call Gemini API
...
```
## Usage Examples
### Using Default Provider Selection
```python
import langextract as lx
# Automatically selects Gemini provider
result = lx.extract(
text_or_documents="...",
prompt_description="Extract key information",
examples=[...],
model_id="gemini-3.5-flash",
)
```
### Passing Parameters to Providers
Parameters flow from `lx.extract()` to providers through several mechanisms:
```python
# 1. Common parameters handled by lx.extract itself:
result = lx.extract(
text_or_documents="Your document",
model_id="gemini-3.5-flash",
prompt_description="Extract key facts",
examples=[...], # Required unless output_schema is provided
max_workers=4, # Parallel processing (provider-dependent)
max_char_buffer=3000, # Document chunking
)
# 2. Provider-specific constructor parameters via language_model_params:
result = lx.extract(
text_or_documents="Your document",
model_id="gemini-3.5-flash",
prompt_description="Extract entities",
examples=[...],
temperature=0.7, # Common sampling parameter
api_key="your-key", # Override environment variable
language_model_params={
"max_output_tokens": 1000,
"top_p": 0.95,
"top_k": 40,
},
)
```
### Using the Factory for Advanced Control
```python
# When you need explicit provider selection or advanced configuration
from langextract import factory
# Specify both model and provider (useful when multiple providers support same model)
config = factory.ModelConfig(
model_id="gemma2:2b",
provider="OllamaLanguageModel", # Explicitly use Ollama
provider_kwargs={
"model_url": "http://localhost:11434"
}
)
model = factory.create_model(config)
```
### Direct Provider Usage
```python
import langextract as lx
# Direct import if you prefer (optional)
from langextract.providers.gemini import GeminiLanguageModel
model = GeminiLanguageModel(
model_id="gemini-3.5-flash",
api_key="your-key"
)
outputs = model.infer(["prompt1", "prompt2"])
```
## Creating a New Provider
**📁 Complete Example**: See [examples/custom_provider_plugin/](../../examples/custom_provider_plugin/) for a fully-functional plugin template with testing and documentation.
### Quick Start Checklist
Creating a provider plugin? Follow this checklist:
#### ☐ **1. Setup Package Structure**
```
langextract-yourprovider/
├── pyproject.toml # Package config with entry point
├── README.md # Documentation
├── LICENSE # License file
└── langextract_yourprovider/ # Package directory
├── __init__.py # Exports provider class
├── provider.py # Provider implementation
└── schema.py # (Optional) Custom schema
```
#### ☐ **2. Configure Entry Point** (`pyproject.toml`)
```toml
[build-system]
requires = ["setuptools>=61.0", "wheel"]
build-backend = "setuptools.build_meta"
[project]
name = "langextract-yourprovider"
version = "0.1.0"
dependencies = ["langextract>=1.0.0"]
[project.entry-points."langextract.providers"]
yourprovider = "langextract_yourprovider:YourProviderLanguageModel"
```
#### ☐ **3. Implement Provider** (`provider.py`)
- [ ] Import required modules
- [ ] Add `@router.register()` decorator with patterns
- [ ] Inherit from `base_model.BaseLanguageModel`
- [ ] Implement `__init__()` method
- [ ] Implement `infer()` method returning `ScoredOutput` objects
- [ ] Export class from `__init__.py`
#### ☐ **4. (Optional) Add Schema Support** (`schema.py`)
- [ ] Create schema class inheriting from `langextract.core.schema.BaseSchema`
- [ ] Implement `from_examples()` class method
- [ ] Implement `from_schema_dict()` if the provider supports `output_schema`
- [ ] Implement `to_provider_config()` method
- [ ] Add `get_schema_class()` to provider
- [ ] Handle schema in provider's `__init__()` and `infer()`
#### ☐ **5. Testing**
- [ ] Install plugin with `pip install -e .`
- [ ] Test that your provider loads and handles basic inference
- [ ] Verify schema support works (if implemented)
#### ☐ **6. Documentation**
- [ ] Document supported model IDs and patterns
- [ ] List required environment variables
- [ ] Provide usage examples
- [ ] Document any provider-specific parameters
#### ☐ **7. Distribution & Community**
- [ ] Test installation with `pip install -e .`
- [ ] Build package with `python -m build`
- [ ] Test in clean environment
- [ ] Publish to PyPI with `twine upload dist/*`
- [ ] Share your provider by opening an issue on [LangExtract GitHub](https://github.com/google/langextract/issues) to get feedback and help others discover it
- [ ] Consider submitting a PR to add your provider to [COMMUNITY_PROVIDERS.md](../../COMMUNITY_PROVIDERS.md)
### Option 1: External Plugin (Recommended)
External plugins are the recommended approach for adding new providers. They're easy to maintain, distribute, and don't require changes to the core package.
#### For Users (Installing an External Plugin)
Simply install the plugin package:
```bash
pip install langextract-yourprovider
# That's it! The provider is now available in langextract
```
#### For Developers (Creating an External Plugin)
1. Create a new package:
```
langextract-myprovider/
├── pyproject.toml
├── README.md
└── langextract_myprovider/
└── __init__.py
```
2. Configure entry point in `pyproject.toml`:
```toml
[build-system]
requires = ["setuptools>=61.0", "wheel"]
build-backend = "setuptools.build_meta"
[project]
name = "langextract-myprovider"
version = "0.1.0"
dependencies = ["langextract>=1.0.0", "your-sdk"]
[project.entry-points."langextract.providers"]
# Pattern 1: Register the class directly
myprovider = "langextract_myprovider:MyProviderLanguageModel"
# Pattern 2: Register a module that self-registers
# myprovider = "langextract_myprovider"
```
3. Implement your provider:
```python
# langextract_myprovider/__init__.py
import os
from langextract.core import base_model, types
from langextract.providers import router
@router.register(r'^mymodel', r'^custom', priority=10)
class MyProviderLanguageModel(base_model.BaseLanguageModel):
def __init__(self, model_id: str, api_key: str = None, **kwargs):
super().__init__()
self.model_id = model_id
self.api_key = api_key or os.environ.get('MYPROVIDER_API_KEY')
# Initialize your client
self.client = MyProviderClient(api_key=self.api_key)
def infer(self, batch_prompts, **kwargs):
# Implement inference
for prompt in batch_prompts:
result = self.client.generate(prompt, **kwargs)
yield [types.ScoredOutput(score=1.0, output=result)]
```
The built-in providers keep SDK response types inside the provider. A local
helper such as `_response_to_scored_output()` translates usable text into
`ScoredOutput` and raises a provider-tagged `InferenceRuntimeError` for blocked,
refused, truncated, or otherwise unusable responses. `infer()` remains the
public plugin contract; the helper is a convention, not a required base method.
Providers using this pattern should re-raise `InferenceRuntimeError` before any
retry or blanket exception handler so the diagnostic is preserved.
**Pattern Registration Explained:**
- The `@router.register` decorator patterns (e.g., `r'^mymodel'`, `r'^custom'`) define which model IDs your provider supports
- When users call `lx.extract(model_id="mymodel-3b")`, the router matches against these patterns
- Your provider will handle any model_id starting with "mymodel" or "custom"
- Users can explicitly select your provider using its class name:
```python
config = lx.factory.ModelConfig(provider="MyProviderLanguageModel")
# Or partial match: provider="myprovider" (matches class name)
```
4. Publish your package to PyPI:
```bash
pip install build twine
python -m build
twine upload dist/*
```
Now users can install and use your provider with just `pip install langextract-myprovider`!
### Adding Schema Support
Schemas enable structured output with strict JSON constraints. Here's how to add schema support to your provider:
#### 1. Create a Schema Class
```
/* Detailed source-code truncated for AI context efficiency. */
```
#### 2. Update Your Provider
```
/* Detailed source-code truncated for AI context efficiency. */
```
#### 3. Schema Usage
When users set `use_schema_constraints=True`, LangExtract will:
1. Call your provider's `get_schema_class()`
2. Use `from_examples()` to build a schema from provided examples
3. Call `to_provider_config()` to get provider-specific kwargs
4. Pass these kwargs to your provider's `__init__()`
5. Your provider uses the schema for structured output
For user-authored schemas passed as `output_schema=...`, also implement
`BaseSchema.from_schema_dict()`. If the provider exposes lower-level schema
kwargs such as `response_schema`, list them in
`output_schema_reserved_provider_kwargs()` so LangExtract can reject ambiguous
requests where both `output_schema` and provider-native schema kwargs are set.
Schemas returned from `from_schema_dict()` should expose
`from_output_schema=True`; `BaseLanguageModel.apply_output_schema()` marks
mutable schema instances automatically, but explicit state is safest for
dataclass or slots-based schemas.
Providers that store schema state after construction should override
`apply_schema()` and call `super().apply_schema(schema_instance)`.
### Option 2: Built-in Provider (Requires Core Team Approval)
**⚠️ Note**: Adding a provider to the core package requires:
- Significant community demand and support
- Commitment to long-term maintenance
- Approval from the LangExtract maintainers
- A pull request to the main repository
This approach should only be used for providers that benefit a large portion of the user base.
1. Create your provider file:
```python
# langextract/providers/myprovider.py
from langextract.core import base_model
from langextract.providers import router
@router.register(r'^mymodel', r'^custom')
class MyProviderLanguageModel(base_model.BaseLanguageModel):
# Implementation same as above
```
2. Import it in `providers/__init__.py`:
```python
# In langextract/providers/__init__.py
from langextract.providers import myprovider # noqa: F401
```
3. Submit a pull request with:
- Provider implementation
- Comprehensive tests
- Documentation
- Justification for inclusion in core
## Environment Variables
The factory automatically resolves API keys from environment:
| Provider | Environment Variables (in priority order) |
|----------|------------------------------------------|
| Gemini | `GEMINI_API_KEY`, `LANGEXTRACT_API_KEY` |
| OpenAI | `OPENAI_API_KEY`, `LANGEXTRACT_API_KEY` |
| Ollama | `OLLAMA_BASE_URL` (default: http://localhost:11434) |
## Design Principles
1. **Zero Configuration**: Providers auto-register when imported
2. **Extensible**: Easy to add new providers without modifying core
3. **Lazy Loading**: Optional dependencies only loaded when needed
4. **Explicit Control**: Users can force specific providers when needed
5. **Pattern Priority**: All patterns have equal priority (0) by default
## Common Issues
### Provider Not Found
```python
InferenceConfigError: No provider registered for model_id='unknown-model'
```
**Solution**: Check available patterns with `langextract.providers.router.list_entries()`
### Plugin Not Loading
```python
# Your plugin isn't being discovered
```
**Solutions**:
1. Manually trigger loading: `lx.providers.load_plugins_once()`
2. Check entry points are installed: `pip show -f your-package`
3. Verify no typos in `pyproject.toml` entry point
4. Ensure package is installed: `pip list | grep your-package`
### Missing Dependencies
```python
InferenceConfigError: OpenAI provider requires openai package
```
**Solution**: Install optional dependencies: `pip install langextract[openai]`
### Schema Not Working
```python
# Schema constraints not being applied
```
**Solutions**:
1. Ensure provider implements `get_schema_class()`
2. Check `use_schema_constraints=True` is set
3. Verify schema's `requires_raw_output` returns `True`
4. Test schema creation with `Schema.from_examples(examples)`
### Pattern Conflicts
```python
# Multiple providers match the same model_id
```
**Solution**: Use explicit provider selection:
```python
config = lx.factory.ModelConfig(
model_id="model-name",
provider="YourProviderClass", # Explicit selection
)
```
---
### Overview (`skills/langextract-usage/README.md`)
# langextract-usage — Agent Skill
This directory is an [Agent Skill](https://agentskills.io) source that teaches
AI coding assistants how to use LangExtract correctly. It follows the open
Agent Skills format (`SKILL.md` with YAML frontmatter, optional
`references/`, `examples/`).
This directory is **not** auto-discovered by any tool from the `skills/`
path it lives in here. To use it, copy or symlink the directory into
whichever path your Agent-Skills-compatible tool reads from.
## Activate
Pick your tool, then install at either project scope (this repo only) or
user scope (all your projects). Paths below are **canonical examples** per
each tool's 2026 docs — some tools (Copilot, Codex) scan several paths,
so any of the documented locations works. Check the linked docs for the
full list if your tool has moved.
Project-scope paths are relative to your workspace/repo root. Run the copy
or symlink command from there.
| Tool | Project-scope path (example) | User-scope path (example) |
|---|---|---|
| [Google Antigravity](https://antigravity.google/docs/skills) | `.agents/skills/langextract-usage/` | `~/.gemini/antigravity/skills/langextract-usage/` |
| [Anthropic Claude Code](https://code.claude.com/docs/en/skills) | `.claude/skills/langextract-usage/` | `~/.claude/skills/langextract-usage/` |
| [OpenAI Codex](https://developers.openai.com/codex/skills) | `.agents/skills/langextract-usage/` | `~/.agents/skills/langextract-usage/` |
| [GitHub Copilot](https://docs.github.com/en/copilot) | `.github/skills/langextract-usage/` | `~/.copilot/skills/langextract-usage/` |
Notes:
- **Antigravity** also recognizes legacy `.agent/skills/` (singular) for
backward compatibility; new installs should use `.agents/skills/`
(plural).
- **Copilot** also accepts `.claude/skills/` or `.agents/skills/` at project
scope, and `~/.claude/skills/` or `~/.agents/skills/` at user scope.
- **Codex** scans `.agents/skills/` from the current directory up through
the repo root, so a project-scope install works from any subdirectory.
- A project-scope `.agents/skills/langextract-usage/` therefore activates
the skill in Antigravity, Codex, and Copilot simultaneously.
### Copy (static install)
```bash
cp -R skills/langextract-usage
```
### Symlink (tracks this repo's updates)
```bash
ln -s "$(pwd)/skills/langextract-usage"
```
### Other tools
- **Agent-Skills-compatible tools not listed above** — point the tool at
this directory as a skill source, following its own docs.
- **Tools that read their own instruction format** (e.g. Cursor
`.cursor/rules/`, Windsurf `.windsurf/rules/`, Aider `CONVENTIONS.md`) —
copy the relevant sections of `SKILL.md` / `references/*.md` into that
tool's convention. The content is portable; only the activation
mechanism differs.
After activating, restart your agent session if the tool does not
auto-detect changes.
## Contents
- `SKILL.md` — entry point; install, basic usage, key parameters, working with
results, common issues
- `references/providers.md` — Gemini, OpenAI, Ollama, `ModelConfig`, custom
provider plugins
- `references/resolver-params.md` — fuzzy alignment tuning
- `references/prompt-validation.md` — `PromptValidationLevel` details
- `examples/` — runnable scripts (`basic_extraction.py`,
`relationship_extraction.py`, `multiple_documents.py`)
## Maintenance
When changing user-facing LangExtract APIs (imports, `lx.extract()` kwargs,
resolver or validation behavior), please update the affected files in this
subtree in the same PR. If you spot drift, open an issue or PR.
---
### Examples Batch Api Example (`docs/examples/batch_api_example.md`)
# Vertex AI Batch Processing Guide
The Vertex AI Batch API offers significant cost savings (~50%) for large, non-time-critical workloads. `langextract` seamlessly integrates this with automatic routing, caching, and fault tolerance.
**[Vertex AI Batch Prediction Documentation →](https://docs.cloud.google.com/vertex-ai/generative-ai/docs/multimodal/batch-prediction-gemini)**
**[Quotas & Limits →](https://docs.cloud.google.com/vertex-ai/generative-ai/docs/quotas#batch-prediction-quotas)**
## Real-World Example: Processing Shakespeare
This example demonstrates how to process a large text (the first ~20 pages of *Romeo and Juliet*) using the Batch API. We use a small chunk size (`max_char_buffer=500`) to generate enough chunks to trigger batch processing.
```
/* Detailed source-code truncated for AI context efficiency. */
```
## GCS File Structure
The library automatically creates and manages a GCS bucket for you, named:
`langextract-{project}-{location}-batch`
Inside this bucket, data is organized as follows:
- **Input**: `batch-input/{job_name}.jsonl`
- **Output**: `batch-input/{job_name}/dest/prediction-model-{timestamp}/predictions.jsonl`
- **Cache**: `cache/{hash}.json` (Individual cached results)
## Cost Optimization & Caching
LangExtract's batch processing is designed to minimize costs:
1. **Cost Efficiency**: Vertex AI Batch predictions are typically ~50% cheaper than online predictions.
2. **Smart Caching**:
- Results are cached in your GCS bucket (`cache/` directory).
- **Instant Retrieval**: Re-running identical prompts fetches results directly from storage, bypassing model inference.
- **Reduced Inference**: You avoid paying for redundant model calls on previously processed data.
- **Lifecycle Management**: Use `retention_days` (e.g., 30) to automatically clean up old data and manage storage usage.
## Analyze Results
```python
print(f"Extracted {len(results.extractions)} entities.")
print("First 5 extractions:")
for extraction in results.extractions[:5]:
print(f"- {extraction.extraction_class}: {extraction.extraction_text}")
```
## Sample Output
```text
Extracted 767 entities.
First 5 extractions:
- character: ESCALUS
- character: MERCUTIO
- character: PARIS
- character: Page to Paris
- character: MONTAGUE
```
> **Note on `batch_length`**: The `batch_length` parameter controls how many chunks are submitted in a single batch job. For optimal performance with the Batch API, set this to a high value (e.g., `1000`) to process all chunks in a single job rather than multiple sequential jobs.
## Key Features
### 1. Automatic Routing
`langextract` automatically switches between real-time and batch APIs based on your `threshold`.
- **< Threshold**: Uses real-time API for immediate results.
- **>= Threshold**: Uses Batch API for cost savings.
### 2. Fault Tolerance & Caching
Built-in GCS caching (`enable_caching=True`) allows you to resume interrupted jobs without re-processing completed items, saving time and cost.
### 3. Automated Storage
`langextract` handles all GCS operations automatically using a dedicated bucket (`gs://langextract-{project}-{location}-batch`). Note that input/output files are retained for debugging.
## Tracking Job Status
To monitor progress, you can watch the log file from a separate terminal:
```bash
tail -f batch_process.log
```
When running a batch job, `langextract` provides clear log feedback with a direct link to the Google Cloud Console:
```text
INFO - Batch job created successfully: projects/123456789/locations/us/batchPredictionJobs/987654321
INFO - Job State: JobState.JOB_STATE_PENDING
INFO - Job Console URL: https://console.cloud.google.com/vertex-ai/jobs/batch-predictions/987654321?project=123456789
INFO - Batch job is running... (State: JOB_STATE_PENDING)
INFO - Batch job is running... (State: JOB_STATE_RUNNING)
```
- **Completion**: Once the job succeeds, `langextract` automatically downloads, parses, and aligns the results.
---
### Examples Japanese Extraction (`docs/examples/japanese_extraction.md`)
# Japanese Information Extraction
This example demonstrates how to use LangExtract to extract structured information from Japanese text.
> **Note:** For non-spaced languages like Japanese, use `UnicodeTokenizer` to ensure correct character-based segmentation and alignment.
## Full Pipeline Example
```
/* Detailed source-code truncated for AI context efficiency. */
```
---
### Examples Longer Text Example (`docs/examples/longer_text_example.md`)
# *Romeo and Juliet* Full Text Extraction
LangExtract can process entire documents directly from URLs, handling large texts with high accuracy through parallel processing and enhanced sensitivity features. This example demonstrates extraction from the complete text of *Romeo and Juliet* from Project Gutenberg.
## Example code
The following code uses a comprehensive prompt and examples optimized for large, complex literary texts. For large complex inputs, using more detailed examples is suggested to increase extraction robustness.
> **Warning:** Running this example processes a large document (~44 000 tokens) and will incur costs. For large-scale use, a Tier 2 Gemini quota is suggested to avoid rate-limit issues ([details](https://ai.google.dev/gemini-api/docs/rate-limits#tier-2)). Please review the [Gemini API pricing](https://ai.google.dev/gemini-api/docs/pricing) before proceeding.
```
/* Detailed source-code truncated for AI context efficiency. */
```
This creates an interactive HTML visualization for exploring the extracted entities:
```python
# Analyze character mentions
characters = {}
for e in result.extractions:
if e.extraction_class == "character":
char_name = e.extraction_text
if char_name not in characters:
characters[char_name] = {"count": 0, "attributes": set()}
characters[char_name]["count"] += 1
if e.attributes:
for attr_key, attr_val in e.attributes.items():
characters[char_name]["attributes"].add(f"{attr_key}: {attr_val}")
# Print character summary
print(f"\nCHARACTER SUMMARY ({len(characters)} unique characters)")
print("=" * 60)
sorted_chars = sorted(characters.items(), key=lambda x: x[1]["count"], reverse=True)
for char_name, char_data in sorted_chars[:10]: # Top 10 characters
attrs_preview = list(char_data["attributes"])[:3]
attrs_str = f" ({', '.join(attrs_preview)})" if attrs_preview else ""
print(f"{char_name}: {char_data['count']} mentions{attrs_str}")
# Entity type breakdown
entity_counts = Counter(e.extraction_class for e in result.extractions)
print(f"\nENTITY TYPE BREAKDOWN")
print("=" * 60)
for entity_type, count in entity_counts.most_common():
percentage = (count / len(result.extractions)) * 100
print(f"{entity_type}: {count} ({percentage:.1f}%)")
```
## Sample output
```
Downloading and processing Romeo and Juliet from Project Gutenberg...
Downloaded 147,843 characters (25,976 words) from 1513-0.txt
Extracted 4,088 entities from 147,843 characters
Interactive visualization saved to romeo_juliet_visualization.html
CHARACTER SUMMARY (153 unique characters)
============================================================
ROMEO: 287 mentions (emotional_state: excitement, emotional_state: eager to please)
JULIET: 204 mentions (emotional_state: fond, emotional_state: resilient)
NURSE: 168 mentions (emotional_state: reporting, emotional_state: teasing and evasive)
MERCUTIO: 107 mentions (emotional_state: approving, emotional_state: responsive)
BENVOLIO: 82 mentions (emotional_state: cautious, emotional_state: teasing)
ENTITY TYPE BREAKDOWN
============================================================
character: 1,685 (41.2%)
emotion: 1,524 (37.3%)
relationship: 879 (21.5%)
```
## Key benefits for long documents
### Sequential extraction passes
Multiple extraction passes improve recall by performing independent extractions and merging non-overlapping results. Each pass uses identical parameters and processing—they are independent runs of the same extraction task. The number of passes is controlled by the `extraction_passes` parameter (e.g., `extraction_passes=3`).
**How it works**: Each pass processes the full text independently using the same prompt and examples. Results are then merged using a "first-pass wins" strategy for overlapping entities, while adding unique non-overlapping entities from later passes. This approach captures entities that might be missed in any single run due to the stochastic nature of language model generation.
### Portable and Interoperable Data with JSONL
LangExtract uses JSONL, a human-readable format ideal for language model data. Each line is a self-contained JSON object, making outputs easy to parse, share, and integrate with other tools. You can save results with `lx.io.save_annotated_documents` and reload them for later analysis, ensuring your data is both portable and persistent.
### Optimal long context management
While single-inference approaches can be powerful, their accuracy may be affected by distant context. LangExtract uses smart chunking strategies that respect text delimiters (such as paragraph breaks) to keep context intact and well-formed for the model. Users can configure context sizes (`max_char_buffer`) combined with parallel processing (`max_workers`) to maintain extraction quality across large documents. Multiple sequential extraction passes further enhance sensitivity by capturing entities that might be missed in any single run due to the stochastic nature of language model generation.
### Enhanced accuracy through chunking
The chunked processing approach can improve extraction quality over a single inference pass on a large document because each chunk uses a smaller, more manageable context size. This helps the model focus on the most relevant information and prevents interference from distant context. While the overall latency and time required remain similar due to parallelization, the extraction quality can be substantially higher with better entity coverage and more accurate attribute assignment across the entire document.¹
### Interactive visualization at scale
Seamlessly explore hundreds or thousands of entities through interactive HTML visualizations generated directly from JSONL output files. The generated visualizations handle large result sets efficiently, providing navigation and detailed entity inspection capabilities for comprehensive analysis of complex documents.
### Schema-guided knowledge extraction
LangExtract combines precise text positioning with world knowledge enrichment, enabling extraction of information not explicitly stated in the text (like character identities and traits). Under the hood, the library implements [Controlled Generation](https://cloud.google.com/vertex-ai/generative-ai/docs/multimodal/control-generated-output) with supported models to ensure extracted data adheres to your specified schema while maintaining robust extractions across large inputs.
---
¹ Models like Gemini 1.5 Pro show strong performance on many benchmarks, but [needle-in-a-haystack tests](https://cloud.google.com/blog/products/ai-machine-learning/the-needle-in-the-haystack-test-and-how-gemini-pro-solves-it) across million-token contexts indicate that performance can vary in multi-fact retrieval scenarios. This demonstrates how LangExtract's smaller context windows approach ensures consistently high quality across entire documents by avoiding the complexity and potential degradation of massive single-context processing.
---
### Examples Medication Examples (`docs/examples/medication_examples.md`)
# Medication Extraction Examples
LangExtract excels at extracting structured medical information from clinical text, making it particularly useful for healthcare applications. The methodology originated from research in medical information extraction, where early versions of the techniques were demonstrated to accelerate annotation tasks significantly.
> **Disclaimer:** This demonstration is only for illustrative purposes of LangExtract's baseline capability. It does not represent a finished or approved product, is not intended to diagnose or suggest treatment of any disease or condition, and should not be used for medical advice.
---
**Medical Information Extraction Research:**
The concepts and methods underlying LangExtract were first demonstrated in:
Goel, A., Lehman, E., Gulati, A., Chen, R., Nori, H., Hager, G. D., & Durr, N. J. (2023).
"LLMs Accelerate Annotation for Medical Information Extraction."
*Machine Learning for Health (ML4H), PMLR, 2023*.
[arXiv:2312.02296](https://arxiv.org/abs/2312.02296)
---
## Basic Named Entity Recognition (NER)
In this basic medical example, LangExtract extracts structured medication information:
```
/* Detailed source-code truncated for AI context efficiency. */
```
This will produce an output similar to:
```
Input: Patient took 400 mg PO Ibuprofen q4h for two days.
Extracted entities:
• Dosage: 400 mg (pos: 13-19)
• Route: PO (pos: 20-22)
• Medication: Ibuprofen (pos: 23-32)
• Frequency: q4h (pos: 33-36)
• Duration: for two days (pos: 37-49)
Interactive visualization saved to medical_ner_visualization.html
```
The interactive HTML visualization allows you to explore the extracted entities visually, with each entity type color-coded and clickable for detailed inspection.
## Relationship Extraction (RE)
For more complex extractions that involve relationships between entities, LangExtract can also extract structured relationships. This example shows how to extract medications and their associated attributes:
```
/* Detailed source-code truncated for AI context efficiency. */
```
This will produce output similar to:
```
Input text: The patient was prescribed Lisinopril and Metformin last month.
He takes the Lisinopril 10mg daily for hypertension, but often misses
his Metformin 500mg dose which should be taken twice daily for diabetes.
Extracted Medications:
* Lisinopril
• Medication: Lisinopril (pos: 28-38)
• Dosage: 10mg (pos: 89-93)
• Frequency: daily (pos: 94-99)
• Condition: hypertension (pos: 104-116)
* Metformin
• Medication: Metformin (pos: 43-52)
• Dosage: 500mg (pos: 149-154)
• Frequency: twice daily (pos: 182-193)
• Condition: diabetes (pos: 198-206)
Interactive visualization saved to medical_relationship_visualization.html
```
The visualization highlights how the `medication_group` attributes connect related entities, making it easy to see which dosages, frequencies, and conditions belong to each medication. Each medication group is visually distinguished in the interactive display.
**Understanding Relationship Extraction:**
This example demonstrates how attributes enable efficient relationship extraction. Using the `medication_group` attribute as a linking key, related entities are grouped together logically. This approach simplifies extracting connected information and eliminates the need for additional processing steps, while preserving the precise alignment between extracted text and its original location in the document. The interactive visualization makes these relationships immediately apparent, with connected entities sharing visual groupings and color coding.
## Key Features Demonstrated
- **Named Entity Recognition**: Extracts entities with their types (medication, dosage, route, etc.)
- **Relationship Extraction**: Groups related entities using attributes
- **Position Tracking**: Records exact positions of extracted entities in the source text
- **Structured Output**: Organizes information in a format suitable for healthcare applications
- **Interactive Visualization**: Generates HTML visualizations for exploring complex medical extractions with entity groupings and relationships clearly displayed
---
### Examples Output Schema (`docs/examples/output_schema.md`)
# Custom Output Schema Example
LangExtract usually derives provider schema constraints from examples. For
advanced cases, pass `output_schema` to constrain the raw model output more
directly. This example restricts a `status` attribute to the enum values
`present` and `absent`.
Examples are optional when `output_schema` is provided. When examples are
included, they still guide the prompt; `output_schema` replaces only the
provider schema constraint. The schema must describe LangExtract's JSON output
envelope with a top-level `extractions` array.
Gemini and OpenAI support `output_schema`. Ollama does not currently support
user-provided output schemas.
The helper emits `additionalProperties: False` so schemas work with OpenAI
strict structured outputs. Gemini receives user-provided schemas through its
native JSON Schema field, so JSON Schema keywords such as
`additionalProperties` are preserved.
## Full Pipeline Example
```
/* Detailed source-code truncated for AI context efficiency. */
```
This will produce output similar to:
```text
Input: Patient has hypertension. Patient denies diabetes.
Extracted conditions:
• hypertension: present
• diabetes: absent
```
## Multiple Extraction Classes
For heterogeneous extraction classes, pass multiple item schemas. The helper
wraps them in `anyOf` under `extractions.items`:
```python
output_schema = lx.schema.extractions_schema(
lx.schema.extraction_item_schema("condition"),
lx.schema.extraction_item_schema("medication"),
)
```
## Raw Schema Equivalent
For full control, pass a raw JSON schema dictionary. When targeting OpenAI
strict mode, every object schema must declare `required` fields and
`additionalProperties: False`.
Attribute objects use the `_attributes` property name.
LangExtract's resolver expects that suffix when parsing raw model output.
Each extraction item should use extraction-class text keys such as
`condition`; generic fields such as `extraction_class`, `extraction_text`,
and `attributes` are not resolver output keys. Extraction class names ending
in `_attributes` are reserved for attribute objects.
The full pipeline example above produces this equivalent envelope:
```python
output_schema = {
"type": "object",
"properties": {
"extractions": {
"type": "array",
"items": {
"type": "object",
"properties": {
"condition": {"type": "string"},
"condition_attributes": {
"type": "object",
"properties": {
"status": {
"type": "string",
"enum": ["present", "absent"],
}
},
"required": ["status"],
"additionalProperties": False,
},
},
"required": ["condition", "condition_attributes"],
"additionalProperties": False,
},
}
},
"required": ["extractions"],
"additionalProperties": False,
}
```
Use raw schemas when you need JSON Schema constructs that the helpers do not
cover directly, such as custom `anyOf` variants. OpenAI strict structured
outputs support `anyOf`; use `strict=False` only in lower-level provider code
if you need to experiment with schema features outside OpenAI's strict subset.
## Optional Attributes
The helper marks every supplied attribute as required by default so the schema
is compatible with OpenAI strict structured outputs. To allow an attribute to
be absent in practice, make the value nullable while keeping the key required:
```python
output_schema = lx.schema.extractions_schema(
lx.schema.extraction_item_schema(
"condition",
attributes={
"status": {
"anyOf": [
{"type": "string", "enum": ["present", "absent"]},
{"type": "null"},
]
}
},
)
)
```
If you need a schema where an attribute key may be omitted entirely, use a raw
schema for that provider-specific shape.
## Errors and Pitfalls
- Invalid envelopes raise `InferenceConfigError` before provider construction.
- `output_schema` can be passed with either `model_id`/`config` or a
preconfigured `model` when the provider supports user schemas.
- Examples are optional with `output_schema`. When supplied, keep example
classes and attribute names aligned with the schema to avoid confusing the
model.
- `output_schema` requires raw JSON provider output. Leave `format_type` unset
or set it to `lx.data.FormatType.JSON`, and do not force fences.
- Keep the resolver's default `"_attributes"` suffix. Custom
`attribute_suffix`/`extraction_attributes_suffix` settings are incompatible
with the raw schema envelope.
- Do not combine `output_schema` with provider schema kwargs such as
`response_format`, `response_schema`, or `response_json_schema`.
- When targeting Gemini 2.0 models, add Gemini's `propertyOrdering` keyword
to object schemas that need an explicit property order. The LangExtract
helpers stay provider-neutral and do not add that Gemini-specific extension.
- Raw schemas must describe `extractions.items` inline, including each
extraction text key and `_attributes` object. LangExtract
does not resolve `$ref` for those resolver keys before provider construction.
- Use `anyOf`, not `oneOf`, for item unions. Gemini treats `oneOf` like
`anyOf`, and OpenAI strict structured outputs reject `oneOf`.
- `lx.schema.extraction_item_schema(..., additional_properties=False)` applies
that setting to both the outer extraction item object and its nested
`_attributes` object.
- OpenAI uses strict structured outputs by default with LangExtract's default
schema name. The lower-level `OpenAISchema.from_schema_dict(...,
schema_name=..., strict=False)` constructor is an escape hatch for callers
configuring provider models directly.
- LangExtract validates only the output envelope locally; the provider API
validates the JSON schema itself. OpenAI strict mode requires every object
to list all properties in `required` and set
`additionalProperties: false` — the `lx.schema` helpers emit compliant
schemas, and the OpenAI API reports the exact path of any violation in
hand-written schemas. Schema size/depth limits, enum limits, and keyword
support also vary by provider, model, and endpoint.
- Avoid `stop`/`stop_sequences` with `output_schema`: stop sequences can
truncate schema-constrained JSON mid-document while the response still
reports a normal finish reason.
---
--- METRICS ---
- Files Extracted: 11
- Estimated Token Budget: ~19500 tokens
- Canonical Reference: https://codewiki.google/github.com/google/langextract